Since 10.3.0 a numeric sort can skip whole blocks of documents with the doc-values skip index. For FLOAT and DOUBLE on a NUMERIC field, that check compares numbers in two encodings that disagree for negative values.
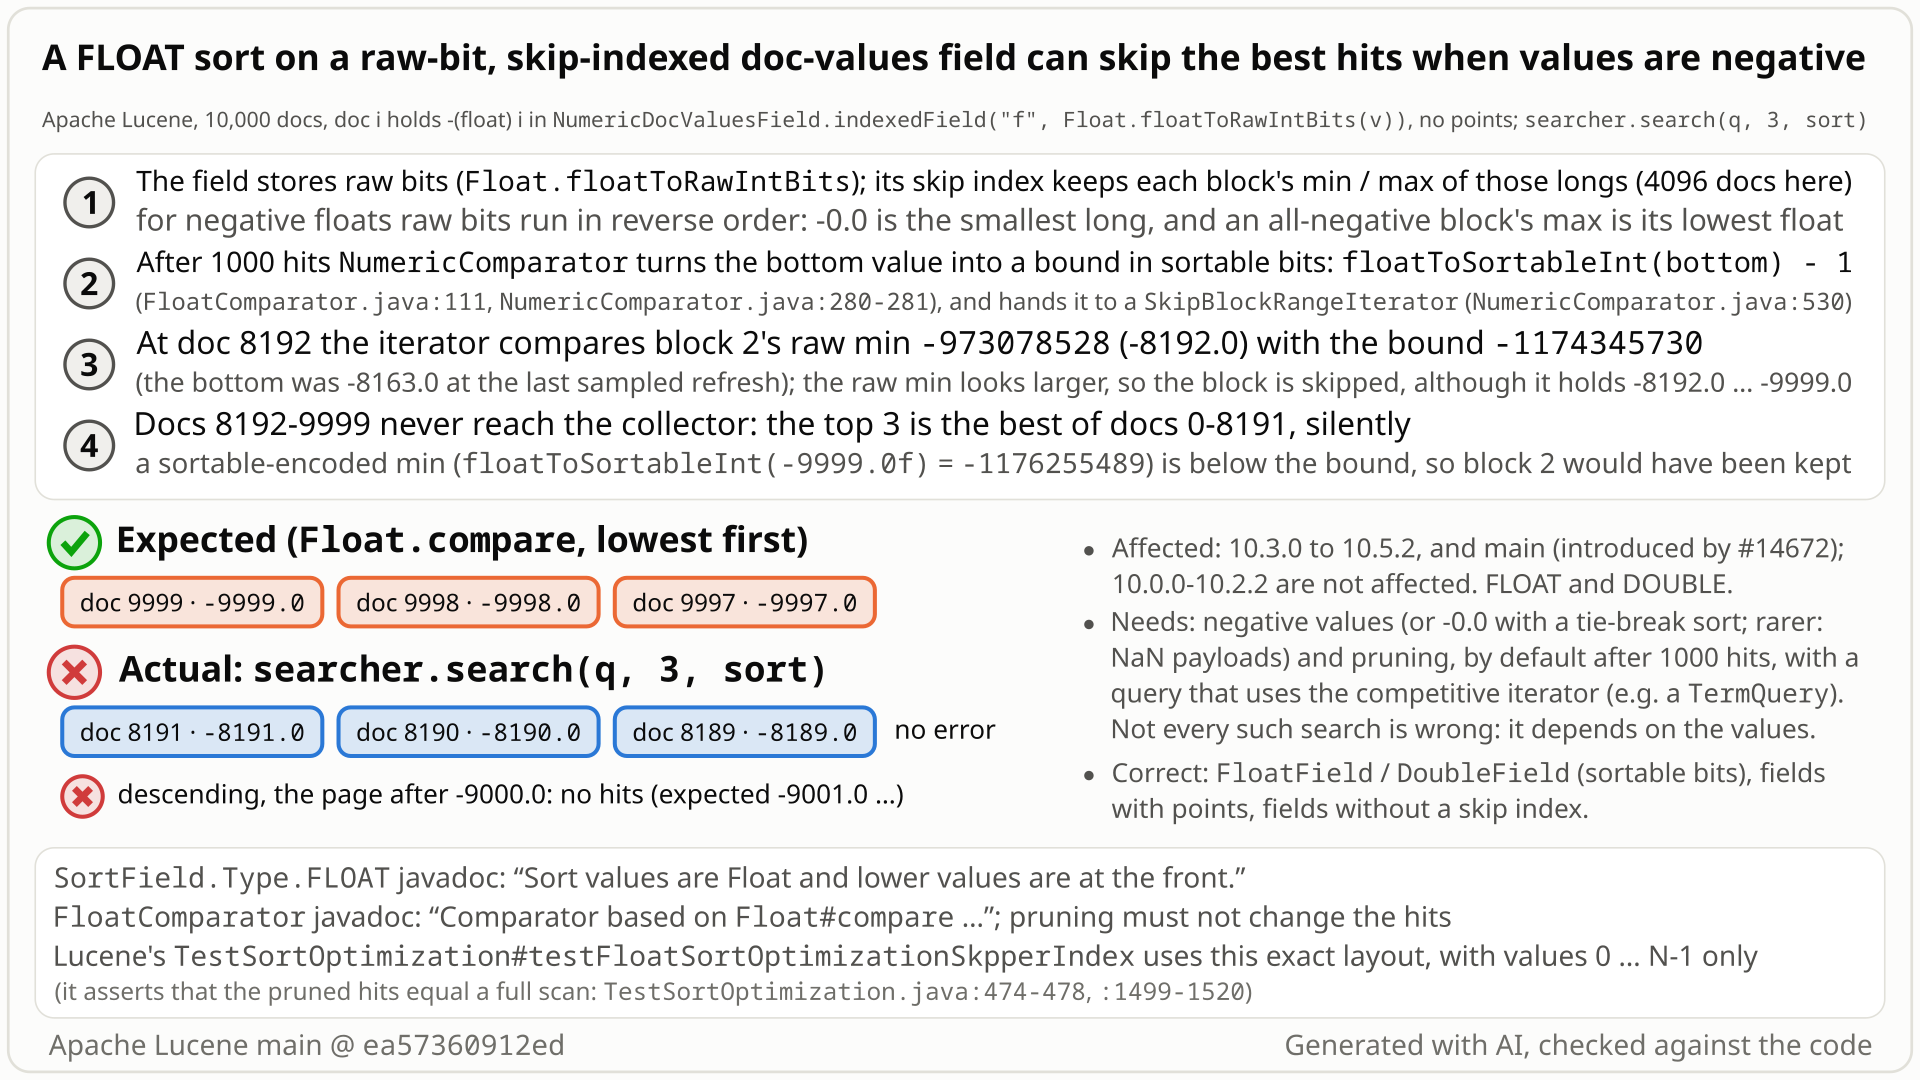
- Index 10,000 docs; doc i holds the float -i as raw bits in a NUMERIC doc-values field with a skip index and no points,
NumericDocValuesField.indexedField("f", Float.floatToRawIntBits(v)): the layout of Lucene's own skip-index sort test. Sort aTermQuerythat matches every doc bySortField.Type.FLOAT, ascending, top 3. - You expect -9999, -9998, -9997, which the same values without a skip index return. You get -8191, -8190, -8189, with no error. A descending
searchAfter(-9000)page comes back empty, and doubles fail the same way. - Why: after the first 8,192 docs, Lucene asks the skip index which blocks (4,096 docs each here) could still beat the current 3rd-best value. That bar is in sortable bits (
floatToSortableInt), but each block's min and max are the stored raw bits. The two agree for positive numbers; for negative numbers the raw bits grow as the number gets more negative. - So the last block (docs 8,192-9,999, values -8,192 to -9,999) has a raw min of -973,078,528, above the bar of -1,174,345,730 (the sortable bits of -8,163, minus 1). It looks non-competitive and is skipped, although it holds the three answers.
- Only this hand-built layout is hit;
FloatField/DoubleField(sortable bits), fields with points and fields without a skip index are correct. It needs pruning to kick in (by default after 1,000 hits), and not every search over negative values goes wrong: that depends on the values in each block and on the bound.
Applications that store floats or doubles as raw bits (FloatDocValuesField's encoding) in a single-valued NUMERIC field with a skip index and no points, and sort with SortField.Type.FLOAT/DOUBLE. A negative value (or -0.0 with a tie-break) plus pruning can give wrong pages, silently; whether it does depends on the values. FloatField/DoubleField are not affected. 10.3.0-10.6.0 (10.6.0 by reading) and main.
Mechanism, terms and numbers972 words
Since 10.3.0 (#14672), a numeric sort on a field that has a doc-values skip index and no points prunes with the skip index: once more hits than the hits threshold (default 1,000) have been counted, NumericComparator turns the current bottom (and the searchAfter top) into a bound and skips each skip-index block (nominally 4,096 docs at level 0) whose min/max cannot beat it. For SortField.Type.FLOAT / DOUBLE, FloatComparator / DoubleComparator give that bound in sortable bits (NumericUtils.floatToSortableInt / doubleToSortableLong), but on a NUMERIC field the skip index records the min/max of the stored longs, which are raw bits (Float.floatToRawIntBits): the only NUMERIC encoding these comparators decode, the encoding FloatDocValuesField writes, and the layout of Lucene's own skip-index float sort test. The two encodings agree for non-negative numbers (+0.0 to +Infinity) and the canonical NaN, run in opposite directions for values whose sign bit is set, and also differ for NaNs with a non-canonical payload, because the bounds canonicalize NaN. So once a segment holds negative values (or -0.0 with a tie-break sort), blocks that hold the best hits can be skipped; whether a search goes wrong depends on the magnitudes of the block's values and of the bound. In a 10,000-doc index where doc i holds -i, the ascending top 3 is -8191, -8190, -8189 instead of -9999, -9998, -9997, a descending searchAfter(-9000) page is empty, and there is no error. Lucene's FloatField / DoubleField (SORTED_NUMERIC, sortable bits), fields with points and fields without a skip index are not affected. Every release from 10.3.0 to 10.6.0 (10.6.0 by reading) and main is affected; 10.0.0 to 10.2.2 are not. No upstream report was found.
- Raw bits:
Float.floatToRawIntBits/Double.doubleToRawLongBits, whatFloatDocValuesField/DoubleDocValuesFieldstore in a NUMERIC doc-values field, and whatFloatComparator/DoubleComparatordecode (Float.intBitsToFloat). - Sortable bits:
NumericUtils.floatToSortableInt/doubleToSortableLong, the encoding ofFloatPoint,FloatFieldand the comparators' pruning bounds. It first turns any NaN into the canonical NaN (Float.floatToIntBits), then keeps the bits when the sign bit is clear and flips all other bits when it is set, so signed-integer order equals numeric order. - Skip index: per block of docs (nominally 4,096 at level 0, plus coarser levels), the min and max of the stored longs (
NumericDocValuesField.indexedField, orFieldType.setDocValuesSkipIndexType(RANGE)).
| value | raw bits | sortable bits |
|---|---|---|
| 1.0 | 1,065,353,216 | 1,065,353,216 |
| 0.0 | 0 | 0 |
| -0.0 | -2,147,483,648 (smallest int) | -1 |
| -1.0 | -1,082,130,432 | -1,065,353,217 |
| -2.0 | -1,073,741,824 (larger than -1.0's) | -1,073,741,825 (smaller) |
| -8,192.0 | -973,078,528 | -1,174,405,121 |
| -9,999.0 | -971,228,160 | -1,176,255,489 |
NumericComparator.buildCompetitiveDISIBuilderuses points if the field has them, otherwise the doc-values skipper (NumericComparator.java:117-131), whatever the sort type or doc-values type.- Once more hits than the threshold (default 1,000) have been counted (until then
updateCompetitiveIteratorreturns early,:242-244, also with asearchAftertop, which only adds a second bound),encodeBottom/encodeTop(:277-314) take the bounds frombottomAsComparableLong()/topAsComparableLong(), which for floats areNumericUtils.floatToSortableInt(bottom)(FloatComparator.java:110-117; doubles the same,DoubleComparator.java:111,:116). new SkipBlockRangeIterator(skipper, minValueAsLong, maxValueAsLong)(NumericComparator.java:530) hands those sortable bounds toDocValuesSkipper.advance(min, max), which skips a block whenminValue(0) > maxValue || maxValue(0) < minValue(DocValuesSkipper.java:125): raw block bounds against sortable bounds.- The same comparator reads each document's value as raw bits (
FloatComparator.java:81). For segments without sign-bit values the encodings coincide, which is why Lucene's test with values 0..N-1 passes. With negative values, blocks holding the best hits can look non-competitive. A sign-bit value is needed but not enough: for floats, an ascending sort skips an all-negative block when the bit patterns of the block's smallest magnitude and of the bound's magnitude add up to more than 2^31 - 2 (roughly, both 2 or more); a descending sort skips one only when the magnitudes are small or the block holds only -0.0. On the repro's layout one -5 among positives, values in [-1, -0.0001] and the first descending page over -i were all correct; -i/1000 ascending was wrong (fact-check runs). -0.0 is the smallest raw int but sortable -1, so with a tie-break sort the -0.0 documents that should win the tie are skipped.
Repro, one segment of 10,000 docs, doc i = -i (doc 0 holds -0.0), TermQuery matching all, query cache off. Blocks: docs 0-4095 raw min -2,147,483,648 (-0.0), max -981,471,232 (-4095); docs 4096-8191 raw min -981,467,136 (-4096), max -973,080,576 (-8191); docs 8192-9999 raw min -973,078,528 (-8192), max -971,228,160 (-9999). The TermQuery runs on DenseConjunctionBulkScorer, which collects docs 0-8191 as one range and then asks the competitive iterator for the next doc. By then the bound is max = -1,174,345,730 (sortable bits of -8,163.0, the bottom at the last sampled refresh, minus 1); the last block's raw min -973,078,528 is greater, so advance(8192) returns NO_MORE_DOCS. The same index with doc i = +i also collects exactly 8,192 docs and is right, so the 8,192 is not part of the bug: it ends the term's first dense postings run (one level-1 postings block, 32 x 256 docs), which the bulk scorer collects as one range. On 10.3.x that block is 32 x 128 = 4,096 docs and the top 3 is -4095, -4094, -4093.
A NaN whose sign bit is set (Float.intBitsToFloat(0xFFC00000)) is also missed: Float.compare sorts it above every number, but its raw bits are negative. With docs 0-8191 holding 1000..9191, docs 8192-9998 holding 0..1806 and doc 9999 holding that NaN, the descending top 3 is docs 8191, 8190, 8189 instead of docs 9999, 8191, 8190. Two layouts whose skip index has no negative minimum fail too: every doc holding the positive-sign NaN 0x7f800001 (or the double 0x7ff0000000000001), descending with a reverse doc-id tie-break (the bound is the canonical NaN 0x7fc00000), and floats stored zero-extended (Integer.toUnsignedLong(Float.floatToRawIntBits(v))), ascending; the canonical NaN passes.
Exposure and likelihood376 words
- Who is hit. A FLOAT/DOUBLE sort on a single-valued NUMERIC doc-values field that holds raw bits, with a skip index (
NumericDocValuesField.indexedField(name, Float.floatToRawIntBits(v)), the double equivalent, orFieldType.setDocValuesSkipIndexType(RANGE)) and no points. It is opt-in, but it is the layout of Lucene's ownTestSortOptimization#testFloatSortOptimizationSkpperIndex, andFieldType#setDocValuesSkipIndexTypesays a skip index is "typically useful on fields that are part of the index sort". - Trigger. A value whose raw and sortable bits differ in the segment (a negative value; -0.0 together with a tie-break sort; a NaN with the sign bit set; rarer, a NaN with another payload and a tie-break sort), and pruning that engages: more matches than the hits threshold (default 1,000; a
searchAfteralone does not start it), with a query whose scorer consults the competitive iterator. Even then not every search is wrong: it depends on the magnitudes of the values in each block and of the bound (see What goes wrong). Reproduced with aTermQuery(also with the default query cache), MUST + FILTER conjunctions, 3 and 5 segments, an index sorted on the field, and random unclustered values (ascending top 5 wrong in 20 of 20 mixed-sign random indices). A dense single-segmentMatchAllDocsQueryand a pure SHOULD disjunction did not prune in the probes and stayed correct. Descending withoutsearchAfterwas correct on random data. - What they see. Deterministic, silent wrong or missing top-N hits: ascending pages miss the smallest values, descending
searchAfterpages can be empty, -0.0 ties come out in the wrong order. Every returned hit still matches the query and carries its own value. Default codec,IndexWriterConfig, searcher and hits threshold;-eaand-dathe same. - Not hit.
FloatField/DoubleFieldand other SORTED_NUMERIC sortable fields withSortedNumericSortField(0 wrong results in 119,460 randomized checks), fields with points, fields without a skip index. Elasticsearch, OpenSearch and Solr (default branches read on 2026-10-26, not run) do not build the affected layout; custom applications are unknown. - How likely. Registry likelihood "plausible": the layout is hand-built, but on it ordinary negative data and an ordinary sorted query over more than 1,000 hits fail deterministically at about 10,000 docs (the repro, the independent reproduction's random data, the intended-behaviour check's natural data); some value ranges stay correct by luck. Priority medium.
The test shows that an ascending SortField.Type.FLOAT sort on raw-float-bit NUMERIC doc values with a skip index and no points (NumericDocValuesField.indexedField) misses the smallest negative values once doc-values-skipper pruning engages (10,000 docs valued 0..-9999, TermQuery).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestFloatSortSkipIndexNegative extends LuceneTestCase {

  public void testAscendingFloatSortWithNegativeValues() throws IOException {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      for (int i = 0; i < 10_000; i++) {
        Document doc = new Document();
        doc.add(new StringField("all", "x", Field.Store.NO));
        doc.add(NumericDocValuesField.indexedField("f", Float.floatToRawIntBits(-i)));
        w.addDocument(doc);
      }
      w.forceMerge(1);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        searcher.setQueryCache(null);
        Sort sort = new Sort(new SortField("f", SortField.Type.FLOAT));
        List<Object> top3 = new ArrayList<>();
        for (ScoreDoc hit : searcher.search(new TermQuery(new Term("all", "x")), 3, sort).scoreDocs) {
          top3.add(((FieldDoc) hit).fields[0]);
        }
        // expected the three smallest values [-9999, -9998, -9997]; actual [-8191, -8190, -8189]
        assertEquals(List.of(-9999f, -9998f, -9997f), top3);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-144/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestFloatSortSkipIndexNegative
- Expected vs actual
- Expected the top 3
[-9999.0, -9998.0, -9997.0]; actual[-8191.0, -8190.0, -8189.0], with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[-9999.0, -9998.0, -9997.0]> but was:<[-8191.0, -8190.0, -8189.0]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.TestFloatSortSkipIndexNegative.testAscendingFloatSortWithNegativeValues(TestFloatSortSkipIndexNegative.java:57)SortField.Type.FLOAT: "lower values are at the front";FloatComparatoris "based onFloat#compare". Skipping must not change the hits.- Lucene's own
testFloatSortOptimizationSkpperIndexuses this exact layout and asserts pruned hits equal a full scan, with values 0..N-1 only. - The comparator decodes the values as raw bits, then reads their skip index as sortable bits.
The full argument264 words
- Contract.
SortField.Type.FLOAT: "Sort using term values as encoded Floats. Sort values are Float and lower values are at the front. Fields must either be not indexed, or indexed withFloatPoint." (SortField.java:82-86;DOUBLE:94-98). The field has no points.FloatComparator: "Comparator based onFloat#compare... This comparator provides a skipping functionality – an iterator that can skip over non-competitive documents." (FloatComparator.java:26-29). - Upstream test. #14672 added
testFloatSortOptimizationSkpperIndexwithFloatDocValuesField.indexedField(field, Float.floatToRawIntBits(value))(TestSortOptimization.java:474-478); its helper checks that a searcher that "hides index structures to force a linear scan" returns "the same hits" (:1499-1520). It indexes only1f * i,i >= 0(:484-487), where raw and sortable bits are equal. There is no double variant. - Self-contradiction.
FloatComparatordecodes the NUMERIC values withFloat.intBitsToFloat(:81) but compares the skip index built from those values with sortable bounds (:110-117,NumericComparator.java:530). - CHANGES 10.3.0: "Numeric sort queries can take advantage of DocValuesSkipper to dynamic prune." (
CHANGES.txt:1582), with no type or sign restriction; 10.2.2 returns the right hits. - Precedent. In #16573 / #16629 (fixed in 10.5.2) maintainers treated the same raw-vs-sortable mismatch in range-query code as a bug: on #16573 HoustonPutman wrote that "
NUMERICexpects floats and doubles to not be in sorted order", and on #16629 romseygeek, about points min/max not matching the actual double values, wrote "I think we need to check that that [sic] we aren't making this assumption in other places as well", namingIndexSortSortedNumericDocValuesRangeQuery. Earlier competitive-iterator false negatives were fixed as bugs (LUCENE-10106, LUCENE-10126).
The devil's-advocate check220 words
The intended-behaviour checker built the strongest case: the FLOAT javadoc says "not indexed, or indexed with FloatPoint", and a skip index is "indexed"; Lucene has no first-class float field with a NUMERIC skip index, so the user owns the encoding; TestSegmentReordering stores sortable bits in a NUMERIC skip-indexed field and sorts it with Type.FLOAT, which could be read as the convention; and SortField.setOptimizeSortWithIndexedData(false) turns pruning off.
Why it fails: the same PR's own test uses raw bits plus a skip index and asserts pruned hits equal a full scan, and, although "indexed" read literally is ambiguous (a maintainer may raise it), the class javadoc's "indexed with both doc values and points" (SortField.java:42-44) shows the FloatPoint sentence is the points precondition. Raw bits are the only NUMERIC encoding FloatComparator decodes correctly: sortable bits in a NUMERIC field give wrong sort values for negatives even without a skip index (executed control), so TestSegmentReordering only works because its values are non-negative. The off switch is deprecated, "should only be used for compatibility with 8.x indices that got created with inconsistent data across fields" (SortField.java:608-629). Nothing in javadoc, CHANGES, MIGRATE, tests or the PR reviews limits skipper pruning to non-negative values. Verdict: not intended, a defect. The cross-model reviewer with the same lens rated the intended argument weak.
Recommended Option A+: option A plus a maximum check, so only segments whose raw values all lie from +0.0 to +Infinity keep skip-index pruning
Skip the skip-index pruning for a FLOAT/DOUBLE sort on a NUMERIC field unless the segment's raw values all lie between +0.0 and +Infinity, where raw and sortable bits are equal (+19 lines in NumericComparator.buildCompetitiveDISIBuilder). The repro, 4 edge-encoding tests and 163 nearby tests pass. Cost: no skip-index pruning on such segments, as before 10.3.0.
// raw bits from +0.0 to +Infinity equal their sortable bits; also give up when the segment
// holds a NaN (its payload may differ from the canonical NaN of the bounds) or float bits
// stored zero-extended
long positiveInfinityBits =
    NumericComparator.this instanceof FloatComparator
        ? Float.floatToRawIntBits(Float.POSITIVE_INFINITY)
        : Double.doubleToRawLongBits(Double.POSITIVE_INFINITY);
if (rawIeeeBits && (skipper.minValue() < 0 || skipper.maxValue() > positiveInfinityBits)) {
  return null;
}
All options and trade-offs4 options · 1,465 words
Options A and B were implemented and validated with gradle in a scratch worktree at ea57360912ed (removed after the runs), together with a randomized differential test written for the check (random FLOAT and DOUBLE indices of 2,000-20,000 docs over 1-4 segments, with negative, -0.0, infinite and NaN values, random direction, tie-break, page size and searchAfter; stock main fails it 3 of 3 on 5 seeds; its DOUBLE values come from floats, and it has no positive-sign non-canonical NaN and no zero-extended values). The fact checks then found that both key on a negative skipper minimum, which misses two rarer encodings; an edge-encoding test (stock fails 3 of 4) and option A+, which closes that gap, were added. Option C was not written. Until a fix lands, users can turn pruning off with the deprecated SortField.setOptimizeSortWithIndexedData(false) or an exact total-hit count, or change the field: FloatField / DoubleField (points plus sortable SORTED_NUMERIC doc values, no skip index) sorted with SortedNumericSortField prune through points and are correct; to keep a doc-values skip index without points, store sortable bits with SortedNumericDocValuesField.indexedField(name, NumericUtils.floatToSortableInt(v)) and sort with SortedNumericSortField (executed: correct and pruned). Open PR #16163 touches the same builder but keeps the comparison (read, not run); today pruning waits for the hits threshold even with searchAfter, and #16163 would change that.
Option A+: option A plus a maximum check, so only segments whose raw values all lie from +0.0 to +Infinity keep skip-index pruning (validated by the checks) (recommended)
Raw and sortable bits are equal exactly for the raw range from +0.0 to +Infinity (plus the canonical NaN). Option A+ keeps option A and also gives up when the segment's raw maximum is above +Infinity's bits, which catches every NaN payload and zero-extended float bits. The change is +19 lines in buildCompetitiveDISIBuilder (option A's lines plus the ones below).
// raw bits from +0.0 to +Infinity equal their sortable bits; also give up when the segment
// holds a NaN (its payload may differ from the canonical NaN of the bounds) or float bits
// stored zero-extended
long positiveInfinityBits =
    NumericComparator.this instanceof FloatComparator
        ? Float.floatToRawIntBits(Float.POSITIVE_INFINITY)
        : Double.doubleToRawLongBits(Double.POSITIVE_INFINITY);
if (rawIeeeBits && (skipper.minValue() < 0 || skipper.maxValue() > positiveInfinityBits)) {
  return null;
}
Trade-offs
- Everything option A gives up, and also skip-index pruning on segments that hold any NaN, including the canonical NaN, where stock pruning was right.
- The same style points as option A. No benchmark was run.
What the checks validated
- The repro runner: the edge-encoding test 4 of 4 (
-ea,-da; stock, A and B fail 3 of 4), the finder's repro 6 of 6 (-ea,-da), the differential 3 of 3 on 5 seeds, the independent reproduction's test (seed1A2B3C4D) 6 of 6, the intended-behaviour check's (seed7E57AB1E) 5 of 5. - Gradle in a fresh extraction of
ea57360912ed: the 163-test set above plus the edge test, 167 tests, 0 failures (seedDEADBEEF, assertions on; seedCAFEBABE, assertions off);tidyonly joined theifonto one line. These runs used an earlier wording of the code comment; the final file was re-run with the repro runner. - Not run: the whole
searchpackage, other modules.
Option A: no skip-index pruning on segments that hold sign-bit values (the hunt's sketch, minimal) (validated by the checks)
The hunt's sketch. For the sign-extended raw bits FloatDocValuesField / DoubleDocValuesField write, a segment whose skipper minimum (DocValuesSkipper.minValue(), segment-wide) is non-negative has no value with the sign bit set, and there raw and sortable bits are identical, except NaNs with a non-canonical payload. It keys on the doc-values type, because SORTED_NUMERIC float/double values are sortable-encoded and already correct; a negative-sign NaN also makes the minimum negative. Gap (executed): a positive-sign non-canonical NaN with a tie-break sort, and floats stored zero-extended, keep a non-negative minimum, so option A still fails 3 of the 4 edge-encoding tests; option A+ closes it. The code below is the diff's text.
DocValuesSkipper skipper = reader.getDocValuesSkipper(field);
if (skipper != null) {
  // FLOAT/DOUBLE NUMERIC doc values hold raw IEEE bits (FloatDocValuesField /
  // DoubleDocValuesField), whose signed-long order differs from the sortable encoding used
  // for the bottom/top bounds as soon as a value has its sign bit set.
  FieldInfo fi = reader.getFieldInfos().fieldInfo(field);
  boolean rawIeeeBits =
      (NumericComparator.this instanceof FloatComparator
              || NumericComparator.this instanceof DoubleComparator)
          && fi != null
          && fi.getDocValuesType() == org.apache.lucene.index.DocValuesType.NUMERIC;
  if (rawIeeeBits && skipper.minValue() < 0) {
    return null;
  }
  return new DVSkipperCompetitiveDISIBuilder(skipper, this);
}
Trade-offs
- Gives up skip-index pruning on every segment that holds a negative value, -0.0 or a negative-sign NaN, the same as 10.2.x, which never pruned with the skipper; non-negative segments keep it. On a mixed-sign segment (-i for the first 8,192 docs, +i after) it visits all 10,000 docs where option B visits 8,192, both correct.
- The
instanceoftest and the fully qualifiedDocValuesTypeare style points a maintainer may want changed (a hook on the comparator, an import). No benchmark was run.
What the checks validated
- Gradle, stock: the repro fails 6 of 6 with assertions on and off.
- Gradle with the fix: the repro, the differential test and 12 upstream classes (
TestSortOptimization,TestSort,TestSearchAfter,TestTopFieldCollector,TestTopFieldCollectorEarlyTermination,TestDenseConjunctionBulkScorer,TestBooleanQuery,TestSortedNumericSortField,TestSortRandom,TestSkipBlockRangeIterator,TestElevationComparator,comparators.TestNumericComparator): 163 tests, 0 failures (seedDEADBEEF, assertions on; seedCAFEBABE, assertions off). - Gradle with the fix: all of
org.apache.lucene.search.*in:lucene:corewith the repro, 2,336 tests, 0 failures, 49 skipped;tidyleaves the fix unchanged. - The repro runner: the finder's, the independent reproduction's, the cross-model review's and the reviewer's tests pass; the bounded-exhaustive harness and a randomized differential (2,113,290 checks) find 0 mismatches; the differential test passes on 5 seeds; the security probe's hit lists no longer depend on hidden documents.
- Not run: the rest of
:lucene:core, other modules.
Option B: map the sortable bounds to a raw-bit range on segments that hold sign-bit values (keeps more pruning) (validated by the checks)
+63/-4 in NumericComparator.java. buildCompetitiveDISIBuilder tells the skipper builder whether the field holds raw float (32) or double (64) bits (a FLOAT/DOUBLE sort on a NUMERIC field). When it does and skipper.minValue() < 0, doUpdateCompetitiveIterator replaces the sortable range [lo, hi] by the smallest raw-bit range that holds the raw bits of every value in it, plus every NaN bit pattern when the range reaches above +Infinity.
if (lo < 0) { // sign bit set: [lo, min(hi, -1)] in reverse order
  min = Math.min(hi, -1) ^ highest; // highest = Integer.MAX_VALUE or Long.MAX_VALUE
  max = lo ^ highest;
}
if (hi >= 0) { // sign bit clear: the same bits
  min = Math.min(min, Math.max(lo, 0));
  max = Math.max(max, hi);
}
if (hi > positiveInfinity) { // NaNs may compete: every NaN bit pattern, either sign
  min = Math.min(min, (positiveInfinity + 1) | lowest);
  max = highest;
}
Trade-offs
- Can keep pruning for ascending sorts on segments with negative values: the mixed-sign probe visits 8,192 docs instead of 10,000 (the pruned block is the positive one); the all-negative probe visits all 10,000, because the answers are in the last block; pruning of negative blocks follows from the mapping but was not measured. Non-negative segments are unchanged.
- Still gives up pruning when the competitive range covers both signs, for example a descending sort whose bottom is negative, because one raw range then spans nearly everything; an exact version needs a two-range block test.
- More code than option A, and it must stay in step with
NumericUtils. A first variant that mapped on every raw-bit segment failed upstreamTestNumericComparator.testEmptyCompetitiveIteratorOptimization(the NaN clause stopped a descending sort on non-negative values from pruning); limiting it toskipper.minValue() < 0fixed that. - The same gap as option A: it activates only when
skipper.minValue() < 0, so it still fails 3 of the 4 edge-encoding tests; closing it needs option A+'s maximum check (not written for B).
What the checks validated
- Gradle with the fix: the same 163 tests, 0 failures (seed
DEADBEEF, assertions on; seedCAFEBABE, assertions off); all oforg.apache.lucene.search.*with the repro and the differential, 2,339 tests, 0 failures, 49 skipped;tidyclean. - The repro runner: the differential passes on 5 seeds and with
--da; the finder's repro (-ea,-da), the independent reproduction's test (with its pruning-engaged control) and the intended-behaviour check's test pass; the security probe shows 0 wrong searches and hit lists that do not depend on hidden documents. - Not run: the rest of
:lucene:core, other modules, a benchmark.
Teach SkipBlockRangeIterator (or a sibling) to accept the union of the two raw-bit intervals a sortable range maps to, so no pruning is lost.
Trade-offs
Most code; touches a public class; untested.
An AI tool building a bounded-exhaustive check of sorted search (the real TopFieldCollector against a brute-force sort on every tiny index) noticed in the code that the skip-index bound and the block min/max use different encodings. The check then found 77,738 wrong results in 2,597,184 for FLOAT, and a default-codec JUnit confirmed it.
The method in full191 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier), a hunt unit (sorting / TopFieldCollector), 2026-10-25, main ea57360912ed.
- The finder wrote a harness that runs the real
TopFieldCollectoron the stock jar against an independent brute-force sort for every small index layout (tiny codec with a skip interval of 2, at most 5 docs, several field encodings and sort types). - While building it, the finder noticed by code reading that the skipper bounds are sortable-encoded while the skipper's block min/max are raw bits. The harness then witnessed it: for NUMERIC + skip index + FLOAT with the values (-3, -2), 77,738 of 2,597,184 checks were wrong; for DOUBLE with (-0.0, 0.0), 30,090 of 4,328,640. With the fix sketch both gave 0.
- A default-codec JUnit with 10,000 docs on the stock main jar confirmed it (6 of 6 failing). A randomized differential at scale (up to 30,000 docs, 1-4 segments, deletions, index sorts) found 268 wrong results in 11,489 checks on the affected family and 0 in 119,460 on the sortable SORTED_NUMERIC family.
- So it is a code-reading find confirmed by the exhaustive check, not a blind discovery by the tool.
No report found (2026-10-26): 182 logged queries over GitHub issues, PRs and review comments, git history, all 413 open PRs, four mailing lists, the JIRA archive, three downstream trackers and the web. Closest, a different bug: #16573 / #16629, the same raw-bits hazard in range queries, fixed in 10.5.2.
Searches4 searches
No report of this bug was found, and upstream main, branch_10x, branch_10_6 and branch_10_5 still have the code. Related items, none of them this bug: #16573 (hossman) / #16629 (HoustonPutman, fixed in 10.5.2): range queries over float/double points plus NumericDocValuesField; the maintainers stated the hazard and asked to check "other places", naming a range query, not sorting. #16698 / #16699 (open): range-query follow-up. #749 (LUCENE-10466, 2022): FloatDocValuesField raw bits vs floatToSortableInt in IndexSortSortedNumericDocValuesRangeQuery. #14666 / #14672: introduced the code; its review did not discuss float encoding. Open PR #16163 builds the skipper iterator immediately for searchAfter and keeps the comparison (diff read, not run). Framing suggestion: one of the "other places" #16629 asked about.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and review comments (apache/lucene) | 2026-10-26 | REST and GraphQL search: skipper float/double/negative/sort, NumericComparator, FloatComparator, DoubleComparator, SkipBlockRangeIterator, indexedField, "raw bits", floatToRawIntBits sort, "sort optimization" float, "competitive iterator" skipper, search_after skipper, "negative zero" | no report; #16573 / #16629 and #749 are the closest (range queries) |
| Open PRs and branches | 2026-10-26 | changed files of all 413 open PRs: 8 touch NumericComparator, SortField, TestSortOptimization or TopFieldCollector (#16163, #16857, #16847, #14395, #14775, #15752, #16276, #13525); the patches of the first 7 grepped by the prior-report search, #13525's (multi-vector work in progress; in TestSortOptimization only an import and a FieldInfo constructor argument) read in the resolution step; main, branch_10x, branch_10_6, branch_10_5 | nothing changes the bounds encoding; #16163 touches the same builder |
| Mailing lists, JIRA archive, downstream trackers, web | 2026-10-26 | dev@, java-user@, issues@, commits@; JIRA (frozen 2022); Elasticsearch, OpenSearch and Solr trackers; web search | nothing about this bug |
| Earlier passes | 2026-10-26 | the finder's 45-query pass; the intended-behaviour check's GitHub searches (16 query strings) and 26-query pass | no report |
Introduced by #14672 "Dynamic pruning with DocValueSkipper" (merged 2025-06-06), first released in 10.3.0. Every release from 10.3.0 to 10.5.2 and main fails the repro; 10.0.0 to 10.2.2 pass; 10.3.0 with only NumericComparator reverted passes.
Versions tested6 rows
#14672 (gf2121, closes #14666) was committed on 2025-06-06 as 9a7bcc9b590 on main and cherry-picked as e2fdc61ad32 to branch_10x; CHANGES 10.3.0: "Numeric sort queries can take advantage of DocValuesSkipper to dynamic prune." It added the skipper pruning path for every numeric sort type and reused the comparators' sortable bounds (from #13246, correct for points). Later changes kept the mismatch: #15397 / #15410, #15632 (SkipBlockRangeIterator), #15663, #15757.
Every release row ran the hunt's repro on the release's Maven Central jars (SHA-1 checked), seed DEADBEEF, assertions on, on OpenJDK 25.0.3, Linux aarch64 (only main was also run with assertions off). The main commit pair was not built from source; branch_10x and branch_10_6 were read, not run. The change of the first dense postings run from 4,096 docs (10.3.x) to 8,192 (10.4.0 and later) was not bisected.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed (unreleased 11.0) | affected | 6 of 6 fail, -ea and -da; ascending top 3 -8191, -8190, -8189 |
| 10.4.0 to 10.5.2 | affected | 6 of 6 fail; same wrong hits as main |
| 10.3.0 to 10.3.2 | affected | 6 of 6 fail; first dense postings run 4,096 docs, ascending top 3 -4095, -4094, -4093 |
| 10.0.0 to 10.2.2 | not affected | 6 of 6 pass: skip index, but no skipper-based sort pruning |
| 9.12.3 | n/a | does not compile: no skip index API (added in 10.0.0 by #13449) |
10.3.0 with only NumericComparator.java from d176a42b659 (before #14672: the parent of the branch_10x cherry-pick e2fdc61ad32) | revert | 6 of 6 pass |
Tests written independently by the finder, AI verifiers and cross-model reviews (OpenAI GPT-5.6) all fail on main and pass with the fix; an adjudication re-ran two of them on new seeds. No intended-behaviour argument survived. This page's own gradle runs reproduced it and validated two fixes.
Checks and verdicts524 words
Every check wrote or re-ran its own test on the stock main jars; all voted real, with no dissent.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review (refute lens) | real, high | An independent reviewer from another model family (OpenAI GPT-5.6). Its own test fails 2 of 4 on main (-ea, -da, 3 seeds) and on 10.5.2, passes on 10.2.2 and with the fix. Its plain -0.0 probe passed, so the -0.0 claim was narrowed to a tie-break sort. |
| Independent reproducer | real | Own test (13,788 docs, sort oracle plus a no-skip control) fails 5 of 6 on main, 10.5.2 and 10.3.0; only its positive-value control passes. Reach probes: default query cache, MUST + FILTER, 3 segments, random data. |
| Cross-model review (intended lens) | real, high; intended argument weak | Own 2-test class fails 2 of 2 on main (-ea, -da), 10.3.0 and 10.5.2 with no-skip and point-index controls passing; upstream TestSortOptimization passes 31 of 31 with the fix. |
| Intended-behaviour devil's advocate | real | No intended, documented or misuse argument survives. Own natural-data test (5 segments, default query cache, an index sorted on the field) fails 5 of 5; 4 context tests pass. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with seed 1A2B3C4D (5 of 6 fail, -ea and -da; 0 with the fix) and the intended-behaviour check's with seed 7E57AB1E (5 of 5 fail). |
| History, prior-report and security follow-ups | introduced by #14672 (10.3.0); new; security none | Release sweep over 14 targets plus a one-file revert; 182 prior-art queries; a fails-closed security probe over 45,072 returned hits. Security stays none: one residual signal (which visible hits a page shows can depend on hidden documents' values, 299 of 720 paired searches) is out of scope under SECURITY.md; the cross-model fact check dissented (see the brief, section 12). |
| This page's own runs | reproduced; two fixes validated | Gradle: the repro fails 6 of 6 stock (assertions on and off); options A and B pass 163 nearby tests and the whole search package. A differential test fails on stock on 5 seeds and passes with both options. |
| Fact checks of this page and their resolution | 13 errors raised, 12 fixed, 1 kept with reasons | An independent fact check re-ran the repro, the fixes and the release sweep and found 5 wording errors; a cross-model fact check (OpenAI GPT-5.6) found 8 (2 high); a diagram check passed with 6 minor items. All wording errors were fixed and the visuals re-rendered. The reviewer's reasoned claim that the fixes miss two rarer encodings was executed and confirmed, and option A+ was added. |
| Correction to the registry row | registry wording out of date | The registry card below still carries wording this page corrects: its title, impact_note, priority_note and likelihood_note read as if any negative value plus pruning (or a searchAfter alone) gives wrong pages; its affected_versions calls the 4,096 docs on 10.3.x a skipper block (it is the first dense postings run); its upstream field counts 7 open PRs touching the files (there are 8) and 17 intended-behaviour check searches (16 query strings). The text of this page is the corrected version. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 626 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,404 words
- Registry title
- A FLOAT or DOUBLE sort on a NUMERIC doc-values field with a skip index and no points silently returns wrong or missing top hits when values have the sign bit set (negative values, or -0.0 with a tie-break sort): skipper pruning compares sortable-encoded bounds with the raw IEEE-bit block min/max
- Area
- search / sorting (NumericComparator doc-values-skipper pruning for FLOAT/DOUBLE)
- Priority
- Medium, rank 81: Once any value is negative, FLOAT/DOUBLE sorts deterministically and silently return wrong or empty top-N pages, but only on a hand-built raw-bit NUMERIC field with a skip index and no points (the layout of Lucene's own test, no known downstream user), and only since 10.3.
- Impact class
- silent wrong results
- Impact note
- Applications on 10.3.0-10.6.0 (10.6.0 by reading) or main that store floats or doubles in a single-valued NUMERIC doc-values field in FloatDocValuesField/DoubleDocValuesField's raw-bit encoding with a doc-values skip index and no points (NumericDocValuesField.indexedField or FieldType.setDocValuesSkipIndexType; the layout of Lucene's own TestSortOptimization#testFloatSortOptimizationSkpperIndex) and sort on it with SortField.Type.FLOAT/DOUBLE: once any value has the sign bit set and pruning engages (more matches than the default 1000-hit threshold, or searchAfter, with a query whose scorer consults the competitive iterator: TermQuery, conjunctions, multi-segment or index-sorted indices), top-N pages silently miss the smallest values or come back empty, with the default codec, IndexWriterConfig and searcher, -ea or -da, at about 10,000 docs; Lucene's FloatField/DoubleField (SORTED_NUMERIC, sortable bits), fields with points and fields without a skip index are not affected, and none of the major downstreams checked (Elasticsearch, OpenSearch, Solr) builds the affected layout.
- Summary
- You store float or double values as raw IEEE bits in a single-valued NUMERIC doc-values field with a skip index and no points (for example NumericDocValuesField.indexedField("f", Float.floatToRawIntBits(v)), the layout of Lucene's own skip-index sort test) and sort on it with SortField.Type.FLOAT or DOUBLE. You expect the same hits as on the same values without a skip index, lowest value first. Instead, with 10,000 docs holding 0, -1, ..., -9999 and a TermQuery that matches all of them, the ascending top 3 is [-8191, -8190, -8189] instead of [-9999, -9998, -9997] and a descending searchAfter(-9000) returns no hits, because the pruning compares bounds in NumericUtils sortable order with skipper block min/max in raw-bit order, and the two orders disagree for values with the sign bit set.
- Introduced
- 9a7bcc9b590 on main / e2fdc61ad32 on branch_10x (apache/lucene#14672 'Dynamic pruning with DocValueSkipper', by gf2121, closes #14666) [read: git log -S 'getDocValuesSkipper(field)' and -S DVSkipperCompetitiveDISIBuilder on NumericComparator.java each return only 9a7bcc9b590; it added the doc-values-skipper pruning path for every numeric sort type and fed it the comparators' existing sortable bounds (FloatComparator/DoubleComparator bottomAsComparableLong/topAsComparableLong = NumericUtils.floatToSortableInt/doubleToSortableLong, from #13246, 2024-04-10, correct for the points path, where FloatPoint/DoublePoint are sortable-encoded); exec: the finder repro passes on 10.2.2 and fails on 10.3.0, and 10.3.0 with only NumericComparator.java swapped back to its pre-#14672 version (parent d176a42b659, via --shadow-src) passes 6/6; the commit pair was not built from source]; later refactors kept the mismatch: #15397/#15410, #15632 (block-only SkipBlockRangeIterator), #15663, #15757 (2025-06-06 (9a7bcc9b590 on main and e2fdc61ad32 on branch_10x))
- First affected version
- 10.3.0 [exec]
- Affected versions
- 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main through e1faeba08bd [exec; on e1faeba08bd (2026-11-02) the minimal repro fails 1/1 and the finder class 6/6 with -ea and -da; earlier runs: the finder repro fails 6/6 on each with seed DEADBEEF, main also with -da; the independent reproduction, the cross-model review, the intended-behaviour check and the adjudication reproduced on main with their own tests, -ea and -da; the independent reproduction and the cross-model review also on 10.3.0 and 10.5.2, the intended-behaviour check on 10.5.2]; not affected: 10.0.0, 10.1.0, 10.2.0, 10.2.1 and 10.2.2 [exec: 6/6 pass; they have the skip index but no skipper-based sort pruning]; not applicable: 9.x [exec on 9.12.3: compile error, NumericDocValuesField.indexedField does not exist; read: DocValuesSkipper arrived in 10.0.0 with #13449]; 10.6.0 (released 2026-10-29) [exec 2026-11-02: minimal repro fails with -ea]; affected by reading: branch_10_6 and branch_11x (11.0, unreleased; its comparator, SortField and collector files are identical to main) [read 2026-11-02]; branch_10x was decommissioned on 2026-10-29 (#16911); the exact wrong hits differ by version (10.3.x scans only the first 4096-doc skipper block before the bad pruning, 10.4.0 and later the first 8192 docs) [exec]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 182 logged read-only queries over apache/lucene issues, PRs and review comments (REST and GraphQL search), git history of main and the release branches, the changed-file lists of all 413 open PRs (the patches of the 7 that touch NumericComparator.java, SortField.java, TestSortOptimization.java or TopFieldCollector.java grepped), the dev@, java-user@, issues@ and commits@ lists, the JIRA archive, the Elasticsearch, OpenSearch and Solr trackers, and the web; plus the finder's 45-query pass and the intended-behaviour check's 17 GitHub searches and 26-query pass; 40 hits read, none of them this bug); not fixed on upstream main, branch_10x, branch_10_6 or branch_10_5; open PR #16163 (builds the skipper iterator immediately for search_after) keeps the sortable-vs-raw comparison and would not fix it (diff read, not run); related prior items, a different bug (different code and fix): #16573 / #16629 (2026, range queries over float/double points + NumericDocValuesField, fixed in 10.5.2; maintainers state there that NUMERIC floats and doubles are not stored in sorted order, and romseygeek asked to check whether the assumption is made in other places, naming IndexSortSortedNumericDocValuesRangeQuery), #16698 / #16699 (open range-query follow-up), #749 (LUCENE-10466, 2022), #14666 / #14672 (introduced the code; float encoding not discussed in review), LUCENE-10106 / LUCENE-10126 (earlier competitive-iterator false negatives with unrelated causes)
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26): the JUnit repro with gradle in a scratch worktree, stock (assertions on and off) and with two fixes, each with 12 nearby upstream test classes and the wholeorg.apache.lucene.searchtest package of:lucene:core(the worktree was removed after the runs); the repro through the repro runner with-eaand-daon main, and with-eaon the Maven Central jars of 9.12.3 and 10.0.0 to 10.5.2 (SHA-1 checked); the independent tests of AI verifiers, cross-model reviews and an adjudication; a randomized differential test and a probe for this page; after the fact checks, an edge-encoding test and a third fix (option A+) with gradle and the repro runner. On 2026-10-26 upstream main (later that daya9779ef3c19), branch_10x, branch_10_6 and branch_10_5 kept the same bounds encoding, raw decode and comparison (read, not run).
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:117-131 (buildCompetitiveDISIBuilder: skipper builder whenever the field has no points), :277-312 (encodeBottom/encodeTop from bottomAsComparableLong/topAsComparableLong), :507-532 (DVSkipperCompetitiveDISIBuilder, new SkipBlockRangeIterator(skipper, minValueAsLong, maxValueAsLong) at :530)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/comparators/FloatComparator.java:27 (based on Float#compare), :81 (Float.intBitsToFloat decode), :59, :111, :116 (NumericUtils.floatToSortableInt); DoubleComparator.java the same lines with Double / doubleToSortableLonga Lucene main checkout lucene/core/src/java/org/apache/lucene/document/FloatDocValuesField.java:21, :40 (Float.floatToRawIntBits) and DoubleDocValuesField.java:21, :39 (Double.doubleToRawLongBits); NumericDocValuesField.java:50-60 (indexedField adds a skip index to a 64-bit long value)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/SortField.java:80-98 (FLOAT/DOUBLE: lower values first; not indexed or indexed with FloatPoint/DoublePoint), :612-658 (setOptimizeSortWithIndexedData deprecated, 8.x compatibility only)a Lucene main checkout lucene/core/src/test/org/apache/lucene/search/TestSortOptimization.java:474-478 (testFloatSortOptimizationSkpperIndex: FloatDocValuesField.indexedField(field, Float.floatToRawIntBits(value)), non-negative values only), :1499-1520 (optimized hits must equal a linear scan)a Lucene main checkout lucene/CHANGES.txt:1582 (10.3.0: GITHUB#14672 numeric sort queries can take advantage of DocValuesSkipper to dynamic prune)
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:117-131, :241-266, :277-314, :527-531; search/comparators/FloatComparator.java:58-60, :81, :110-117; search/comparators/DoubleComparator.java:59, :81, :111, :116; index/DocValuesSkipper.java:118-136; util/NumericUtils.java:84-91; document/FloatDocValuesField.java:19-21, :40; document/NumericDocValuesField.java:45-60; index/DocValuesSkipIndexType.java:28-31Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/comparators/NumericComparator.java:242-244; search/TopFieldCollector.java:83-88; util/NumericUtils.java:48, :71; codecs/lucene104/Lucene104PostingsFormat.java:348-351; codecs/lucene104/Lucene104PostingsReader.java:1100-1129; codecs/lucene90/Lucene90DocValuesFormat.java:226; index/DocValuesSkipper.java:127-133
- Who is affected
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/document/FieldType.java:525-530
- Why it looks unintended
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/SortField.java:42-44, :82-86, :94-98, :608-629; search/comparators/FloatComparator.java:26-29, :81, :110-117Lucene main ea57360912ed: lucene/core/src/test/org/apache/lucene/search/TestSortOptimization.java:474-478, :484-487, :1499-1520; lucene/CHANGES.txt:1582
- History
Lucene main ea57360912ed: lucene/CHANGES.txt:1582; dev-tools/doap/lucene.rdf:115-116 (10.3.0 released 2025-09-13)
- TestFloatSortSkipIndexNegative.java (JUnit test):
repro/LFV-144/src/org/apache/lucene/search/TestFloatSortSkipIndexNegative.java(61 lines)
Every value on screen comes from a traced probe run on the main jars or from the code. Made in parallel with this page; the alt text follows the scene's summary card.
assets/LFV-144/bug.png(626 KB)