CachingCollector records a search's hits so that replay(other) can feed them to a second collector instead of re-running the query. replay drives that collector segment by segment, like IndexSearcher, but without IndexSearcher's catch for the per-segment stop signal.
- For each segment,
IndexSearcherasks the collector for a leaf collector, callscollect(doc)for every match, and thenfinish(). - A leaf collector that needs no more hits from a segment throws
CollectionTerminatedException.IndexSearchercatches it and continues with the next segment; that is howLeafCollector#collectdocuments it. - A
TopFieldCollectorwhose sort is the index sort uses it: the segment's documents arrive in sort order, so once its queue is full and it has counted more hits than its threshold (1,000 whenIndexSearcherbuilds it), no later document of that segment can compete.
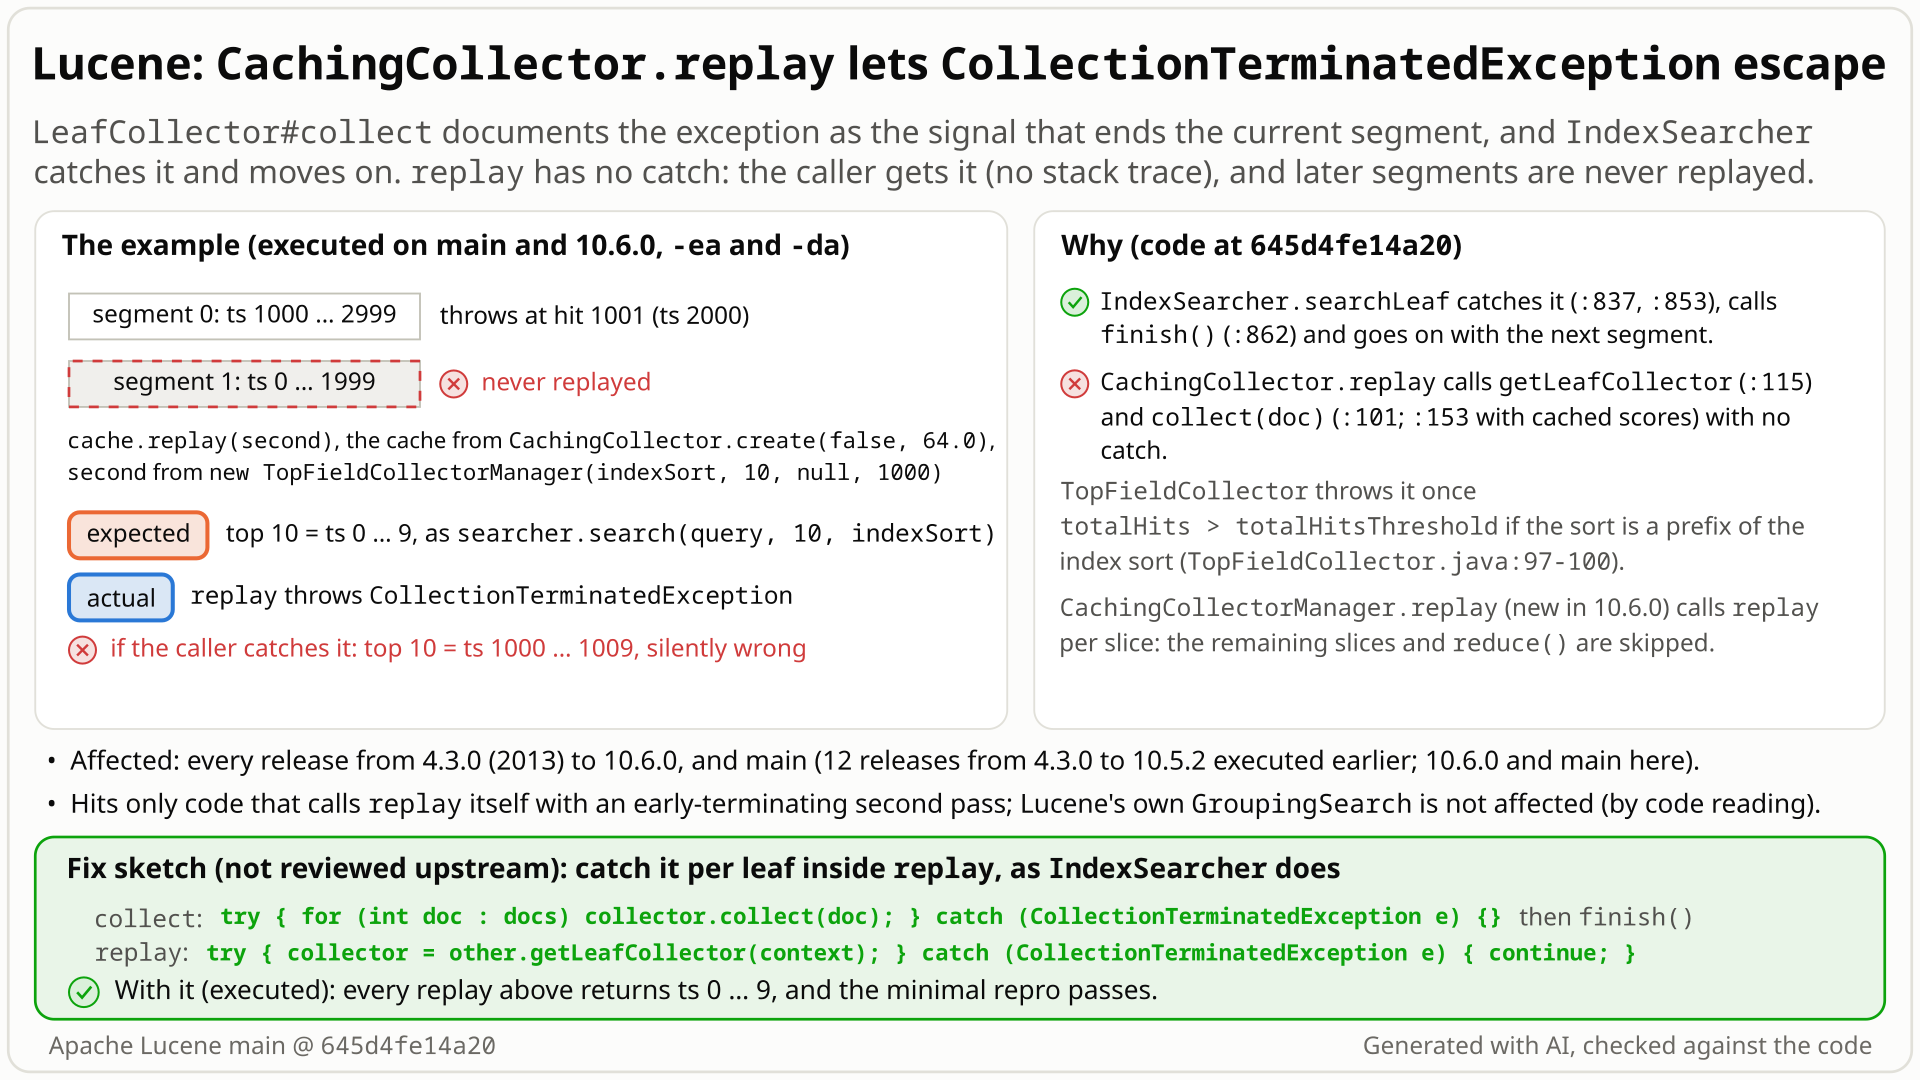
IndexSearcher's per-segment loop on the two-segment index-sort example: where the stop signal is caught, where it escapes, and the top 10 each returns. Select the still to open it at full size. Generated with AI, checked against the code.- Sort the index by a long field
tsand write two segments, all documents matchingf:a: segment 0 holdsts1000..2999, segment 1 holdsts0..1999. Cache a first pass withCachingCollector.create(false, 64.0). - Replay the cache into
new TopFieldCollectorManager(indexSort, 10, null, 1000).newCollector(), the collectorIndexSearcher.search(query, 10, indexSort)builds. You expect that search's top 10:ts0..9, all from segment 1. - In segment 0 the collector has its best 10 hits after 10 documents. At the 1,001st hit it throws
CollectionTerminatedException, the documented signal for "skip the rest of this segment".IndexSearchercatches it and goes on to segment 1;replayhas no catch. - So
replaythrows the exception, with no stack trace. Catching it yourself does not help: segment 1 was never replayed, and the top 10 come back asts1000..1009.CachingCollectorManager.replayalso skips the remaining slices andreduce().
Applications that call CachingCollector#replay or CachingCollectorManager#replay (10.6.0) themselves with a second pass that ends segments early: an index-sorted or index-order TopFieldCollector (by default once it has counted more than 1,000 hits, for example on one segment with that many), a MultiCollector whose children all stop, or a custom collector. Lucene's GroupingSearch is not affected.
Mechanism, terms and numbers534 words
CachingCollector records the hits of a first search so that replay(other) can feed them to a second collector instead of re-running the query; CachingCollectorManager (new in 10.6.0) does the same per slice and then reduces. A leaf collector may end a segment early by throwing CollectionTerminatedException, which LeafCollector#collect documents as the per-segment stop signal and IndexSearcher.searchLeaf catches, both from getLeafCollector and from scoring (IndexSearcher.java:835-855 on main 645d4fe14a20). The replay loops have no such catch (CachingCollector.java:115, :100-102, :151-154), so the exception escapes replay, without a stack trace, and the remaining segments are never replayed. A stock TopFieldCollector sorted by the index sort throws it once it has counted more hits than its threshold (1,000 by default; one segment with that many is enough): replaying a two-segment index-sorted cache into it throws, and catching the exception returns the top 10 ts 1000..1009 instead of 0..9. It has been there since the exception was added in 4.3.0 (LUCENE-4862, 2013) and affects every release to 10.6.0 and main (13 releases and main executed, the others by source history). Catching the exception per segment in replay, as IndexSearcher does, fixes it; the core caching tests, the grouping module and the whole core module pass with the fix.
IndexSearcher.searchLeaf(IndexSearcher.java:831-863) wrapscollector.getLeafCollector(ctx)intryand returns on the exception (:835-841, "there is no doc of interest in this reader context"), wraps scoring intryand falls through on it (:849-855, "collection was terminated prematurely"), then callsleafCollector.finish()(:862).CachingCollector#replay(CachingCollector.java:106-118) callsother.getLeafCollector(context)(:115) andcollect(collector, i)(:116) for each cached segment.collectloops over the cached doc IDs and callscollector.collect(doc)(:100-102, thenfinish()at:103); with cached scores,ScoreCachingCollector#collectruns the same loop with the score set (:151-154) but never callsfinish()(LFV-180). There is notryanywhere, so the exception from either call leavesreplayand the loop over segments stops.CachingCollectorManager#replay(CachingCollectorManager.java:118-130) creates one second-pass collector per slice, callscache.replay(...)(:126) and thenreduce(...)(:129). An exception in the first slice skips the other slices and the reduce.
TopFieldCollector(TopFieldCollector.java:92-103): when the search sort is part of the index sort and a document is not competitive,if (totalHits > totalHitsThreshold) throw new CollectionTerminatedException();(:98-100).IndexSearcher#search(Query, int, Sort)passesTOTAL_HITS_THRESHOLD = 1000(IndexSearcher.java:100,:733). On upstream main after #16857 (merged 2026-10-29) the same throw sits inIndexSortedLeafFieldComparator.MultiCollectorthrows it fromgetLeafCollectorwhen no child wants the segment (MultiCollector.java:142-143) and fromcollectonce every child has stopped (:218-226).- Any custom collector, as the exception's javadoc invites: "Throw this exception in LeafCollector#collect(int) to prematurely terminate collection of the current leaf" (
CollectionTerminatedException.java:19-21).
The exception is stackless: fillInStackTrace is overridden because it is "never re-thrown" (CollectionTerminatedException.java:35-39), so the trace shows Caused by: org.apache.lucene.search.CollectionTerminatedException with no frames. Catching it around replay leaves the later segments unreplayed: in the index-sort example the top 10 are ts 1000..1009 instead of 0..9.
Exposure and likelihood199 words
- Opt-in.
CachingCollectorandCachingCollectorManagerare@lucene.experimentalexpert APIs (CachingCollector.java:38,CachingCollectorManager.java:48). Within that usage the defaults suffice: the index-sort example needs only a segment with more than 1,000 hits. - Loud by default. The request fails with a stackless runtime exception. Results are silently wrong only if the caller catches it around
CachingCollector#replay: the second-pass collector it holds misses every segment after the first stopped one. AroundCachingCollectorManager#replaya catch leaves no result at all, because the later slices andreduce()are skipped (CachingCollectorManager.java:123-129). - Deterministic. Same result with assertions on and off, with a sequential
IndexSearcher; nothing is written or corrupted. - Not affected.
GroupingSearch, the only in-tree replay user (GroupingSearch.java:209): its second-pass collectors useInteger.MAX_VALUEthresholds (TopGroupsCollector.java:134,:142) and never stop early (read, not executed). Solr's grouping cache likewise, by code reading. - Workaround. A second pass with a
totalHitsThresholdofInteger.MAX_VALUEnever throws (totalHits > totalHitsThreshold,TopFieldCollector.java:98, never holds), as inGroupingSearch; replay then feeds it every cached hit instead of stopping early. Or re-run the search instead of replaying (read, not executed). - Likelihood: rare. Nobody reported it in the 13 years since 4.3.0.
One JUnit method on the public API: a one-document index, a CachingCollector filled by a MatchAllDocsQuery search, then replay into a SimpleCollector whose collect throws CollectionTerminatedException. Deterministic; the test itself uses no randomness (the test framework still randomizes codec and similarity defaults, fixed by the seed); fails the same way with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCachingCollectorReplayTerminatedLeaf extends LuceneTestCase {

  @SuppressWarnings("deprecation")
  public void testReplayIntoCollectorThatTerminatesLeaf() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        w.addDocument(new Document());
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        CachingCollector cache = CachingCollector.create(false, 1.0);
        new IndexSearcher(reader).search(MatchAllDocsQuery.INSTANCE, cache);
        SimpleCollector terminating =
            new SimpleCollector() {
              @Override
              public void collect(int doc) {
                throw new CollectionTerminatedException();
              }

              @Override
              public ScoreMode scoreMode() {
                return ScoreMode.COMPLETE_NO_SCORES;
              }
            };
        try {
          cache.replay(terminating);
        } catch (CollectionTerminatedException e) {
          // Expected: replay ends the leaf, as IndexSearcher.search does; actual: the exception escapes.
          throw new AssertionError("CachingCollector.replay let " + e + " escape", e);
        }
      }
    }
  }
}
cp $REPRO/TestCachingCollectorReplayTerminatedLeaf.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestCachingCollectorReplayTerminatedLeaf -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
- Expected
replayreturns normally: the collector's segment ends, as withIndexSearcher.search.- Observed
replaythrowsCollectionTerminatedException(no stack frames), with assertions on and off, on main, 10.6.0 and 10.5.2.
More files, environment, full output207 words
The test sits in org.apache.lucene.search, as Lucene's own tests do, but uses only public API. It uses the deprecated IndexSearcher#search(Query, Collector) because CachingCollector is a Collector; the manager form exists only from 10.6.0 on. It compiles against 10.5.2, 10.6.0 and main; 9.12.3 has no MatchAllDocsQuery.INSTANCE, so on older releases write new MatchAllDocsQuery().
The collector throws on its first hit, so one document is enough. The comment line in the catch states the expectation: IndexSearcher.search with the same collector ends the segment and returns. The realistic trigger is the two-segment index-sort example in "The finding in 30 seconds"; it is described there, not added as a second test.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Also fails on the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestCachingCollectorReplayTerminatedLeaf.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestCachingCollectorReplayTerminatedLeaf -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
TestCachingCollectorReplayTerminatedLeaf > testReplayIntoCollectorThatTerminatesLeaf FAILED
    java.lang.AssertionError: CachingCollector.replay let org.apache.lucene.search.CollectionTerminatedException escape
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:F0069F7D7DA18069]:0)
        at org.apache.lucene.search.TestCachingCollectorReplayTerminatedLeaf.testReplayIntoCollectorThatTerminatesLeaf(TestCachingCollectorReplayTerminatedLeaf.java:54)

        Caused by:
        org.apache.lucene.search.CollectionTerminatedException
> Task :lucene:core:test FAILED

# the same with -Ptests.asserts=false; the cause has no frames (the exception is stackless)LeafCollector#collectdocuments the exception as the way to end just the current segment (LeafCollector.java:76-79), andreplaydrives the segments itself.- The exception is stackless because it is "never re-thrown" (
CollectionTerminatedException.java:37); the replay javadocs never mention it. - The core drivers catch it (
IndexSearcher,MultiCollector,SuggestIndexSearcher); where upstream resolved the same omission elsewhere, it fixed the code (LUCENE-6772, #12609).
The full argument417 words
- Contract.
LeafCollector#collect: "The collection of the current segment can be terminated by throwing a CollectionTerminatedException. In this case, the last docs of the current LeafReaderContext will be skipped and IndexSearcher will swallow the exception and continue collection with the next leaf" (LeafCollector.java:76-79).LeafCollector#finishruns once the leaf "has finished collecting successfully, including when a CollectionTerminatedException is thrown" (:150-151), which reads as an obligation of whoever drives the leaf; the no-score replay callsfinish()itself (CachingCollector.java:103; the scored replay does not, LFV-180). These javadocs nameIndexSearcher, so applying them to replay is an inference from the collector protocol, not an explicit guarantee. - Replay replaces a search.
CachingCollector: if the cache overflowed, "you must instead re-run the original search" (CachingCollector.java:25-31);CachingCollectorManager: "replayed to a second-pass CollectorManager without re-running the query" (CachingCollectorManager.java:24-27). The replay javadocs list what differs (no scorer without cached scores) and what they throw (IllegalStateException):CachingCollector.java:345-354,CachingCollectorManager.java:113-117.CachingCollector#replayalso keeps a stale@throws IllegalArgumentExceptionabout out-of-order collection (:351-352; out-of-order scoring was removed in 5.0.0, LUCENE-6179, and replay never throws it). This exception is not among them. - The core drivers handle it.
IndexSearcher(IndexSearcher.java:835-855),MultiCollector(MultiCollector.java:128-134,:218-226) and, since #12609,SuggestIndexSearcher(SuggestIndexSearcher.java:74-77). Not every in-tree driver does:SortRescorerand grouping'sBlockGroupingCollectorrun only collectors they build withInteger.MAX_VALUEthresholds and have no catch (the reason jpountz gave on #12380, next point); the sandboxPostCollectionFaceting, which like replay feeds already-collected documents to collectors the caller supplies, has no catch either; andDrillSidewaysScorer.java:149-151has an open TODO about the exception. (Read only; none of these was executed or is claimed as a bug.) - Precedent. LUCENE-6326 / LUCENE-6772 (#7387, #7830) fixed
MultiCollectorin 5.4. Before #12609, jpountz had explained on #12380 (2023-09-28) thatSuggestIndexSearcherskipped the catch aroundgetLeafCollectoronly because, "unlike IndexSearcher which may run any Collector", it runs a collector "which never throws aCollectionTerminatedException", and offered to approve the change;replay(Collector other)accepts any collector. LUCENE-6337 (#7398) reported the same omission inToParentBlockJoinIndexSearcher; it was never fixed and is still open, and the class was removed in 2017 (LUCENE-6959). - No recorded decision. LUCENE-4862 created the exception and taught only
IndexSearcher(its commit touchesCHANGES.txt,CollectionTerminatedException.java,Collector.java,IndexSearcher.javaand a test); its comments never mentionCachingCollector. No commit ever added or removed a handler in replay, and no upstream test combines replay with the exception.
The devil's-advocate check203 words
Strongest case (the intended-behaviour check, the cross-model review and the review, each rating it at most moderate): the exception's javadoc says IndexSearcher swallows it and that you should not catch it when calling IndexSearcher's methods (CollectionTerminatedException.java:23-25), so the contract could bind IndexSearcher only and let other drivers' callers catch it; the APIs are @lucene.experimental; and replay is a lean pump that also skips setWeight and the competitive iterator.
Why it fails: catching it outside replay is not a correct use, because replay has already abandoned the remaining segments ([1000..1009] instead of [0..9]). The steps replay skips are optional by design (competitiveIterator "Optionally returns", setWeight a default no-op), while the exception is the one stop signal LeafCollector#collect documents. Experimental status allows API changes, not a driver that breaks the collector protocol, and nothing documents a "no early-terminating collectors" precondition. A documentation-only resolution is possible, but wherever upstream resolved this omission in another driver, it fixed the code (LUCENE-6772, #12609) and never documented a limitation instead; LUCENE-6337 stayed open until its searcher was removed in 2017. Conceded: the javadocs do not promise IndexSearcher's semantics for replay in so many words, and an Integer.MAX_VALUE threshold avoids the stock trigger.
Recommended Catch the exception per segment in replay, as IndexSearcher.searchLeaf does
Catch CollectionTerminatedException per segment in CachingCollector, as IndexSearcher.searchLeaf does: around getLeafCollector in replay (skip the segment) and around both replay collect loops (end the segment). One file, +21/-6. The test and the index-sort scenario pass, and so do the core caching tests, the grouping module and the whole core module.
All options and trade-offs3 options · 599 words
Two options were built and run in a scratch worktree of 645d4fe14a20; a documentation-only change is not recommended. LFV-180 (the missing finish() in the scored replay and in the wrapped first pass) touches the same method, so option B combines both.
Catch the exception per segment in replay, as IndexSearcher.searchLeaf does (validated by the checks) (recommended)
Three try/catch blocks in CachingCollector.java that mirror the two catches of IndexSearcher.java:835-855: an exception from other.getLeafCollector(context) skips that segment (no leaf collector, so no finish(), as IndexSearcher returns); an exception from the no-score collect loop ends the segment and the existing collector.finish() still runs; an exception from the scored loop ends the segment. It is not fully equivalent to IndexSearcher on the scored replay: segments there still end without finish() (LFV-180, option B), and setScorer stays outside the catch.
// NoScoreCachingCollector#replay
final LeafCollector collector;
try {
  collector = other.getLeafCollector(context);
} catch (CollectionTerminatedException _) {
  // there is no doc of interest in this reader context
  // continue with the following leaf
  continue;
}
collect(collector, i);
// both collect(...) loops (no-score loop shown)
try {
  for (int doc : docs) {
    collector.collect(doc);
  }
} catch (CollectionTerminatedException _) {
  // collection of this leaf was terminated early, continue with the following leaf
}
Trade-offs
- Behaviour change. A caller that catches the exception around
replaytoday gets the complete result instead of a truncated one; no documented contract supports relying on the escape, which is undocumented and stackless. setScorer. The scored replay callssetScorerbefore thetry; inIndexSearcherit runs insidescorer.score(...), under the catch. Moving it into thetrywould mirror that exactly;LeafCollector#setScorerdoes not document the exception, so it was left out (not built).finish()on the scored replay is still missing: that is LFV-180 (option B).- Cost. One
tryper segment, nothing per document. Conflict. Open PR #15210 edits other lines of the file.
What the checks validated
- Stock: the minimal test fails with assertions on and off. With the fix: it passes with assertions on and off, and the index-sort scenario passes 2 of 2 (top 10
ts0..9). TestCachingCollector,TestCachingCollectorManager,TestMultiCollector,TestMultiCollectorManager,TestIndexSearcher(39 tests with the new one, 1 skipped) and the whole grouping module (56 tests): 0 failures, assertions on and off. The whole core module: 748 classes, 8,897 tests, 0 failures, 322 skipped (748 is the number of coreTest*.javafiles, so no copied test ran).ecjLintandforbiddenApis(main and test) pass;checkGoogleJavaFormatpasses forCachingCollector.javaand asks only to wrap the test's 105-column comment line.
Option A plus collector.finish() after the scored replay's try/catch, so both replay paths end every replayed segment with finish() "including when a CollectionTerminatedException is thrown" (LeafCollector.java:150-151), plus super.finish() in NoScoreCachingLeafCollector#finish (LFV-180's fix for the wrapped first pass). +24/-7 in one file.
Trade-offs
One PR for two issues; reviewers may prefer them separate.
What the checks validated
This doc's test, LFV-180's TestCachingCollectorFinish (facet), the closest core suites (39 tests, 1 skipped) and the grouping module (56 tests) pass with assertions on. The whole core module was run for option A only.
A javadoc note such as "replay does not support collectors that throw CollectionTerminatedException".
Trade-offs
Rules out an index-sorted TopFieldCollector's early termination in a second pass: callers would have to turn it off with an Integer.MAX_VALUE threshold or re-run the search, since catching the exception gives wrong hits. It also contradicts LeafCollector#collect.
By code reading, Solr's grouping cache and Lucene's GroupingSearch replay only into second passes that never stop early, so neither is affected.
A bounded-exhaustive check: a harness ran the real collector managers on every index of 1-3 segments with 1-6 documents under every slicing and compared each result with a plain search. Replay into an index-order TopFieldCollectorManager threw CollectionTerminatedException 271,021 times; the finder then reduced it to a JUnit.
The method in full107 words
Method: bounded-exhaustive translation validation (semi-formal). The harness of a hunt unit (concurrent collector managers) runs the real collector managers on every index of 1-3 segments x 1-6 documents (258 shapes) under every distinct IndexSearcher slicing (3,750), sequentially and with a 3-thread pool, and compares each result with a plain IndexSearcher.search. Among its CachingCollectorManager checks, the failure kind "replay into TopFieldCollectorManager(INDEXORDER, 1, 0) threw CollectionTerminatedException" appeared 271,021 times in the run with assertions on, in every slicing. The finder reduced it to a one-segment public-API JUnit on the stock main jars and a release-compatible SimpleCollector variant; this doc's test is a one-document, one-method version of those.
No prior report found: 136 query lines on 2026-10-26 (GitHub issues and PRs, commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive, downstream trackers, the web), refreshed on 2026-10-30. Not fixed on upstream main 2f424fd428da. The same omission was reported for three other drivers: upstream fixed two, and the third report stayed open until its class was removed.
Searches5 searches
Related, not reports of this bug: LUCENE-6326 / LUCENE-6772 (#7387, #7830; MultiCollector, fixed in 5.4), #12609 (SuggestIndexSearcher, merged 2023) and LUCENE-6337 (#7398, ToParentBlockJoinIndexSearcher, still open; the class was removed in 2017) are the same omission at other drivers; #16247 (added CachingCollectorManager) and #12380 (added finish()) are the two recent changes to replay, and their reviews never mention the exception; #12270 made the exception stackless because it is always ignored; #5436 (LUCENE-4370) is a 2012 comment on code that no longer exists; #10401 (LUCENE-9361, open) proposes removing CachingCollector; open PR #15210 edits other lines of CachingCollector.java (a textual conflict, not a fix). In the registry, LFV-180 (the missing finish() in the scored replay and in the wrapped first pass) touches the same method. Search limit: the extended prior-report tool run stopped after 8 of its 20 GitHub queries (GitHub's search rate limit); the GraphQL searches, on a separate quota, covered every term of the unrun queries.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, lucene-solr, solr, lucenenet, Elasticsearch, OpenSearch, all of GitHub) | 2026-10-26 | a scripted prior-report search (16 issue/PR, 3 commit and 2 downstream-repository queries) and 58 GraphQL searches over class, method, exception and symptom names; 33 hits read | no report of this bug; the related items above |
| Open apache/lucene PRs | 2026-10-26 | changed files of all 413 open PRs | none changes the replay loops; #15210 edits other lines of the file |
| Mailing lists, JIRA archive, web | 2026-10-26 | 20 list queries (dev@, java-user@, issues@, commits@), 4 JIRA and 8 web queries, direct subject listings | no report; three list threads on throwing the exception from getLeafCollector, the LUCENE-6772 change and timeouts are context |
| Git history | 2026-10-26 | git log -S/-G CollectionTerminatedException and --grep over all branches | no commit adds or removes a handler in replay |
| Refresh | 2026-10-30 | 4 keyword searches, CachingCollector and CollectionTerminatedException items by update date, commits to both replay files on upstream main, the state of #15210 and #16857 | nothing new; upstream main 2f424fd428da unchanged in both files; #16857 merged 2026-10-29 (moves the index-sort throw, see Suggested fix) |
Introduced with the exception itself: LUCENE-4862 (jpountz, 2013-03-21, first released in 4.3.0) taught only IndexSearcher to catch it. Every release from 4.3.0 to 10.6.0 and main is affected (13 releases and main executed, the rest by source history); 4.2.1 has no such exception. CachingCollectorManager (#16247, new in 10.6.0) inherits it.
Versions tested6 rows
986444de446b (trunk) / 65b70503ab16 (branch_4x), LUCENE-4862 (migrated issue #5927, pre-GitHub, no PR), added CollectionTerminatedException and the catch around scoring in IndexSearcher only; CachingCollector.replay dated from 3.2 (LUCENE-3102). LUCENE-4858 (a5c3b88fe7ae, 2013-04-09, also 4.3.0) added the catch for setNextReader, today getLeafCollector, again in IndexSearcher only. LUCENE-5527 (85642f59ddf0, 2014) rewrote replay into today's per-segment shape, #12380 (8811f31b9ca6, 2023) added finish() to the no-score replay, and #16247 (3afffeef5a8d, gaobinlong, 2026-07-08) added CachingCollectorManager.replay; none added a handler.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle and standalone, assertions on and off); the index-sort scenario returns [1000..1009] |
| 10.6.0 | affected | the minimal test fails, assertions on and off; the index-sort scenario fails (release jars) |
| 10.5.2, 9.12.3 | affected | the minimal test (10.5.2) and the index-sort scenario (both) fail |
| 4.3.0 to 10.5.2 (12 releases run) | affected | the follow-up's history probe fails 4 of 4 cases on 4.3.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 |
| 4.2.1 | no such exception | the probe does not compile; with an ordinary exception both drivers behave the same |
main 645d4fe14a20 with the fix | not affected | the minimal test and the index-sort scenario pass; core caching tests, grouping and the whole core module pass |
A cross-model refute review (executed), independent verifiers and an adjudication rate it real; each rates the intended-behaviour case at most moderate. This doc's test was run on main, 10.6.0 and 10.5.2, and with the fix.
Checks and verdicts281 words
Every check re-ran a repro on stock jars; the reviewer from another model family (OpenAI GPT-5.6) executed its own test in the refute lens and only read code in the works-as-designed lens.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Harness: 271,021 failing checks; JUnit fails 2 of 2 on main (assertions on and off); the legacy variant fails on main, 10.5.2 and 9.12.3; passes with the fix. |
| cross-model refute review | real, high | Own SimpleCollector test fails on main, the IndexSearcher control passes; intended case moderate; noted the scored replay's missing finish() (LFV-180). |
| Independent reproducer | real | 11 of 11 own tests fail (collect and getLeafCollector paths, both cache modes, sequential and executor manager), 110 of 110 over 10 iterations, 7 of 7 on 10.5.2 and 9.12.3; pass with its own per-segment catch. |
| Works-as-designed review | real, high (reading only) | Intended case moderate; a separate run re-ran the finder's repro (2 of 2 fail). |
| Devil's advocate | real | Index-sort probe fails on main, 10.5.2 and 9.12.3; a caller-side catch gives [1000..1009]; no comment, test or discussion chose propagation. |
| adjudication | confirmed, high | The independent reproduction's tests with a new seed: 11 of 11 fail (assertions on and off), 11 of 11 pass with the independent reproduction's fix; the intended-behaviour check's probe 2 of 2 fail. |
| this doc | real | Minimal test on main 645d4fe14a20 (gradle and standalone, assertions on and off), 10.6.0, 10.5.2 and a scratch build of upstream main 2f424fd428da; the index-sort scenario on main, 10.6.0 and upstream main; fix A (test, scenario, closest suites, grouping, the whole core module, lint) and option B in a scratch worktree. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 494 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,669 words
- Registry title
- CachingCollector#replay (and CachingCollectorManager#replay) lets a CollectionTerminatedException from the second-pass collector escape to the caller instead of ending only that leaf as IndexSearcher does, so replaying into an early-terminating collector, such as a TopFieldCollector sorted by the index sort, throws
- Area
- search / CachingCollector replay (CachingCollector, CachingCollectorManager)
- Priority
- Low, rank 709: CachingCollector replay lets a CollectionTerminatedException from an early-terminating second pass escape (wrong top hits if the caller catches it), loud and only for applications that drive replay themselves.
- Impact class
- crash
- Impact note
- Hits only applications that call CachingCollector#replay (released, @lucene.experimental) or CachingCollectorManager#replay (new in 10.6.0, released 2026-10-29) themselves with a second pass that ends a leaf early: a TopFieldCollector sorted by index order or by a prefix of the index sort with a finite totalHitsThreshold (IndexSearcher's own default is 1000) once a segment has more hits than the threshold, a MultiCollector whose children all terminate, or a custom collector that throws the exception as LeafCollector#collect documents; for them it fires deterministically on ordinary data with the default configuration, -ea and -da: replay throws a stackless CollectionTerminatedException, stops at the first terminated leaf (CachingCollectorManager also skips the remaining slices and reduce()), and gives silently wrong top hits only if the caller catches the exception around replay; nothing is corrupted, and in-tree GroupingSearch is not affected (its second-pass collectors use Integer.MAX_VALUE thresholds, by code reading).
- Summary
- You run a query once through a CachingCollector (or CachingCollectorManager) and then replay the cached hits into a second-pass collector, expecting the same result as running that collector through IndexSearcher. When the second-pass collector stops a segment early by throwing CollectionTerminatedException, which is how LeafCollector#collect documents early termination and what a stock TopFieldCollector sorted by the index sort does once a segment has more than 1000 hits, IndexSearcher simply moves on to the next segment, but replay lets the exception escape to the caller, without a stack trace. Catching it around replay is no workaround: the later segments are never replayed, so in the repro the top 10 come back as [1000..1009] instead of [0..9].
- Introduced
- 65b70503ab16 (branch_4x, svn r1459408, merged from trunk 986444de446b, r1459400; LUCENE-4862 'Ability to terminate queries on a per-segment basis', GitHub mirror #5927, by jpountz, reviewed on the issue by shaie; pre-GitHub, no PR): it added CollectionTerminatedException and a catch around scoring in IndexSearcher only, and left CachingCollector.replay (since 3.2, LUCENE-3102) without a handler [read: git show --stat lists CHANGES.txt, CollectionTerminatedException.java, Collector.java, IndexSearcher.java and TestEarlyTermination.java only; exec: release level, 4.2.1 has no such exception (probe does not compile; a baseline with an ordinary RuntimeException shows IndexSearcher and replay behaving the same), 4.3.0 fails 4 of 4]; the getLeafCollector path (then setNextReader) followed with a5c3b88fe7ae (branch_4x r1466057, trunk e2e3e2bfdafd; LUCENE-4858, #5923, by shaie with jpountz, 2013-04-09, also 4.3.0); carried forward unchanged in substance by 85642f59ddf0 (LUCENE-5527, 2014, replay rewritten to its current per-leaf shape) and 8811f31b9ca6 (#12380, 2023, added finish() to the no-score replay but no handler); the CachingCollectorManager entry point 3afffeef5a8d (#16247, by gaobinlong, merged 2026-07-08, first released in 10.6.0) inherits it [read]; no commit on any branch ever added or removed a handler in replay [read: git log --all -S/-G CollectionTerminatedException on both files] (2013-03-21 (LUCENE-4862, collect path); 2013-04-09 (LUCENE-4858, getLeafCollector path); 2026-07-08 (#16247, CachingCollectorManager entry point, first released in 10.6.0))
- First affected version
- 4.3.0 [exec] for CachingCollector.replay (4.2.1 is the last release without the bug: CollectionTerminatedException does not exist there [exec: probe does not compile]); CachingCollectorManager.replay: 10.6.0 (released 2026-10-29; listed under 10.6.0 in CHANGES.txt)
- Affected versions
- every release from 4.3.0 to 10.6.0 (10.6.0 by reading) and main ea57360912ed. [exec] the follow-up's history probes (public-API main() programs, 4 cases: collect and getLeafCollector paths x cacheScores false and true) fail 4 of 4 on 4.3.0, 4.10.4, 5.0.0, 5.5.5, 6.6.6, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea, and -da on 9.12.3, 10.5.2 and main) and pass 4 of 4 with the fix shadowed on main; the finder's legacy JUnit fails 2 of 2 on 9.12.3, 10.5.2 and main; the independent reproduction's JUnit fails 7 of 7 on 10.5.2 and 9.12.3; the intended-behaviour check's index-sort probe (stock TopFieldCollectorManager trigger) fails 2 of 2 on 9.12.3, 10.5.2 and main; the CachingCollectorManager JUnit fails 2 of 2 on main and does not compile on 10.5.2 (class absent). [read] the other releases from 4.3.0 to 10.5.2 by tag containment and the absence of any handler commit; branch_10x, branch_10_6 and branch_9_12 still have no handler (follow-up prior-report record, read, not executed). The stock-collector trigger was executed only on 9.12.3, 10.5.2 and main; older releases ran the minimal custom-collector probe. The 4.x-7.x runs used JDK 25, not the JDK those releases supported. Not executed: x86, a concurrent first pass with intra-segment partitions.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: scripted prior-report search original spec (16 GitHub issue/PR, 3 commit and 2 downstream-repo queries) and extended spec (20 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA-archive and 8 web queries), 58 GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, apache/lucenenet and all of GitHub, direct JIRA and list-subject searches, the file lists of all 413 open apache/lucene PRs and git log -S/--grep over the full history: 136 query lines, 33 hits read, none the same bug; the finder's and the intended-behaviour check's own searches also found nothing); not fixed upstream: on main ea57360912ed, branch_10x, branch_10_6 and branch_9_12 replay still calls getLeafCollector and collect without a handler, and no open PR changes the replay loops (#15210 edits other lines of CachingCollector.java; #16857 moves the index-sort throw inside the TopFieldCollector code, and after its merge (2026-10-29) the repro still fails on e1faeba08bd, -ea and -da); related, not reports of this bug (the same bug class at other collector drivers, precedents for the fix): LUCENE-6326 / LUCENE-6772 (#7387, #7830, MultiCollector, fixed in 5.4), #12609 (SuggestIndexSearcher, merged 2023), LUCENE-6337 (#7398, ToParentBlockJoinIndexSearcher, open); also #5436 / LUCENE-4370 (a 2012 comment on CachingCollector's 4.x setNextReader handling, a different defect in code that no longer exists), #16247 and #12380 (the two recent changes to replay, whose reviews never mention the exception) and #12270 (why the exception is stackless); gaps: one scripted search run was stopped after 8 of 20 GitHub REST queries (GitHub's search rate limit; the GraphQL searches covered their terms), the bare 'replay' query read 50 of 52 results, closed unmerged PRs that edit CachingCollector.java without naming it cannot be found by text search, and forums only via web search
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner, and passes with the recommended fix (with the index-sort scenario, the closest suites, the grouping module and the whole core module). Also fails on the 10.6.0 and 10.5.2 release jars; the index-sort scenario fails on 10.6.0 and on a scratch build of upstream main2f424fd428da(2026-10-30, after #16857 moved the index-sort throw). The hunt's earlier runs (finder, verifiers, adjudication, follow-up: 25 history runs over 4.2.1-10.5.2) used mainea57360912ed, where every cited source file exceptCHANGES.txtis identical.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:38 (@lucene.experimental), :98-104 (no-score per-leaf collect loop, finish() at :103, no handler), :106-118 (replay: getLeafCollector at :115 with no handler), :145-155 (scored per-leaf collect loop, no handler, no finish())a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/CachingCollectorManager.java:48 (@lucene.experimental), :114-130 (replay javadoc lists only IllegalStateException; per-slice cache.replay at :126, reduce at :129)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/CollectionTerminatedException.java:19-25 ('terminate collection of the current leaf'; 'IndexSearcher swallows this exception and never re-throws it'), :35-38 (fillInStackTrace: 'never re-thrown so we can save the expensive stacktrace')a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:100 (TOTAL_HITS_THRESHOLD = 1000), :831-863 (searchLeaf catches the exception from getLeafCollector at :837 and from scoring at :853, then calls finish())a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/LeafCollector.java:75-79 (collect: the exception terminates 'the current segment' and IndexSearcher continues with the next leaf), :149-159 (finish is called 'including when a CollectionTerminatedException is thrown')a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:91-101 (index-sort / index-order early termination throws at :100 once totalHits > totalHitsThreshold)a Lucene main checkout lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroupsCollector.java:134, :142 (Integer.MAX_VALUE thresholds: GroupingSearch's second pass never terminates early)a Lucene main checkout lucene/CHANGES.txt:438 (Lucene 10.6.0 section), :525 (GITHUB#16247 CachingCollectorManager)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:25-31, :98-118, :144-155, :345-354a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollectorManager.java:24-31, :113-130a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:100, :733, :831-863a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/LeafCollector.java:76-79, :149-159a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CollectionTerminatedException.java:19-26, :35-39a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:92-103; MultiCollector.java:128-143, :218-226
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:38; CachingCollectorManager.java:48a Lucene main checkout (645d4fe14a20) lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:209; TopGroupsCollector.java:134, :142a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopFieldCollector.java:78, :92-103; CachingCollectorManager.java:118-130
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/LeafCollector.java:76-79, :149-159; CollectionTerminatedException.java:19-26, :35-39a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/CachingCollector.java:25-31, :103, :345-354; CachingCollectorManager.java:24-27, :113-117a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:835-855; MultiCollector.java:128-134, :218-226a Lucene main checkout (645d4fe14a20) lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:74-77GitHub apache/lucene #12380 review comments (gh api pulls/12380/comments, read 2026-10-30: jpountz 2023-09-28 on SuggestIndexSearcher.java)a Lucene main checkout (645d4fe14a20) lucene/sandbox/src/java/org/apache/lucene/sandbox/facet/utils/PostCollectionFaceting.java:37-52, :332-337, :424, :447-452 (no CollectionTerminatedException handler in the file)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/SortRescorer.java:49, :72-79; lucene/grouping/src/java/org/apache/lucene/search/grouping/BlockGroupingCollector.java:293-298, :303-313a Lucene main checkout (645d4fe14a20) lucene/facet/src/java/org/apache/lucene/facet/DrillSidewaysScorer.java:149-151 (TODO); CachingCollector.java:351-352 (stale @throws IllegalArgumentException)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:835-862
- History
a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:456 (10.6.0 section), :543 (GITHUB#16247)
- TestCachingCollectorReplayTerminatedLeaf.java (one test, public API):
repro/LFV-154/src/org/apache/lucene/search/TestCachingCollectorReplayTerminatedLeaf.java(59 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the two-segment index-sort example.
assets/LFV-154/bug.png(494 KB)