SegmentTermsEnum.computeBlockStats() builds the Stats object by walking the terms dictionary but never sets indexNumBytes, so it stays 0. The size is at hand: FieldReader reads the trie's byte range in .tip (indexStart, indexEnd) and opens exactly that slice. The older Lucene90 copy of the method still has the assignment; #14333 dropped it.
- Each field's terms dictionary, the block tree, lives mainly in two files:
.timholds the terms in blocks, and.tipholds a small index that leads a lookup to the right block. Since 10.3 that index is a trie; before, it was an FST. Terms.getStats(), an expert debugging call, walks the whole dictionary and returns aStatsobject with counters such as terms, blocks and suffix bytes.CheckIndex -level 2 -verboseprints it for every field.- Its first lines are
index trie:andN bytes: the fieldStats.indexNumBytes, documented as "Byte size of the index".
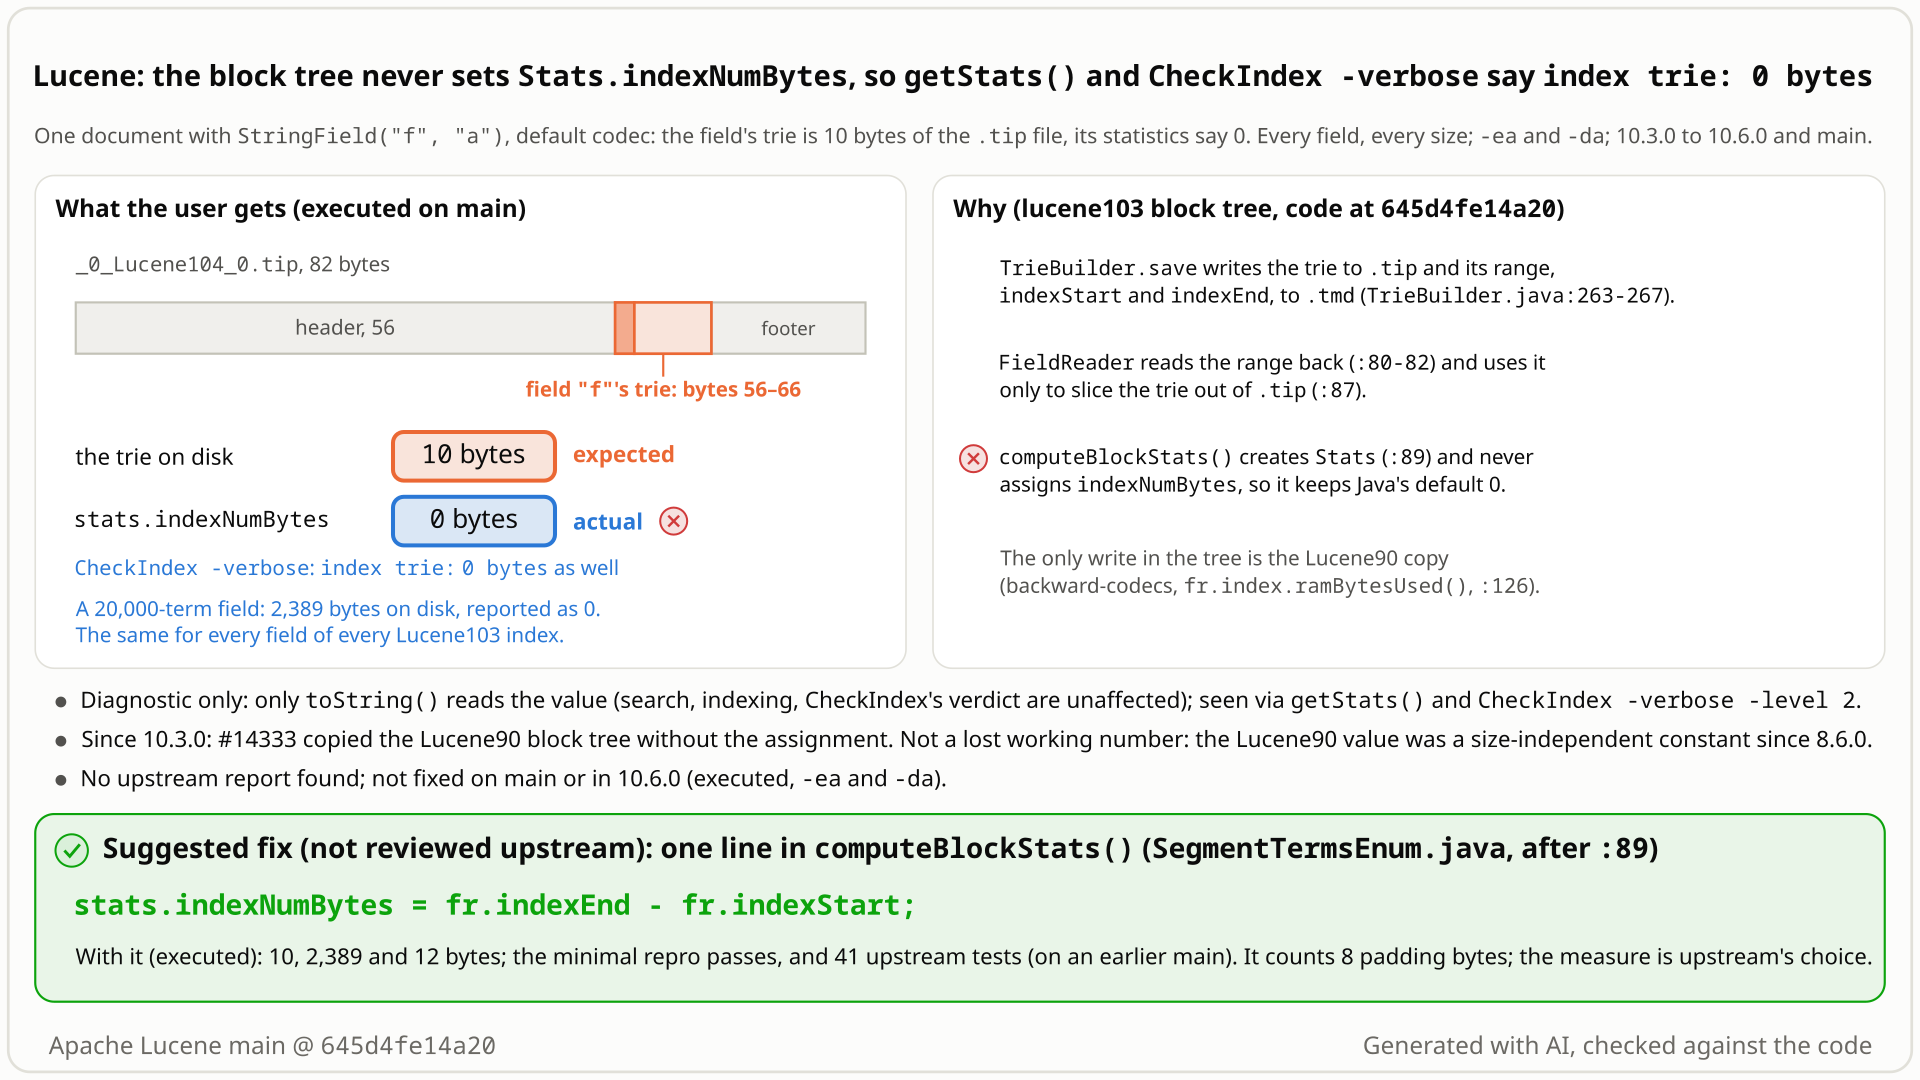
.tip file, and FieldReader knows that range, but computeBlockStats() never copies it into Stats.indexNumBytes, so getStats() and CheckIndex print 0. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document with
StringField("f", "a")under the default codec. The field's terms index, a trie in the.tipfile, takes 10 of that file's 82 bytes; for 10,000 unique ids it takes 1,197 bytes. - Ask for the field's block-tree statistics:
Terms.getStats(), orCheckIndex -level 2 -verbose, which prints them per field. You expectindexNumBytes, documented as "Byte size of the index" and printed asindex trie: N bytes, to show those sizes. - You get
indexNumBytes = 0andindex trie: 0 bytes, for every field that has terms, in every index written with the default codec since 10.3.0, with assertions on or off. CheckIndex still reports the index clean. - Why: when #14333 replaced the FST terms index with a trie, its copy of
computeBlockStats()lost the one line that set this field. Nothing else writes it, so it keeps Java's default 0, althoughFieldReaderknows the trie's byte range. - Not a regression of a working number: since 8.6.0 the older block tree printed a fixed heap-accounting constant (56 bytes on 9.12.3 to 10.2.2 in these runs; JVM-dependent shallow object sizes) whatever the field's size. Nothing in Lucene reads the value back.
Anyone who reads block-tree statistics of an index written by 10.3.0 or later with the default codec: CheckIndex -verbose at -level 2 or 3 (the default level 1 skips them), or code calling Terms.getStats(). Every field with terms shows 0; no special input is needed. Nothing in Lucene reads the value, so search, indexing, merges and CheckIndex verdicts are unaffected.
Mechanism, terms and numbers511 words
The default terms dictionary since 10.3.0, the Lucene103 block tree, never assigns Stats.indexNumBytes, documented as "Byte size of the index". SegmentTermsEnum.computeBlockStats() creates the Stats object and walks the whole terms dictionary to fill the other counters, but never sets this one, so it keeps Java's default 0. Terms.getStats() therefore reports 0, and CheckIndex -verbose at level 2 or 3 prints index trie: / 0 bytes for every field that has terms, for example for a field of 10,000 ids whose trie takes 1,197 bytes of a 1,269-byte .tip file. FieldReader already holds the trie's byte range (indexStart, indexEnd). The line that set the field was dropped when #14333 copied the Lucene90 block tree to create the Lucene103 one. Nothing else reads the value, so this is a small diagnostic defect; and since 8.6.0 the older block tree printed a size-independent constant there, so it is not a regression of a working number.
// SegmentTermsEnum.java:87-91
/** Runs next() through the entire terms dict, computing aggregate statistics. */
public Stats computeBlockStats() throws IOException {
  Stats stats = new Stats(fr.parent.segment, fr.fieldInfo.name);   // indexNumBytes stays 0
  currentFrame = staticFrame;
... // fills the term and block counters- Contract:
Stats.java:34-35,/** Byte size of the index. */ public long indexNumBytes;, printed byStats.toStringunderindex trie:asN bytes(Stats.java:184-185).Statsis@lucene.internal(Stats.java:31). - Nobody writes it: in
lucene/core,lucene/backward-codecs,lucene/codecsandlucene/test-frameworksources the only write is in the old Lucene90 copy,backward_codecs/lucene90/blocktree/SegmentTermsEnum.java:124-127:if (fr.index != null) { stats.indexNumBytes = fr.index.ramBytesUsed(); }. - The size is known:
FieldReaderreadsindexStart,rootFPandindexEndfrom the terms metadata (FieldReader.java:80-82) and opens the trie as a slice ofindexEnd - indexStartbytes of.tip(:86-87).TrieBuilder.savewrites the nodes and 8 padding bytes ("additional 8 bytes for over-reading") to.tip, and recordsindexStart,rootFPandindexEndin the terms metadata file (TrieBuilder.java:263-268), so one term gives a 10-byte range. - Why the line went missing (a reading of the mechanics, not a stated intent): the Lucene103
FieldReaderhas no index object to callramBytesUsed()on; it builds aTrieReaderon demand. - Where it shows:
FieldReader.getStats()("For debugging -- used by CheckIndex too",FieldReader.java:110-114). CheckIndex stores each field'sStats(CheckIndex.java:2254-2259) and prints them only with verbose output (:2488-2493). It collects them intestPostings, which runs only at level >=MIN_LEVEL_FOR_INTEGRITY_CHECKS= 2 (:1114,:1125,:4754); the command-line default is level 1 (:4748).
| field | trie range (indexEnd - indexStart) | .tip file | indexNumBytes | with the fix |
|---|---|---|---|---|
one term a | 10 bytes | 82 bytes | 0 | 10 |
| 10,000 unique ids, 304 blocks | 1,197 bytes | 1,269 bytes | 0 | 1,197 |
CheckIndex at level 2 with verbose output prints index trie: / 0 bytes for both and reports the index clean; with the fix it prints 10 bytes and 1197 bytes.
Exposure and likelihood194 words
- Default: the default codec, an ordinary
IndexWriter; the smallest case is one document with one term. - Effect: one wrong number in debugging output. No wrong results, no index damage, no exception. CheckIndex's checks next to it recompute
sumDocFreqandsumTotalTermFreqthemselves (CheckIndex.java:2261-2281) and never read theStatsfields. Nor does the 0 hide a resident heap structure:FieldReaderkeeps only the trie's offsets (FieldReader.java:44-46) and builds aTrieReaderover anIndexInputslice of.tipon demand (:86-87); a terms enum allocates only small temporaryNodeobjects while it walks (TrieReader.java:78-82,SegmentTermsEnum.java:58,:177-186). Where the.tipbytes live is up to theDirectory(the repro'sByteBuffersDirectorykeeps them on the heap). - Scale: independent of the index: 0 for a 2-term field and for a 200,000-term field alike.
- People read this line: 2015-16 JIRA issues (now GitHub #8476 and #7254) paste CheckIndex output with real
index FST: N bytesvalues. - Likelihood: every such diagnostic run on a 10.3+ index shows the 0, but these are occasional debugging actions, nothing acts on the number, and nobody has reported it in the roughly 14 months since 10.3.0.
One JUnit test, public API only: one document with one StringField term, the default codec, ByteBuffersDirectory. It reads Terms.getStats() and expects indexNumBytes > 0. Deterministic, single thread, the same result with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene103.blocktree;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestStatsIndexNumBytes extends LuceneTestCase {

  public void testIndexNumBytesIsSet() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
        Document doc = new Document();
        doc.add(new StringField("f", "a", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        Stats stats = (Stats) reader.leaves().get(0).reader().terms("f").getStats();
        // expected: "Byte size of the index", the field's trie bytes in the .tip file (> 0); actual: 0
        assertTrue(
            "expected indexNumBytes > 0 but was " + stats.indexNumBytes, stats.indexNumBytes > 0);
      }
    }
  }
}
cp $REPRO/TestStatsIndexNumBytes.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene103/blocktree/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene103.blocktree.TestStatsIndexNumBytes -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same failure)
- Expected
getStats().indexNumBytes, the "Byte size of the index", is greater than 0: field f's trie takes 10 bytes of.tiphere.- Observed
AssertionError: expected indexNumBytes > 0 but was 0, with assertions on and off.
More files, environment, full output244 words
- Smallest input. One document, one term: the Lucene103 writer always saves the field's trie to
.tip(10 bytes here), and the test passes with the fix, so one term already shows the bug. - API. Public only:
IndexWriter,DirectoryReader,Terms.getStats()cast to the publicStatsclass. The packageorg.apache.lucene.codecs.lucene103.blocktreeis for locality; no package-private API is used. - Releases. The same test fails on the 10.6.0 release jars with assertions on and off; the hunt's earlier two-method test (10,000 ids, plus a CheckIndex check) failed on every release from 10.3.0 to 10.5.2.
- As the regression test: this same method. The closest upstream test,
testFinalBlockinTestLucene104PostingsFormat, already reads the sameStats. The repro's one comment line is 103 characters, socheckGoogleJavaFormatasks to wrap it (./gradlew tidydoes).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also fails on 10.6.0; 10.3.0 to 10.5.2 fail the hunt's test |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
cp $REPRO/TestStatsIndexNumBytes.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene103/blocktree/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene103.blocktree.TestStatsIndexNumBytes -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same failure)
# gradle, main 645d4fe14a20, seed DEADBEEF, assertions on
TestStatsIndexNumBytes > testIndexNumBytesIsSet FAILED
    java.lang.AssertionError: expected indexNumBytes > 0 but was 0
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:15DBA2BD6AD76884]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.codecs.lucene103.blocktree.TestStatsIndexNumBytes.testIndexNumBytesIsSet(TestStatsIndexNumBytes.java:43)
1 test completed, 1 failed
BUILD FAILED
# gradle, assertions off (-Ptests.asserts=false): the same AssertionError
# 10.6.0 release jars, assertions on and off: the same AssertionError
# with the recommended fix: BUILD SUCCESSFUL, 1 test, 0 failures (assertions on and off)- The javadoc says "Byte size of the index", and the output prints it as
index trie: N bytes. - The 4.0 block tree set it from the index's size; #14333 copied the code but dropped the assignment.
- In #13330 (2024) a reviewer caught the same removal in the older block tree, and the author put the assignment back before merge.
The full argument249 words
- Contract: "Byte size of the index" (
Stats.java:34) and the labelindex trie: N bytes(:184-185). The neighbouring counters are on-disk sizes:totalBlockSuffixBytes"Total number of bytes used to store term suffixes" (:73-74),totalBlockStatsBytes(:86-89),totalBlockOtherBytes(:92-95). - History of the field: the first block tree (LUCENE-3030, 4.0.0-alpha) set it with
stats.indexNumBytes = index.sizeInBytes(), and the block trees up to 10.2 kept an assignment (a probe reads non-zero values on 7.7.3 to 10.2.2). #14333 created the Lucene103 copy without it. - What it means: in a 2013 java-user thread ("Understanding FST Prefix & CheckIndex output") a user asked whether "index FST bytes" is the field's part of the
.tipfile, and Michael McCandless answered "Yes." - Precedent: in #13330 (2024) an earlier revision of the PR removed the same assignment from the then-core Lucene90 block tree; benwtrent asked in review whether that was wanted, and the PR's author, jpountz, put it back before merge, calling the removal "a leftover from a previous change". When LUCENE-6617 (2015) made the FST node and arc counts unavailable, the matching
Statsfields were removed rather than left at 0. - No sign of intent: no CHANGES or MIGRATE entry, test or code comment says 0 is intended, and no description, review or comment of #14333 or #14563 mentions
Stats,indexNumBytesorgetStats. The two upstream tests that read thisStatsclass,testFinalBlockinTestLucene104PostingsFormatand its copy in backward-codecsTestLucene103PostingsFormat, check block counts only.
The devil's-advocate check144 words
The strongest case for "intended": the Lucene90 value was FST.ramBytesUsed(), a heap figure, and the Lucene103 field reader keeps no resident trie on the heap (only its offsets; a terms enum allocates temporary nodes), so 0 could mean "no resident heap"; Stats is @lucene.internal and getStats() a debugging API; and the old number had been a meaningless constant for years. The cross-model reviews (OpenAI GPT-5.6) rated this intended-behaviour argument "moderate", and both still judged the bug real with high confidence.
Why it fails: the javadoc says "Byte size of the index", not heap; the 4.0 original measured the index size; the sibling counters are on-disk bytes; and a field that nobody assigns is not a measurement under any reading. The internal/debug status lowers the severity, not the correctness. The constant-before-10.3 point is real, so this is not a regression of a working number.
Recommended A. Set the field from the trie's byte range
In computeBlockStats(), add stats.indexNumBytes = fr.indexEnd - fr.indexStart;, the field's byte range in .tip (it includes 8 padding bytes). Validated with gradle: the test fails before and passes after, assertions on and off, and 212 codec, CheckIndex and terms tests run with 0 failures (8 skipped). Upstream may prefer excluding the padding or removing the field.
// SegmentTermsEnum.java:88-90
   public Stats computeBlockStats() throws IOException {
     Stats stats = new Stats(fr.parent.segment, fr.fieldInfo.name);
+    stats.indexNumBytes = fr.indexEnd - fr.indexStart;
All options and trade-offs4 options · 406 words
One fix was built and validated; the alternatives were not run.
One reasonable reading of "Byte size of the index": the field's part of the .tip file, exactly the slice FieldReader opens (FieldReader.java:86-87), from metadata the reader already holds.
// SegmentTermsEnum.java:88-90
   public Stats computeBlockStats() throws IOException {
     Stats stats = new Stats(fr.parent.segment, fr.fieldInfo.name);
+    stats.indexNumBytes = fr.indexEnd - fr.indexStart;
Trade-offs
- Includes the 8 padding bytes
TrieBuilder.savewrites (TrieBuilder.java:266), so one term reports 10 bytes. - The added line is O(1), though
getStats()itself still walks the whole terms dictionary; debugging output only, no hot path changes. - It turns the old heap-accounting figure into an on-disk extent. It fits the javadoc and the 2013 java-user answer, but maintainers may prefer B, a relabelled heading, or C.
- Lucene103-format segments only: Lucene90-format segments read through backward-codecs keep their old
ramBytesUsed()figure (see the aside).
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, OpenJDK 25.0.3, seed DEADBEEF: the minimal test fails before the change and passes after it, with assertions on and off. :lucene:core:testoverorg.apache.lucene.codecs.lucene103.*,org.apache.lucene.codecs.lucene104.*(incl.TestLucene104PostingsFormat),TestCheckIndex,TestTermsEnum*andTestTerms: 15 classes (including the new test), 212 tests, 8 skipped, 0 failures.:lucene:core:checkGoogleJavaFormatwith only the fix applied: clean.- A probe with the fix prints
index trie: 1197 bytesfor 10,000 ids and 10 bytes for one term; unfixed main prints 0 for both. - Earlier and independently: the hunt's fix check (2 of 2 pass),
TestLucene104PostingsFormatandTestCheckIndex(41 tests, 0 failures), and the cross-model reviewer's own test pass with it.
stats.indexNumBytes = fr.indexEnd - fr.indexStart - Long.BYTES; reports only the trie nodes (2 bytes for one term). Not run.
Trade-offs
More exact, but it ties Stats to a layout detail of TrieBuilder.save that could change.
As LUCENE-6617 did for the FST node and arc counts. Not run.
Trade-offs
Stats is @lucene.internal, so the API cost is small, but CheckIndex loses the one per-field terms-index size it prints.
The backward-codecs Lucene90 computeBlockStats could use fr.index.numBytes() (FST.java:506-508, the FST's serialized size) instead of ramBytesUsed(), which for an off-heap FST is a constant (FST.java:496-499, OffHeapFSTStore.java:46-47). Not run.
Trade-offs
Changes the output for 9.x-format segments; independent of fix A.
Any tool built on Lucene that shows CheckIndex verbose output or Terms.getStats() shows 0 bytes for every terms index; a read-only code search of three downstream search servers found no use of this field.
Non-formal. While building a file:line table of the Lucene103 block tree for a model, the finder grepped for writes to indexNumBytes and found only the declaration and the print. A public-API JUnit test then showed 0 on main, 10.5.2 and 10.3.0; verifiers and cross-model reviews confirmed it.
The method in full104 words
- First signal: code reading in the hunt unit on the Lucene103 block tree. A grep for writes to
indexNumBytesinlucene/corefound only the declaration and the read inStats.toString. No model produced or witnessed it, so the method is non-formal. - Repro: the finder's JUnit (10,000
StringFieldids in one segment,getStats()and CheckIndex verbose at level 2) failed 2 of 2 on main with assertions on and off, on 10.5.2 and on 10.3.0, and passed with the one-line fix. - Minimal repro (2026-10-29): cut to one document with one term and one test method; fails on main
645d4fe14a20with assertions on and off.
No prior report found (2026-10-26): GitHub issues, PRs and comments incl. the JIRA archive, commits, mailing lists, three downstream projects, the web, and all 413 open PRs' changed files. Nearest: #13330 (2024), where a reviewer caught the same removal in the older block tree and the author put the assignment back before merge.
Searches5 searches
The identifiers are narrow and easy to search (indexNumBytes, computeBlockStats, "index trie"). The scripted search ran 29 queries plus manual ones; web search returned generic pages only; private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and comments (apache/lucene incl. the migrated JIRA archive) | 2026-10-26 | two scripted search runs (15 and 11 GitHub queries) on indexNumBytes, computeBlockStats, getStats, blockTreeStats, "index trie", "index FST", "0 bytes" CheckIndex; manual searches for lines Stats.toString prints; 15 issues and PRs read in full | no report; #13330 is a precedent (same omission in the older block tree, caught in review) |
| Commits and JIRA | 2026-10-26 | 5 commit and 6 JIRA queries; git log -S indexNumBytes; LUCENE-6199 read | no commit fixes or discusses the gap |
| Mailing lists | 2026-10-26 | 25 queries over dev@, java-user@, issues@ and commits@ | no report; a 2013 java-user answer says the stat is the field's part of .tip |
| Open PRs | 2026-10-26 | the changed files of all 413 open apache/lucene PRs | none touches either Stats.java or assigns the field; #15556, #14894, #14716, #14494 touch nearby code |
| Downstream projects and the web | 2026-10-26 | three downstream search servers; 7 web queries | nothing relevant |
Introduced by #14333 (878e23f77390, 2025-04-14) and released through its backport #14563 in 10.3.0. Fails on every release from 10.3.0 to 10.6.0 and on main. 10.2.2 and older use the older block tree, which since 8.6.0 printed a size-independent constant. Not fixed upstream as of 2026-11-01.
Versions tested7 rows
Introduced by #14333, "A specialized Trie for Block Tree Index" (Guo Feng, gf2121), merged to main 2025-04-14 as 878e23f77390; it created codecs.lucene103.blocktree as a copy of the Lucene90 block tree. Released through the branch_10x backport #14563 (65fd8648eb63, 2025-05-09); git tag --contains lists exactly 10.3.0 to 10.6.0. No commit-level A/B was run: the release pair 10.2.2 (no Lucene103 package) / 10.3.0 (fails) and the single creating commit pin it.
Before 10.3 the older code stored FST.ramBytesUsed(), which is BASE_RAM_BYTES_USED + fstReader.ramBytesUsed() (FST.java:496-499); for an off-heap FST that is only fixed shallow object sizes, the FST's plus its OffHeapFSTStore's (OffHeapFSTStore.java:46-47): 24 + 32 = 56 bytes on 9.12.3 and 10.2.2. These constants depend on the JVM and platform (all runs: OpenJDK 25.0.3, Linux aarch64). On MMapDirectory the terms-index FST went off heap in 8.0.0 for non-primary-key fields (LUCENE-8635), in 8.1.0 also for ID-like fields such as the probe's two (docCount == sumDocFreq) when the reader is not opened from a writer (LUCENE-8671), and for every reader from 8.6.0 (LUCENE-9257). So the probe (MMapDirectory, a 20,000-term and a 1-term field) still tracked the sizes on 8.0.0 and reads the same value for both fields from 8.1.0 on. On 8.5.2 a heap-backed directory still tracked the size (65 vs 28,716 bytes).
Not fixed upstream (a snapshot): upstream main f815e679bf6 (2026-11-01) has no change in codecs/lucene103/blocktree/ since 645d4fe14a20.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (gradle and standalone); passes with fix A |
| 10.6.0 | affected | minimal test fails with assertions on and off (release jars) |
| 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 | affected | the hunt's test fails 2 of 2 (10.3.0 and 10.5.2 also with assertions off) |
| 9.12.3, 10.0.0, 10.2.2 | constant, not 0 | no Lucene103 block tree; the Lucene90 stats print 56 bytes for both probe fields (JVM-dependent shallow object sizes) |
| 8.1.0 to 9.0.0 (8.1.0, 8.2.0, 8.3.0, 8.4.0, 8.5.2, 8.6.0, 8.11.4, 9.0.0 run) | constant, not 0 | 88 (8.1.0-8.3.0), 72 (8.4.0-8.11.4 as run), 80 (9.0.0) for both probe fields |
| 7.7.3, 8.0.0 | not affected | tracks the index: 2843 / 57 and 2867 / 81 bytes (on-heap FST; 8.0.0 kept ID-like fields such as the probe's on heap) |
fix A on 645d4fe14a20 | not affected | 10 bytes for one term, 1,197 for 10,000 ids; 212 tests run, 0 failures (8 skipped) |
The finder's test, a cross-model refute review (OpenAI GPT-5.6, own test), an independent reproducer, a cross-model intended-behaviour review, a devil's-advocate verifier and the adjudication all call it real. This doc's gradle runs confirm the failure and the fix on main 645d4fe14a20, and the test fails on 10.6.0.
Checks and verdicts256 words
Each check ran its own test or probe; the adjudication re-ran two of them. The devil's-advocate verifier and the adjudication required the framing correction (the older number was a constant, so no regression claim).
| Check | Verdict | What it found |
|---|---|---|
| finder | fails 2 of 2 | 10,000 ids, getStats() and CheckIndex verbose: fails on main with assertions on and off, on 10.5.2 and 10.3.0; passes with the fix. |
| cross-model refute review | real, high | OpenAI GPT-5.6, executed: its own test (one document, 600 repeated StringFields) shows a 90-byte trie reported as 0 and CheckIndex printing 0; passes with the fix. |
| Independent reproducer | real | Own JUnit: 20,000 terms, 607 blocks, a 2,473-byte .tip, indexNumBytes = 0 on main, 10.5.2 and 10.3.0; 56 for both a large and a 1-term field on 10.2.2 and 9.12.3. |
| Cross-model intended lens | real, high | OpenAI GPT-5.6: its own test printed serializedTrieBytes=509 indexNumBytes=0 totalBlockCount=125; heap argument rated moderate. |
| Devil's advocate | real, framing corrected | Found the 4.0 sizeInBytes() origin and the pre-10.3 constants; required dropping any regression claim. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test (assertions on and off) and the finder's: 2 of 2 fail each time. |
| re-runs and minimal repro | still reproduces | Main a9779ef3c193 (2026-10-26); the minimal test on 645d4fe14a20 (2026-10-29), 5 of 5 failures with a random seed. |
| this doc | fails before, passes after | Gradle before and after fix A, assertions on and off; 15 classes, 212 tests with the fix; numbers probe; 10.6.0 release jars. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 408 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,251 words
- Registry title
- Lucene103 block tree never sets Stats.indexNumBytes, so Terms.getStats() and CheckIndex -verbose print 'index trie: 0 bytes' for every field
- Area
- codecs / block-tree terms dictionary (Lucene103 Stats, CheckIndex verbose statistics)
- Priority
- Low, rank 1212: The Lucene103 block tree never sets indexNumBytes, so CheckIndex -verbose prints 0 bytes for every terms index, diagnostic only.
- Impact class
- minor
- Impact note
- Diagnostic only: anyone who runs CheckIndex -verbose at level 2 or more, or calls the expert debugging API Terms.getStats(), on an index written with the default codec since 10.3.0 gets a 0-byte terms-index figure for every field; no indexing, search, merge or CheckIndex verdict reads the value, and no scale or special input is needed.
- Summary
- You run CheckIndex -verbose at level 2 or more (or call Terms.getStats()) on an index written with the default codec and expect each field's block-tree statistics to say how many bytes its terms index takes, as the field's javadoc 'Byte size of the index' and the printed label 'index trie: N bytes' promise. Since 10.3.0 the Lucene103 block tree never assigns Stats.indexNumBytes, so every field prints 'index trie: 0 bytes', even a 20,000-term field with 607 blocks in a segment whose .tip file is 2,473 bytes. Nothing else reads the number, so search and indexing are unaffected, and the older Lucene90 block tree had already stopped reporting the real size (a constant such as 56 bytes since 8.6.0), so this is a small diagnostic defect, not a regression of a working metric.
- Introduced
- 878e23f77390058b6787e0a0537de9087d1019b3 on main (PR #14333 'A specialized Trie for Block Tree Index', author gf2121), which created codecs.lucene103.blocktree by copying the Lucene90 block tree; its copy of SegmentTermsEnum.computeBlockStats() drops the 'if (fr.index != null) { stats.indexNumBytes = fr.index.ramBytesUsed(); }' block and nothing else assigns the field, while the same commit relabels Stats.toString from 'index FST:' to 'index trie:'. The released code came from the branch_10x backport 65fd8648eb633b90ca7f7b69bbae39b373ddaa16 (#14563), with identical computeBlockStats and Stats [read: diff of computeBlockStats across 878e23f77390, git show at the backport and at the 10.3.0 and 10.5.2 tags; exec: the release pair 10.2.2 (package absent) / 10.3.0 (fails) pins it; no commit-level A/B, because 878e23f77390 is in no release] (2025-04-14 on main (878e23f77390); 2025-05-09 on branch_10x (65fd8648eb63), the commit that reached a release)
- First affected version
- 10.3.0 [exec]; 10.2.2 is the last release without the Lucene103 block tree [exec]
- Affected versions
- 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed [exec: both tests fail on each, with -ea, and also with -da on 10.3.0, 10.5.2 and main]; 10.6.0 (released 2026-10-29) [exec: the minimal test fails on the release jars with -ea and -da]. Not affected in the always-0 form: 10.2.2 and older, which use the Lucene90 block tree (the test cannot compile there; a version-spanning probe reads non-zero values) [exec]. Caveat [exec + read]: the older value was not the index size either. The Lucene90 code stores FST.ramBytesUsed(), and an off-heap FST reports only its shallow size, so the probe (MMapDirectory, reader opened from the directory) reads a size-independent constant per field: 88 bytes on 8.1.0-8.3.0, 72 on 8.4.0-8.11.4, 80 on 9.0.0 and 56 on 9.12.3, 10.0.0 and 10.2.2; it tracked the size on 7.7.3 and 8.0.0, and on 8.5.2 only with a heap-backed directory (the intended-behaviour check: 65 vs 28,716 bytes on ByteBuffersDirectory), because the FST is always off-heap only from 8.6.0 (LUCENE-9257)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26: scripted searches with 29 queries (15 GitHub issue/PR including comments, 2 commit, 9 mailing-list over dev@, java-user@ and issues@, 3 JIRA; 91 distinct hits, 0 high, every medium hit read); the intended-behaviour check's scripted searches (33 queries including commits@, 122 hits, 0 high); 7 manual GitHub searches including Elasticsearch, OpenSearch and Solr; direct reads of 15 issues and PRs, a 2013 java-user thread and JIRA LUCENE-6199; the changed files of all 413 open apache/lucene PRs; git history; 7 web queries): no issue, PR, review comment, list post, JIRA entry or downstream item reports the 0 or the older constant; not fixed: no open PR touches either Stats.java or assigns indexNumBytes (#15556, #14894, #14716 and #14494 touch the lucene103 SegmentTermsEnum or FieldReader elsewhere); related, not reports of this bug: #13330 (2024; its first version deleted the same assignment from the then-core Lucene90 computeBlockStats, benwtrent asked about it in review and jpountz restored it before merge, calling the removal 'a leftover from a previous change': precedent that maintainers treat an unassigned indexNumBytes as a mistake), the 2013 java-user thread 'Understanding FST Prefix & CheckIndex output' (mikemccand confirms that 'index FST bytes' is the field's part of the .tip file: intent), #14333 and #14563 (the introducing change and its backport; no discussion of Stats), #9681 (LUCENE-8635) and #10297 (LUCENE-9257), which made off-heap FST ramBytesUsed() shallow and off-heap the only mode (the cause of the older constant; neither discusses Stats); gaps: web search returned generic pages only, and private reports to security@lucene.apache.org are not visible
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test through gradle with assertions on and off, before and after the recommended fix, in a scratch worktree, plus 15 codec, CheckIndex and terms test classes with the fix and a numbers probe before and after it (2026-11-01); the minimal test standalone on main (2026-10-29) and on the 10.6.0 release jars (2026-11-01), assertions on and off; the hunt's two-method test on mainea57360912edanda9779ef3c193and on all 7 releases 10.3.0 to 10.5.2; a version probe on 7.7.3 to 10.2.2.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Stats.java:28-31 (@lucene.internal), :34-35 ('/** Byte size of the index. */ public long indexNumBytes;'), :184-185 (toString prints 'index trie:' and 'N bytes')lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/SegmentTermsEnum.java:87-89 (computeBlockStats creates Stats and never assigns indexNumBytes)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/FieldReader.java:80-82 (indexStart, rootFP, indexEnd read from the terms metadata), :86-87 (the trie is an IndexInput slice of indexEnd - indexStart bytes), :110-113 (getStats, 'For debugging -- used by CheckIndex too')lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:2254-2259 (getStats result stored in Status.blockTreeStats), :2488-2492 (printed only with verbose output), :4748 (CLI default level 1) and :4754 (MIN_LEVEL_FOR_INTEGRITY_CHECKS = 2, needed for the postings check that collects the stats); lucene/core/src/java/org/apache/lucene/index/Terms.java:215-216 ('Expert: returns additional information about this Terms instance for debugging purposes')lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene90/blocktree/SegmentTermsEnum.java:126 ('stats.indexNumBytes = fr.index.ramBytesUsed();', the only write to the field in the tree)a Lucene clone tag releases/lucene/10.3.0 (release commit e2871287e4a, dated 2025-09-05)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/SegmentTermsEnum.java:87-91 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Stats.java:28-35, :184-185 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/FieldReader.java:44-46, :80-87, :110-114 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/TrieBuilder.java:263-268 (at 645d4fe14a20)lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene90/blocktree/SegmentTermsEnum.java:121-127 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1114, :1125, :2254-2259, :2488-2493, :4742, :4748, :4754 (at 645d4fe14a20)
- Who is affected
lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:2254-2281, :2488-2493 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/FieldReader.java:86-87 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/FieldReader.java:44-46; TrieReader.java:78-82; SegmentTermsEnum.java:58, :177-186 (at 645d4fe14a20)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Stats.java:34-35, :73-95, :184-185 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/codecs/lucene104/TestLucene104PostingsFormat.java:78-101 (testFinalBlock) (at 645d4fe14a20)lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene103/TestLucene103PostingsFormat.java:79-101 (testFinalBlock) (at 645d4fe14a20)
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/TrieBuilder.java:263-268; FieldReader.java:86-87 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/util/fst/FST.java:496-508; OffHeapFSTStore.java:32-33, :46-47 (at 645d4fe14a20)
- History
a Lucene clone (git tag --contains 65fd8648eb63; CHANGES.txt at releases/lucene-solr/8.0.0, 8.1.0, 8.6.0: LUCENE-8635, LUCENE-8671, LUCENE-9257; codecs/blocktree/FieldReader.java at 8.0.0 and 8.1.0)lucene/core/src/java/org/apache/lucene/util/fst/FST.java:496-499; OffHeapFSTStore.java:46-47 (at 645d4fe14a20)
- Diagrams
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/TrieBuilder.java:263-268; FieldReader.java:80-87; SegmentTermsEnum.java:87-89 (at 645d4fe14a20)
- TestStatsIndexNumBytes.java:
repro/LFV-162/src/org/apache/lucene/codecs/lucene103/blocktree/TestStatsIndexNumBytes.java(48 lines)
assets/LFV-162/bug.png(408 KB)