- With
IndexWriterConfig.setIndexSort, each flushed segment is written in sort order, so at flushIndexWriterre-orders the buffered doc values and norms before handing them to the codec's consumer (when the documents arrived already sorted, nothing is re-ordered and the defective iterator is not used). - The consumer reads each field through an iterator:
nextDoc()walks the documents that have a value, one by one, and returnsNO_MORE_DOCS(2147483647) after the last one. intoBitSet(upTo, bits, offset)is the bulk shortcut: it marks every remaining document belowupToin one call, and its javadoc says it "should behave exactly as" thatnextDoc()loop, which implies the same end position.
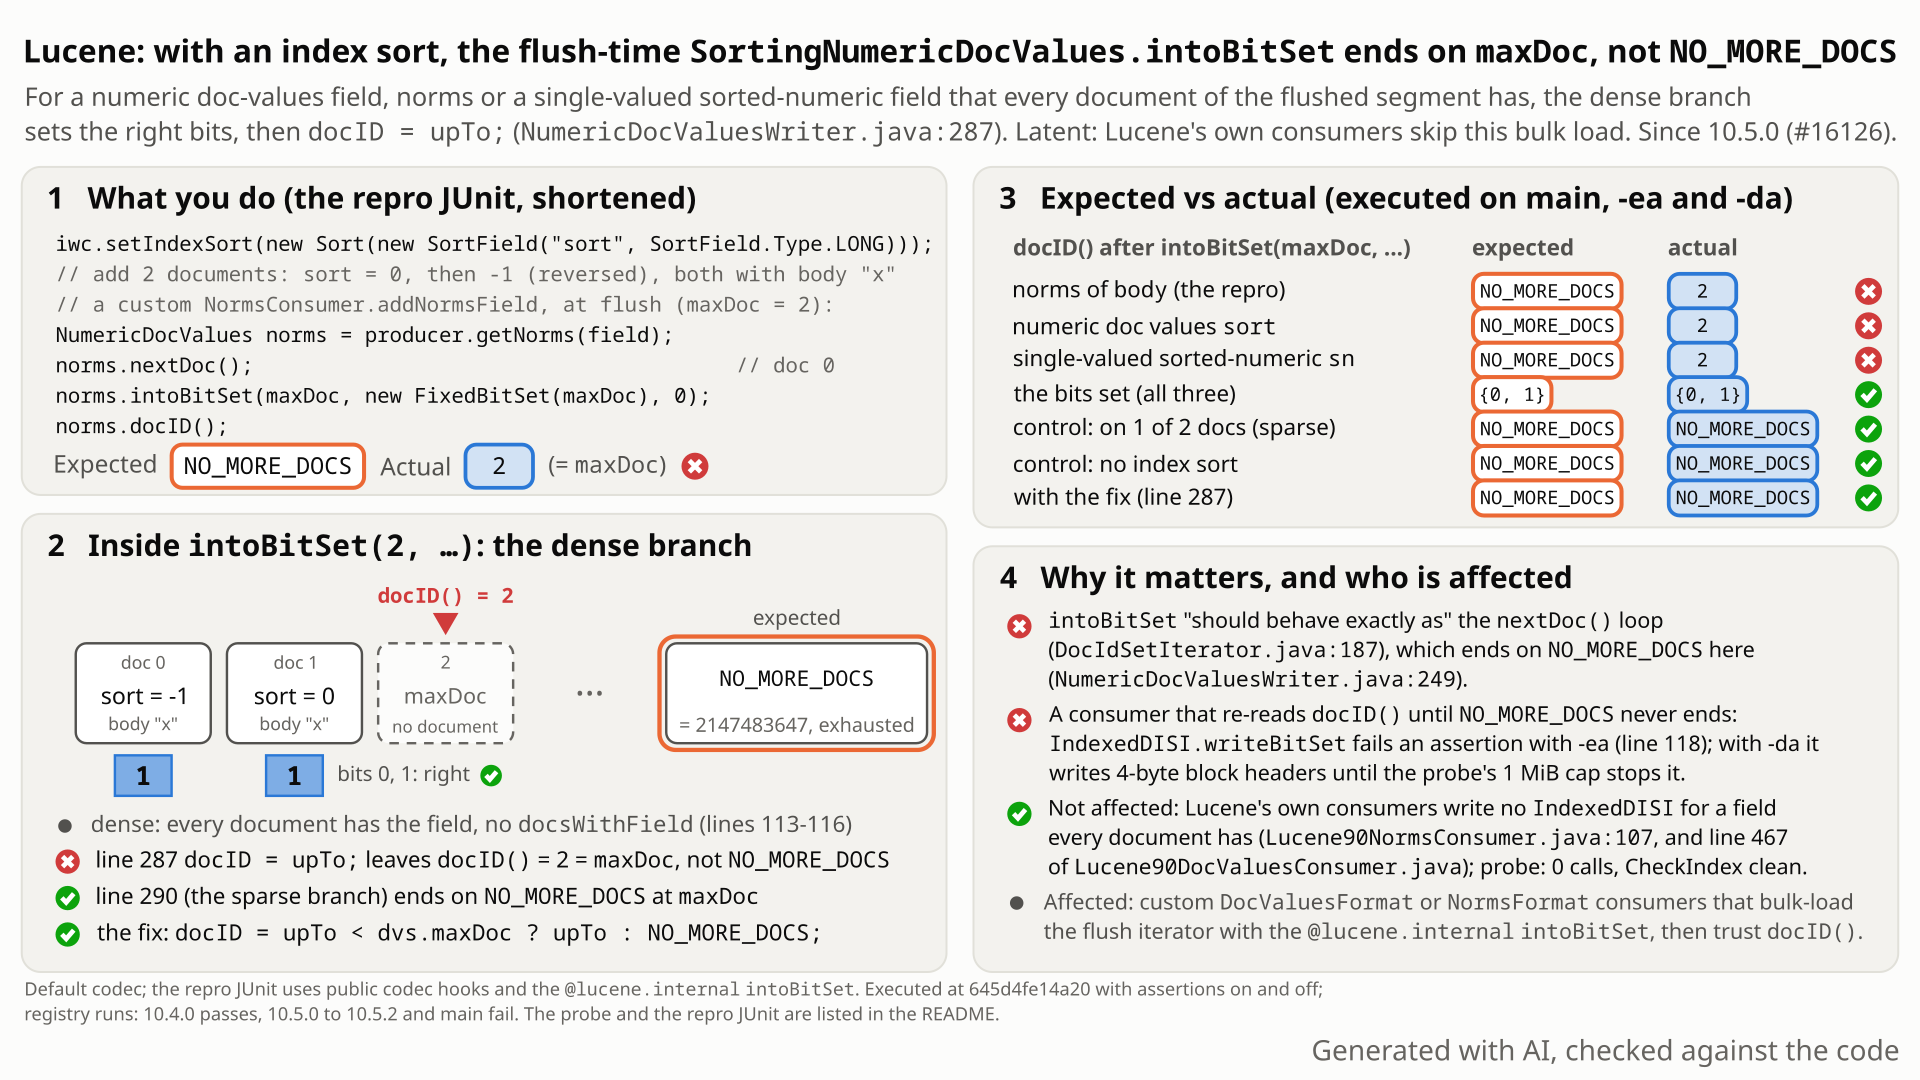
nextDoc() loop visits docs 0 and 1 and ends on NO_MORE_DOCS; intoBitSet(2) sets the same two bits but stops on 2 (maxDoc), so a consumer that re-reads docID() until NO_MORE_DOCS never ends. Select the still to open it at full size. Generated with AI, checked against the code.- Set an index sort and add 2 documents, each with a sort value (0 and -1, so the flush reorders them) and a text field
body, so both documents have norms. - At flush,
IndexWriterhands your codec's norms consumer an iterator over those norms. The consumer callsnextDoc()(doc 0), thenintoBitSet(2, bits, 0)to load every document in one call. - You expect bits 0 and 1 set and the iterator finished:
docID()returnsNO_MORE_DOCS(2147483647), where the referencenextDoc()loop in theintoBitSetjavadoc ends. - Instead the bits are right but
docID()returns 2, the segment'smaxDoc, which is not a document. A consumer that re-readsdocID()untilNO_MORE_DOCSnever ends:IndexedDISI.writeBitSetfed this iterator fails an assertion, or with assertions off writes empty block headers without end. - Lucene's own doc-values and norms formats skip the bulk load when every document has the field, so default indexes are not affected. Numeric doc values and single-valued sorted-numeric fields share the same iterator.
Only code that plugs a custom DocValuesFormat or NormsFormat into an index-sorted IndexWriter and bulk-loads the flush-time iterator of a field every document has, when the flush reorders the documents. A consumer like IndexedDISI.writeBitSet then hangs or fails the flush; other consumer shapes were not tested. Default codecs (in the tested paths), search results and existing indexes are not affected.
Mechanism, terms and numbers581 words
When an index sort is set and the flush actually reorders the documents, IndexWriter re-orders each numeric doc-values field and the norms at flush and hands the codec's consumer a NumericDocValuesWriter.SortingNumericDocValues iterator (already-sorted input gets an unsorted iterator). If every document of the segment has the field, that iterator's intoBitSet(upTo, bitSet, offset) with upTo >= maxDoc sets the right bits but leaves docID() at maxDoc (2 for a 2-document segment) instead of NO_MORE_DOCS. The intoBitSet javadoc says the method "should behave exactly as" the docID()/nextDoc() loop, which ends on NO_MORE_DOCS here, and the sparse branch of the same method does end there. A consumer that re-reads docID() until NO_MORE_DOCS never ends, as IndexedDISI.writeBitSet does. Lucene's own consumers skip the bulk load for such fields, so default indexes are unaffected; a custom codec that bulk-loads the flush-time iterator is. Introduced by #16126 in 10.5.0; one line fixes it.
- The dense flag. At flush with an index sort,
NumericDocValuesWriter.getDocValuesProducercallssortDocValues(..., sortMap.size() == docsWithField.cardinality())(NumericDocValuesWriter.java:150-155); norms do the same (NormValuesWriter.java:74-80). The flag is true exactly when every document has a value, and thensortDocValueskeepsdocsWithField = null(:113-116), the dense representation from #12381 (9.8.0). - The iterator. The consumer gets
new SortingNumericDocValues(sorted)(NumericDocValuesWriter.java:169; normsNormValuesWriter.java:95). A single-valuedSortedNumericDocValuesFieldgets the same producer wrapped inDocValues.singleton(SortedNumericDocValuesWriter.java:215-226). - Its
nextDoc()returnsNO_MORE_DOCSoncedocID + 1 == maxDoc(:247-254). - Its
intoBitSet(:281-293, added by #16126) clampsupTotomaxDoc(:283). The dense branch sets the bits and thendocID = upTo;(:287), which ismaxDocwhenever the caller asked formaxDocor more. The sparse branch of the same method maps that case toNO_MORE_DOCS:docID = upTo < dvs.maxDoc ? dvs.advance(upTo) : NO_MORE_DOCS; // set the current doc(:290). - The contract.
DocIdSetIterator#intoBitSet"should behave exactly as if implemented as"for (int doc = docID(); doc < upTo; doc = nextDoc()) bitSet.set(doc - offset);(DocIdSetIterator.java:187-195), which ends onNO_MORE_DOCShere;docID()may only be -1, the current document orNO_MORE_DOCS(:113-124). The method is@lucene.internal(:203).
The bits are right in every run; only the position is wrong. IndexedDISI.writeBitSet loops for (doc = it.nextDoc(); doc != NO_MORE_DOCS; doc = it.docID()) with one intoBitSet per 65,536-document block (IndexedDISI.java:210-213). After the first block the position is maxDoc, so the next intoBitSet sets nothing, and the empty block trips assert cardinality > 0 (IndexedDISI.java:118); with assertions off it writes a 4-byte block header (:117, :119) and loops again without end (the hunt's test stopped it at 1 MiB). That spin comes from re-reading docID(); by reading only, a consumer that calls nextDoc() and longValue() instead would get maxDoc + 1 and index past the values array (NumericDocValuesWriter.java:247-254, :269-270). Other consumer shapes were not tested.
Lucene90DocValuesConsumer writes no IndexedDISI when numDocsWithValue == maxDoc (Lucene90DocValuesConsumer.java:467, before writeDISI at :474), Lucene90NormsConsumer likewise (Lucene90NormsConsumer.java:107, before IndexedDISI.writeBitSet at :117), and SortingCodecReader always builds a non-null docsWithField (SortingCodecReader.java:793-804), so merges never take the dense branch. An executed probe saw 0 intoBitSet calls on dense fields across index-sorted flushes of 1, 2, 3, 100 and 65,543 documents, a sorted forceMerge and addIndexes of a SortingCodecReader, with a clean CheckIndex.
Exposure and likelihood260 words
- Who is hit. An application or library whose custom doc-values or norms consumer (plugged in through
FilterCodec,PerFieldDocValuesFormator its own codec;DocValuesFormat,DocValuesConsumerandNormsConsumerare@lucene.experimental) callsintoBitSetup tomaxDocorNO_MORE_DOCSon the flush-time iterator, directly or through the@lucene.internalIndexedDISI.writeBitSet, and then readsdocID(), for a numeric doc-values, single-valued sorted-numeric or norms field that every document of an index-sorted segment has. - Default vs opt-in. Opt-in: in the tested stock paths nothing observable changes, and the index, values, norms and sort order are correct; by reading, the current
Lucene90doc-values and norms consumers (and the backward-codecsLucene80DocValuesConsumer) skip the docs-with-field encoding for a field every document has. - Scale. None needed: 2 documents are enough, and a field present on every document is the ordinary case, so a consumer shaped like
IndexedDISI.writeBitSetfails at the first index-sorted flush that reorders such a field. - How it shows. It depends on the consumer. In the executed case,
IndexedDISI.writeBitSet(which re-readsdocID()untilNO_MORE_DOCS) fails the flush with anAssertionErroror writes until the output fails: no wrong match and no committed segment. Other consumer shapes were not tested; by reading, one that callsnextDoc()andlongValue()would fail out of bounds instead. - Why fix it anyway. #16126 added these overrides as an optimization (CHANGES "Optimizations"), for callers that bulk-load; the dense case is the common one for such a caller, and the sparse branch next to it already ends correctly. The fix is one line and adds one comparison per bulk call.
One JUnit test on public classes (it calls the publicly callable but @lucene.internal intoBitSet directly): an index-sorted IndexWriter with a FilterCodec whose norms consumer calls intoBitSet(maxDoc) on the flush-time iterator of a field both documents have, records docID(), then delegates. Two documents, deterministic, the same result with assertions on or off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.codecs.FilterCodec;
import org.apache.lucene.codecs.NormsConsumer;
import org.apache.lucene.codecs.NormsFormat;
import org.apache.lucene.codecs.NormsProducer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.TextField;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.FixedBitSet;

public class TestSortedFlushIntoBitSetEndPosition extends LuceneTestCase {

  public void testIntoBitSetUpToMaxDocEndsOnNoMoreDocs() throws IOException {
    int[] docIDAfter = {-1};
    FilterCodec codec =
        new FilterCodec(TestUtil.getDefaultCodec().getName(), TestUtil.getDefaultCodec()) {
          @Override
          public NormsFormat normsFormat() {
            NormsFormat in = delegate.normsFormat();
            return new NormsFormat() {
              @Override
              public NormsConsumer normsConsumer(SegmentWriteState state) throws IOException {
                NormsConsumer consumer = in.normsConsumer(state);
                int maxDoc = state.segmentInfo.maxDoc();
                return new NormsConsumer() {
                  @Override
                  public void addNormsField(FieldInfo field, NormsProducer producer)
                      throws IOException {
                    NumericDocValues norms = producer.getNorms(field);
                    norms.nextDoc();
                    norms.intoBitSet(maxDoc, new FixedBitSet(maxDoc), 0);
                    docIDAfter[0] = norms.docID();
                    consumer.addNormsField(field, producer);
                  }

                  @Override
                  public void close() throws IOException {
                    consumer.close();
                  }
                };
              }

              @Override
              public NormsProducer normsProducer(SegmentReadState state) throws IOException {
                return in.normsProducer(state);
              }
            };
          }
        };
    IndexWriterConfig iwc =
        new IndexWriterConfig()
            .setCodec(codec)
            .setIndexSort(new Sort(new SortField("sort", SortField.Type.LONG)));
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      for (int i = 0; i < 2; i++) {
        Document doc = new Document();
        doc.add(new NumericDocValuesField("sort", -i));
        doc.add(new TextField("body", "x", Field.Store.NO));
        w.addDocument(doc);
      }
      w.commit();
    }
    // Expected: intoBitSet(maxDoc) over every doc ends on NO_MORE_DOCS; actual: docID() == maxDoc.
    assertEquals("docID() after intoBitSet(maxDoc)", DocIdSetIterator.NO_MORE_DOCS, docIDAfter[0]);
  }
}
cp $REPRO/TestSortedFlushIntoBitSetEndPosition.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.index.TestSortedFlushIntoBitSetEndPosition -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off: -Ptests.asserts=false instead (same result)
- Expected
- After
intoBitSet(2, ...)on the 2-document segment,docID()isNO_MORE_DOCS(2147483647), where thenextDoc()loop ends. - Observed
docID()is 2, the segment'smaxDoc:expected:<2147483647> but was:<2>, with assertions on and off, on main and 10.6.0.
More files, environment, full output363 words
One test class, one method, in org.apache.lucene.index (package for locality only). Public classes, but not only supported API: IndexWriterConfig.setIndexSort, FilterCodec, NormsFormat/NormsConsumer (the codec classes are @lucene.experimental), ByteBuffersDirectory, and a direct call of DocIdSetIterator#intoBitSet, which is publicly callable but tagged @lucene.internal (DocIdSetIterator.java:203); that is the main reason the cross-model reviews rated it out of contract. The probe sits in a norms consumer because NormsConsumer has only two methods to delegate; norms flush through the same SortingNumericDocValues as numeric doc values. The sort values are 0 and -1 so that the flush really sorts (already-sorted input takes the unsorted path). The bits are not asserted: they are correct, and only the end position is claimed.
Not shown by this test, which covers the norms path only; executed elsewhere: the numeric doc-values and single-valued sorted-numeric paths, upTo = NO_MORE_DOCS, and the IndexedDISI.writeBitSet runaway (the hunt's 5-test class on a 100-document segment: but was:<100> for doc values, for upTo = NO_MORE_DOCS and for norms, and writeBitSet fails with AssertionError, or with assertions off passes 1 MiB of output; the independent reproducer's 12-test class: docID() = 100 for the single-valued sorted-numeric path). The one test is the repro and, unchanged, the suggested regression test.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT) and 10.6.0: fails; 10.4.0: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
# gradle on main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (=false gives the same)
TestSortedFlushIntoBitSetEndPosition > testIntoBitSetUpToMaxDocEndsOnNoMoreDocs FAILED
    java.lang.AssertionError: docID() after intoBitSet(maxDoc) expected:<2147483647> but was:<2>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:9CB77348D7A246]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.index.TestSortedFlushIntoBitSetEndPosition.testIntoBitSetUpToMaxDocEndsOnNoMoreDocs(TestSortedFlushIntoBitSetEndPosition.java:91)
1 test completed, 1 failed

# the same test on the 10.6.0 release jars (assertions on and off): expected:<2147483647> but was:<2>
# the same test on the 10.4.0 release jars: passes

# the hunt's 5-test class on a 100-document segment (main ea57360912ed; not part of the repro)
testSortedDenseDocValuesUpToMaxDoc     => dv:sort: docID() after intoBitSet(100) over every doc expected:<2147483647> but was:<100>
testSortedDenseDocValuesUpToNoMoreDocs => dv:sort: docID() after intoBitSet(2147483647) over every doc expected:<2147483647> but was:<100>
testSortedDenseNorms                   => norms:body: docID() after intoBitSet(100) over every doc expected:<2147483647> but was:<100>
testWriteBitSetOnSortedDenseField      -ea: writeBitSet failed: java.lang.AssertionError
                                       -da: writeBitSet failed: java.lang.IllegalStateException: runaway output: more than 1048576 bytes written
(testUnsortedDenseControl passes)- The
intoBitSetjavadoc says it "should behave exactly as" thenextDoc()loop, which ends onNO_MORE_DOCShere;docID()has no "one past the last document" state. - The sparse branch of the same method, from the same commit, ends on
NO_MORE_DOCSfor the same call. - Lucene's test framework checks the position after
intoBitSet; 10.4.0, using the default loop, passes the repro.
The full argument258 words
- The contract.
DocIdSetIterator#intoBitSet"should behave exactly as if implemented as" thedocID()/nextDoc()loop (DocIdSetIterator.java:187-195);docID()returns -1,NO_MORE_DOCSor "the doc ID it is currently on" (:113-124). The call meets both stated preconditions: the iterator is positioned, andoffset(0) is not greater thandocID()(:196-197). - The same method. The sparse branch, written in the same commit, ends on
NO_MORE_DOCS(NumericDocValuesWriter.java:290, "set the current doc"), and the class'snextDoc()ends there too (:247-254). - Tests.
BaseDocIdSetTestCasechecks "if docID() / nextDoc() return the same value after #intoBitSet has been called" (BaseDocIdSetTestCase.java:222), andBaseDocValuesFormatTestCaseassertsexpected.docID() == values.docID()afterintoBitSet(BaseDocValuesFormatTestCase.java:1085-1089). No test covers the writer-side iterators: #16126 added none. - History. From 10.2.0 to 10.4.0 the class inherited the default loop and ended on
NO_MORE_DOCS(10.4.0 passes the repro). The #16126 PR body describes the change as "mostly iterators wrapping other iterators so we just delegate the method"; this method is not a delegation. The PR had one approval, no comments and no follow-up. - Precedent (it shows maintainers fix such edge cases; it does not settle this one). Lucene fixed other
intoBitSetedge cases as bugs: #14922 (IndexedDISI, CHANGES 10.3.0 "Bug Fixes"), #16250/#16252 (RoaringDocIdSet, CHANGES 10.5.0 "Bug Fixes") and #16105 (BatchDocValuesRangeIterator, a public class, an end state at themaxDocboundary). Those were reachable from Lucene's own code or from search; this one is a flush-time state no in-tree caller reaches, so a maintainer may weigh it differently.
The devil's-advocate check184 words
The strongest case for "works as designed" came from the cross-model reviews (OpenAI GPT-5.6): intoBitSet is @lucene.internal ("This API is for internal purposes only and might change in incompatible ways in the next release"), IndexedDISI is @lucene.internal, the consumer APIs are @lucene.experimental, and the stock consumers deliberately encode a field present on every document without a docs-with-field bitset, so the wrong end state is unobservable in supported use; a codec that relies on an internal bulk hook is outside the contract.
Why it does not make the position correct (though it may well decide how a maintainer triages the report): @lucene.internal limits API stability, not the behaviour the method's own javadoc states, and #16126 added this override as an optimization for callers that bulk-load. The same reviewer wrote that its argument "does not establish that maxDoc itself was a deliberate semantic choice" and that the assignment "is an oversight suitable for low-risk internal hardening". The scope argument correctly lowers the severity (latent, minor); it does not make the position right. Verdict: a real, latent defect; no in-tree consumer reaches the branch.
Recommended A. End the dense branch on NO_MORE_DOCS when the call reached maxDoc
End the dense branch the way the sparse branch already does: docID = upTo < dvs.maxDoc ? upTo : NO_MORE_DOCS; in SortingNumericDocValues#intoBitSet. One line; it fixes numeric doc values, norms and single-valued sorted-numeric at once. The repro then passes with assertions on and off, and the closest core suites pass.
       if (upTo > docID) {
         if (dvs.docsWithField == null) {
           bitSet.set(docID - offset, upTo - offset);
-          docID = upTo;
+          docID = upTo < dvs.maxDoc ? upTo : NO_MORE_DOCS;
         } else {
All options and trade-offs3 options · 481 words
Fixes A and B were run through gradle in a scratch worktree of 645d4fe14a20. A is recommended: the smallest change, the one the finder, the independent reproducer, the adjudication and the cross-model reviews ran, and it mirrors the sparse branch next to it.
A. End the dense branch on NO_MORE_DOCS when the call reached maxDoc (validated by the checks) (recommended)
One line at NumericDocValuesWriter.java:287. After the clamp, upTo == maxDoc means the last document was consumed, which is where nextDoc() returns NO_MORE_DOCS; for upTo < maxDoc the dense position stays upTo.
       if (upTo > docID) {
         if (dvs.docsWithField == null) {
           bitSet.set(docID - offset, upTo - offset);
-          docID = upTo;
+          docID = upTo < dvs.maxDoc ? upTo : NO_MORE_DOCS;
         } else {
Trade-offs
- Fixes all three paths at once (numeric doc values, norms, single-valued sorted-numeric), since they share the class.
- Cost: one comparison per bulk call (not benchmarked); no change for
upTo < maxDocor for the sparse branch.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(2026-11-01): the repro fails on stock main and passes with A, each with-Ptests.asserts=trueand=false. - With A: 10 core test classes, 470 tests, 0 failures, 35 skipped (34
@Nightly, 1 assumption): the repro,TestIndexSorting,TestSortingCodecReader,TestNorms,TestCustomNorms,TestDocValuesIndexing,TestDocValues,TestLucene90DocValuesFormat,TestLucene90DocValuesFormatVariableSkipIntervalandTestLucene90NormsFormat. - With A and the test in place,
:lucene:core:check -x testpasses (google-java-format, ecj lint, forbidden APIs). The full core suite was not run. - Earlier, the same change: the hunt's 5 tests pass (assertions on) and the independent 12 tests pass (assertions on and off); a reviewer's runs of 10
TestLucene90DocValuesFormatintoBitSettests and 8TestLucene90NormsFormatsparse tests pass.
Drop the assignment from both branches and end with docID = upTo < dvs.maxDoc ? dvs.advance(upTo) : NO_MORE_DOCS;, which also works for the dense case because NumericDVs.advance(target) returns target when docsWithField == null (:318-325).
Trade-offs
- Same behaviour as A, with one rule for both branches so they cannot drift apart again.
- Touches the sparse branch too (a slightly larger diff to review).
What the checks validated
- Gradle, same worktree: the repro passes with B with
-Ptests.asserts=trueand=false; the repro plusTestIndexSorting: 2 classes, 63 tests, 0 failures. - Not run with the other suites or the static checks.
For example let IndexedDISI.writeBitSet treat docID() >= maxDoc as the end.
Trade-offs
Keeps this iterator out of line with the intoBitSet and docID() contracts that the default implementation and the sparse branch follow; hardening one consumer without fixing the iterator leaves other consumers exposed. A maintainer could still reasonably harden the in-tree consumer as well, or decline the report because no in-tree caller reaches the branch.
A custom doc-values or norms format that bulk-loads the flush-time iterator of an index-sorted segment should treat docID() >= maxDoc as the end after intoBitSet until a fix ships; Lucene's own formats need no change.
Non-formal: code reading. While modelling the input contract of IndexedDISI.writeBitSet in a Z3 model, the finder read the iterators that feed it and noticed the dense branch's end position; the model records the consequence but gave no counterexample for this bug. A JUnit test on the stock jars then confirmed it, and independent checkers reproduced it.
The method in full148 words
Method: non-formal (code reading). A hunt unit on IndexedDISI and doc-values bulk iteration wrote a Z3 bit-vector model of IndexedDISI's arithmetic (38 obligations, 0 unexpected). One obligation records what happens when a source iterator's intoBitSet does not move past upTo: writeBitSet then flushes a block of cardinality 0. Reading the iterators that can feed writeBitSet, the finder found that SortingNumericDocValues does exactly that in its dense branch. No tool output gave the first signal, so the find is classed as non-formal.
The finder then wrote a JUnit test with a real index-sorted IndexWriter flush through a FilterCodec on the stock main jars (5 tests, 4 failing with assertions on and off, the unsorted control passing). It was reviewed by a reviewer from another model family (OpenAI GPT-5.6), reproduced independently (which added the single-valued sorted-numeric path), judged, and cut to the one-test repro on 645d4fe14a20.
No prior report found: GitHub issues, PRs, commits and open-PR file lists, four mailing lists, the JIRA archive and three downstream projects, searched 2026-10-26 (31 hits read, none this bug) and refreshed 2026-11-01. The closest items fix other intoBitSet edge cases in other classes.
Searches5 searches
The introducing PR #16126 has no discussion or follow-up. The nearest items are separate intoBitSet fixes elsewhere: #16097 (the reader-side sibling, whose dense branch ends on NO_MORE_DOCS), #16102/#16105, #14882/#14922, #16250/#16252 and #14517/#14523. GitHub text search does not index diffs (the open-PR file scan covers that), and private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | three scripted searches plus 21 manual issue/PR queries and 3 commit searches (SortingNumericDocValues, NumericDocValuesWriter, NormValuesWriter, writeBitSet, docIDRunEnd, 16126, intoBitSet with maxDoc / NO_MORE_DOCS / norms / flush / index sort); every intoBitSet item created after #16126 (28); the comments and timeline of #16126 | no report of this defect |
| Open PRs (apache/lucene) | 2026-10-26 | changed-file lists of all 413 open PRs, for the writer, iterator and consumer files | only #14475 touches the writers, and it predates the override |
| Mailing lists and JIRA archive | 2026-10-26 | dev@, java-user@, issues@, commits@; JIRA queries on the writer classes and writeBitSet | mailing lists: only PR notification mails and unrelated intoBitSet fixes; JIRA: only issues from before intoBitSet existed |
| Downstream (Elasticsearch, OpenSearch, Solr) | 2026-10-26 | 6 manual searches plus scripted downstream queries | no report; no consumer read bulk-loads a dense flush iterator |
| Refresh (apache/lucene) | 2026-11-01 | the 127 issues and PRs updated since 2026-10-25, titles and bodies grepped for intoBitSet, SortingNumeric, NumericDocValuesWriter, NormValuesWriter, DocValuesWriter, docIDRunEnd, writeBitSet | 2 hits (#16897, #16835), both reader-side range speedups, not this bug |
Introduced in 10.5.0 by #16126 (88f3d24ce7e1, merged 2026-05-26), which added the intoBitSet override. Affects 10.5.0-10.6.0 and main; 10.2.0-10.4.0 use the default loop and pass; 9.x, 10.0.0 and 10.1.0 lack the API. Still unfixed upstream on 2026-11-01.
Versions tested6 rows
Introduced by #16126 "Implement #intoBitSet and #docIDRunEnd in DocValuesWriter implementations" (Ignacio Vera, merged 2026-05-26 after one approval; 88f3d24ce7e1 on main, backport ef8dd5fb8bc4; CHANGES 10.5.0 "Optimizations"). git log -S 'docID = upTo;' on the file returns only this commit on main's history (with --all, also the backport), and git tag --contains on the backport gives 10.5.0, 10.5.1, 10.5.2 and 10.6.0. The dense state the branch keys on comes from #12381 (9.8.0) and was harmless until the override, because the inherited default loop ends on NO_MORE_DOCS. The line is still present on upstream main, branch_11x, branch_10_6 and branch_10_5 (2026-11-01).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 (also ea57360912ed, a9779ef3c193) | affected | but was:<2> with assertions on and off (minimal test, gradle and standalone) |
| 10.6.0 | affected | minimal test fails with assertions on and off (release jars, SHA-1 checked) |
| 10.5.0, 10.5.1, 10.5.2 | affected | the hunt's test fails 4 of 5 and the independent test 6 of 12; the method text is identical to main |
| 10.2.0, 10.3.2, 10.4.0 | not affected | pass: the API exists, but the class uses the default loop |
| 9.12.3, 10.0.0, 10.1.0 | n/a | intoBitSet(int, FixedBitSet, int) does not exist (9.12.3: the test does not compile) |
fix A / fix B on 645d4fe14a20 | not affected | the minimal test passes with assertions on and off |
Confirmed, medium confidence: the finder, an independent reproducer, an intended-behaviour devil's advocate and an adjudication reproduced it and rate it real. Cross-model reviews (OpenAI GPT-5.6) also reproduced it and agreed on root cause and fix, but rated it not real on scope alone (@lucene.internal).
Checks and verdicts352 words
Every check that executed code agrees on the root cause, every check that ran the one-line fix saw it pass, and all rate the impact minor and latent: correct bits, wrong end position, no in-tree consumer reaches it.
| Check | Verdict | What it found |
|---|---|---|
| finder | reproduced (minor, latent) | JUnit 5 run / 4 failed on main and 10.5.2 (assertions on and off) and on 10.5.0 (assertions on); 10.4.0 passes; the unsorted control passes; the fix passes (assertions on). |
| cross-model review, refute lens (OpenAI GPT-5.6) | not real, high (scope only) | Own direct test and own public IndexWriter + custom DocValuesFormat test fail (assertions on and off, 3 seeds); root cause and fix agreed; out of contract because intoBitSet and IndexedDISI are @lucene.internal; maintainers may accept the fix as hardening. |
| independent reproducer | real | Own JUnit with the javadoc loop as oracle: 6 of 12 fail on main (assertions on and off), 10.5.2 and 10.5.0, the bits always identical; found the single-valued sorted-numeric path; 6 controls pass; 10.4.0 and the fix 12 of 12. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6) | not real, high (scope only) | Own test fails on main and 10.5.2 (but was:<17>), passes on 10.4.0 and with the fix; calls maxDoc an oversight suitable for internal hardening. |
| intended-behaviour devil's advocate | real (latent, minor) | No doc, test, CHANGES entry or PR discussion supports maxDoc as an end state; re-ran main (assertions on and off), 10.5.2 and 10.4.0. |
| adjudication | confirmed, medium | Re-ran the independent test (12 run / 6 failed, assertions on and off), the finder's (5 / 4) and the fix (12 / 12); medium because the cross-model reviews rated it out of contract. |
| security screen | not security-sensitive | Executed probe: stock consumers make 0 intoBitSet calls on dense fields during index-sorted flushes, a sorted merge and addIndexes; CheckIndex clean. |
| main refresh and minimal repro | still reproduces | Identical per-test results on main a9779ef3c193 (assertions on); the one-test repro fails on 645d4fe14a20 with assertions on and off and on 10.6.0, passes on 10.4.0 and with fixes A and B. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 617 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,345 words
- Registry title
- With an index sort, the flush-time iterator that IndexWriter hands to a doc-values or norms consumer for a numeric field that every document has ends intoBitSet(upTo >= maxDoc) on docID() == maxDoc instead of NO_MORE_DOCS, so a custom consumer that bulk-loads it and loops until NO_MORE_DOCS never finishes (latent: Lucene's own consumers skip the bulk load for such fields)
- Area
- index / doc values and norms flush with index sorting (NumericDocValuesWriter.SortingNumericDocValues)
- Priority
- Low, rank 1067: The index-sorted flush iterator ends intoBitSet at maxDoc instead of NO_MORE_DOCS for dense numeric fields, latent because Lucene's own consumers skip that bulk load.
- Impact class
- minor
- Impact note
- Latent: only a custom DocValuesFormat or NormsFormat consumer (public codec extension points) that calls the @lucene.internal DocIdSetIterator#intoBitSet up to maxDoc or NO_MORE_DOCS on the flush-time iterator of an index-sorted segment, for a numeric doc-values, single-valued sorted-numeric or norms field that every document of the segment has, and then relies on docID() is hit, and it would be hit at the first flush of ordinary data; stock Lucene never takes the defective branch (the Lucene90 and backward Lucene80 consumers skip the bulk load when every document has a value, SortingCodecReader always passes a docs-with-field set; executed: zero intoBitSet calls on dense fields and a clean CheckIndex), none of the downstream consumers read takes it, the bits it sets are correct, no scale is needed, and 10.5.0 to 10.6.0 are affected.
- Summary
- You sort an index at flush and every document in the segment has a given numeric doc-values field (or norms, or a single-valued SortedNumericDocValuesField); a custom DocValuesFormat or NormsFormat consumer bulk-loads the iterator it gets at flush with intoBitSet(maxDoc) or intoBitSet(NO_MORE_DOCS) and expects it to end on NO_MORE_DOCS, as the reference loop in the intoBitSet javadoc does. Instead NumericDocValuesWriter.SortingNumericDocValues sets the right bits but leaves docID() at maxDoc, a position the docID() contract never allows, so a consumer that loops until NO_MORE_DOCS never ends; fed to IndexedDISI.writeBitSet it fails the flush with an AssertionError (-ea) or keeps writing empty-block headers until the output fails (-da). Lucene's own consumers never bulk-load a field that every document has, so stock indexes and search results are not affected.
- Introduced
- 88f3d24ce7e1b3e7b6716d078b69b0098d467a8c (main) and its branch_10x backport ef8dd5fb8bc466ce8a22eb41d167f036554fc64a, PR #16126 'Implement #intoBitSet and #docIDRunEnd in DocValuesWriter implementations' (author and merger iverase, approved by martijnvg; CHANGES 10.5.0 Optimizations; no tests for these iterators), which added the SortingNumericDocValues.intoBitSet override whose dense branch ends with 'docID = upTo;' [read: git log -S 'docID = upTo;' and -S on the override signature return only this commit, git blame attributes NumericDocValuesWriter.java:281-293 to it, git tag --contains on the backport gives 10.5.0, 10.5.1, 10.5.2 and 10.6.0; exec: release level only, 10.4.0 passes and 10.5.0 fails]; the dense state the branch keys on (docsWithField == null) comes from #12381 (01200b58046e, 9.8.0) and was harmless until the override, because the inherited default loop ends on NO_MORE_DOCS [read] (2026-05-26 (merged on main; branch_10x backport committed the same day))
- First affected version
- 10.5.0 [exec] (10.4.0 is the last unaffected release [exec]; 10.2.0 to 10.4.0 have DocIdSetIterator#intoBitSet but no override in this class, so the default loop is used [exec 10.2.0, 10.3.2, 10.4.0]; before 10.2.0 the method does not exist [exec: the repro does not compile on 9.12.3])
- Affected versions
- 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main (ea57360912ed, a9779ef3c193 and 645d4fe14a20). [exec] the minimal test fails on 10.6.0 and main 645d4fe14a20 (-ea and -da) and passes on 10.4.0; the finder's JUnit fails 4 of 5 on 10.5.0, 10.5.1, 10.5.2 and main, and on 10.5.2 and main also with -da; the independent reproduction's JUnit fails 6 of 12 on 10.5.0, 10.5.1, 10.5.2 (-ea and -da) and main (-ea and -da); both pass on 10.4.0 (the independent reproduction's OBS lines show the probe ran on SortingNumericDocValues and ended on NO_MORE_DOCS, so the pass is not vacuous), the finder's also on 10.2.0 and 10.3.2; 9.12.3 is not applicable (DocIdSetIterator#intoBitSet(int, FixedBitSet, int) does not exist; it first shipped in 10.2.0 via #14069 and #14134). [read] the method text is identical (sha1) at 10.5.0, 10.5.1, 10.5.2 and main; 10.0.0 and 10.1.0 lack the API. Not fixed upstream: main, branch_10x, branch_10_6 and branch_10_5 still have 'docID = upTo;' in the dense branch (read-only GitHub API, 2026-10-26).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that disputed it (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26: three scripted searches (the finder's: 16 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list and 4 JIRA queries; writer classes: 24 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list over dev@, java-user@, issues@ and commits@, and 4 JIRA queries; consumer side and symptom: 16 mailing-list and 3 JIRA queries), plus 21 manual GitHub issue/PR queries, 3 commit searches, 6 downstream-repo searches (Elasticsearch, OpenSearch, Solr), every intoBitSet item created after #16126 (28), the changed files of all 413 open apache/lucene PRs, the review comments, issue comments and timeline of #16126, manual mailing-list and JIRA REST queries, and web queries; 31 hits read, none the same bug); not fixed: upstream main (head ea57360912ed), branch_10x, branch_10_6 and branch_10_5 still have 'docID = upTo;' in the dense branch, and the only open PR that touches the writers (#14475) predates the override; related, not reports of this bug: #16126 (introduced it; one LGTM, no comments, no follow-up), #12381 (the dense representation), #16097 (the reader-side sibling, whose dense branch ends on NO_MORE_DOCS), #16102/#16105, #14882/#14922, #16250/#16252 and #14517/#14523 (other intoBitSet end-state or boundary fixes in other classes); gaps: GitHub text search does not index diffs (covered by the open-PR file scan), and private reports to security@lucene.apache.org are not visible
- Lucene commit tested
- main
645d4fe14a20(the minimal repro through gradle with-Ptests.asserts=trueand=false, stock and with fixes A and B; fix A with the closest core suites and:lucene:core:check -x test; standalone runs with assertions on and off and a second seed), the 10.6.0 and 10.4.0 release jars (SHA-1 checked), and, by the hunt and its verifiers, mainea57360912edanda9779ef3c193and the releases 10.2.0, 10.3.2, 10.4.0, 10.5.0, 10.5.1 and 10.5.2 (9.12.3 does not compile: the API is absent). Every cited Java source file (and SECURITY.md) is byte-identical atea57360912edand645d4fe14a20;lucene/CHANGES.txtgained 33 lines in between, and its cited lines are given at645d4fe14a20; upstream mainf815e679bf6c(2026-11-01),branch_11x,branch_10_6andbranch_10_5still have the defective line (read).
- Finding record
lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:150-157 (sorted producer; dense flag sortMap.size() == docsWithField.cardinality() at :155), :247-254 (nextDoc returns NO_MORE_DOCS after maxDoc - 1), :281-293 (SortingNumericDocValues.intoBitSet: upTo clamped to maxDoc, dense branch 'docID = upTo;' at :287, sparse branch maps upTo >= maxDoc to NO_MORE_DOCS at :290)lucene/core/src/java/org/apache/lucene/index/NormValuesWriter.java:74-96 (norms flush with an index sort returns the same SortingNumericDocValues) and SortedNumericDocValuesWriter.java:215-224 (single-valued sorted-numeric wraps the same producer in DocValues.singleton)lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:186-205 (intoBitSet 'should behave exactly as if implemented as' the docID()/nextDoc() loop; @lucene.internal at :203)lucene/core/src/java/org/apache/lucene/codecs/lucene90/IndexedDISI.java:94 (@lucene.internal) and :210-222 (writeBitSet loop: intoBitSet per block, then doc = it.docID() until NO_MORE_DOCS)lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:462-475 and Lucene90NormsConsumer.java:102-121 (IndexedDISI only when 0 < numDocsWithValue < maxDoc); SortingCodecReader.java:793-804 (always a non-null docsWithField)lucene/CHANGES.txt:1109 (GITHUB#16126 under 10.5.0 Optimizations), :1211 (GITHUB#16250 under 10.5.0 Bug Fixes), :1738 (GITHUB#14922 under 10.3.0 Bug Fixes)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:110-131, :150-170, :247-254, :281-293, :318-325lucene/core/src/java/org/apache/lucene/index/NormValuesWriter.java:74-96lucene/core/src/java/org/apache/lucene/index/SortedNumericDocValuesWriter.java:215-226lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:113-124, :186-205lucene/core/src/java/org/apache/lucene/codecs/lucene90/IndexedDISI.java:113-136, :210-222lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:461-475; Lucene90NormsConsumer.java:102-121; index/SortingCodecReader.java:793-804
- Who is affected
lucene/CHANGES.txt:1142 (GITHUB#16126 under 10.5.0 Optimizations)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:113-124, :186-205lucene/core/src/java/org/apache/lucene/index/NumericDocValuesWriter.java:247-254, :281-293lucene/test-framework/src/java/org/apache/lucene/tests/util/BaseDocIdSetTestCase.java:222; lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseDocValuesFormatTestCase.java:1081-1089build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:506lucene/CHANGES.txt:1142, :1244, :1771
- TestSortedFlushIntoBitSetEndPosition.java (one JUnit test, public API):
repro/LFV-165/src/org/apache/lucene/index/TestSortedFlushIntoBitSetEndPosition.java(93 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output.
assets/LFV-165/bug.png(617 KB)