To end a block, the writer looks back over the last 2 × delta terms for a split point. That window must start at index 1 or later: ordinary splits guarantee it, the splits at a field's end do not whenever 3 × delta > target. The constructor accepts such settings, so the flush throws.
- Blocks of terms. UniformSplit writes a field's sorted terms in blocks of about
targetNumBlockLinesterms, give or takedeltaNumLines(default 32 ± 3). - Where a block ends. When a block reaches target + delta terms, the writer looks back over its last 2 × delta terms and starts the next block at the term with the shortest distinguishing prefix, which keeps the terms dictionary small.
- The last block. When the field's terms run out, the leftover terms go through the same split, unless there are at most target − delta of them: those are written as one block. The split repeats on whatever it leaves until no terms are left.
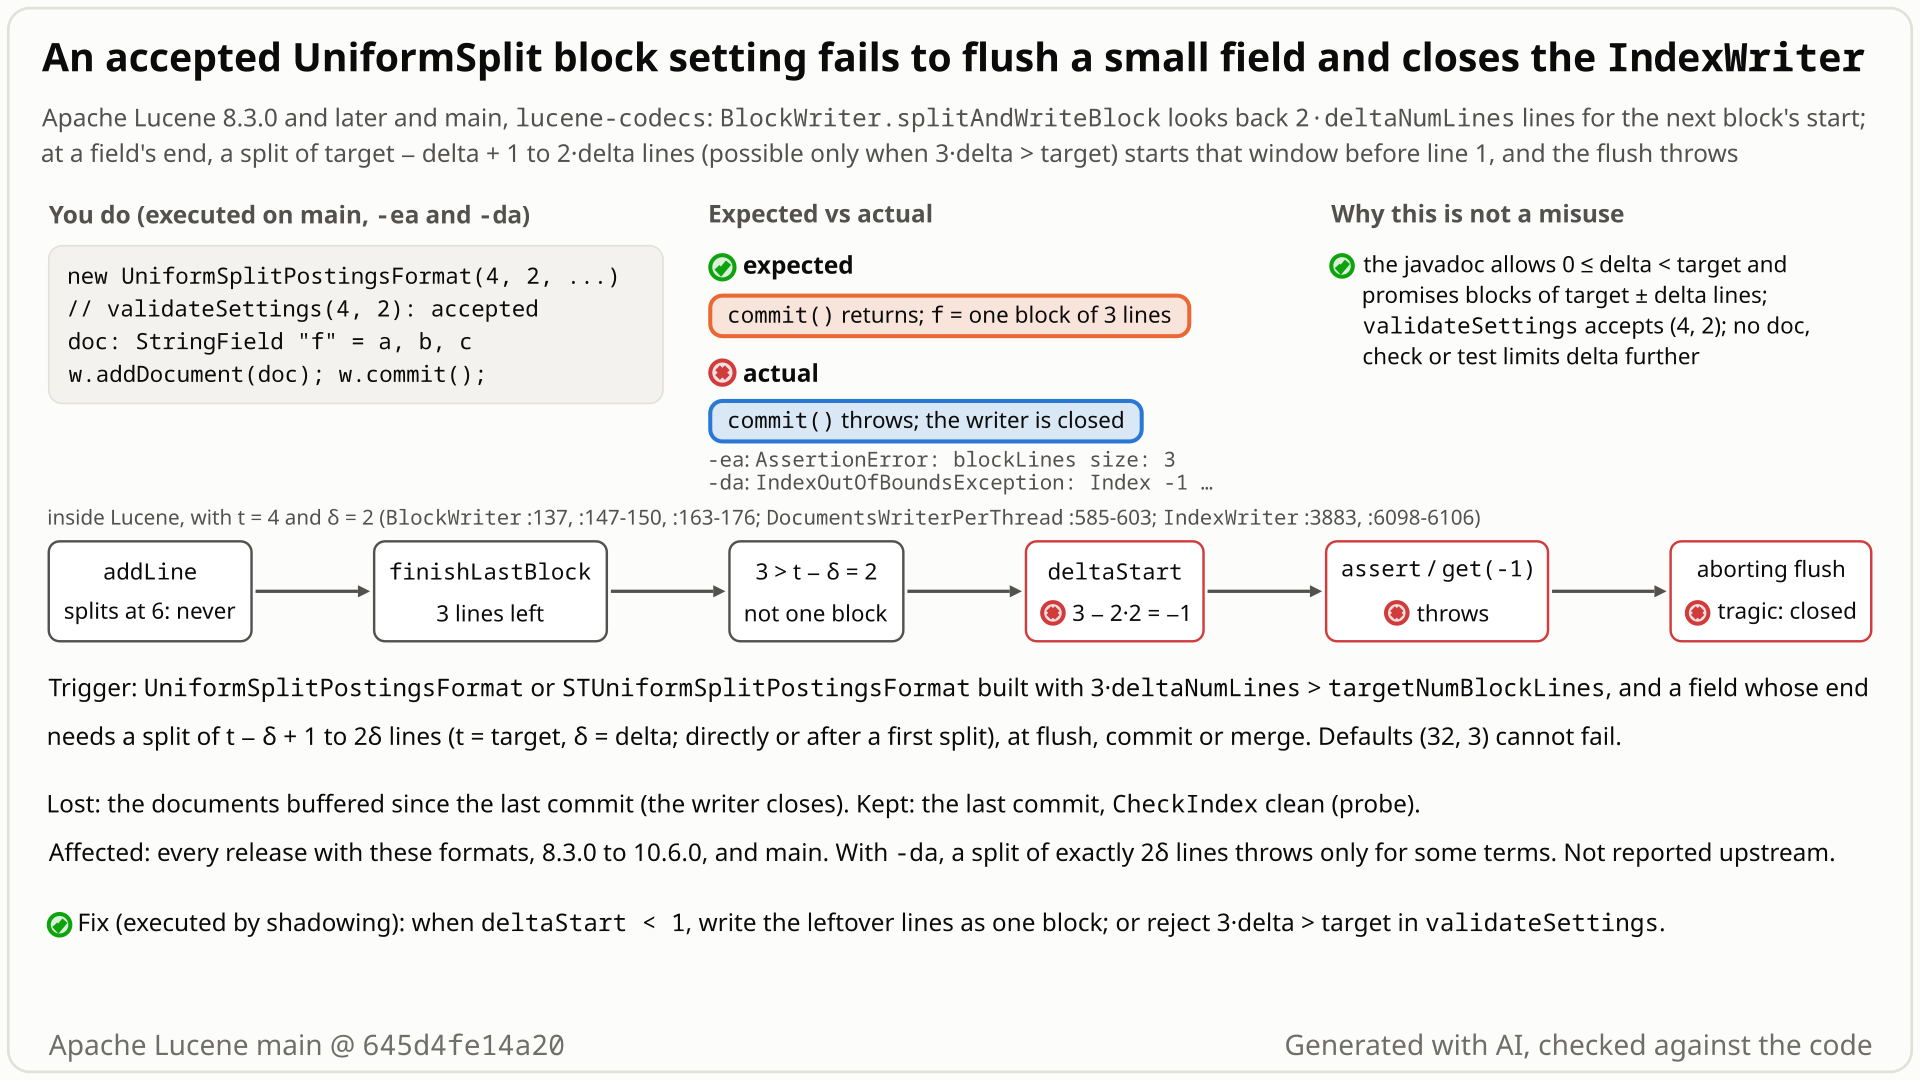
- You build
new UniformSplitPostingsFormat(4, 2, null, null, false): blocks of 4 ± 2 terms. The constructor accepts it, because the documented rule is only0 <= deltaNumLines < targetNumBlockLines. - You add one document with the 3 values
a,b,cin fieldfand commit. You expect one block of 3 terms, inside the promised 2 to 6. - Instead the commit throws:
AssertionError: blockLines size: 3with assertions on,IndexOutOfBoundsException: Index -1 out of bounds for length 3with them off. TheIndexWritercloses and loses everything since the last commit. - Why: at the end of a field the writer writes the leftover terms as one block only if there are at most 4 − 2 = 2. With 3 it looks back over the last 2 × 2 = 4 terms for a split point, starting at index 3 − 4 = −1.
- Every setting with 3 × delta > target can hit it: under (32, 12), any field whose end needs a split of 21 to 24 terms, either as the whole leftover or after a first split of a leftover of up to 43, in flushes and merges and for both formats. The defaults (32, 3) and formats loaded by name cannot fail.
Applications that build either format with deltaNumLines > targetNumBlockLines / 3; no such user is known. Then any flush, commit or merge can hit it, at any scale: the writer closes and uncommitted documents are lost; the last commit stays intact. Just past the boundary only 1 to 5 random fields in 400 fail, so tests can miss it.
Mechanism, terms and numbers1,241 words
UniformSplitPostingsFormat and STUniformSplitPostingsFormat (codecs module, opt-in) take targetNumBlockLines and deltaNumLines in their public constructors; the javadoc asks only 0 <= deltaNumLines < targetNumBlockLines and promises blocks of target ± delta terms, and validateSettings enforces exactly that. When the writer finishes a field, it writes the leftover terms as one block only if there are at most target − delta of them; otherwise it looks for a split point in the last 2 × delta terms, starting at index numLines − 2 × delta, and only asserts that this is at least 1. For a split of target − delta + 1 to 2 × delta terms, a range that exists exactly when 3 × delta > target, the start is 0 or negative; at a field's end such a split is either the whole leftover or what a first split of a larger leftover (up to target + delta − 1 terms) leaves. The flush, commit or merge then throws (AssertionError with assertions on; IndexOutOfBoundsException with them off, at exactly 2 × delta terms only for some terms), the IndexWriter closes through its tragic-event path and everything buffered since the last commit is lost; the last commit stays intact and passes CheckIndex. The smallest case is one document with 3 values under (4, 2). The defaults (32, 3) cannot fail. The code is unchanged since the formats were added (LUCENE-8753, 8.3.0).
- Ordinary splits.
BlockWriter.addLineappends one line per term and callssplitAndWriteBlockonce the block holdstargetNumBlockLines + deltaNumLineslines (BlockWriter.java:137-139). There the window starts at(target + delta) − 2 × delta = target − delta >= 1. - The end of a field.
UniformSplitTermsWriter.writeFieldTermscallsfinishLastBlockafter the last term ("Flush remaining terms.",UniformSplitTermsWriter.java:333-334), which loopssplitAndWriteBlockwhile lines remain (BlockWriter.java:147-153); the leftover has 1 to target + delta − 1 lines. When the first call splits normally (deltaStart >= 1), it leaves at most 2 × delta lines, and the loop splits those again. - The split.
splitAndWriteBlock(BlockWriter.java:161-191) writesnumLines <= target − deltaas one block (:165-169); otherwiseint deltaStart = numLines - deltaNumLines * 2;(:170),assert deltaStart >= 1 : "blockLines size: " + numLines;(:171), thenblockLines.get(i)forifromdeltaStart(:175-176), keeping the last line with the shortest prefix (<=at:178), and writessubList(0, minMdpEndIndex)(:184). A call with target − delta + 1 to 2 × delta lines hasdeltaStart <= 0. At a field's end it comes either directly (the leftover r has that many lines) or second: for a leftover r of 2 × delta + 1 to target + delta − 1 lines, the first call ends the block at the last shortest-prefix line k of the window and leaves r − k lines, which land in that range when k < r − (target − delta). With 3 × delta <= target every remainder is at most 2 × delta <= target − delta and is written as one block. - What is thrown. Assertions on: the assert fails. Assertions off,
deltaStart < 0:blockLines.get(deltaStart)throws at:176(hereIndex -1). Assertions off,deltaStart == 0(a call of exactly 2 × delta lines): the loop picks index 0 only when line 0 has the strictly shortest prefix, and thenaddBlockKey'sblockLines.get(0)on the empty sub-list throws (BlockWriter.java:278-282); otherwise (last shortest prefix at k >= 1) the split writes a valid block of k lines, butfinishLastBlocksplits the remaining 2 × delta − k lines again, and that split throws (Index -kat:176) when k < 3 × delta − target, possible when 3 × delta >= target + 2, e.g. (6, 4) or (32, 12); otherwise the field is written. The fact check ran this under (6, 4) with one 8-value field:atohcommits,a, aa … agthrowsIndex 0,a, b, ba, bb, bc, bd, be, bfthrowsIndex -1 out of bounds for length 7; with assertions on all three throwblockLines size: 8, and with the fix all three commit. So with assertions off the failures are a strict subset of those with assertions on: each follows a call withdeltaStart <= 0. - Both formats.
STBlockWriter.finishLastBlockonly callssuper(STBlockWriter.java:86-90). - Validation lets it through.
validateSettings(UniformSplitTermsWriter.java:238-260), called by the constructor (UniformSplitPostingsFormat.java:105), checks only target > 0, delta >= 0, delta < target and target + delta <= 1,000. - Why the writer closes. A flush failure is recorded as aborting,
abort()runs and the exception is passed toIndexWriter.onTragicEvent(DocumentsWriterPerThread.java:585-589,:594-605;IndexWriter.java:453-454), the same for both exceptions;prepareCommitInternalthen rolls the writer back (IndexWriter.java:3879-3883,:6098-6106). A merge failure callstragicEvent(t, "merge")(IndexWriter.java:5109-5113).
The failing splitAndWriteBlock call always has target − delta + 1 to 2 × delta lines. It is either the field's whole leftover or what finishLastBlock's first split of a larger leftover leaves, so any leftover from target − delta + 1 to target + delta − 1 lines can fail, the larger ones only for some terms.
| setting (target, delta) | 3 × delta > target? | lines in the failing call | leftovers that can fail |
|---|---|---|---|
| (32, 3), the default | no | none | none |
(10, 2), used by TestBlockWriter | no | none | none |
| (4, 2) | yes | 3, 4 | 3 to 5; 5 only for some terms (executed) |
| (32, 11) | yes (33 > 32) | 22 only (the exact 2 × delta case) | 22 to 42; above 22 only for some terms (from the code) |
| (32, 12) | yes | 21 to 24 | 21 to 43; above 24 only for some terms (from the code) |
The (4, 2) 5-term case, run by the diagram probe: a, b, ba, bb, bc throws blockLines size: 4 with assertions on and Index 0 out of bounds for length 0 with them off; a, ab, b, ba, bb throws blockLines size: 3 and Index -1 out of bounds for length 3; a to e commits.
- Writer state (UniformSplit, both assertion modes): under (4, 2), commit 1 with one value succeeds; a 3-value document plus a document in another field then make commit 2 throw. The writer is closed (
isOpen()false, a tragic exception recorded, the nextaddDocumentthrowsAlreadyClosedException) and the reopened index has 1 of the 3 documents added;CheckIndexis clean. - Merge path (both formats): two committed segments with 2 and 1 values each flushed fine;
forceMerge(1)writes a 3-term field and throws, and the writer closes; the last commit (2 documents, all 3 values readable) is intact andCheckIndex-clean. - Moderate settings: (32, 12) with a 22-value field, (64, 22) with 43 values and (100, 34) with 67 values throw with assertions on and off.
- Sweep: all 78 accepted settings with target 1..12, fields of 1..40 values, two term shapes, both formats: 0 failures when 3 × delta <= target; with assertions off 1,164 of 3,120 flushes fail for sequential terms and 914 of 3,120 for random terms. Fields of more than 2 × delta values, which reach the failing range only after a first split, account for 806 of 1,268 (sequential) and 600 of 1,268 (random) of them.
Exposure and likelihood286 words
- Who. Applications that build
UniformSplitPostingsFormatorSTUniformSplitPostingsFormatthrough the public 5-argument constructors, or through a subclass and the protected constructors, withdeltaNumLines > targetNumBlockLines / 3. The formats are opt-in (codecs module,@lucene.experimental) and the setting is non-default. Default-constructed and SPI-loaded instances use (32, 3) and cannot fail. - No known user. A code search found no code that builds these formats with non-default settings (only copies of Lucene's own default-settings test), and Solr selects postings formats by SPI name, which uses the defaults. The search is not exhaustive.
- What it costs. The flush, commit or merge throws and the
IndexWritercloses; everything buffered since the last commit is lost, including other threads' documents, since it is a writer-wide rollback (this follows from the rollback; all runs were single-threaded). The committed index stays consistent andCheckIndex-clean, and in the executed checks every assertions-off flush that did not throw read back all its terms. It is not index corruption. - Merges stay blocked. A merge whose output field needs such a split fails again in each new writer session until the setting is changed; switching the field back to the defaults recovers (
forceMerge(1)succeeds,CheckIndexclean). - Scale. None needed: one document with 3 values under (4, 2). With a wide window failures are frequent: about a third of fields, e.g. 143 of 400 random fields under (32, 16) with assertions off. Just past the boundary failures are rare on ordinary data. With assertions off: 1 of 400 random fields under (32, 11), 4 of 400 under (64, 22), 5 of 400 under (100, 34), 26 of 400 under (32, 12).
- How likely: rare. Loud, and limited to a non-default setting nobody is known to use.
One JUnit test, one thread, deterministic, public constructor only: UniformSplitPostingsFormat(4, 2), one document with 3 StringField values in one field, then commit(). It fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.uniformsplit;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestUniformSplitLargeDeltaFlush extends LuceneTestCase {

  public void testCommitThreeTermsWithTarget4Delta2() throws Exception {
    IndexWriterConfig iwc =
        new IndexWriterConfig()
            .setCodec(
                TestUtil.alwaysPostingsFormat(
                    new UniformSplitPostingsFormat(4, 2, null, null, false)));
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, iwc)) {
      Document doc = new Document();
      doc.add(new StringField("f", "a", Field.Store.NO));
      doc.add(new StringField("f", "b", Field.Store.NO));
      doc.add(new StringField("f", "c", Field.Store.NO));
      w.addDocument(doc);
      try {
        w.commit();
      } catch (Throwable t) {
        // Expected: commit succeeds, (4, 2) meets the documented 0 <= deltaNumLines < targetNumBlockLines; actual: it throws.
        throw new AssertionError("commit with UniformSplitPostingsFormat(4, 2) threw " + t, t);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:codecs:test --tests TestUniformSplitLargeDeltaFlush -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
commit()succeeds and fieldfis written as one block of 3 terms.- Observed
commit()throwsAssertionError: blockLines size: 3with assertions on,IndexOutOfBoundsException: Index -1 out of bounds for length 3with them off.
More files, environment, full output287 words
(4, 2) meets the documented rule 0 <= deltaNumLines < targetNumBlockLines. The test sits in org.apache.lucene.codecs.uniformsplit, where an upstream test would go, but uses only the public constructor; ByteBuffersDirectory and an explicit postings format fix the directory and codec choices that matter; the test framework still randomizes unrelated things such as locale and time zone, which do not affect the path. Line 45 is w.commit(); line 48 is the test's own wrapper, which says the commit was expected to succeed. If you add it upstream, wrap the long comment line for the formatter.
The writer close, the merge path and STUniformSplitPostingsFormat share the root cause and were executed by the longer checks (in the collapsed explanation above); they are not part of this repro.
Regression test: this same test; it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Also fails on the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestUniformSplitLargeDeltaFlush.java $LUCENE/lucene/codecs/src/test/org/apache/lucene/codecs/uniformsplit/
cd $LUCENE && ./gradlew :lucene:codecs:test --tests TestUniformSplitLargeDeltaFlush -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails too, with IndexOutOfBoundsException: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed)
TestUniformSplitLargeDeltaFlush > testCommitThreeTermsWithTarget4Delta2 FAILED
    java.lang.AssertionError: commit with UniformSplitPostingsFormat(4, 2) threw java.lang.AssertionError: blockLines size: 3
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:778092D94C5D7E5]:0)
        at org.apache.lucene.codecs.uniformsplit.TestUniformSplitLargeDeltaFlush.testCommitThreeTermsWithTarget4Delta2(TestUniformSplitLargeDeltaFlush.java:48)
        Caused by:
        java.lang.AssertionError: blockLines size: 3
            at org.apache.lucene.codecs.uniformsplit.BlockWriter.splitAndWriteBlock(BlockWriter.java:171)
            at org.apache.lucene.codecs.uniformsplit.BlockWriter.finishLastBlock(BlockWriter.java:149)
            at org.apache.lucene.codecs.uniformsplit.UniformSplitTermsWriter.writeFieldTerms(UniformSplitTermsWriter.java:334)
            at org.apache.lucene.codecs.uniformsplit.UniformSplitTermsWriter.write(UniformSplitTermsWriter.java:274)
            at org.apache.lucene.codecs.perfield.PerFieldPostingsFormat$FieldsWriter.write(PerFieldPostingsFormat.java:162)
            at org.apache.lucene.index.FreqProxTermsWriter.flush(FreqProxTermsWriter.java:133)
            ...
            at org.apache.lucene.index.IndexWriter.commit(IndexWriter.java:4215)
            at org.apache.lucene.codecs.uniformsplit.TestUniformSplitLargeDeltaFlush.testCommitThreeTermsWithTarget4Delta2(TestUniformSplitLargeDeltaFlush.java:45)

# same, -Ptests.asserts=false (JDK frames trimmed)
    java.lang.AssertionError: commit with UniformSplitPostingsFormat(4, 2) threw java.lang.IndexOutOfBoundsException: Index -1 out of bounds for length 3
        Caused by:
        java.lang.IndexOutOfBoundsException: Index -1 out of bounds for length 3
            at java.base/java.util.ArrayList.get(ArrayList.java:428)
            at org.apache.lucene.codecs.uniformsplit.BlockWriter.splitAndWriteBlock(BlockWriter.java:176)
at org.apache.lucene.codecs.uniformsplit.BlockWriter.finishLastBlock(BlockWriter.java:149)- The constructor accepts any
0 <= deltaNumLines < targetNumBlockLines, promises blocks of target ± delta terms and says the defaults "can be tuned". - Writing the failing split's terms (at most 2 × delta < target + delta) as one block keeps that promise.
- No javadoc, test or design discussion limits delta further; the internal assert is the only trace.
The full argument309 words
- The settings are inside the documented contract. The constructor javadoc (
UniformSplitPostingsFormat.java:73-76, the same atUniformSplitTermsWriter.java:169-172):deltaNumLines"Must be greater than or equal to 0 and strictly less than {@code targetNumBlockLines}. The block size will be {@code targetNumBlockLines}+-{@code deltaNumLines}." The class javadoc: "Each block size (number of terms) is {@code targetNumBlockLines}+-{@code deltaNumLines}" (UniformSplitTermsWriter.java:48-50) and "A good sweet spot for the target block size is 32 with delta of 3 (10%) (default values). This can be tuned in the constructor." (:70-71). The range is loose at a field's end even today: the stock end-of-field split can write a block below target − delta (e.g. 24 lines for a 30-line leftover under the defaults (32, 3),BlockWriter.java:165-185); the defect is the exception on accepted settings, not the block size. - Validation accepts them.
validateSettings(UniformSplitTermsWriter.java:238-260) checks exactly the documented rule; (4, 2), (32, 11), (32, 12) and (64, 22) pass. - A valid result exists. A failing split has at most 2 × delta < target + delta terms, so one block keeps the promised range, and the reader needs no block-size setting: with the fix every value reads back and
CheckIndexis clean. - Nothing limits delta further. No javadoc, test,
CHANGES.txtorMIGRATE.mdentry. Upstream tests use only (32, 3) (TestUniformSplitPostingFormat.java:43-48,TestSTUniformSplitPostingFormat.java:32-37) andBlockWriter(..., 10, 2, ...)(TestBlockWriter.java:45), all with 3 × delta <= target. The design discussion (#9798, lucene-solr #633, #676, #828) never discusses delta bounds or the last block, andgit log -Lon the body ofsplitAndWriteBlockfinds only the introducing commit (with its javadoc, also a reformatting); the file's other commits do not touch the method. - Sibling practice. BlockTree's
validateSettingsrejects settings its splitter cannot handle: "maxItemsInBlock must be at least 2*(minItemsInBlock-1)" (Lucene103BlockTreeTermsWriter.java:354-360). UniformSplit accepts the settings and then fails at flush.
The devil's-advocate check189 words
The strongest case: these are @lucene.experimental formats in the codecs module; the javadoc calls 10% the sweet spot and the design describes delta as an "allowed delta variation (10%)"; the assert records the author's precondition; and nobody uses such settings.
Why it fails: @lucene.experimental warns that the API may change, not that documented arguments may crash the writer. The 10% is a recommended default, never a stated limit, and the same javadoc says the defaults can be tuned. The assert is internal, invisible to users and false for every accepted setting with 3 × delta > target. Low reach bears on priority, not on whether it is a bug. If large deltas are unwanted, the fix is to reject them in validateSettings, not to fail the flush and close the writer. The reading-only GPT reviews rated the intended-behaviour case "weak"; a later cross-model fact check rated it "moderate" (experimental, opt-in, an artificial setting, a loud failure that keeps the last commit) and noted that maintainers may reasonably prefer rejecting such settings in validation. That bears on which fix to lead with, not on whether the flush should throw.
Recommended Write the leftover as one block when the window would start below 1 (validated)
In BlockWriter.splitAndWriteBlock, when the look-back window would start below index 1 (only possible for a field's last block), write the leftover terms as one block instead of asserting (+8/−1 lines). The repro passes with assertions on and off, and so do the uniformsplit tests, the whole codecs test module (693 tests) and lint.
int deltaStart = numLines - deltaNumLines * 2;
if (deltaStart < 1) {
  // Only reachable from finishLastBlock, for the last lines of a field, when
  // 3 * deltaNumLines > targetNumBlockLines: write them as one block (numLines <= 2 *
  // deltaNumLines < targetNumBlockLines + deltaNumLines, so the block size stays in range).
  writeBlock(blockLines, dictionaryBuilder);
  blockLines.clear();
  return;
}
All options and trade-offs3 options · 593 words
Option A was built and run here. B, a simpler clamp, was run by the study and has a drawback. C, tightening validation, was not run.
Replace the assert deltaStart >= 1 in BlockWriter.splitAndWriteBlock (BlockWriter.java:171) with a branch that writes the remaining lines as one block and returns. addLine always splits at target + delta lines, where deltaStart >= 1, so the branch is reached only from finishLastBlock, directly or on its second call, and the blocks written before it are unchanged; settings with 3 × delta <= target behave exactly as today.
int deltaStart = numLines - deltaNumLines * 2;
if (deltaStart < 1) {
  // Only reachable from finishLastBlock, for the last lines of a field, when
  // 3 * deltaNumLines > targetNumBlockLines: write them as one block (numLines <= 2 *
  // deltaNumLines < targetNumBlockLines + deltaNumLines, so the block size stays in range).
  writeBlock(blockLines, dictionaryBuilder);
  blockLines.clear();
  return;
}
Trade-offs
- Block size. The last block then has target − delta + 1 to 2 × delta lines, inside the promised target ± delta; its split point is not chosen by the shortest-prefix rule, which affects only the dictionary key of one block per field.
- No format change. The reader needs no setting; with the fix every value reads back (iteration and
seekExact), merges succeed andCheckIndexis clean. - It drops the
assert; the condition it guarded is now handled.
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-31):
- stock: the minimal test fails with assertions on and off;
- with the fix: the minimal test passes with assertions on and off;
- the
org.apache.lucene.codecs.uniformsplit.*tests (the 7 upstream classes plus the minimal test) pass with assertions on and off: 8 classes, 83 tests, 0 failures, 4 skipped; - the whole
:lucene:codecs:testpasses (26 classes, 693 tests, 0 failures, 78 skipped; run after the copied test was removed, assertions on);checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor codecs pass; - earlier, with the fix loaded over the stock jars: the settings sweeps give 0 failures (3,120 flushes in the study, 12,480 in the tie-break), and the independent reproducer's 5 tests and the tie-break's production-API check pass with assertions on and off.
int deltaStart = Math.max(1, numLines - deltaNumLines * 2); and no assert.
Trade-offs
The finder's 4-case test (which includes the repro's (4, 2) 3-term case), the settings sweep (0 of 3,120 flushes fail) and the 7 upstream uniformsplit test classes pass. But, as the study's refute reviewer noted, it can write a 1-line block that is not the last block of the field (when the shortest prefix is at index 1). The stock end-of-field split also writes blocks below target − delta, but not 1-line ones when 3 × delta < target; so the first option is preferred. Not run in this doc's validation.
Add the check to validateSettings and the constructor javadoc, like BlockTree's 2*(minItemsInBlock-1) rule.
Trade-offs
Simple and fails fast at construction. But it narrows a documented and accepted range: applications whose data happens to avoid the window today (under (32, 11) about 1 field in 400 fails) would fail at construction after an upgrade; existing indexes stay readable, because the reader does not use the settings. The minimal test would have to expect an IllegalArgumentException from the constructor instead of a successful commit.
No downstream product is known to build these formats with non-default settings; Solr loads them by name, which uses the safe defaults.
While building small-block UniformSplit test fixtures, (4, 2), for a differential test of automaton term intersection, the finder hit the writer's own assertion. Code reading of the last-block split, an exhaustive sweep of all 78 accepted settings with target up to 12, and a public-API JUnit on the stock jars confirmed it.
The method in full128 words
Method: semi-formal. An assertion failure seen while building fixtures for another hunt unit (a codec differential of automaton term intersection), outside that unit's target files; then code reading of BlockWriter.splitAndWriteBlock.
- Bounded-exhaustive sweep. All 78 settings with
targetNumBlockLines <= 12that the constructor accepts, every field size 1..40, on the stock jar: 1,164 of 3,120 flushes fail with assertions off, every one with 3 × delta > target and none otherwise; 0 with either fix sketch. - Widening. An independent reproducer found the merge path and that the assertions-off failures are a subset; a devil's-advocate verifier reached it from another package through production API; the follow-up measured failure rates on random data just past the boundary.
- The minimal repro above is the smallest case: 3 terms under (4, 2).
None found: no issue, PR, commit, list post or downstream report (searched 2026-10-26 and 2026-10-30/31). Closest: the design review of the formats (#9798, lucene-solr #828), which never discusses delta bounds, and #10277, a block-size tuning thread that does not change delta.
Searches3 searches
- #9798 (LUCENE-8753) and lucene-solr #633, #676, #828: where the code came from; delta appears only as the design's "allowed delta variation (10%)"; nothing on bounds, the last block or
validateSettings. - #10277 (LUCENE-9237): the only tuning discussion, block size 26 against 32; the thread does not change delta, and a target of 26 is outside the window for any delta of 8 or less.
- #10647 (LUCENE-9607, open): a different test failure, on the read side.
- #10148 (LUCENE-9106): the last functional change to
BlockWriter(serializer hooks); the split logic untouched. - Open PRs #16851, #14716, #13525 touch
uniformsplit/but notBlockWriter,STBlockWriterorvalidateSettings. - Limits: forks and private trackers are invisible; lucene-solr PRs before 2019-03 were not scanned (the formats did not exist); web results were noise.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive, lucene-solr, solr, Elasticsearch, OpenSearch, all of GitHub) | 2026-10-30/31 | a prior-art run of 97 queries (GitHub 40, commits 6, downstream 5, lists 32, JIRA 6, web 8), 48 GraphQL and 12 REST searches (UniformSplit, deltaNumLines, targetNumBlockLines, splitAndWriteBlock, BlockWriter, the exception messages), and the changed files of every open and closed-unmerged apache/lucene PR (1,032) and of 2,094 lucene-solr PRs since 2019-03 | related items only (#9798, lucene-solr #633/#676/#828, #10277, #10647, #10148, open PRs #16851, #14716, #13525); none the same bug |
| Mailing lists (dev@, java-user@, issues@, commits@, builds@), JIRA SOLR and LUCENE, web | 2026-10-30/31 | the list queries above plus a second run of 32 list queries including builds@; full comment threads of the nearest issues and PRs | no report (7 builds@ CI mails name UniformSplit tests, with no BlockWriter frame) |
| Earlier searches | 2026-10-26 and 2026-10-30 | the study follow-up's 113 logged queries, 44 GraphQL searches and a changed-file scan of 413 open PRs; the re-verification's gh searches | no report (verdict new) |
Introduced with the formats by b963b7c3dbe (LUCENE-8753, 2019-09-06), first released in 8.3.0. Fails on every sampled release from 8.3.0 to 10.6.0 and on main; 8.2.0 and older lack the formats. Not fixed upstream.
Versions tested7 rows
Introduced by b963b7c3dbecda86c2917ad341caee63b93815ac, "LUCENE-8753: New UniformSplit and SharedTermsUniformSplit PostingsFormats" (committed by David Smiley, 2019-09-06; code from lucene-solr #828 by Bruno Roustant, following #633 and absorbing #676; JIRA issue now #9798; branch_8x cherry-pick b8a1857b0bd). The split code and the four validation checks are in this first version; on mainline history git log -S on the deltaStart line and the assert finds only this commit (across all refs also the branch_8x cherry-pick and a branch-bookkeeping commit), and git log -L on the method body finds only this commit (with its javadoc included, also the reformatting 7f8b7ffbcad, 2021-01-03).
Every one of the 48 release tags from 8.3.0 to 10.6.0 in the history clone has both lines verbatim and the same four checks; releases not executed are covered by that reading, and 8.8.2 to 8.11.4, not tagged there, were executed. Not fixed: unchanged on upstream main 2f424fd428da (2026-10-30), branch_10_6 and branch_11x; no CHANGES.txt entry.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (gradle and standalone runner); passes with the fix |
| 10.6.0 | affected | minimal test and the study's portable main() fail, assertions on and off |
| 10.5.2 | affected | minimal test fails, assertions on and off |
| 9.0.0, 9.12.3, 10.0.0 | affected | minimal test (imports ported for 9.0.0) or the portable main() fails |
| 8.4.1, 8.5.0, 8.8.2 to 8.11.4 | affected | a port of the minimal test or the portable main() fails |
| 8.3.0 | first affected | minimal test (8.x port) and the portable main() fail, assertions on and off |
| 8.2.0 and older | no such API | the test does not compile: the formats do not exist |
An independent reproducer, a devil's-advocate verifier, an adjudication, a re-verification and a tie-breaker reproduced it, each running its own or the minimal test. Of OpenAI GPT-5.6 reviews, the one that could run code reproduced it (real, high); both reading-only ones agreed on the root cause.
Checks and verdicts447 words
Each check ran its own tests or re-ran an earlier one on stock jars; two of the cross-model reviewers could only read code.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Its 4-case JUnit ((4, 2) with 3 and 4 terms, (10, 4) with 7 and 8) fails on main with assertions on and off and on 10.5.2 and 9.12.3 with them off; the 78-setting sweep; both fix sketches pass. |
| Refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test (one document with 4 terms under (5, 2)) fails for both formats with assertions on and off, (5, 1) passes; root cause agreed; noted the clamp fix's 1-line block. |
| Independent reproducer | real | Own 5-test JUnit fails 3 of 5 on main, 10.5.2 and 9.12.3; a portable main() fails 10 of 10 bug cases on 8.3.0, 8.11.4 and main with all controls passing; found the merge path and that the assertions-off failures are a subset. |
| Works-as-designed lens (OpenAI GPT-5.6, reading only) | real (medium) | Intended-behaviour argument weak; root cause agreed. |
| Intended-behaviour devil's advocate | real (high) | Public-API test from another package fails 3 of 6, including a (32, 16) merge of two healthy segments; the last commit survives a failed merge and CheckIndex is clean. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test: 3 of 5 fail with assertions on and off; 0 of 5 with the fix. |
| Re-verification on main 645d4fe14a20 | real | The minimal test fails on main and 10.5.2 with assertions on and off; the fix passes it. |
| Second refute lens (OpenAI GPT-5.6, reading only) | not real (low, procedural) | Could not run anything, so it could not reproduce; agreed on the root cause, inputs in contract, intended argument weak, and asked for a re-run that can execute code. |
| Tie-breaker | real | Minimal test on main and 10.5.2, the intended-behaviour check's test on main, and its own production-API check (writer state, merge, settings sweeps) on main and 10.5.2; everything passes with the fix. |
| This doc's fix validation | real | Gradle in a scratch worktree: the minimal test fails on stock main and passes with the recommended fix, as do the uniformsplit tests, the whole codecs module and lint. |
| Fact check of this doc (executed) | real | Re-ran the gradle command (stock fails, the fix passes, assertions on and off) and the 10.6.0 jars; found two wording errors, now fixed: the third assertions-off outcome at exactly 2 × delta lines and the wide-window failure rate. |
| Cross-model fact check (OpenAI GPT-5.6, reading only) | real | Agreed the bug is real and rated the intended-behaviour case moderate; found the incomplete trigger table, three wording errors and four overclaims, now fixed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 446 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,196 words
- Registry title
- UniformSplit postings formats fail to flush or merge a field when deltaNumLines > targetNumBlockLines/3, a setting validateSettings accepts
- Area
- codecs / UniformSplit postings formats (BlockWriter last-block split; UniformSplit and SharedTermsUniformSplit)
- Priority
- Low, rank 688: A UniformSplit postings format built with deltaNumLines above targetNumBlockLines/3, which validation accepts, fails flushes and merges and closes the writer, loud and limited to a non-default setting nobody is known to use.
- Impact class
- crash
- Impact note
- Only applications that build UniformSplitPostingsFormat or STUniformSplitPostingsFormat (opt-in formats in the codecs module) with a non-default deltaNumLines > targetNumBlockLines/3, which validateSettings accepts, are hit: a flush, commit or merge that writes a field whose last block has between target-delta+1 and 2*delta lines throws (AssertionError with -ea, IndexOutOfBoundsException with -da; with -da the exact-2*delta case throws only for some term sets), the IndexWriter closes through its tragic-event path and buffered uncommitted documents are lost, while the last commit stays intact and passes CheckIndex; the defaults (32,3), SPI-loaded instances and every setting with 3*delta <= target cannot fail; no scale needed.
- Summary
- You build a UniformSplit (or SharedTermsUniformSplit) postings format with targetNumBlockLines=4 and deltaNumLines=2, which the constructor accepts because its documented rule is only 0 <= delta < target, and commit a field with 3 terms. You expect the commit to succeed and the blocks to hold target +- delta lines. Instead the flush throws (AssertionError 'blockLines size: 3' with assertions on, IndexOutOfBoundsException 'Index -1 out of bounds for length 3' with them off) and the IndexWriter closes, because the code that splits a field's last block assumes its look-back window of 2*delta lines starts at line 1 or later, which is false whenever 3*delta > target and the last block has between target-delta+1 and 2*delta lines.
- Introduced
- b963b7c3dbe (b963b7c3dbecda86c2917ad341caee63b93815ac, LUCENE-8753 'New UniformSplit and SharedTermsUniformSplit PostingsFormats', committed by dsmiley; PR apache/lucene-solr#828 by bruno-roustant, following #633 and absorbing #676; the JIRA issue is now apache/lucene#9798; branch_8x cherry-pick b8a1857b0bd) [read: git blame, git log -L on splitAndWriteBlock and git log -S on the deltaStart and assert lines return only this commit; validateSettings has had the same four checks since it] [exec: 8.2.0 has no uniformsplit package, 8.3.0 fails] (2019-09-06)
- First affected version
- 8.3.0 [exec] (the first release with UniformSplit; 8.2.0 lacks the package, so the repro does not compile there [exec]); main line 9.0.0 [exec]
- Affected versions
- every release that ships the UniformSplit and SharedTermsUniformSplit formats: 8.3.0-8.11.4, 9.0.0-9.12.3, 10.0.0-10.5.2 and main ea57360912ed [exec: the follow-up's history main() fails 10 of 10 bug cases (4 flushes and 1 merge per format) with 0 control failures on 8.3.0, 8.4.1, 8.5.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main, each with -ea and -da; the independent reproduction's JUnit on 10.5.2 and 9.12.3 and its main() on 8.11.4 and 8.3.0; the intended-behaviour check's public-API test on 10.5.2 with -da] [read: the releases in between by code identity, the split methods being unchanged since b963b7c3dbe]; not a regression; not fixed upstream (BlockWriter.java last changed 2021-01-03 on main and branch_10x, reformatting only; no CHANGES entry; no open PR touches BlockWriter or validateSettings) [read 2026-10-26]; executed on aarch64 with JDK 25 only
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: 113 logged query lines: a scripted prior-report search over apache/lucene issues, PRs and commits, the Elasticsearch, OpenSearch and Solr trackers, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive (249 distinct hits, 0 high overlap); 44 GitHub GraphQL issue and PR searches over apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch and opensearch-project/OpenSearch; 7 web searches; the changed-file lists of all 413 open apache/lucene PRs; a local full-history git search; plus the finder's, the independent reproduction's and the intended-behaviour check's manual searches): no issue, PR, commit, review comment, list post or downstream item reports it; the nearest items are the introducing design review (LUCENE-8753 #9798, lucene-solr #633, #676 and #828: no discussion of delta bounds or last-block splitting), LUCENE-9237 (#10277: a block-size benchmark of 26 against 32 with the default delta, outside the window) and the open LUCENE-9607 (#10647, a different test failure); 3 open PRs touch uniformsplit/ (#16851, #14716, #13525) but none touches BlockWriter or validateSettings; not fixed upstream; gaps: GitHub search cannot select closed, unmerged PRs by touched file, and web results were noise
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, together with the uniformsplit tests and the whole codecs test module. Also fails on the 10.6.0 and 10.5.2 release jars; the version sweep covers 8.2.0 (no formats) to 10.6.0. Upstream main2f424fd428da(2026-10-30) has the same code.
- Finding record
a Lucene main checkout lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/BlockWriter.java:129-140 (addLine: splitAndWriteBlock at exactly target+delta lines), :147-153 (finishLastBlock: loops splitAndWriteBlock on the residual), :161-191 (splitAndWriteBlock: :165 single-block case for numLines <= target-delta, :170 'int deltaStart = numLines - deltaNumLines * 2;', :171 'assert deltaStart >= 1 : "blockLines size: " + numLines;', :175-182 MDP loop with '<=' at :178, :184 subList(0, minMdpEndIndex)), :278-282 (addBlockKey: blockLines.get(0))a Lucene main checkout lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitTermsWriter.java:70-71 ('A good sweet spot for the target block size is 32 with delta of 3 (10%) (default values). This can be tuned in the constructor.'), :165-172 (constructor parameter contract), :188 (calls validateSettings), :238-260 (validateSettings: target > 0, delta >= 0, delta < target, target + delta <= MAX_NUM_BLOCK_LINES)a Lucene main checkout lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitPostingsFormat.java:59-66 (no-arg constructor, used by SPI: the defaults), :69-76 (javadoc: delta 'Must be greater than or equal to 0 and strictly less than targetNumBlockLines'; 'The block size will be targetNumBlockLines+-deltaNumLines'), :85-105 (public 5-argument constructor; validateSettings at :105); sharedterms/STBlockWriter.java:87-89 (finishLastBlock delegates to super)
- The finding in 30 seconds
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/BlockWriter.java:129-140 (at 645d4fe14a20) (:137-139), :147-153, :161-191 (:165-169, :170, :171, :175-182, :184), :278-282; :184-185 (subList, the end-of-field block sizes in not_intended)lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitTermsWriter.java:48-54, (at 645d4fe14a20) :102-111, :238-260, :333-334lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitPostingsFormat.java:58-66, (at 645d4fe14a20) :68-76, :85-105lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STBlockWriter.java:86-90; (at 645d4fe14a20) sharedterms/STUniformSplitPostingsFormat.java:69-86lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:585-589, (at 645d4fe14a20) :594-605; IndexWriter.java:453-454, :3879-3883, :5109-5113, :6068-6106lucene/codecs/src/test/org/apache/lucene/codecs/uniformsplit/TestBlockWriter.java:45 (at 645d4fe14a20)
- Who is affected
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitPostingsFormat.java:36, (at 645d4fe14a20) :58-66; UniformSplitTermsWriter.java:102-108lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitPostingsFormat.java:97-105; (at 645d4fe14a20) sharedterms/STUniformSplitPostingsFormat.java:78-86 (protected constructors)
- Why it looks unintended
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/UniformSplitPostingsFormat.java:36, (at 645d4fe14a20) :73-76; UniformSplitTermsWriter.java:48-50, :70-71, :169-172, :238-260lucene/codecs/src/test/org/apache/lucene/codecs/uniformsplit/TestUniformSplitPostingFormat.java:43-48; (at 645d4fe14a20) sharedterms/TestSTUniformSplitPostingFormat.java:32-37; TestBlockWriter.java:45lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java:343-361 (at 645d4fe14a20) (:354-360)
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene103/blocktree/Lucene103BlockTreeTermsWriter.java:354-360 (at 645d4fe14a20)
- TestUniformSplitLargeDeltaFlush.java (one test, public constructor):
repro/LFV-166/src/org/apache/lucene/codecs/uniformsplit/TestUniformSplitLargeDeltaFlush.java(52 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and the fix diff; re-rendered after the diagram check (section 4's wording, two more probe cases and the 10.6.0 line on the summary card).
assets/LFV-166/bug.png(446 KB)