For a dense block, docIDRunEnd() stretches the run to the end of the enclosing 8,192-doc skip block if that block is full. After a term's last complete skip block there is none: the reader stores the sentinel NO_MORE_DOCS yet counts 8,192 more docs, and the shortcut ignores the sentinel. Near 2^31 its test passes and returns NO_MORE_DOCS + 1.
- The default postings format stores a term's doc IDs in blocks of 256 (level 0). After every 32 blocks, 8,192 docs, it writes a level-1 skip entry with the last doc ID of that stretch, so
advancecan jump ahead. A term's last fewer than 8,192 docs have no level-1 entry. - A block whose 256 doc IDs are consecutive is stored as a full bit set: a dense block.
docIDRunEnd()returns one past the last doc of the run of consecutive matching docs that contains the current doc, and must be greater thandocID(). CheckIndex (level 2 and up) checks it; query scorers use it to handle a whole run at once.- Doc IDs are Java
ints:NO_MORE_DOCSis 2^31 - 1 = 2,147,483,647, and adding 1 wraps to -2,147,483,648. One index holds at mostIndexWriter.MAX_DOCS= 2,147,483,519 documents.
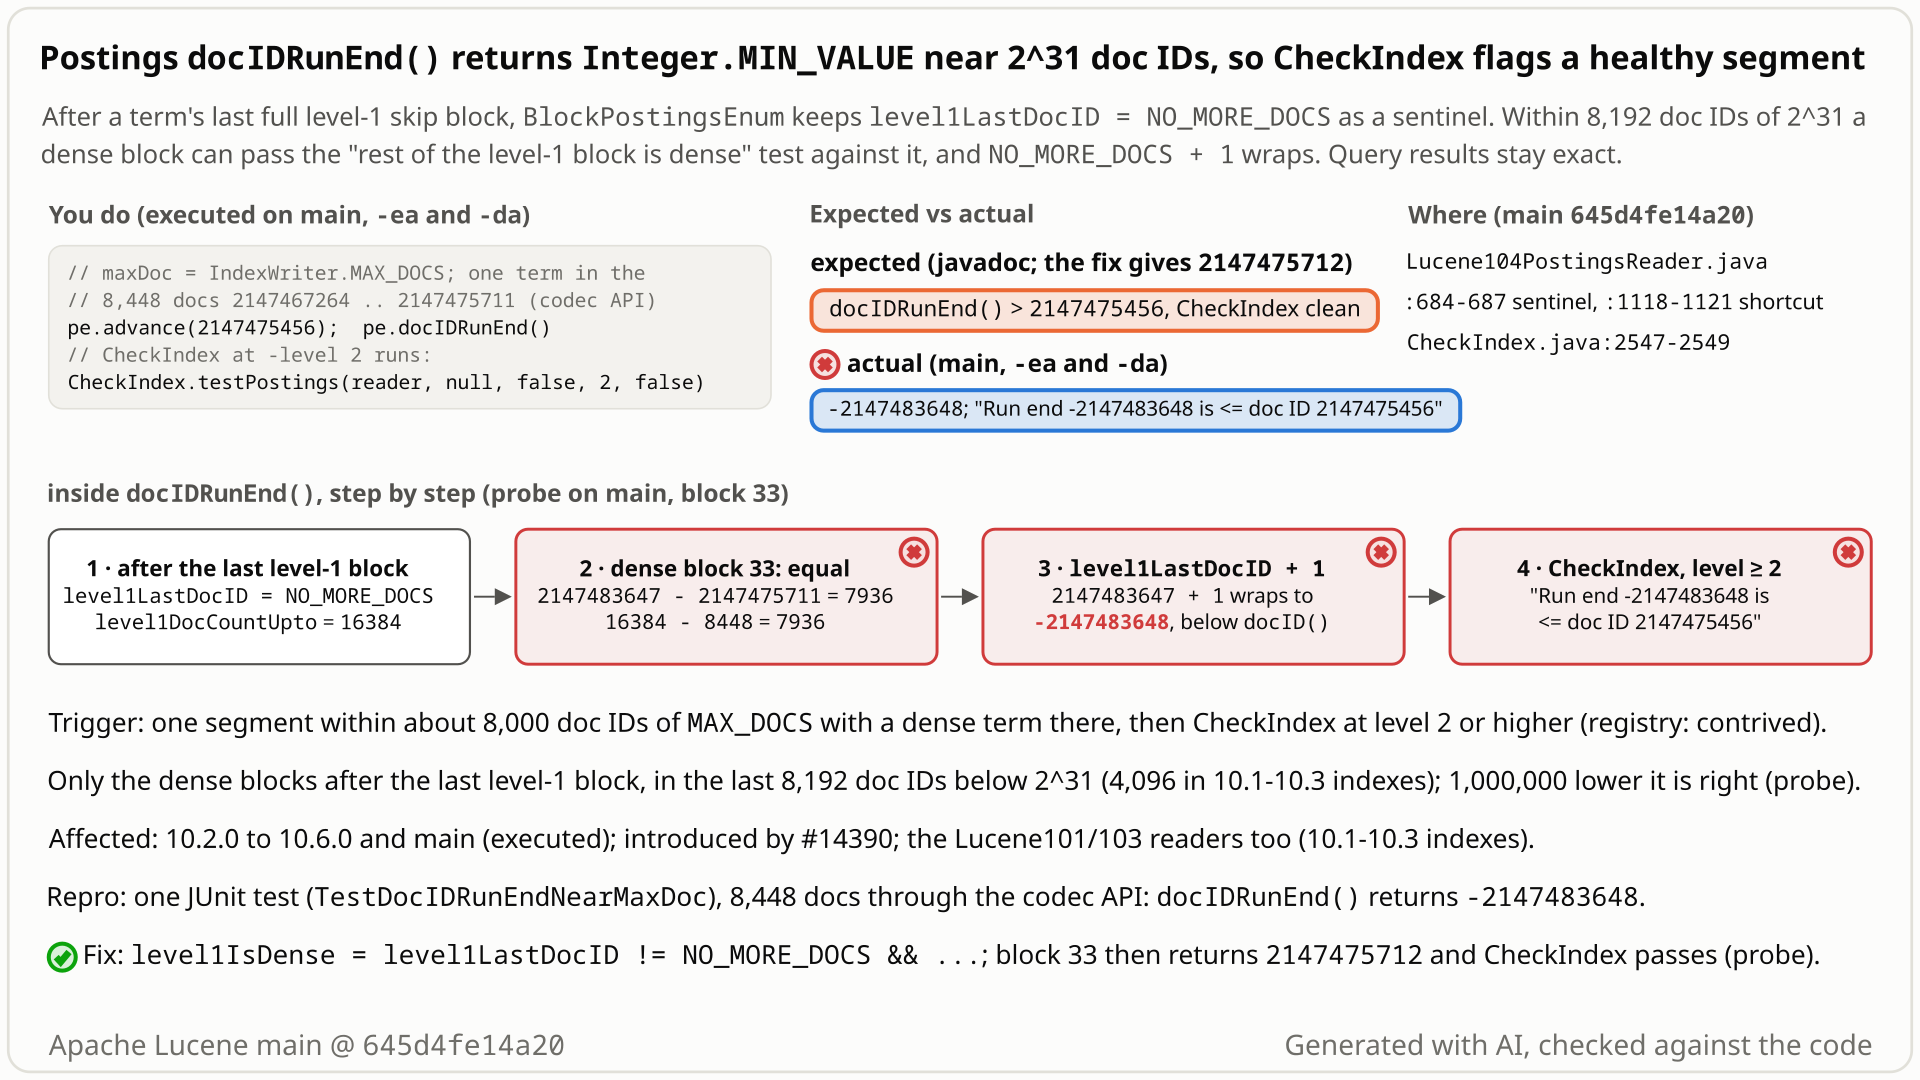
NO_MORE_DOCS + 1 = -2,147,483,648; the same layout 1,000,000 doc IDs lower gives 1,007,936 vs 7,936 and the right answer. Select the still to open it at full size. Generated with AI, checked against the code.- You force-merge an index to one segment at the limit,
IndexWriter.MAX_DOCS= 2,147,483,519 documents, each with the termf:x(the shape of Lucene's owntestExactlyAtTrueLimittest), and run CheckIndex at-level 2. - You expect "No problems were detected". At doc 2,147,475,456 the postings of
f:xare a dense block of 256 docs, sodocIDRunEnd()should return 2,147,475,712, the end of that block. - Instead it returns -2,147,483,648 there, and on all 7,936 docs of the 31 dense blocks after the term's last complete 8,192-doc skip block. CheckIndex throws "Run end -2147483648 is <= doc ID 2147475456" and reports 1 broken segment containing 2,147,483,519 documents, which
-exorcisewould remove. - Why: after the last skip block the reader marks "no next skip block" with
NO_MORE_DOCS(2,147,483,647) yet counts 8,192 more docs. The shortcut compares the doc-ID gap to that phantom block's end, 2,147,483,647 - 2,147,475,711 = 7,936, with its remaining docs, 8,192 - 256 = 7,936, finds them equal and returnsNO_MORE_DOCS + 1, which overflows. - Smaller segments are fine (a 67,108,864-doc segment is clean), queries return exact results because the bad value only shortens a run, and with a one-condition guard the full segment passes CheckIndex.
Holders of one segment within about 8,000 doc IDs of the 2^31 limit, for example a shard force-merged at MAX_DOCS, who run CheckIndex at level 2 or higher (not the default) or Lucene's test framework at that scale. Default codec, every release since 10.2.0. Searches stay exact; the risk is acting on a false corruption report.
Mechanism, terms and numbers872 words
BlockPostingsEnum#docIDRunEnd() in the default postings reader (Lucene104PostingsReader, and the same code in the Lucene101 and Lucene103 readers) extends a fully dense 256-doc block's run to the end of the enclosing 8,192-doc level-1 skip block when the doc-ID gap and the doc-count gap to that block's end are equal. After a term's last complete level-1 block there is no such block: skipLevel1To sets level1LastDocID = NO_MORE_DOCS as a sentinel but still adds 8,192 to level1DocCountUpto, and the shortcut does not exclude the sentinel. For ordinary doc IDs the gaps differ by about two billion and the method is correct; within 8,192 doc IDs of 2^31 they can be equal, and the method returns NO_MORE_DOCS + 1 = Integer.MIN_VALUE, breaking its contract ("The returned doc is greater than docID()").
For a term in every document this happens on every dense block after the term's last complete level-1 block once maxDoc >= 2,147,475,712, up to IndexWriter.MAX_DOCS = 2,147,483,519. On a default-codec segment of exactly MAX_DOCS documents written by IndexWriter, CheckIndex at level 2 reports "Run end -2147483648 is <= doc ID 2147475456" and "1 broken segments (containing 2147483519 documents)", and says -exorcise would remove the segment; with a one-condition guard the same segment is clean. Query results stay exact (the value is below docID(), so consumers only lose a shortcut). Introduced by #14390 in 10.2.0; every release from 10.2.0 to 10.6.0 and main is affected.
Constants: BLOCK_SIZE = 256, LEVEL1_FACTOR = 32, LEVEL1_NUM_DOCS = 8,192 (Lucene104PostingsFormat.java:343, :348, :351).
- Small terms never reach it. With
docFreq < LEVEL1_NUM_DOCSthe enum starts withlevel1LastDocID = NO_MORE_DOCSandlevel1DocCountUpto = 0(Lucene104PostingsReader.java:559-568); the shortcut's right side is then negative and can never match. A term needs at least one complete level-1 block. - The sentinel state.
skipLevel1To(:674on) computesdocCountLeft = docFreq - level1DocCountUpto(:683), then addsLEVEL1_NUM_DOCStolevel1DocCountUpto(:684), and only then, if fewer than 8,192 docs are left, setslevel1LastDocID = NO_MORE_DOCSand stops (:686-688). In a term's tail the counter therefore includes a full phantom level-1 block. - The unguarded shortcut.
docIDRunEnd()(:1099-1129), for a UNARY block whose four 64-bit words are all set (:1101-1115), computeslevel0DocCountUpto = docFreq - docCountLeft(:1117) and testslevel1LastDocID - level0LastDocID == level1DocCountUpto - level0DocCountUpto(:1118-1119); if true it returnslevel1LastDocID + 1(:1121), elselevel0LastDocID + 1(:1124). - When it misfires. For the j-th full block after the last complete level-1 block (j = 1..31) the right side is 8,192 - 256 x j (at most 7,936) and the left side is
NO_MORE_DOCS - level0LastDocID, about two billion for ordinary doc IDs. They are equal exactly whenlevel0LastDocID = NO_MORE_DOCS - (8,192 - 256 x j), so only blocks whose docs are all at or above 2^31 - 8,192 = 2,147,475,456 can trigger it; then:1121returnsNO_MORE_DOCS + 1=Integer.MIN_VALUE, with assertions on or off. - Worked example (the minimal test). One term of 8,448 consecutive doc IDs, 2,147,467,264 to 2,147,475,711: one complete level-1 block ending at 2,147,475,455, then one dense block 2,147,475,456 to 2,147,475,711. At doc 2,147,475,456:
level1LastDocID= 2,147,483,647 (sentinel),level1DocCountUpto= 16,384 (two blocks counted, one exists),level0LastDocID= 2,147,475,711,level0DocCountUpto= 8,448. Left 7,936, right 7,936: it returns -2,147,483,648 instead of 2,147,475,712. Shifted 1,000,000 doc IDs lower, the left side is 1,007,936 and the answer is right. - A term in every document. After k complete level-1 blocks the test reduces to k x 8,192 = 2^31 - 8,192, so k = 262,143: it fires on every dense tail block exactly when
maxDocis in [2,147,475,712,MAX_DOCS]. A Z3 bit-vector model with Javaintsemantics derived this range (unique k) and proved the bad state unreachable whilelevel0LastDocID < MAX_DOCS - 16,386. - The reader knows the sentinel elsewhere.
Impacts.numLevels()returns 1 whenlevel1LastDocID == NO_MORE_DOCS(:1358);docIDRunEnd()does not check it. - Older formats. The backward-codecs readers for indexes written by 10.1.x to 10.3.x (Lucene101 and Lucene103 formats) have the same shortcut with 128-doc blocks and 4,096-doc level-1 blocks (
Lucene101PostingsReader.java:1059-1062,Lucene103PostingsReader.java:1105-1108, sentinel at:679in both); their first failing doc is 2,147,479,552. 10.1.0 code has no postingsdocIDRunEnd, but 10.1.0 already writes the Lucene101 format, and a term it wrote near 2^31 returns -2,147,483,648 at doc 2,147,479,552 once main reads it (executed). - Who sees the value. CheckIndex
testPostingsruns only at level >= 2 (CheckIndex.java:1114-1125,:4754) and checks runs of every term withdocFreq > 1024, every 1024th term, or all terms at level 3 (:2090-2104);checkDocIDRunsthrows "Run end X is <= doc ID Y" (:2549) and the segment is reported FAILED with "exorciseIndex() would remove reference to this segment" (:1208). The CLI default is level 1 (:4742,:4748);new CheckIndex(dir)withoutsetLevelkeeps 0 (:499). The test framework'sAssertingPostingsEnumassertsendDocID > startDocID(AssertingLeafReader.java:609).DenseConjunctionBulkScorerevaluates a clause with a short run end normally andDisjunctionDISIApproximationdiscards it withMath.max(DenseConjunctionBulkScorer.java:196-212,DisjunctionDISIApproximation.java:225-233).
Exposure and likelihood302 words
- Who is hit. A single segment within about 8,000 doc IDs of
IndexWriter.MAX_DOCSwith a term that is dense near the end of the doc-ID space, for example a term in every document of a shard force-merged to one segment at the hard limit, checked with CheckIndex at level 2 or higher, or Lucene's own tests at that scale with the default postings format (such astestExactlyAtTrueLimit: predicted, not run). - Default vs opt-in. The default codec and
IndexWritersettings produce the state; nothing is configured. Seeing it needs CheckIndex at level 2 or 3 (the CLI default is 1), the test framework's check-on-close, or a caller ofdocIDRunEnd()that relies on the contract. - Scale.
maxDoc >= 2,147,475,712for a term in every document; in general a dense 256-doc block whose docs are all at or above 2,147,475,456 (2,147,479,552 for indexes written by 10.1.x to 10.3.x) right after the term's last complete level-1 block. A 67,108,864-doc segment is clean. - What goes wrong. CheckIndex reports a valid segment as broken ("1 broken segments (containing 2147483519 documents)") and says
-exorcisewould remove it; an operator who trusts it and runs-exorcisewould drop about 2^31 healthy documents (follows from CheckIndex's code and warning; not executed).docIDRunEnd()breaks its contract on up to 7,936 docs per term. Under the test framework,AssertingPostingsEnumfails. - Queries are fine. The value is below
docID(), so it can only shorten a run. Five FILTER conjunctions, some with nested disjunctions, over aMAX_DOCSsegment with holes inside the affected tail returned exact results with assertions on and off while the bad value was consumed 2 to 4 times per query; the same with the fix, with no measurable time difference. - Likelihood: contrived. Almost no deployment runs single segments at the 2^31 limit, but Lucene supports and tests that limit.
One JUnit test, about 2 seconds: it writes one term of 8,448 consecutive doc IDs ending at 2,147,475,711 with the default postings writer, in a segment of IndexWriter.MAX_DOCS documents, reads it back, advances to doc 2,147,475,456 and checks only the docIDRunEnd() contract. It fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene104;

import java.util.HashMap;
import java.util.Map;
import org.apache.lucene.codecs.Codec;
import org.apache.lucene.codecs.lucene104.Lucene104PostingsFormat.IntBlockTermState;
import org.apache.lucene.index.DocValuesSkipIndexType;
import org.apache.lucene.index.DocValuesType;
import org.apache.lucene.index.FieldInfo;
import org.apache.lucene.index.FieldInfos;
import org.apache.lucene.index.IndexOptions;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.PostingsEnum;
import org.apache.lucene.index.SegmentInfo;
import org.apache.lucene.index.SegmentReadState;
import org.apache.lucene.index.SegmentWriteState;
import org.apache.lucene.index.VectorEncoding;
import org.apache.lucene.index.VectorSimilarityFunction;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.InfoStream;
import org.apache.lucene.util.StringHelper;
import org.apache.lucene.util.Version;

public class TestDocIDRunEndNearMaxDoc extends LuceneTestCase {

  public void testDenseBlockAfterLastLevel1Block() throws Exception {
    FieldInfo fi =
        new FieldInfo(
            "f", 0, false, true, false, IndexOptions.DOCS, DocValuesType.NONE,
            DocValuesSkipIndexType.NONE, -1, Map.of(), 0, 0, 0, 0, VectorEncoding.FLOAT32,
            VectorSimilarityFunction.EUCLIDEAN, false, false);
    FieldInfos fieldInfos = new FieldInfos(new FieldInfo[] {fi});
    int firstDoc = Integer.MAX_VALUE - 16383;
    try (Directory dir = new ByteBuffersDirectory()) {
      SegmentInfo si =
          new SegmentInfo(
              dir, Version.LATEST, Version.LATEST, "_0", IndexWriter.MAX_DOCS, false, false,
              Codec.getDefault(), Map.of(), StringHelper.randomId(), new HashMap<>(), null);
      IntBlockTermState state = new IntBlockTermState();
      state.docFreq = 8192 + 256;
      SegmentWriteState writeState =
          new SegmentWriteState(InfoStream.NO_OUTPUT, dir, si, fieldInfos, null, IOContext.DEFAULT);
      try (Lucene104PostingsWriter writer = new Lucene104PostingsWriter(writeState)) {
        writer.setField(fi);
        writer.startTerm(null);
        for (int i = 0; i < state.docFreq; i++) {
          writer.startDoc(firstDoc + i, 1);
          writer.finishDoc();
        }
        writer.finishTerm(state);
      }
      SegmentReadState readState = new SegmentReadState(dir, si, fieldInfos, IOContext.DEFAULT);
      try (Lucene104PostingsReader reader = new Lucene104PostingsReader(readState)) {
        PostingsEnum pe = reader.postings(fi, state, null, PostingsEnum.NONE);
        int doc = pe.advance(firstDoc + 8192);
        int runEnd = pe.docIDRunEnd();
        // one level-1 block, then a dense block: expected runEnd > docID(), actual MIN_VALUE
        assertTrue("expected docIDRunEnd() > " + doc + ", got " + runEnd, runEnd > doc);
      }
    }
  }
}
cp $REPRO/TestDocIDRunEndNearMaxDoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene104/
cd $LUCENE
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene104.TestDocIDRunEndNearMaxDoc
./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene104.TestDocIDRunEndNearMaxDoc -Ptests.asserts=false
- Expected
docIDRunEnd()returns a doc greater than 2,147,475,456 (2,147,475,712, the end of the dense block, with the fix).- Observed
docIDRunEnd()returns -2,147,483,648 (Integer.MIN_VALUE); on a fullMAX_DOCSsegment CheckIndex reports "Run end -2147483648 is <= doc ID 2147475456".
More files, environment, full output403 words
The test is codec level: it uses the public Lucene104PostingsWriter (setField, startTerm, startDoc/finishDoc, finishTerm) on a SegmentInfo with maxDoc = IndexWriter.MAX_DOCS, then Lucene104PostingsReader.postings (marked @lucene.experimental) with the term state the writer filled in. The terms dictionary is skipped because docIDRunEnd does not use it. The doc IDs must be consecutive across the level-1 boundary: with docs 0..8,191 followed by the 256-doc block, that block's first delta is large, it is stored PACKED rather than dense, and the test passes on main.
It is deterministic (the failing value does not depend on the seed; seeds DEADBEEF, 5EED1234 and 7E1B4EA4 fail), single-threaded and needs the default test heap. The FieldInfo arguments are packed for brevity (./gradlew tidy reformats them). As a regression test it can stay its own class or become a method of TestLucene104PostingsFormat (same package).
The CheckIndex report is not part of this test. It was seen end to end on a segment of exactly MAX_DOCS documents that IndexWriter wrote (a plain program with only lucene-core: two small single-segment indexes built with addDocument and forceMerge(1), then addIndexes(CodecReader...) of 512 copies into one new segment, about 4 minutes and 79 MB), and in the study's codec-level CheckIndex.testPostings runs. The @Monster test testExactlyAtTrueLimit itself was not run.
| lucene | main 645d4fe14a20; also fails on the 10.4.0, 10.5.2 and 10.6.0 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
# gradle, main 645d4fe14a20, stock (same failure with -Ptests.asserts=false)
> Task :lucene:core:test FAILED

TestDocIDRunEndNearMaxDoc > testDenseBlockAfterLastLevel1Block FAILED
    java.lang.AssertionError: expected docIDRunEnd() > 2147475456, got -2147483648
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:71C1222622114FDE]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.codecs.lucene104.TestDocIDRunEndNearMaxDoc.testDenseBlockAfterLastLevel1Block(TestDocIDRunEndNearMaxDoc.java:77)
:lucene:core:test (FAILURE): 1 test, 1  failure

# with the fix: :lucene:core:test (SUCCESS): 1 test (assertions on and off)

# end to end: IndexWriter-built segment of MAX_DOCS documents, CheckIndex level 2, main, assertions off (excerpt; timestamps removed)
advance(2147475456) = 2147475456, docIDRunEnd() = -2147483648
docIDRunEnd() contract (result > docID()) over 8063 postings from 2147475456 to 2147483518: violations=7936 first at doc 2147475456 (docIDRunEnd()=-2147483648), last at doc 2147483391
1 of 1: name=_0 maxDoc=2147483519
    codec=Lucene104
    test: terms, freq, prox...ERROR: org.apache.lucene.index.CheckIndex$CheckIndexException: Run end -2147483648 is <= doc ID 2147475456
FAILED
    WARNING: exorciseIndex() would remove reference to this segment; full exception:
WARNING: 1 broken segments (containing 2147483519 documents) detected

# same index with the guard
advance(2147475456) = 2147475456, docIDRunEnd() = 2147475712
    test: terms, freq, prox...OK [1 terms; 2147483519 terms/docs pairs; 2147483519 tokens]
No problems were detected with this index.docIDRunEnd()promises "The returned doc is greater than docID()", with no exception near 2^31; CheckIndex andAssertingPostingsEnumenforce it.IndexWriter.MAX_DOCS= 2,147,483,519 is the documented hard limit, and Lucene's@MonstertesttestExactlyAtTrueLimitbuilds this segment shape.- The same reader treats the sentinel as "no level 1" in
Impacts.numLevels(); no review of the shortcut ever discussed it.
The full argument200 words
- Contract.
DocIdSetIterator.java:245-263: "1. The returned doc is greater thandocID(). 2. All docs in range[docID(), docIDRunEnd())match this iterator." The only exception: "It is illegal to call this method when the iterator is exhausted or not positioned." The method is public, without@lucene.internalor@lucene.experimental. - Lucene enforces it. #14390 added the postings shortcut together with
CheckIndex.checkDocIDRuns, which rejects a run end<= doc;AssertingPostingsEnumasserts it too. - The limit is supported.
IndexWriter.MAX_DOCS=Integer.MAX_VALUE - 128is the "Hard limit on the maximum number of documents that may be added to the index" (IndexWriter.java:202-208).TestIndexWriterMaxDocs#testExactlyAtTrueLimit(:47-89) adds exactlyMAX_DOCSdocuments with oneStringField, callsforceMerge(1)and closes a test directory, which runs CheckIndex. - The reader handles the sentinel elsewhere.
Impacts.numLevels()(Lucene104PostingsReader.java:1358). - History. The bodies, comments and reviews of #14390, #14693 and #15160 never mention the
NO_MORE_DOCSlevel-1 sentinel or doc IDs near 2^31; no comment, test,CHANGES.txtorMIGRATE.mdentry allowsInteger.MIN_VALUE. - Precedent. #16161 "SkipBlockRangeIterator: Don't extend docIdRunEnd into sparse blocks" (merged 2026-06-01) fixed the same class of bug, a run end extended up the skip levels without a density check, in the doc-values skipper iterator.
The devil's-advocate check214 words
The strongest case for "not a bug": (1) nobody runs a single segment within 8,192 docs of 2^31; (2) the first repros wrote postings through @lucene.experimental codec classes and a hand-built SegmentInfo instead of IndexWriter; (3) the sentinel looks meant to make the density test fail, so the author assumed doc IDs stay far from 2^31; (4) no query returns a wrong result. A later reading-only adversary also gave a procedural "not real" because it could not run code; on the merits it agreed with the root cause and the fix.
Why it fails: (1) the limit is documented and has its own test; (2) the same value at the same doc was reproduced on a segment that IndexWriter wrote and DirectoryReader opened, and the codec-level test only feeds the default writer legal doc IDs below MAX_DOCS; (3) that assumption is written nowhere, the contract has no exception, and the reader's own numLevels() handles the sentinel; (4) low impact lowers the priority, it does not make a false corruption report intended. Nor is it a case of an absurd parameter that then fails loudly: the parameter is Lucene's own tested limit, and the loud failure is a false report on a valid segment that recommends removing it. Verdict: a defect, low priority.
Recommended Guard the shortcut against the sentinel, in all three readers
Skip the level-1 shortcut when level1LastDocID is the NO_MORE_DOCS sentinel: level1IsDense = level1LastDocID != NO_MORE_DOCS && (the existing equality), in the Lucene104 reader and in the Lucene101 and Lucene103 readers of backward-codecs. Reader-only, no format change; the test passes and the closest suites, including the nightly testDocIDRunEnd, stay green.
int level0DocCountUpto = docFreq - docCountLeft;
// After the last complete level-1 block, level1LastDocID is the NO_MORE_DOCS sentinel:
// there is no level-1 block to extend the run into.
boolean level1IsDense =
    level1LastDocID != NO_MORE_DOCS
        && level1LastDocID - level0LastDocID == level1DocCountUpto - level0DocCountUpto;
if (level1IsDense) {
  return level1LastDocID + 1;
}
return level0LastDocID + 1;
All options and trade-offs3 options · 516 words
Two fixes were checked; the guard is the smaller and fully validated one.
Guard the shortcut against the sentinel, in all three readers (validated by the checks) (recommended)
+12/-3 in Lucene104PostingsReader, backward_codecs/lucene101/Lucene101PostingsReader and backward_codecs/lucene103/Lucene103PostingsReader (the last two with two spaces less indentation). In a term's tail the method falls back to level0LastDocID + 1, the end of the current dense block; wherever a real level-1 block exists the shortcut is unchanged.
int level0DocCountUpto = docFreq - docCountLeft;
// After the last complete level-1 block, level1LastDocID is the NO_MORE_DOCS sentinel:
// there is no level-1 block to extend the run into.
boolean level1IsDense =
    level1LastDocID != NO_MORE_DOCS
        && level1LastDocID - level0LastDocID == level1DocCountUpto - level0DocCountUpto;
if (level1IsDense) {
  return level1LastDocID + 1;
}
return level0LastDocID + 1;
Trade-offs
- One extra
intcomparison per call on a dense block. No result changes outside the bug window: for terms below 8,192 docs, and for tails far from 2^31, the equality is already false. - Reader-only: no format change; existing indexes written by 10.1.x to 10.6.x are read correctly without reindexing (the data on disk is valid).
- Mirrors how
Impacts.numLevels()already treats the sentinel.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20, JDK 25.0.3: the minimal test fails stock and passes with the fix, with assertions on and off. - With the fix:
org.apache.lucene.codecs.lucene104.*,TestCheckIndex,TestDenseConjunctionBulkScorer,TestBulkScorerConsistencyandTestDocIdSetIterator: 12 classes, 226 tests, 6 skipped, 0 failures; backward-codecslucene101.*andlucene103.*: 11 classes, 106 tests, 6 skipped, 0 failures. - The
@NightlyBasePostingsFormatTestCase#testDocIDRunEnd(100 force-merged IndexWriter segments, each checked by CheckIndex at level 3; skipped by default) with-Ptests.nightly=trueforTestLucene104PostingsFormat,TestLucene101PostingsFormat,TestLucene101PostingsFormatV0andTestLucene103PostingsFormat: 4 tests, 0 failures. :lucene:core:check :lucene:backward-codecs:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- The Lucene104 hunk alone makes the IndexWriter-built
MAX_DOCSsegment CheckIndex-clean; ported to the 10.2.0 reader it makes the version-spanning probe pass.
In skipLevel1To, move level1DocCountUpto += LEVEL1_NUM_DOCS; below the if (docCountLeft < LEVEL1_NUM_DOCS) { level1LastDocID = NO_MORE_DOCS; break; } block, so the counter only counts level-1 blocks that exist. In the tail the shortcut's right side is then negative and never matches.
docCountLeft = docFreq - level1DocCountUpto;

if (docCountLeft < LEVEL1_NUM_DOCS) {
  level1LastDocID = NO_MORE_DOCS;
  break;
}
level1DocCountUpto += LEVEL1_NUM_DOCS;
Trade-offs
Fixes the state where it is created and also stops level1DocCountUpto from wrapping to Integer.MIN_VALUE for an all-docs term at MAX_DOCS (262,144 x 8,192 = 2^31 with the phantom block). The field is read only in skipLevel1To and docIDRunEnd, and the method is not entered again after the sentinel, but it touches the advance path and changes a field's meaning, so it needs a closer review; the two backward-codecs readers need the same change.
What the checks validated
The minimal test passes with only this change shadowed into the stock main jar, assertions on and off. No suites were run.
Would silence the false report.
Trade-offs
Hides a real contract violation from every other caller of docIDRunEnd().
Tools that run CheckIndex at level 2 or higher on segments near 2^31 documents and act on the verdict automatically, for example with -exorcise, would drop a healthy segment.
While modelling the Lucene104 postings reader's skip state, the finder noticed that the level-1 shortcut does not exclude the NO_MORE_DOCS sentinel. A Z3 bit-vector model with Java int semantics then gave a witness, proved the state unreachable below about 2^31 - 2^14 doc IDs, and the exact all-docs range, which a codec-level test and an all-docs run confirmed.
The method in full245 words
Method: semi-formal (the hypothesis came from code reading; the SMT model then produced the witness, the unreachability bound and the exact trigger range).
- The finder's hunt unit modelled the Lucene104 reader's skip state. Reading
docIDRunEndnext toskipLevel1To, it noticed that the level-1 shortcut compares a doc-ID gap measured from theNO_MORE_DOCSsentinel with a doc count that includes a phantom level-1 block. - A Z3 bit-vector model of the skip arithmetic with 32-bit Java
intsemantics: Q4a found a witness (level0LastDocID= 2,147,477,503, returningNO_MORE_DOCS + 1); Q4b showed the state unreachable whilelevel0LastDocID < MAX_DOCS - 16,386; Q4c gave the all-docs trigger range,maxDocin [2,147,475,712,MAX_DOCS] with the unique count k = 262,143 of complete level-1 blocks. - A codec-level JUnit on the stock jar failed on main (assertions on and off) and on 10.4.0 and 10.5.2 (assertions on). A run on a separate test host wrote 2,147,475,712 postings of an all-docs term in 10.7 s and failed a CheckIndex-style loop at doc 2,147,475,456, the first doc of the predicted tail block.
- The unit's postings differential (191 million checks, 0 mismatches) never reached doc IDs near 2^31; its mutant "level-1 density always true" was killed, so the shortcut is exercised at ordinary scale.
- Cross-model reviews, an independent reproducer, a devil's advocate and an adjudication then confirmed it; the repro was later cut to the one test above, and a tie-break on current main reproduced it on an IndexWriter-built segment.
No prior report found in GitHub issues and PRs (including the migrated JIRA issues), commits, five mailing lists, downstream projects or the web; last refreshed 2026-10-31. Closest: #16161, the same class of run-end bug in the doc-values skipper iterator.
Searches5 searches
Verdict new. "New" means no public report was found; private reports to the security list and unindexed chats cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, incl. migrated JIRA), commits, downstream projects, web | 2026-10-31 (earlier rounds 2026-10-22/23 and 2026-10-26) | 139 queries: identifiers (docIDRunEnd, level1LastDocID, level1IsDense, level1DocCountUpto, skipLevel1To, LEVEL1_NUM_DOCS, checkDocIDRuns), symptoms ("Run end", "is <= doc ID", Integer.MIN_VALUE, -2147483648) and scale (MAX_DOCS, testExactlyAtTrueLimit, 2^31); 15 manual GitHub searches | 355 distinct hits, 0 high and 22 medium overlap, none the same bug |
| Mailing lists (dev@, java-user@, issues@, commits@, builds@) | 2026-10-31 | 40 queries in the main run plus 20 in a lists run | 61 hits in the lists run, all low overlap; no report |
| Open PRs | 2026-10-31 | changed files of all 410 open PRs matched against the postings readers and writers, CheckIndex and DocIdSetIterator (26 PRs) | none changes docIDRunEnd, level1IsDense or checkDocIDRuns |
| Threads read in full | 2026-10-31 | #14390, #14693, #15160, #13585, #13862, #13892, the 10.6.0 announcement and CHANGES.txt | the sentinel and doc IDs near 2^31 are never discussed; listed docIDRunEnd fixes are for doc-values iterators and BitSetIterator |
| GitHub refresh | 2026-10-31 | docIDRunEnd, level1IsDense, "Run end is <= doc ID", Lucene104PostingsReader; issues and PRs updated since 2026-10-30 | no results |
Introduced in 10.2.0 by #14390 (2025-03-24), which added the shortcut and CheckIndex's run check; copied into the 10.3 and 10.4 readers. Affects 10.2.0 to 10.6.0 and main; 10.1.0 and older have no postings docIDRunEnd, but 10.1.x indexes are affected once 10.2.0 or later reads them. Not fixed upstream.
Versions tested7 rows
Introduced by #14390 "Implement #docIDRunEnd() on PostingsEnum." (author and merger jpountz, approved by gf2121; db00348ef18e on main and the backport 6bef45756a96, both 2025-03-24), which added the level1IsDense shortcut to Lucene101PostingsReader and CheckIndex.checkDocIDRuns. #14693 (06afbe701640, 10.3.0) copied the method into Lucene103PostingsReader; #15160 (00f2b01e7985, 10.4.0, 256-doc blocks) kept the level-1 expression. The sentinel state itself comes from #13585 (b4a8810b7ae, 9.12.0) and was harmless before #14390. Not fixed: upstream main 2f424fd428da, branch_10_6 and the 10.6.0 tag still have the unguarded expression.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off; an IndexWriter-built MAX_DOCS segment fails CheckIndex level 2 at doc 2,147,475,456 |
| 10.4.0 to 10.6.0 | affected | Lucene104 format: first failing doc 2,147,475,456 (minimal test on 10.4.0, 10.5.2 and 10.6.0) |
| 10.2.0 to 10.3.2 | affected | Lucene101/103 formats: first failing doc 2,147,479,552; CheckIndex reports the segment broken |
| 9.12.3, 10.0.0, 10.1.0 | not affected | no postings docIDRunEnd; the same near-limit postings read back exactly and CheckIndex is clean |
| 10.1.0 index read on main | affected | Lucene101 format version 0 written by 10.1.0: main's Lucene101PostingsReader returns -2,147,483,648 at doc 2,147,479,552; 1,000,000 lower it is right |
| 10.2.0 with only the guard | fix | the version-spanning probe passes |
| main with the guard (three readers) | fix | minimal test passes; closest suites and nightly testDocIDRunEnd green; MAX_DOCS segment CheckIndex-clean |
The study's cross-model reviews (OpenAI GPT-5.6), independent reproducer, devil's advocate and adjudication rated it real. On current main a reading-only cross-model adversarial review could not run code and gave a procedural "not real"; a tie-break then reproduced the bug on an IndexWriter-built segment of 2,147,483,519 documents.
Checks and verdicts269 words
| Check | Verdict | What it found |
|---|---|---|
| Finder (code reading, Z3 skip-state model, codec-level JUnit) | candidate | Fails on main (assertions on and off) and on 10.4.0 and 10.5.2 (assertions on); an all-docs run of 2,147,475,712 postings fails at doc 2,147,475,456. |
| Cross-model review, refute lens (OpenAI GPT-5.6, executed) | real (high) | Own test fails 1 of 2, control passes; the guard passes it and an IndexWriter-built docIDRunEnd test over 100 iterations. |
| Independent reproducer | real | Own tests with a different witness fail on main, 10.5.2, 10.4.0, 10.3.2 and 10.2.0; controls 1,000,000 doc IDs lower pass; an all-docs term fails at both ends of the Z3 range and passes just below it. |
| Cross-model adversary, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Experimental codec classes do not exempt the public docIDRunEnd contract; MAX_DOCS is supported and tested. |
| Devil's advocate | real | No intended argument survives; corrected the CheckIndex level to 2 or higher. |
| Adjudication | confirmed (high) | Re-ran the independent repro with a new seed. |
| Security screen | not security-sensitive | Five FILTER conjunctions over a MAX_DOCS segment return exact results while the bad value is consumed. |
| Current-main reproducer (2026-10-31) | real | Minimal test fails on main 645d4fe14a20, 10.5.2 and 10.6.0, assertions on and off; passes with the guard. |
| Cross-model adversary on current main (GPT, reading only) | not real (procedural) | Could not run code; agreed with the root cause and the fix; asked for an IndexWriter-built segment. |
| Tie-break (2026-10-31) | real (high) | IndexWriter-built segment of 2,147,483,519 documents: CheckIndex level 2 reports it broken; with the guard it is clean; 263,144- and 67,108,864-doc controls are clean. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 486 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,399 words
- Registry title
- Postings docIDRunEnd() returns Integer.MIN_VALUE for dense blocks after a term's last level-1 skip block when doc IDs are within 8,192 (4,096 before 10.4) of 2^31, so CheckIndex at level 2 or higher reports a healthy segment of about 2^31 documents as corrupt
- Area
- codecs / postings reader (Lucene104 BlockPostingsEnum#docIDRunEnd, also the Lucene101 and Lucene103 readers); index / CheckIndex
- Priority
- Low, rank 983: The postings docIDRunEnd() returns Integer.MIN_VALUE near 2^31 docs, so CheckIndex flags a healthy segment as corrupt while query results stay exact.
- Impact class
- wrong error
- Impact note
- Hits only holders of a single segment within about 8,000 doc IDs of IndexWriter.MAX_DOCS (maxDoc >= 2,147,475,712 for a term in every document, for example a shard force-merged to one segment at the hard limit) who run CheckIndex at level 2 or higher (or the test framework's check-on-close): they get a false 'Run end -2147483648 is <= doc ID ...' corruption report on a healthy segment, which -exorcise would turn into a dropped segment; default codec, every release since 10.2.0; query results stay exact (executed), only a dense-run shortcut is lost on at most 31 tail blocks per term.
- Summary
- You have one segment of about 2^31 documents (within about 8,000 docs of IndexWriter.MAX_DOCS) with a term whose postings are dense near the end of the doc-ID space, for example a term that every document has, and you call docIDRunEnd() on its postings or run CheckIndex at level 2 or higher. You expect docIDRunEnd() to return a doc ID greater than the current one, as its javadoc promises, and CheckIndex to pass. Instead, in the dense blocks after the term's last full 8,192-doc level-1 skip block (4,096 docs in 10.2-10.3), the default postings reader returns Integer.MIN_VALUE and CheckIndex reports the healthy segment as corrupt ('Run end -2147483648 is <= doc ID 2147475456'); query results stay correct, and the repro writes the postings through the public codec API rather than indexing 2^31 documents with IndexWriter.
- Introduced
- db00348ef18e3a8090bdab478bdc525f8297d8b9 (main) and its branch_10x backport 6bef45756a96df61cf9c8b34644327b53d651330, PR #14390 'Implement #docIDRunEnd() on PostingsEnum.' (author and merger jpountz, approved by gf2121), which added the level1IsDense shortcut to Lucene101PostingsReader without excluding the NO_MORE_DOCS level-1 sentinel; copied verbatim into Lucene103PostingsReader by #14693 (06afbe701640, 10.3.0) and kept by #15160 (00f2b01e7985, Lucene104 with 256-doc blocks, 10.4.0) [read: git log -S 'level1IsDense' over the three readers returns exactly these 3 commits, git blame -w -M -C -C, git tag --contains and merge-base on the backports; exec: release level, 10.1.0 unaffected because the API is absent, 10.2.0 fails, and adding only the guard flips 10.2.0 and main to pass]; the sentinel state itself (level1DocCountUpto advanced by a full block, level1LastDocID = NO_MORE_DOCS) comes from #13585 (b4a8810b7ae, 9.12.0) and was harmless before #14390 [exec: 9.12.3, 10.0.0 and 10.1.0 read the same near-limit postings back exactly and CheckIndex is clean] (2025-03-24 (merged on main; branch_10x backport the same day))
- First affected version
- 10.2.0 [exec] (10.1.0 is the last unaffected release: DocIdSetIterator#docIDRunEnd, #14312, first shipped in 10.2.0 [exec: 9.12.3, 10.0.0 and 10.1.0 pass; the independent reproduction's repro does not compile on 10.1.0])
- Affected versions
- 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2, 10.6.0 and main ea57360912ed (-ea and -da). [exec 2026-10-31] 10.6.0 release jars (SHA-1 checked against Maven Central): the minimal test fails with -ea and -da and the version-spanning probe fails with -ea. [exec, codec level] the follow-up's version-spanning probe fails on all 10 releases and main; the independent reproduction's repro fails on 10.2.0, 10.3.2, 10.4.0, 10.5.2 and main; the finder's on 10.4.0, 10.5.2 and main; window: the last 4,096 doc IDs below 2^31 for Lucene101/103 (10.2.x-10.3.x, failing doc 2147479552), the last 8,192 for Lucene104 (10.4.0 on, failing doc 2147475456). [read] the unreleased branch_10x and branch_10_6 and the backward-codecs Lucene101 and Lucene103 readers on main (which read 10.2.x and 10.3.x indexes) have the identical expression. Not fixed upstream: main, branch_10x and branch_10_6 heads still unguarded (read-only check, 2026-10-26).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code and voted “not real” while agreeing with the root cause (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading
- Upstream and prior reports
- none found (2026-10-26, verdict new: five scripted prior-report searches (the finder's and four follow-up runs) with 86 distinct queries: 30 GitHub issue/PR, 5 commit, 6 downstream (Elasticsearch, OpenSearch, Solr), 30 mailing-list over dev@, java-user@, issues@, commits@ and builds@, 9 JIRA-archive and 6 web queries; plus 9 manual checks: the changed-file lists of all 413 open apache/lucene PRs, the diffs of the 4 open PRs that touch postings readers, the comments and review comments of #14390 and #14693, the upstream commit history and contents of the readers, CHANGES.txt, LUCENE-8520 and 8 builds@ threads read in full; 22 hits read, none the same bug); not fixed: upstream main ea57360912ed, branch_10x 1309534296e3 and branch_10_6 2763db11b0a7 still have the unguarded expression, the last commit to Lucene104PostingsReader.java (#16491) changes comments only, and no open PR changes docIDRunEnd in any postings reader; related, not reports of this bug: #14390 (introduced it; its review covered BLOCK_SIZE and test coverage, not the sentinel), #14693 and #15160 (carried it forward), #16161 (closest analogue: a SkipBlockRangeIterator run end extended through skip levels without a density check, other code and fix), #16450 and #16513 (doc-values docIDRunEnd fixes and contract tests), #9566 / LUCENE-8520 (a 2018 testExactlyAtTrueLimit failure from another cause), #16847 (open draft for more than 2^31 docs per index; segments stay capped at MAX_DOCS); gaps: keyword search only, private reports to security@lucene.apache.org and unindexed chats are not visible
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test through gradle in a scratch worktree and through a standalone JUnit runner, assertions on and off; an end-to-end program on a segment ofIndexWriter.MAX_DOCSdocuments written byIndexWriter(assertions off); the recommended fix with the closest core and backward-codecs suites. Release jars (Maven Central, SHA-1 checked): 9.12.3, 10.0.0 and 10.1.0 (clean, no postingsdocIDRunEnd), 10.2.0 to 10.5.2 and 10.6.0 (affected). The study ran on mainea57360912ed;Lucene104PostingsReader.javais the same blob there, at645d4fe14a20and at upstream main2f424fd428da(read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:559-560 (docFreq < LEVEL1_NUM_DOCS: no level-1 data), :674-689 (skipLevel1To: level1DocCountUpto += LEVEL1_NUM_DOCS, then level1LastDocID = NO_MORE_DOCS at :687), :1099-1129 (docIDRunEnd: level1IsDense test at :1118-1119, return level1LastDocID + 1 at :1121), :1358 (getImpacts already treats level1LastDocID == NO_MORE_DOCS as 'no level 1')lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene101/Lucene101PostingsReader.java:679, :1059-1061 and lucene103/Lucene103PostingsReader.java:679, :1105-1107 (the same sentinel and unguarded shortcut)lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:245-263 (docIDRunEnd contract: 'The returned doc is greater than docID()'; only exception: exhausted or unpositioned)lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1114-1125 (testPostings only at level >= MIN_LEVEL_FOR_INTEGRITY_CHECKS), :2090-2104 (checkDocIDRuns for docFreq > 1024, every 1024th term, or slow checks), :2537-2559 (checkDocIDRuns throws 'Run end X is <= doc ID Y'), :4748-4754 (DEFAULT_VALUE = MIN_VALUE, MIN_LEVEL_FOR_INTEGRITY_CHECKS = 2)lucene/core/src/java/org/apache/lucene/search/DenseConjunctionBulkScorer.java:196-212 (a run end below minRunEndThreshold puts the clause into windowClauses; collectRange only for run ends at or above it) and DisjunctionDISIApproximation.java:225-233 (Math.max discards the bad value)lucene/test-framework/src/java/org/apache/lucene/tests/index/AssertingLeafReader.java:603-610 (AssertingPostingsEnum#docIDRunEnd asserts endDocID > startDocID); lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:208 (MAX_DOCS = Integer.MAX_VALUE - 128); lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:47-85 (@Monster testExactlyAtTrueLimit: MAX_DOCS docs with one StringField term, forceMerge(1))
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:559-568, :674-689 (:683-688), :1099-1129 (:1117-1124), :1358lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsFormat.java:343, :348, :351lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene101/Lucene101PostingsReader.java:679, :1059-1062; lucene/backward-codecs/src/java/org/apache/lucene/backward_codecs/lucene103/Lucene103PostingsReader.java:679, :1105-1108lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:499, :1114-1125, :1208, :2090-2104, :2537-2559, :4742, :4748, :4754lucene/test-framework/src/java/org/apache/lucene/tests/index/AssertingLeafReader.java:603-611lucene/core/src/java/org/apache/lucene/search/DenseConjunctionBulkScorer.java:196-212; lucene/core/src/java/org/apache/lucene/search/DisjunctionDISIApproximation.java:225-233
- Who is affected
lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1114-1125, :1208, :4742-4757lucene/test-framework/src/java/org/apache/lucene/tests/store/BaseDirectoryWrapper.java:33; tests/util/TestUtil.java:302-303
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/DocIdSetIterator.java:245-263lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:202-208lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:47-89lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:1358a Lucene clone: git show --stat db00348ef18e (#14390: Lucene101PostingsReader.java, CheckIndex.java, BasePostingsFormatTestCase.java)
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:683-688 (level1DocCountUpto is read only at :683, :684 (the += itself) and :1119)
- History
a Lucene clone: git log -1 db00348ef18e, 6bef45756a96; git tag --contains 6bef45756a96 (releases 10.2.0 to 10.6.0)
- TestDocIDRunEndNearMaxDoc.java (JUnit, lucene/core tests, package org.apache.lucene.codecs.lucene104):
repro/LFV-170/src/org/apache/lucene/codecs/lucene104/TestDocIDRunEndNearMaxDoc.java(81 lines)
Made separately from this text, from the code at 645d4fe14a20 and a probe that prints the reader's skip state for this layout and a control shifted 1,000,000 doc IDs lower, with assertions on and off, stock and with the guard; the PNG is the summary still.
assets/LFV-170/bug.png(486 KB)