StoredFieldDataInput stores a binary field from a DataInput plus a byte count. Its ByteArrayDataInput constructor takes that count from ByteArrayDataInput.length(), which is the input's end position (offset + len). Only when the input is at position 0 is the end position also the number of bytes, so every other input stores too many.
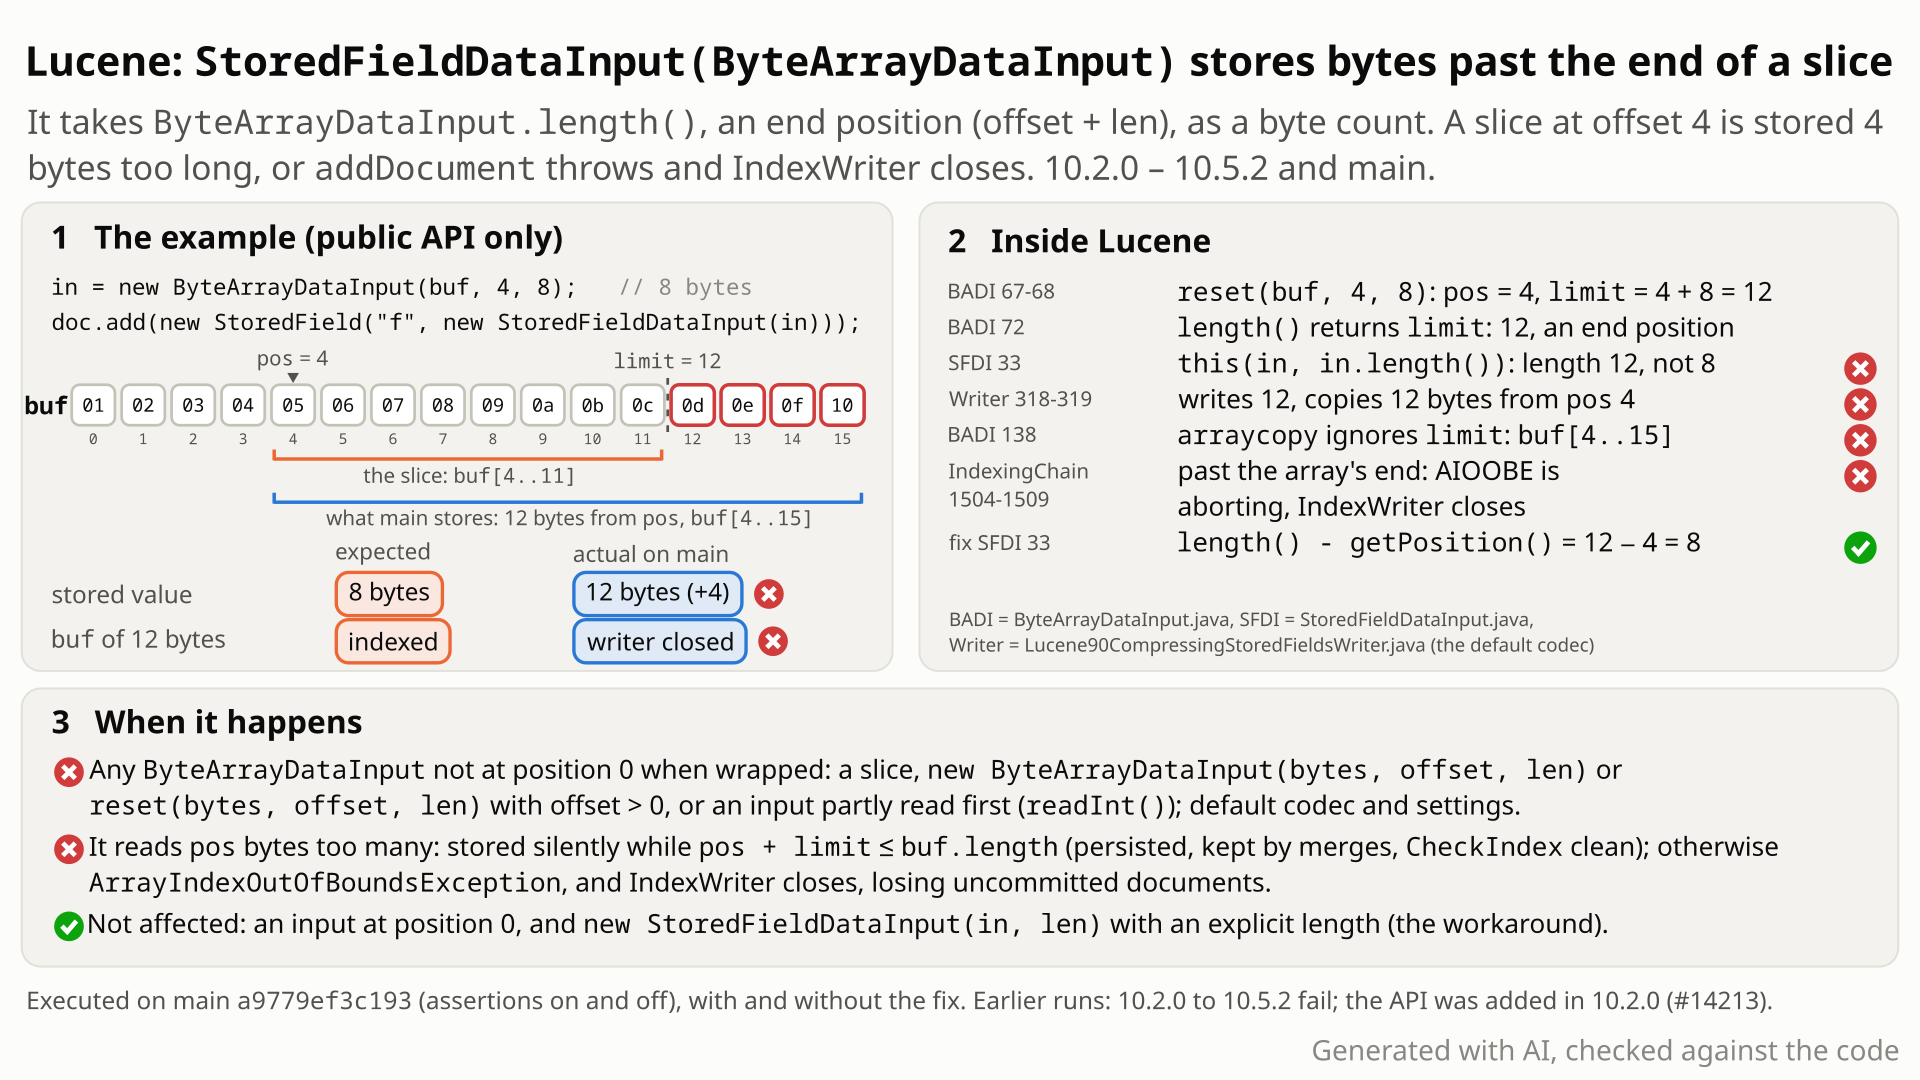
- Take a 16-byte array
01 02 ... 10and store bytes 4 to 11 as a binary field:new StoredField("f", new StoredFieldDataInput(new ByteArrayDataInput(buf, 4, 8))). Plain defaults are enough:new IndexWriterConfig(), the default codec. - You expect field
fto hold those 8 bytes,05 ... 0c, andgetLength()to return 8. - Instead
getLength()returns 12 and the document stores 12 bytes: the slice plus0d 0e 0f 10, with no error.ByteArrayDataInput.length()is the end position, 4 + 8 = 12, and the writer copies 12 bytes starting at position 4. - The 12 bytes survive commit and
forceMerge(1),CheckIndexreports the index clean, and a fixed Lucene still returns them for that document. An input whose 4-byte header was read first is hit the same way: 16 bytes stored instead of the 12 unread ones. - If too few bytes follow (the same 8-byte slice of a 12-byte array), the copy runs off the array:
ArrayIndexOutOfBoundsException, and theIndexWriterrolls back to its last commit and closes, dropping the documents not yet committed (one, in the probe).
Applications that store binary values with this @lucene.experimental constructor from a ByteArrayDataInput that is not at position 0: a slice of a larger buffer, or an input partly read first. Plain default settings are enough; every such document. No Lucene code outside tests calls the constructor, and public code search found no downstream caller.
Mechanism, terms and numbers649 words
StoredFieldDataInput (#14213, 10.2.0, @lucene.experimental) stores a binary field straight from a DataInput and a byte count. Its convenience constructor StoredFieldDataInput(ByteArrayDataInput) takes that count from ByteArrayDataInput.length(), which returns the input's end position (offset + len), not the bytes it holds. Both copy implementations (the default codec's writer and the base method other formats inherit) then copy that many bytes from the input's current position, so an input that is not at position 0 (a slice at a non-zero offset, or an input partly read first) stores as many extra bytes from the caller's array as its position, silently: the value survives merges and CheckIndex reports the index clean. When too few bytes follow, the copy throws ArrayIndexOutOfBoundsException inside the stored-fields write, which is an aborting exception, and the IndexWriter closes and rolls back to its last commit. Every release from 10.2.0 to 10.6.0 (10.6.0 by reading) and main is affected; a one-line fix (length() - getPosition()) passes the repro and the closest test suites.
StoredFieldDataInput: a record(DataInput in, int length), "A fixed size DataInput which includes the length of the input", with@param length the length of the data input(StoredFieldDataInput.java:22-29,@lucene.experimental).new StoredField(name, value)stores it as a binary field (StoredField.java:116-122). It was added in 10.2.0 by #14213.ByteArrayDataInput: aDataInputover abyte[]with a read positionposand an endlimit.new ByteArrayDataInput(bytes, offset, len)andreset(bytes, offset, len)setpos = offsetandlimit = offset + len(ByteArrayDataInput.java:39-41,:65-69).length()returnslimit(:71-73): an end position, deliberately so since 2011, and Lucene's own readers use it that way (while (in.getPosition() < in.length())).
- The convenience constructor is
this(byteArrayDataInput, byteArrayDataInput.length())(StoredFieldDataInput.java:32-34): the end position becomes the byte count. - The default codec's writer writes
getLength()as the stored length and copies that many bytes from the input's current position (Lucene90CompressingStoredFieldsWriter.java:312-320). Formats that keep the base method do the same withreadBytes(StoredFieldsWriter.java:76-82; SimpleText executed). These are the only two copy implementations in Lucene; the test framework's wrapper writers delegate to them, and index sorting first writes through a temporary default-codec writer.ByteArrayDataInput.readBytesis a plainSystem.arraycopythat ignoreslimit(ByteArrayDataInput.java:135-140). - So Lucene copies
[pos, limit + pos)instead of[pos, limit):posbytes too many. - If those bytes exist in the caller's array, they are stored with no error and read back as part of the value (the reader trusts the stored length,
Lucene90CompressingStoredFieldsReader.java:293). - If not,
arraycopythrowsArrayIndexOutOfBoundsExceptioninside the stored-fields write.IndexingChaintreats any exception there as aborting (IndexingChain.java:1504-1509), which becomes a tragic event: theIndexWriterrolls back to its last commit and closes (IndexWriter.java:6098-6106).
For a fresh slice (bytes, offset, len) the value is silently offset bytes too long when 2*offset + len <= bytes.length; otherwise the writer closes. Executed on main a9779ef3c193:
| input | expected | stored on main |
|---|---|---|
new ByteArrayDataInput(buf16, 4, 8) | 8 bytes 05..0c | 12 bytes 05..10 (getLength() 12) |
new ByteArrayDataInput(buf24, 0, 16) after readInt() | 12 bytes 05..10 | 16 bytes 05..14 |
new ByteArrayDataInput(buf12, 4, 8) | 8 bytes, writer open | ArrayIndexOutOfBoundsException, writer closed, an uncommitted earlier document lost (1 of 2 left) |
new ByteArrayDataInput(buf8) (control) | 8 bytes | 8 bytes |
The 12-byte value of the first row survives forceMerge(1) of 2 segments into 1 and CheckIndex reports the index clean, with plain new IndexWriterConfig() defaults; an index written that way and opened with the fix still returns the 12 bytes for that document and 8 for a new one. In a probe of a shared 128-byte buffer, a 16-byte record at offset 16 stored 32 bytes, the record plus the next record of the buffer, and that value survived forceMerge(1) from 2 segments to 1; CheckIndex reported the index clean.
Exposure and likelihood355 words
- Who is exposed. Callers of
new StoredField(name, new StoredFieldDataInput(in))whereinis aByteArrayDataInputbuilt withnew ByteArrayDataInput(bytes, offset, len)orreset(bytes, offset, len)withoffset > 0(for example from aBytesRefwith a non-zero offset, or a slice of a pooled buffer), or an input that was partly read before wrapping (a header). Every such document is hit. - Settings. Plain defaults are enough: a probe with
new IndexWriterConfig()(default codec, default merge policy) stores the 12 bytes. The JUnit pins the default codec and takes the rest of its configuration from the test framework's randomizednewIndexWriterConfig(). Other stored-fields formats are hit through the base writer method: SimpleText fails the same way (executed with the hardened upstream test). - Silent and lasting. In the common case nothing fails: the value is
posbytes too long, made of whatever follows in the caller's array (the next record of a shared buffer, or a previous request's leftovers in a reused one, in a probe). It survives commit and merges, CheckIndex reports the index clean, and a fixed Lucene still returns the extra bytes for segments already written (executed: an index written by unfixed main, opened with the fix, returns 12 bytes for the old document and 8 for a new one). - Loud variant. When fewer than
posbytes follow,addDocumentthrowsArrayIndexOutOfBoundsExceptionand theIndexWriterrolls back to its last commit and closes. A rollback discards every change since the last commit (IndexWriter.rollback()javadoc); the probe shows one buffered, uncommitted document lost besides the bad one (the committed index keeps 1 of the 2 documents added before it), and the nextaddDocumentthrowsAlreadyClosedException. - Bounded. At most
posextra bytes per value, never outside the caller's own array; no query-side effect. - How likely. Plausible but narrow. Slicing a buffer is a natural way to build the input (the introducing PR's own test builds it from
value.offset), but no non-test Lucene code calls this constructor, and public code search found no downstream caller in the repositories searched (the only hit outside Lucene, a codec wrapper, only delegateswriteField; private code is not visible).
The test shows that StoredFieldDataInput(ByteArrayDataInput) uses the input's end position as its length, so a slice that does not start at 0 is stored with extra trailing bytes.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.StoredField;
import org.apache.lucene.store.ByteArrayDataInput;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.BytesRef;

public class TestStoredFieldDataInputSlice extends LuceneTestCase {

  public void testStoredValueOfSliceAtNonZeroOffset() throws IOException {
    byte[] buf = new byte[16];
    for (int i = 0; i < buf.length; i++) {
      buf[i] = (byte) i;
    }
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
      Document doc = new Document();
      doc.add(new StoredField("f", new StoredFieldDataInput(new ByteArrayDataInput(buf, 4, 8))));
      w.addDocument(doc);
      try (DirectoryReader r = DirectoryReader.open(w)) {
        // expected: the 8 bytes buf[4..12); actual: the 12 bytes buf[4..16)
        assertEquals(new BytesRef(buf, 4, 8), r.storedFields().document(0).getBinaryValue("f"));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-175/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestStoredFieldDataInputSlice
- Expected vs actual
- Expected: the stored value of
new ByteArrayDataInput(buf16, 4, 8)is those 8 bytesbuf[4..12); actual: 12 bytesbuf[4..16), with-eaand-da.
More files, environment, full output52 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[4 5 6 7 8 9 a b]> but was:<[4 5 6 7 8 9 a b c d e f]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.index.TestStoredFieldDataInputSlice.testStoredValueOfSliceAtNonZeroOffset(TestStoredFieldDataInputSlice.java:44)- The record documents
lengthas a byte count, andStoredFieldVisitorsays readers "must readStoredFieldDataInput#lengthbytes". - The introducing PR's own test builds the input from
value.offsetand expects exactlyvalueback; it passes only because that offset is always 0, and fails at offset 3. - No javadoc asks for an input at position 0.
The full argument264 words
- Contract.
StoredFieldDataInput: "A fixed size DataInput which includes the length of the input",@param length the length of the data input, andgetLength()"Returns the length of the data input" (StoredFieldDataInput.java:22-29,:41-44).StoredFieldVisitor.binaryField(FieldInfo, StoredFieldDataInput): "Implementors of this method must readStoredFieldDataInput#lengthbytes" (StoredFieldVisitor.java:43-45). The reader builds the record with a byte count (Lucene90CompressingStoredFieldsReader.java:293). - The author's test. #14213 added to
BaseStoredFieldsFormatTestCase.testMergeFilterReadera fieldb2=new StoredFieldDataInput(new ByteArrayDataInput(value.bytes, value.offset, value.length))and asserts it equalsvalue(:687-693,:724-726).valueis a freshBytesRefwith offset 0. The same pattern at offset 3 fails: "b2 must equal b expected:<[61 62 63 64]> but was:<[61 62 63 64 7 7 7]>"; with a random offset of 1-5 it fails in the Lucene90 and SimpleText format tests. - Same PR, same intent.
testNullStoredDataInputField, "test a null data input value doesn't abort the entire segment", asserts no tragic exception and that the earlier document survives (TestIndexWriterExceptions.java:1757-1783). (There the null is rejected by theStoredFieldconstructor before indexing, so it shows intent, not this path.) - No precondition anywhere. The constructor's javadoc is "Creates a StoredFieldDataInput from a ByteArrayDataInput" (
StoredFieldDataInput.java:31). The #14213 discussion never mentions offsets, slices orlength(); CHANGES has only "GITHUB#14213: Allowing indexing stored-only StoredField directly from DataInput" under 10.2.0 (lucene/CHANGES.txt:1920). - Effect. Silently wrong stored bytes, or a closed
IndexWriterwith lost documents, for a valid input built with public constructors. - Precedent. LUCENE-4423 (2012), an offset/length bug on the read side of binary stored fields, was fixed as a bug.
The devil's-advocate check309 words
The strongest case for "works as designed": ByteArrayDataInput.length() returning the end position is deliberate and old (LUCENE-3224, 2011, changed limit = len to limit = offset + len; length() returns limit since LUCENE-3030), and Lucene code uses it as an end bound (Lucene104PostingsReader.java:1451). Both classes are @lucene.experimental; ByteArrayDataInput "omits all low-level checks" and even warns that rewind() "sets pos to 0, which is not right if you had called reset w/ non-zero offset!!" (ByteArrayDataInput.java:23-24, :51-55). The canonical constructor StoredFieldDataInput(DataInput, int) handles slices. So the convenience constructor just copies length(), and slice users should pass the length.
Why it fails: the record's length is documented and consumed as a byte count, nothing tells callers the convenience constructor needs position 0, and the introducing PR's own test builds the input from an offset and expects exactly len bytes back. The quirks of ByteArrayDataInput lower the severity; they do not make silently wrong stored data or a closed writer intended. Verdict: a defect in the convenience constructor, not in ByteArrayDataInput. The independent reproduction and the cross-model reviews rated the intended-behaviour argument weak; the intended-behaviour check and the adjudication rejected it without a strength rating.
The partly read input is the weaker half. The cross-model fact check of the brief (2026-10-27, reading only) rates the argument weak for a fresh slice but moderate for an input read partly before it is wrapped: for an input that starts at 0, length() as its total extent is more defensible, and no upstream test wraps a partly consumed input (the #14213 test covers only the slice form). There a documentation-only answer or removing the convenience constructor is a more plausible maintainer response. Still against it: the record's length is consumed as a byte count from the current position, and no javadoc says the input must be unread.
Recommended Use the bytes remaining in the convenience constructor
In the convenience constructor, use the bytes left in the input: byteArrayDataInput.length() - byteArrayDataInput.getPosition(). One line: it fixes slices and partly read inputs and changes nothing at position 0. Values already written keep their extra bytes. It passes the repro and 226 tests of the closest suites.
-  /** Creates a StoredFieldDataInput from a ByteArrayDataInput */
+  /**
+   * Creates a StoredFieldDataInput from a ByteArrayDataInput, holding the bytes from its current
+   * position to its end
+   */
   public StoredFieldDataInput(ByteArrayDataInput byteArrayDataInput) {
-    this(byteArrayDataInput, byteArrayDataInput.length());
+    // ByteArrayDataInput#length() is the end position of the input, not the number of bytes left
+    this(byteArrayDataInput, byteArrayDataInput.length() - byteArrayDataInput.getPosition());
   }
All options and trade-offs5 options · 904 words
Option A was built and validated; option B (a test change) was validated with it. C and D are alternatives that were not built. Until a fix ships, pass the length explicitly, new StoredFieldDataInput(in, len), or wrap a fresh ByteArrayDataInput at position 0 over an array that holds exactly the value. A fix does not rewrite segments already written: users who used the pattern need to check and reindex.
StoredFieldDataInput(ByteArrayDataInput) passes length() - getPosition() and its javadoc says it holds the bytes from the current position to the end. 1 file, +6/-2.
-  /** Creates a StoredFieldDataInput from a ByteArrayDataInput */
+  /**
+   * Creates a StoredFieldDataInput from a ByteArrayDataInput, holding the bytes from its current
+   * position to its end
+   */
   public StoredFieldDataInput(ByteArrayDataInput byteArrayDataInput) {
-    this(byteArrayDataInput, byteArrayDataInput.length());
+    // ByteArrayDataInput#length() is the end position of the input, not the number of bytes left
+    this(byteArrayDataInput, byteArrayDataInput.length() - byteArrayDataInput.getPosition());
   }
Trade-offs
- Unchanged for every input at position 0, which covers all of Lucene's own callers (
TestBinaryDocument,TestDirectoryReader,BaseStoredFieldsFormatTestCase). - Does not repair values already written.
- Expected cost: one accessor call and one subtraction when the record is built; not benchmarked. The same line is on
branch_10xandbranch_10_6(read), so the diff should apply there; the fix ran against the 10.2.0 jars, not the branch heads. - Unchanged by the fix: the record wraps the live input and takes its length once, at construction. Moving the input after wrapping makes the count stale, and adding the same
Documenttwice re-reads a consumed input. The diff's javadoc "holding the bytes" is loose on this; "whose length is the number of bytes from its current position to its end when it is created" is closer. - Edge cases (read, not executed):
pos == limitgives an empty value;pos > limit(possible via the uncheckedsetPositionandskipBytes) gives a negative length, which the base writer rejects withNegativeArraySizeExceptionand the default codec's writer, with assertions off, writes as a negative vInt with no bytes. The record does not validate an explicit negative length either. ThrowingIllegalArgumentExceptionin the constructor whengetPosition() > length()would close this beforeaddDocument, without aborting the writer.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: stock + the new test, 4 of 5 fail with assertions on and off; + the fix, the new test passes 5 of 5, and the closest suites pass with assertions on (seed DEADBEEF) and off (seed 5EED0175):TestStoredFieldDataInputPosition,TestBinaryDocument,TestDirectoryReader, the threeTestLucene90StoredFieldsFormat*classes,TestCompressingStoredFieldsFormatandTestIndexSortinginlucene/core(188 tests),TestSimpleTextStoredFieldsFormat(19) andTestAssertingStoredFieldsFormat(19): 226 tests, 13 skipped, 0 failures, with option B applied and a line-wrapping draft of the new test; the final test with the fix passes in gradle (5 + 20 + 19 tests, assertions on; and 121 tests with A + B and assertions off in the fact check). On the final files google-java-format, ecjLintTest and forbiddenApisTest pass; an earliercheckrun on the draft passed ecjLint and forbiddenApis but failed google-java-format on the draft test's line wrapping. - Standalone runner: 5 of 5 on main with assertions on and off, and on the 10.2.0 jars with the class shadowed in. Earlier checks with the same line: the finder's test 3 of 3, the independent reproducer's 5 of 5, the cross-model reviewer's 4 of 4, the security probe 4 of 4. The persistence probe passes with the fix (8 bytes after
forceMerge(1), CheckIndex clean). - Not run: the full
lucene/coretest suite.
In BaseStoredFieldsFormatTestCase.testMergeFilterReader, build b2 from a copy of value at offset 1-5 of a randomly padded array (+6/-2), so every stored-fields format test covers the case.
Trade-offs
A test change only, to ship with option A. One small padded array per test document: expected negligible, not measured.
What the checks validated
On stock main it fails in TestLucene90StoredFieldsFormat and, through the base StoredFieldsWriter.writeField, in TestSimpleTextStoredFieldsFormat (ArrayIndexOutOfBoundsException: arraycopy: last source index 38 out of bounds for byte[33] for seed DEADBEEF), with assertions on and off; with option A all stored-fields format suites above pass. Why it fails on stock for any seed: with offset o (1-5) and padding p (0-5), stock reads up to index 2o + len of an array of o + len + p, so p < o throws and p >= o stores o extra bytes, which the read-back check catches; the DEADBEEF message fits o = 5, p = 0 and a 28-byte value.
Say in the constructor javadoc that the input must be fresh and at position 0, and point slice users to StoredFieldDataInput(DataInput, int). Not built.
Trade-offs
Leaves silently wrong stored data for anyone who misses the sentence, and contradicts the introducing PR's own test pattern.
The API is experimental, so it may change. Not built.
Trade-offs
API churn for the whole-array case, which works today; callers must compute the length themselves.
Throw when a read passes limit.
Trade-offs
The class deliberately "omits all low-level checks" on a hot path, and an exception inside the stored-fields write would still abort it and close the writer.
No downstream caller of this constructor is known; an application that slices shared or pooled buffers this way would persist, and later return to readers of the document, whatever bytes follow each slice, such as a neighbouring record.
Code reading. While modelling the chunk arithmetic of the compressing stored-fields writer, a finder read the stored-field write paths and saw that the convenience constructor copies ByteArrayDataInput.length(); a JUnit on the stock jars confirmed it. The model did not cover this class, so this is not a formal finding.
The method in full125 words
Method: code reading, then a JUnit on the stock jars (non-formal).
- The hunt unit on the compressing stored-fields format built a Z3 model of the writer's chunk arithmetic. That model does not mention
StoredFieldDataInput. - While reading the write paths for the model, the finder noticed that
StoredFieldDataInput(ByteArrayDataInput)copieslength(), whichByteArrayDataInputdefines as its limit, and wrote a 3-test public-API JUnit that failed on main, 10.5.2 and 10.2.0. It was found on 2026-10-26 in about 0.7 hours. - Before the candidate was filed, an independent reviewer from another model family (OpenAI GPT-5.6) tried to refute it and instead reproduced it with its own test. An independent reproducer, a devil's advocate, a second cross-model review and an adjudication followed, then history, prior-report and security follow-ups.
No prior report found (2026-10-26, re-checked 2026-10-27): GitHub issues, PRs, commits and review threads, the mailing lists, the JIRA archive, downstream projects and the web. #14213 introduced the constructor and its discussion never mentions offsets; no open PR touches the file.
Searches4 searches
No issue, PR, review comment, list thread, JIRA ticket or downstream report describes this defect, and nobody has fixed it on any branch. Closest, not this bug: #14213 (introduced the constructor), #4297 / LUCENE-3224 (2011, made limit = offset + len), #12581 (2023, the expert DataInput stored-field methods, which take an explicit length) and LUCENE-4423 (2012, an analogous offset/length bug on the read side, in different code).
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; dev@, java-user@, issues@ and commits@; JIRA archive; web | 2026-10-26 | three runs of a scripted prior-report search (the finder's and two follow-up runs), class, keyword, symptom and error-message terms | only the related items above |
| GitHub (apache/lucene, Elasticsearch, OpenSearch, Solr, all of GitHub) | 2026-10-26 | manual issue, PR and code searches for StoredFieldDataInput, ByteArrayDataInput length/limit/offset and related terms | no report; the only code hit outside Lucene and its forks delegates writeField |
| Review threads and open PRs | 2026-10-26 | every comment, review comment and review of #14213; the changed files of all 413 open apache/lucene PRs | no mention of offsets or length(); no open PR touches StoredFieldDataInput.java or ByteArrayDataInput.java |
| GitHub, re-check | 2026-10-27 | PR and issue search StoredFieldDataInput in apache/lucene; the file on main, branch_10x and branch_10_6 | only #14213; line 33 unchanged on upstream main 20ced71c1e6e, branch_10x and branch_10_6 |
Introduced with the API by #14213 (f12e44b6515, merged 2025-02-19) and first released in 10.2.0. Fails on every release from 10.2.0 to 10.5.2 and on main, and 10.6.0 has the same line (read); 10.1.0 and older lack the API. Not fixed on upstream main, branch_10x or branch_10_6 (2026-10-27).
Versions tested6 rows
Introduced by #14213 "Support DataInput as source for StoredField" (@Tim-Brooks, merged by @iverase on 2025-02-19, milestone 10.2.0): f12e44b6515 on main, backport 2dedd1da89a on branch_10x. The one commit added the record, this constructor and StoredField(String, StoredFieldDataInput); StoredFieldDataInput.java has no other commit on main, branch_10x or branch_10_2 to branch_10_6. git tag --contains 2dedd1da89a lists 10.2.0 to 10.6.0. CHANGES lists it under 10.2.0 as an improvement. ByteArrayDataInput.length() returning offset + len dates from 2011 (LUCENE-3030, LUCENE-3224). branch_10_6 has the same line, so the released 10.6.0 (tagged at 4ae946e5a9b) has the bug (read, not executed).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 4 of 5 fail (gradle and the standalone runner, assertions on and off); the finder's test 3 of 3 |
| 10.5.2 | affected | this doc's test 4 of 5 fail, assertions on and off |
| 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1 | affected | the finder's test 3 of 3 fail on each (release jars, SHA-1 checked) |
| 10.2.0 | affected | this doc's test 4 of 5 fail; with the fix shadowed in, 5 of 5 pass |
| 10.1.0, 10.0.0, 9.12.3 | no API | compile error: StoredFieldDataInput does not exist |
| main + fix | not affected | this doc's test 5 of 5; 226 tests of the closest suites, 0 failures |
An independent reproducer, a devil's advocate and an adjudication confirmed it with their own runs; a reviewer from another model family reproduced it with its own test, a second ran read-only. A registry re-run on a9779ef3c193 and this doc's test reproduce it, and the fix passes.
Checks and verdicts508 words
The reviews by another model family (OpenAI GPT-5.6) were one executed (refute lens) and one read-only (works-as-designed lens); the other checks were run by the hunt's AI tools, and not every run record names the model. On 2026-10-27 the brief and this doc had a fact check (executed, 0 errors), a cross-model fact check (reading only, 3 errors) and a diagram check (0 errors).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | 3-test public-API JUnit fails 3 of 3 on main (-ea, -da), 10.5.2 and 10.2.0; the one-line fix passes 3 of 3. |
| cross-model review, refute lens | real (high) | Executed its own test: 3 of 4 fail on main (two seeds, also -da), 4 of 4 pass with the fix; upstream TestBinaryDocument and TestDirectoryReader binary-field tests pass with the fix. |
| Independent reproducer | real | Own JUnit with a BytesRef oracle and 2 controls fails 3 of 5 on main (-ea, -da), 10.5.2 (-ea, -da) and 10.2.0; does not compile on 9.12.3; passes 5 of 5 with the fix. |
| Cross-model review, works-as-designed lens | real (high), read-only | Intended argument weak; ran no Java itself (a separate run re-ran the finder's test, which fails); not fully independent, it saw the independent reproduction's and the intended-behaviour check's verdicts. |
| Intended-behaviour devil's advocate | real | The upstream test pattern at offset 3 fails; the explicit-length control passes; built the strongest intended case and showed why it fails. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit with -ea and -da (3 of 5 fail each) and checked the root cause in the source. |
| security screen + 2026-10-27 re-evaluation | out of scope of SECURITY.md, then not security-sensitive on re-evaluation | The screen probed shared and reused buffers, a partly read input and CheckIndex (3 of 4 fail as designed; CheckIndex clean); a re-evaluation on 2026-10-27 under the strict rule found it out of scope of SECURITY.md, so its security call is none. |
| registry re-run on a9779ef3c193 | still reproduces | The finder's test fails 3 of 3 with byte-identical messages. |
| this doc | reproduced, fix validated | New 5-test JUnit fails 4 of 5 on main (gradle and standalone, -ea and -da), 10.5.2 and 10.2.0; the fix passes it and 226 tests of the closest suites. |
| fact check of the brief and doc (2026-10-27) | pass, 0 errors | Re-ran the gradle command on a clean tree (two seeds, assertions on and off), the standalone runner with new seeds on main, 10.5.2 and 10.2.0 and 20 iterations, the fix, A + B (121 tests) and both probes; 6 wording nits, fixed. |
| cross-model fact check (OpenAI GPT-5.6, reading only) | sound; 3 errors | 1 medium and 2 low errors, 7 overclaims, 6 missing caveats; all fixed except the note on hunt jargon. |
| diagram check (2026-10-27) | pass, 0 errors | Re-ran the diagram probe on main, with assertions on and off and with the fix; 9 minor notes. The two "executed" labels it flagged were then executed on the exact example. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 516 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,396 words
- Registry title
- StoredFieldDataInput(ByteArrayDataInput) takes the input's end position as its length, so a ByteArrayDataInput that does not start at position 0 (a slice at a non-zero offset, or a partly read input) silently stores extra trailing bytes, or makes addDocument fail and close IndexWriter
- Area
- index / stored fields (StoredFieldDataInput: DataInput-backed StoredField values, #14213)
- Priority
- Medium, rank 244: Since 10.2.0 the experimental StoredFieldDataInput(ByteArrayDataInput) constructor persists extra trailing bytes (or closes IndexWriter) for any input not at position 0, but no Lucene or downstream caller is known.
- Impact class
- silent wrong results
- Impact note
- Applications that store a binary value through the @lucene.experimental StoredFieldDataInput(ByteArrayDataInput) convenience constructor with an input whose position is not 0 (new ByteArrayDataInput(bytes, offset, len) or reset(bytes, offset, len) with offset > 0, or an input partly read before wrapping) are hit on every such document with the default codec and settings, in every release since 10.2.0: the stored value silently carries as many extra trailing bytes from the caller's array as the start position (persisted, kept through merges, CheckIndex clean), or, when fewer bytes than that follow the slice, addDocument throws ArrayIndexOutOfBoundsException and IndexWriter closes, losing uncommitted documents; no non-test Lucene code calls this constructor, and code search found no downstream caller.
- Summary
- You add new StoredField(name, new StoredFieldDataInput(new ByteArrayDataInput(bytes, offset, len))) and expect the stored value to be exactly those len bytes, because the record's length is documented as 'the length of the data input'. The convenience constructor copies ByteArrayDataInput.length(), which is the end position offset + len, so for an 8-byte slice at offset 4 of a 16-byte array the document stores 12 bytes, the slice plus the next 4, with no error. If fewer bytes than the offset follow the slice, the stored fields writer reads past the array, addDocument throws ArrayIndexOutOfBoundsException and IndexWriter closes itself.
- Introduced
- f12e44b6515a25933dc5e9316df72d8b093eae12 (main) and its branch_10x backport 2dedd1da89acec3d7440348a0d4fd8c1d75225d7, PR #14213 'Support DataInput as source for StoredField' (author Tim-Brooks, merged by iverase, milestone 10.2.0; CHANGES 10.2.0 'GITHUB#14213: Allowing indexing stored-only StoredField directly from DataInput'), which added the StoredFieldDataInput record together with the line 'this(byteArrayDataInput, byteArrayDataInput.length());' [read: StoredFieldDataInput.java has only this commit on main, branch_10x and branch_10_2..branch_10_6, and the line is unchanged up to ea57360912ed; exec: 10.1.0 cannot compile the repro, 10.2.0 fails it]. ByteArrayDataInput.length() has returned limit = offset + len since LUCENE-3030 (b7846ffaa1f) and LUCENE-3224 (6b41b73894d), 2011, by design [read] (2025-02-19 (merged 06:44:41 UTC; author date 2025-02-18 23:44:41 -07:00))
- First affected version
- 10.2.0 [exec]; the API does not exist before it (10.1.0, 10.0.0 and 9.12.3 do not compile the repro) [exec]
- Affected versions
- 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed. [exec] the finder's JUnit fails 3 of 3 on every one of these releases (follow-up history runs, SHA-1-checked release jars) and on main with -ea and -da; the independent reproduction's JUnit fails 3 of 5 on main (-ea, -da), 10.5.2 (-ea, -da) and 10.2.0; the security probe fails 3 of 4 on main (-ea, -da), 10.5.2 and 10.2.0. Not affected: 10.1.0 and older, including all 9.x (9.12.3 executed), because StoredFieldDataInput does not exist there [exec: compile errors]. [read] branch_10_6 has the same constructor line, so the released 10.6.0 (4ae946e5a9b) has it too; 10.6.0 was not executed. Only the default stored fields format was executed; the default StoredFieldsWriter.writeField(FieldInfo, StoredFieldDataInput), which other codecs inherit, reads length() bytes the same way [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: three scripted prior-report searches (the finder's: 16 GitHub issue/PR, 3 commit, 2 downstream-repo and 4 JIRA queries; follow-up run 1: 8 GitHub issue/PR, 2 commit, 1 downstream-repo, 12 mailing-list queries over dev@, java-user@, issues@ and commits@, and 4 JIRA queries; follow-up run 2: 24 mailing-list, 6 JIRA and 6 web queries), plus manual GitHub issue, PR and code searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr and all of GitHub, the changed-file lists of all 413 open apache/lucene PRs, every comment, review comment and review of #14213, the commit history of StoredFieldDataInput.java on main, branch_10x and branch_10_2..branch_10_6, and direct mailing-list and JIRA searches; 20 hits read, none the same bug); not fixed: upstream main HEAD ea57360912ed, branch_10x and branch_10_2..branch_10_6 still have 'this(byteArrayDataInput, byteArrayDataInput.length())', and no open PR touches StoredFieldDataInput.java or ByteArrayDataInput.java; related, not reports of this bug: #14213 (introduced the constructor; its discussion never mentions offsets, slices or length()), #4297 / LUCENE-3224 (2011, made limit = offset + len), #12581 (2023, the expert DataInput stored-field methods, which take an explicit length), LUCENE-4423 (2012, an analogous offset bug on the read side, in different code); gaps: GitHub search was rate-limited (the follow-up tool run used 8 GitHub queries; the finder's 16 and the manual queries cover the rest), multi-word queries match tokens, and private downstream code and private reports to security@lucene.apache.org are not visible
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 (assertions on and off) and 10.2.0 (assertions on) release jars with this doc's test; amain()probe with plainnew IndexWriterConfig()defaults on main (assertions on and off); the finder's test on every release from 10.2.0 to 10.5.2 and on mainea57360912ed(2026-10-26). The fix was validated in the scratch worktree: the new test, 226 tests of the closest suites inlucene/core,lucene/codecsandlucene/test-frameworkwith assertions on and off, and google-java-format, ecjLint and forbiddenApis on the final files.
- Finding record
lucene/core/src/java/org/apache/lucene/index/StoredFieldDataInput.java:22-34 (record javadoc 'A fixed size DataInput which includes the length of the input', '@param length the length of the data input', @lucene.experimental; :32-34 the convenience constructor 'this(byteArrayDataInput, byteArrayDataInput.length())')lucene/core/src/java/org/apache/lucene/store/ByteArrayDataInput.java:65-73 (reset sets pos = offset, limit = offset + len; length() returns limit) and :129-139 (readBytes is a plain System.arraycopy from pos, 'AIOOBE not EOF if you read too much')lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:312-320 (writeField(FieldInfo, StoredFieldDataInput) writes getLength() as the vInt length and copies that many bytes from the input) and codecs/StoredFieldsWriter.java:77-81 (the default writeField reads value.length() bytes)lucene/core/src/java/org/apache/lucene/index/StoredFieldVisitor.java:43-45 ('Implementors of this method must read StoredFieldDataInput#length bytes') and codecs/lucene90/compressing/Lucene90CompressingStoredFieldsReader.java:293 (the reader builds new StoredFieldDataInput(in, length) with a byte count)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1449-1454 (try around storedFieldsConsumer.writeField at :1450; any Throwable from storedFieldsConsumer.writeField goes to onAbortingException) and document/StoredField.java:109-120 (StoredField(String, StoredFieldDataInput), constructor at :116)lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseStoredFieldsFormatTestCase.java:688-693 (the #14213 test builds new StoredFieldDataInput(new ByteArrayDataInput(value.bytes, value.offset, value.length)) and expects value back; offset is 0 there); core/src/test/.../TestDirectoryReader.java:403 and document/TestBinaryDocument.java:82 (the other callers, offset 0); CHANGES.txt:1904 (under Lucene 10.2.0)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/StoredFieldDataInput.java:22-34 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/store/ByteArrayDataInput.java:23-24, (at a9779ef3c193) :39-41, :65-73, :135-140lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsWriter.java:312-320; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/codecs/StoredFieldsWriter.java:76-82lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingStoredFieldsReader.java:293; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/document/StoredField.java:116-122lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1504-1509; (at a9779ef3c193) IndexWriter.java:6098-6106; DocumentsWriterPerThread.java:594-605lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:1451 (at a9779ef3c193) (length() used as an end bound)lucene/test-framework/src/java/org/apache/lucene/tests/codecs/asserting/AssertingStoredFieldsFormat.java:169-173; (at a9779ef3c193) .../cranky/CrankyStoredFieldsFormat.java:151-157; lucene/core/src/java/org/apache/lucene/index/SortingStoredFieldsConsumer.java:79-81, :95-100
- Who is affected
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:6098-6106 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:2567-2571 (at a9779ef3c193) (rollback javadoc), :1639
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/StoredFieldDataInput.java:22-44; (at a9779ef3c193) StoredFieldVisitor.java:43-45lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseStoredFieldsFormatTestCase.java:669-726 (at a9779ef3c193) (testMergeFilterReader)lucene/core/src/test/org/apache/lucene/index/TestIndexWriterExceptions.java:1757-1783 (at a9779ef3c193)lucene/CHANGES.txt:1823 (at a9779ef3c193) (Lucene 10.2.0 header), :1920lucene/core/src/java/org/apache/lucene/store/ByteArrayDataInput.java:23-24, (at a9779ef3c193) :51-55; lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104PostingsReader.java:1451
- Suggested fix
lucene/core/src/java/org/apache/lucene/store/ByteArrayDataInput.java:23-24; (at a9779ef3c193) IndexingChain.java:1504-1509gh api (read-only, 2026-10-27): StoredFieldDataInput.java on branch_10x and branch_10_6, line 33 unchangedlucene/core/src/java/org/apache/lucene/store/ByteArrayDataInput.java:61-63, (at a9779ef3c193) :80-82; StoredFieldsWriter.java:79; ByteBuffersDataOutput.java:312-331; BaseStoredFieldsFormatTestCase.java:724-725
- Prior reports
gh search prs / gh search issues / gh api contents and commits, read-only, 2026-10-27
- History
a Lucene clone: git tag --contains 2dedd1da89alucene/CHANGES.txt:1823, (at a9779ef3c193) :1920gh api (read-only, 2026-10-27): commits touching StoredFieldDataInput.java on main; the file on branch_10x and branch_10_6; no releases/lucene/10.6.0 tag
- TestStoredFieldDataInputSlice.java (JUnit test):
repro/LFV-175/src/org/apache/lucene/index/TestStoredFieldDataInputSlice.java(48 lines)
A three-panel picture of the repro's slice case, made in parallel with this doc from the executed repro on main a9779ef3c193 and the code. The alt text describes the PNG. Two statements on screen, the example's value surviving forceMerge(1) with CheckIndex clean and values written before a fix keeping their extra bytes, were executed on exactly this example after the diagram check (the persistence probe in the repro files).
assets/LFV-175/bug.png(516 KB)