Since #16431, fromDoubleField and fromFloatField tell the top-k search the best value of each skip block by decoding the block's largest stored bit pattern. For raw IEEE bits that goes wrong as soon as a block holds a NaN or only negative values.
- Doubles as raw bits.
DoubleDocValuesFieldstores a double as its 64 IEEE bits in a long (Double.doubleToRawLongBits);fromDoubleFieldturns the long back into the double.FloatDocValuesFieldandfromFloatFielddo the same with 32 bits. - Skip index. A numeric doc-values field can opt in to a skip index (
NumericDocValuesField.indexedField): for each block of documents (normally 4,096 with a value) it stores the smallest and largest stored long. - Block-max pruning (new in #16431, unreleased).
FunctionScoreQuerytells the top-k search the best score a block can reach, read from the skip index through the decoder, so blocks that cannot beat the current top hits are skipped. - The premise. That only works if a larger long always means a larger value (
Monotonicity.INCREASING). For raw IEEE bits it holds for non-negative numbers only.
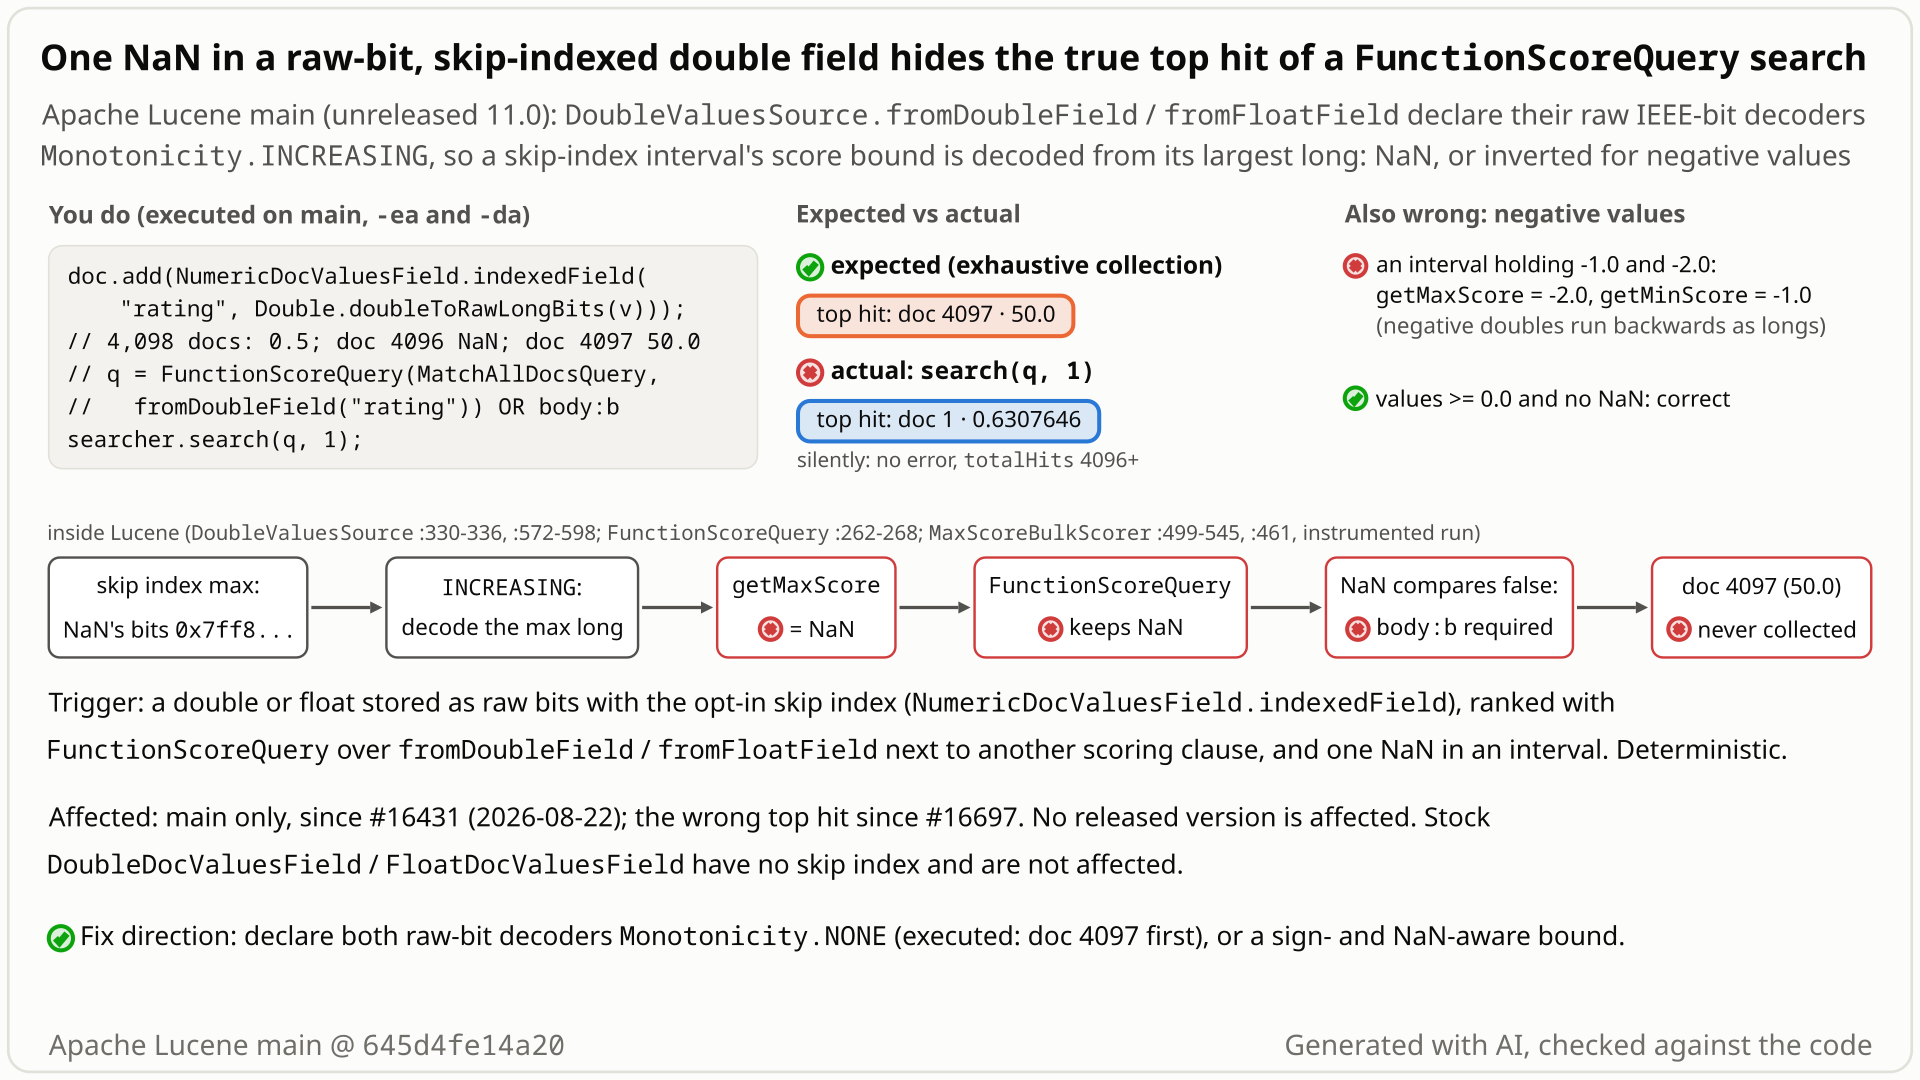
body:b required there, and doc 4097 (50.0) is skipped. Select the still to open it at full size. Generated with AI, checked against the code.- Store a double
ratingas raw bits in a doc-values field with a skip index (NumericDocValuesField.indexedField("rating", Double.doubleToRawLongBits(v))): 0.5 on docs 0-4095, NaN on doc 4096, 50.0 on doc 4097. Doc 1 also matchesbody:b. - Search
body:bORFunctionScoreQuery(MatchAllDocsQuery, fromDoubleField("rating"))withIndexSearcher.search(q, 1). You expect doc 4097 with score 50.0: the NaN document scores 0, and an exhaustive search returns doc 4097 first. - Instead you get doc 1 with score 0.631 (0.5 plus the text score 0.131), and
totalHits"4096+" whilecount(q)is 4,098. No error, with assertions on or off. With 0.5 instead of NaN on doc 4096, doc 4097 comes back. - Why: the skip index keeps each block's smallest and largest stored long. NaN's bits (0x7ff8...) are larger than 50.0's (0x4049...), so block 4096-4097 claims "best score NaN". Every
<or>=comparison with NaN is false, so the searcher makesbody:brequired in that block and skips doc 4097, which does not match it. - Negative values sort backwards as bits too: a block {-1.0, -2.0} reports
getMaxScore-2.0 andgetMinScore-1.0. Declaring the two decodersMonotonicity.NONE(two lines) fixes both.
Applications on main or the 11.0 branch (unreleased, since #16431) that store doubles or floats as raw bits in a doc-values field with the opt-in skip index and rank them with FunctionScoreQuery next to another scoring clause. One positive NaN (unvalidated input) hides real top hits in its block. Stock DoubleDocValuesField/FloatDocValuesField have no skip index and are unaffected.
Mechanism, terms and numbers733 words
DoubleValuesSource.fromDoubleField and fromFloatField decode a stored long as raw IEEE 754 bits, the encoding of DoubleDocValuesField and FloatDocValuesField. #16431 (unreleased, 11.0.0) declared both decoders Monotonicity.INCREASING and gave the field sources block-max bounds: with a doc-values skip index, getMaxScore is the decoded largest stored long of the block and getMinScore the decoded smallest. Read as signed longs, raw bits sort like the values only for non-negative numbers; negative values sort in reverse, and a positive NaN sorts above +Infinity and every number. So one NaN makes a block's bound NaN; FunctionScoreQuery passes it on, and in a BooleanQuery of SHOULD clauses MaxScoreBulkScorer then makes the other clause required for that block, so documents that are competitive only through the function score are never collected. With 4,098 documents, the default codec and IndexSearcher.search(q, 1), the top hit is doc 1 (0.631) instead of doc 4097 (50.0). A block of negative values gets inverted bounds. Only hand-built raw-bit fields with the opt-in skip index are affected; only main and branch_11x have the code; every release returns the right hit.
- The premise.
Monotonicity.INCREASINGis documented as "Increasing function" (DoubleValuesSource.java:51-58).fromDoubleFieldisfromField(field, Double::longBitsToDouble, Monotonicity.INCREASING)(:331),fromFloatFieldisfromField(field, (v) -> (double) Float.intBitsToFloat((int) v), Monotonicity.INCREASING)(:336);fromLongFieldis declared the same way (:341), where it is right. - The bounds trust it. With a skipper,
getMaxScore(upTo)takes the first skipper level that coversupTo(:556-569) and returns(float) decoder.applyAsDouble(skipper.maxValue(level))(:571-584);getMinScoredoes the same withminValue(:586-599). Without a skipper they stay at +/-Infinity. - Raw bits are not ordered like the values. As signed longs, -1.0 =
0xbff0000000000000is smaller than -2.0 =0xc000000000000000, and NaN =0x7ff8000000000000is above +Infinity =0x7ff0000000000000and every number. In the repro the block of docs 4096-4097 stores min = the bits of 50.0 and max = the bits of NaN, sogetMaxScore(4097)is NaN andgetMinScoreis 50.0; block 0-4095 reports 0.5. FunctionScoreQuerypasses NaN on. Its scorer'sgetMaxScorereturns +Infinity only for an infinite value bound and otherwiseinnerMaxScore * valueMaxScore * boost= NaN (FunctionScoreQuery.java:262-269); itsscore()maps the NaN document itself to 0 (:243-252).- The searcher makes the other clause required.
IndexSearcher.search(q, n)is TOP_SCORES and raises the minimum competitive score after 1,000 hits (IndexSearcher.java:100,:599;TopScoreDocCollector.java:58-60). ABooleanQueryof two or more SHOULD clauses withminimumNumberShouldMatch<= 1 gets aMaxScoreBulkScorer(BooleanScorerSupplier.java:308-328; a largerminimumNumberShouldMatchfalls back toWANDScorer,:316-321).partitionScorers()keeps a clause essential unless the running sum of bounds is below the threshold (MaxScoreBulkScorer.java:502); with NaN that<test is false, so the function clause is the only essential clause, the test at:540is false too, and the text clause becomes required (:524-547, applied at:460-461).
- Window [0, 4096): threshold 0.0; both clauses essential (text bound 0.13076457, function bound 0.5).
- Window [4096, 4098): threshold 0.63076466 (one step above doc 1's score 0.6307646); text bound 0.0, non-essential; function bound NaN, essential;
firstRequiredScorer = 0, so both clauses are required. No document in 4096-4097 matchesbody:b, so doc 4097 is never collected. - Control (0.5 instead of NaN): the window holding doc 4097 has the function bound 50.0, the text clause is not required, and doc 4097 is returned.
The finder's 5,000 documents (NaN on doc 4500, 50.0 on doc 4999) return doc 1 (score 4.19) instead of doc 4999; fromFloatField fails the same way; MUST text + SHOULD function query and a disjunction nested in a conjunction also lose hits. FunctionScoreQuery alone, DisjunctionMaxQuery and, with assertions off, minimumNumberShouldMatch=2 lost no hits in the security probe; a NaN with the sign bit set (bits 0xfff8...) among positive values lost none either (448 checks), because it sorts below every non-negative value's bits. With assertions on, minimumNumberShouldMatch queries (which use WANDScorer) can throw an AssertionError from WANDScorer.scaleMaxScore instead.
An all-negative block reports its smallest value as the maximum and its largest as the minimum; a block with two or more distinct negative values reports a too-high minimum even next to positive values. getMinScore has no in-tree production caller, and FunctionScoreQuery scores negative values 0, so at query level the negative half overlaps LFV-203.
Exposure and likelihood333 words
- Who. Users of main or
branch_11xwho index a double or float as raw IEEE bits with the opt-in skip index (NumericDocValuesField.indexedField(name, Double.doubleToRawLongBits(v))orFloat.floatToRawIntBits(v), or a field type withDocValuesSkipIndexType.RANGE) and rank it withFunctionScoreQueryoverfromDoubleField/fromFloatFieldas one scoring clause next to another, in a top-k search: the defaultIndexSearcher.search(q, n)once 1,000 hits are collected, or any TOP_SCORES collector. - Trigger. One positive NaN in a skip block, such as
Double.NaNorDouble.parseDouble("NaN")from unvalidated input (bits0x7ff8000000000000). IEEE 754 does not fix the sign of a NaN that arithmetic produces; on the Linux aarch64 machine used here, 0.0/0.0 andMath.sqrt(-1.0)at run time were positive too. A NaN with the sign bit set lost no hits in the probe. A block closes after at least 4,096 documents with a value (a dense run of one repeated value can extend it). For a fixed index, query and collector the outcome is deterministic (70 of 70 bug-test runs failed over 10 iterations in a verifier's suite). - Effect. Silent wrong results: the block's best documents disappear from the top hits, and
totalHitsis reported as a lower bound ("4096+") whilecount()is right. No exception with assertions off; default codec and searcher. - Never a superset. In 6 probe runs of 3,024 checks each, no non-matching, deleted or filtered document was returned.
- Scale. The NaN document's block (4,096 documents by default); for a disjunction nested in a conjunction up to its 32,768-document level-1 group (329 of the 736 true top hits lost at 50,000 documents). Deleting the NaN document does not end it until its segment is rewritten (the merge itself was not executed).
- Not affected. The stock
DoubleDocValuesField/FloatDocValuesField(no skip index, so the bound stays +Infinity); every release. - How likely: rare. It needs the hand-built layout,
FunctionScoreQuerynext to another scoring clause, and a NaN in the field. Elasticsearch and OpenSearch do not callfromDoubleField/fromFloatField(read-only code search of their default branches, 2026-10-26).
One JUnit class (Lucene's test framework) that reaches the bug through public API only, default codec pinned, in-memory index: testNaNValueHidesTopHit (4,098 documents, the steps above, search(q, 1)) and testMaxScoreOfNegativeValues (two documents, -1.0 and -2.0).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queries.function;

import java.util.Arrays;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.NumericDocValuesField;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.DoubleValues;
import org.apache.lucene.search.DoubleValuesSource;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestRawBitsDoubleFieldBounds extends LuceneTestCase {

  private static IndexWriter writer(Directory dir, double[] ratings) throws Exception {
    IndexWriter w =
        new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()));
    for (int i = 0; i < ratings.length; i++) {
      Document doc = new Document();
      doc.add(NumericDocValuesField.indexedField("rating", Double.doubleToRawLongBits(ratings[i])));
      if (i == 1) {
        doc.add(new StringField("body", "b", Field.Store.NO));
      }
      w.addDocument(doc);
    }
    return w;
  }

  public void testMaxScoreOfNegativeValues() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = writer(dir, new double[] {-1.0, -2.0});
        DirectoryReader reader = DirectoryReader.open(w)) {
      DoubleValues values =
          DoubleValuesSource.fromDoubleField("rating").getValues(reader.leaves().get(0), null);
      float max = values.getMaxScore(values.advanceShallow(0));
      assertTrue("expected getMaxScore >= -1.0 (the block's largest value), was " + max, max >= -1);
    }
  }

  public void testNaNValueHidesTopHit() throws Exception {
    double[] ratings = new double[4098];
    Arrays.fill(ratings, 0.5);
    ratings[4096] = Double.NaN;
    ratings[4097] = 50;
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = writer(dir, ratings);
        DirectoryReader reader = DirectoryReader.open(w)) {
      Query query =
          new BooleanQuery.Builder()
              .add(
                  new FunctionScoreQuery(
                      MatchAllDocsQuery.INSTANCE, DoubleValuesSource.fromDoubleField("rating")),
                  Occur.SHOULD)
              .add(new TermQuery(new Term("body", "b")), Occur.SHOULD)
              .build();
      // expected: doc 4097 (rating 50) is the top hit; actual: doc 1 (0.5 plus the term score)
      assertEquals(4097, new IndexSearcher(reader).search(query, 1).scoreDocs[0].doc);
    }
  }
}
cd $LUCENE && ./gradlew :lucene:queries:test --tests TestRawBitsDoubleFieldBounds -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
search(q, 1)returns doc 4097 (score 50.0), and the {-1.0, -2.0} block'sgetMaxScoreis at least -1.0.- Observed
- It returns doc 1 (score 0.631):
expected:<4097> but was:<1>; andgetMaxScoreis -2.0. Both with assertions on and off.
More files, environment, full output332 words
The default codec is pinned with TestUtil.getDefaultCodec() (new Lucene104Codec()) because the bug needs its doc-values skip index (LuceneTestCase would otherwise pick a codec from the seed; its "test environment" log line names that randomized class default, Asserting(Lucene104), which the writer's setCodec overrides); ByteBuffersDirectory, a plain IndexSearcher, one thread, nothing random. Two methods, because the title claims two symptoms of one root cause; the NaN method alone carries the user-visible bug.
4,098 documents is the smallest index found for the NaN method: the NaN and the best document must sit in the second skip block, after the 1,000-hit threshold has raised the competitive score; the 12 smaller layouts tried (3 to 4,097 documents) return the right top hit, and the 7 tried with 4,098 to 8,193 documents all return the wrong one. The negative method asserts only the bound's contract (>= -1.0), not an exact value, so both fixes pass it.
Regression test: this same class; it passes with either fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with either fix: passes. Release 10.6.0: the hunt's portable NaN top-hit test passes (this class needs the new bound API, which 10.6.0 lacks) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestRawBitsDoubleFieldBounds.java $LUCENE/lucene/queries/src/test/org/apache/lucene/queries/function/
cd $LUCENE && ./gradlew :lucene:queries:test --tests TestRawBitsDoubleFieldBounds -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
> Task :lucene:queries:test FAILED

TestRawBitsDoubleFieldBounds > testNaNValueHidesTopHit FAILED
    java.lang.AssertionError: expected:<4097> but was:<1>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:DF889CC89C4366E0]:0)
        at org.apache.lucene.queries.function.TestRawBitsDoubleFieldBounds.testNaNValueHidesTopHit(TestRawBitsDoubleFieldBounds.java:85)

TestRawBitsDoubleFieldBounds > testMaxScoreOfNegativeValues FAILED
    java.lang.AssertionError: expected getMaxScore >= -1.0 (the block's largest value), was -2.0
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:1F545E63F103144B]:0)
        at org.apache.lucene.queries.function.TestRawBitsDoubleFieldBounds.testMaxScoreOfNegativeValues(TestRawBitsDoubleFieldBounds.java:64)

2 tests completed, 2 failed

# the numbers behind it (probe on the same build): exhaustive top 3 = doc 4097 (50.0), doc 1 (0.6307646), doc 0 (0.5), 4098 hits;
# search(q, 1) = doc 1 (0.6307646), totalHits 4096+; count(q) = 4098; block 4096-4097: getMaxScore = NaNINCREASINGis documented as "Increasing function"; raw IEEE bits read as longs are not (negatives reverse, NaN on top).- NaN is a handled value:
FunctionScoreQueryscores it 0, as upstreamtestNaNchecks. The bug hides another, legal 50.0 document. - A bound must cover the block's best score. Before #16431 it was +Infinity; every release returns the right hit.
The full argument257 words
- The premise.
DoubleValuesSource.java:52:INCREASINGis "Increasing function".Double::longBitsToDoubleover signed longs decreases over the negative half and maps the top of the range to NaN. This is Lucene's own claim about its built-in decoders, not a user lambda. - A bound must bound.
DoubleValues#getMaxScore/getMinScore"Return the maximum/minimum score that documents between the current position andupTocan produce" (DoubleValues.java:55-69);Scorer#getMaxScorelikewise (Scorer.java:76-79); TOP_SCORES allows "skipping over non-competitive hits" (ScoreMode.java:28-32). The upstream testTestDoubleValuesSource#testMaxScoreBeyondTheCurrentBlockassertsgetMinScore(upTo) <= value <= getMaxScore(upTo)(:412-421), but only forfromLongField(:400-403). - NaN is a handled value.
TestFunctionScoreQuery#testNaN(:255-274) indexes the bits of NaN, reads them throughfromDoubleFieldand expects score 0;score()maps NaN to 0 on purpose (FunctionScoreQuery.java:250). - History. Before #16431 the bound was +Infinity: useless for pruning, always safe; 10.0.0, 10.5.2 and 10.6.0 return the right hit. In the #16431 review uschindler pointed out that functions such as
1/xor-xare not increasing and asked whether only "a pure DocValuesValueSource as function" was the safe case, which led to theMonotonicityenum; the discussion was about functions applied to the field values (custom functions and expressions versus a plain doc-values source) and never mentioned NaN, negative values or the raw IEEE bit encoding. #16697 then fixed other unsafe bounds of the same feature. In #16629, which fixed the same raw-bits ordering hazard in the doc-values range query (#16573), romseygeek asked to "check that that we aren't making this assumption in other places as well".
The devil's-advocate check126 words
The strongest case: a skip index on raw-bit doubles is not a supported layout, since no Lucene field class builds one, and testNaN's own explanation calls NaN "an illegal score". A weaker one: score bounds need not be value bounds.
Why it fails: NumericDocValuesField.indexedField is public API, DoubleDocValuesField documents the raw-bit encoding, and an upstream test builds exactly such a field (TestSortOptimization#testFloatSortOptimizationSkpperIndex indexes FloatDocValuesField.indexedField(field, Float.floatToRawIntBits(value))). Declaring these two factories INCREASING has an effect only on such fields; without a skipper the bound is +Infinity. The "illegal score" text is about the NaN document's own score, which FunctionScoreQuery already maps to 0. The weaker argument touches only the negative half. Two intended-behaviour reviewers (one from another model family) rated the case for "intended" weak.
Recommended A: declare the raw-bits decoders Monotonicity.NONE (validated, recommended)
Declare both raw-bits decoders Monotonicity.NONE in fromDoubleField and fromFloatField (two lines): their bound goes back to +Infinity, as in every release, so no block is skipped on a wrong bound. The repro, the queries module and the closest core suites pass. A sign-aware bound passes the same tests and keeps the pruning; it covers a positive NaN only.
// raw IEEE-754 bits are not ordered like the doubles they encode (negative values are ordered
// in reverse and NaN is above +Infinity), so skip-index bounds cannot be decoded directly
return fromField(field, Double::longBitsToDouble, Monotonicity.NONE);

// same as fromDoubleField: raw float bits are not ordered like floats
return fromField(field, (v) -> (double) Float.intBitsToFloat((int) v), Monotonicity.NONE);
All options and trade-offs4 options · 1,053 words
Options A and B were both built and run through gradle. A is recommended as the smallest change: it restores the pre-#16431 behaviour for exactly these two sources. B is the choice if maintainers want to keep pruning on raw-bit fields. C and D are not enough on their own.
fromDoubleField and fromFloatField pass Monotonicity.NONE instead of INCREASING (DoubleValuesSource.java:331, :336; +5/-2 lines with the comments).
// raw IEEE-754 bits are not ordered like the doubles they encode (negative values are ordered
// in reverse and NaN is above +Infinity), so skip-index bounds cannot be decoded directly
return fromField(field, Double::longBitsToDouble, Monotonicity.NONE);

// same as fromDoubleField: raw float bits are not ordered like floats
return fromField(field, (v) -> (double) Float.intBitsToFloat((int) v), Monotonicity.NONE);
Trade-offs
- Pruning lost on these fields only. The bound of these two sources is +Infinity again, as before #16431 and in every release, also for blocks whose bound is correct today (non-negative values and no NaN; SMT Q2a2). The stock
DoubleDocValuesField/FloatDocValuesFieldhave no skip index, so their bound was +Infinity anyway; only hand-built skip-indexed raw-bit fields lose block-max pruning. - Other sources unchanged.
fromLongField,fromIntFieldandfromFieldwith a declared monotonicity keep their bounds. - Side effect. It also makes LFV-221 (the bound rounded to the nearest float) moot for these two sources.
- Cost. No extra work per document; those fields lose block-max pruning, so top-k queries on them can score more documents than on main today; no benchmark was run.
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-31). Stock, the minimal test fails 2 of 2 with assertions on and 2 of 2 with assertions off, and the finder's 5,000-document test fails 2 of 2. With the fix:
- the minimal test: pass with assertions on (2 tests, 0 failures), pass with assertions off (2 tests, 0 failures);
- the finder's 5,000-document test: pass (2 tests, 0 failures);
- the whole
:lucene:queries:test: pass (51 classes, 512 tests, 0 failures, 5 skipped); - core
TestDoubleValuesSource,TestLongValuesSourceandTestMaxScoreBulkScorer: pass (32 tests, 0 failures); - the other modules' users of
fromDoubleField/fromFloatField(all of:lucene:expressions:test; facetTestMultiDoubleValuesSource,TestRangeFacetCounts,TestTaxonomyFacetValueSource; groupingTestDoubleRangeGroupSelector): pass (expressions 170 tests, 0 failures; facet 36 tests, 0 failures; grouping 7 tests, 0 failures); checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor core: pass.
B: sign-aware bounds for raw IEEE bits (keeps pruning; passes the same tests, positive NaN only) (validated by the checks)
A private flag on the field source marks the two raw-bits factories (+38/-4 lines in DoubleValuesSource.java). getMaxScore decodes the block's largest raw long when it is non-negative, else the smallest (all values negative). getMinScore decodes the smallest raw long when it is non-negative, the largest when all are negative, and returns -Infinity for mixed signs. A NaN result becomes +/-Infinity. The logic follows the sign-aware fix of the independent reproducer, which passed its 12 tests.
if (rawFloatBits) {
  // a non-negative raw maximum is the largest value; if all raw values are negative,
  // the smallest one is the largest value; NaN bounds nothing
  long maxRaw = skipper.maxValue(level);
  double max = decoder.applyAsDouble(maxRaw >= 0 ? maxRaw : skipper.minValue(level));
  return Double.isNaN(max) ? Float.POSITIVE_INFINITY : (float) max;
}
Trade-offs
- Keeps pruning for blocks without NaN; a block with a positive NaN, or for the minimum a block with mixed signs, falls back to an infinite bound.
- Positive NaN only. A NaN with the sign bit set (bits
0xfff8...) sorts among the negative longs, sogetMaxScorenever decodes it: for an all-negative block {-1.0, sign-bit NaN} it returns -1.0, and for a block that also holds a non-negative value it returns the largest non-negative value. The comment "NaN bounds nothing" holds for a positive NaN only (read from the diff, not run).FunctionScoreQueryscores such documents 0, and a negative bound for an all-negative block is LFV-203's clamp issue with or without NaN. No test with a sign-bit NaN was run against B. - More code: a second private constructor and a flag that
equals/hashCodeinclude. - Assumes the stored long is the sign-extended bit pattern, which is what
DoubleDocValuesField,FloatDocValuesFieldandindexedField(name, Float.floatToRawIntBits(v))store. - Keeps the float cast, so LFV-221 still applies to
fromDoubleField. No benchmark was run.
What the checks validated
None of these tests has a sign-bit NaN. Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-31). Stock, the minimal test fails 2 of 2 with assertions on and 2 of 2 with assertions off, and the finder's 5,000-document test fails 2 of 2. With the fix:
- the minimal test: pass with assertions on (2 tests, 0 failures), pass with assertions off (2 tests, 0 failures);
- the finder's 5,000-document test: pass (2 tests, 0 failures);
- the whole
:lucene:queries:test: pass (51 classes, 512 tests, 0 failures, 5 skipped); - core
TestDoubleValuesSource,TestLongValuesSourceandTestMaxScoreBulkScorer: pass (32 tests, 0 failures); - the other modules' users of
fromDoubleField/fromFloatField(all of:lucene:expressions:test; facetTestMultiDoubleValuesSource,TestRangeFacetCounts,TestTaxonomyFacetValueSource; groupingTestDoubleRangeGroupSelector): pass (expressions 170 tests, 0 failures; facet 36 tests, 0 failures; grouping 7 tests, 0 failures); checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor core: pass.- The independent reproduction's two classes, which also cover
fromFloatField, the mixed-sign minimum and a finite-bound check that the NONE fix fails by design:TestRawBitsDecoderBoundsV1pass (7 tests, 0 failures),TestFunctionScoreNaNBoundV1pass (5 tests, 0 failures), seed C0FFEE01.
FunctionScoreQuery's getMaxScore would treat NaN like an infinite value bound.
Trade-offs
Removes the dropped top hit (the hunt's randomized top-k-versus-exhaustive differential had no top-k mismatch left at a fix level that included this guard together with two sibling fixes), but leaves the public DoubleValues#getMaxScore/getMinScore wrong (NaN, and inverted for negative values) for every other caller. Not run as a standalone patch.
LFV-203's clamp (Math.max(0f, ...)) and LFV-211's inner-bound fix change other parts of the same return.
Trade-offs
Each alone leaves the finder's test failing 2 of 2; Math.max(0f, NaN) is NaN. With all five fixes of the hunt combined, upstream TestFunctionScoreQuery (17) and TestDoubleValuesSource (11) pass.
Where end users can set such a field, one document with NaN can push other documents of its block out of the top hits, and the effect outlives deleting that document until its segment is rewritten; the probe never returned a hidden, deleted or non-matching document.
While modelling the new bounds, the finder asked whether Lucene's built-in decoders are really increasing. SMT solvers (Z3 and cvc5) found raw bit patterns whose signed order is the reverse of their values, and a block whose largest bits decode to NaN next to a finite value; a public-API JUnit then showed the dropped top hit.
The method in full141 words
Method: semi-formal (the hunt's tier for a solver-witnessed hypothesis confirmed by execution). The hunt unit covered function queries and block-max pruning.
- Model. The finder encoded the decoders in floating-point/bit-vector SMT (QF_FPBV). Z3 4.12.2 and cvc5 1.4.2 both answered SAT for two raw longs (and two raw ints) in signed order whose doubles (floats) are in the opposite order, and for a block whose largest raw long decodes to NaN while it holds a positive finite value; UNSAT for "the bound is wrong although the block maximum is non-negative". Vacuity checks were SAT.
- JUnit. A directed public-API test (5,000 documents) then showed the wrong top hit on main, with assertions on and off; the minimal repro is that test cut down to 4,098 documents and a plain
search(q, 1). - Differential. The unit's randomized top-k-versus-exhaustive comparison also flags
fromDoubleFieldwith NaN values.
No prior report found (220 logged searches over GitHub issues, PRs and review comments, mailing lists, JIRA and downstream repositories on 2026-10-26; re-checked 2026-10-31). Closest: #16573/#16629, the same raw-bits ordering hazard in range-query code, where a maintainer asked to check other places.
Searches3 searches
- #16431 (the introducing PR): its review discussed the monotonicity of functions applied to the field values (custom functions and expressions versus a plain doc-values source), never NaN, negative values or the raw bit encoding.
- #16573 / #16629 (2026): raw float/double bits in NUMERIC doc values are not ordered like the values, in the doc-values range-query rewrite; a different code path and fix. romseygeek asked there to check "other places", naming only a range query.
- #16697 (fixes other defects of the same methods), #16429 (the feature request), #3347 (LUCENE-2271, open since 2010: NaN per-document scores in the old collector, a different mechanism).
- Open PRs touching
DoubleValuesSource.java(#13187, #14475, #14775), its tests (#16847) orDocValuesSkipper.java(#15737, #16358) do not touch the decoders or the bounds. - Same family (the hunt's own findings): LFV-203, LFV-211, LFV-214 and LFV-221 (same
getMaxScorepath), LFV-273 (the-0.0case of the per-documentscore()clamps,FunctionScoreQuery.java:246,FunctionQuery.java:132) and LFV-144 (the same raw-bits fact in sort pruning). - Limits: no GitHub code search of apache/lucene in the prior-art search (the downstream remark comes from a read-only code search of the Elasticsearch, OpenSearch and Solr default branches); private security reports cannot be searched; three issue searches on 2026-10-31 hit the rate limit.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and review comments (apache/lucene incl. the migrated JIRA archive), commits, open PRs | 2026-10-26 | 220 logged read-only queries in all sources (REST replayed from cache, then GraphQL search after GitHub's search rate limit ran out); git history of main and the release branches; the changed-file lists of all 413 open PRs, and the patches of those touching DoubleValuesSource.java | 22 hits read in full; none is this bug |
| Mailing lists (dev@, java-user@, issues@, commits@), LUCENE and SOLR JIRA, Elasticsearch, OpenSearch and Solr repositories, web | 2026-10-26 | list searches and thread reads, JQL, downstream GraphQL search, 7 web queries | no report; only notification mails of #16431 and #16697 |
| GitHub issues and PRs (apache/lucene) | 2026-10-31 | FunctionScoreQuery, DoubleValuesSource, fromDoubleField, Monotonicity and getMaxScore, sorted by last update; tracking issue #16937 | nothing new (newest hits #16855 and #16705, unrelated); #16937 does not mention it |
Introduced by #16431 (0d4f93a9ff9, merged 2026-08-22), which declared the decoders INCREASING; the wrong top hit is reachable end to end since #16697 (2026-10-09). On main and branch_11x; no release (10.0.0, 10.5.2 and 10.6.0 return the right hit).
Versions tested7 rows
Introduced by 0d4f93a9ff93ccc396c1323f26416b57d8dc08d9, #16431 "Enable Block-Max WAND dynamic pruning for FunctionScoreQuery via DocValuesSkipper (+422% QPS)" (Rajat Jain, co-author Uwe Schindler; merged to main 2026-08-22; resolves #16429). It attached INCREASING to the raw-bits decoders that fromDoubleField/fromFloatField have used since LUCENE-5325 (3f24fd81c83, 2016) and added the skipper-based bounds. git blame of the two lines and git log -S'Monotonicity.INCREASING' return only this commit.
Masked at first: until #16697 (d150ba27d11, Zhang Chao, 2026-10-09) the tested end-to-end queries threw inside the skipper (a separate advanceShallow defect) before they could return a hit; the bounds were already wrong, and #16697's change shadowed onto the introducing commit gives the wrong top hit.
Now (refs as fetched 2026-10-31): main 2f424fd428da (12.0.0-SNAPSHOT) and branch_11x 603af8703753 carry the same files, and the later branch_11x commits up to d0c0decc6606 (2026-10-30, GitHub compare) do not touch them; CHANGES.txt lists #16431 and #16697 under 11.0.0. 10.6.0 does not contain #16431.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails 2 of 2 with assertions on and off (gradle and standalone); passes with either fix |
main d150ba27d11, ea57360912ed, a9779ef3c193 | affected | the finder's test fails 2 of 2 (wrong top hit doc 1 instead of doc 4999; bound -2.0 for {-1.0, -2.0}) |
0d4f93a9ff9 (#16431) | bounds only | wrong bounds; the end-to-end queries threw in the skipper first; with #16697's change shadowed: the wrong top hit |
main 2f424fd428da, branch_11x 603af8703753 to d0c0decc6606 | same code | the affected files are identical to 645d4fe14a20; the 5 branch_11x commits after 603af8703753 do not touch them (read, not run) |
| 10.6.0 | not affected | the portable NaN top-hit test passes 2 of 2 (it fails on 645d4fe14a20); no bound API |
10.0.0, 10.5.2, parent a1fcd50799f | not affected | the portable NaN top-hit tests pass (10.5.2 and the parent with assertions on and off); FunctionScoreQuery's bound is +Infinity |
| 9.12.3 | no skip index | the trigger cannot be written: NumericDocValuesField.indexedField does not exist |
Reproduced by an independent reproducer (7 of 7 bug tests, 70/70 over 10 iterations), a devil's-advocate verifier, two executed reviews by OpenAI GPT-5.6, an adjudication and this doc's gradle run; controls without NaN pass. Both fixes pass the minimal repro, the finder's test and the independent reproduction's NaN tests; fix A fails only the independent reproduction's five finite-bound checks, which reject it by design.
Checks and verdicts383 words
Every check ran its own tests or re-ran an earlier one on stock builds; the cross-model reviewers executed code.
| Check | Verdict | What it found |
|---|---|---|
| Finder (SMT, then JUnit) | candidate | Z3 and cvc5: raw bits whose order is the reverse of their values and a NaN block maximum (SAT); the bound is right for a non-negative maximum (UNSAT); the directed JUnit fails 2/2 on main with assertions on and off; each sibling FunctionScoreQuery fix alone leaves it failing. |
| Refute lens (OpenAI GPT-5.6, executed) | real (high) | Its own two test classes fail on main over five seeds, assertions on and off; controls and the fix pass; upstream TestDoubleValuesSource 11/11 and TestFunctionScoreQuery 17/17 with the fix. |
| Independent reproducer | real | Own public-API tests, default codec: 7 of 7 bug tests fail (double and float), 5 controls pass, assertions on and off; 70/70 over 10 iterations; found the mixed-sign getMinScore case; 10.5.2 passes; its sign-aware fix passes 12/12. |
| Works-as-designed lens (OpenAI GPT-5.6) | real (high) | Intended-behaviour argument weak; its own 5-test class fails 3 of 5 on main and passes 5/5 with the NONE fix, re-run separately with two seeds. |
| Intended-behaviour devil's advocate | real | No intended, documented, misuse or unreachable argument survives; its own float probe fails 2 of 3 (inverted bounds, wrong search(q, 1) top hit); the non-negative control passes. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's tests with seed 1D6E0426: 12 run, 7 failed, assertions on and off; with the NONE fix every NaN test passes (the 5 remaining failures are the independent reproduction's deliberate check that the bound stays finite). |
| Re-verification on newer main and the minimal repro | still reproduces | Still fails on a9779ef3c193; the minimal class fails 2/2 on 645d4fe14a20 with assertions on and off, 10/10 over 5 random-seed iterations, and passes with the NONE fix. |
| This doc's fix validation (gradle) | real; both fixes pass the tests run | Scratch worktree of 645d4fe14a20, gradle: stock fails the minimal and the finder's tests; fix A (NONE) and fix B (sign-aware) each pass them, the whole queries module and the closest core and other-module suites; fix B also passes the independent reproduction's two classes. An instrumented trace shows the window where the text clause becomes required; 10.6.0 passes the portable NaN test. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 469 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,444 words
- Registry title
- DoubleValuesSource.fromDoubleField/fromFloatField declare their raw IEEE-bit decoders INCREASING, so on a skip-indexed raw-bits field one NaN makes a block's score bound NaN (FunctionScoreQuery under TOP_SCORES then silently drops the true top hit) and all-negative blocks get inverted bounds
- Area
- search / function scoring (DoubleValuesSource skip-index score bounds for FunctionScoreQuery block-max pruning)
- Priority
- Low, rank 717: FromDoubleField and fromFloatField declare raw-bit decoders INCREASING, so one NaN in a skip interval drops the true top hit under TOP_SCORES, unreleased and only for hand-built raw-bit skip-indexed fields.
- Impact class
- silent wrong results
- Impact note
- Applications on unreleased main (11.0.0-SNAPSHOT, since #16431) that index a double or float as raw IEEE bits in a NUMERIC doc-values field with the opt-in doc-values skip index (NumericDocValuesField.indexedField(name, Double.doubleToRawLongBits(v)) or a custom FieldType; the stock DoubleDocValuesField/FloatDocValuesField have no skip index and are unaffected) and rank it with FunctionScoreQuery over fromDoubleField/fromFloatField next to another scoring clause: once one document of a 4,096-document skip interval holds NaN, the default IndexSearcher.search(q, n) (TOP_SCORES once the 1,000-hit threshold is passed) silently misses competitive documents of that interval, including the true top hit, with the default codec and searcher, -ea or -da, at about 5,000 docs; all-negative intervals also get wrong public DoubleValues#getMaxScore/getMinScore bounds; no released version is affected.
- Summary
- You index doubles as raw IEEE bits in a NUMERIC doc-values field with a skip index (NumericDocValuesField.indexedField('rating', Double.doubleToRawLongBits(v))) and search BooleanQuery(SHOULD FunctionScoreQuery(MatchAllDocsQuery, DoubleValuesSource.fromDoubleField('rating')), SHOULD TermQuery) for the top hit, expecting the same top hit as an exhaustive search (a NaN value simply scores 0, as upstream TestFunctionScoreQuery#testNaN expects). Instead, with 5,000 docs valued 0.5, one NaN at doc 4500 and 50.0 at doc 4999, TOP_SCORES returns doc 1 (score 4.19) instead of doc 4999 (score 50). The cause is that fromDoubleField declares Double::longBitsToDouble INCREASING, so a block's maximum is read as the decoded largest raw long: NaN's raw bits are above every number's, giving a NaN bound, and negative values are in reverse raw order, so a block holding {-1.0, -2.0} reports getMaxScore -2.0 and getMinScore -1.0.
- Introduced
- 0d4f93a9ff9 on main (apache/lucene#16431 'Enable Block-Max WAND dynamic pruning for FunctionScoreQuery via DocValuesSkipper (+422% QPS)', by rajat315315 with uschindler as co-author, resolves #16429, merged 2026-08-22) [exec: the follow-up history sweep shows the bound defects at 0d4f93a9ff9 with -ea and -da (candidate repro 'value -1.0 > getMaxScore(4095) = -2.0'; the independent reproduction's 4 bound tests), while its parent a1fcd50799f has no bound API and passes the portable NaN top-hit tests; read: git blame of DoubleValuesSource.java:331 and :336 and git log --all -S'Monotonicity.INCREASING' -- DoubleValuesSource.java return only 0d4f93a9ff9]; it attached Monotonicity.INCREASING to the raw-bits decoders Double::longBitsToDouble and Float.intBitsToFloat((int) v), which fromDoubleField/fromFloatField have used since LUCENE-5325 (3f24fd81c83, 2016), and added the skipper-based getMaxScore/getMinScore that decode skipper.maxValue/minValue through them; the end-to-end wrong top hit became reachable with #16697 (d150ba27d11, by easyice, 2026-10-09), which fixed a separate advanceShallow defect that made the tested queries throw first [exec: #16697's DoubleValuesSource change shadowed onto 0d4f93a9ff9 gives main's wrong top hit] (2026-08-22 (0d4f93a9ff9 on main); wrong top hit reachable end to end from 2026-10-09 (d150ba27d11, #16697))
- First affected version
- unreleased (main only; 11.0.0 would be the first release with it) [exec: 10.0.0 and 10.5.2 correct; read: git tag --contains 0d4f93a9ff9 is empty]
- Affected versions
- main (11.0.0-SNAPSHOT) from 0d4f93a9ff9 (2026-08-22) through ea57360912ed (upstream main HEAD on 2026-10-26) [exec: wrong DoubleValues bounds at 0d4f93a9ff9, d150ba27d11 and main, -ea and -da; wrong TOP_SCORES top hit at d150ba27d11 and main, and at 0d4f93a9ff9 only with #16697's change shadowed, because before #16697 the tested queries threw in the skipper first]; not affected: 10.0.0 and 10.5.2 [exec: the portable NaN top-hit test and the independent reproduction's FunctionScoreQuery NaN tests pass, on 10.5.2 with -ea and -da; the bound API does not exist there and FunctionScoreQuery's bound is +Infinity] and the parent commit a1fcd50799f [exec]; not applicable: 9.x [exec on 9.12.3: compile error, no NumericDocValuesField.indexedField]; unreleased branch_10x (1309534296e) and branch_10_6 (2763db11b0a) do not contain #16431 and have no Monotonicity [read, 2026-10-26]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3/cvc5; also reached by fuzzing/PBT
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 220 logged read-only queries over apache/lucene issues, PRs and review comments (REST replayed from the finder's cache plus GraphQL search, because GitHub's search rate limit ran out), git history of main and the release branches, the changed-file lists of all 413 open PRs (the patches of those touching DoubleValuesSource.java read), the dev@, java-user@, issues@ and commits@ lists, the LUCENE JIRA archive and SOLR JIRA, the Elasticsearch, OpenSearch and Solr repositories, and 7 web queries; plus the finder's scripted prior-report search and manual searches, and the independent reproduction's and the intended-behaviour check's searches; 22 hits read, none of them this bug; no GitHub code search); not fixed on upstream main (HEAD ea57360912ed on 2026-10-26 still declares both decoders INCREASING at DoubleValuesSource.java:330-337); open PRs touching DoubleValuesSource.java (#13187, #14475, #14775), its tests (#16847) or DocValuesSkipper.java (#15737, #16358) do not touch the decoders or the bounds; origin: #16431 (resolves #16429; its review discussed monotonicity only for user-supplied functions); #16697 fixed other defects in the same methods; related prior items, different bugs (different code and fix): #16573 / #16629 (2026, raw-bit NUMERIC floats and doubles are not ordered like the values, in the doc-values range-query rewrite; a maintainer asked there to check other places for the same assumption and named only IndexSortSortedNumericDocValuesRangeQuery), #16698 / #16699, #749 (LUCENE-10466), #3347 (LUCENE-2271, open since 2010: NaN per-document function scores in the old collector)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off through gradle in a scratch worktree and through a standalone runner; an instrumented trace shows the window where the text clause becomes required. Both fixes pass the minimal test, the finder's 5,000-document test, the whole queries module and the closest core suites. Release 10.6.0 passes the hunt's portable NaN top-hit test (standalone runner). Upstream main2f424fd428da(2026-10-30) andbranch_11x603af8703753(2026-10-29) carry the same code, and the laterbranch_11xcommits up tod0c0decc6606(2026-10-30) do not touch it [read].
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/DoubleValuesSource.java:51-58 (Monotonicity: 'INCREASING: Increasing function'), :330-337 (fromDoubleField = fromField(field, Double::longBitsToDouble, Monotonicity.INCREASING); fromFloatField = Float.intBitsToFloat((int) v), INCREASING), :572-599 (getMaxScore/getMinScore decode skipper.maxValue/minValue of the level through the decoder)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/DoubleValues.java:55-69 (getMaxScore/getMinScore: 'maximum/minimum score that documents between the current position and upTo can produce')a Lucene main checkout lucene/queries/src/java/org/apache/lucene/queries/function/FunctionScoreQuery.java:243-252 (score() maps missing, negative and NaN values to 0), :262-268 (getMaxScore guards only Float.isInfinite, returns innerMaxScore * valueMaxScore * boost)a Lucene main checkout lucene/core/src/java/org/apache/lucene/document/DoubleDocValuesField.java:19-21, :38-40 (raw-bit encoding via Double.doubleToRawLongBits, no skip index); lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java:226 (DEFAULT_SKIP_INDEX_INTERVAL_SIZE = 4096); lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:100 (TOTAL_HITS_THRESHOLD = 1000)a Lucene main checkout lucene/queries/src/test/org/apache/lucene/queries/function/TestFunctionScoreQuery.java:255-271 (testNaN: a NaN value read through fromDoubleField must score 0); lucene/core/src/test/org/apache/lucene/search/TestDoubleValuesSource.java:412-421 (testMaxScoreBeyondTheCurrentBlock asserts getMinScore(upTo) <= value <= getMaxScore(upTo), fromLongField only)a Lucene main checkout lucene/CHANGES.txt:223-224 (Lucene 11.0.0: GITHUB#16431, GITHUB#16697 add Block-Max WAND dynamic score skipping in FunctionScoreQuery and DoubleValuesSource using DocValuesSkipper)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/DoubleValuesSource.java:51-58, (at 645d4fe14a20) :330-341, :556-569, :571-584, :586-599lucene/queries/src/java/org/apache/lucene/queries/function/FunctionScoreQuery.java:243-252, (at 645d4fe14a20) :262-269lucene/core/src/java/org/apache/lucene/search/MaxScoreBulkScorer.java:447-472 (at 645d4fe14a20) (:460-461), :474-551 (:490-492, :502, :509, :524-547, :540); BooleanScorerSupplier.java:315-328; IndexSearcher.java:100, :599; TopScoreDocCollector.java:58-60lucene/core/src/java/org/apache/lucene/document/DoubleDocValuesField.java:19-21, (at 645d4fe14a20) :38-40; FloatDocValuesField.java:40; NumericDocValuesField.java:39-60; lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java:226
- Who is affected
lucene/core/src/java/org/apache/lucene/document/NumericDocValuesField.java:39-60 (at 645d4fe14a20) (TYPE has no skip index; indexedField uses RANGE); DoubleDocValuesField.java:38-40; FloatDocValuesField.java:40; lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesFormat.java:226lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90DocValuesConsumer.java:250-262 (at 645d4fe14a20) (a skip-index interval keeps growing past 4,096 documents while a dense run of one value continues)
- Minimal repro
lucene/test-framework/src/java/org/apache/lucene/tests/util/TestUtil.java:1330-1332 (at 645d4fe14a20) (getDefaultCodec = new Lucene104Codec()); LuceneTestCase.java:464-469 and SetupAndRestoreStaticEnv.java:200-214 (the env NOTE line reports the randomized class codec)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/DoubleValuesSource.java:51-58; (at 645d4fe14a20) DoubleValues.java:55-69; Scorer.java:76-79; ScoreMode.java:28-32lucene/core/src/test/org/apache/lucene/search/TestDoubleValuesSource.java:400-403, (at 645d4fe14a20) :412-421; lucene/queries/src/test/org/apache/lucene/queries/function/TestFunctionScoreQuery.java:255-274; lucene/queries/src/java/org/apache/lucene/queries/function/FunctionScoreQuery.java:250lucene/core/src/test/org/apache/lucene/search/TestSortOptimization.java:474-477 (at 645d4fe14a20) (FloatDocValuesField.indexedField with raw float bits)
- History
a Lucene clone refs as fetched 2026-10-31: origin/main 2f424fd428da, origin/branch_11x 603af8703753 (DoubleValuesSource.java, DoubleValues.java, FunctionScoreQuery.java, MaxScoreBulkScorer.java identical to 645d4fe14a20; contains 0d4f93a9ff9); releases/lucene/10.6.0 does not contain 0d4f93a9ff9lucene/CHANGES.txt:238-239 (at 645d4fe14a20)GitHub compare 603af8703753...branch_11x, 2026-10-31 (read-only): 5 commits ahead, head d0c0decc6606 (2026-10-30), none touches DoubleValuesSource.java, DoubleValues.java, FunctionScoreQuery.java or MaxScoreBulkScorer.java; compare 2f424fd428da...main: identical
- TestRawBitsDoubleFieldBounds.java (one test class):
repro/LFV-189/src/org/apache/lucene/queries/function/TestRawBitsDoubleFieldBounds.java(88 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and an instrumented run of it (the skip block's stored minimum and maximum, the bounds and the dropped window).
assets/LFV-189/bug.png(469 KB)