AutomatonQuery adds up its heap once, in the constructor, and keeps the sum. A query over a non-deterministic automaton runs on an NFARunAutomaton, which builds DFA states as it meets terms and keeps them on the query. The kept sum never sees those states.
- ramBytesUsed(). Queries that implement
Accountablereport an estimate of the heap they hold.LRUQueryCachecaches the matching documents of filters, keyed by query, charges each cached query this estimate, and evicts entries once it holds more thanmaxSizeentries ormaxRamBytesUsedbytes. - DFA or NFA. A wildcard such as
*a?????????compiles to a non-deterministic automaton (NFA). Lucene can turn it into a DFA up front (determinize it), or run it as an NFA that builds DFA states lazily, only for the inputs it meets, and remembers them. - Main changed the default. Up to 10.6,
WildcardQuery(Term)andRegexpQuery(Term)determinized up front. On main (#15939, #15961) they run non-deterministic patterns as an NFA. In 10.x only anAutomatonQuerybuilt from a non-determinized automaton, orRegexpQuery(..., doDeterminization=false), ran as an NFA.
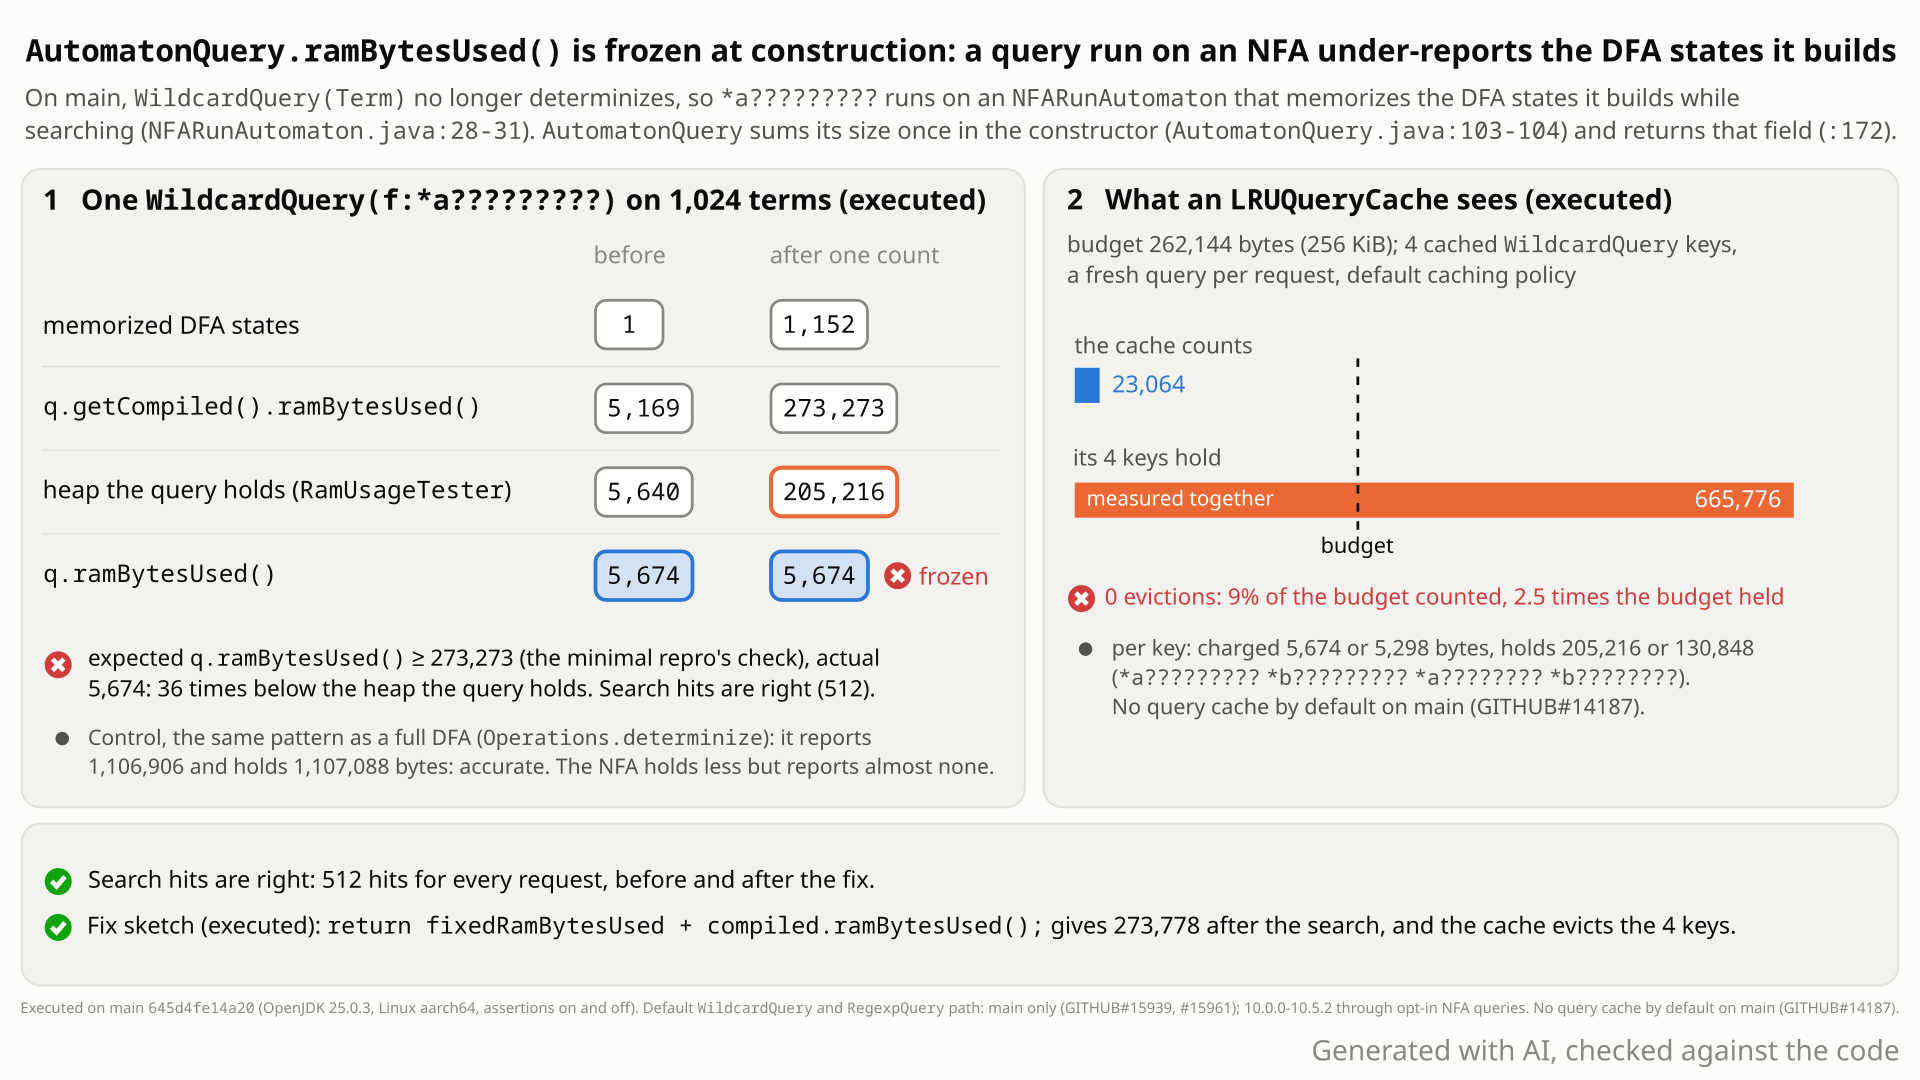
- On Lucene main, index all 1,024 ten-letter strings over {a, b} and count
new WildcardQuery(new Term("f", "*a?????????")). Before the search the query reportsramBytesUsed()= 5,674 bytes and really holds 5,640: correct. - You expect the number to follow the query's heap:
ramBytesUsed()is an estimate of the object's heap, andLRUQueryCachecharges it against itsmaxRamBytesUsedbudget. - On main this pattern is not turned into a DFA up front. The search builds DFA states inside the query's
NFARunAutomatonand keeps them: the query now holds 205,216 bytes, and its compiled automaton reports 273,273. - Instead
ramBytesUsed()still says 5,674, becauseAutomatonQuerycomputed it once in its constructor and stored it in a final field: 36x too low here, 310x for a longer pattern on a 20,000-document field. - A cache believes it:
LRUQueryCache(1000, 1 MiB)keeps 4 wildcard filters that hold 7.4 MB, accounts 37 KB and evicts nothing. Hits stay correct. Releases 10.0 to 10.6 are hit only through opt-in NFA queries.
On main: applications that build default WildcardQuery or RegexpQuery objects (also through the classic QueryParser) and install an LRUQueryCache, which is off by default there. In 10.0 to 10.6: only opt-in NFA queries, and the cache overrun needs a reused query instance. The cache's byte budget no longer bounds the heap these filters retain; hits stay correct.
Mechanism, terms and numbers706 words
AutomatonQuery implements Accountable, but it computes ramBytesUsed() once, in its constructor, and stores the sum in a final field (private final long ramBytesUsed; // cache). When the automaton is not deterministic, its CompiledAutomaton runs it with an NFARunAutomaton, which determinizes lazily and keeps every DFA state it builds for the life of the query. The NFA's own estimate and CompiledAutomaton.ramBytesUsed() follow that growth; the query's stored value does not. On main, WildcardQuery(Term) and RegexpQuery(Term) no longer determinize (#15939, #15961), so the default constructors take this path: after one count over 1,024 terms, WildcardQuery(*a?????????) reports 5,674 bytes while it holds 205,216 (36x); on a 20,000-document field *a???????????? reports 6,714 for 2,081,152 (310x). LRUQueryCache charges a cached query exactly this value, so with a 1 MiB budget 4 cached wildcard filters retain 7,399,536 bytes while the cache accounts 37,368 and evicts nothing. Search hits are always correct. Releases 10.0.0 to 10.6.0 are affected through the opt-in NFA paths (an AutomatonQuery over a non-determinized automaton, RegexpQuery(..., doDeterminization=false)); 9.x is not.
- Construction.
AutomatonQuery.java:93-105: the constructor buildscompiled = new CompiledAutomaton(automaton, false, true, isBinary)(:99) and storesBASE_RAM_BYTES + term.ramBytesUsed() + automatonBytes + compiled.ramBytesUsed()in the final fieldramBytesUsed(:57, commented "// cache";:102-104).ramBytesUsed()returns the field (:170-173). - NFA execution.
CompiledAutomaton.java:253-257: if neither the automaton nor its UTF-8 form is deterministic, it keeps no DFA and createsnew NFARunAutomaton(binary, 0x100); its javadoc says such an automaton "will be executed using NFARunAutomaton" and still calls the class "Immutable" (:36-40). - The states grow during the search.
NFARunAutomaton.java:28-31: "It will lazily determinize on-demand, memorizing the generated DFA states that has been explored." New states go intodStateToOrdanddStatesunderstateRegistryLock(:49-51,findDState:159-177); each state's transitions fill in as terms are stepped (:309-332). Nothing drops them while the query lives. - Who counts them.
NFARunAutomaton.ramBytesUsed()(:260-268) andCompiledAutomaton.ramBytesUsed()(:554-561) are live.AutomatonQueryread the compiled estimate once, when the NFA had one state. - The default path on main.
WildcardQuery.java:49-60passestoAutomaton(term)(:67-101, a concatenation, no determinize) toAutomatonQuery;RegexpQuery.java:54-56,:90-101passesnew RegExp(...).toAutomaton(provider). The classic query parser builds both (QueryParserBase.java:512,:579). - The cache.
LRUQueryCache.java:465-471chargesRamUsageEstimator.sizeOf(query, 32), which isramBytesUsed()for anAccountable(RamUsageEstimator.java:378-386); for a filter the key is the constant-score wrapper, whose value is an object header and a reference (16 bytes here) plus the wrapped query's (AbstractMultiTermQueryConstantScoreWrapper.java:52-56). The DocIdSet is built first, so the NFA has already run on that segment (LRUQueryCache.java:609-610); the query is then sized once, at its first reference (:990-999,:1110-1121).UsageTrackingQueryCachingPolicy.java:45-54,:122-125: aMultiTermQueryis cached after 2 uses.
Same 1,024-term index as the repro, one count, retained heap measured with the test framework's RamUsageTester:
| query | ramBytesUsed() before / after | retained before / after |
|---|---|---|
default WildcardQuery(*a?????????), NFA | 5,674 / 5,674 | 5,640 / 205,216 |
opt-in AutomatonQuery(RegExp(".*a.{9}").toAutomaton()), NFA | 5,666 / 5,666 | 5,632 / 205,208 |
| the same language determinized by the caller (DFA control) | 1,106,898 / 1,106,898 | 1,107,080 / 1,107,080 |
The DFA is accounted to within 182 bytes (about 0.02%). The defect is the accounting, not extra memory: here the lazy NFA holds less than the full DFA would.
On the study's field of 20,000 documents with random 20-letter a/b terms (19,809 distinct), after one count: *a???? reports 3,890 and retains 18,560; *a????????? 5,674 and 465,552; *a???????????? 6,714 and 2,081,152; *a??????????????? 7,810 and 12,744,056. A non-leading pattern, a*b??????????, reproduces too: 6,442 reported vs 583,008 retained on the same field (the study's refute-lens reviewer saw 6,442 vs 1,025,888 on its own index of 12,000 random 18-letter terms).
Cache: that field in one segment, new LRUQueryCache(1000, 1 MiB), the default UsageTrackingQueryCachingPolicy, and 4 patterns (*a????????????, *b????????????, *a???????????b, *b???????????a) each sent 3 times as a fresh ConstantScoreQuery(new WildcardQuery(...)): the cache accounts 37,368 bytes in total while its 4 cached query keys retain 7,399,536 bytes (7.1x the budget). Fresh per-request queries share one key on main because #15961 gave NFA-backed automata value equality (NFARunAutomaton.java:270-281).
Exposure and likelihood352 words
- Who, on main (unreleased 11.0). Default
WildcardQuery/RegexpQueryobjects for non-deterministic patterns (a*or.*followed by more pattern), used as filters or counts, with an application-installedLRUQueryCache. Caching is off by default on main (IndexSearcher.java:82-84, #14187); MIGRATE.md shows how to turn it back on (lucene/MIGRATE.md:227-236). By default the cache only caches on segments of 10,000+ documents (LRUQueryCache.java:251-253). - Who, on 10.0.0 to 10.6.0. Only callers that opt into NFA execution:
new AutomatonQuery(term, automaton)over an automaton they did not determinize (10.0 stopped determinizing behind the scenes,lucene/MIGRATE.md:922-926), orRegexpQuery(..., doDeterminization=false)(#12767). The defaultIndexSearchercache is on there (LRUQueryCache(1000, min(32 MB, heap / 20)), 10.6.0IndexSearcher.java:95-100), but NFA-backed queries compare by identity, so the overrun needs the application to reuse the same query instance. - What happens. The cache's byte budget no longer bounds the heap these keys actually retain: the cache keeps the bytes it records under
maxRamBytesUsed, but for these keys those are construction-time values, so in the runs shown onlymaxSize(1,000 entries by default) limits them. Any other reader oframBytesUsed()after a search gets the stale value too. - How much. It grows with the pattern and the field: about 1.5x to 2x more retained per extra
?on the study's field (18.6 KB for*a????, 2.1 MB for*a????????????, 12.7 MB for*a???????????????), so short patterns leave little unaccounted heap. Main also runs, as an NFA with no work limit, patterns whose determinization with the default limit (the one 10.x'sWildcardQuery(Term)applied up front) throwsTooComplexToDeterminizeException: for one 16-?pattern on 100,000 documents the study saw the compiled automaton count 39 MB while the query reported 8,162 bytes (run on main, not on a 10.x release; not re-measured). - What it does not do. No hit is wrong; nothing is bypassed or exposed. No
OutOfMemoryErrorrun was made. - How likely: rare. It takes long patterns on fields with many distinct terms, repeated often enough to be cached, with a cache installed (main) or an opt-in NFA API and reused instances (10.x).
One JUnit test (Lucene's test framework; the behaviour under test is reached through public APIs only): index every 10-letter a/b string once, run one count of WildcardQuery(f:*a?????????) (512 hits), and assert that the query's ramBytesUsed() is at least its compiled automaton's. No RamUsageTester, no cache, single thread, deterministic.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestAutomatonQueryRamBytesUsedAfterSearch extends LuceneTestCase {

  public void testRamBytesUsedCoversCompiledAutomatonAfterSearch() throws IOException {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig config = new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec());
      try (IndexWriter w = new IndexWriter(dir, config)) {
        for (int i = 0; i < 1024; i++) { // every 10-character string over {a, b}
          String bits = Integer.toBinaryString(1024 + i).substring(1);
          String term = bits.replace('0', 'a').replace('1', 'b');
          Document doc = new Document();
          doc.add(new StringField("f", term, Field.Store.NO));
          w.addDocument(doc);
        }
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        WildcardQuery q = new WildcardQuery(new Term("f", "*a?????????"));
        new IndexSearcher(reader).count(q);
        long compiled = q.getCompiled().ramBytesUsed();
        assertTrue(
            "expected WildcardQuery.ramBytesUsed() >= its compiled automaton's "
                + compiled
                + " after one search, but was "
                + q.ramBytesUsed(),
            q.ramBytesUsed() >= compiled);
      }
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests TestAutomatonQueryRamBytesUsedAfterSearch -Ptests.seed=DEADBEEF
- Expected
- After the search
q.ramBytesUsed()is at leastq.getCompiled().ramBytesUsed()(273,273), since the query holds that automaton. - Observed
AssertionError: expected WildcardQuery.ramBytesUsed() >= its compiled automaton's 273273 after one search, but was 5674, with assertions on and off.
More files, environment, full output250 words
The assertion is the lower bound Lucene's own formula implies: the query holds its CompiledAutomaton, and its value is defined as a fixed part plus compiled.ramBytesUsed(). It needs no tolerance and no outside measurement. The retained sizes on this page come from separate checks with RamUsageTester, not from the repro.
Release jars: the test passes on 10.5.2 and 10.6.0, where WildcardQuery(Term) is determinized up front. To run it on the released versions, replace the WildcardQuery line with new AutomatonQuery(new Term("f", ".*a.{9}"), new RegExp(".*a.{9}").toAutomaton()): that fails on main (5,666 vs 273,273), 10.5.2 and 10.6.0 (5,674 vs 273,281). Use one form or the other, not both; the swap also changes the declared type to AutomatonQuery and imports org.apache.lucene.util.automaton.RegExp.
Regression test: this same test; it passes with the recommended fix and fits as one more method in TestAutomatonQuery.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Releases 10.5.2 and 10.6.0: passes (default path determinized there) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestAutomatonQueryRamBytesUsedAfterSearch.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestAutomatonQueryRamBytesUsedAfterSearch -Ptests.seed=DEADBEEF
# the same result with -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF (assertions on; the same with -Ptests.asserts=false)
TestAutomatonQueryRamBytesUsedAfterSearch > testRamBytesUsedCoversCompiledAutomatonAfterSearch FAILED
    java.lang.AssertionError: expected WildcardQuery.ramBytesUsed() >= its compiled automaton's 273273 after one search, but was 5674
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:CCE427083B0F174A]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.assertTrue(Assert.java:42)
        at org.apache.lucene.search.TestAutomatonQueryRamBytesUsedAfterSearch.testRamBytesUsedCoversCompiledAutomatonAfterSearch(TestAutomatonQueryRamBytesUsedAfterSearch.java:50)

# with the recommended fix: 1 test, 0 failures (assertions on and off)ramBytesUsed()is "an estimate of the JVM heap memory used by this object"; it stays fixed while the query grows 36x.- The stored value dates from 2019, when compiled automata were always DFAs; #13741 made the NFA's own estimate live.
- #16390 fixed a far smaller error here, a double count; its issue says the value "feeds LRUQueryCache eviction decisions".
The full argument230 words
- The contract.
Accountable.java:34-40: "Returns an estimate of the JVM heap memory used by this object in bytes."LRUQueryCache.java:60-62: it evicts "in order to remain under a given maximum size and number of bytes used". - The field predates NFA execution. LUCENE-8855 (
a76c962ee61, 2019, #9898) cached the value for "finalized" queries to avoid recomputing it, when aCompiledAutomatonwas always a DFA. LUCENE-10010 (#225,c972c6a7754, 2021) made the compiled form grow after construction; the field was not revisited. - Upstream wants the states counted. On #13715 Robert Muir listed "
ramBytesUseddoesn't considernfaRunAutomaton" as a problem, and Patrick Zhai, the NFA's author, noted that the NFA "will remember all the states that has been determinized". #13741 then madeNFARunAutomatonandCompiledAutomatoncount them live; only the outerAutomatonQuerycopy stayed frozen. - Smaller errors here were bugs. #16389/#16390 (a double count in this method, fixed in 10.6.0; "ramBytesUsed() feeds LRUQueryCache eviction decisions"); #16046 (an 18-35% over-count in
CompiledAutomaton.ramBytesUsed()). - Upstream tests.
TestAutomatonQuery.java:289-303holds the value within 10% ofRamUsageTester,TestNFARunAutomaton.java:46-53within 30%, on fresh objects only; the helper atTestAutomatonQuery.java:305-320defines the value as shallow size + term +q.getCompiled().ramBytesUsed(), the relation the repro checks after a search. - Precedent. LUCENE-9350 (#10390) stopped
FuzzyQueryfrom keeping automata on the query because they "can end up blowing up query caches"; #15097/#15124 and #16405/#16406 fixed other cache under-counts.
The devil's-advocate check273 words
The strongest case: ramBytesUsed() is only "an estimate"; Accountable is @lucene.internal, and AutomatonQuery, CompiledAutomaton and LRUQueryCache are @lucene.experimental; the field is labelled "// cache" on purpose, and LRUQueryCache itself sizes a query only once (LRUQueryCache.java:973-999), so both treat a query's size as fixed; the NFARunAutomaton javadoc documents the growth; the WildcardQuery javadoc warns against a leading *; caching is off by default on main; on #15939 Robert Muir wrote that RegexpQuery "is convenience for a one-off" and that a heavily reused pattern should use AutomatonQuery; and on #16031 (closed unmerged) a contributor argued that FuzzyQuery#ramBytesUsed should return "a stable value" rather than "jump from 0 to N after the first execution".
Why it fails: keeping the states is intended; nothing in the code, the docs or the history says under-reporting them is, and upstream already made the inner estimates live (#13741). The "// cache" was right when written and went stale with #225. The cache's one-time sizing is no excuse: the DocIdSet is built before the key is sized (LRUQueryCache.java:609-610), so a live value would cover the first segment. The leading-* warning is about speed, and a non-leading pattern and the opt-in RegExp path reproduce. The "one-off" remark is about DFA versus NFA speed, while here the reuse comes from Lucene's own cache, which on main shares one key across fresh queries. #16031 concerns a query that holds no automaton and was not merged. No reviewer found the intended-behaviour case convincing: every review that rated its strength called it moderate, and the devil's-advocate review concluded with high confidence that the stale value is not intended.
Recommended A live value, read under the NFA's lock
Keep only the fixed part in a field and return it plus compiled.ramBytesUsed() on every call, and read the NFA's states under the lock that already guards them. The repro and the study's cache test pass, as do 312 tests in the closest suites. The cache still sizes a query once, so later growth stays uncounted.
// AutomatonQuery
private final long fixedRamBytesUsed; // BASE_RAM_BYTES + term + automaton (unless shared)
public long ramBytesUsed() {
  return fixedRamBytesUsed + compiled.ramBytesUsed();
}

// NFARunAutomaton
public long ramBytesUsed() {
  synchronized (stateRegistryLock) {
    return BASE_RAM_BYTES + ... + RamUsageEstimator.sizeOfMap(dStateToOrd) + ...;
  }
}
All options and trade-offs4 options · 677 words
Option A was built and run through gradle. B (bound the NFA's state cache) and C (do not keep the states on the query) change the design and cap what a query can hold; D (re-size cached keys) closes the cache-side gap A leaves. None of B-D was run. Workarounds that need no fix: determinize patterns yourself and use AutomatonQuery (MIGRATE.md's recipe, which also restores a work limit), keep MultiTermQuery filters out of the cache with a custom QueryCachingPolicy, or run without a query cache (the default on main).
AutomatonQuery keeps BASE_RAM_BYTES + term + automaton (unless shared) in a field and adds compiled.ramBytesUsed() on every call. NFARunAutomaton.ramBytesUsed() takes stateRegistryLock, which already guards its state map, so a live read cannot iterate dStateToOrd while another thread adds a state. 2 files, +15/-10.
// AutomatonQuery
private final long fixedRamBytesUsed; // BASE_RAM_BYTES + term + automaton (unless shared)
public long ramBytesUsed() {
  return fixedRamBytesUsed + compiled.ramBytesUsed();
}

// NFARunAutomaton
public long ramBytesUsed() {
  synchronized (stateRegistryLock) {
    return BASE_RAM_BYTES + ... + RamUsageEstimator.sizeOfMap(dStateToOrd) + ...;
  }
}
Trade-offs
- Why the lock.
RamUsageEstimator.sizeOfMapiterates theHashMap(RamUsageEstimator.java:260-278),findDStateadds to it understateRegistryLock(NFARunAutomaton.java:163-176), and the class is documented as safe for concurrent stepping (:29-31). Inside Lucene nothing reads the NFA's estimate during a search today; with a live query value the cache would, while other slices of the same query may still be stepping. The study's one-method sketch lacks this part. - Cache gap.
LRUQueryCachestill sizes a query once, at its first reference (LRUQueryCache.java:990-999): the first segment's states are counted, since they are built before the key is sized; states built later, on other segments or by later searches, are not. - Cost. A live read is O(number of DFA states) and blocks stepping on that query meanwhile; the cache does it once per admitted query.
- Javadoc.
CompiledAutomaton's "Immutable" (CompiledAutomaton.java:37) could be reworded in the same change.
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-31; the worktree was removed afterwards):
- stock: the minimal test fails with assertions on and off;
- with the fix: the minimal test passes with assertions on and off;
- the study's 2-test class (the value at least half of what
RamUsageTestermeasures after a search, and the 1 MiBLRUQueryCachebudget test) passes 2/2 with assertions on and off; - the closest suites,
TestAutomatonQuery,TestAutomatonQueryUnicode,TestLRUQueryCache,TestWildcardQuery,TestRegexpQueryand all oforg.apache.lucene.util.automaton.*: 20 classes, 312 tests, 0 failures, 5 skipped; :lucene:core:checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainpass;- with the lock-free one-method version the minimal-case query reports 273,778 bytes after the count against 205,216 measured; the lock does not change the value.
Not run: a concurrent search through a cache, a multi-segment cache test, benchmarks.
On #225 Patrick Zhai called a limit on "the number of state that NFA can cache" "a feature not implemented yet". A bound (stop caching, or drop states, past a size) caps what one query can hold whatever the accounting does.
Trade-offs
It also limits patterns whose determinization exceeds the default work limit (the limit 10.x's WildcardQuery(Term) applied up front), which main now runs as an NFA without one. A larger design change with performance trade-offs (re-stepping without cached states). Not run.
Hold the lazily built states per search or per segment instead of on the CompiledAutomaton, as LUCENE-9350 did for FuzzyQuery's automata.
Trade-offs
The query's size then stays fixed and the existing value becomes right, but every search rebuilds its states. Not run.
LRUQueryCache could refresh a query's bytes when another segment's entry for it is added, so growth after admission is charged.
Trade-offs
Closes the gap option A leaves, but touches the per-distinct-query accounting #16657 just restructured (LRUQueryCache.java:465-467, :973-999). Not run.
Services that turn user wildcard or regex text into queries and install a query cache on main should not count on maxRamBytesUsed to bound those queries until a fix ships.
A hunt unit checked that NFA and DFA execution of wildcard and regex queries agree. While measuring how the NFA's lazily built state cache grows, the finder compared each query's ramBytesUsed() with its measured heap before and after one search, saw the value never move, and confirmed it with a JUnit on the stock main jars.
The method in full126 words
Method: semi-formal (the hunt's tier for systematic checks against an independent measurement). The unit did bounded-exhaustive translation validation of NFA versus DFA execution of WildcardQuery and RegexpQuery against a reference semantics; the lazily built DFA-state cache is the only mutable part of a CompiledAutomaton.
- Signal. For
*a????to*a???????????????on a 20,000-document field,RamUsageTester.ramUsed(query)grew from a few KB to 18.6 KB-12.7 MB after one search whileramBytesUsed()stayed at 3.9-7.8 KB. - Confirmation. A 2-test JUnit on the stock main jars (the value, and an
LRUQueryCachebudget under the default caching policy) failed with assertions on and off; independent verifiers, cross-model reviews from another model family (OpenAI GPT-5.6) and an adjudication confirmed it, and a 2026-10-29 minimization cut the repro to the one test above.
No prior report found: 131 logged queries on 2026-10-26 and a second full pass on 2026-10-31 (GitHub issues, PRs and commits, the JIRA archive, four mailing lists, downstream repositories, the web, the files of all open PRs). Closest: #13715/#13741, which made the NFA's own estimate live, and #16389/#16390, the opposite error in this method.
Searches2 searches
- #13715 (open) and #13741 (merged, 10.0): a maintainer listed "
ramBytesUseddoesn't considernfaRunAutomaton" forCompiledAutomaton, in a thread aboutequals/hashCode; #13741 fixed that level with a live value.AutomatonQuery's frozen copy, staleness after a search and the cache are not mentioned. Judgement call: if you count this bug as an incomplete follow-up of them, reclassify it as known. - #16389/#16390 (fixed, 10.6.0): a double count in this method; the fix keeps the value computed once. #225: the unbounded state cache is known ("not implemented yet"), accounting is not discussed. #16031 (closed unmerged,
FuzzyQuery): argued for a stable value. #16816 (open): rewrites the constructor, keeps the value computed once. #16657: the cache sizes a query once per distinct query. - Downstream: an Elasticsearch benchmark comment (#145747) measured NFA size right after construction and called it bounded, the number that goes stale.
- Limits: GitHub search is keyword-based and does not index PR diffs or review comments; private security reports are invisible; JIRA is a static archive.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch and Solr), mailing lists, JIRA, web | 2026-10-26 | 131 logged query lines: the scripted prior-report search (51 queries), 61 GraphQL searches, 24 mailing-list and 8 JIRA queries, manual web searches, the changed files of all 413 open apache/lucene PRs | 36 hits read, none the same bug |
| the same sources | 2026-10-31 | the scripted prior-report search with the cache bypassed (45 GitHub issue/PR, 6 commit, 4 downstream, 32 mailing-list, 6 JIRA and 6 web queries; 1,837 distinct hits), 34 GraphQL phrasings, all 409 open PRs by touched file, upstream code and CHANGES | 44 items read, none the same bug; no upstream fix |
Introduced in 10.0.0 by #225 (c972c6a7754e, 2021), which ran NFAs with lazily built states while AutomatonQuery kept a value computed at construction (LUCENE-8855, 2019). The default WildcardQuery/RegexpQuery path exists on main only, since #15939 and #15961 (2026). 9.x is unaffected; not fixed upstream.
Versions tested6 rows
Root cause c972c6a7754e, apache/lucene#225, LUCENE-10010 "Introduce NFARunAutomaton to run NFA directly" (Patrick Zhai, merged 2021-12-20, first released in 10.0.0). The query's field comes from LUCENE-8855 (a76c962ee61f, 2019-06-26, 8.2.0). Built and run: the parent e79012550444 rejects an NFA in the constructor; c972c6a7754e reports 1,025 bytes before and after a count while the query retains 207,904.
Default path on main: #15939 (650684e6b440, 2026-04-12) and #15961 (86593e51b28d, 2026-04-19) removed the up-front determinization (CHANGES 11.0.0). Reverting only the determinize call #15961 removed makes the minimal repro pass on main.
Later changes that did not fix it: #13741 (10.0) made the NFA's own estimate live; #16046 (10.5.0) and #16390 (10.6.0) fixed over-counts and kept the value computed once.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off; opt-in probe fails; passes with the fix |
| 10.6.0, 10.5.2 | opt-in only | minimal test passes (default path determinized); opt-in NFA probe fails, assertions on and off |
| 10.0.0 to 10.5.1 (11 releases) | opt-in only | opt-in NFA history probe fails |
| 9.0.0, 9.12.3 | not affected | always determinized (no NFA path); reported 1,428,699 and retained 1,062,384, both unchanged after a count |
c972c6a7754e (#225) vs parent e79012550444 | boundary | #225: 1,025 reported, 207,904 retained after a count; parent: NFA rejected |
upstream main 2f424fd428da | read | blob-identical files |
Confirmed by an executed cross-model review (OpenAI GPT-5.6), an independent reproducer, a devil's-advocate verifier and an adjudication; the version-history runs, a minimization, a current-main reproducer and a tie-break re-ran it. The only dissent is procedural: a read-only review that could not run code. This doc's gradle run reproduced it and validated the fix.
Checks and verdicts325 words
Every executed check agrees.
| Check | Verdict | What it found |
|---|---|---|
| Finder (NFA vs DFA translation validation, then JUnit) | candidate | Reported vs retained for 12 pattern lengths; a 2-test JUnit fails 2/2 on main with assertions on and off and passes on 10.5.2 and 10.0.0. |
| refute review (OpenAI GPT-5.6, executed) | real (high) | Own 4-test suite fails 3/4 on main, incl. the non-leading a*b??????????; with the fix 4/4 pass and TestAutomatonQuery and TestLRUQueryCache pass. |
| Independent reproducer | real | Own 6-test class fails 5/6 on main and 2/6 on 10.5.2 and 10.0.0 through the opt-in paths; 4 keys retain 2.7 MB under 1 MiB, 0 evictions. |
| Intended lens (OpenAI GPT-5.6, read-only) | real (medium) | Root cause agrees; separate runs fail on main and through RegexpQuery(..., doDeterminization=false) on 10.5.2 and 10.0.0. |
| Intended-behaviour devil's advocate | real (high) | Probes on main, 10.5.2 and 10.0.0; no intended, documented or misuse argument survives. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's class (5/6 fail); required four corrections, applied here (affected versions, cache off by default on main, current javadoc, no wrong hits). |
| History follow-up | confirmed | 13 10.x releases, 9.0.0 and 9.12.3, the introducing commit and its parent, and a #15961 shadow revert. |
| Minimal repro | verified | The one-test class fails on 645d4fe14a20 with assertions on and off and two seeds. |
| Current-main reproducer | real | Fails on main; passes on 10.5.2 and 10.6.0; the opt-in probe fails on all three. |
| Adversary review on current main (OpenAI GPT-5.6, read-only) | not real (procedural, low) | Could not run code; agreed on the root cause and that the inputs are in contract. |
| Second adjudication | real | RamUsageTester oracle and DFA control; the cache test at 645d4fe14a20 (7.4 MB held, 37 KB accounted); the fix shadow passes. |
| This doc | real; fix validated | Gradle in a scratch worktree of 645d4fe14a20: stock fails; the fix passes the repro, the cache test and 312 tests in the closest suites. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 432 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,616 words
- Registry title
- AutomatonQuery.ramBytesUsed() is computed once at construction, so a query that runs on an NFA (WildcardQuery and RegexpQuery by default on main, opt-in NFA queries since 10.0.0) under-reports the DFA states it builds while searching, and an LRUQueryCache can hold far more heap than its RAM budget
- Area
- search / AutomatonQuery RAM accounting (NFARunAutomaton lazily built DFA states; LRUQueryCache RAM budget)
- Priority
- Low, rank 730: AutomatonQuery freezes ramBytesUsed at construction, so NFA-run wildcard and regex queries (default on main, opt-in on 10.x) under-report retained DFA states by 36x to 310x and an installed LRUQueryCache can overrun its budget, while results stay correct.
- Impact class
- silent wrong results
- Impact note
- Applications that keep an NFA-executed AutomatonQuery alive after running it, above all as an LRUQueryCache key, are hit: on main every WildcardQuery or RegexpQuery whose automaton is not deterministic (default constructors, also from the classic QueryParser) keeps reporting its construction-time size after it ran (5,674 bytes reported vs 205,216 retained after one count over 1,024 terms; 6,714 vs 2,081,152 for a longer pattern on a 20,000-document field), so an application-installed LRUQueryCache (the IndexSearcher default cache is off on main since GITHUB#14187) charges a few KB per cached key while each key keeps its DFA states (4 keys retained 2.7 to 7.4 MB under a 1 MiB budget, 0 evictions); in 10.0.0-10.6.0 only the opt-in NFA APIs reach it (an AutomatonQuery over a non-deterministic automaton, RegexpQuery(..., doDeterminization=false)), and the cache overrun there also needs the application to reuse the same query instance; search hits are always correct, the harm is heap that the cache budget does not see (an OutOfMemoryError was not executed).
- Summary
- You run a WildcardQuery or RegexpQuery whose automaton is not deterministic, for example '*a?????????' or 'a*b??????????', and expect its ramBytesUsed() to estimate the heap the query holds, which is what the Accountable javadoc says and what LRUQueryCache uses to stay within maxRamBytesUsed. On main such a query runs on an NFARunAutomaton that builds DFA states lazily during the search and keeps them on the query object, but AutomatonQuery stored ramBytesUsed() in a final field when it was constructed, so after one search the value is 36x to 310x too small (5,674 bytes reported vs 205,216 retained over 1,024 terms; 6,714 vs 2,081,152 on a 20,000-document field). An LRUQueryCache with a 1 MiB budget then keeps 4 such queries as keys that retain 2.7 to 7.4 MB while it accounts about 36 KB in total and evicts nothing; the matching documents are correct.
- Introduced
- c972c6a7754e9ff1f838ed72ff09e7def00be5f8, apache/lucene#225 'LUCENE-10010 Introduce NFARunAutomaton to run NFA directly' (zhaih, merged 2021-12-20): CompiledAutomaton began wrapping non-deterministic automata in an NFARunAutomaton that determinizes lazily and keeps its states for the life of the query, while AutomatonQuery kept the construction-time 'private final long ramBytesUsed; // cache' field added by LUCENE-8855 (a76c962ee61f, 2019-06-26, first released in 8.2.0; harmless while a CompiledAutomaton was always an immutable DFA) [read: git show of both commits; release-level boundary exec: every 9.x release tested passes, 10.0.0 fails; commit boundary exec 2026-10-31: c972c6a7754e and its parent e79012550444 were built and run; the parent rejects an NFA in the constructor (IllegalArgumentException 'Automaton must be deterministic'), c972c6a7754e reports 1,025 bytes before and after a count while the query retains 207,904]. Default-path exposure on main only: 650684e6b440 (apache/lucene#15939, RegexpQuery(Term) no longer determinizes, merged 2026-04-12) and 86593e51b28d (apache/lucene#15961, WildcardQuery(Term) no longer determinizes and NFA-backed queries get value equality, so fresh per-request queries share one cache key, merged 2026-04-19) [exec: a shadow revert of only the two removed determinize calls makes the default-path tests pass on main] (2021-12-20 (root cause, #225); 2026-04-12 and 2026-04-19 (default WildcardQuery/RegexpQuery path, #15939 and #15961))
- First affected version
- 10.0.0 [exec] through the opt-in NFA paths (an AutomatonQuery built from a non-deterministic automaton, e.g. new RegExp(s).toAutomaton(), which no longer determinizes since 10.0; RegexpQuery(..., doDeterminization=false) from #12767); the default WildcardQuery/RegexpQuery path is unreleased (main / 11.0.0); 9.12.3 is the last unaffected release [exec]
- Affected versions
- all 13 releases from 10.0.0 to 10.6.0 [exec: the opt-in NFA AutomatonQuery probe fails on each with -ea, on 10.0.0, 10.5.2 and 10.6.0 also with -da; the default WildcardQuery/RegexpQuery checks pass on 10.0.0, 10.1.0, 10.2.2, 10.3.2, 10.4.0 and 10.5.2, and the minimal default-WildcardQuery test passes on 10.0.0, 10.5.2 and 10.6.0, because those queries are determinized up front]; main ea57360912ed [exec: opt-in NFA, default WildcardQuery and default RegexpQuery fail, -ea and -da] and main 645d4fe14a20 [exec: the minimal default-WildcardQuery test and the opt-in probe fail, -ea and -da]. Not affected: 9.0.0 and 9.12.3 [exec, pass]; 8.x and earlier [read, always a DFA]. Query-cache overrun: on 10.0.0 and 10.5.2 only when the application reuses the same NFA-backed query instance (NFA-backed queries compare by identity there) [exec by the independent reproduction and the intended-behaviour check]; with fresh per-request queries only on main [exec]. Not fixed upstream: upstream main HEAD was ea57360912ed (2026-10-24) when first checked on 2026-10-26, and on 2026-10-31 upstream main 2f424fd428da has the same AutomatonQuery.java, CompiledAutomaton.java, NFARunAutomaton.java, LRUQueryCache.java, WildcardQuery.java and RegexpQuery.java blobs as 645d4fe14a20 [read]; the last commit touching AutomatonQuery.java is #16390 (2026-07-14), and no open PR changes ramBytesUsed(); branch_10x and branch_10_6 were not checked. Executed on aarch64 Linux with JDK 25 only.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: 131 logged query lines: a scripted prior-report search over apache/lucene issues, PRs and commits, the Elasticsearch, OpenSearch and Solr repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (51 queries), 61 GraphQL searches, the changed files of all 413 open apache/lucene PRs, 24 direct mailing-list and 8 direct JIRA queries, manual web searches; 36 hits read, none the same bug); not fixed: upstream main HEAD ea57360912ed still has 'private final long ramBytesUsed; // cache' (AutomatonQuery.java:57), the last commit touching AutomatonQuery.java is #16390 (2026-07-14), and no open PR changes ramBytesUsed() (#16816 rewrites the constructor, #16801 the cost estimate); closest items, not reports of this bug: #13715 (open, about equals/hashCode of NFA-backed CompiledAutomaton; a maintainer listed 'ramBytesUsed doesn't consider nfaRunAutomaton' for CompiledAutomaton and the NFA author noted that the NFA remembers every state it determinizes), #13741 (fixed that at the CompiledAutomaton level with a live value, which AutomatonQuery never re-reads), #16389/#16390 (the opposite error, a double count, fixed by recomputing the value once in the constructor; its text says ramBytesUsed() feeds LRUQueryCache eviction decisions), #16046, #225 (the NFA author called a limit on cached NFA states 'a feature not implemented yet'), #16031 (FuzzyQuery, closed unmerged, argued for a value that does not jump after the first execution); precedents for the defect class: LUCENE-9350 (#10390), LUCENE-10103 (#11141), #15097/#15124, #16405/#16406; downstream consumers of the construction-time value (elastic/elasticsearch#142150, #145747) report no growth; gaps: GitHub search is lexical and GitHub's search rate limit was reached (a scripted prior-report search needed several runs; all its queries completed in the final run), and private reports to security@lucene.apache.org are not visible
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner (two seeds); with the recommended fix it passes, and so do the study's cache test and the closest suites (20 classes, 312 tests). Release jars 10.5.2 and 10.6.0: the minimal test passes (the default path is determinized there) and the opt-in NFA probe fails with assertions on and off. History runs: the opt-in probe fails on every 10.x release from 10.0.0, and 9.0.0 and 9.12.3 pass; the introducing commitc972c6a7754eand its parent were built and run. Upstream main2f424fd428dahas blob-identical files (read, 2026-10-31).
- Finding record
lucene/core/src/java/org/apache/lucene/search/AutomatonQuery.java:57 ('private final long ramBytesUsed; // cache'), :99-104 (assigned once in the constructor), :170-173 (returned) @ ea57360912edlucene/core/src/java/org/apache/lucene/util/automaton/NFARunAutomaton.java:28-37 (class javadoc: lazily determinizes, memorizing the generated DFA states; @lucene.internal), :49-51 (dStateToOrd guarded by stateRegistryLock, dStates), :159-177 (states added), :260-268 (live ramBytesUsed incl. dStateToOrd and dStates, read without the lock) @ ea57360912edlucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:464-471 (queryRamBytesUsed = RamUsageEstimator.sizeOf(query, 32)), :988-998 (acquireQuery: a key's bytes sampled once at first reference), :62 ('remain under a given maximum size and number of bytes used') @ ea57360912edlucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-87 ('Caching is disabled by default', DEFAULT_QUERY_CACHE = null, default policy UsageTrackingQueryCachingPolicy) and lucene/CHANGES.txt:94-102, :309, :325 (GITHUB#15939, GITHUB#15961, GITHUB#14187) @ ea57360912edSECURITY.md:28, :38, :44-46, :50 @ ea57360912ed; lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:512, :579 (classic parser builds new RegexpQuery/WildcardQuery); lucene/core/src/java/org/apache/lucene/search/UsageTrackingQueryCachingPolicy.java:49-51, :124 (MultiTermQuery cached after 2 uses)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/AutomatonQuery.java:43, (at 645d4fe14a20) :50, :57, :93-105, :161-163, :170-173lucene/core/src/java/org/apache/lucene/util/automaton/CompiledAutomaton.java:36-40, (at 645d4fe14a20) :253-257, :554-561lucene/core/src/java/org/apache/lucene/util/automaton/NFARunAutomaton.java:28-37, (at 645d4fe14a20) :49-51, :159-177, :260-268, :270-281, :309-332lucene/core/src/java/org/apache/lucene/search/WildcardQuery.java:49-60, (at 645d4fe14a20) :67-101; RegexpQuery.java:54-56, :90-101; lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:512, :579lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:465-471, (at 645d4fe14a20) :609-610, :990-999, :1110-1121; lucene/core/src/java/org/apache/lucene/util/RamUsageEstimator.java:378-386; lucene/core/src/java/org/apache/lucene/search/UsageTrackingQueryCachingPolicy.java:45-54; lucene/core/src/java/org/apache/lucene/search/AbstractMultiTermQueryConstantScoreWrapper.java:52-56, :122-125
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-84; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:251-253; lucene/MIGRATE.md:227-236, :922-926; lucene/CHANGES.txt:343 (#14187)a Lucene clone releases/lucene/10.6.0: lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:95-100; RegexpQuery.java:158-190 (doDeterminization) (read)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/util/Accountable.java:30, (at 645d4fe14a20) :34-40; lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:60-62, :609-610, :973-999; lucene/core/src/java/org/apache/lucene/search/WildcardQuery.java:31-32lucene/core/src/test/org/apache/lucene/search/TestAutomatonQuery.java:289-303, (at 645d4fe14a20) :305-320; lucene/core/src/test/org/apache/lucene/util/automaton/TestNFARunAutomaton.java:46-53
- Suggested fix
lucene/core/src/java/org/apache/lucene/util/RamUsageEstimator.java:260-278; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/util/automaton/NFARunAutomaton.java:29-31, :163-176; lucene/core/src/java/org/apache/lucene/search/LRUQueryCache.java:465-467, :973-999; lucene/MIGRATE.md:337-354
- History
lucene/CHANGES.txt:94-103 (at 645d4fe14a20)
- TestAutomatonQueryRamBytesUsedAfterSearch.java (one test):
repro/LFV-192/src/org/apache/lucene/search/TestAutomatonQueryRamBytesUsedAfterSearch.java(59 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro and the recorded verification runs (reported and retained sizes; the cache numbers).
assets/LFV-192/bug.png(432 KB)