Phrase matching adds each query term's offset to a document position in a Java int. Past 2,147,483,647 the sum wraps to a negative number: the exact matcher then stops making progress and spins forever inside one document, and the sloppy matcher sees a negative distance and accepts a document it should reject.
- Every indexed term has a position: in
x a b, x is at 0, a at 1 and b at 2. Positions stop atIndexWriter.MAX_POSITION= 2,147,483,519 (2^31 - 129). - A
PhraseQuerygives each of its terms a position inside the phrase, its offset:"a b"is a@0 b@1.PhraseQuery.Builder#add(term, position)lets you choose them, with gaps; it checks only that they are>= 0and in order. - To match, Lucene expects each term at (start of the phrase in the document) + (its offset). Slop 0 needs exactly that; slop n allows n moves. Lucene computes these sums in
int, which wraps to a negative number past 2,147,483,647.
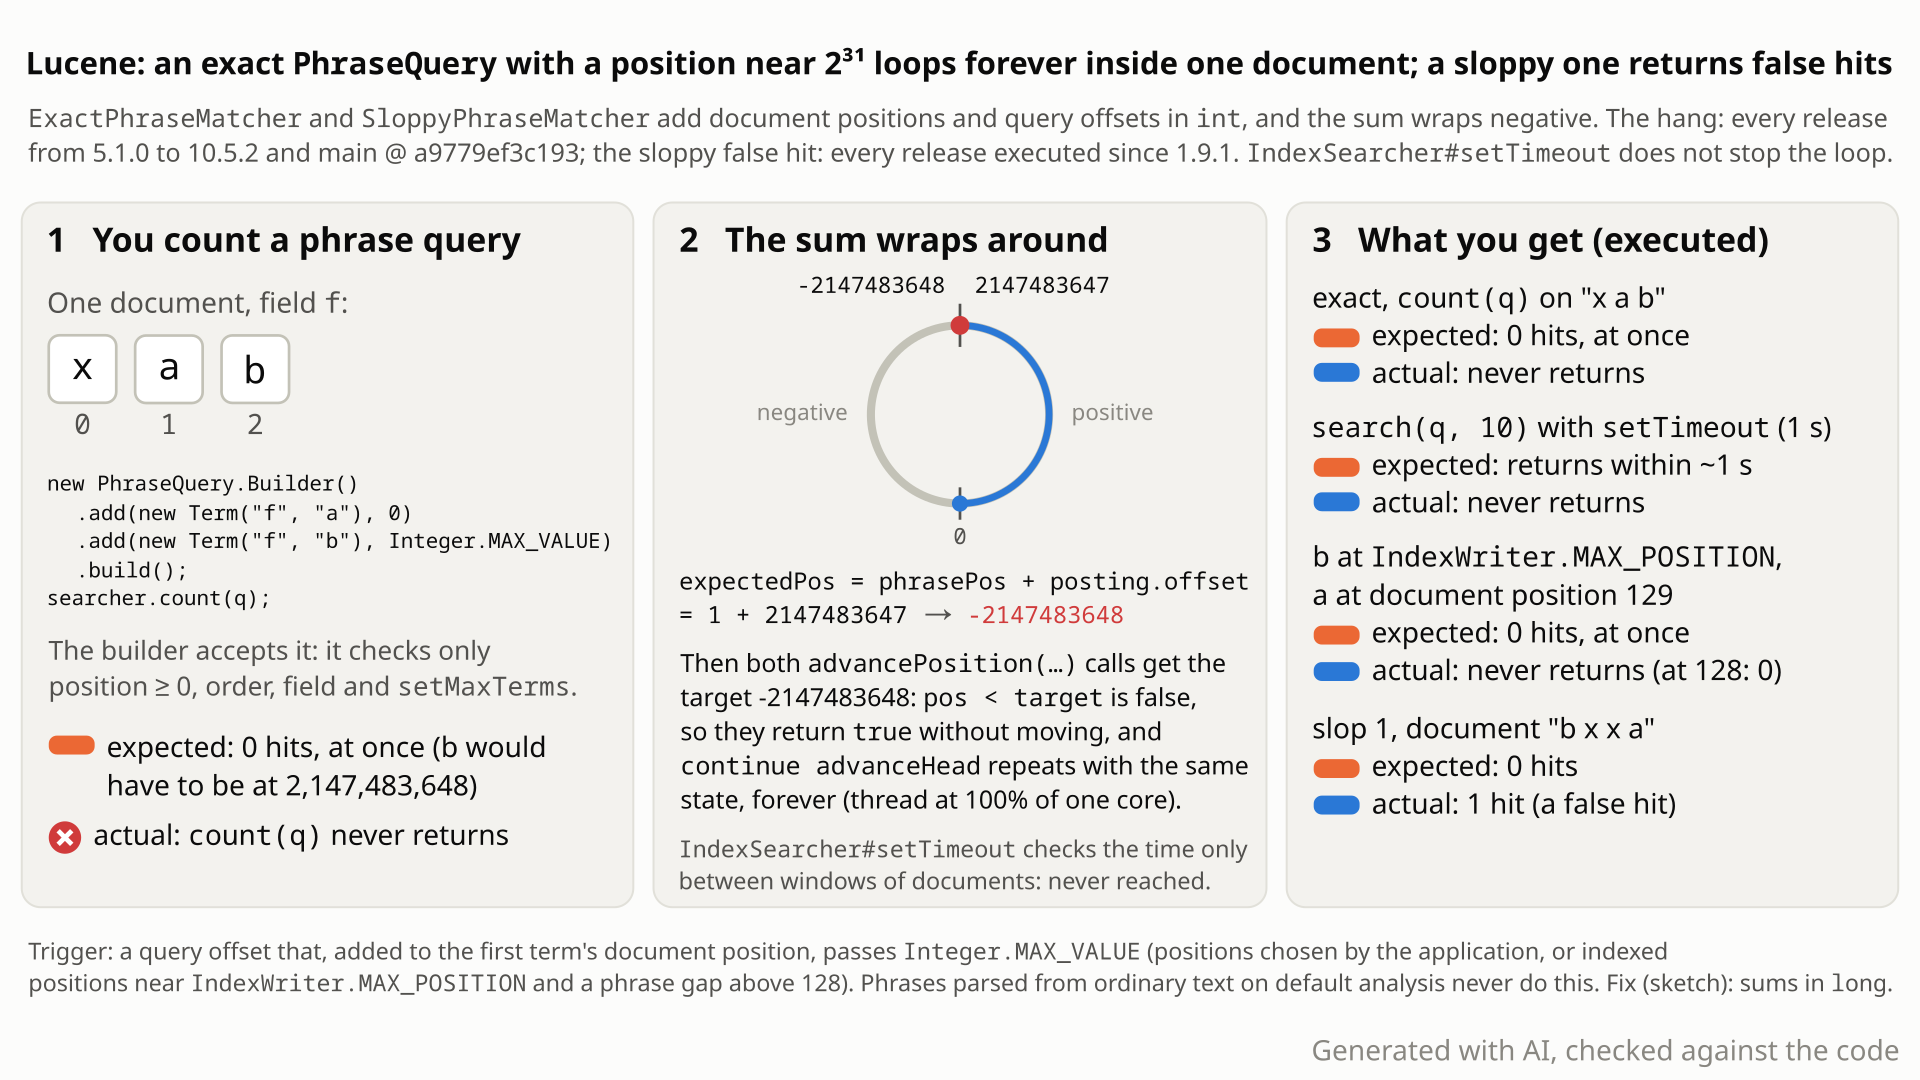
- Index one document,
x a b(x at position 0, a at 1, b at 2). Build aPhraseQuerywith a at position 0 and b at 2,147,483,647 (Integer.MAX_VALUE); the builder accepts it. - You expect
count= 0 at once: no document can have b 2,147,483,647 positions after a (indexed positions stop at 2,147,483,519). - Instead the exact matcher computes a's position plus b's offset in
int: 1 + 2,147,483,647 wraps to -2,147,483,648. Both of its "advance to" steps then do nothing, so the loop repeats the same state forever: one thread at 100% CPU, and a 1 sIndexSearcher#setTimeoutdoes not stop it. - With slop 1 the same query matches
b x x a, where b is 3 positions before a: the span 3 - (-2,147,483,647) wraps to -2,147,483,646, which passes "span <= slop". Count 1 instead of 0. - Not only absurd offsets: giving b the offset 2,147,483,519 (
IndexWriter.MAX_POSITION) is meaningful, it matches a document with b at that position, yet it hangs once a is at position 129; a phrase gap of 300 hangs on a document whose positions are near 2^31.
Nothing to opt into (default codec, plain IndexSearchers); one document is enough. It needs a phrase whose offset plus the first term's document position passes 2^31: positions an application sets itself (a sentinel such as Integer.MAX_VALUE, client-chosen positions) or indexed positions near 2^31 with a gap above 128. Phrases parsed from ordinary text on default analysis never do: rare.
Mechanism, terms and numbers816 words
PhraseQuery.Builder#add(Term, int) accepts any query position that is >= 0 and in order, and MultiPhraseQuery.Builder#add(Term[], int) any int. The phrase matchers add a document position and such a query offset in int. When the sum passes Integer.MAX_VALUE it wraps negative: with slop 0, ExactPhraseMatcher#nextMatch stops making progress and loops forever inside one document (ExactPhraseMatcher.java:159-171 on main a9779ef3c193), and IndexSearcher#setTimeout cannot end it because the timeout is checked between windows of documents; with slop 1 or more, SloppyPhraseMatcher gets a negative span that passes matchLength <= slop, so a document about 2^31 positions away matches. The smallest trigger is a@0 b@Integer.MAX_VALUE on the one-document index x a b; b@IndexWriter.MAX_POSITION hangs once a is at position 129, and a gap of 300 hangs against legal indexed positions near 2^31. No codec or searcher option is needed (the runs used the default codec and plain IndexSearchers; the overflowing sums are in the matchers); one document is enough; phrases parsed from ordinary text on default analysis never do this. The hang came with LUCENE-6260 in 5.1.0 (2015); the sloppy false hit reproduces on every executed release from 1.9.1. Computing the two sums in long (two small hunks) fixes every PhraseQuery case that was run except slop Integer.MAX_VALUE, where the clamped span still matches. Executed with the fix, an exact MultiPhraseQuery whose lowest position is negative still hangs when the lead's document position minus that position passes Integer.MAX_VALUE (for example a@-200 b@0 with a at 2,147,483,448), and MultiPhraseQuery positions more than 2^31 apart still give false hits; rebasing MultiPhraseQuery positions to 0 would cover both (not built).
- Query offset: the position a term has inside the phrase.
PhraseQuery.Builder#add(Term, int)checks onlyposition >= 0, the order, the field andsetMaxTerms(PhraseQuery.java:126-155);MultiPhraseQuery.Builder#add(Term[], int)checks only the field (MultiPhraseQuery.java:125-140), and negative MultiPhraseQuery positions are a tested feature. - Lead: the exact matcher walks the positions of the first query term (offset 0 after
PhraseQuery#rewrite) and checks that every other term sits atlead position + its offset. IndexWriter.MAX_POSITION=Integer.MAX_VALUE - 128(IndexWriter.java:211): the largest indexed position. It bounds documents only; its 128 of headroom does not cover adding a query offset.
ExactPhraseMatcher#nextMatch (ExactPhraseMatcher.java:149-180), for a@0 b@2147483647 on x a b (a at 1):
phrasePos = lead.pos - lead.offset= 1 (:159);expectedPos = phrasePos + posting.offset= 1 + 2147483647, which wraps to -2147483648 (:162).advancePosition(b, -2147483648)(:165) moves to the first position at or after the target; b's current position, -1, is not below it, so it returns true without moving (:135-146).- b is not at the expected position, so the lead is re-targeted to
b.pos - b.offset + lead.offset= -1 - 2147483647, which also wraps to -2147483648 (:170); the lead does not move either. continue advanceHead(:171) starts again from the same state. Nothing ever changes, so this is a true infinite loop, and it makes no postings or reader calls.
Why a timeout cannot help. With IndexSearcher#setTimeout, IndexSearcher wraps the bulk scorer in TimeLimitingBulkScorer (IndexSearcher.java:846-848), which checks the timeout only before each window of documents (TimeLimitingBulkScorer.java:72-83). The loop never leaves one document's TwoPhaseIterator#matches, although QueryTimeout's javadoc says that with setTimeout "bulk scoring will be time-bound" (QueryTimeout.java:20-23).
PhrasePositions#nextPosition stores position = postings.nextPosition() - offset (PhrasePositions.java:55); SloppyPhraseMatcher#nextMatch measures matchLength = end - pp.position (SloppyPhraseMatcher.java:212, 226, 228) and matches when matchLength <= slop (:236). For a@0 b@2147483647 slop 1 on b x x a: position(a) = 3, position(b) = 0 - 2147483647, end = 3, so the span is 2147483650, which wraps to -2147483646 and passes <= 1. MultiPhraseQuery a@Integer.MIN_VALUE b@0 slop 1 on a x x b gives the same false hit through PhrasePositions.java:55.
The lead's document position plus a query offset must pass 2,147,483,647:
- offset
Integer.MAX_VALUEwith the lead at position 1 or later (at 0 the sum is exactlyInteger.MAX_VALUEand the result is correct); - offset
MAX_POSITIONwith the lead at position 129 or later (128 gives the correct 0); - a small gap, such as the 300 that the classic
QueryParserbuilds from a quoted phrase with 299 stopwords between two words, against a legal indexed position within 300 of 2^31 (for example from a huge position-increment gap).
MultiPhraseQuery with slop 0 reaches the same exact-matcher loop. Its positions are not rebased and may be negative, so it also triggers when lead.pos - lead.offset itself passes Integer.MAX_VALUE (ExactPhraseMatcher.java:159): the lead's document position minus a negative lowest query position, for example a@-200 b@0 with a at 2,147,483,448 (executed by the fact check; still hangs with the fix below).
Exposure and likelihood277 words
- Who is hit. Applications that run a
PhraseQueryorMultiPhraseQuerywhose query offset, added to the document position of the phrase's first term, passes 2^31 - 1 (for aMultiPhraseQuerywith a negative lowest position, also that document position minus the negative position): an application that maps its own values (not token positions) to phrase positions, or uses a sentinel such asInteger.MAX_VALUEfor "far away"; an application that exposes explicit phrase positions to its clients without a bound; an index whose analysis puts positions within a few hundred of 2^31 (a hugegetPositionIncrementGap) together with a phrase gap above 128, which the classicQueryParserbuilds from a quoted phrase with that many stopwords. - Default vs opt-in. Nothing to opt into. The runs used the default codec, plain
IndexSearchers, the default analyzer and similarity; the overflowing sums are in the matchers, not behind a codec or searcher option (code reading); other codecs and searcher configurations were not run. - Scale. One document that contains the phrase's terms, with the first term at position 1 or later.
- Effect, slop 0. The search thread spins at 100% CPU forever on the first such document (still spinning after 60 s in an independent run);
IndexSearcher#setTimeoutdoes not end it, so a request handler that relies on the timeout loses the thread. Repeated requests could use up a search thread pool (inferred, not executed). ThatThread#interruptandExitableDirectoryReaderwould not stop it either is code reading only. - Effect, slop > 0. Silent false hits (count 1 instead of 0), no exception.
- How likely: rare. Phrases that the query parsers build from ordinary text on default analysis never have such offsets.
The test shows that an exact PhraseQuery with a@0 and b@Integer.MAX_VALUE, counted on the one-document index "x a b", never returns: ExactPhraseMatcher.nextMatch computes position 1 + Integer.MAX_VALUE in int, the sum wraps, and the matcher loops forever inside the document.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import com.carrotsearch.randomizedtesting.annotations.Timeout;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestPhraseQueryPositionOverflow extends LuceneTestCase {

  @Timeout(millis = 5000)
  public void testExactPhraseWithHugePositionTerminates() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new TextField("f", "x a b", Field.Store.NO));
      w.addDocument(doc);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        PhraseQuery q =
            new PhraseQuery.Builder()
                .add(new Term("f", "a"), 0)
                .add(new Term("f", "b"), Integer.MAX_VALUE)
                .build();
        // expected: count 0 within the timeout; actual: a's position 1 + Integer.MAX_VALUE overflows and count() never returns
        assertEquals(0, new IndexSearcher(reader).count(q));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-196/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestPhraseQueryPositionOverflow
- Expected vs actual
- Expected:
count(q) == 0, returned within the 5 s@Timeout; actual:Test timeout exceeded (>= 5000 msec), and the leaked test thread is still RUNNABLE atExactPhraseMatcher.nextMatch(ExactPhraseMatcher.java:171).
More files, environment, full output110 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 2 failed
    => java.lang.Exception: Test timeout exceeded (>= 5000 msec).
  JUnit Vintage:TestPhraseQueryPositionOverflow
    ClassSource [className = 'org.apache.lucene.search.TestPhraseQueryPositionOverflow', filePosition = null]
    => org.opentest4j.MultipleFailuresError: Multiple Failures (3 failures)
	java.lang.AssertionError: The test or suite printed 16388 bytes to stdout and stderr, even though the limit was set to 8192 bytes. Increase the limit with @Limit, ignore it completely with @SuppressSysoutChecks or run with -Dtests.verbose=true
	com.carrotsearch.randomizedtesting.ThreadLeakError: 1 thread leaked from SUITE scope at org.apache.lucene.search.TestPhraseQueryPositionOverflow:
   1) Thread[id=41, name=TEST-TestPhraseQueryPositionOverflow.testExactPhraseWithHugePositionTerminates-seed#[DEADBEEF]-worker, state=RUNNABLE, group=TGRP-TestPhraseQueryPositionOverflow]
        at org.apache.lucene.search.ExactPhraseMatcher.nextMatch(ExactPhraseMatcher.java:171)
        at org.apache.lucene.search.PhraseScorer$1.matches(PhraseScorer.java:68)
        at org.apache.lucene.search.Weight$DefaultBulkScorer.scoreTwoPhaseIterator(Weight.java:311)
        at org.apache.lucene.search.Weight$DefaultBulkScorer.score(Weight.java:282)
        at org.apache.lucene.search.LRUQueryCache.cacheIntoBitSet(LRUQueryCache.java:617)
        at org.apache.lucene.search.LRUQueryCache.cacheImpl(LRUQueryCache.java:588)
at org.apache.lucene.search.LRUQueryCache.tryPopulateCache(LRUQueryCache.java:609)- The builder accepts these positions: it checks only
>= 0and order, and no javadoc bounds them. - The offsets can be meaningful: a@0 b@
MAX_POSITIONmatches a document with b there, yet hangs once a is at 129. - Slop is "the maximum edit distance for a document to match"; this one is 2^31 away. Lucene fixed the same overflow in
SpanNotQuery.
The full argument308 words
- Legal input.
PhraseQuery.Builder#add(Term, int): the position "must be greater than or equal to that of the previously added term", and the code checksposition < 0, the order, the field andsetMaxTerms(PhraseQuery.java:119-155).MultiPhraseQuery.Builder#add(Term[], int)checks only the field (MultiPhraseQuery.java:121-140).IndexWriter.MAX_POSITIONis the "Maximum value of the token position in an indexed field" (IndexWriter.java:210-211). No javadoc,MIGRATE.md, CHANGES entry or package doc bounds query positions. #15332 addedsetMaxTerms, whose javadoc says "This helps prevent excessive memory usage for very long phrases" (PhraseQuery.java:99-105); no position bound was discussed. The builders' lack of a bound is not an explicit promise about extreme positions, but nothing tells a caller to avoid them. - Meaningful offsets. The control test (a@0 b@
MAX_POSITIONon a document with b atMAX_POSITION) matches, count 1; the same query hangs on a document with a at 129. A gap of only 300 hangs against legal indexed positions near 2^31, so the trigger is not limited to absurd query values. - The slop contract. "The slop defines the maximum edit distance for a document to match" (
PhraseQuery.java:268-283).TestPhraseQuery.java:339builds a phrase with slopInteger.MAX_VALUE, so extreme values are expected to work. - Termination. A query its builder accepts that spins forever inside one document is not plausibly intended; no test, comment, PR or list thread treats such offsets as unsupported.
- Upstream treats this class as a bug. LUCENE-8034 (#9082) fixed
SpanNotQuery's overflow nearInteger.MAX_VALUEin 7.2.0 with a test (TestBasics#testSpanNotNoOverflowOnLargeSpans);ExtendedIntervalIteratorguardsend += afterwith an// overflowcheck (LUCENE-8612);IndexingChainrejects "position overflowed Integer.MAX_VALUE" at index time. - History. LUCENE-6260 (#7322), which wrote the overflowing exact-matcher lines in 2015, discusses only performance. The scorer it replaced computed document position minus query position, which cannot overflow, and returned the correct 0.
The devil's-advocate check146 words
The strongest case for "works as designed": a phrase offset near 2^31 is garbage in, garbage out; Lucene's SECURITY.md (lines 28 and 38) makes the application responsible for bounding input passed straight to Lucene APIs; the matchers are @lucene.internal; and the query timeout is cooperative by design, checked between documents.
Why it fails: the public builders accept the offsets and some are meaningful (MAX_POSITION matches a legal document); the small-gap variant needs no large query offset at all; the matchers are reached through the public PhraseQuery and MultiPhraseQuery; and a wrong hit or a query that never terminates on accepted input is a correctness bug whatever the threat model says (the threat model decides only the security label). The timeout point is right, so the timeout bypass is a consequence of the in-document loop, not a second defect. Verdict: not intended, a defect.
Recommended long arithmetic at the two overflowing sums
Compute the two sums in long: ExactPhraseMatcher stops the document once phrasePos + offset passes Integer.MAX_VALUE; SloppyPhraseMatcher clamps end - pp.position. Two files, +15/-4; the test passes 7 of 7, the whole lucene/core module passes. Still open (executed): an exact MultiPhraseQuery with a negative lowest position near 2^31 hangs; MultiPhraseQuery spreads above 2^31 and slop Integer.MAX_VALUE give false hits.
// ExactPhraseMatcher#nextMatch
final long expected = (long) phrasePos + posting.offset;
if (expected > Integer.MAX_VALUE) {
  // no document position is that large: no match at this or any later lead position
  break advanceHead;
}
final int expectedPos = (int) expected;

// SloppyPhraseMatcher: matchLength = span(pp) instead of end - pp.position
private int span(PhrasePositions pp) {
  long d = (long) end - pp.position;
  return d > Integer.MAX_VALUE ? Integer.MAX_VALUE : (int) d;
}
All options and trade-offs4 options · 1,001 words
One fix was built and validated; three alternatives were not built.
Two hunks, 2 files, +15/-4 (the finder's fix). Exact: compute phrasePos + posting.offset in long and end the search in this document when it passes Integer.MAX_VALUE; later lead positions only grow, so no later match is possible. For PhraseQuery every offset is >= 0 and the lead has the smallest (the postings are sorted by position, PhraseQuery.java:381-383, 543-545), so lead.pos - lead.offset and the lead re-target stay inside int (code reading; PhraseQuery#rewrite also rebases the first offset to 0). Sloppy: a span(pp) helper replaces the three end - pp.position; a clamped span is larger than any slop below Integer.MAX_VALUE.
// ExactPhraseMatcher#nextMatch
final long expected = (long) phrasePos + posting.offset;
if (expected > Integer.MAX_VALUE) {
  // no document position is that large: no match at this or any later lead position
  break advanceHead;
}
final int expectedPos = (int) expected;

// SloppyPhraseMatcher: matchLength = span(pp) instead of end - pp.position
private int span(PhrasePositions pp) {
  long d = (long) end - pp.position;
  return d > Integer.MAX_VALUE ? Integer.MAX_VALUE : (int) d;
}
Trade-offs
- One
longadd and compare per term per lead position in the exact matcher's inner loop, a hot path. Lucene's SECURITY.md asks that robustness fixes not slow down hot paths (line 46). Not benchmarked. - Does not cover (executed by the fact check): an exact
MultiPhraseQuerywith a negative lowest position whose lead document position minus that position passesInteger.MAX_VALUE, becausephrasePos = lead.pos - lead.offset(ExactPhraseMatcher.java:159) is not guarded: a@-200 b@0 with a at 2,147,483,448 still spins (option B covers it);MultiPhraseQuerypositions more than 2^31 apart (option B); slopInteger.MAX_VALUE, where a@0 b@Integer.MAX_VALUEcounts 1 onb x x awith the fix (comparing the span with the slop inlongwould cover it; not built). - Not executed: the other
intposition expressions,pp.position + pp.offsetinSloppyPhraseMatcher.java:244, 259, 269, 615(the Matches API and repeated terms) andPostingsAndFreq#compareTo(PhraseQuery.java:381-383, reached by option B's case). - The open PR #16913 changes
SloppyPhraseMatcherandPhrasePositions(match offsets of repeated terms) without touching this arithmetic; a fix PR would need a rebase if it lands first. - A CHANGES "Bug Fixes" line would be usual; none is drafted.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle: the new test fails 6 of 7 on the stock tree and passes 7 of 7 with the fix, with assertions on and off. - 20 suites (the 8
*Phrase*suites oforg.apache.lucene.search,TestMatchesIterator, the two search-equivalence suites, the five explanation suites,TestPositionIncrement,TestTimeLimitingBulkScorer, the phrase test ofTestBooleanSimilarityand the new test): 365 tests, 0 failures, assertions on and off. - The whole
lucene/coremodule: 749 suites, 8,896 tests, 0 failures, assertions on and off.:lucene:core:check -x test(google-java-format, ecjLint, forbiddenApis) passes. - Earlier, by the hunt: the finder's 5 of 5, the independent reproducer's 12 of 13 (the one left is the withdrawn
toStringcase), a cross-model reviewer's 3 of 3, the QueryParser document-side test, and 88 + 50 focused upstream phrase tests. - The fact check's edge probes: a repeated term a@0 a@
Integer.MAX_VALUE(exact onx a a, slop 1 ona x x a) and three terms a@0 b@1 c@Integer.MAX_VALUEonx a b creturn 0 with the fix (stock: the two exact cases hang). - Not run: a benchmark, nightly tests.
Two MultiPhraseQuery cases stay open with the fix above. (1) Executed by the fact check: an exact MultiPhraseQuery whose lowest position is negative hangs when the lead's document position minus that position passes Integer.MAX_VALUE (ExactPhraseMatcher.java:159), because MultiPhraseQuery does not rebase its positions (MultiPhraseQuery.java:182-195): a@-200 b@0 with a at 2,147,483,448 and a@-2147483000 b@0 with a at 1000 do not return within 5 s, stock and with the fix. (2) An executed probe, stock and with the fix above (same results): an exact MultiPhraseQuery a@Integer.MIN_VALUE b@Integer.MAX_VALUE counts 1 on b a, a@Integer.MAX_VALUE b@Integer.MIN_VALUE counts 1 on a b, and the first with slop 1 counts 1 on b a; expected 0 each (the first query correctly gives 0 on a b). MAX_VALUE - MIN_VALUE = 2^32 - 1 is -1 in int, so the matcher looks for b one position before a; PhraseQuery.PostingsAndFreq#compareTo also subtracts positions in int (PhraseQuery.java:381-383). Options: rebase MultiPhraseQuery positions to start at 0, as PhraseQuery#rewrite does, and reject positions whose spread does not fit in an int; with the fix above this covers both cases, since every offset is then >= 0 and the lead's is 0 (code reading). Or carry PhrasePositions.position and the exact matcher's phrasePos and re-target in long, with Integer.compare in compareTo.
Trade-offs
Case (2) needs explicit positions more than 2^31 apart; case (1) needs only a negative lowest position and indexed positions near 2^31 (a spread of 200 is enough). No query parser was surveyed for either shape. Rejecting spreads is an API change; long positions touch more of the sloppy matcher.
Reject PhraseQuery offsets above IndexWriter.MAX_POSITION and MultiPhraseQuery spreads that do not fit in an int.
Trade-offs
Removes the absurd shapes and the MultiPhraseQuery spread case, but not a MultiPhraseQuery with a negative lowest position and a small spread (a@-200 b@0 passes a spread bound and still hangs near 2^31), nor the hang from a small gap (300) against legal indexed positions near 2^31, so the matcher arithmetic must still be fixed. It also turns accepted queries into exceptions. Not built.
Make TwoPhaseIterator#matches of phrase scorers consult the QueryTimeout.
Trade-offs
Turns the hang into a timeout but keeps the wrong loop and the false hits, and adds work to every match call. Not a substitute. Not built.
A service that lets its clients set explicit phrase positions should bound them until a fix ships: one such request can pin a search thread that the query timeout cannot stop.
Found by hand while writing a model of the phrase matchers: the documented limits (query positions >= 0, indexed positions up to MAX_POSITION) were written down as preconditions, and the matchers' int sums were checked against them. A public-API JUnit then showed the hang and the false hits.
The method in full114 words
Method: non-formal (the hunt's hunt unit on phrase matching, 2026-10-26, main ea57360912ed).
- Signal. While writing the model-to-line map of a shared positional harness for phrase and span queries, the finder recorded the documented limits as preconditions and checked the
intexpressions document position +/- query offset in both matchers against them by hand. No solver was needed:phrasePos + offsetwith an offset up toInteger.MAX_VALUEoverflows. The harness's exhaustive scope (offsets up to 9, positions up to 8) cannot reach these values, which is why the tier stays non-formal. - Witness. A 5-test public-API JUnit on the stock jars: 5 of 5 fail with assertions on and off, on main, 10.5.2 and 9.12.3.
No prior report found: 230 queries on 2026-10-26 over GitHub issues, PRs and commits, downstream repositories, the mailing lists, the JIRA archive and the web, plus the changed files of all 413 open PRs; re-checked 2026-10-28. Related precedents in other code: LUCENE-8034 (SpanNotQuery overflow) and the guard in Intervals.extend.
Searches6 searches
Related, not reports of this bug: #9082 / LUCENE-8034 (SpanNotQuery overflow near Integer.MAX_VALUE, fixed in 7.2.0; its downstream report elastic/elasticsearch#27134 first drew a maintainer's "It's not really a bug, just an overflow if you use a very high dist value. Don't do that", and Lucene fixed it anyway); #9658 / LUCENE-8612 (the overflow guard in Intervals.extend); #4288 / LUCENE-3215 (negative sloppy positions from query holes, not an overflow); #7442 / LUCENE-6382 (MAX_POSITION, indexed positions only); #7317 / LUCENE-6255 (the builder's checks); #15332 (setMaxTerms); #10171 / LUCENE-9130 (slop confusion, Not A Bug); #12211 (a different DrillSideways bug). Open PRs touching the files (#14716, #15423, #16851, and #16913 opened 2026-10-26) do not change the arithmetic. Gaps: private security reports cannot be searched; chat channels and ports other than Lucene.NET were not searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and downstream repositories | 2026-10-26 | 100 GraphQL searches (class names, identifiers, symptoms, old JIRA keys) and a scripted prior-report search (20 issue/PR, 3 commit, 2 downstream queries); git log -S on the three expressions | no report; the precedents and related items above |
| Open PRs | 2026-10-26 | the changed files of all 413 open apache/lucene PRs, patches grepped for the expressions | #14716, #15423, #16851 touch the files, not the arithmetic |
| Mailing lists | 2026-10-26 | 52 tool queries over dev@, java-user@, issues@ and commits@ | no report |
| JIRA archive | 2026-10-26 | 13 tool queries, 14 LUCENE issues read with comments, 6 SOLR JQL queries | no report |
| Web | 2026-10-26 | 12 general web queries | no report |
| GitHub (re-check) | 2026-10-28 | repo:apache/lucene ExactPhraseMatcher, phrase overflow, PhraseQuery updated:>=2026-10-26, MultiPhraseQuery updated:>=2026-10-26; the latest commits on the three matcher files | only #16913 is new (match offsets of repeated terms, not this bug); no new commit on the matcher files |
The hang came with LUCENE-6260 (5e9b2465991, 2015, first released in 5.1.0): its parent returns the correct 0 and the commit spins, and every executed release from 5.1.0 to 10.5.2 and main hangs. The sloppy false hit is older: it reproduces on every executed release from 1.9.1.
Versions tested8 rows
Introduced by 5e9b2465991 on branch_5x (trunk twin fd8c4b31201), "LUCENE-6260: Simplify ExactPhraseScorer." (jpountz, 2015-02-20; JIRA patch era, migrated as #7322). It replaced the chunked exact-phrase intersection of LUCENE-2410, which computed document position minus query position, with the lead/advancePosition loop and wrote all three overflowing expressions; the issue discusses performance only. LUCENE-8249 (7.4.0) moved the loop into ExactPhraseMatcher#nextMatch; #15861 (2026-04) changed only frequency loading.
The sloppy span arithmetic dates from the 2001 initial import; query offsets large enough to overflow it arrived with explicit phrase positions (fd4cd859c57, 2004, first released in 1.4.2). In 1.9.1 to 2.4.1 the false hit is visible only at scorer level (a HitCollector sees it with score NaN). IndexSearcher#setTimeout (9.3.0 on) did not stop the hang in any executed release that has it. 97 of the 106 releases from 5.1.0 to 10.5.2 are tagged in the history clone and all contain the expressions; the overflowing lines are on main, branch_10x, branch_10_6 and branch_9_12.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | the brief's test 6 of 7 fail (gradle and the standalone runner, assertions on and off) |
| 10.5.2 | affected | the brief's test 6 of 7; the finder's 5 of 5; the independent 7 of 13 |
| 9.0.0, 9.3.0, 9.12.3, 10.0.0 | affected | three exact checks hang, two sloppy checks count 1; on 9.3.0 and 9.12.3 the 1 s timeout does not stop it |
| 5.1.0, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4 | affected | three exact checks hang, two sloppy checks count 1 |
5e9b2465991 (LUCENE-6260) | commit isolation | hangs (source build of the commit) |
41206ce9e96 (its parent) | commit isolation | no hang, exact count 0; sloppy false hit |
| 1.9.1 to 5.0.0 (10 releases) | sloppy only | no hang; the sloppy false hit (scorer level only in 1.9.1 to 2.4.1) |
| main + fix | not affected | the brief's test 7 of 7; the whole lucene/core module, 8,896 tests, 0 failures (assertions on and off) |
An independent reproducer, an intended-behaviour devil's advocate, two executed reviews by another model family (OpenAI GPT-5.6) and an adjudication agree: real, high confidence, not intended. The brief re-ran it on main a9779ef3c193 and 10.5.2 and validated the fix with gradle.
Checks and verdicts327 words
The cross-model reviews ran Java.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | 5-test public-API JUnit: 5 of 5 fail on main (-ea, -da), 10.5.2 and 9.12.3; with the fix 5 of 5 pass and 88 upstream phrase tests pass. |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6, executed: its own test reproduced the hang (lead at position 1) and the sloppy false hit with assertions on and off; root cause agreed; the fix passed its checks and 35 core phrase tests. |
| Independent reproducer | real | 13-test JUnit outside org.apache.lucene: 7 of 13 fail on main (-ea, -da), 10.5.2, 9.12.3; 6 controls pass; boundary 128/129; still spinning after 60 s; MultiPhraseQuery exact hang; fix 12 of 13. |
| Cross-model review, works-as-designed lens | real, high | OpenAI GPT-5.6, executed: its own test 2 of 3 fail, the positive control a@0 b@MAX_POSITION matches, 3 of 3 with the fix; intended argument weak. |
| Intended-behaviour devil's advocate | real | No documentation bounds query positions; the document-side trigger through the classic QueryParser hangs on main, 10.5.2 and 9.12.3 and passes with the fix. |
| adjudication | confirmed, high | Re-ran the independent JUnit on main with assertions on and off (7 of 13 fail, controls pass) and traced the loop by hand. |
| main refresh | still reproduces | The finder's test 5 of 5 fail on a9779ef3c193, same messages. |
| brief re-runs | reproduced; fix validated | New 7-test JUnit through gradle and the standalone runner, stock and fixed, main and 10.5.2; the whole lucene/core module with the fix; the MultiPhraseQuery spread probe. |
| fact check of the brief | reproduced; fix coverage narrowed | Re-ran the repro through gradle (three seeds, assertions on and off) and on 10.5.2, and the fix (7 of 7); its own probes found the three edge cases the fix leaves open (an exact MultiPhraseQuery with a negative lowest position near 2^31, MultiPhraseQuery spreads above 2^31, slop Integer.MAX_VALUE). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 499 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,724 words
- Registry title
- The phrase matchers add a document position and a query position offset in int: with an offset near 2^31 an exact PhraseQuery or MultiPhraseQuery loops forever inside one document (IndexSearcher#setTimeout does not stop it) and a sloppy one returns false hits
- Area
- search / phrase matching (ExactPhraseMatcher, SloppyPhraseMatcher and PhrasePositions position arithmetic; PhraseQuery.Builder and MultiPhraseQuery.Builder accept the positions)
- Priority
- Low, rank 520: A phrase position offset near 2^31 makes the exact phrase matcher loop forever where timeouts cannot stop it and the sloppy one return false hits, severe but it needs Integer.MAX-scale query or indexed positions.
- Impact class
- hang
- Impact note
- Hits any index, codec and searcher configuration (nothing to opt into) when a PhraseQuery or MultiPhraseQuery has a position offset that, added to the document position of the phrase's first term, passes Integer.MAX_VALUE (an offset of Integer.MAX_VALUE with that term at document position 1 or later, an offset of IndexWriter.MAX_POSITION with it at 129 or later, or a phrase gap above 128 against indexed positions within a few hundred of 2^31): with slop 0 the search thread then spins at 100% CPU forever on the first such document and IndexSearcher#setTimeout does not stop it, and with slop 1 or more the query returns false hits; one document is enough (no scale needed), but phrases that the query parsers build from ordinary text on indexes with default analysis never have such offsets.
- Summary
- You build a PhraseQuery with term a at position 0 and term b at position Integer.MAX_VALUE (the builder accepts it, because it only checks that positions are >= 0 and in order) and count it on a one-document index whose text is 'x a b'. You expect 0 hits, because no indexed position can be that far from a. Instead the exact matcher adds a's document position 1 and b's offset Integer.MAX_VALUE in int, the sum wraps to a negative number, both of its advance steps then leave its state unchanged, and IndexSearcher#count never returns, even with a 1 s IndexSearcher#setTimeout; with slop 1 the same kind of overflow makes the sloppy matcher return the document 'b x x a' as a hit.
- Introduced
- Hang: 5e9b2465991 on branch_5x (trunk twin fd8c4b31201), 'LUCENE-6260: Simplify ExactPhraseScorer.' (migrated as apache/lucene#7322, author jpountz; Subversion era, no pull request), which replaced the chunked exact-phrase intersection with the lead/advancePosition loop and introduced all three overflowing int expressions: phrasePos = lead.pos - lead.offset, expectedPos = phrasePos + posting.offset, and the lead re-target posting.pos - posting.offset + lead.offset [read: git blame on the study base attributes all three to fd8c4b31201; exec: commit-level A/B on source builds of the commit and its parent, parent 41206ce9e96 terminates with the correct count 0, 5e9b2465991 spins]. The issue text and comments discuss performance only. Sloppy false hit: older and not from one commit. The int span in the sloppy scorer ('int matchLength = end - start', rewritten as 'matchLength = end - pp.position' by LUCENE-3215, c54608b60dc, 2011) and PhrasePositions 'position = nextPosition() - offset' date from the initial import (bd3948c539e, 2001); query offsets that can make them overflow became possible with fd4cd859c57 (2004-09-15), which added explicit positions to PhraseQuery and PhrasePrefixQuery (CHANGES.txt 1.4.2 item 4) [read]. Later refactors moved the exact loop without changing the arithmetic: LUCENE-8249 (7.4.0) created ExactPhraseMatcher#nextMatch, and #15861 (2026-04-21) changed only how frequencies are loaded [read]. (2015-02-20 (hang: author and commit date of 5e9b2465991 and fd8c4b31201); sloppy side: 2004-09-15 (explicit query positions, fd4cd859c57) on span arithmetic from the 2001 initial import)
- First affected version
- 5.1.0 for the hang (the first release tag containing 5e9b2465991, tag commit dated 2015-04-13; 5.0.0, tagged 2015-02-19, does not contain it and terminates [exec]); the sloppy false hit is far older: 1.9.1 (2006) [exec], the oldest release that could be executed, and by reading 1.4.2 (2004), the first release with PhraseQuery#add(Term, int); in 1.9.1 to 2.4.1 the false hit is visible only at scorer level (a HitCollector sees it with score NaN, the top-docs path returned 0), and from 2.9.0 the top-docs path counts it too [exec]
- Affected versions
- Hang: every release from 5.1.0 to 10.6.0 (10.6.0 by reading) and main ea57360912ed. [exec] reproduced on 5.1.0, 5.5.5, 6.0.0, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.3.0, 9.12.3, 10.0.0, 10.5.2, main (-ea and -da) and commit 5e9b2465991; [read] 97 of the 106 releases from 5.1.0 to 10.5.2 on Maven Central are tagged in the history clone and every one of those tags contains the three int expressions (the other 9, 8.8.2 to 8.11.4, have no tag; 8.11.4 was executed). Not affected by the hang: 5.0.0 and earlier [exec: 1.9.1, 2.0.0, 2.1.0, 2.4.1, 2.9.0, 2.9.4, 3.0.3, 3.6.2, 4.10.4, 5.0.0 and the parent commit 41206ce9e96 return the correct count 0; read: none of the 54 release tags before 5.1.0 contains the expressions, and their exact scorers subtract the query position from the document position, which cannot overflow for positions >= 0]. IndexSearcher#setTimeout (added in 9.3.0) did not stop the hang in any executed release that has it [exec: 9.3.0, 9.12.3, 10.5.2, main]; the releases in between were not run with a timeout. Sloppy false hit (slop 1; PhraseQuery with an offset of Integer.MAX_VALUE, MultiPhraseQuery with Integer.MIN_VALUE): reproduced on every executed release from 1.9.1 to 10.5.2 and on main [exec: 21 releases, main and both commits], scorer level only in 1.9.1 to 2.4.1. Not executed: 1.4.2 to 1.9 (not on Maven Central under org.apache.lucene). Not fixed: upstream main was still ea57360912ed on 2026-10-26, the overflowing expressions are present on main, branch_10x, branch_10_6 and branch_9_12, and no commit touches ExactPhraseMatcher, SloppyPhraseMatcher or PhrasePositions after it [read, read-only GitHub API]. The history runs used JDK 25 and seed DEADBEEF; the version-adapted main() repros use NIOFSDirectory on 5.x and later and RAMDirectory on 4.x and older.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: 230 query lines (100 GitHub GraphQL searches; scripted prior-report searches over GitHub issues/PRs (20), commits (3), downstream repositories (2), the dev@, java-user@, issues@ and commits@ lists (52), the JIRA archive (13) and the web (12); 14 JIRA issue reads and 6 queries of the SOLR JIRA archive; the changed-file lists of all 413 open apache/lucene PRs; git log -S on the overflowing expressions), 32 hits read, none the same bug; earlier passes by the finder (5 GitHub searches), the independent reproduction (partial, rate-limited) and the intended-behaviour check (32 queries) also found nothing); not fixed: upstream main HEAD is ea57360912ed, the expressions are present on main, branch_10x, branch_10_6 and branch_9_12, and the open PRs that touch the files (#14716, #15423, #16851) do not change the arithmetic; related, not reports of this bug: precedents of the same class in other code, #9082 / LUCENE-8034 (SpanNotQuery end + post overflow near Integer.MAX_VALUE, fixed in 7.2 with a test; its downstream report elastic/elasticsearch#27134 first drew a maintainer's 'just an overflow ... don't do that') and #9658 / LUCENE-8612 (Intervals.extend ships an explicit overflow guard); same-code history, #4288 / LUCENE-3215 (negative PhrasePositions positions from query holes, not an overflow), #7442 / LUCENE-6382 (IndexWriter.MAX_POSITION bounds indexed positions only), #7317 / LUCENE-6255 (the builder's lower-bound and order checks), #7322 / LUCENE-6260 (wrote the exact-matcher arithmetic, no overflow remarks), #15332 (PhraseQuery.Builder#setMaxTerms, no position bound); #12211 (the finder's and the independent reproduction's top tool hit) is a different DrillSideways bug; gaps: private security@ reports cannot be searched, Lucene ports other than Lucene.NET and chat were not searched, forums only through general web search
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-28) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 release jars. Earlier hunt runs on mainea57360912ed(the involved files are identical), on 21 releases from 1.9.1 to 10.5.2 and on the introducing commit and its parent. The fix was validated in the scratch worktree: the new test, 19 related suites and the wholelucene/coremodule (749 suites, 8,896 tests) with assertions on and off, and:lucene:core:check -x test.
- Finding record
a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/ExactPhraseMatcher.java:149-180 (nextMatch: phrasePos, expectedPos, lead re-target, continue advanceHead)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/SloppyPhraseMatcher.java:212, 226, 228 (matchLength = end - pp.position), :236 (return matchLength <= slop); lucene/core/src/java/org/apache/lucene/search/PhrasePositions.java:53-55 (position = postings.nextPosition() - offset)a Lucene main checkout lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:126-155 (Builder#add(Term,int): >= 0, order, field, maxTerms), :268-283 (getSlop javadoc: maximum edit distance); lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:121-139 (Builder#add(Term[],int): field check only)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:211 (MAX_POSITION = Integer.MAX_VALUE - 128); lucene/core/src/java/org/apache/lucene/index/QueryTimeout.java:20-23 ('bulk scoring will be time-bound'); lucene/core/src/java/org/apache/lucene/search/TimeLimitingBulkScorer.java (checks between scoring windows)a Lucene main checkout SECURITY.md lines 28 and 38 (out of scope: unbounded input passed directly to Lucene APIs; timeouts named as a bounding mechanism), line 50 (in-scope definition)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/ExactPhraseMatcher.java:131-146 (at a9779ef3c193) (advancePosition), :149-180 (nextMatch: :159 phrasePos, :162 expectedPos, :165, :169-171 re-target and continue advanceHead)lucene/core/src/java/org/apache/lucene/search/SloppyPhraseMatcher.java:212, (at a9779ef3c193) 226, 228 (matchLength = end - pp.position), :236, :302-310 (advancePP, end); lucene/core/src/java/org/apache/lucene/search/PhrasePositions.java:55 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:126-155 (at a9779ef3c193) (Builder#add), :304-316 (rewrite rebases to 0); lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:125-140, (at a9779ef3c193) :306-307; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:210-211 (at a9779ef3c193)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:846-848; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/search/TimeLimitingBulkScorer.java:72-83; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/QueryTimeout.java:20-23 (at a9779ef3c193)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:99-105, (at a9779ef3c193) :119-155, :268-283; lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:121-140; (at a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:210-211 (at a9779ef3c193)lucene/core/src/test/org/apache/lucene/search/TestPhraseQuery.java:339; (at a9779ef3c193) lucene/queries/src/test/org/apache/lucene/queries/spans/TestBasics.java:232; lucene/queries/src/java/org/apache/lucene/queries/intervals/ExtendedIntervalIterator.java:73-77; lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2010-2011; SECURITY.md:28, :38
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:304-316 (at a9779ef3c193) (rewrite), :381-383 (compareTo); Lucene main a9779ef3c193 SECURITY.md:46read-only GitHub API 2026-10-28: pulls/16913/files (PhrasePositions.java, SloppyPhraseMatcher.java, TestMatchesIterator.java, TestSloppyPhraseQuery.java; keeps nextPosition() - offset and end - pp.position)lucene/core/src/java/org/apache/lucene/search/ExactPhraseMatcher.java:159, (at a9779ef3c193) :162, :170; lucene/core/src/java/org/apache/lucene/search/MultiPhraseQuery.java:182-195, :305-307; lucene/core/src/java/org/apache/lucene/search/SloppyPhraseMatcher.java:244, 259, 269, 615; lucene/core/src/java/org/apache/lucene/search/PhraseQuery.java:543-545
- Prior reports
read-only GitHub API 2026-10-28: search/issues 'repo:apache/lucene ExactPhraseMatcher' (12), 'repo:apache/lucene phrase overflow' (14), 'repo:apache/lucene PhraseQuery updated:>=2026-10-26' (1: #16913), 'repo:apache/lucene "MultiPhraseQuery" updated:>=2026-10-26' (0); commits?path= for ExactPhraseMatcher.java (7b61978b14f), SloppyPhraseMatcher.java (54283150a81), PhrasePositions.java (c2825cfc4b2); commits/main (645d4fe14a2)
- TestPhraseQueryPositionOverflow.java (JUnit test):
repro/LFV-196/src/org/apache/lucene/search/TestPhraseQueryPositionOverflow.java(51 lines)
Made in parallel with this doc from its own executed probe on main a9779ef3c193; every on-screen value comes from the code or that probe.
assets/LFV-196/bug.png(499 KB)