One empty leaf makes a whole reader unsearchable, because a bounds check added for partition ranges also runs on the whole-leaf range.
- A reader is a list of leaves (segments). A leaf's
maxDoc()is its number of document ids, and it can be 0:new ParallelLeafReader()with no sub-readers is a stock leaf withmaxDoc()0. IndexSearchergroups the leaves into slices, the units of work it runs, in parallel when it has an executor.- Since 10.0 a slice holds partitions: a leaf plus a doc-id range. A whole leaf gets the range
[0, NO_MORE_DOCS); intra-segment search can also split a big leaf into real sub-ranges such as[0, 500)and[500, 1000).
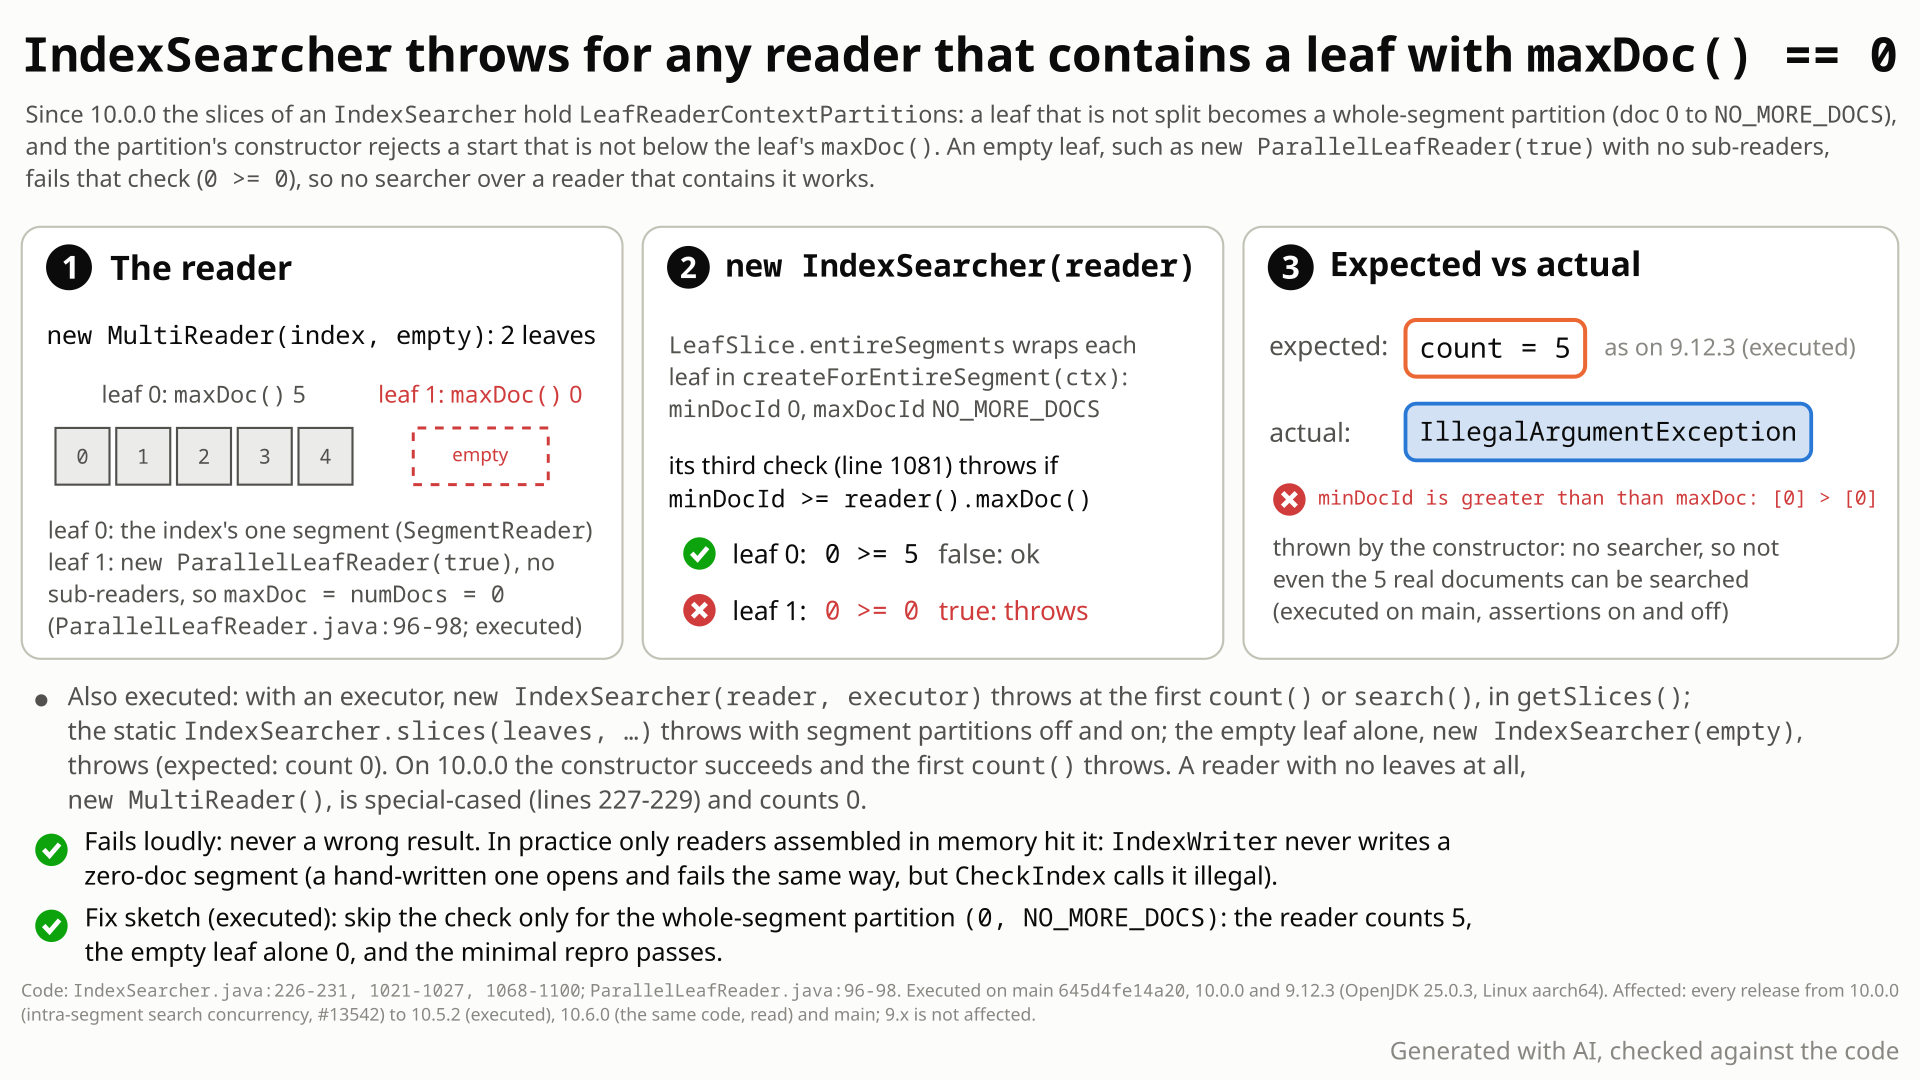
[0, NO_MORE_DOCS), the partition check 0 >= maxDoc() reads 0 >= 0, and IndexSearcher throws instead of counting 0 as 9.12.3 does. Select the still to open it at full size. Generated with AI, checked against the code.- Build a reader whose one leaf has no documents:
new ParallelLeafReader(true)with no sub-readers hasmaxDoc()0. Runnew IndexSearcher(reader).count(new MatchAllDocsQuery()). - You expect 0, as on 9.12.3. Put the same empty leaf next to a real 5-document index in a
MultiReaderand you expect 5. - Instead the
IndexSearcherconstructor throwsIllegalArgumentException: minDocId is greater than than maxDoc: [0] > [0], with assertions on or off. TheMultiReaderwith 5 real documents fails the same way. - Why: since 10.0 slicing wraps every leaf in a partition with the range
[0, NO_MORE_DOCS), and the partition constructor rejectsminDocId >= maxDoc(). The check also runs on that whole-leaf range, and for an empty leaf it reads0 >= 0. - Indexes that
IndexWriterwrites never contain an empty leaf, so in practice only readers assembled in memory hit it. It always fails loudly and never returns a wrong result.
Applications that build a reader in memory with an empty leaf: a ParallelLeafReader with no sub-readers (alone, wrapped or inside a MultiReader) or a custom LeafReader whose maxDoc() is 0. Every searcher with Lucene's own slicing fails over that reader, with or without an executor. Readers over indexes that IndexWriter wrote are not affected.
Mechanism, terms and numbers456 words
Since 10.0.0 IndexSearcher's own slicing wraps every leaf of its reader in a LeafReaderContextPartition, a leaf plus a doc-id range; a whole leaf gets [0, NO_MORE_DOCS) from createForEntireSegment. The partition constructor throws IllegalArgumentException when minDocId >= leaf.maxDoc(), a check that intra-segment concurrency (#13542) added to the partition constructor at a reviewer's request. It runs for the whole-leaf partition too, and for a leaf with maxDoc() == 0 it reads 0 >= 0. So a reader that contains an empty leaf cannot be searched: new IndexSearcher(new ParallelLeafReader(true)) throws where 9.12.3 counts 0, and a MultiReader of a 5-document index plus that leaf throws where 9.12.3 finds 5. A reader with no leaves at all is special-cased and works. Indexes that IndexWriter writes never contain an empty leaf, so in practice only readers assembled in memory hit it. Every release from 10.0.0 to 10.6.0 and main is affected; 9.x is not.
new IndexSearcher(reader)(:189-191) delegates toIndexSearcher(IndexReaderContext, Executor)(:218-232). Without an executor it builds its one slice at once:leafContexts.isEmpty() ? new LeafSlice[0] : new LeafSlice[] {LeafSlice.entireSegments(leafContexts)}(:226-231). A reader with no leaves is special-cased; a leaf with no documents is not.LeafSlice.entireSegmentswraps every leaf withLeafReaderContextPartition.createForEntireSegment(ctx)(:1021-1028).createForEntireSegmentalways passesminDocId0 andmaxDocIdDocIdSetIterator.NO_MORE_DOCS(:1097-1100).- The private constructor (
:1068-1094) checksminDocId >= maxDocId,minDocId < 0andminDocId >= leafReaderContext.reader().maxDoc()(:1081-1088). For an empty leaf the third reads0 >= 0and throws "minDocId is greater than than maxDoc: [0] > [0]" (the message says>; the check is>=). - Every other stock slicing path reaches the same constructor: executor searchers lazily through
getSlices()andcomputeAndCacheSlices()(:537-543,:545-565) on the firstcount()orsearch(), and the public staticslices(leaves, maxDocsPerSlice, maxSegmentsPerSlice, allowSegmentPartitions)(:341-390) with partitions off (:385) and on (:422; an empty leaf always fits in a slice).
Before #13542 a slice held plain leaves and nothing was checked per leaf, so 9.x searched the empty leaf and found nothing in it.
ParallelLeafReader's constructor accepts zero readers and then sets this.maxDoc = this.numDocs = 0 (ParallelLeafReader.java:96-98). Any custom LeafReader whose maxDoc() is 0 does the same. Wrapping it, nesting it or putting it in a MultiReader next to real indexes does not help: every leaf is wrapped.
On 10.0.0 the no-executor constructor still computed slices lazily, so the first count() or search() throws; from 10.1.0 (#13893) the constructor throws, and from 10.2.0 (#14343) through LeafSlice.entireSegments. With an executor it throws from getSlices() in every affected version.
Exposure and likelihood271 words
- Who is hit: applications that assemble a reader in memory with an empty leaf. One empty leaf makes the whole
MultiReaderunsearchable, its non-empty leaves included. - Default vs opt-in: the default
IndexSearcher, no setting involved; what is opt-in is the reader composition. - Scale: none; one empty leaf is enough and no index is needed.
- Severity: a loud, deterministic
IllegalArgumentExceptionon every attempt. Nothing is persisted, no wrong result is ever returned, nothing hangs and no search task is submitted (executed probe). - Not hit: readers over indexes that
IndexWriterwrote.IndexWriternever writes a 0-doc segment (LUCENE-5173: "Lucene never writes segments with 0 documents anymore",lucene/CHANGES.txt:13437), andCheckIndexrejects one (CheckIndex.java:1011-1013). A hand-written 0-doc segment does open (a fact-check probe:DirectoryReader.opengives one leaf withmaxDoc()0 andIndexSearcherthrows the same exception), butCheckIndexrejects it as illegal and index files are trusted input (SECURITY.md:30-34). A fully hard-deleted segment kept by the merge policy, a fully soft-deleted segment (SoftDeletesDirectoryReaderWrapperdrops the leaf) and aFilterDirectoryReaderthat hides every document through live docs all keepmaxDoc() > 0and search fine (executed). AParallelCompositeReaderwith no readers has no leaves;MemoryIndexandTermVectorLeafReaderreportmaxDoc()1. - Downstream: a read-only code search found no readerless
ParallelLeafReaderin Elasticsearch, OpenSearch or Solr; Solr's oneParallelLeafReaderalways has inputs and feeds a merge. A spot check, not proof. - Exposure so far: 13 releases over two years (10.0.0 to 10.6.0) and no report found.
- Workaround: leave zero-doc leaves out of the reader. Overriding the protected
slices(List)cannot help the no-executor constructor, which builds its slice directly (IndexSearcher.java:226-231).
One JUnit class on Lucene's test framework, one test method, no index and no directory, deterministic and single-threaded, public API only. It uses a plain IndexSearcher, and the try/catch only turns the exception into an expected-vs-actual message.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.index.ParallelLeafReader;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSearchZeroDocLeaf extends LuceneTestCase {

  public void testCountOnEmptyParallelLeafReader() throws Exception {
    try (ParallelLeafReader empty = new ParallelLeafReader(true)) {
      int count;
      try {
        count = new IndexSearcher(empty).count(new MatchAllDocsQuery());
      } catch (IllegalArgumentException e) {
        // expected: count 0 on a reader whose only leaf has maxDoc() == 0; actual: it throws
        throw new AssertionError("expected count 0 for a maxDoc() == 0 leaf, but threw " + e, e);
      }
      assertEquals(0, count);
    }
  }
}
cp $REPRO/TestSearchZeroDocLeaf.java $LUCENE/lucene/core/src/test/org/apache/lucene/search/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestSearchZeroDocLeaf -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
countreturns 0, as on 9.12.3.- Observed
IllegalArgumentException: minDocId is greater than than maxDoc: [0] > [0]from theIndexSearcherconstructor, assertions on and off.
More files, environment, full output193 words
Copy the class into lucene/core/src/test/org/apache/lucene/search/ of a checkout and run it with gradle; it needs only core and the test framework. It fails the same way with assertions off (-Ptests.asserts=false). The same class is the suggested regression test: it fails on stock main through gradle and passes with either fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; releases 10.6.0 and 10.0.0: fail; 9.12.3: passes; with fix A or C: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is plain Java) |
# gradle, main 645d4fe14a20, -Ptests.seed=DEADBEEF (trimmed)
TestSearchZeroDocLeaf > testCountOnEmptyParallelLeafReader FAILED
    java.lang.AssertionError: expected count 0 for a maxDoc() == 0 leaf, but threw java.lang.IllegalArgumentException: minDocId is greater than than maxDoc: [0] > [0]
        at org.apache.lucene.search.TestSearchZeroDocLeaf.testCountOnEmptyParallelLeafReader(TestSearchZeroDocLeaf.java:31)
        Caused by:
        java.lang.IllegalArgumentException: minDocId is greater than than maxDoc: [0] > [0]
            at org.apache.lucene.search.IndexSearcher$LeafReaderContextPartition.<init>(IndexSearcher.java:1086)
            at org.apache.lucene.search.IndexSearcher$LeafReaderContextPartition.createForEntireSegment(IndexSearcher.java:1099)
            at org.apache.lucene.search.IndexSearcher$LeafSlice.entireSegments(IndexSearcher.java:1025)
            at org.apache.lucene.search.IndexSearcher.<init>(IndexSearcher.java:230)
            at org.apache.lucene.search.IndexSearcher.<init>(IndexSearcher.java:202)
            at org.apache.lucene.search.IndexSearcher.<init>(IndexSearcher.java:190)
            at org.apache.lucene.search.TestSearchZeroDocLeaf.testCountOnEmptyParallelLeafReader(TestSearchZeroDocLeaf.java:28)
:lucene:core:test (FAILURE): 1 test, 1  failure

# standalone runner, seed DEADBEEF (summary of the runs)
main 645d4fe14a20  -ea: FAIL 1/1   -da: FAIL 1/1
10.6.0             -ea: FAIL 1/1
10.0.0             -ea: FAIL 1/1   (the constructor succeeds; count() throws from getSlices())
9.12.3 -ea: pass 1/1IndexSearcher(IndexReader)states no precondition,IndexReader#maxDochas no lower bound, andLeafReadersays any subclass "is searchable".ParallelLeafReaderhandles zero sub-readers on purpose, andIndexSearcheritself special-cases a reader with no leaves.- 9.12.3 searches these readers; no CHANGES or MIGRATE entry announces a restriction.
The full argument260 words
The contract is implied, not stated outright.
IndexSearcher(IndexReader): "Creates a searcher searching the provided index." (IndexSearcher.java:188-191): no precondition, not@lucene.experimental.IndexReader#maxDoc: "Returns one greater than the largest possible document number." (IndexReader.java:300-305): no lower bound.LeafReader: "Search of an index is done entirely through this abstract interface, so that any subclass which implements it is searchable." (LeafReader.java:31-34)ParallelLeafReaderhandles zero sub-readers on purpose (ParallelLeafReader.java:96-98); the upstream testTestParallelReaderEmptyIndexbuilds one (:49-50, LUCENE-1918), though only foraddIndexes.IndexSearcherspecial-cases a reader with no leaves (IndexSearcher.java:227-229).- 9.12.3 searches these readers correctly (executed). The 10.0.0 CHANGES entry for #13542 (
lucene/CHANGES.txt:2332) and MIGRATE's six #13542 items say nothing about empty leaves, and no upstream test asserts the rejection.
History of the check. In the #13542 review jpountz asked (2024-07-31, on the private constructor that both factories share): "Can you add validation, e.g. minDocId >= 0, maxDocId > minDocId, minDocId < context.reader().maxDoc(), etc?", and javanna answered (2024-08-26) "good with the proposed validation", keeping NO_MORE_DOCS as the upper bound when targeting the entire segment. None of the PR's 30 comments, 99 review comments and 77 reviews mentions empty or 0-doc leaves.
Precedent. LUCENE-5045 (#6109, 2013): DrillSideways threw IllegalArgumentException on an empty reader; the report says "there's nothing technically wrong from running a search against an empty index", and it was fixed as a bug. In #15803 (2026-03-10) mikemccand wrote "Lucene tries hard to never produce a 0-doc segment" and still asked for an explicit test with 0-doc segments.
The devil's-advocate check163 words
The strongest case for "intended" (rated moderate by the cross-model reviewers, weak to moderate by the devil's-advocate verifier): the check is deliberate and is literally what the reviewer asked for ("minDocId < context.reader().maxDoc()"); LeafReaderContextPartition is @lucene.experimental; and Lucene never writes 0-doc segments (LUCENE-5173; CheckIndex rejects maxDoc <= 0), so an empty leaf is an unusual, synthetic reader.
Why it fails: the failure surfaces through the stable IndexSearcher(IndexReader) constructor, not the experimental partition API; the review was about partition bounds, and nobody discussed what the check does to the whole-leaf partition of an empty leaf; LUCENE-5173 and CheckIndex govern segments written to disk, while ParallelLeafReader is a public reader that handles zero inputs on purpose; and a fix that keeps the validation for real partitions leaves search working, with 0 hits in the empty leaf and correct counts beside it. That the effect on the empty whole-leaf partition was overlooked is an inference, not something the PR says. Verdict: not intended; rare.
Recommended Range-check only true partitions (C, recommended, validated)
Range-check only true partitions: move the constructor's three checks into createFromAndTo, since createForEntireSegment's range is the whole leaf by construction. It passes the repro and the slicing suites, and keeps working if open PR #16952 changes the whole-leaf range to (0, maxDoc), where the one-condition alternative stops working.
public static LeafReaderContextPartition createFromAndTo(
    LeafReaderContext ctx, int minDocId, int maxDocId) {
  assert maxDocId != DocIdSetIterator.NO_MORE_DOCS;
  // only a true partition needs a range check: the entire-segment partition is valid for any
  // leaf, including one with no documents
  if (minDocId >= maxDocId) { throw ... }            // moved from the constructor, unchanged
  if (minDocId < 0) { throw ... }                    // moved, unchanged
  if (minDocId >= ctx.reader().maxDoc()) { throw ... } // moved, unchanged
  return new LeafReaderContextPartition(ctx, minDocId, maxDocId, maxDocId - minDocId);
}
All options and trade-offs3 options · 749 words
Two fixes were built and validated; for every partition Lucene itself creates on today's main they behave the same. C is recommended because it does not depend on how the whole-leaf range is represented, which open PR #16952 changes.
The change is +21/-20 lines in IndexSearcher.java: the three checks move, unchanged, from the private LeafReaderContextPartition constructor into createFromAndTo, the only factory that takes caller-supplied bounds. createForEntireSegment passes no check, because its range is the whole leaf, whatever the leaf's size.
public static LeafReaderContextPartition createFromAndTo(
    LeafReaderContext ctx, int minDocId, int maxDocId) {
  assert maxDocId != DocIdSetIterator.NO_MORE_DOCS;
  // only a true partition needs a range check: the entire-segment partition is valid for any
  // leaf, including one with no documents
  if (minDocId >= maxDocId) { throw ... }            // moved from the constructor, unchanged
  if (minDocId < 0) { throw ... }                    // moved, unchanged
  if (minDocId >= ctx.reader().maxDoc()) { throw ... } // moved, unchanged
  return new LeafReaderContextPartition(ctx, minDocId, maxDocId, maxDocId - minDocId);
}
Trade-offs
- True partitions keep exactly the same checks and messages; only the whole-leaf partition, whose bounds the code chooses itself, is no longer checked.
- It survives #16952 (open, opened 2026-10-30), which makes
createForEntireSegmentpass(0, maxDoc): there an empty leaf would otherwise fail the first check (0 >= 0). - It moves about 20 lines, so it conflicts textually with draft #16847, which edits the third check.
- No behaviour change for any leaf with at least one document.
What the checks validated
Gradle in a scratch worktree of 645d4fe14a20, OpenJDK 25.0.3, seed DEADBEEF (2026-10-31). Stock: the minimal test fails with assertions on and off. With C:
- the minimal test plus
TestIndexSearcher,TestTaskExecutor,TestTotalHitCountCollector,TestTopFieldCollectorEarlyTermination,TestSegmentToThreadMapping,TestForTooMuchCloning,TestParallelLeafReader,TestParallelReaderEmptyIndexandTestParallelCompositeReader: 10 classes, 65 tests, 0 failures, 1 skipped, with assertions on and off; - core lint (
checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTest) passes with the test in place; - with open PR #16952 applied as well: the same run plus a verifier's sequential and executor
search(q, 10)tests passes (11 classes, 70 tests, 0 failures, 1 skipped), while the minimal test alone fails on #16952 without a fix.
With the patched IndexSearcher.java shadowed on main's jars: the finder's 3 tests (the empty leaf alone and next to a 5-doc index), a verifier's 7 tests (sequential, executor and static slices(); 5 of 7 fail on stock) with assertions on and off, and another verifier's executor/static test (4/4) all pass. The whole org.apache.lucene.search package was run with A only.
The change is +3/-1 lines in IndexSearcher.java: the hunt's one-condition fix.
// the whole-segment partition (0, NO_MORE_DOCS) is also valid for a leaf with no documents
if (minDocId >= leafReaderContext.reader().maxDoc()
    && (minDocId != 0 || maxDocId != DocIdSetIterator.NO_MORE_DOCS)) {
Trade-offs
- One condition, the smallest change; for every partition Lucene itself creates on today's main it behaves exactly like C (they differ only for a direct
createFromAndTo(ctx, 0, NO_MORE_DOCS)call on a 0-doc leaf with assertions off, which A accepts and C rejects). - It keys on the
NO_MORE_DOCSsentinel, so it stops working if open PR #16952 is merged: with #16952 applied, the minimal test fails with A on top (minDocId is greater than or equal to maxDocId: [0] > [0]).
What the checks validated
Gradle in the same scratch worktree of 645d4fe14a20: the minimal test passes with assertions on and off; the minimal test plus the suites listed under C: 10 classes, 65 tests, 0 failures, 1 skipped; the whole org.apache.lucene.search package: 215 classes, 2,340 tests, 0 failures, 49 skipped; core lint passes with the test in place.
Earlier, in the hunt: every repro (the finder's 3, the verifiers' 7 and 7, the adjudication's re-run 5), 10.0.0 and the introducing commit with it applied, the bounded-exhaustive harness (0 failures) and TestIndexSearcher, TestCachingCollector(Manager), TestMultiCollector(Manager) and TestDocValuesStatsCollector.
Leave leaves with maxDoc() == 0 out of LeafSlice.entireSegments and slices(...).
Trade-offs
Collectors would never see the leaf, the slices would no longer cover every leaf of the reader, and the public static slices() would return different slices. A reader whose only leaf is empty would get no slice at all, and search() asserts leafContexts.isEmpty() in that case (IndexSearcher.java:764), so that would need changing too. More invasive than C for no gain.
No downstream engine is known to build such a reader: a read-only code search found no readerless ParallelLeafReader in Elasticsearch, OpenSearch or Solr.
A hunt on concurrent collector managers and slicing checked the public static IndexSearcher.slices(...) on the real jar against its own properties over every small leaf layout. "Does not throw for a legal reader" failed in 31,176 of 178,996 layouts: exactly those with a 0-doc leaf. It was then reduced by hand to a public-API test.
The method in full173 words
Method: bounded-exhaustive translation validation (the hunt's semi-formal tier) of the public static IndexSearcher.slices(leaves, maxDocsPerSlice, maxSegmentsPerSlice, allowSegmentPartitions) in a hunt on concurrent collector managers and slicing, run on the real main jar (ea57360912ed).
- A harness enumerated 1-3 leaves of 0-10 documents, every
maxDocsPerSliceandmaxSegmentsPerSliceup to the bound, partitions off and on, plus a few shapes nearIndexWriter.MAX_DOCS, and checked properties P0-P6 on the result. - P0, "slices() does not throw for a legal reader", failed in 31,176 of 178,996 configurations, which is exactly the number of enumerated configurations that contain a 0-doc leaf (recomputed from the harness loops); 116,100 of 1,013,068 in a 3 x 0..16 run.
- The partition properties P1-P6 held in all 5,894,928 configurations of 1-4 leaves with 1-12 documents (23,834,568 in a 4 x 1..16 run); z3 discharged the partition arithmetic obligations; the variant with the fix had 0 failures.
- The finder then reduced it by hand to a 3-test public-API JUnit on the stock jars; the hunt later cut that to the one-method test shown here.
No prior report found (191 logged queries on 2026-10-26 over GitHub, downstream trackers, the lists, JIRA and the web; rechecked 2026-10-29 and 2026-10-31). Open PR #16952 and draft #16847 edit the same code without fixing it.
Searches4 searches
Verdict new: no issue, PR, commit, list thread, JIRA entry, downstream report or web page reports it; the exact error text appears upstream only in the source and in the commits@ mail of #13542.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), and Elasticsearch, OpenSearch and Solr issues and code | 2026-10-26 | a scripted prior-report search (two runs) plus GraphQL searches (83 GitHub queries in all), commit searches and git log -S on the full history, the changed-file lists of all 413 open PRs, 15 downstream issue/PR queries and 4 code searches | only related items: #13542 (introduced it), #13893 and #14343 (moved where it throws), #14428, #13860, #16847 (same check rewritten), #15324 and #16855 / #16856 (different NO_MORE_DOCS bugs) |
| Mailing lists and JIRA | 2026-10-26 | dev@, java-user@, issues@, commits@ and the Solr lists (53 queries); the JIRA archive and Solr JIRA (17) | only the commits@ mail of #13542 contains the error text; LUCENE-1918 and LUCENE-5045 are older empty-reader bugs in other code |
| Web | 2026-10-26 | 10 queries, including the exact error text | nothing relevant |
| GitHub (recheck) | 2026-10-31 | 8 issue/PR searches (exact error text, class names, empty-leaf phrasings; the control "createForEntireSegment" returns #13542, #15324 and #16855) and the 19 issues and PRs created since 2026-10-29 by title | nothing reports it; #16952 (open, 2026-10-30) changes the whole-leaf range and keeps the failure |
Introduced in 10.0.0 by #13542 (fafd6af004e, merged 2024-09-10), which added the partitions and their checks; its parent passes and it fails. Every release from 10.0.0 to 10.6.0 fails, every release from 9.1.0 to 9.12.3 passes.
Versions tested6 rows
Introduced by #13542 "Add support for intra-segment search concurrency" (javanna; merged into main 2024-09-10 as fafd6af004e; first release 10.0.0). git blame gives every line of the constructor and createForEntireSegment to it, a pickaxe on the error text finds only it, and git log -L shows no later change. branch_9x never received it, so 9.12.x, released after the merge, is not affected. Where the exception surfaces moved with #13893 (10.1.0) and #14343 (10.2.0); the check did not change.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0 | affected | minimal test fails (main with assertions on and off; gradle and standalone runner) |
10.1.0 to 10.5.2, main ea57360912ed | affected | the finder's repro fails 2/3: the constructor throws |
| 10.0.0 | affected | fails; the constructor succeeds and the first count()/search() throws (lazy slices) |
| 9.1.0 to 9.12.3 | not affected | all 20 releases pass; slices held plain leaves with no per-leaf check |
fafd6af004e (#13542) vs its parent 942065cc3e7 | bisect | the commit fails 2/3 and 4/4 (executor and static slices); its parent passes 3/3 and 4/4 |
open PR #16952 applied to 645d4fe14a20 | not merged | still fails, now in the first check (minDocId is greater than or equal to maxDocId: [0] > [0]); fix A on top still fails, fix C passes |
A cross-model review with a shell (OpenAI GPT-5.6), an independent reproducer, a reading-only GPT-5.6 review, a devil's-advocate verifier and an adjudication all found it real; the adjudication confirmed it (high confidence, crash). This doc's runs reproduced it on main, 10.6.0 and 10.0.0 and validated both fixes through gradle.
Checks and verdicts355 words
Every executed check ran on stock builds; each verifier wrote its own tests from the claim.
| Check | Verdict | What it found |
|---|---|---|
| Finder (bounded-exhaustive check of slices(), then a JUnit) | candidate | 31,176 of 178,996 layouts throw, exactly those with a 0-doc leaf; the 3-test JUnit fails 2/3 on main (assertions on and off), 10.5.2 and 10.0.0, passes on 9.12.3 and with the fix. |
| refute review (OpenAI GPT-5.6, with a shell) | real (high) | Own tests fail 2/3 on main, a one-document control passes; its release-compatible test fails on main and 10.0.0, passes on 9.12.3; with the fix its tests and TestIndexSearcher (10/10) pass. |
| Independent reproducer | real | Own public-API tests outside org.apache.lucene: 3/5 fail with assertions on and off (both controls pass), 3/5 on 10.5.2 and 10.0.0, 0/5 on 9.12.3; the static slices() test 2/2; 7/7 pass with the fix. |
| Works-as-designed lens (OpenAI GPT-5.6, reading only) | real (high) | It could not run code; intended argument moderate, root cause agreed. A separate executor and static-slices test fails 4/4 on main and passes with the fix. |
| Intended-behaviour devil's advocate | real (not intended; impact low) | Re-ran the finder's repro (fails on main, passes on 9.12.3); read the #13542 review threads, CHANGES, MIGRATE, LUCENE-5173 and CheckIndex. |
| Adjudication | confirmed (high), crash | Re-ran the independent reproduction's tests with a fresh seed: 3/5 fail with assertions on and off, 0/5 on 9.12.3, 0/5 with the fix. |
| This doc's runs | real | Gradle in a scratch worktree of 645d4fe14a20: stock fails with assertions on and off, fixes A and C pass; releases 10.6.0 and 10.0.0 fail, 9.12.3 passes; open PR #16952 keeps the failure. |
| Independent fact checks of this doc (one executed, one cross-model with OpenAI GPT-5.6) | holds after one wording fix | Re-ran the gradle command (assertions on and off, output identical), fixes A and C, the suites with a new seed and open PR #16952 with each fix. A hand-written 0-doc segment opens from a directory and throws the same exception (CheckIndex calls it illegal), so the reach wording now says indexes that IndexWriter writes, not every directory reader. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 564 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,514 words
- Registry title
- IndexSearcher throws IllegalArgumentException for any reader that contains a leaf with maxDoc() == 0 (for example a ParallelLeafReader with no sub-readers): the whole-segment LeafReaderContextPartition of that leaf fails a bounds check added for partition ranges (regression in 10.0.0)
- Area
- search / IndexSearcher slicing (LeafSlice, LeafReaderContextPartition)
- Priority
- Low, rank 785: Since 10.0.0 IndexSearcher rejects any reader that contains a 0-doc leaf (for example an empty ParallelLeafReader), loud and in practice only for readers assembled in memory.
- Impact class
- crash
- Impact note
- Hits only applications that assemble a reader in memory with a leaf whose maxDoc() is 0 (a ParallelLeafReader with no sub-readers, alone, wrapped or inside a MultiReader, or a custom LeafReader reporting maxDoc() == 0); for them every searcher over that reader fails with a clean IllegalArgumentException, in the no-executor constructor (10.1.0 on) or on the first count()/search() (executor searchers, and 10.0.0), with -ea and -da; readers over indexes that IndexWriter wrote never contain such a leaf (a hand-written 0-doc segment, which CheckIndex rejects, does open and fails the same way), no scale is needed, nothing is persisted and no wrong result is ever returned; affected since 10.0.0 (9.x not affected).
- Summary
- You build an IndexSearcher over a reader that contains an empty leaf, for example new ParallelLeafReader() with no sub-readers, possibly next to a real index inside a MultiReader, and you expect searches to work and simply find no hits in the empty part, as they do on 9.12.3. Instead the searcher throws IllegalArgumentException 'minDocId is greater than than maxDoc: [0] > [0]', because slicing wraps every leaf in a whole-segment partition that starts at doc 0 and the partition constructor rejects a start that is not below the leaf's maxDoc(). In the repro, a MultiReader of a 5-doc index plus an empty ParallelLeafReader cannot be searched at all instead of returning 5 hits.
- Introduced
- fafd6af004e0 on main: #13542 'Add support for intra-segment search concurrency' by javanna (merged 2024-09-10, closes #9721); it added LeafReaderContextPartition with three constructor checks, among them 'minDocId >= leafReaderContext.reader().maxDoc() -> IllegalArgumentException' (added after a review request by jpountz), and createForEntireSegment, which always passes minDocId 0 and maxDocId NO_MORE_DOCS [exec: jars built from the history clone at the parent 942065cc3e7 pass the repro 3 of 3 and the executor/static-slices test 4 of 4; at fafd6af004e they fail 2 of 3 (also with -da) and 4 of 4; read: git blame gives every line of the constructor and createForEntireSegment to fafd6af004e, git log --all -S on the error text finds only that commit, git log -L shows no later change]; #13893 (main a888af76b2f, 10.1.0) and #14343 (main bdf4deff313, 10.2.0) later moved where the no-executor searcher throws (into the constructor), not the defect [exec, read] (2024-09-10 (#13542, authored and committed on main); first release 10.0.0 (tag commit eadc07cc6a1, 2024-10-09))
- First affected version
- 10.0.0 [exec]; 9.12.3 and every 9.x release from 9.1.0 are not affected [exec] (branch_9x never received #13542; 9.12.x shipped after the merge from branch_9x)
- Affected versions
- all 12 releases from 10.0.0 to 10.5.2 (10.0.0, 10.1.0, 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2) and main ea57360912ed through 645d4fe14a2 (2026-10-29) [exec]: the finder's JUnit fails 2 of 3 on each with -ea, and with -da on 10.0.0, 10.5.2 and main; the executor/static-slices test fails 4 of 4 on 10.0.0, 10.5.2 and main. Not affected [exec]: all 20 releases from 9.1.0 to 9.12.3 (3 of 3 pass; -da too on 9.12.3; the executor/static test's pre-#13542 variant passes 4 of 4 on 9.12.3) and the parent commit 942065cc3e7. Releases before 9.1.0 were not run (the test framework package differs); the failing check does not exist there [read]. [read] the check is unchanged on main 645d4fe14a2, branch_10x 657014b3c57 (IndexSearcher.java:1093) and branch_10_6 4ae946e5a9b (10.6.0 RC1), and 10.6.0 (released 2026-10-29) shipped with it: the minimal test fails on its release jars (4ae946e5a9b9) with -ea [exec 2026-10-31]. Where it throws: on 10.0.0 and fafd6af004e the no-executor constructor succeeds and the first count()/search() throws; from 10.1.0 the constructor itself throws; with an executor it throws lazily from getSlices() in every affected version; the public static slices(leaves, ..., allowSegmentPartitions) throws for false and true. Not executed: x86; the history runs used JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new: 191 query lines, among them scripted prior-report searches over GitHub issues/PRs (83 GitHub queries in all, REST and GraphQL), commits (8), downstream repositories (15 issue/PR queries and 4 code searches over Elasticsearch, OpenSearch and Solr), the dev@, java-user@, issues@ and commits@ lists plus the Solr lists (53), the JIRA archive and Solr JIRA (17) and the web (10), plus the changed-file lists of all 413 open apache/lucene PRs and the full git history; no issue, PR, commit, list thread, JIRA entry, downstream report or web page reports it; the error text appears upstream only in IndexSearcher.java and in the commits@ mail of #13542); not fixed upstream: the check is unchanged on main ea57360912ed and 645d4fe14a2, branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b (recheck 2026-10-29, no new report; #16911 (merged 2026-10-29 as 48cf3f515d6: branch_10x decommissioned) and #16929 (merged on main 2026-10-29 as 3386cdab564: branch_10x replaced by branch_11x)); open PRs near the fix site: #16847 (draft by jimczi, long global doc ids) rewrites the check as 'minDocId >= leafReaderContext.maxLeafDoc()', same meaning, so a fix may need rebasing onto it; #13860 (open slicing refactor) still wraps every leaf with createForEntireSegment; related, not reports of this bug: #13542 (introduced it), #13893 (10.1.0, moved the throw into the no-executor constructor), #14428 (closed unmerged, would have made slicing lazy again), #15803 (mikemccand: Lucene 'tries hard to never produce a 0-doc segment' but still asked for 0-doc-segment tests), #2993 / LUCENE-1918 (2009, empty ParallelReader on the addIndexes path; added TestParallelReaderEmptyIndex) and #6109 / LUCENE-5045 (2013, DrillSideways IllegalArgumentException on an empty reader, fixed as a bug), #15324, #16855 / #16856 (different bugs about the NO_MORE_DOCS upper bound in bulk scorers); open PR #16952 (kkewwei, opened 2026-10-30, head fb1a3d8b44d, no reviews or comments as of 2026-11-02; on no branch) changes createForEntireSegment from (0, NO_MORE_DOCS) to (0, maxDoc) and does not fix this bug: with it, the whole-leaf partition of an empty leaf fails the constructor's first check instead ('minDocId is greater than or equal to maxDocId: [0] > [0]'), and the one-condition fix (option A, keyed on NO_MORE_DOCS) stops working, while option C (range checks only for true partitions) passes with and without it [exec on 645d4fe and on main e1faeba08bd, -ea and -da]; the PR author wrote that their #16897 waits on it
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off through a standalone runner and through gradle in a scratch worktree, and passes there with either fix (A or C), together with the slicing and parallel-reader suites and core lint; fix A also passes the wholeorg.apache.lucene.searchpackage. Releases 10.6.0 and 10.0.0 fail, 9.12.3 passes (standalone runner). Open PR #16952 (headfb1a3d8b44d9) applied to the same worktree: the test still fails, fix C passes, fix A does not. Earlier, the hunt ran every release from 9.1.0 to 10.5.2, mainea57360912edand the introducing commit and its parent (48 targets), and re-verified on645d4fe14a20(2026-10-29). Upstream main2f424fd428da(2026-10-30) andbranch_11x603af870375carry the sameIndexSearcher.java[read].
- Finding record
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:188-191 (IndexSearcher(IndexReader), no @lucene.experimental), :226-231 (no-executor constructor: leafContexts.isEmpty() special case, else LeafSlice.entireSegments), :1021-1028 (entireSegments wraps every leaf with createForEntireSegment), :1068-1088 (LeafReaderContextPartition constructor checks; the failing one is :1081-1088), :1097-1100 (createForEntireSegment: minDocId 0, maxDocId NO_MORE_DOCS)lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:82-99 (zero sub-readers allowed; maxDoc = numDocs = 0)lucene/core/src/java/org/apache/lucene/index/LeafReader.java:30-36 ('any subclass which implements it is searchable'), lucene/core/src/java/org/apache/lucene/index/IndexReader.java:300-305 (maxDoc javadoc, no lower bound), lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:49-50 (upstream test builds a readerless ParallelLeafReader)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:189-191, 218-232 (226-231), 341-390 (385, 422), 537-543, 545-565, 1021-1028, 1068-1094 (1081-1088), 1097-1100a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:82-99 (96-98)
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:13437; lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1011-1013a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/codecs/lucene99/Lucene99SegmentInfoFormat.java:137-140 (rejects only docCount < 0); SECURITY.md:30-34 (index files are trusted)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:188-191, 227-229; lucene/core/src/java/org/apache/lucene/index/IndexReader.java:300-305; lucene/core/src/java/org/apache/lucene/index/LeafReader.java:31-34; lucene/core/src/java/org/apache/lucene/index/ParallelLeafReader.java:96-98; lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:49-50; lucene/CHANGES.txt:2332
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:764 (assert leafContexts.isEmpty()), 1068-1111
- History
a Lucene clone refs as last fetched: origin/main 2f424fd428da, origin/branch_11x 603af870375, origin/branch_10_6 7e5aec4370e (IndexSearcher.java check present) [read]
- TestSearchZeroDocLeaf.java (one test class):
repro/LFV-202/src/org/apache/lucene/search/TestSearchZeroDocLeaf.java(36 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and an executed probe of the minimal case (stock main with assertions on and off, the fix, 9.12.3 and 10.0.0).
assets/LFV-202/bug.png(564 KB)