Java's word splitter cuts Thai text into pieces; ThaiTokenizer then decides which pieces are words. That decision looks at one character only.
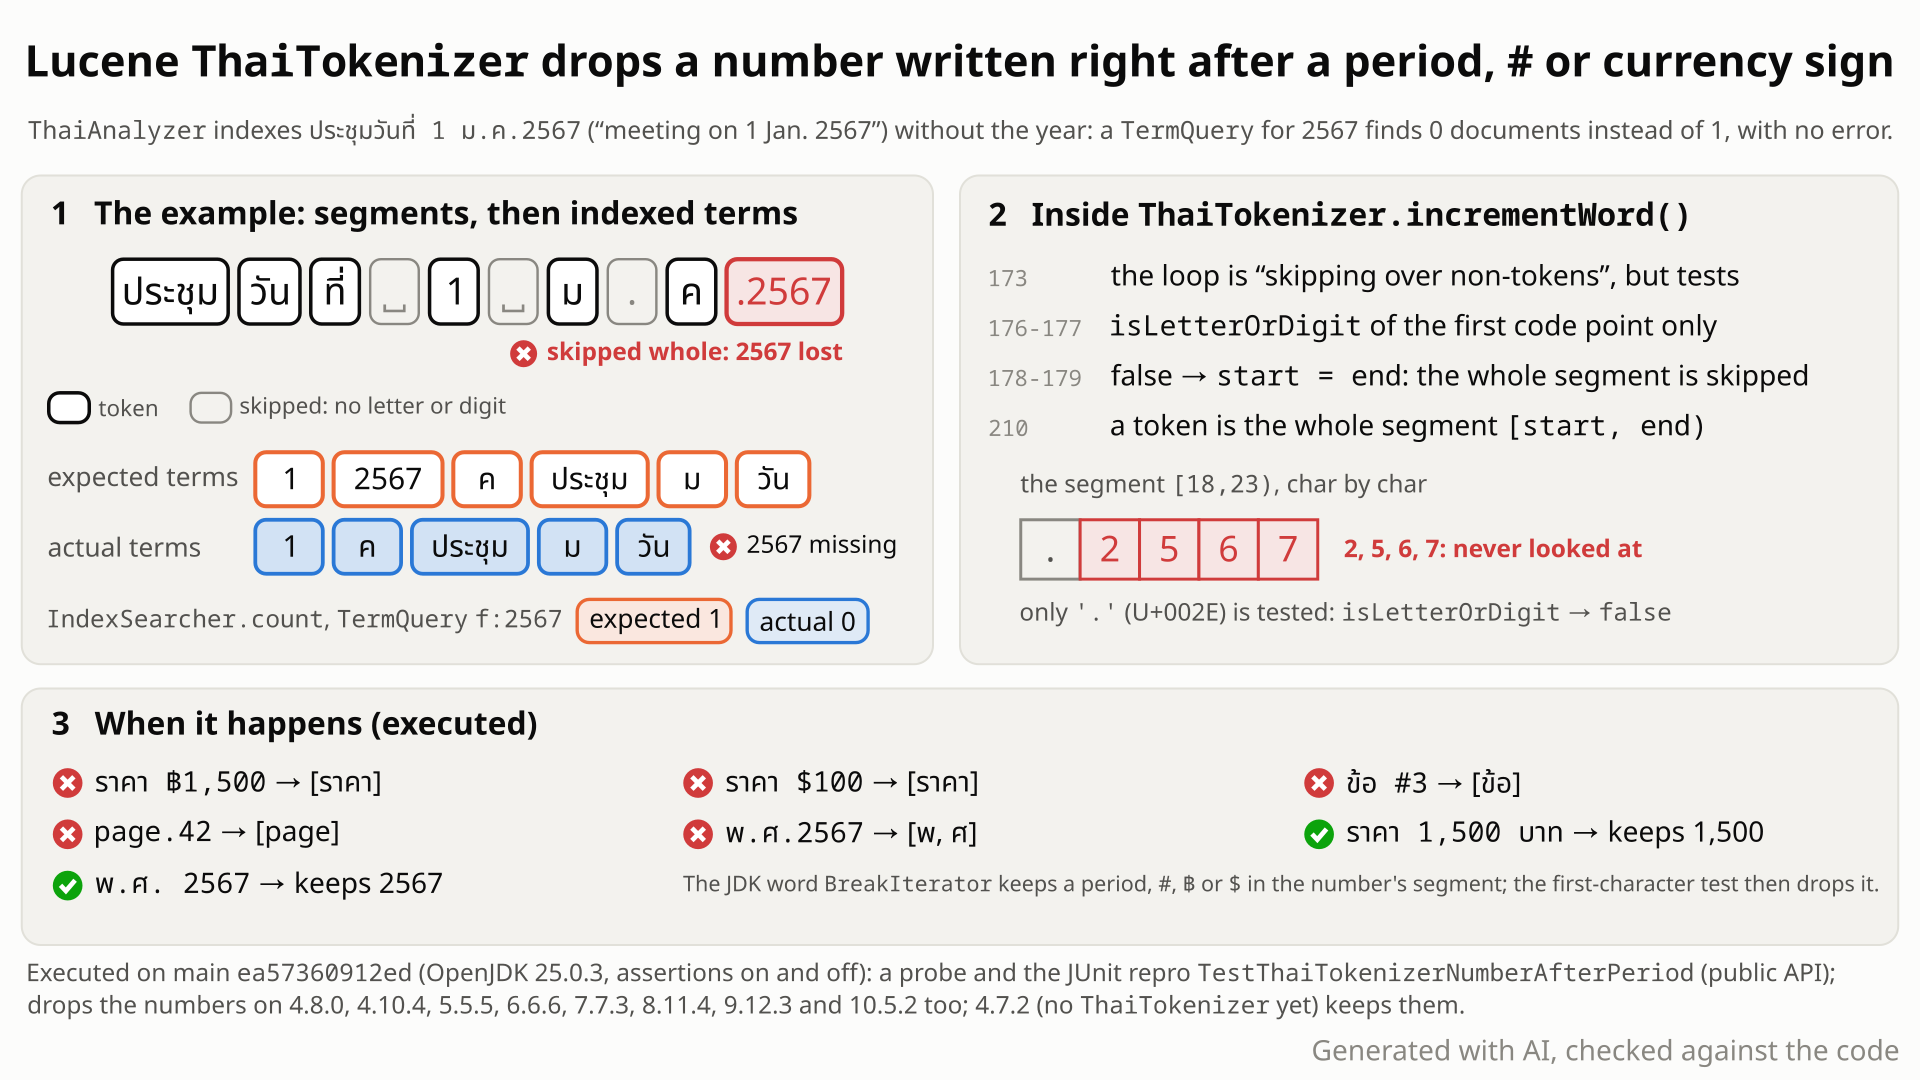
ประชุมวันที่ 1 ม.ค.2567 is split into word pieces, why the skip loop throws away .2567 (it tests only the first character), and the same loss in prices such as ราคา ฿1,500. Select the still to open it at full size. Generated with AI, checked against the code.- Index the Thai sentence
ประชุมวันที่ 1 ม.ค.2567("meeting on 1 Jan. 2567") with the stockThaiAnalyzerand countTermQuery(f:2567). You expect 1 hit, as when the date is written with a space (ม.ค. 2567). You get 0. - Prices too:
ราคา ฿1,500is analyzed as just[ราคา], andราคา $100as[ราคา]. Writtenราคา 1,500 บาท, without the sign, the amount1,500is a term. - Why: Java's word splitter keeps a period,
#or currency sign (any except¢) together with the number after it, so.2567and฿1,500are one piece each. That split is correct. ThaiTokenizerthen skips every piece whose first character is not a letter or digit (ThaiTokenizer.java:173-180). It looks only at that first character, so.,฿or#takes the whole number with it.- No error, and the index is well formed. Skipping a piece only when it has no letter or digit, and starting the token at its first one, keeps
1,500and2567; with that change all of analysis-common (1,918 tests including 9 new ones, 18 skipped) runs with 0 failures.
Anyone indexing or searching Thai text with the stock ThaiAnalyzer, ThaiTokenizer or the thai tokenizer, at default settings. Everyday-looking text triggers it: prices with a currency sign, item numbers with #, dates like พ.ศ.2567, Latin page.42. Every occurrence is lost, whatever the index size, queries lose the number too, and recovering it needs a reindex.
Mechanism, terms and numbers535 words
ThaiAnalyzer, ThaiTokenizer and the thai tokenizer SPI silently drop a number when the JDK word BreakIterator returns it in one segment with a leading period, # or currency sign (any currency sign except the cent sign). ราคา ฿1,500 ("price ฿1,500") is analyzed as [ราคา], the Buddhist Era date พ.ศ.2567 as [พ, ศ], and page.42 as [page]; a document containing ประชุมวันที่ 1 ม.ค.2567 gets 0 hits for TermQuery(f:2567) instead of 1. The JDK segments correctly; ThaiTokenizer.incrementWord skips every segment whose first code point is not a letter or digit, so the whole number is thrown away. Nothing throws and the index is well formed. Every release from 4.8.0 (2014, LUCENE-4984) to 10.5.2 and main is affected (8 releases and main executed; all 107 release tags in that range contain the loop); a small change to the skip loop fixes every tested case.
- Segment: a piece of text between two boundaries of the JDK word
BreakIteratorfor Thai. Some segments are words or numbers, others are spaces or punctuation. - Number prefix: the JDK word rules'
<pre-num>class, "the period, the number sign, and all currency symbols except the cents sign". Such a character goes into the same segment as the number after it, by the rule<pre-num>(<number><word>)*{<number>{<post-num>}}.
ThaiAnalyzerstarts its chain withnew ThaiTokenizer()(ThaiAnalyzer.java:101-102); the filters after it only see what the tokenizer emits.- The JDK splits
พ.ศ.2567into[พ][.][ศ][.2567],ราคา ฿1,500into[ราคา][ ][฿1,500]andpage.42into[page][.42]. The cent sign is not a prefix:ราคา ¢50gives[ราคา][ ][¢][50]. ThaiTokenizer.incrementWordskips "non-tokens" withwhile (end != BreakIterator.DONE && !Character.isLetterOrDigit(Character.codePointAt(buffer, sentenceStart + start, sentenceEnd)))(ThaiTokenizer.java:173-180): it tests the first code point of the segment only..,#,฿and$are not letters or digits, so the whole segment, digits included, is skipped. The term is never created; the user-dictionary lookup (:186-207) also starts after the skip.
| input | main | expected (and with the fix) |
|---|---|---|
ราคา ฿1,500 | [ราคา] | [ราคา, 1,500] |
ราคา $100, ราคา €20 | [ราคา] | [ราคา, 100], [ราคา, 20] |
พ.ศ.2567, ค.ศ.2024, ม.ค.67 | [พ, ศ], [ค, ศ], [ม, ค] | with 2567, 2024, 67 |
ข้อ #3, ค่า .5 | [ข้อ], [ค่า] | with 3, 5 |
page.42, No.5, abc.123 | [page], [no], [abc] | with 42, 5, 123 |
controls ราคา 1,500 บาท, พ.ศ. 2567, ราคา ¢50, 1.5 | numbers kept | same |
End to end, one document ประชุมวันที่ 1 ม.ค.2567: TermQuery(f:2567) counts 0 (expected 1); written ม.ค. 2567 it counts 1. At query time the same analyzer drops the number: the classic QueryParser turns +ราคา +฿1,500 into +body:ราคา, which matches any price.
Secondary symptoms of the same loop: a Latin word glued to a prefixed number is lost with it (#1word gives no token, because the JDK rule also absorbs (<number><word>)*); a prefix right after a digit starts its own segment, so 1#2, 1$2 and 1฿2 are analyzed as [1]; a segment that starts with a combining mark (่า, a tone mark with no base consonant, malformed Thai) gives no token.
Exposure and likelihood302 words
- Who is hit. Users of
ThaiAnalyzer,ThaiTokenizer, or thethaitokenizer through the SPI (CustomAnalyzer, factory configurations), with default settings. It is the Thai analyzer of analysis-common; outside its own package (whereThaiAnalyzerandThaiTokenizerFactorycreate the tokenizer), no main Lucene code uses these classes. Downstream engines that expose Lucene's Thai analysis were not tested. - Everyday-looking input. A price with its sign (
ราคา ฿1,500, even after a space), an item number (ข้อ #3), a decimal with a leading period (.5), a date abbreviation followed by the year without a space (พ.ศ.2567,ม.ค.67), Latin text such aspage.42orNo.5. Numbers that start with a digit (1,500,1.5) and spaced dates are not affected. How often each form occurs in real Thai text was not measured. - Silent and deterministic. No exception or warning;
CheckIndexis clean and the stored value is intact. The loss happens in the tokenizer, one segment at a time, so it is the same for every occurrence, with-eaand-da, whatever the index size, on JREs that segment like OpenJDK 11, 17 and 25 (all three were run). - Both sides. Indexed documents lack the number, so term, phrase and boolean searches for it miss them. In a query the number is dropped:
+ราคา +฿1,500matches any price, and a query of only฿1,500matches nothing. - Not more than that. No crash and no corruption; indexing one document does not change another. One warm timing run, not a benchmark, showed no slowdown. At query time the dropped number can add false positives, as above.
- Reindex. Documents indexed before a fix lack the terms; a fix changes analysis output, so it needs a CHANGES/MIGRATE note.
- How common. Not measured on a corpus.
The test shows that the stock ThaiAnalyzer drops the year in 'พ.ศ.2567' (Buddhist Era 2567), because ThaiTokenizer skips the whole word segment '.2567' when its first character is not a letter or digit.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.th;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestThaiAnalyzerNumberAfterPeriod extends BaseTokenStreamTestCase {

  public void testBuddhistEraYear() throws Exception {
    assumeTrue(
        "JRE does not support Thai dictionary-based BreakIterator", ThaiTokenizer.DBBI_AVAILABLE);
    try (ThaiAnalyzer a = new ThaiAnalyzer()) {
      // expected: [พ, ศ, 2567]; actual: [พ, ศ] (the year 2567 is dropped)
      assertAnalyzesTo(a, "พ.ศ.2567", new String[] {"พ", "ศ", "2567"});
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-225/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.th.TestThaiAnalyzerNumberAfterPeriod
- Expected vs actual
- Expected tokens: [พ, ศ, 2567]. Actual: [พ, ศ] (
AssertionError: token 2 does not exist).
More files, environment, full output41 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: token 2 does not exist
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:257)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:573)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:637)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertAnalyzesTo(BaseTokenStreamTestCase.java:792)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertAnalyzesTo(BaseTokenStreamTestCase.java:777)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertAnalyzesTo(BaseTokenStreamTestCase.java:862)
[...]- The loop's comment says it skips "non-tokens", and it tests letter-or-digit: digits are meant to be tokens (
TestThaiAnalyzer.testDigits). - Java's word rules call these signs "punctuation that can occur at the beginning of a number"; only Lucene's first-character shortcut drops the number.
- Before 4.8
ThaiAnalyzerkept these numbers;ICUTokenizerandStandardTokenizerkeep them today.
The full argument300 words
- Comment and test.
// find the next set of boundaries, skipping over non-tokens(ThaiTokenizer.java:173), tested withCharacter.isLetterOrDigit(:176)..2567contains four digits. - Upstream tests.
TestThaiAnalyzer.testDigits(TestThaiAnalyzer.java:131-135) checks that๑๒๓๔is indexed as1234. No explicit upstream test puts a prefix character before a number (random-text tests may generate one but do not check which characters become tokens), and no test, javadoc, CHANGES or MIGRATE entry documents the drop. With it removed (fix A), the 56 upstream Thai tests pass, and all of analysis-common, 1,918 tests including the 9 new ones (18 skipped), runs with 0 failures. - The JDK means these as numbers.
BreakIteratorRules.java:100-102and:136-139(JDK 25): the prefix class is "punctuation that can occur at the beginning of a number", and the rule keeps a sequence "that starts with a number-prefix character and a number" together. - Where the loop comes from. It copies
ICUTokenizer's// find the next set of boundaries, skipping over non-tokens (rule status 0)(ICUTokenizer.java:209-214), which skips a span with no letter or number.java.text.BreakIteratorhas no rule status; the first-code-point test stands in for it (our reading; the commit and issue do not explain the choice). - Before and beside. 4.7.2's
ThaiAnalyzer(StandardTokenizer + ThaiWordFilter) gives[พ, ศ, 2567]and[ราคา, 1,500]; so does the 4.8.0 jar withmatchVersionLUCENE_47.ICUTokenizer, named in theThaiTokenizerjavadoc as the portable alternative (ThaiTokenizer.java:35-37), gives[ค.ศ, 2024]and[page, 42];StandardAnalyzergives[page, 42]. LUCENE-4984 changed the chain to fix offsets with CharFilters; its discussion says nothing about numbers. - Precedent. LUCENE-2404 (2010): a committer called the old ThaiWordFilter's first-character test "cheating with the UnicodeBlock check on charAt(0)". LUCENE-5076 (open): a first-code-point-only word test in ICU-module code, called a bug by a committer.
The devil's-advocate check298 words
The case for "intended" (raised by the cross-model reviews, which rated it moderate, and examined by a third verifier, which found that it does not survive): ThaiTokenizer promises only that it "uses BreakIterator to tokenize Thai text" and warns that it may not be supported by all JREs; the JDK's own BreakIterator javadoc (the nextWordStartAfter example) calls a span a word only "If the characters between this boundary and the next boundary include at least one letter", and .2567 has none; and พ.ศ.2567 without a space is informal.
Why it fails:
- That idiom scans every character of the span; Lucene's loop scans one. And Lucene's test is letter or digit, not letter. Together,
.2567is a token. - The JRE splits these inputs correctly: OpenJDK 11, 17 and 25 split every input of the table the same way. The loss is Lucene's.
- The currency case,
ราคา ฿1,500after a space, is a plausible everyday way to write a price (not checked against a corpus), so "informal input" does not cover it. - "Twelve years and nobody complained": nobody discussed it or closed it as won't-fix either, and the loss is silent.
What a maintainer could still raise:
- Prefix-free terms are not a written contract, so which terms a prefixed number gives is a design choice, and changing it changes analysis output (reindex; CHANGES and MIGRATE notes).
- The input kinds differ: the price after a space is the hardest to call intended; a date without a space (
พ.ศ.2567) and Latin or decimal forms (page.42,.5) leave more room for a style or token-policy argument. - Against a shared design: in the same
SegmentingTokenizerBasefamily,HMMChineseTokenizerhas no first-character test, and the test tokenizer inTestSegmentingTokenizerBaseskips forward to the first letter or digit, as the fix does.
Recommended A: skip only segments with no letter or digit; start the token at the first one
In ThaiTokenizer.incrementWord, skip a word piece only if none of its characters is a letter or digit; otherwise start the token at the first one (฿1,500 -> 1,500, offsets [6,11)). +16/-4 lines; all of analysis-common (1,918 tests including the 9 new ones, 18 skipped) runs with 0 failures. Existing indexes need a reindex to gain the numbers.
All options and trade-offs3 options · 992 words
Option A was validated with gradle in a scratch worktree at ea57360912ed (JDK 25.0.3) and through the repro runner; option C on the 10.5.2, 9.12.3 and main jars; option B was not run. With A, file the related LFV-229 (a user-dictionary match that ends inside a character cluster) separately: A changes its symptom but does not fix it.
A: skip only segments with no letter or digit; start the token at the first one (validated by the checks) (recommended)
Replace the first-code-point test with a scan of the segment: if no code point is a letter or digit, skip the segment as before; otherwise move start to the first letter or digit and emit from there. Results: ราคา ฿1,500 -> ราคา, 1,500 [6,11); พ.ศ.2567 -> พ, ศ, 2567 [4,8); ข้อ #3 -> 3 [5,6); page.42 -> 42 [5,7); #1word -> 1word [1,6). Punctuation-only and space segments are still skipped (ราคา - บาท -> [ราคา, บาท]), and every control is unchanged. A prefix after a digit is fixed too (1#2 -> [1, 2]). This is the finder's patch; an independent verifier wrote an equivalent one.
// ThaiTokenizer.incrementWord: replaces the loop at lines 174-180
int end = wordBreaker.next();
while (end != BreakIterator.DONE) {
  int s = start;
  while (s < end) {
    int cp = Character.codePointAt(buffer, sentenceStart + s, sentenceEnd);
    if (Character.isLetterOrDigit(cp)) {
      break;
    }
    s += Character.charCount(cp);
  }
  if (s < end) {
    start = s; // drop a leading '.', '#' or currency sign, keep the number
    break;
  }
  start = end;
  end = wordBreaker.next();
}
Trade-offs
- New terms, so reindex. Old indexes lack the numbers. Mixing analyzers changes results: after the fix,
ราคา ฿1,500in a query analyzes toราคาand1,500, which an old index cannot match. Positions after a recovered number shift by one. Needs a CHANGES entry and a MIGRATE note. - The token excludes the prefix (
1,500, not฿1,500), asICUTokenizerandStandardTokenizerproduce for these inputs. - User dictionary. The lookup starts at the trimmed start: with
{1,500บาท},฿1,500บาทgives1,500บาท[1,9) (stock:[บาท]). An entry that itself starts with a prefix character (฿1,500) still never matches, as on stock. - Every leading non-letter/digit is trimmed, not only
.,#and currency signs. A segment that starts with a combining mark now yields the rest:้ำgivesำand่าgivesา(stock: nothing);ICUTokenizergives the sameำandาfor these inputs. Whether a stray tone mark should leave its vowel as a token is its own question. With{แม่น},แม่น้ำgives[แม่น, ำ]instead of[แม่น]; that is LFV-229, which needs its own fix. - Cost. A segment that starts with a letter or digit costs one check, as now; a punctuation or space segment is scanned to its end (usually one character). Not benchmarked.
What the checks validated
- The repro: 3 of 4 fail on stock, 4 of 4 pass with the fix (gradle; the repro runner with
-ea). - The fix check: 3 of 5 fail on stock, 5 of 5 pass with the fix, with
-eaand-da. :lucene:analysis:common:test --tests 'org.apache.lucene.analysis.th.*': 65 tests (56 upstream + 9 new) pass with-ea(seed 1A2B3C4D) and with-Ptests.asserts=false(seed 77AA77AA).- All of
:lucene:analysis:common:test: 1,918 tests including the 9 new ones, 18 skipped, 0 failed.TestRandomChains(:lucene:analysis.tests): 2 tests pass; random chains need not pick ThaiTokenizer. checkGoogleJavaFormatpasses on the patchedThaiTokenizer.java.- The finder's bounded-exhaustive check: 13,107 of 111,110 strings of up to 5 symbols lose a letter or digit on main, 0 with the fix. Its 10-symbol alphabet has no
#, currency sign or supplementary character, and it checks that letters and digits land in some token, not that the tokens are right; the fix-check oracle adds#,฿and$. - Scope: the suites ran on main only (OpenJDK 25.0.3, Linux aarch64, one seed per assertion mode). On releases the fix was checked only by the history step's 4.8.0 jar with the loop replaced.
Skip only segments without any letter or digit, but keep start, so the token is ฿1,500 or .2567.
Trade-offs
A smaller change in offsets, but TermQuery(f:2567) still misses พ.ศ.2567, and the terms differ from ICUTokenizer and StandardTokenizer. Not recommended.
What the checks validated
Not run.
C: workaround on released versions: split the prefix off with a char filter (validated by the checks)
Without patching Lucene, put a PatternReplaceCharFilter in front of the ThaiTokenizer chain that inserts a space between a prefix character and a digit, unless the prefix follows a digit (so 1.5 is untouched). Switching to ICUTokenizer (analysis-icu) also keeps the numbers, but segments Thai differently, so it is a reindex with different terms.
Pattern p = Pattern.compile("(?<!\\p{N})([.#\\p{Sc}])(?=\\p{N})");
// in Analyzer.initReader(field, reader):
return new PatternReplaceCharFilter(p, "$1 ", reader);
Trade-offs
Restores the number of every prefixed input in the table, with the same offsets as option A, and needs no Lucene change. But it is an application-side chain that must be used at index and at query time, documents already indexed need a reindex, it leaves a prefix after a digit alone (1#2, 1$2, 1฿2 still lose the 2), and it also changes the segmentation of other ./#/currency-digit pairs that follow a non-digit.
What the checks validated
On 10.5.2, 9.12.3 and main, with ThaiTokenizer + LowerCaseFilter + DecimalDigitFilter + StopFilter(ThaiAnalyzer.getDefaultStopSet()): all 11 prefixed inputs of the table get their number back with the same offsets as option A; 1.5, 50%, ราคา ¢50, ราคา 1,500 บาท and พ.ศ. 2567 are unchanged. On main it also works in front of a copy of the full stock ThaiAnalyzer chain, with ThaiCharFilter and the 10.6 ThaiNormalizationFilter and ThaiRepeatFilter; that copy without the extra char filter gives exactly ThaiAnalyzer's tokens and offsets.
An AI tool exploring ThaiTokenizer with user-dictionary words that contain periods saw a year go missing, confirmed it with a public-API JUnit and then checked all 111,110 strings of up to 5 symbols. Independent verifiers and a reviewer from another model family (OpenAI GPT-5.6) reproduced it with their own tests.
The method in full213 words
Method: targeted exploration, then a bounded-exhaustive check (the hunt's non-formal tier; no formal tool produced the first signal).
- The finder explored
ThaiTokenizerwith user-dictionary words that contain periods (พ.ศ.), noticed thatพ.ศ.2567lost its year, and wrote a public-API JUnit: 3 of 4 tests fail on main with-eaand-da, and on 10.5.2 and 9.12.3. - It then enumerated all 111,110 strings of 1 to 5 symbols over
{ก, า, 1, x, '.', ',', '-', space, U+0E48, U+0E4C}with the oracle "every letter or digit lies inside some token": 13,107 strings lose one on main (3,927 after a period, the rest after a tone or cancellation mark), 0 with the fix. The alphabet has no#or currency sign, and the oracle checks coverage, not that the tokens are right. That oracle is stronger than anything Lucene documents; the verdict rests on the number cases. - An independent reviewer from another model family (OpenAI GPT-5.6) ran its own checks (
release.2026gives[release],ปี.2026gives[ปี]). Claude verifiers wrote their own tests: the independent reproduction (ค.ศ.2024,ม.ค.67,page.42, a search) and the intended-behaviour check (฿1,500,$100,#3), which also found the JDK's number-prefix rule. An adjudication re-ran both with fresh seeds.
No report found (searched 2026-10-26). The nearest items are the change that introduced the loop (LUCENE-4984) and first-character shortcuts in other code (LUCENE-2404, LUCENE-5076); none reports this.
Searches5 searches
Novelty new: no issue, PR, JIRA entry, mailing-list thread, forum post or web page reports ThaiTokenizer, ThaiAnalyzer or a downstream thai tokenizer dropping a number after ., # or a currency sign, or questions the first-code-point test. Gaps: all searches match keywords, so a report written only in Thai or in a closed forum cannot be ruled out; private security reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene and migrated JIRA issues) | 2026-10-26 | 18 issue/PR and 3 commit queries with the prior-report tool; 121 GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, apache/lucenenet and all of GitHub | no report; LUCENE-4984 / #6048 introduced the loop (none of its 13 comments is about numbers) |
| Downstream repositories | 2026-10-26 | Elasticsearch, OpenSearch and Solr issues; GraphQL searches | adoption issues for the 10.6 Thai changes; no number loss |
| Mailing lists (dev@, java-user@, issues@, commits@) and the LUCENE JIRA archive | 2026-10-26 | 32 list queries, 8 + 4 JIRA queries | nothing |
| Web | 2026-10-26 | 15 queries, 2 in Thai; 7 pages read | a forum thread and a Q&A about keeping # as a token (no number lost) |
| Open PRs and recent commits | 2026-10-26 | changed paths of all 413 open apache/lucene PRs; Thai file history on main and branch_10x | no PR touches the Thai package; the loop is unchanged |
Introduced by LUCENE-4984 (6e2f6a69eb0, 2014-03-21), first released in 4.8.0: 4.7.2 keeps the numbers, 4.8.0 drops them, and the 4.8.0 jar with only the loop replaced keeps them. Every release since, through 10.5.2 and main, is affected.
Versions tested7 rows
LUCENE-4984 (issue #6048 "Fix ThaiWordFilter"; commit "LUCENE-4984: Fix ThaiWordFilter, smartcn WordTokenFilter"; patch by Robert Muir, +1 from two other committers) added ThaiTokenizer with this loop and switched ThaiAnalyzer to it: trunk 6e2f6a69eb0 (svn r1579846) and the branch_4x backport 72a0e1d09e4 (svn r1579855), which shipped in 4.8.0. There was no PR (pre-GitHub). The loop was later only reformatted (8ef6a0da568, LUCENE-9570); the 2026 Thai changes (#16722, #16727, b304eeae024, on branch_10x backported as 361da20c595) do not touch it.
In 4.8-5.x a matchVersion below 4.8 still selected the old, unaffected chain; LUCENE-5969 removed it for 6.0. All 107 release tags from 4.8.0 to 10.5.2 contain one of the two introducing commits. The record runs used JDK 25.0.3; OpenJDK 11 and 17 segment every input of the table the same way; the Java 7/8 JREs of 2014-era users were not tested.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | the repro fails 3 of 4 with -ea and -da (seeds 1A2B3C4D and 0FAC7C25); TermQuery 2567: 0 hits |
| 9.12.3, 10.5.2 | affected | the repro fails 3 of 4 (same messages); every table row gives the same terms as on main |
| 4.8.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4 | affected | version probe: พ.ศ.2567 -> [พ, ศ], ราคา ฿1,500 -> [ราคา], abc.123 -> [abc], TermQuery 2567: 0 hits |
| 4.7.2 (last before) | not affected | [พ, ศ, 2567], [ราคา, 1,500], [abc, 123], 1 hit (StandardTokenizer + ThaiWordFilter) |
| 4.8.0 with matchVersion LUCENE_47 | A/B | the old chain on the same jar keeps the numbers |
| 4.8.0 with only the skip loop replaced | A/B | keeps the numbers: the loss comes from the loop |
| main with fix A | fix | the repro passes 4 of 4; all of analysis-common, 1,918 tests including the 9 new ones (18 skipped), runs with 0 failures |
Reproduced on main with and without assertions and on 10.5.2 and 9.12.3; confirmed by independent verifiers, cross-model reviews and an adjudication, each from its own runs or reading; fix A validated with gradle.
Checks and verdicts437 words
Each check worked from the code or its own runs. Fact checks of this page's brief and a diagram check ran on 2026-10-26; their corrections are applied (see the last item).
| Check | Verdict | What it found |
|---|---|---|
| Finder's JUnit | candidate | TestThaiTokenizerNumberAfterPeriod: 3 of 4 fail on main with -ea and -da, on 10.5.2 and on 9.12.3; passes 4 of 4 with the fix, and 37 tests of four upstream Thai suites pass with it. |
| Cross-model refute review (OpenAI GPT-5.6, executed) | real, high confidence | Its own checks (release.2026, ปี.2026) fail on main with -ea and -da; the fix makes them pass. Intended-behaviour argument rated moderate. |
| Independent reproducer | real | Own JUnit: 4 of 8 fail on main, 10.5.2 and 9.12.3; its own loop-only patch fixes all 8 with correct offsets; ICUTokenizer and StandardTokenizer keep the numbers; the 4.10.4 old chain keeps them. |
| Works-as-designed review (OpenAI GPT-5.6, reading only) | real, medium confidence | Root cause agreed, inputs in contract; a separate run re-ran the finder's JUnit on main -ea, main -da and 10.5.2 (3 of 4 fail each). |
| Intended-behaviour devil's advocate | real, high confidence | No intended or misuse argument survives; found the JDK number-prefix rule; its currency test fails 3 of 4 on main, 10.5.2 and 9.12.3 and passes with the fix. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test (seed C0FFEE02: 4 of 8 fail, -ea and -da) and the intended-behaviour check's (3 of 4 fail). |
| Security screen | none | Recall loss only: linear work, CheckIndex clean, the loss stays in the prefixed segment, a keyword-field restriction still applies. |
| Brief runs | fails 3 of 4 on main, 10.5.2, 9.12.3; fix passes | The page's repro through the repro runner and gradle; the fix check, the Thai suites, all analysis-common tests and the format check with fix A; the workaround on three versions. |
| Fact checks of this page and its diagram | bug confirmed; text corrected | A fact check re-ran the repro at a fresh seed (harness and gradle, assertions on and off, main, 10.5.2 and 9.12.3), the fix with the analysis-common suite, its own probes and ICUTokenizer; a second came from an independent reviewer from another model family (OpenAI GPT-5.6) that read the files and run logs only; a diagram check re-ran the section 7 inputs on nine releases. All confirmed the bug, the mechanism, the history and the fix; their corrections of counts, scope, citations and wording are applied, and new runs close the gaps they found (all table inputs on three JDKs and three Lucene versions, the workaround with the full main chain). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 409 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,279 words
- Registry title
- ThaiTokenizer and ThaiAnalyzer silently drop a number written directly after a period, '#' or currency sign (2567 in 'พ.ศ.2567', 1,500 in 'ราคา ฿1,500', 42 in 'page.42'), because a word segment is skipped whole when its first character is not a letter or digit
- Area
- analysis / Thai (ThaiTokenizer#incrementWord skip loop; ThaiAnalyzer and the 'thai' tokenizer SPI)
- Priority
- Medium, rank 31: Since 4.8.0 the stock ThaiAnalyzer and ThaiTokenizer silently drop numbers written after a period, '#' or currency sign (baht amounts, Thai dates written without a space), ordinary Thai text that needs a reindex once fixed, limited to Thai-language indexes.
- Impact class
- silent wrong results
- Impact note
- Anyone who indexes or searches Thai text with the stock ThaiAnalyzer, ThaiTokenizer or the 'thai' tokenizer SPI at default settings silently loses every number that the JDK word BreakIterator returns in one segment with a leading period, '#' or currency sign (every currency sign except the cent sign): Thai dates written without a space ('พ.ศ.2567', 'ค.ศ.2024', 'ม.ค.67'), amounts even after a space ('ราคา ฿1,500', 'ราคา $100'), item numbers ('ข้อ #3'), leading-period decimals ('.5') and Latin text such as 'page.42' or 'No.5'; a TermQuery for the number then misses the document, deterministically at any index size, with -ea and -da, in every release from 4.8.0 (2014) to 10.5.2, while numbers that start with a digit ('1.5', '1,500') and spaced dates ('พ.ศ. 2567') are unaffected, nothing throws and the index stays well formed.
- Summary
- You index Thai text such as 'ประชุมวันที่ 1 ม.ค.2567' or 'ราคา ฿1,500' with the stock ThaiAnalyzer and expect the year 2567 or the amount 1,500 to be searchable, as they are when written 'พ.ศ. 2567' or 'ราคา 1,500 บาท'. Instead the number never reaches the index: the JDK word BreakIterator returns it together with its leading period or currency sign as one segment ('.2567', '฿1,500'), and ThaiTokenizer skips any segment whose first character is not a letter or digit, so the whole number is thrown away. A TermQuery for 2567 then finds 0 documents instead of 1, with no error.
- Introduced
- 6e2f6a69eb0adbefe90798b178e51539ab81aeca (trunk, svn r1579846; LUCENE-4984 / GitHub #6048 'Fix ThaiWordFilter', ThaiTokenizer patch by rmuir, +1 from rjernst and s1monw; pre-GitHub, no PR) and its branch_4x backport 72a0e1d09e421b3cb76dbadd743ec9449ad701d8 (svn r1579855), which shipped in 4.8.0; the commit added ThaiTokenizer with the first-code-point skip loop and switched ThaiAnalyzer to it [read: git blame of ThaiTokenizer.java:173-180 (lines 175-177 only reformatted by 8ef6a0da568, LUCENE-9570; git blame -w -M -C on its parent gives 6e2f6a69eb0 for the whole loop); exec: 4.7.2 keeps the numbers and 4.8.0 drops them on the same JDK, the 4.8.0 jar with matchVersion LUCENE_47 keeps them, and the 4.8.0 jar with only the skip loop replaced keeps them] (2014-03-21 (trunk commit and branch_4x backport))
- First affected version
- 4.8.0 [exec] (4.7.2, the last release before, has no ThaiTokenizer, and its ThaiAnalyzer, StandardTokenizer + ThaiWordFilter, keeps the numbers [exec])
- Affected versions
- every release from 4.8.0 to 10.5.2 (the last release before 10.6.0) and main ea57360912ed: 4.8.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3 and 8.11.4 [exec: main() probes, -da], 9.12.3, 10.5.2 and main [exec: probe -da and the finder's JUnit, 3 of 4 fail; the independent reproduction, the intended-behaviour check and the refute reviewer also reproduced on 9.12.3 and 10.5.2]; all 107 release tags from 4.8.0 to 10.5.2 contain one of the two introducing commits and the loop is identical, ignoring whitespace, in the inspected tags 4.8.0 to 10.5.2 [read]; in 4.8-5.x matchVersion < 4.8 still selected the old, unaffected chain (removed for 6.0 by LUCENE-5969); not fixed upstream: the loop is unchanged on main and branch_10x (newest ThaiTokenizer.java commit b304eeae024, 2026-09-29) and no open PR touches the Thai package [read-only check 2026-10-26]. JRE caveat: the drop needs the JDK word BreakIterator to keep the prefix and the number in one segment; executed on JDK 25.0.3, with supplementary runs on OpenJDK 11.0.33 and 17.0.21 that segment the same way; the Java 7/8 JREs of 2014-era users were not tested
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-26, read-only: a scripted prior-report search with 73 queries (18 GitHub issue/PR, 3 commit, 2 downstream-repo, 32 mailing-list over dev@, java-user@, issues@ and commits@, 8 JIRA, 10 web), 121 GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, apache/lucenenet, elastic/elasticsearch, opensearch-project and all of GitHub, 4 direct JIRA queries, 5 extra web queries (2 in Thai), the changed paths of all 413 open apache/lucene PRs, and the commit history of the Thai files on main and branch_10x; 57 GitHub items and 7 web pages read in full; the finder's, the independent reproduction's, the cross-model review's and the intended-behaviour check's own searches found nothing either). Not fixed upstream: the skip loop is unchanged on main and branch_10x and no open PR touches the Thai package or SegmentingTokenizerBase. Nearest items, none a report of this bug: LUCENE-4984 / #6048 (introduced the loop; none of its 13 comments discusses numbers or punctuation-led segments), LUCENE-2404 / #3479 (2010: rmuir on the since-removed ThaiWordFilter 'cheating with the UnicodeBlock check on charAt(0)'), LUCENE-5076 / #6140 (open: a first-code-point-only word test in ICU-module code, called a bug by a committer; that code no longer exists and ThaiTokenizer is not mentioned). Gaps: keyword search only, so a report written only in Thai or in a closed forum cannot be ruled out; private reports to security@lucene.apache.org are not visible.
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26) on JDK 25.0.3: the JUnit repro through the repro runner with -ea and -da, and through gradle in a scratch worktree, stock and with the fix (the worktree was removed after the runs); the same repro on the 10.5.2 and 9.12.3 jars; the history step's version probes on 4.7.2, 4.8.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3 and 8.11.4; the segmentation of every input in the table also on OpenJDK 11.0.33 and 17.0.21; the fact checks re-ran the repro at a fresh seed on main, 10.5.2 and 9.12.3, with -ea and -da.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiTokenizer.java:29-37 (class javadoc: uses BreakIterator, JRE warning, ICUTokenizer as the portable alternative), :173-180 (skip loop: comment 'skipping over non-tokens', Character.isLetterOrDigit on the first code point only)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:34 (class javadoc) and :101-109 (createComponents starts with ThaiTokenizer)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiTokenizerFactory.java:44 (SPI name 'thai')lucene/analysis/common/src/test/org/apache/lucene/analysis/th/TestThaiAnalyzer.java:131-135 (testDigits: digits are indexed)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiTokenizer.java:46-47, 135, 166-221 (word BreakIterator; incrementWord; skip loop 173-180)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-109 (createComponents)JDK 25 sources: java.base/sun/text/resources/BreakIteratorRules.java:100-102, 136-139; jdk.localedata/sun/text/resources/ext/BreakIteratorRules_th.java:64, 73
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiTokenizerFactory.java:39-44 (SPI name thai)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-109grep of non-test sources under lucene for ThaiTokenizer / ThaiAnalyzer (only the th package and module-info); lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:102, ThaiTokenizerFactory.java:74
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiTokenizer.java:28-38, 173-180lucene/analysis/common/src/test/org/apache/lucene/analysis/th/TestThaiAnalyzer.java:131-135 (testDigits)lucene/analysis/icu/src/java/org/apache/lucene/analysis/icu/segmentation/ICUTokenizer.java:209-214JDK 25 sources: java.base/sun/text/resources/BreakIteratorRules.java:100-102, 136-139; java/text/BreakIterator.java class javadoc (nextWordStartAfter)lucene/analysis/smartcn/src/java/org/apache/lucene/analysis/cn/smart/HMMChineseTokenizer.java:65-76; lucene/analysis/common/src/test/org/apache/lucene/analysis/util/TestSegmentingTokenizerBase.java:238-251
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:102-107, 119-123 (the chain with the 10.6 filters, and ThaiCharFilter, on main)
- TestThaiAnalyzerNumberAfterPeriod.java (JUnit test):
repro/LFV-225/src/org/apache/lucene/analysis/th/TestThaiAnalyzerNumberAfterPeriod.java(31 lines)
A summary diagram (PNG). The diagram is produced separately from this text. Its footnote names the finder's JUnit TestThaiTokenizerNumberAfterPeriod, an earlier public-API repro of the same bug (its testSearchByYear is the user code shown); the repro on this page is TestThaiNumberAfterPrefix. A diagram check re-ran the release inputs of its section 7.
assets/LFV-225/bug.png(409 KB)