Each group comes back with a page of its documents and maxScore, its best score. Since 10.5.0, with the default relevance order inside groups, that best score is read from the first document of the requested page. On page 1 that is right; on a later page it is that page's first score, lower than the best unless the two tie, or -Infinity when the page is empty.
- You index each group as one block of adjacent documents and mark the last one;
GroupingSearch(groupEndQuery)then groups the hits in a single pass. - For each group it returns a page of documents:
setGroupDocsOffset(n)skips the group's n best documents andsetGroupDocsLimit(m)returns the next m. - Each group also carries
maxScore, documented as "Max score in this group", andTopGroups.maxScoreis the "Highest score across all hits". Applications use them to normalise or display scores.
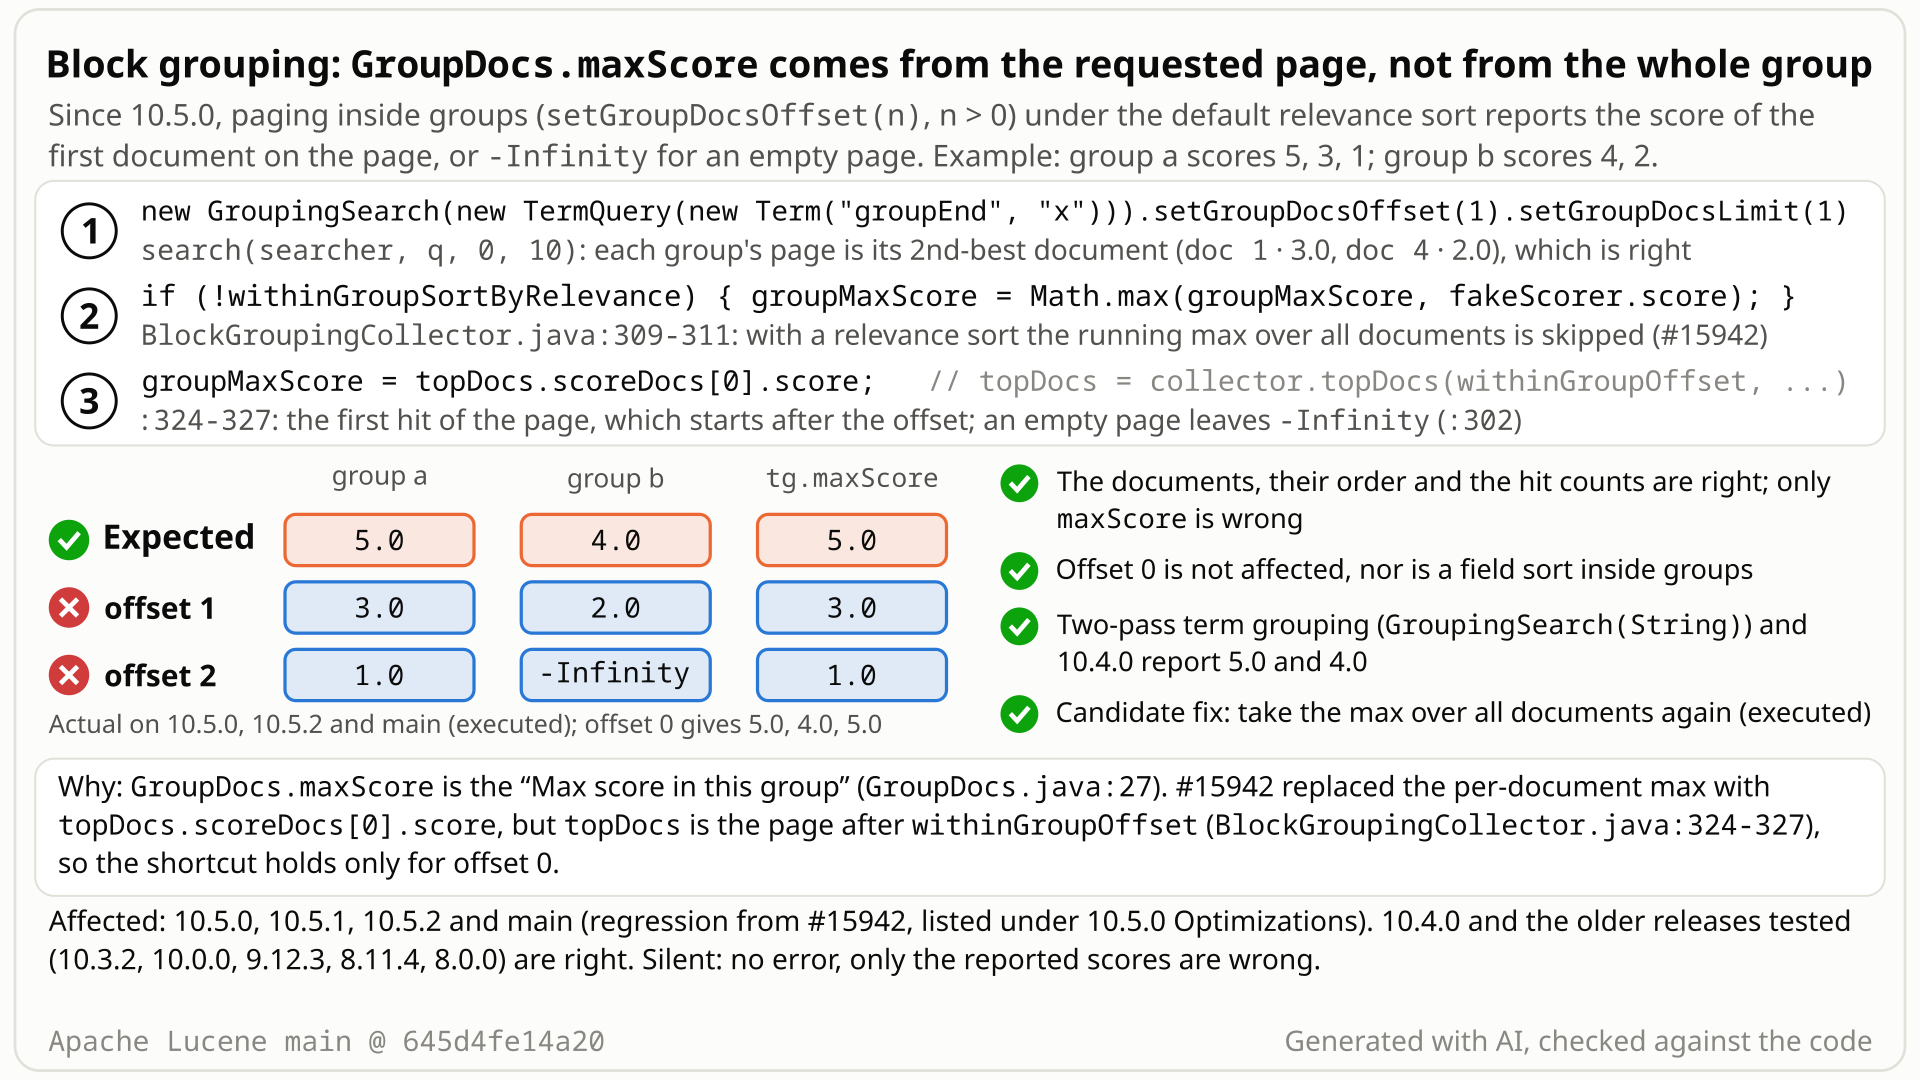
- Index two groups as document blocks: group a with scores 5, 3, 1 and group b with scores 4, 2. Search them with
GroupingSearch(groupEndQuery)and the default sorts (relevance). - Ask for page 2 inside each group, 2 documents per page:
setGroupDocsOffset(2).setGroupDocsLimit(2). The pages come back right: group a's third document (score 1), and nothing for group b, which has 2 hits. - You expect each group's
maxScore, documented as "Max score in this group", to stay 5 and 4, andTopGroups.maxScoreto be 5. That is what 10.4.0 and two-pass term grouping report. - Instead 10.5.0 and later report 1 and -Infinity, and 1 overall. With offset 1 they report 3 and 2: always the score of the first document on the page.
- Why: since 10.5.0 the relevance case skips the per-document maximum and reads the top hit of the page, which starts after the offset. An empty page keeps the starting value, -Infinity.
Block grouping users who keep the default relevance order inside groups, page inside groups (offset above 0) and read maxScore. It is silently wrong whenever the page's first document scores below the group's best (with distinct scores, always) and -Infinity for every empty page. Rare: a code search found no block grouping use in Solr, Elasticsearch or OpenSearch.
Mechanism, terms and numbers451 words
With block grouping (GroupingSearch(Query groupEndDocs), BlockGroupingCollector or BlockGroupingCollectorManager) and the default relevance order inside groups, a request for a later page inside each group (setGroupDocsOffset(n), withinGroupOffset > 0) reports each group's maxScore as the score of the first document on that page, or -Infinity when the page is past the end of the group, and TopGroups.maxScore inherits the wrong value. GroupDocs.maxScore is documented as "Max score in this group" and TopGroups.maxScore as "Highest score across all hits". The cause is #15942 (first released in 10.5.0), an optimisation that reads the group maximum from the top hit of the page; that is right only for offset 0, the default. In the repro, blocks with scores 5, 3, 1 and 4, 2 and page 2 at 2 per page give maxScores 1 and -Infinity (1 overall) instead of 5 and 4 (5 overall). The returned documents, their order and the hit counts are correct.
- Block grouping: documents of one group are indexed together with
IndexWriter.addDocuments, and a query (groupEndDocs) matches the last document of each block.GroupingSearch(Query)builds aBlockGroupingCollectorManagerfor it (GroupingSearch.java:221-237). - Within-group page:
withinGroupOffset(setGroupDocsOffset) and the page size (setGroupDocsLimit); the package docs describe the offset as "which 'slice' of top documents you want to retrieve from each group" (package-info.java:45-46). - maxScore:
GroupDocs.maxScore, "Max score in this group" (GroupDocs.java:27);TopGroups.maxScore, "Highest score across all hits, or Float.NaN if scores were not computed" (TopGroups.java:59).
GroupingSearch.groupByDocBlockpassesgroupDocsOffsetaswithinGroupOffsetandgroupDocsOffset + groupDocsLimitasmaxDocsPerGroup(GroupingSearch.java:234-235); the manager callsgetTopGroups(withinGroupSort, 0, withinGroupOffset, maxDocsPerGroup)(BlockGroupingCollectorManager.java:152).- In
BlockGroupingCollector.getTopGroups,groupMaxScorestarts atFloat.NEGATIVE_INFINITY(BlockGroupingCollector.java:302). The loop over the group's documents takesMath.maxonly when the within-group sort is not relevance (:309-311, added by #15942). topDocs = collector.topDocs(withinGroupOffset, maxDocsPerGroup)(:324) is the requested page, which starts after the offset. For a relevance sort,groupMaxScore = topDocs.scoreDocs[0].score(:325-327, added by #15942): the (offset+1)-th best score. An empty page assigns nothing, so-Infinitystays.TopGroups.maxScoreisgroups[0].maxScore()with a relevance group sort (:344-346) or the maximum of the per-group values otherwise (:339-341), so it inherits the wrong per-group values.
- Only
GroupDocs.maxScoreandTopGroups.maxScoreare wrong. The pages, their order, the per-group hit counts and the group order match an exact model (an executed probe: 40 random indexes per target, some with several segments, with random deletions and a FILTER clause). - A field sort inside groups still takes the maximum over every document and is right.
- Offset 0, the default, is right.
Exposure and likelihood255 words
- Who is hit. Code that pages inside block groups under relevance order and normalises or shows scores per group (score / maxScore) or uses
TopGroups.maxScore. The value is wrong, deterministically, whenever the first document on the requested page scores below the group's best (with distinct scores, every group on every such page), and it is-Infinityfor every empty page. It is right when that document ties the group's best: with tied top scores (groups 5, 5, 1 and 4, 4, offset 1, 2 per page) block grouping reports 5, 4 and 5 on main (executed). With constant-score or filter-only queries every document ties, so there only the empty pages are wrong. - Default or opt-in. Relevance order inside groups is the default (
GroupingSearch.java:51-52); paging inside groups is opt-in (default offset 0, unaffected). - Effect. A lower number than the real maximum, or
-Infinityfor a group that has hits. Scores normalised by it are relative to the page, not the group: the page's first hit gets 1 (with offset 1, 3/3 instead of 3/5), and only a score from an earlier page of the group would get a ratio above 1. A positive score divided by-Infinitygives -0.0. No error. - Scale. None needed: 5 documents in the repro.
- How likely: rare. A GitHub code search (exact class names, default branches) found no use of
BlockGroupingCollectororBlockGroupingCollectorManagerin Solr, Elasticsearch or OpenSearch; it cannot see private applications. The bug has shipped only since 10.5.0, and the searches below found no user report.
The test shows that block grouping (GroupingSearch(Query groupEndDocs), default relevance sorts) reports the wrong GroupDocs.maxScore when paging inside groups with setGroupDocsOffset(1).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.grouping;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.ConstantScoreQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.MatchAllDocsQuery;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBlockGroupingMaxScoreOffset extends LuceneTestCase {

  public void testMaxScoreWithGroupDocsOffset() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document top = new Document();
      top.add(new StringField("id", "top", Field.Store.NO));
      Document end = new Document();
      end.add(new StringField("groupEnd", "x", Field.Store.NO));
      w.addDocuments(List.of(top, end));
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        Query query =
            new BooleanQuery.Builder()
                .add(MatchAllDocsQuery.INSTANCE, Occur.SHOULD)
                .add(new ConstantScoreQuery(new TermQuery(new Term("id", "top"))), Occur.SHOULD)
                .build();
        GroupingSearch grouping = new GroupingSearch(new TermQuery(new Term("groupEnd", "x")));
        grouping.setGroupDocsOffset(1);
        TopGroups<?> result = grouping.search(new IndexSearcher(reader), query, 0, 10);
        // expected 2.0, the best score in the group; actual 1.0, the first score on the page
        assertEquals("group maxScore", 2f, result.groups[0].maxScore(), 0f);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-230/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.grouping.TestBlockGroupingMaxScoreOffset
- Expected vs actual
- Expected the best score in the group,
2.0; actual:1.0, the score of the first document on the requested page (group maxScore expected:<2.0> but was:<1.0>), with-eaand-da.
More files, environment, full output35 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: group maxScore expected:<2.0> but was:<1.0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
org.apache.lucene.search.grouping.TestBlockGroupingMaxScoreOffset.testMaxScoreWithGroupDocsOffset(TestBlockGroupingMaxScoreOffset.java:58)- The contracts mean the whole group:
GroupDocs"Max score in this group",TopGroups.maxScore"Highest score across all hits". - Two-pass grouping,
TopGroups.mergeand block grouping up to 10.4.0 all take the maximum before the offset. - #15942 is listed under Optimizations with no change in meaning, and -Infinity for a group with 2 hits cannot be meant.
The full argument190 words
- Contracts.
GroupDocs.java:27"Max score in this group" (the same record'stotalHitscounts every hit of the group);TopGroups.java:59"Highest score across all hits";GroupingSearch.java:330"Whether to include the score of the most relevant document per group". - Legal trigger.
package-info.java:45-46documentswithinGroupOffset, the block example at:129-137passesdocOffset, andBlockGroupingCollectorManager.java:93documents and:120-122validates it. - Siblings. Two-pass
TopGroupsCollector.java:177-190readsallTopDocs.scoreDocs[0]and then slices fromwithinGroupOffset;TopGroups.merge(#15879, by the same author) readsmergedTopDocs.scoreDocs[0](TopGroups.java:239-246) before slicing bydocOffset(:250-260). - History. Block grouping reported the group maximum in every release run from 8.0.0 to 10.4.0 (8.0.0, 8.11.4, 9.12.3, 10.0.0, 10.3.2, 10.4.0; executed). The releases in between were not run; none of them contains the #15942 backport.
- Intent.
lucene/CHANGES.txt:1093lists #15942 under 10.5.0 Optimizations. Its PR text: "For thegroupMaxScore, we can get the maxScore from the top scoreDoc in the merged top docs", which is equivalent only for offset 0. The commit changed onlyBlockGroupingCollector.javaandCHANGES.txt, with no test. - Why tests missed it.
TestGrouping.java:1632-1633has the maxScore comparison as a commented-out TODO since 2011;TestBlockGroupingandTestGroupingSearchnever assertmaxScore.
The devil's-advocate check130 words
The strongest case for "intended" (the works-as-designed reviewer from another model family, OpenAI GPT-5.6, and the intended-behaviour devil's advocate): #15942 was a deliberate, reviewed change; the grouping API is @lucene.experimental; no test pins maxScore with an offset; and maxScore could be read as the best score on the returned page.
Why it fails: every javadoc says whole group or all hits; experimental allows API changes, not values that contradict their own javadoc; the same optimisation on the two other paths takes the maximum before the offset; the CHANGES entry announces no change in meaning; and -Infinity for a group with 2 hits is not a page maximum either. The refute reviewer and the works-as-designed reviewer rated the intended argument weak; the devil's advocate concluded that no intended argument survives.
Recommended Keep the shortcut only when the page starts at the group's first document
Use the page's top hit only when the page starts at the group's first document: set maxScoreFromFirstHit = withinGroupSortByRelevance && withinGroupOffset == 0 and take the per-document maximum whenever it is false. This keeps #15942's saving for offset 0. Validated on main: the repro passes, as do all 57 grouping tests and check.
// The first hit of a relevance-sorted page is the group's best hit only if the page starts at
// the group's first document
final boolean maxScoreFromFirstHit = withinGroupSortByRelevance && withinGroupOffset == 0;
...
  if (!maxScoreFromFirstHit) {
    groupMaxScore = Math.max(groupMaxScore, fakeScorer.score);
  }
...
if (maxScoreFromFirstHit && topDocs.scoreDocs.length > 0) {
  groupMaxScore = topDocs.scoreDocs[0].score;
}
All options and trade-offs3 options · 450 words
Two fixes were validated; a third was not built. Either validated fix also corrects TopGroups.maxScore, which reads the per-group values. That holds for a search with one slice: the separate TopGroups.mergeBlockGroups problem with an executor and several slices (LFV-239, TopGroups.java:404-420) is not touched by either.
Keep the shortcut only when the page starts at the group's first document (validated by the checks) (recommended)
In BlockGroupingCollector.getTopGroups (1 file, +5/-2). With offset 0 the page is never empty (a group has at least one hit and maxDocsPerGroup >= 1 is validated), so the shortcut stays exact there; for an offset above 0 the loop that already visits every document takes the maximum. The hunt's judge proposed this shape (the devil's advocate asked that a fix keep the offset-0 saving); it was first built and run for this doc.
// The first hit of a relevance-sorted page is the group's best hit only if the page starts at
// the group's first document
final boolean maxScoreFromFirstHit = withinGroupSortByRelevance && withinGroupOffset == 0;
...
  if (!maxScoreFromFirstHit) {
    groupMaxScore = Math.max(groupMaxScore, fakeScorer.score);
  }
...
if (maxScoreFromFirstHit && topDocs.scoreDocs.length > 0) {
  groupMaxScore = topDocs.scoreDocs[0].score;
}
Trade-offs
Keeps #15942's optimisation for the default offset 0; slightly more logic than a plain revert.
What the checks validated
Scratch worktree of 645d4fe14a20, gradle, JDK 25.0.3: stock + test 1 of 1 fails (assertions on and off); fix + test: the whole :lucene:grouping:test (15 suites, 57 tests, incl. TestBlockGrouping, TestGrouping, TestGroupingSearch, TestTopGroups) passes with -Ptests.asserts=true and false; :lucene:grouping:check -x test (google-java-format, ecjLint, forbiddenApis) succeeds. The finder's 3 tests (incl. the offset-0 control) and an independent 5-test suite (incl. three controls) pass with the fixed class.
Always take Math.max in the loop and drop the assignment from scoreDocs[0] (+1/-6). The value then no longer depends on the sort.
if (needsScores) {
  fakeScorer.score = og.scores[docIDX];
  groupMaxScore = Math.max(groupMaxScore, fakeScorer.score);
}
Trade-offs
Simplest. Gives up #15942's saving: one Math.max per document of each returned group, in a loop that runs anyway (not measured).
What the checks validated
The finder's fix: their test, the cross-model refute reviewer's own test and an independent 5-test suite pass; the refute review ran upstream TestBlockGrouping, TestGroupingSearch and TestTopGroups green; 10.5.2 with the #15942 hunks reverted passes. This doc's test passes with it.
Take collector.topDocs() once, read scoreDocs[0].score as the group maximum, then slice from withinGroupOffset, as TopGroupsCollector.java:177-190 does.
Trade-offs
Consistent with the sibling path, but more code, and the page is then built by slicing instead of topDocs(start, howMany), which a reviewer would have to check for equivalence.
A code search found no use of block grouping in Solr, Elasticsearch or OpenSearch, so only applications that call Lucene's block grouping directly see the wrong numbers.
While writing the reference model for a bounded-exhaustive grouping harness, the finder read #15942 and suspected the offset case. On the stock jar, the harness (tiny indexes, every segment split, every sort and page) then reported group-maxScore mismatches in block-grouping cases with a within-group offset above 0 and relevance order. The repro was reduced by hand.
The method in full139 words
Method: semi-formal (a hypothesis while writing a harness's exact reference semantics, then witnessed by the harness on the stock jar).
- Harness. A bounded-exhaustive translation-validation harness for grouping: tiny indexes with groups in {A, B, none} and values {0, 1, 2}, every split into segments, 7 slicings, every group sort x within-group sort x group page x document page, compared with an exact reference model and with two-pass term grouping.
- Signal. The kinds
BREF:GROUP_MAXSCORE,BLOCK_VS_TERM:GROUP_MAXSCOREandBDIST:GROUP_MAXSCOREreported mismatches in block cases with a within-group offset above 0 and a relevance within-group sort (scope block5: 19,683 indexes, 13,988,052 checks, 29 s; 1,208,571, 1,107,897 and 211,137 mismatches, counts not split by root cause). With the hunt unit's combined grouping fixes shadowed, theBREF:GROUP_MAXSCOREkind disappears. - Repro. Minimised by hand to two blocks; this doc's one-method test is a further reduction.
No prior report found (searched 2026-10-26, rechecked 2026-10-29): 61 tool queries over GitHub, commits, downstream repositories, four mailing lists, JIRA and the web, plus manual GitHub searches and the files of every open grouping PR. Closest: #15942 itself, which introduced it.
Searches3 searches
Related, not reports of this bug: #15942 (the change that introduced it; its one review does not discuss offsets); #15936 (BlockGroupingCollectorManager; its review fixed a different maxScore problem in TopGroups.mergeBlockGroups before merge); #15879 and open #16569 (the same optimisation in TopGroups.merge and TopGroupsCollector, both taking the maximum before the offset); #15872/#15873 (two-pass NaN maxScore for a group without hits, fixed); #15995 (TopGroupsCollectorManager ignored withinGroupOffset, fixed); #10039 (LUCENE-8996, shard-merge NaN maxScore, fixed 2019). Open #16847 touches the file but not these lines. Gaps: GitHub issue search does not index PR diffs (PRs were checked by file list); JIRA and list search are word-based; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs, commits and downstream repositories | 2026-10-26 | a scripted prior-report search (20 GitHub issue/PR, 4 commit, 3 downstream queries), the finder's earlier 10-query run, 13 manual GitHub searches (incl. every module:grouping item since 2026-03-15 and the file lists of all 7 open grouping PRs), API reads of #15942, #15879, #15936, #15995 and #16569 with their reviews | no report; the related items above |
| dev@, java-user@, issues@ and commits@ lists; JIRA archive; web | 2026-10-26 | 24 list queries through the tool and 16 direct list queries, 4 + 4 JIRA searches, 6 web searches | only automated mirrors of #15942, #15936, #15872 and #15995 |
| GitHub (recheck for this doc) | 2026-10-29 | upstream heads and file history on main, branch_10x, branch_10_6, branch_10_5; 5 searches; the changed files of all 73 PRs updated since 2026-10-26 | still unfixed; nothing new (one old branch-merge PR, closed unmerged, touches grouping files) |
Introduced by #15942 (56fa833e554 on main, backport 7a551555d54, 2026-04-27), first released in 10.5.0. Fails on 10.5.0, 10.5.1, 10.5.2 and main; passes on 10.4.0, 10.3.2, 10.0.0, 9.12.3, 8.11.4 and 8.0.0. Reverting only #15942's hunks on 10.5.2 makes it pass.
Versions tested6 rows
Introduced by #15942, "Skip max score computation when sorting by relevance in BlockGroupingCollector" (author gaobinlong; approved (2026-04-08) and merged (2026-04-27) by benwtrent, milestone 10.5.0): 56fa833e554 on main and 7a551555d54 on branch_10x, the same day. Its diff wrapped the existing Math.max (BlockGroupingCollector.java:310) in the relevance guard (:309-311) and added :325-327; git log -S and git blame -w identify it as the introducing change; git tag --contains 7a551555d54 lists exactly 10.5.0, 10.5.1, 10.5.2 and 10.6.0.
Older, different behaviour (context only): up to 7.x the group maximum came from TopDocs.getMaxScore(), right for a non-empty page but NaN for an empty one (7.7.3 executed). LUCENE-8405 (8.0.0) switched to the per-document maximum, correct until 10.4.0.
Upstream: main, branch_10x and branch_10_6 still have the lines on 2026-10-29. Not built: a commit-level bisect on main (the release bracket, the blame and the single-change revert pin it).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20, ea57360912ed | affected | 1, -Infinity, 1 instead of 5, 4, 5 (page 2); 3, 2, 3 with offset 1 |
| 10.5.0, 10.5.1, 10.5.2 | affected | same values |
| 10.5.2 with only #15942 reverted | not affected | passes 3 of 3 |
| 10.4.0 | not affected | passes (also this doc's test) |
| 10.3.2, 10.0.0, 9.12.3, 8.11.4, 8.0.0 | not affected | pass |
| 7.7.3 | partly | offset 1 right; empty page gives NaN (an older, different defect, gone since 8.0.0) |
An independent reproducer, reviews by another model family (OpenAI GPT-5.6, one executed), an intended-behaviour devil's advocate and an adjudication agree: real, high confidence. This doc re-ran a one-method repro on main 645d4fe14a20 and on releases, and validated the fix with gradle.
Checks and verdicts222 words
The works-as-designed review by the other model family ran reading-only; a separate run re-ran the finder's test (fails on main, 10.5.0 and 10.5.2, passes on 10.4.0). The refute-lens review executed its own test and the fix.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Harness group-maxScore mismatches in block cases with an offset above 0 and relevance order; JUnit fails on main (-ea, -da), 10.5.0, 10.5.2, passes on 10.4.0 and with the fix. |
| cross-model review, refute lens | real, high | OpenAI GPT-5.6, executed: own one-block test fails on main and 10.5.0, passes on 10.4.0; the fix passes it and upstream TestBlockGrouping, TestGroupingSearch, TestTopGroups. |
| Independent reproducer | real | Own 5-test suite fails 2 of 5 on main, 10.5.0, 10.5.2; passes on 10.4.0 and 9.12.3; three controls pass everywhere. |
| Cross-model review, works-as-designed lens | real, high | OpenAI GPT-5.6, reading-only; intended argument weak. |
| Intended-behaviour devil's advocate | real, high | Re-ran the finder's test; rebutted each intended argument. |
| adjudication | confirmed, high | Re-ran the independent reproduction's suite and the finder's test with fresh seeds, -ea and -da. |
| this doc | confirmed on 645d4fe14a20 | One-method repro fails via gradle and the standalone runner (-ea, -da) and on 10.5.0 and 10.5.2, passes on 10.4.0; the recommended fix passes the whole grouping module and check. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 557 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,200 words
- Registry title
- Block grouping reports the wrong group maxScore when paging inside groups (withinGroupOffset > 0, relevance order): the score of the first document on the page, or -Infinity for an empty page; regression in 10.5.0
- Area
- grouping / block grouping (BlockGroupingCollector.getTopGroups group maxScore; GroupingSearch(Query) and BlockGroupingCollectorManager within-group paging)
- Priority
- Low, rank 564: Since 10.5.0 block grouping that pages inside groups (withinGroupOffset > 0) under relevance order reports the first on-page document's score, or -Infinity for an empty page, as each group's maxScore, deterministic for those users but metadata only (documents and order are correct) in a block-grouping API with no known downstream use.
- Impact class
- silent wrong results
- Impact note
- Hits applications on 10.5.0-10.5.2, 10.6.0 (by reading) and main that use block grouping (GroupingSearch(Query groupEndDocs), BlockGroupingCollector or BlockGroupingCollectorManager) with the default relevance order inside groups and page inside groups (setGroupDocsOffset / withinGroupOffset > 0; the default 0 is unaffected): every such request silently reports GroupDocs.maxScore as the score of the first document on the requested page, or -Infinity for a group with hits whose page is empty, and TopGroups.maxScore inherits the wrong value, while the returned documents, their order, the hit counts and the group order stay correct, so only score normalisation or display based on maxScore goes wrong; no scale needed.
- Summary
- You index each group as a document block and search with GroupingSearch(Query groupEndDocs) and the default relevance sorts, asking for the second page of documents inside each group with setGroupDocsOffset(1). You expect each group's maxScore to be the best score in the group (GroupDocs documents it as 'Max score in this group'), as two-pass term grouping reports and as block grouping did up to 10.4.0. Since 10.5.0 it is instead the score of the first document on the requested page, or -Infinity when the page is past the end of the group, and TopGroups.maxScore inherits the wrong value; the documents returned are correct.
- Introduced
- 56fa833e554034a2e781da432b56ed09d0bc7ba4 (main) and its branch_10x backport 7a551555d54f82daf00c1ad5c0985e0e56e73af7: GITHUB#15942 'Skip max score computation when sorting by relevance in BlockGroupingCollector' by gaobinlong, approved (2026-04-08) and merged (2026-04-27) by benwtrent, listed under 10.5.0 Optimizations (CHANGES.txt:1060) [read: the #15942 diff wrapped the existing Math.max (BlockGroupingCollector.java:310) in the relevance guard (:309-311) and added :325-327; git log -S 'topDocs.scoreDocs[0].score' and git blame -w in the history clone identify it as the introducing change; exec: 10.4.0 passes, 10.5.0 fails, and 10.5.2 with only the #15942 hunks of BlockGroupingCollector reverted passes 3 of 3]. No commit-level bisect on main was built. (2026-04-27 (UTC; author date 2026-04-28 01:48 +0800), the same day on main and branch_10x)
- First affected version
- 10.5.0 [exec] (tag dated 2026-06-25; git tag --contains 7a551555d54 lists exactly 10.5.0, 10.5.1, 10.5.2 and 10.6.0); 10.4.0 is the last release without it [exec]
- Affected versions
- 10.5.0, 10.5.1 and 10.5.2 (every 10.5.x release), 10.6.0 (by reading, see below) and main ea57360912ed [exec]: the finder's JUnit fails 2 of 3 on all four (main with -ea and -da); the independent reproduction's own JUnit fails 2 of 5 on main (-ea and -da), 10.5.0 and 10.5.2; the refute reviewer's own test fails on main and 10.5.0. Upstream main, branch_10x, branch_10_6 and branch_10_5 still have the faulty lines as of 2026-10-26 [read, GitHub contents API and branch commit logs]. Not affected [exec]: 10.4.0, 10.3.2, 10.0.0, 9.12.3, 8.11.4 and 8.0.0 (finder's JUnit, mechanical API ports for 9.x and 8.x; the independent reproduction's suite on 10.4.0 and 9.12.3). Context, not this bug: 7.7.3 gives NaN for an empty page (an older defect from TopDocs.getMaxScore, gone since 8.0.0 with LUCENE-8405) while its offset-1 case is correct [exec]. Releases between the listed ones were not run; none contains the backport commit [read]. All runs on aarch64 with JDK 25.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, read-only, follow-up prior-report record verdict new: a scripted prior-report search with 61 queries (20 apache/lucene issue/PR, 4 commit, 3 downstream-repository, 24 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 6 web; 577 distinct hits, 1 high = #15942 (the introducing change), 16 medium, comments of the top 20 read), the finder's earlier scripted prior-report search (10 queries, 21 hits), 13 manual GitHub searches (among them every module:grouping issue and PR created since 2026-03-15 and the file lists of all 7 open module:grouping PRs), 16 direct list queries, 4 JIRA text searches and GitHub API reads of #15942, #15879, #15936, #15995 and #16569 with their reviews; the independent reproduction's and the intended-behaviour check's own searches found nothing either). Related, not this bug: #15942 (the introducing PR; its one review did not discuss offsets), #15936 (BlockGroupingCollectorManager; its review fixed a different maxScore problem in TopGroups.mergeBlockGroups before merge), #15879 and open #16569 (the same optimisation in TopGroups.merge and TopGroupsCollector, both taking the max before the offset), #15872/#15873 (two-pass NaN maxScore for a group without hits, fixed), #15995 (TopGroupsCollectorManager ignored withinGroupOffset, fixed), LUCENE-8996/#10039 (shard-merge NaN maxScore, fixed 2019). Not fixed upstream: upstream main, branch_10x, branch_10_6 and branch_10_5 still have the lines, and the one open PR touching the file (#16847) leaves them alone.
- Lucene commit tested
- main
645d4fe14a20(runs of 2026-10-29) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.0, 10.5.2 and 10.4.0 release jars. The fix was validated in the scratch worktree: the repro, the whole:lucene:grouping:test(57 tests) and:lucene:grouping:check -x test. Earlier hunt runs: mainea57360912ed(the grouping module is identical) and the finder's test on 10 releases from 7.7.3 to 10.5.2, plus 10.5.2 with only #15942 reverted.
- Finding record
lucene/grouping/src/java/org/apache/lucene/search/grouping/BlockGroupingCollector.java:274-275 (at ea57360912ed) (maxScore init, groupSortByRelevance), 285, 302 (groupMaxScore = NEGATIVE_INFINITY when scores are needed), 309-311 (per-document max skipped for a relevance within-group sort), 324-327 (topDocs(withinGroupOffset, maxDocsPerGroup), then groupMaxScore = topDocs.scoreDocs[0].score), 339-345 (TopGroups.maxScore from the per-group values or groups[0])lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupDocs.java:27 (at ea57360912ed) ('@param maxScore Max score in this group'); TopGroups.java:59 ('Highest score across all hits, or Float.NaN if scores were not computed'); GroupingSearch.java:56 (includeMaxScore = true), 221-235 (groupByDocBlock passes groupDocsOffset), 307-338 (setGroupDocsOffset, setIncludeMaxScore 'the score of the most relevant document per group'); BlockGroupingCollectorManager.java:93, 120-122, 152 (withinGroupOffset documented, validated >= 0, passed to getTopGroups)lucene/grouping/src/test/org/apache/lucene/search/grouping/TestGrouping.java:1632-1633 (at ea57360912ed) (commented-out maxScore comparison); lucene/CHANGES.txt:1060 (GITHUB#15942 under 10.5.0 Optimizations)
- The finding in 30 seconds
lucene/grouping/src/java/org/apache/lucene/search/grouping/BlockGroupingCollector.java:285, (at 645d4fe14a20) :292-294, :302, :305-314, :309-311, :324-327, :331-346lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:50-56, (at 645d4fe14a20) :221-237, :307-338; BlockGroupingCollectorManager.java:93, :120-122, :152lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupDocs.java:27; (at 645d4fe14a20) TopGroups.java:59; package-info.java:45-46
- Who is affected
lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:51-52, (at 645d4fe14a20) :231
- Why it looks unintended
lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupDocs.java:27, (at 645d4fe14a20) :33; TopGroups.java:38, :59, :239-260; GroupingSearch.java:44, :330; BlockGroupingCollector.java:61; BlockGroupingCollectorManager.java:93, :120-122; TopGroupsCollector.java:177-190; package-info.java:45-46, :129-137lucene/CHANGES.txt:898, (at 645d4fe14a20) :1039, :1093
- Suggested fix
lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroupsCollector.java:177-190 (at 645d4fe14a20)
- TestBlockGroupingMaxScoreOffset.java (JUnit test):
repro/LFV-230/src/org/apache/lucene/search/grouping/TestBlockGroupingMaxScoreOffset.java(62 lines)
A diagram, made in parallel with this doc.
assets/LFV-230/bug.png(557 KB)