In Thai, ๆ (Maiyamok) means "say the previous word again". A token's offsets are the [start, end) range of the original text it came from; highlighters put their markup there.
- Analyze
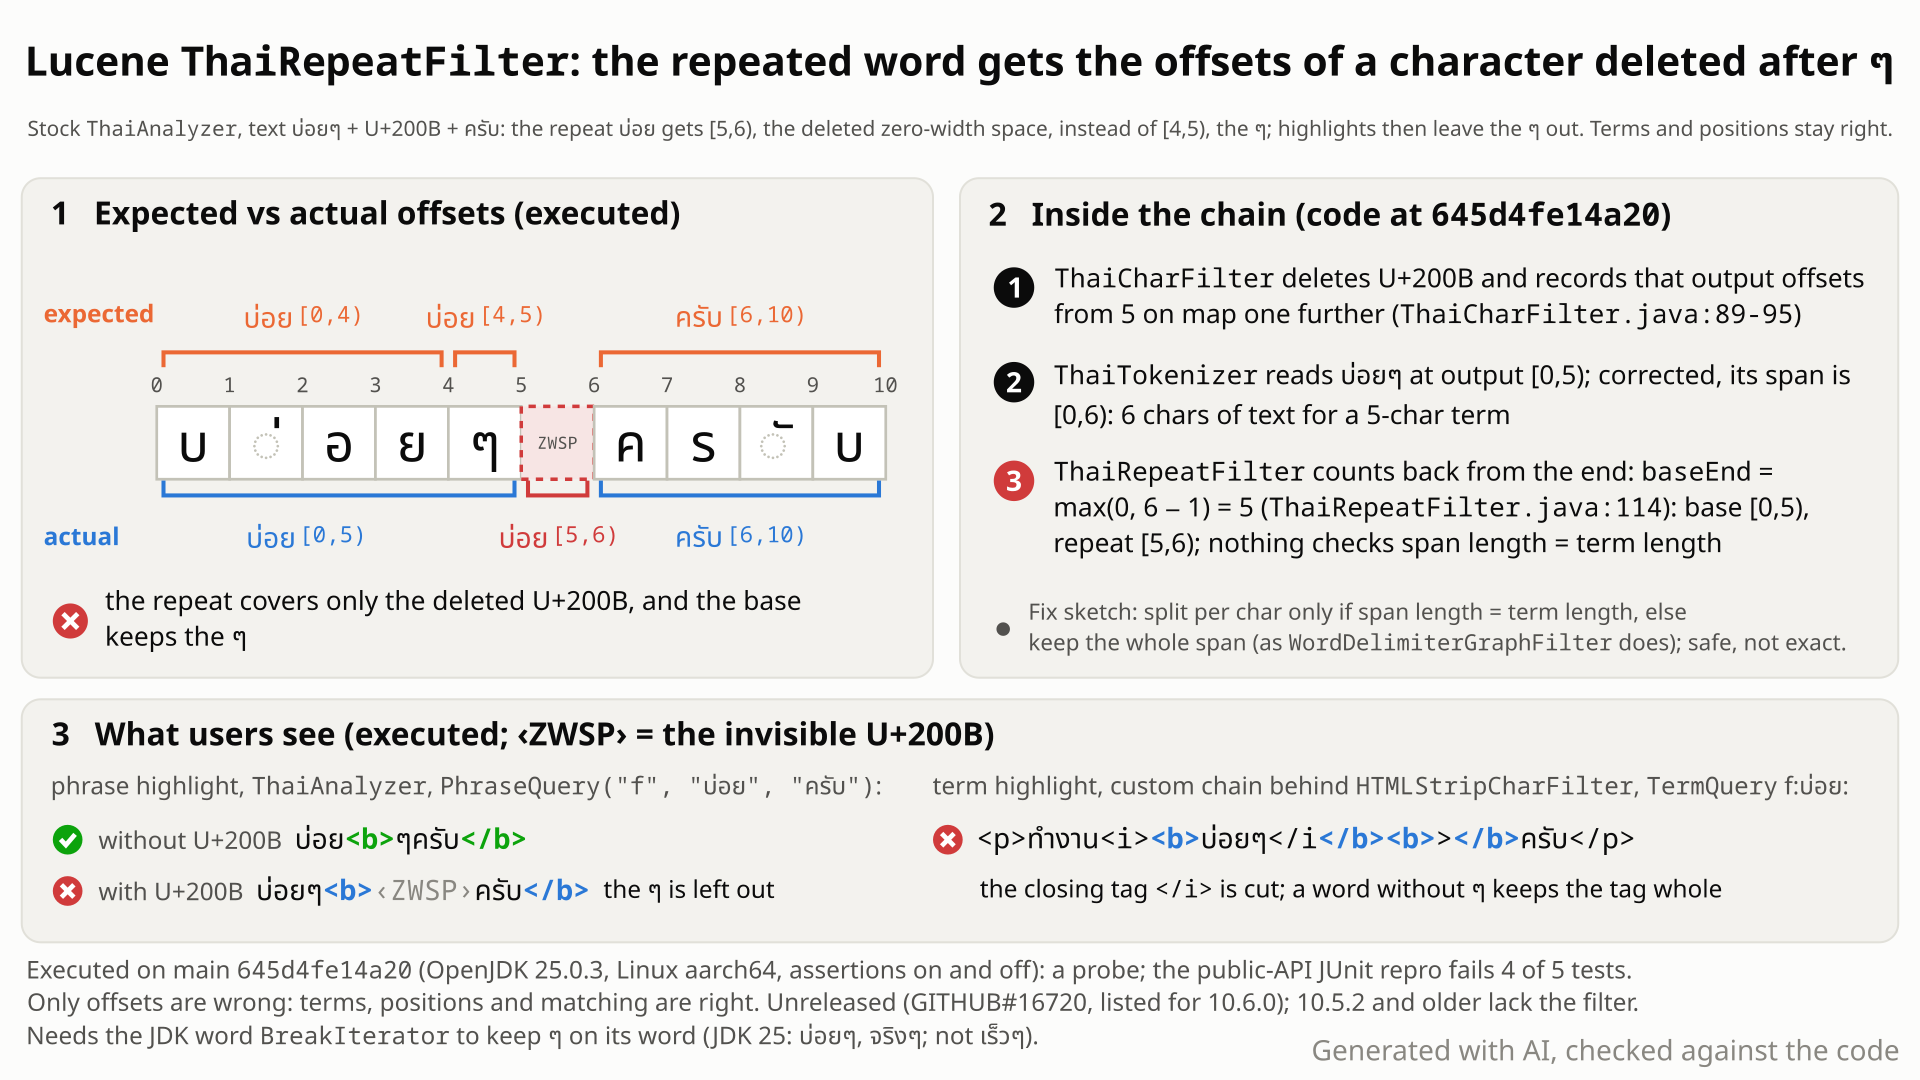
บ่อยๆ+ U+200B (a zero-width space) +ครับwith the stockThaiAnalyzerof 10.6.ThaiRepeatFilterturnsบ่อยๆ("often") into two tokensบ่อย: the word, and a repeat that stands for theๆat offset 4. - You expect what the same text without the zero-width space gives: the word at [0,4) and the repeat at [4,5), exactly the
ๆ. The filter's CHANGES entry promises "exact OffsetAttribute and highlighter compatibility". ThaiCharFilterfirst deletes the zero-width space, and Lucene's offset correction then ends the token after the deleted character:บ่อยๆreaches the filter as [0,6), 6 source characters for a 5-character term.ThaiRepeatFilterassumes the span's last character is theๆand counts back from the end: the word gets [0,5), which includes theๆ, and the repeat gets [5,6), only the deleted zero-width space.- Terms, positions and matches are right; highlights are not. A phrase highlight gives
บ่อยๆ<b>‹ZWSP›ครับ</b>(‹ZWSP› marks the invisible U+200B), with theๆleft out; behindHTMLStripCharFilterthe repeat gets the>of the next tag and the highlighter cuts it:<i><b>บ่อยๆ</i</b><b>></b>.
Users of the stock ThaiAnalyzer from 10.6.0 on, when a zero-width character follows a word with ๆ that the JDK keeps in one token (on JDK 25: จริงๆ, บ่อยๆ, ดีๆ, อื่นๆ), and custom chains with HTMLStripCharFilter before ThaiRepeatFilter. Only offsets and highlights are wrong; deterministic, any index size.
Mechanism, terms and numbers557 words
ThaiRepeatFilter (new in 10.6, #16720) expands the Thai repetition mark Maiyamok ๆ (U+0E46): บ่อยๆ becomes the token บ่อย plus a second บ่อย that stands for the ๆ. It computes their offsets by counting back from the end of the incoming span: the word gets [start, end - 1) and the repeat the last character (ThaiRepeatFilter.java:114-123 on main 645d4fe14a20). That is right only when the span maps 1:1 onto the term. The stock ThaiAnalyzer puts ThaiCharFilter in front (ThaiAnalyzer.java:119-123), which deletes zero-width characters (ThaiCharFilter.java:89-94), and CharFilter offset correction ends a token after the characters deleted right behind it (BaseCharFilter.java:40-53). So for บ่อยๆ + U+200B + ครับ the span is [0,6), the word gets [0,5) (which contains the ๆ) and the repeat [5,6), only the deleted zero-width space. Terms, positions, matching and scoring are correct; offsets in the index and highlights are wrong. Lucene's other offset-splitting filters keep the whole span when its length differs from the term's; this one has no such check.
- Maiyamok
ๆ(U+0E46): the Thai repetition mark.บ่อยๆ("often") is readบ่อย บ่อย.ThaiRepeatFilter(10.6, #16720) emits the word, then one copy perๆ, each copy at its own position with the offsets of itsๆ. - Offsets:
OffsetAttributestart and end, the range of the original text a token came from. They are stored with postings or term vectors and used by highlighters. - CharFilter: edits the text before the tokenizer sees it and records where, so the tokenizer can map offsets back (
correctOffset).ThaiCharFilter, which the stockThaiAnalyzeralways uses, deletes U+200B, U+200C, U+200D and U+FEFF;HTMLStripCharFilterdeletes markup.
Input offsets: บ0 ่1 อ2 ย3 ๆ4 U+200B 5 ค6 ร7 ั8 บ9.
ThaiAnalyzerbuildsThaiTokenizer->LowerCaseFilter->DecimalDigitFilter->ThaiNormalizationFilter->ThaiRepeatFilter->StopFilterand wraps every reader inThaiCharFilter(ThaiAnalyzer.java:101-109,:119-123).ThaiCharFilterdrops U+200B at output offset 5 and recordsaddOffCorrectMap(5, 1)(ThaiCharFilter.java:89-94). The tokenizer seesบ่อยๆครับ.BaseCharFilter.correct(off)adds the diff recorded at the largest offset<= off(BaseCharFilter.java:40-53), so the tokenบ่อยๆ, which ends at output offset 5, ends at source offsetcorrect(5)= 6: it arrives as[0,6). That widening is the long-known CharFilter end-offset behaviour (#6796, #7653) and harmless by itself: the span still covers the whole word.ThaiRepeatFilter(case 2,ThaiRepeatFilter.java:104-129) counts 1 trailingๆ, cuts the term toบ่อย, setsbaseEnd = Math.max(origStart, origEnd - maiyamokCount)= 5 (:114), gives the word[0,5)(:115) and the repeat[baseEnd, origEnd)=[5,6)(:118-123). Nothing comparesorigEnd - origStartwith the term length (:75-77).- For a token of two or more
ๆ(case 1,:79-102) the copies get one character each, counted from the start, the last ending atorigEnd(:87-96): the same one-character-per-ๆassumption. A single standaloneๆis not split: theif (count > 1)block (:87-100) is skipped and the token keeps its incoming span.
With HTMLStripCharFilter + ThaiTokenizer + ThaiRepeatFilter, บ่อยๆ</b>ครับ arrives as [0,9), so the word gets [0,8) = บ่อยๆ</b and the repeat [8,9) = >.
Exposure and likelihood287 words
- Default chain, no opt-in.
ThaiAnalyzeralways usesThaiCharFilterandThaiRepeatFilter. Any of U+200B, U+200C, U+200D or U+FEFF right after an attachedๆtriggers it.ThaiCharFilter's javadoc names zero-width characters among the typographic anomalies it exists to remove (ThaiCharFilter.java:27-30). - JDK-dependent reach. The JDK word BreakIterator must keep the
ๆin the word's token. On JDK 25.0.3 it does forจริงๆ,บ่อยๆ,ดีๆ,อื่นๆand not forเร็วๆ,มากๆ, whoseๆbecomes its own token. - Custom chains: chains with
ThaiRepeatFilter(SPI namethaiRepeat) where a CharFilter deletes characters right after a word ending inๆand the tokenizer keeps thatๆin the word's token, so the deleted characters land in the tail of the span. Executed withHTMLStripCharFilter(a tag right after the word is enough) andThaiCharFilter, also with a whitespace tokenizer and with two or moreๆ. - What breaks: offsets in postings, term-vector offsets and highlights. Terms, positions, matching, scoring and filtering are unchanged; nothing throws; every span stays inside the token's original span.
- How it shows: a phrase or other position-sensitive highlight of the repeated word leaves the
ๆout; a term query highlights both tokens, so it still covers theๆ. In raw-HTML highlighting the highlighter's tags land inside the following tag (</i+>).HTMLStripCharFilteralready mis-nests highlight markup before a closing tag for plain tokens (<i><b>abc</i></b>); ThaiRepeatFilter adds the cut in the tag text. Withescape=trueonly the highlight position is wrong. - Timing: in 10.6.0, released on 2026-10-29 from the RC1 revision.
- Downstream: Elasticsearch merged a
thai_repeatport of the filter into its Lucene-snapshot branch (elastic/elasticsearch#160853); opensearch-project/OpenSearch#23151 (open) plans one.
One JUnit method on the public API: the stock ThaiAnalyzer on one 10-character string, deterministic. It asserts only that the repeated token's span contains its ๆ at offset 4. It runs in lucene/analysis/common, with assertions on or off, and is also the regression test.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.th;

import java.io.IOException;
import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.tokenattributes.CharTermAttribute;
import org.apache.lucene.analysis.tokenattributes.OffsetAttribute;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestThaiRepeatFilterZeroWidthSpace extends BaseTokenStreamTestCase {

  public void testRepeatedTokenCoversMaiyamokAfterZeroWidthSpace() throws IOException {
    assumeTrue("needs the Thai BreakIterator", ThaiTokenizer.DBBI_AVAILABLE);
    // "บ่อยๆ" ("often", the Maiyamok ๆ at offset 4), U+200B ZERO WIDTH SPACE at offset 5
    // (ThaiCharFilter removes it), then "ครับ" at [6,10)
    String text = "บ่อยๆ\u200Bครับ";
    List<String> terms = new ArrayList<>();
    List<String> spans = new ArrayList<>();
    int repeatStart = -1;
    int repeatEnd = -1;
    try (Analyzer analyzer = new ThaiAnalyzer();
        TokenStream ts = analyzer.tokenStream("f", text)) {
      CharTermAttribute term = ts.addAttribute(CharTermAttribute.class);
      OffsetAttribute offset = ts.addAttribute(OffsetAttribute.class);
      ts.reset();
      while (ts.incrementToken()) {
        if (terms.size() == 1) { // the second token: the repetition that ๆ stands for
          repeatStart = offset.startOffset();
          repeatEnd = offset.endOffset();
        }
        terms.add(term.toString());
        spans.add("[" + offset.startOffset() + "," + offset.endOffset() + ")");
      }
      ts.end();
    }
    assertEquals(List.of("บ่อย", "บ่อย", "ครับ"), terms);
    assertTrue(
        "the repeated token must cover the Maiyamok at offset 4; offsets: " + spans,
        repeatStart <= 4 && 4 < repeatEnd);
  }
}
cp $REPRO/TestThaiRepeatFilterZeroWidthSpace.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/th/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.th.TestThaiRepeatFilterZeroWidthSpace -Ptests.seed=5EED0231
# also with -Ptests.asserts=false
- Expected
- The repeated
บ่อยcovers itsๆ: [4,5), as for the same text without the zero-width space. - Observed
- The word gets [0,5), which includes the
ๆ, and the repeat [5,6), only the deleted zero-width space:offsets: [[0,5), [5,6), [6,10)].
More files, environment, full output228 words
The input's U+200B is written as the escape \u200B. The assumeTrue mirrors Lucene's Thai tests (skipped on a JDK without the Thai dictionary BreakIterator). The trigger also needs the JDK to keep บ่อยๆ in one token, which JDK 25.0.3 does; on a JDK that splits off the ๆ the filter takes its other branch and the test passes.
On 10.5.2 the test fails earlier, at the terms check ([บ่อยๆ U+200B, ครับ]), because 10.5.2's ThaiAnalyzer has neither ThaiCharFilter nor ThaiRepeatFilter: the bug cannot occur there.
The finder's wider test (5 methods: this case, the HTMLStripCharFilter chain, both highlight symptoms and a control) fails 4 of 5 on 645d4fe14a20; it is kept out of the minimal repro.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); also jars built at branch_10_6 4ae946e5a9b (10.6.0 RC1) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp $REPRO/TestThaiRepeatFilterZeroWidthSpace.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/th/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.th.TestThaiRepeatFilterZeroWidthSpace -Ptests.seed=5EED0231
# also with -Ptests.asserts=false
TestThaiRepeatFilterZeroWidthSpace > testRepeatedTokenCoversMaiyamokAfterZeroWidthSpace FAILED
    java.lang.AssertionError: the repeated token must cover the Maiyamok at offset 4; offsets: [[0,5), [5,6), [6,10)]
        at __randomizedtesting.SeedInfo.seed([5EED0231:856B084623294010]:0)
        ...
        at org.apache.lucene.analysis.th.TestThaiRepeatFilterZeroWidthSpace.testRepeatedTokenCoversMaiyamokAfterZeroWidthSpace(TestThaiRepeatFilterZeroWidthSpace.java:55)
:lucene:analysis:common:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false, on the standalone runner (-ea, -da) and on the 10.6.0 RC1 jars (-ea, -da)
# without the zero-width space: บ่อย[0,4) บ่อย[4,5) ครับ[5,9)
# with the recommended fix: :lucene:analysis:common:test (SUCCESS): 1 test- The CHANGES entry promises "exact OffsetAttribute and highlighter compatibility"; the introducing commit says the repeats' offsets "match the corresponding 'ๆ' character(s)".
- The trigger is Lucene's default chain:
ThaiAnalyzeritself puts the deletingThaiCharFilterin front ofThaiRepeatFilter. - Lucene's other splitting filters keep the whole span when it differs from the term length (
WordDelimiterGraphFilter,CJKBigramFilter); this one does not.
The full argument250 words
- The record promises exact offsets.
lucene/CHANGES.txt:494-495: "Add ThaiRepeatFilter and ThaiRepeatFilterFactory to expand Thai repetition mark (Maiyamok) with exact OffsetAttribute and highlighter compatibility." The squash commitb7c2c202ba69carries the in-PR message: "Ensure both the primary term and repeated Maiyamok tokens receive precise, non-overlapping start/end offsets. For attached Maiyamok (e.g. 'เร็วๆ'), set primary token endOffset to boundary before 'ๆ' and set repeated token offsets to match the corresponding 'ๆ' character(s)."TestThaiRepeatFilter#testAttachedMaiyamokasserts[0,4)and[4,5)forเร็วๆ(TestThaiRepeatFilter.java:38-44). The class javadoc does not restrict the input (ThaiRepeatFilter.java:27-34). - The repro asks for less than "exact": only that the repeat's span contains its
ๆ. The current output breaks even that. - The default analyzer composes it.
ThaiCharFilter(#16717) andThaiRepeatFilter(#16720) came from the same author and were merged 45 minutes apart;ThaiAnalyzeruses both (ThaiAnalyzer.java:101-123). - Lucene guards this case elsewhere.
WordDelimiterGraphFilter: "if length by start + end offsets doesn't match the term's text then set offsets for all our word parts/concats to the incoming offsets" (:257-263);WordDelimiterFilter.hasIllegalOffsets(:432-434);CJKBigramFilter: "crazy offsets (modified by synonym or charfilter): just preserve" (:284-285). - Why the tests missed it. The explicit tests use
MockTokenizerorThaiTokenizerinput with no CharFilter (TestThaiRepeatFilter.java:30-91); the randomized test checks consistency and offset bounds, not which characters a token covers. #16720 had one approving comment and no review threads. - Not to report: the repeats' position increment of 1 was a deliberate choice in #16720.
The devil's-advocate check211 words
The strongest case for "works as designed" (the refute review and the cross-model review rated it moderate; the intended-behaviour check built it and rejected it; nobody accepted it): the analysis package says "Token filters should not modify offsets. If you feel that your filter would need to modify offsets, then it should probably be implemented as a tokenizer" (package-info.java:416-417); #9496 (LUCENE-8450, open) says filters "cannot perform simple arithmetic to calculate the original ('correct') offset of a character in the interior of the token" once CharFilters change token lengths, and #8817 (LUCENE-7766, open) reports the same for WordDelimiter(Graph)Filter; OffsetAttribute allows a span that differs from the term length (OffsetAttribute.java:27-29); and CharFilter end-offset attribution is an old open limitation (#6796, #7653).
Why it fails: the filter's record promises exact offsets and highlighter compatibility; a span that is too wide would be the accepted outcome, but here the repeat's span misses its own ๆ and the word's span takes it, and the defensive handling Lucene uses elsewhere (keep the whole span, a convention that #8817 disputes) is missing; the trigger is the shipped default analyzer; and in LUCENE-4984 (#6048) the earlier Thai splitting filter was replaced by ThaiTokenizer because, as a token filter, it created positions and updated offsets.
Recommended A. Whole-span guard in ThaiRepeatFilter (validated)
Split per character only when the span length equals the term length (endOffset - startOffset == length); otherwise give the word and every repeat the whole incoming span, as WordDelimiterGraphFilter does: +10 -6 in ThaiRepeatFilter. The test and all 1910 analysis-common tests pass. Safe, not exact: after a CharFilter change both tokens share the span.
+      // Offsets can only be split per character if they map 1:1 onto the term (a CharFilter may
+      // have removed or contracted characters inside the token's span, e.g. a zero-width space
+      // or markup after the Maiyamok); otherwise every emitted token keeps the original span.
+      boolean exactOffsets = origEnd - origStart == len;
...
-        int baseEnd = Math.max(origStart, origEnd - maiyamokCount);
+        int baseEnd = exactOffsets ? Math.max(origStart, origEnd - maiyamokCount) : origEnd;
...
-          int s = Math.min(origEnd, baseEnd + i);
-          int e = (i == maiyamokCount - 1) ? origEnd : Math.min(origEnd, s + 1);
+          int s = exactOffsets ? Math.min(origEnd, baseEnd + i) : origStart;
+          int e = (i == maiyamokCount - 1 || !exactOffsets) ? origEnd : Math.min(origEnd, s + 1);
All options and trade-offs4 options · 804 words
One option was built and validated (A). B to D are alternatives from the reviews and the brief, not built.
The finder's guard, re-made as a git diff on 645d4fe14a20 (1 file, +10 -6). Compute exactOffsets once per token; when it is false, the word and every repeat keep [origStart, origEnd), in both branches (case 1 gets the same change for firstEnd, s and e). The idiom of WordDelimiterGraphFilter and CJKBigramFilter: a conservative fallback, not an exact mapping. The length test is a heuristic: equal lengths do not prove a 1:1 mapping (a replacement that keeps the character count, or a deletion and an insertion that cancel out, were not tested), and a length difference does not prove that a CharFilter acted.
+      // Offsets can only be split per character if they map 1:1 onto the term (a CharFilter may
+      // have removed or contracted characters inside the token's span, e.g. a zero-width space
+      // or markup after the Maiyamok); otherwise every emitted token keeps the original span.
+      boolean exactOffsets = origEnd - origStart == len;
...
-        int baseEnd = Math.max(origStart, origEnd - maiyamokCount);
+        int baseEnd = exactOffsets ? Math.max(origStart, origEnd - maiyamokCount) : origEnd;
...
-          int s = Math.min(origEnd, baseEnd + i);
-          int e = (i == maiyamokCount - 1) ? origEnd : Math.min(origEnd, s + 1);
+          int s = exactOffsets ? Math.min(origEnd, baseEnd + i) : origStart;
+          int e = (i == maiyamokCount - 1 || !exactOffsets) ? origEnd : Math.min(origEnd, s + 1);
Trade-offs
- Safe, not exact: after a CharFilter change the word's span also covers the
ๆ. Tests that require the word not to cover it still fail: the independent reproduction's test fails 5 of 9 with the guard (its 4 ownership tests and one control; its 2 highlight tests pass), the refute reviewer's exact-offset tests 2 of 4. - It widens a case main gets right by coincidence: a deletion before the
ๆ(มาก+ U+200B +ๆ). - The same coarseness in
WordDelimiterFilteris the subject of open #8817 (LUCENE-7766). - Today's output is kept only when the incoming span length equals the term length (the
exactOffsetsbranch is today's code). - Any other mismatch also gets the whole span, whatever caused it, including a token filter that changed the term's length.
ThaiNormalizationFilter, which runs right beforeThaiRepeatFilterinThaiAnalyzer, shortens terms (ThaiNormalizationFilter.java:44): withWhitespaceTokenizer+ThaiNormalizationFilter+ThaiRepeatFilterand no CharFilter,ดีีๆ นะgives the exactดี[0,3),ดี[3,4)on main andดี[0,4)twice with the guard.
What the checks validated
- The minimal test passes with assertions on and off (gradle, and the standalone runner).
:lucene:analysis:common:testwith the fix, assertions on and off: 340 suites, 1910 tests, 18 skipped, 0 failed (all 10thsuites included);:lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- The finder's 5-method test passes 5 of 5 with it, so both highlight symptoms go away.
- Offsets with the fix:
บ่อย[0,6)twice for the zero-width input,บ่อย[0,9)twice for the HTML input; without a CharFilter change unchanged ([0,4),[4,5)). - Every run of the guard was on main; on branch_10_6 and branch_10x the diff applies cleanly (same
ThaiRepeatFilter.javablob) but was not run.
A tokenizer can map each character back through the CharFilter chain with correctOffset(int); a token filter cannot. Expanding ๆ in ThaiTokenizer (or handing it the split points) would let the word end at the ๆ's own corrected offset. This follows the analysis package's guidance ("it should probably be implemented as a tokenizer", package-info.java:416-417), rmuir's position on #9496 ("The thing dividing text up into tokens, tokenizer is the lucene class for that.") and LUCENE-4984 (#6048), where the earlier Thai splitting filter was replaced by ThaiTokenizer.
Trade-offs
A design change to a new public filter (thaiRepeat works after any tokenizer today); the split would have to account for ThaiNormalizationFilter, which runs before ThaiRepeatFilter. Not built; the offsets it would give are reasoning from BaseCharFilter.java:40-53, not executed.
Change where ThaiCharFilter records the correction for a removed zero-width character.
Trade-offs
Fixes only the default-analyzer trigger; HTMLStripCharFilter and other CharFilters still produce it. It moves the next token's start back over the removed character, and since correct() serves start and end offsets alike, a deletion at a token boundary must belong to one side. Not built.
Reword the CHANGES entry and the class javadoc so that exact offsets hold only when no CharFilter changed the token's characters. Could accompany A.
Trade-offs
No behaviour change; on its own it leaves the misattribution in place.
Downstream, Elasticsearch has merged a thai_repeat port of this filter into its Lucene-snapshot branch and OpenSearch has an open request for one, so their Thai offsets and highlights would carry the same misattribution.
A bounded-exhaustive check (semi-formal): the real ThaiAnalyzer chain ran on every Thai text of up to 3 characters from a 16-character slice in 12 word contexts (52,428 texts, 460,810 checks), against an oracle written from the CHANGES entry. 306 texts broke it; the first, at 2 characters, was ดีๆ + U+200B.
The method in full174 words
Method: bounded-exhaustive translation validation of the ThaiAnalyzer chain on the stock main jar, by a hunt unit (analysis, new filters). The harness runs the real classes, so there is no transcription gap; no model checker, SMT solver or proof produced the signal.
- Scope: every text of up to 3 characters over a 16-character Thai slice (consonants, vowels, tone marks, the Maiyamok, a Thai digit, space, U+200B and U+200D), inside 12 prefix/suffix word contexts: 52,428 texts, 460,810 checks at length 3, in 1.7 s.
- Oracle O4, written from the CHANGES entry: each repeated token covers exactly its own Maiyamok and the base token covers none. 306 texts violate it at length 3; the first violation came at length 2 (
ดีๆ+ U+200B: expected[0,2),[2,4), got[0,3),[3,4)). - Vacuity check: the oracle goes quiet with the guard fix.
- The
HTMLStripCharFilterand highlighter symptoms were then found by targeted runs, and the finder wrote a 5-method JUnit; this doc's repro is its first method as a self-contained class.
No prior report: 197 logged searches on 2026-10-26 (GitHub, five mailing lists, the JIRA archive, downstream projects, the web) and a sweep of all upstream activity since the merge, re-checked on 2026-10-29. Context only: the open CharFilter offset issues #6796, #7653, #9496 and #8817.
Searches5 searches
No report, discussion or fix of this bug was found.
Context, not reports: #6796 (LUCENE-5734) and #7653 (LUCENE-6595), open since 2014 and 2015, describe the CharFilter end-offset attribution this bug builds on; #9496 (LUCENE-8450) says a filter "cannot perform simple arithmetic to calculate the original ('correct') offset of a character in the interior of the token"; #8817 (LUCENE-7766) is about the whole-span guard in WordDelimiterFilter; #6048 (LUCENE-4984) replaced the old Thai splitting filter with ThaiTokenizer. None names ThaiRepeatFilter, which was added on 2026-09-27, and the fix site here is ThaiRepeatFilter.java. If the stricter novelty reading is preferred, #6796, #7653 and #9496 are the items that would make it "known".
Gaps: keyword search only; GitHub search does not index review comments (the feature PRs' threads were read in full); private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | scripted prior-report search runs and 27 manual searches (ThaiRepeatFilter, Maiyamok, thaiRepeat, Thai + offsets / highlight / zero width / HTMLStripCharFilter, hasIllegalOffsets, "exact OffsetAttribute", ...) | only the feature work (#16716-#16722, #16727, #16770) and older offset issues of other components |
| Full sweep of upstream activity | 2026-10-26 | every issue and PR updated since 2026-09-26 (353), every comment since 2026-09-25 (542), every PR review comment since 2026-09-27 (380), the changed files of all 413 open PRs | no mention of offsets of repeated tokens; no open PR touches the th package |
| Mailing lists and JIRA archive | 2026-10-26 | 70 queries over dev@, java-user@, issues@, commits@, builds@ and the bodies of all 141 builds@ mails since 2026-09-27; 7 JIRA queries | no report; builds@ Thai failures are the ThaiTokenizer exception of #16736 (fixed) |
| Downstream and web | 2026-10-26 | all of GitHub, Elasticsearch, OpenSearch, Solr, Lucene.NET; 10 web searches | the ports elastic/elasticsearch#160853 and opensearch-project/OpenSearch#23151, no offset report |
| Re-check (apache/lucene) | 2026-10-29 | issue and PR search for ThaiRepeatFilter, Maiyamok, ThaiCharFilter, ThaiAnalyzer and offset terms; commits on the file on main and branch_10_6; the files of the 415 open PRs | nothing new; the file unchanged since b7c2c202ba69 (main) and ed0288d79909 (branch_10_6). One open PR, #16911 ("Decommission branch 10x", opened 2026-10-26), deletes branch_10x's files wholesale (7630 files) to decommission that branch, ThaiRepeatFilter.java and BaseCharFilter.java included; it is neither a fix nor a report (missed by the re-check's file scan, found by the fact check). |
Introduced with the filter by #16720 (b7c2c202ba69, merged 2026-09-27), backported to branch_10x and branch_10_6; first released in 10.6.0 (2026-10-29). No earlier release has the class.
Versions tested6 rows
#16720 "Add ThaiRepeatFilter to handle Thai Maiyamok (ๆ) reduplication" (kamthorn, approved by rmuir, fixes #16719) is b7c2c202ba69 on main and ed0288d79909 on branch_10x, contained in branch_10_6; CHANGES lists it under 10.6.0. The offset split came from the PR's second commit 6223794e4021; the first PR commit had no setOffset call, so there was never a correct merged version. The default-analyzer trigger also needs ThaiCharFilter in ThaiAnalyzer.initReader, from e64ae25dcd89 (#16717, same author, merged 45 minutes earlier). ThaiRepeatFilter.java is unchanged since.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the test fails, assertions on and off (gradle and standalone) |
branch_10_6 4ae946e5a9b (10.6.0 RC1) | affected | the test fails on jars built at this revision, assertions on and off |
| branch_10x | read only | identical file blobs (not built) |
introducing commit b7c2c202ba69 | commit build | the finder's test fails 4 of 5, assertions on and off, same messages as on main |
its parent b0ae596a78b1, 10.5.2, 9.12.3 | class absent | no ThaiRepeatFilter: the finder's test does not compile; 10.5.2 fails the minimal test only at the terms check |
main 645d4fe14a20 + guard fix | not affected | the test passes; 1910 analysis-common tests pass |
The finder, a reviewer from another model family (executed), an independent reproducer, two devil's advocates and an adjudication each confirmed it; this doc's one-method test was re-run on main 645d4fe14a20 and the 10.6.0 RC1, and the fix was checked against the whole module.
Checks and verdicts279 words
The finder, the independent reproduction, the intended-behaviour check and the refute reviewer each ran their own test on the stock jars. The intended-behaviour review could only read code; a separate run re-ran the finder's test. The adjudication re-ran the independent reproduction's test with a fresh seed.
| Check | Verdict | What it found |
|---|---|---|
| finder (a hunt unit) | candidate | Exhaustive check: 306 texts break the ownership oracle at length 3; 5-method JUnit fails 4 of 5 with -ea and -da, passes with the guard; 22 upstream Thai tests pass with it. |
| cross-model review, refute lens (OpenAI GPT-5.6, executed) | real, high | Own test with other inputs (ThaiCharFilter + whitespace tokenizer on มากๆ + U+200C) fails 2 of 4 with -ea and -da; control passes; with the guard its exact-offset tests still fail (safe, not exact). |
| Independent reproducer | real | Own test, 6 claims and 3 controls: fails 6 of 9 with -ea and -da; a diagnostic separates the CharFilter's wide span from the filter's misattribution. |
| Cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real, medium | Intended argument moderate and rejected; a separate run re-ran the finder's test: 4 of 5 fail. |
| Devil's advocate | real | No intended, documented, misuse or reachability argument survives; own probe fails 1 of 3 (the claim). |
| adjudication | confirmed, high; class minor | Re-ran the independent reproduction's test with a fresh seed: 6 of 9 fail with -ea and -da. |
| this doc (2026-10-29) | reproduced; fix validated | One-method test fails on 645d4fe14a20 and the RC1 jars, -ea and -da; passes with the guard; module 1910 tests and check -x test pass with the guard. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 470 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,500 words
- Registry title
- ThaiRepeatFilter gives the repeated word the offsets of a deleted character or of the following markup instead of the Maiyamok's, when a CharFilter removed characters right after the Maiyamok (a zero-width space in the default ThaiAnalyzer, a closing tag with HTMLStripCharFilter)
- Area
- analysis / Thai (ThaiRepeatFilter offset split; ThaiAnalyzer with ThaiCharFilter, or a custom chain with HTMLStripCharFilter)
- Priority
- Low, rank 1044: Offsets from the new 10.6.0 ThaiRepeatFilter are wrong after a CharFilter deletion only for highlighting and term vectors while terms and matches stay correct, so this presentation-only bug leads the analysis-offset rows like LFV-603 among the minor rows.
- Impact class
- minor
- Impact note
- Only offsets are wrong (postings and term-vector offsets, and highlights built from them; terms, positions, matching and scoring are unchanged): with the stock ThaiAnalyzer of 10.6.0 (released 2026-10-29), a zero-width character (U+200B, U+200C, U+200D or U+FEFF) directly after a Maiyamok that the JDK word BreakIterator keeps attached to its word (on JDK 25 for example จริงๆ, บ่อยๆ, ดีๆ, อื่นๆ, but not เร็วๆ or มากๆ) makes a phrase or other position-sensitive highlight leave the Maiyamok out ('บ่อยๆ<b>U+200Bครับ</b>'), and in a custom HTMLStripCharFilter + tokenizer + ThaiRepeatFilter chain a tag right after the reduplicated word makes the UnifiedHighlighter cut that tag ('<i><b>บ่อยๆ</i</b><b>></b>'); deterministic at any index size, with -ea and -da, in 10.6.0 and on main, branch_10x and branch_10_6 only (no earlier release).
- Summary
- You analyze 'บ่อยๆ' + U+200B + 'ครับ' (a word written with the repetition mark ๆ, then a zero-width space) with the stock ThaiAnalyzer and expect what happens without the zero-width space, and what the filter's CHANGES entry promises ('exact OffsetAttribute and highlighter compatibility'): the base token บ่อย covers the word [0,4) and the repeated token บ่อย covers the ๆ [4,5). Instead the base token gets [0,5), which includes the ๆ, and the repeated token gets [5,6), which is only the removed zero-width space: ThaiRepeatFilter assumes that the last characters of the token's offset span are its trailing ๆ, but the CharFilter's offset correction put the removed character at the end of that span. With HTMLStripCharFilter the repeated token points at the last character of the tag after the word instead, so a highlighter writes its markup inside the tag; terms and positions are correct and nothing fails.
- Introduced
- b7c2c202ba695d8fd8cfb7081ad183b89922a462 (main; apache/lucene#16720 'Add ThaiRepeatFilter to handle Thai Maiyamok reduplication', fixes #16719, author kamthorn, squash-merged 2026-09-27 with one approving comment by rmuir and no review threads; the per-character offset split, baseEnd = origEnd - maiyamokCount, came from the PR's second commit 6223794e4021 'Fix OffsetAttribute handling in ThaiRepeatFilter and add randomized offset tests', while the PR's first commit 9b9eabd23688 had no setOffset call) and its branch_10x backport ed0288d79909 (2026-09-28), which is also on branch_10_6. The default-ThaiAnalyzer trigger also needs ThaiCharFilter in ThaiAnalyzer.initReader, added 45 minutes earlier by e64ae25dcd89 (#16717, same author); the HTMLStripCharFilter trigger needs only ThaiRepeatFilter [read: git log and git blame in the full-history clone, every line of the offset logic ThaiRepeatFilter.java:85-125 from b7c2c202ba69 and the file byte-identical up to ea57360912ed; the PR commits through the read-only GitHub API; exec: the repro fails at b7c2c202ba69 and does not compile at its parent b0ae596a78b1]. There was never a correct earlier behaviour in a merged commit (2026-09-27 (main); 2026-09-28 (branch_10x backport))
- First affected version
- 10.6.0 (released 2026-10-29; branch_10_6 has the identical file); no earlier release contains ThaiRepeatFilter [exec: compile error on 10.5.2 and 9.12.3]
- Affected versions
- main from b7c2c202ba69 (2026-09-27) to ea57360912ed [exec: the finder repro fails 4 of 5 with -ea and -da at both commits, the independent reproduction's test 6 of 9 with -ea at both]; branch_10x from ed0288d79909 and branch_10_6 [read: the ThaiRepeatFilter.java blob 1ef37ff70aef and the ThaiAnalyzer.java and ThaiCharFilter.java blobs are identical on main, branch_10x and branch_10_6 by the read-only GitHub contents API, 2026-10-26; not built or executed]; in no release before 10.6.0: 10.5.2 (the last before it, released 2026-10-04 from branch_10_5), 9.12.3 and every older release lack the class [exec: compile error 'cannot find symbol ThaiRepeatFilter' on 10.5.2, 9.12.3 and on the parent commit b0ae596a78b1; read: the th package in tags 10.5.2, 10.5.0 and 9.12.3 has no ThaiRepeatFilter]; not fixed upstream. JDK caveat: the default-analyzer trigger needs the JDK word BreakIterator to keep the ๆ attached to its word; every run used JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 197 logged read-only queries and reads, 152 of them through scripted prior-report searches over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@, commits@ and builds@ lists and the LUCENE JIRA archive, and 45 manual ones (27 GitHub searches incl. all of GitHub, Elasticsearch, OpenSearch, Solr and Lucene.NET, 10 web searches, direct GitHub, list and JIRA reads); plus a full sweep of every apache/lucene issue and PR updated since 2026-09-26 (353), every issue or PR comment since 2026-09-25 (542) and every PR review comment since 2026-09-27 (380), the bodies of all 141 builds@ mails since 2026-09-27, and the changed files of all 413 open apache/lucene PRs; 18 hits read, none the same bug). Not fixed upstream: ThaiRepeatFilter.java is unchanged since b7c2c202ba69 on main and ed0288d79909 on branch_10x and branch_10_6, and no open PR touches the th package or the CharFilter offset code. Closest items, context and not reports: the introducing #16720 / #16719 and #16717 (no discussion of CharFilters, zero-width characters or highlighting), the downstream ports elastic/elasticsearch#160853 and opensearch-project/OpenSearch#23151 (the latter calls the filter's offsets 'correct'), and the long-standing open CharFilter and splitting-filter offset issues #6796 (LUCENE-5734), #7653 (LUCENE-6595), #9496 (LUCENE-8450) and #8817 (LUCENE-7766), which describe the end-offset attribution this bug builds on and the whole-span guard ThaiRepeatFilter lacks but cannot name a filter added on 2026-09-27
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28): the one-method repro through gradle in a scratch worktree and through the standalone runner, assertions on and off, stock and with the recommended fix (plus the wholelucene/analysis/commonmodule andcheck -x testwith the fix); jars built at branch_10_64ae946e5a9b(10.6.0 RC1), assertions on and off; the 10.5.2 release jars (noThaiRepeatFilter). The hunt's earlier runs (finder, verifiers, adjudication, follow-up, including the introducing commitb7c2c202ba69and its parent, and 9.12.3) used mainea57360912edanda9779ef3c193, where every cited source file exceptCHANGES.txtis identical.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiRepeatFilter.java:27-34 (class javadoc), :80-101 (case 1, a token of only Maiyamok; offsets :88-95), :104-129 (case 2, trailing Maiyamok; baseEnd = max(origStart, origEnd - maiyamokCount) at :114, repeat offsets :118-123); no check that endOffset - startOffset equals the term lengthlucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-122 (ThaiTokenizer, LowerCaseFilter, DecimalDigitFilter, ThaiNormalizationFilter, ThaiRepeatFilter, StopFilter; initReader wraps the reader in ThaiCharFilter)lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:89-95 (removes U+200B, U+200C, U+200D and U+FEFF and records the deletion with addOffCorrectMap)lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:41-53 (correct(off) applies the diff recorded at the largest offset <= off, so a deletion right after a token moves that token's end offset past it)lucene/CHANGES.txt:476-477 (10.6.0, GITHUB#16720: 'expand Thai repetition mark (Maiyamok) with exact OffsetAttribute and highlighter compatibility')lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:262-263 (adjustingOffsets only when savedEndOffset - savedStartOffset == savedTermLength), WordDelimiterFilter.java:434 (hasIllegalOffsets), cjk/CJKBigramFilter.java:284-285 ('crazy offsets (modified by synonym or charfilter): just preserve')
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiRepeatFilter.java:27-34, :67, :75-77, :79-102 (offsets :87-96), :104-129 (baseEnd :114, repeats :118-123)a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-109 (chain), :119-123 (initReader wraps ThaiCharFilter)a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:35, :89-94 (zero-width removal, addOffCorrectMap)a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:40-53 (correct)
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiCharFilter.java:27-30, :89-90a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-123
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:494-495 (10.6.0, GITHUB#16720: 'exact OffsetAttribute and highlighter compatibility')a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/test/org/apache/lucene/analysis/th/TestThaiRepeatFilter.java:30-104 (testAttachedMaiyamok :38-44; testRandomStrings :93-104)a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiRepeatFilter.java:27-34a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiAnalyzer.java:101-123a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:257-263; a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:432-434a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/cjk/CJKBigramFilter.java:284-285a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/package-info.java:416-419a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/OffsetAttribute.java:23-29
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:257-263; a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/cjk/CJKBigramFilter.java:284-285a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/package-info.java:416-419a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:40-53a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/th/ThaiNormalizationFilter.java:44 (termAtt.setLength); ThaiAnalyzer.java:101-109 (chain order)
- Prior reports
GitHub API, read-only, 2026-10-29: apache/lucene#16911 (base branch_10x, 7630 files, 4 additions, 1,606,760 deletions; its file list removes th/ThaiRepeatFilter.java and charfilter/BaseCharFilter.java)
- History
a Lucene clone: git log b7c2c202ba69; git merge-base --is-ancestor ed0288d79909 origin/branch_10_6
- TestThaiRepeatFilterZeroWidthSpace.java (lucene/analysis/common, one test):
repro/LFV-231/src/org/apache/lucene/analysis/th/TestThaiRepeatFilterZeroWidthSpace.java(59 lines)
It is made in parallel with this doc; every on-screen value comes from the code at 645d4fe14a20 or the diagram's executed probe.
assets/LFV-231/bug.png(470 KB)