Grouping decides twice whether the within-group sort means "by relevance": the collector compares with the Sort.RELEVANCE object (==), the merge with equals. An equal copy is therefore collected as a field sort, with no scores, and merged as a score sort.
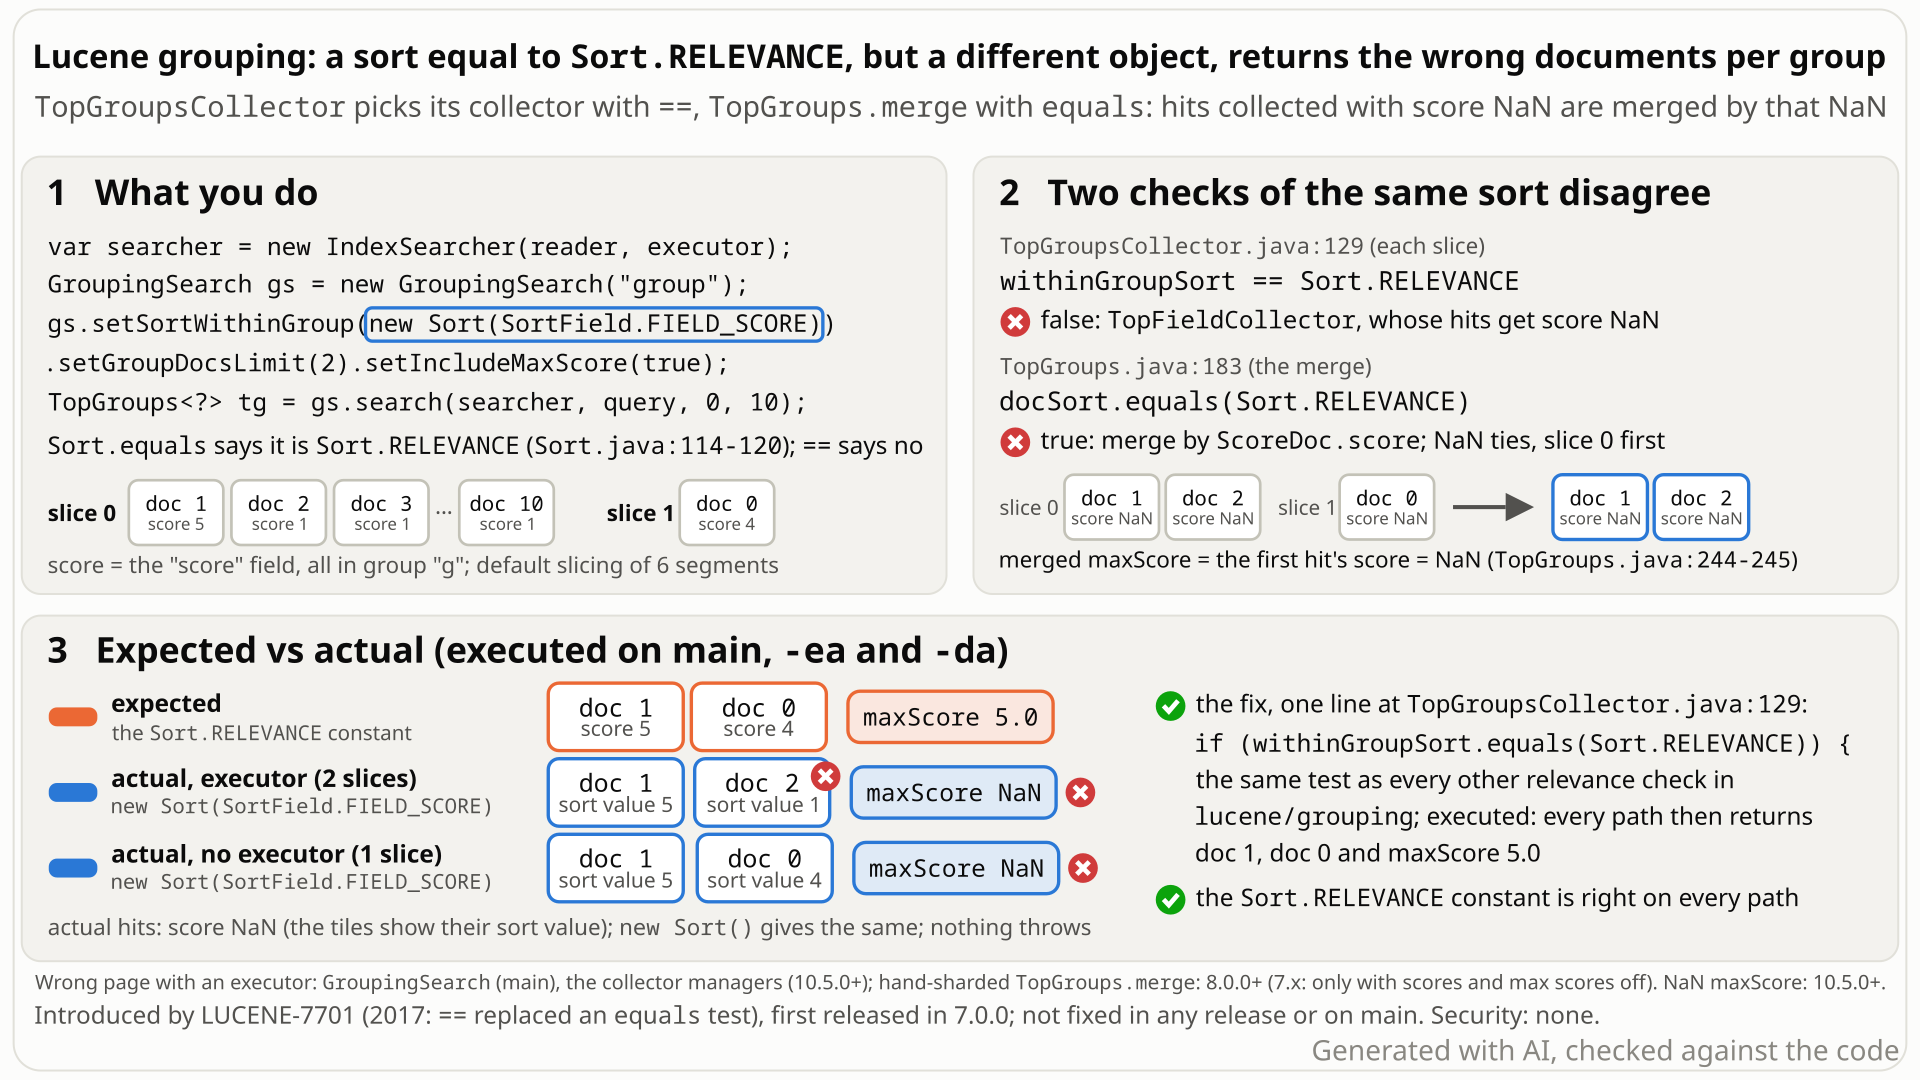
new Sort(SortField.FIELD_SCORE), every hit carries score NaN, so the merge cannot compare them and takes slice 0 first: 5, 1 instead of 5, 4, and maxScore NaN. Select the still to open it at full size. Generated with AI, checked against the code.- Index 11 documents in one group over 6 segments: doc 0 scores 4, doc 1 scores 5, the other nine score 1. With an executor, default slicing (by segment size; the pool size does not matter) puts doc 0's segment alone in slice 1 and the other five segments in slice 0.
- Run
GroupingSearch("group")withsetGroupDocsLimit(2),setIncludeMaxScore(true)andsetSortWithinGroup(new Sort(SortField.FIELD_SCORE)). You expect what the equalSort.RELEVANCEreturns: docs [1, 0] (scores 5 and 4) and maxScore 5.0. - Instead you get docs [1, 2]: doc 2 (score 1) replaces doc 0 (score 4). The collector checks
withinGroupSort == Sort.RELEVANCE(the same object), so it uses the field-sort collector, whose hits carry score NaN. - The merge of the two slices checks
equals, so it orders those hits by score. Every comparison with NaN is false, so slice 0's hits simply come first. Since 10.5.0 it also takes maxScore from the first hit: NaN, on main even without an executor. - No error, with assertions on or off.
Sort.RELEVANCEitself returns [1, 0] and 5.0 on every path. Since 8.0.0 a hand-shardedTopGroups.mergealso takes shard 0's hits first, wrong whenever a later shard holds a better hit.
Direct users of Lucene grouping (GroupingSearch, the grouping collectors and managers, TopGroups.merge) who build the within-group relevance sort as a new object, such as a request builder mapping "score" to new Sort(SortField.FIELD_SCORE). Wrong pages need 2+ slices or shards, with a better hit in a later one; NaN maxScore needs 10.5.0+. The default constant is unaffected.
Mechanism, terms and numbers731 words
Sort.RELEVANCE is new Sort(), and new Sort(), new Sort(SortField.FIELD_SCORE) and the constant are all equal. Two-pass grouping does not treat them alike: the second pass, TopGroupsCollector, picks its per-group collector with withinGroupSort == Sort.RELEVANCE (object identity), so an equal copy is collected by the field-sort collector, whose hits carry score NaN, while TopGroups.merge checks equals and merges those hits by score. Every comparison with NaN is false, so the merged page is slice 0's hits, then slice 1's: a group shows docs [1, 2] (scores 5 and 1) instead of [1, 0] (scores 5 and 4). Since 10.5.0 the merge also takes maxScore from the first hit's NaN score. With 10.5.0's collector managers and main's GroupingSearch, a searcher with an executor and 2 or more slices merges the pages slice by slice, wrong whenever a later slice holds a better hit, and maxScore is NaN even with one slice; a hand-sharded TopGroups.merge has merged shard by shard since 8.0.0. Nothing throws, and the Sort.RELEVANCE constant is correct everywhere. A one-line fix (equals instead of ==) passes the grouping module's tests.
- Two-pass grouping: the first pass finds the top groups; the second pass (
TopGroupsCollector) collects the top documents inside each of them, ordered by the within-group sort (GroupingSearch.setSortWithinGroup, defaultSort.RELEVANCE). - Slices: an
IndexSearcherwith an executor runs one collector per slice; the collector manager merges their results inreduce. Default slicing sorts the segments by size, largest first, and closes a slice once it holds 5 segments or more than 250,000 documents; a segment of more than 250,000 documents gets a slice of its own (IndexSearcher.java:106-108,:350-379). The slices do not depend on the executor's pool size. - Equal sorts:
Sort.RELEVANCEisnew Sort()(Sort.java:41),Sort()isthis(SortField.FIELD_SCORE)(:54-56), andequalscompares the fields (:114-119).
- The
TopGroupsCollector.TopDocsReducerconstructor (TopGroupsCollector.java:127-148) testsif (withinGroupSort == Sort.RELEVANCE)(:129). Only the constant gets aTopScoreDocCollector(:130-136); an equal copy gets aTopFieldCollectorplus aMaxScoreCollector(:137-146). - Field-collected hits are created with score NaN (
FieldValueHitQueue.java:36-38); the score lives only inFieldDoc.fields[0]. Within one slice the order and the slice'smaxScoreare still right: 5.0 for slice 0, 4.0 for slice 1. TopGroups.mergetestsdocSort.equals(Sort.RELEVANCE)(TopGroups.java:183), true here, wraps the hits as plainTopDocs(:218-220) and merges them byScoreDoc.score(:241).- With NaN,
score < scoreandscore > scoreare both false, soTopDocs.mergefalls back to its tie-break, shard index then doc id (TopDocs.java:44-45,:110-120): slice 0's hits come first, [doc 1, doc 2], and doc 0 is cut by the page size 2. - Since #15879 (10.5.0) the merge sets
maxScore = scoreDocs[0].scorefor a relevance sort (TopGroups.java:244-245), NaN here, and skips the per-slice values it uses for other sorts (:231-233). TopGroupsCollectorManager.reducealways callsTopGroups.merge, even for one collector (TopGroupsCollectorManager.java:112-123), and on mainGroupingSearchruns its second pass through it (GroupingSearch.java:197-212). One slice: right page, NaNmaxScore. Two or more slices, or a hand-sharded merge: the inputs' pages one after another, so the page is also wrong whenever a later input holds a better hit, as doc 0 does here.
Line 129 is the only == comparison with a Sort constant in Lucene's main code; every other relevance check in the grouping module uses equals (AllGroupHeadsCollector.java:63, AllGroupHeadsCollectorManager.java:146, BlockGroupingCollector.java:275, :285, TopGroups.java:183, :405).
Index: 6 segments, NoMergePolicy, one group; segment 0 = doc 0 (score 4), segment 1 = doc 1 (5) and doc 2 (1), segments 2-5 = docs 3-10 (1 each). An executor (the test uses 2 threads; any pool size gives the same slices) gives slice 0 = segments 1-5 and slice 1 = segment 0.
| within-group sort | searcher | docs | maxScore |
|---|---|---|---|
Sort.RELEVANCE | sequential or executor | [1, 0] | 5.0 |
new Sort(SortField.FIELD_SCORE) or new Sort() | executor (2 slices) | [1, 2] | NaN |
new Sort(SortField.FIELD_SCORE) or new Sort() | sequential | [1, 0] | NaN |
Inside the merge (executor, new Sort(SortField.FIELD_SCORE)): slice 0 = [doc 1 (FieldDoc, score NaN, sort value 5.0), doc 2 (NaN, 1.0)], maxScore 5.0; slice 1 = [doc 0 (NaN, 4.0)], maxScore 4.0; merged = [doc 1, doc 2], maxScore NaN.
Exposure and likelihood307 words
- Who is exposed. Applications that use the grouping module directly and pass an equal copy of
Sort.RELEVANCEas the within-group sort, for example a sort builder that turns a requested "score" key intonew Sort(SortField.FIELD_SCORE). - Which paths, from which release (executed on the releases under Version history; the tags in between by code reading). A wrong page needs a better hit in a later slice or shard:
- hand-sharded
TopGroups.merge, the way the package docs describe sharding ("Sharding is not directly supported, though is not too difficult, if you can merge the top groups and top documents per group yourself",package-info.java:76-77): wrong page since 8.0.0 (7.x only with scores and max scores off), NaNmaxScoresince 10.5.0; - the grouping collector managers on a searcher with an executor and 2 or more slices: wrong page since 10.5.0; NaN
maxScoresince 10.5.0 even with one slice; GroupingSearchitself: main and, by reading, 10.6.0 (#16247), wrong page with an executor and NaNmaxScoreeven sequentially.
- hand-sharded
- Default or opt-in. Opt-in: the default within-group sort is the constant, which is correct on every path. Nothing else is needed: default codec, config and slicing.
- Scale. None: 11 documents in the test; the bounded-exhaustive check saw wrong pages at 2 documents, one per slice or shard. Deterministic.
- What you see. No error, the same with assertions on and off. Groups, totals and counts are right; only which matching documents a group shows, their order, and
maxScorechange. Comparisons with NaN are false, so a rule that drops groups withmaxScore < thresholdkeeps every group, and one that keeps groups withmaxScore >= thresholddrops every group. - Downstream (read, not run). Solr normalizes a plain
score descto the constant; Elasticsearch and OpenSearch do not useTopGroupsCollector. That fits the absence of reports since 2017, and says nothing about private code.
The test shows that with a within-group sort new Sort(SortField.FIELD_SCORE), which equals Sort.RELEVANCE but is another instance, TopGroups.merge over two shards puts the wrong document at the top of the group, because TopGroupsCollector tests == Sort.RELEVANCE and collects score-NaN field hits.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.grouping;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.FeatureField;
import org.apache.lucene.document.SortedDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LeafReaderContext;
import org.apache.lucene.index.NoMergePolicy;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.Sort;
import org.apache.lucene.search.SortField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestEqualRelevanceSortShardMerge extends LuceneTestCase {

  public void testMergedGroupKeepsBestHit() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w =
            new IndexWriter(dir, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
      for (float score : new float[] {1, 4}) { // one segment per document, each searched as a shard
        Document doc = new Document();
        doc.add(new SortedDocValuesField("group", new BytesRef("g")));
        doc.add(new FeatureField("features", "score", score));
        w.addDocument(doc);
        w.flush();
      }
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        Query query = FeatureField.newLinearQuery("features", "score", 1f);
        Sort withinGroupSort = new Sort(SortField.FIELD_SCORE); // equals Sort.RELEVANCE
        GroupingSearch grouping =
            new GroupingSearch("group").setSortWithinGroup(withinGroupSort).setGroupDocsLimit(1);
        List<TopGroups<BytesRef>> shards = new ArrayList<>();
        for (LeafReaderContext leaf : reader.leaves()) {
          shards.add(grouping.search(new IndexSearcher(leaf.reader()), query, 0, 10));
        }
        TopGroups<BytesRef> merged =
            TopGroups.merge(
                shards, Sort.RELEVANCE, withinGroupSort, 0, 1, TopGroups.ScoreMergeMode.None);
        // expected: group g's top hit is shard 1's score-4 document; actual: shard 0's score-1 document
        assertEquals("shard of group g's top hit", 1, merged.groups[0].scoreDocs()[0].shardIndex);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-232/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/grouping/build/libs/lucene-grouping-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.grouping.TestEqualRelevanceSortShardMerge
- Expected vs actual
- Expected: group g's top hit is shard 1's score-4 document; actual:
shard of group g's top hit expected:<1> but was:<0>(shard 0's score-1 document).
More files, environment, full output39 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: shard of group g's top hit expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.search.grouping.TestEqualRelevanceSortShardMerge.testMergedGroupKeepsBestHit(TestEqualRelevanceSortShardMerge.java:64)Sort.RELEVANCEisnew Sort(),Sort()isSort(SortField.FIELD_SCORE), andSort.equalscompares fields;setSortWithinGroupaccepts anySort.- Every other relevance check in the grouping module,
TopGroups.mergeincluded, usesequals;GroupDocs.maxScoreis documented as "Max score in this group". - A 2017 refactor (LUCENE-7701) replaced an
equalscheck with==without comment, while its migration note promised the old behaviour.
The full argument261 words
- Contracts.
Sortclass javadoc: "A Sort can be created with an empty constructor, yielding an object that will instruct searches to return their hits sorted by relevance" (Sort.java:27-29);Sort()"Sorts by computed relevance" and delegates toSort(SortField.FIELD_SCORE)(:49-56).setSortWithinGroup: "Specified how documents inside a group are sorted. Defaults to Sort#RELEVANCE." (GroupingSearch.java:296-305).GroupDocs.maxScore: "Max score in this group" (GroupDocs.java:27).TopGroups.merge: "Merges a list of TopGroups, for example obtained from the second-pass collector across multiple shards" (TopGroups.java:112-115). - History. LUCENE-7701 (
caf329717ef, 7.0.0) removedif (withinGroupSort.equals(Sort.RELEVANCE)) { // optimize to use TopScoreDocCollectorfrom the old second-pass collector and wrotewithinGroupSort == Sort.RELEVANCEin the new one; the same commit usedsort.equals(Sort.RELEVANCE)in the newAllGroupHeadsCollector, and its MIGRATE entry says "To reproduce the old behaviour of SecondPassGroupingCollector, you should instead use TopGroupsCollector." No comment in the issue mentions the change. LUCENE-6900 (2015) and SOLR-9783 (2016) had deliberately made the same checkequals. - Tests.
TestAllGroupHeadsCollectorpassesnew Sort(SortField.FIELD_SCORE)as the within-group sort ofAllGroupHeadsCollectorManager(which testsequals) and expects the group heads in score order (TestAllGroupHeadsCollector.java:363-371,:511-514,:542-548): upstream already treats an equal copy as relevance there. No test passes an equal copy as the within-group sort ofTopGroupsCollector,TopGroupsCollectorManagerorGroupingSearch:TestGrouping.getRandomSortalways appends anidfield (TestGrouping.java:524-542), and the other grouping tests useSort.RELEVANCEor field sorts. - One-line swaps flip it both ways (executed): 6.6.6 with
==fails like 7.0.0; 7.0.0, 8.0.0, 9.12.3 and 10.5.2 withequalspass.
The devil's-advocate check232 words
The strongest case for "intended" (built by OpenAI GPT-5.6 reviewers, a devil's-advocate AI tool and the adjudication): grouping is @lucene.experimental; several javadocs say "if you want to groupSort by relevance use Sort.RELEVANCE" (FirstPassGroupingCollector.java:71, :85, BlockGroupingCollector.java:203, TopGroups.java:363); the package docs say sharding is not directly supported; and LUCENE-6528 (2015, "Not A Problem") says NaN scores from a FIELD_SCORE field sort are expected.
Why it fails (every reviewer rated it weak): those javadoc lines are about the group sort and about passing a non-null sort (LUCENE-6900), not about object identity; TopGroups.merge itself uses equals and treats the sort as relevance, so the module disagrees with itself; the sequential maxScore NaN on main involves no sharding, with setIncludeMaxScore(true) requested; LUCENE-6528 explains why the hits carry NaN, while the defect is that the merge orders by those NaN scores and takes maxScore from them; and @lucene.experimental marks an unstable API, not permission to return wrong results.
What does not fail is compatibility: new Sort(SortField.FIELD_SCORE) is a field sort by construction, GroupDocs says the hits "may be FieldDoc instances if the withinGroupSort sorted by fields" (GroupDocs.java:29-30), and callers may rely on getting FieldDocs. That bears on the shape of the fix (A returns ScoreDocs, as 6.x did; a type-aware merge, option C, keeps FieldDocs), not on whether the wrong page and the NaN maxScore are intended.
Recommended A: check equality in TopGroupsCollector, like the rest of the module
Check withinGroupSort.equals(Sort.RELEVANCE) at TopGroupsCollector.java:129, like the rest of the module: one line. The test and the whole grouping module (61 tests) pass with assertions on and off, and the static checks pass. The one API-visible change found: such groups then return ScoreDocs with real scores, as the constant does, instead of FieldDocs with NaN.
-      if (withinGroupSort == Sort.RELEVANCE) {
+      if (withinGroupSort.equals(Sort.RELEVANCE)) {
All options and trade-offs4 options · 567 words
One fix was built and validated in a scratch worktree at ea57360912ed, removed afterwards; the other options were not run.
A: check equality in TopGroupsCollector, like the rest of the module (validated by the checks) (recommended)
In TopGroupsCollector.TopDocsReducer, replace withinGroupSort == Sort.RELEVANCE with withinGroupSort.equals(Sort.RELEVANCE). An equal copy then takes the same score-collector path as the constant, which is what 6.x did.
-      if (withinGroupSort == Sort.RELEVANCE) {
+      if (withinGroupSort.equals(Sort.RELEVANCE)) {
Trade-offs
- Hit type changes. Hits of an equal copy become plain
ScoreDocs with real scores instead ofFieldDocs with score NaN (probe: stockFieldDoc doc=1 score=NaN maxScore=NaN, fixedScoreDoc doc=1 score=5.0 maxScore=5.0, the same asSort.RELEVANCE). A caller that casts them toFieldDocor readsfields[0]would break;GroupDocsdocumentsFieldDochits only "if the withinGroupSort sorted by fields" (GroupDocs.java:29-30). The hits then come fromTopScoreDocCollectorinstead ofTopFieldCollector. - Cost. Not benchmarked: one
Sort.equalscall per collector construction, and an equal copy then uses the constant's collector. - Scope. It fixes what Lucene's own collectors produce.
TopGroups.mergestill treats any input whosedocSortequalsSort.RELEVANCEas score-sorted, soFieldDocs with score NaN from another producer (a custom second-pass collector) would still merge in slice order; option C covers that. - Related open PR. #16569 edits the same constructor and keeps
==; the repros still fail with it. A 3-way merge of the fixed file with the PR's head on their shared base is clean (0 conflicts).
What the checks validated
- Gradle, scratch worktree at
ea57360912ed, OpenJDK 25.0.3: the test fails 3 of 5 on stock (assertions on and off) and passes 5 of 5 with the fix. :lucene:grouping:testwith the fix and the test: 15 classes, 61 tests (56 upstream + 5 new), 0 failures, with assertions on, off, and seed 5A17C0DE.:lucene:grouping:check -x testpasses (google-java-format, ecjLint, forbiddenApis) aftertidyre-wrapped two javadoc paragraphs of the test.- Standalone harness with the fix shadowed: the test passes 5 of 5 with assertions on and off (seeds DEADBEEF and 7A11C0DE); the independent reproducer's 17 tests, the refute reviewer's tests and 56 upstream grouping test methods pass; the security probe shows 0 pages out of score order and no NaN
maxScore.
GroupingSearch.setSortWithinGroup, the TopGroupsCollector constructor and TopGroupsCollectorManager replace a sort equal to Sort.RELEVANCE with the constant.
Trade-offs
Same effect for collection, but more places to change, and it keeps the identity check that the rest of the module avoids.
Merge with TopFieldDocs whenever the hits are FieldDocs, and keep the per-shard maxScore.
Trade-offs
Keeps the FieldDoc hit type for callers that rely on it and also fixes merged results from any other producer, but touches the merge for every caller and leaves the collector's identity check in place. Switching the merge to == instead would be wrong: it would break callers that collect with the constant and merge with new Sort(), since the hits would then be treated as FieldDocs. A is the minimal change; C is a real alternative, or an addition to A.
Say in the javadoc that only the constant means relevance.
Trade-offs
Makes Sort.equals meaningless for this API and leaves every existing caller wrong.
Code reading. An AI tool auditing the grouping module noticed that the second pass checks == Sort.RELEVANCE while the merge checks equals, and confirmed it with a probe. Adding new Sort(SortField.FIELD_SCORE) to the unit's bounded-exhaustive grouping check then showed wrong pages and a NaN maxScore at 2 documents.
The method in full134 words
Method: code reading (the hunt's non-formal tier), a hunt unit (grouping), 2026-10-26.
- The finder, an AI tool, compared the relevance check in
TopGroupsCollector(==) with the one inTopGroups.merge(equals) and wrote a scratch probe that showed the wrong page. - It then added a third within-group sort,
new Sort(SortField.FIELD_SCORE), to the unit's bounded-exhaustive harness, which compares sequential, concurrent and hand-sharded grouping with a reference over every small index. Wrong pages (distributed and sequential-versus-concurrent kinds) and wrongmaxScoreappeared already at 2 documents, one per slice or shard. With the constant and with real field sorts the same harness found no such mismatch in larger runs. - So the hypothesis came from reading; the harness confirmed it. A public-API JUnit test on the stock jars followed, then the independent checks below.
No prior report found (2026-10-26): 157 searches over GitHub issues and PRs, downstream repositories, four mailing lists, the LUCENE and SOLR JIRA archives, the web and the full commit history, plus the files of all 413 open PRs; 17 hits read. Open PR #16569 edits the adjacent lines but keeps the identity check.
Searches4 searches
The closest items are the change that introduced the check (#8752, LUCENE-7701), the change that introduced the NaN maxScore (#15879, whose discussion is about performance only), the same one-line equals change made in other code in 2015-2016 (#7958 / LUCENE-6900, SOLR-9783), an analogous collection-versus-merge mismatch in Solr's distributed group.query (SOLR-5046, different code), and other, fixed NaN-maxScore bugs (#10039 / LUCENE-8996, #15872 / #15873). GitHub search caps at 50 results per query (none returned more than 17); GitHub Discussions, chat channels and private security reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene, incl. migrated JIRA) | 2026-10-26 | 13 scripted prior-report search queries and 80 GraphQL searches, 14 of them over Elasticsearch, OpenSearch and Solr (TopGroupsCollector, withinGroupSort, sortWithinGroup, Sort.RELEVANCE, FIELD_SCORE, new Sort(), TopGroups.merge NaN, maxScore NaN, executor and slice phrasings) | no report; 17 related hits read |
| Open PRs and recent activity | 2026-10-26 | changed files of all 413 open PRs; 491 issues and PRs updated since 2026-09-01; TopGroupsCollector.java on main, branch_10x, branch_10_6 and branch_10_5 | #16569 and #16548 touch the file and keep the identity check; all four branches still have it |
| Mailing lists and JIRA | 2026-10-26 | 28 queries over dev@, java-user@, issues@ and commits@; 8 LUCENE and 7 SOLR JIRA queries | no report |
| Downstream code, commits and the web | 2026-10-26 | the 14 downstream searches above; 13 commit-message patterns over the full history plus the upstream commits after the snapshot; 8 web queries | 0 downstream hits for the identifiers; no fix commit; no web report |
Introduced in 7.0.0 by LUCENE-7701 (2017), which swapped an equals check for ==. It grew wider in 8.0.0, 10.5.0 (NaN maxScore, collector managers) and on main (GroupingSearch). Run on 13 releases and main: the three 6.x releases pass, the 10 from 7.0.0 to 10.5.2 and main fail; all 65 tags in that range have == (read). Not fixed upstream.
Versions tested11 rows
Introduced by caf329717ef (LUCENE-7701 "Refactor grouping collectors", #8752; a JIRA patch by romseygeek with a +1 from martijnvg; authored 2017-03-28, committed 2017-04-10; first release 7.0.0). git blame on main points line 129 at 331ccf39106 (LUCENE-8405), which only rewrote the ternary as an if/else. Later changes widened what users see, none of them wrong with the constant: LUCENE-8412 (55bfadbce11, 8.0.0: field-collected hits always NaN), #15879 (b90b9dec25c, 10.5.0: merged maxScore from the first hit), #15603 and #15574 (10.5.0: collector managers that reduce through TopGroups.merge), #16247 (3afffeef5a8, released in 10.6.0: GroupingSearch on the managers). branch_10_6, branch_10x and branch_10_5 still have the check (read).
Executed: the releases in the table. Not executed: 6.0.0-6.4.2, 6.5.1, 6.6.0, 6.6.2-6.6.5, 7.0.1-7.7.2, 8.1.0-8.11.3, 9.1.0-9.12.2 (9.1.0 ran only the 9.x variant), 10.1.0-10.3.2 and 10.5.1. By code reading, every 6.x tag tests equals and every tag from 7.0.0 to 10.5.2 (65) has the identity test exactly once (8.8.2-8.11.4 are untagged in the history clone).
| Version or commit | Verdict | Result |
|---|---|---|
| 6.5.0, 6.6.1, 6.6.6 | not affected | history test passes 7 of 7 (equals check) |
| 7.0.0, 7.7.3 | scores off only | history test fails 1 of 7: hand-sharded merge with getScores=false and getMaxScores=false |
| 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.4.0 | affected | history test fails 2 of 4: wrong page on a hand-sharded merge, maxScore right |
| 9.1.0 | 9.x variant | the hand-sharded 9.x variant fails 1 of 2 (run by the fact check) |
| 10.5.0, 10.5.2 | affected | history test fails 3 of 4 (wrong page, maxScore NaN); the test fails 1 of 5 (collector managers) |
main ea57360912ed | affected | history test 3 of 4 fail; the test 3 of 5 fail (GroupingSearch with an executor, managers, sequential maxScore) |
6.6.6 with == | one-line swap | fails like 7.0.0 |
7.0.0, 8.0.0, 9.12.3, 10.5.2 with equals | one-line swap | every test passes, including maxScore on 10.5.2 |
| main + the fix | not affected | the test passes; the grouping module passes (61 tests) |
| the other tags, 6.0.0-6.6.5 | read, not run | equals check, as in the executed 6.x releases |
| the other tags, 7.0.1-10.5.1 | read, not run | identity check, as in the executed releases around them |
An independent reproducer (17 own tests, 8 fail), an OpenAI GPT-5.6 refute reviewer that ran its own tests, a GPT-5.6 'works as designed' reviewer (reading only), a devil's advocate and an adjudication all say real. A security probe found no effect beyond the ranking inside groups.
Checks and verdicts307 words
All checks ran on main ea57360912ed unless noted, with fixed seeds recorded in their result files.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | The test fails 3 of 5 on main (assertions on and off), 1 of 5 on 10.5.0 and 10.5.2; the 9.x variant fails on 9.12.3; the one-line fix passes 5 of 5; the fix of the sibling tie-break bug LFV-238 leaves 3 of 5 failing. |
| Refute review (OpenAI GPT-5.6) | real (high), intended argument weak | Its own two-segment, two-slice test fails 2 of 3 with assertions on and off and 6 of 9 over 3 iterations of another seed; a maxScore test fails; with the fix its tests and 56 upstream grouping test methods pass. |
| Independent reproducer | real | Own tests with exact scores: 17 run, 8 fail on main (assertions on and off), 9 controls pass; 10.5.2 4 of 17, 9.12.3 1 of 4; with the fix 17 of 17 pass. |
| 'works as designed' review (OpenAI GPT-5.6) | real (high), reading only | Could not run Java; found no identity precondition in the javadocs; a separate run re-ran the test: 3 of 5 fail. |
| Devil's advocate | real | Found that the == check replaced an equals check in a refactor whose migration note promised the old behaviour; re-ran the test with assertions on and off (3 of 5 fail). |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's tests (seed 1A2B3C4D: 17 run, 8 failed; 17 of 17 pass with the fix) and the test with assertions off (3 of 5 fail). |
| Security probe | none | 219,792 checks per run over 1,392 grouped searches (restrictions, deletions, 7 searcher layouts: 1, 2, 8 and 32 slices, an 8-slice searcher with a query cache, two hand-sharded merges): 0 violations, while the bug fired in the same runs. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 560 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,631 words
- Registry title
- Grouping with a within-group sort that equals Sort.RELEVANCE but is a different object (new Sort(), new Sort(SortField.FIELD_SCORE)) returns the wrong documents per group when results from slices or shards are merged, and since 10.5.0 a NaN GroupDocs.maxScore
- Area
- grouping / two-pass grouping (TopGroupsCollector second pass, TopGroups.merge, TopGroupsCollectorManager, GroupingSearch)
- Priority
- Medium, rank 47: A within-group sort that equals but is not the Sort.RELEVANCE constant (for example a request-built new Sort(SortField.FIELD_SCORE)) silently returns the wrong documents per group whenever slices or shards are merged (hand-sharded TopGroups.merge since 8.0.0, the collector managers with an executor since 10.5.0), plus a NaN maxScore since 10.5.0, a natural trigger for direct grouping users, although the default constant is correct and Solr, Elasticsearch and OpenSearch do not reach it.
- Impact class
- silent wrong results
- Impact note
- Applications that pass a within-group sort that equals Sort.RELEVANCE but is not the constant itself (new Sort() or new Sort(SortField.FIELD_SCORE), for example built from a 'sort by score' request) get the wrong documents inside each group whenever 2 or more collectors are merged: a hand-sharded TopGroups.merge (every release since 8.0.0; in 7.x only with scores and max scores off), the grouping collector managers on an IndexSearcher with an executor and 2 or more slices (10.5.0 on; default slicing gives that above 5 segments or 250k documents), and GroupingSearch itself with such an executor (main and, by reading, 10.6.0); since 10.5.0 GroupDocs.maxScore is also NaN with max scores requested, on main even for a sequential GroupingSearch; the default Sort.RELEVANCE constant is correct on every path, nothing throws, -ea and -da behave the same, and it happens at any index size; Solr normalizes 'score desc' to the constant and Elasticsearch and OpenSearch do not use TopGroupsCollector (code reading).
- Summary
- You run two-pass grouping (GroupingSearch, or the grouping collectors and collector managers) with setSortWithinGroup(new Sort(SortField.FIELD_SCORE)) or new Sort(), both of which equal Sort.RELEVANCE, and expect the same result as with the Sort.RELEVANCE constant: the top-scoring documents of each group, and GroupDocs.maxScore equal to the best score. Instead TopGroupsCollector tests 'withinGroupSort == Sort.RELEVANCE' (same object), so it collects each group with the field-sort collector, whose hits carry score NaN, while TopGroups.merge tests equals and merges those hits by their NaN scores. When results from 2 or more slices or shards are merged, each group's page then comes out slice by slice or shard by shard (the finder's test returns a score-1 document instead of the score-4 one), and since 10.5.0 the merged maxScore is NaN, on main even for a sequential GroupingSearch.
- Introduced
- caf329717ef643b2a5a8b7ef0bfb7bd5e096c849 (LUCENE-7701 'Refactor grouping collectors', a JIRA patch by romseygeek with a +1 from martijnvg, migrated as apache/lucene#8752, no GitHub PR; master only, first released in 7.0.0): it replaced the old second-pass collector's 'withinGroupSort.equals(Sort.RELEVANCE)' with 'withinGroupSort == Sort.RELEVANCE' in the new TopGroupsCollector, without comment [read: git log -S in the full-history clone, git tag --contains; exec: one-line swaps on release jars, see affected_versions]. git blame on main points line 129 at 331ccf39106 (LUCENE-8405), which only turned the ternary into an if/else and kept the test. Later changes widened what users see, none is wrong with the constant: 55bfadbce11 (LUCENE-8412, apache/lucene#9459, 8.0.0: field-collected hits always score NaN), #15879 (b90b9dec25c, 10.5.0: merged maxScore taken from scoreDocs[0].score), #15603 and #15574 (8e443458c2f, 5c701b3f553, 10.5.0: collector managers that reduce through TopGroups.merge) and #16247 (3afffeef5a8 on main, d60e550b47f on branch_10_6, released in 10.6.0: GroupingSearch runs on the managers) (2017-03-28 (author date of caf329717ef; committed to master 2017-04-10))
- First affected version
- 7.0.0 [exec] (2017-09-08; there only for a hand-sharded TopGroups.merge with getScores=false and getMaxScores=false); 8.0.0 [exec] is the first release in which the default flags show it; 10.5.0 [exec] is the first with the NaN maxScore and the collector-manager path; last unaffected release 6.6.6 [exec] (6.6.1 is the last release before 7.0.0)
- Affected versions
- 7.0.0-7.7.3: only a hand-sharded TopGroups.merge with getScores=false and getMaxScores=false [exec 7.0.0 -ea and -da, 7.7.3: history test fails 1 of 7]; 8.0.0-10.4.0: every hand-sharded TopGroups.merge returns the wrong documents, maxScore correct [exec 8.0.0, 8.11.4, 9.0.0, 9.12.3 -ea and -da, 10.0.0, 10.4.0: 2 of 4 fail; the finder's and the independent reproduction's 9.x shard-merge tests fail on 9.12.3]; 10.5.0-10.5.2: also the collector managers (wrong documents with an executor, NaN maxScore even with one slice) and a NaN merged maxScore [exec 10.5.0, 10.5.2 -ea and -da: 3 of 4 fail; finder 1 of 5, the independent reproduction 4 of 17 on 10.5.2]; main ea57360912ed: also GroupingSearch (wrong documents with an executor, NaN maxScore sequentially) [exec -ea and -da: finder 3 of 5, the independent reproduction 8 of 17, history test 3 of 4]; branch_10_6 (10.6.0, released 2026-10-29), branch_10x and branch_10_5 still have the identity test at line 129 [read through the upstream contents API on 2026-10-26], so 10.6.0 is very likely affected (not executed); not executed: 7.1.0-7.7.2, 8.1.0-8.11.3, 9.1.0-9.12.2, 10.1.0-10.3.2 and 10.5.1, each between executed releases with the same behaviour, and every one of them tagged in the history clone has the identity test [read] (8.8.2-8.11.3 are untagged there); unaffected: 5.5.0-6.6.6 (equals test on every tag) [read; exec 6.5.0, 6.6.1, 6.6.6 -ea and -da pass 7 of 7]; one-line swaps flip the result both ways [exec: 6.6.6 with the identity test fails like 7.0.0; 7.0.0, 8.0.0, 9.12.3 and 10.5.2 with equals pass every test]; not fixed in any release or on main
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record verdict new: 162 logged read-only queries, 57 through a scripted prior-report search (13 GitHub issue/PR queries on apache/lucene, 28 mailing-list queries over dev@, java-user@, issues@ and commits@, 8 LUCENE JIRA-archive and 8 web queries), 80 GitHub GraphQL searches including 14 over Elasticsearch, OpenSearch and Solr (0 hits for TopGroupsCollector, withinGroupSort and TopGroups.merge NaN), 7 SOLR JIRA queries, 13 commit-message patterns over the full history plus the upstream commits after the snapshot, and scans of the changed files of all 413 open apache/lucene PRs and of the 491 issues and PRs updated since 2026-09-01; 17 hits read, none the same bug); not fixed upstream (main, branch_10x, branch_10_6 and branch_10_5 still have 'withinGroupSort == Sort.RELEVANCE' at TopGroupsCollector.java:129); the open PRs on the same file keep the test: #16569 ('Omit computing max score when sorting by score primarily in TopGroupsCollector', stale, no reviews) edits the adjacent non-RELEVANCE branch and, shadowed over main, leaves every failure in place, and #16548 (totalHitsThresholdPerGroup) does not touch it; closest items, not reports: LUCENE-7701 / #8752 (introduced the identity test), #15879 (introduced the NaN maxScore symptom), LUCENE-6900 / #7958 and SOLR-9783 (the same one-line equals change made in Solr code in 2015-2016), SOLR-5046 (an analogous collection-versus-merge relevance mismatch in Solr's distributed group.query, open since 2013, different code)
- Lucene commit tested
- main
ea57360912ed(commit of 2026-10-24; tested 2026-10-26): the test through gradle in a scratch worktree (assertions on and off) and through a standalone JUnit harness (seeds DEADBEEF and 7A11C0DE, assertions on and off); the Maven Central jars of 10.5.0 and 10.5.2 (the same test) and 9.1.0 and 9.12.3 (a 9.x shard-merge variant); a two-shard history test on 6.5.0, 6.6.1, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.2 and main, plus one-line swaps on 6.6.6, 7.0.0, 8.0.0, 9.12.3 and 10.5.2; the fix in the scratch worktree (the test, the whole grouping module with assertions on and off and a second seed,:lucene:grouping:check -x test), removed afterwards, and shadowed in the standalone harness (the test, assertions on and off, two seeds).
- Finding record
lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroupsCollector.java:127-147 (TopDocsReducer; identity test at :129, TopScoreDocCollector branch :130-136, TopFieldCollector plus MaxScoreCollector branch :137-146)lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroups.java:183 (sortByRelevance = docSort.equals(Sort.RELEVANCE)), :239-245 (TopDocs.merge by score, maxScore from scoreDocs[0].score), :405 (groupSort equals); TopGroupsCollectorManager.java:112-116 (reduce always calls TopGroups.merge); GroupingSearch.java:56 (includeMaxScore defaults to true), :197-211 (second pass through TopGroupsCollectorManager)lucene/grouping/src/java/org/apache/lucene/search/grouping/AllGroupHeadsCollector.java:63, AllGroupHeadsCollectorManager.java:146, BlockGroupingCollector.java:275 and :285 (every other relevance test in the module uses equals); GroupDocs.java:27 ('Max score in this group')lucene/core/src/java/org/apache/lucene/search/Sort.java:26-29 (class javadoc: an empty constructor yields a relevance sort), :37-41 (RELEVANCE = new Sort()), :50-56 (Sort() 'Sorts by computed relevance', delegates to Sort(SortField.FIELD_SCORE))
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroupsCollector.java:122 (TopDocsReducer), :127-148 (its constructor; identity test :129), :177-199 (getTopGroups: per-group maxScore)Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroups.java:112-135 (merge javadoc), :183, :218-220, :231-233, :241, :244-245Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/TopGroupsCollectorManager.java:112-123; GroupingSearch.java:52, :56, :197-212Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/AllGroupHeadsCollector.java:63, AllGroupHeadsCollectorManager.java:146, BlockGroupingCollector.java:275, :285, TopGroups.java:405 (equals)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/Sort.java:27-29, :41, :49-56, :114-119; FieldValueHitQueue.java:36-38; TopDocs.java:44-45, :110-120; IndexSearcher.java:106-108, :226-231, :323-324, :350-379, :545-548Lucene main ea57360912ed grep over lucene/ for '== Sort.<CONSTANT>': TopGroupsCollector.java:129 and the test TestSearchAfter.java:236 only
- Who is affected
Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/package-info.java:76-77; GroupingSearch.java:52, :296-305
- Why it looks unintended
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/Sort.java:27-29, :41, :49-56, :114-119Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupingSearch.java:296-305; GroupDocs.java:27; TopGroups.java:112-115, :183, :363; FirstPassGroupingCollector.java:71, :85; BlockGroupingCollector.java:203; package-info.java:76-77Lucene main ea57360912ed: lucene/grouping/src/test/org/apache/lucene/search/grouping/TestAllGroupHeadsCollector.java:363-371, :504, :511-514, :533, :542-548; AllGroupHeadsCollectorManager.java:146; TestDistinctValuesCollector.java:147, :153; TestGrouping.java:524-542; grep of setSortWithinGroup / TopGroupsCollectorManager in lucene/grouping/src/test
- Suggested fix
Lucene main ea57360912ed: lucene/grouping/src/java/org/apache/lucene/search/grouping/GroupDocs.java:29-30
- TestEqualRelevanceSortShardMerge.java (JUnit test):
repro/LFV-232/src/org/apache/lucene/search/grouping/TestEqualRelevanceSortShardMerge.java(68 lines)
The diagram shows the repro's group on two slices, the two relevance checks (== in the collector, equals in the merge) and the merged page with each sort. Its numbers come from the diagram probe run on ea57360912ed. In the "actual" rows the returned hits carry score NaN, so their tiles show each hit's sort value (its score) instead of a score.
assets/LFV-232/bug.png(560 KB)