The document suggester searches each segment with a bounded queue of candidates and drops a deleted document's completion only at the end, so it is meant to keep a few spare candidates when the segment has deletions.
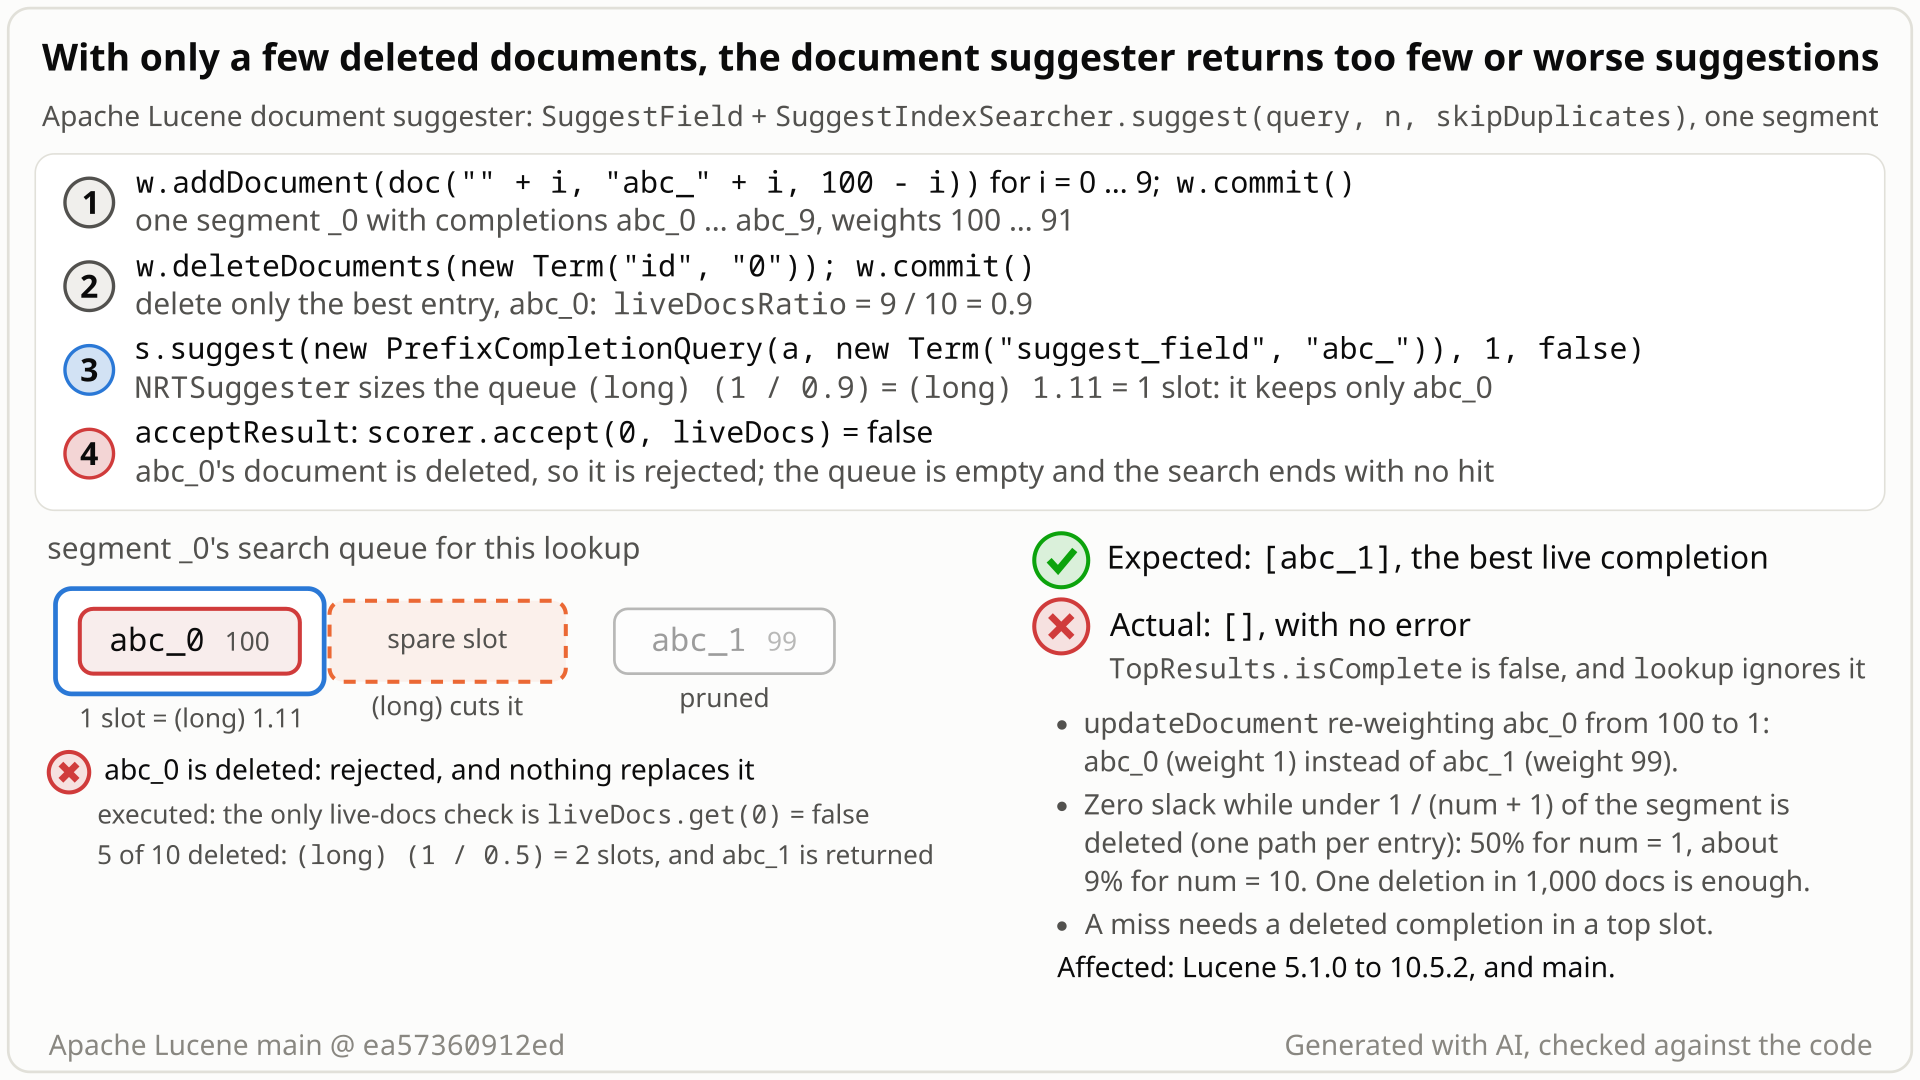
- Index 10 suggestions
abc_0..abc_9with weights 100..91 in one segment (SuggestFieldwith a completion postings format), then delete the document ofabc_0, the best one. - Call
suggest("abc_", 1). You expect the best live suggestion,abc_1(weight 99). You get[]. - Why: each segment is searched with a small queue of candidates, sized
n / liveDocsRatio(with one path per entry) to leave room for deleted entries. Here that is 1 / 0.9 = 1.11, and the cast(long)rounds it down to 1. The one slot holdsabc_0, which is then rejected as deleted, and nothing is left to replace it. - The everyday form:
updateDocumentlowersabc_0's weight from 100 to 1. The deleted old copy still tops its segment, so the lookup returnsabc_0at weight 1 instead ofabc_1at 99. One deletion in 1,000 documents empties the lookup too. - Deleting more, 5 of 10, leaves a spare slot and the lookup works. Rounding up (
Math.ceil) instead returnsabc_1, and the suggest module's 241 tests pass with it.
Anyone using the document suggester (SuggestField or ContextSuggestField with a completion postings format) who deletes or updates documents; by code reading, the Elasticsearch and OpenSearch completion suggesters use it. One deletion, in a segment of 3 documents or of 1,000 (num = 1), can drop or demote a top suggestion, silently, until a merge reclaims the deletion.
Mechanism, terms and numbers727 words
The document suggester (SuggestField or ContextSuggestField with a completion postings format, queried through SuggestIndexSearcher.suggest) searches each segment's FST with a bounded queue of candidate paths and rejects a completion of a deleted document only when its path completes. NRTSuggester.getMaxTopNSearcherQueueSize therefore enlarges the queue "to account for the filtered out suggestions", as (long) (k / liveDocsRatio) with k = topN x analyzed paths per entry; the cast rounds down, so for any segment with liveDocsRatio > k/(k+1) (under 50% deleted for n = 1, under 9.1% for n = 10, one path per entry) the queue is exactly k again, with no spare slot. A deleted completion in one of the segment's top slots is then dropped and nothing replaces it: with abc_0, the best of abc_0..abc_9, deleted, suggest("abc_", 1) returns [] instead of [abc_1], and after updateDocument lowers abc_0's weight from 100 to 1 it returns abc_0/1 instead of abc_1/99. No error is raised. The line is the same in every release since the document suggester appeared, 5.1.0 (2015), through 10.5.2, and the bug reproduces on the 13 releases run and on main. Rounding up fixes every tested case in which one deleted completion takes a result slot and passes the suggest module's 241 tests with assertions on and off; it covers one deleted completion per segment, so a deleted document with two top completions still needs a re-search while the result is incomplete.
- Document suggester:
SuggestField/ContextSuggestFieldvalues indexed with a completion postings format (for exampleCompletion104PostingsFormat) and looked up withSuggestIndexSearcher.suggest(query, n, skipDuplicates). Each segment holds its completions in an FST;NRTSuggester.lookupsearches it. - Queue:
Util.TopNSearcherkeeps at mostmaxQueueDepthcandidate paths. Once full, a path that does not beat the worst one is dropped (Util.java:215-236), and an add beyond the limit evicts the worst (:246-250). - Rejection: when a path completes,
acceptResultchecks the document against the live docs (NRTSuggester.java:205-209,CompletionScorer.java:89-91). A deleted document's completion is rejected and only counted (Util.java:394-398).
lookupcomputesliveDocsRatio = numDocs / maxDoc(NRTSuggester.java:126-127,:304-306) andtopN = n * prefixPaths.size()(:142), and sizes the queue withgetMaxTopNSearcherQueueSize(:143-144).- That method computes
k = topN * maxAnalyzedPathsPerOutput(:294) and thenmaxQueueSize = (long) (maxQueueSize / liveDocsRatio);(:297). The cast rounds down:(long) (k / r) == kwheneverr > k / (k + 1). Only a filter adds more (numDocs / 2,:298-300); the cap is 5000 (:92,:301). - With a queue of exactly
k, the alternatives were already pruned whileaddStartPaths(Util.java:264-292) seeded the queue: each arc after the best one is added and evicted again (:246-250). A rejected completion leaves its slot empty; the search ends (whenmaxQueueDepth == topNit also skips the queue for the last result,Util.java:340-343, but removing that shortcut does not fix the bug). search()reports the result as incomplete (isComplete = rejectCount + topN <= maxQueueDepth,Util.java:409), andlookupignores it (NRTSuggester.java:254-259). In the merged topnthe slot stays empty or goes to a lower-ranked hit of another segment.
| case | n | live ratio | queue | returned | expected (and with the fix) |
|---|---|---|---|---|---|
abc_0 of 10 deleted | 1 | 0.9 | (long) 1.11 = 1 | [] | [abc_1/99] |
abc_0 of 1,000 deleted | 1 | 0.999 | (long) 1.001 = 1 | [] | [abc_1/9999] |
updateDocument(abc_0), weight 100 -> 1 | 1 | 0.9 | 1 | [abc_0/1] | [abc_1/99] |
abc_1 of 10 deleted | 2 | 0.9 | (long) 2.22 = 2 | [abc_0/100] | [abc_0/100, abc_2/98] |
| control: 5 of 10 deleted | 1 | 0.5 | (long) 2.0 = 2 | [abc_1/99] | same |
The zero-slack range: under 50% deleted for k = 1, under 16.7% for k = 5, under 9.1% for k = 10. Which deleted completion costs a slot depends on how keys share prefixes: with keys whose top entries each have their own arc (abc_0..abc_9; the independent reproduction's s_0..s_{N-1}) a deletion anywhere in the top n was lost in every zero-slack case of a 370-case sweep; with item00..item99 a deletion in the last slot of num=5 was lost, while one at rank 3 was handled.
Exposure and likelihood349 words
- Who is hit. Users of the document suggester, an opt-in per field (a completion postings format), with
PrefixCompletionQuery,FuzzyCompletionQueryorContextQuery; all three missed hits in the finder's harness.RegexCompletionQuerygoes through the same lookup (by reading; not run). By code reading, the Elasticsearch and OpenSearch completion suggesters call it with the segment's live docs; nothing was run downstream. - Ordinary operations. One
deleteDocuments, or oneupdateDocument, the usual way to change a suggestion's weight, which leaves the old copy deleted in its segment. No other setting is needed, and a large segment does not protect: one deletion leaves no slack in any segment of at leastk + 2documents (3 fornum = 1), so 1 deletion in 1,000 documents is enough. - Silent and deterministic. No exception or warning;
-eaand-dabehave the same. The result is short, or a lower-ranked suggestion takes the slot (weight 1 instead of 99 in the update case). - Wide range. Zero slack for any segment under 50% deleted at
n = 1, under 16.7% atn = 5, under 9.1% atn = 10(one prefix path, one analyzed path per entry). - Not every lookup. A miss needs a deleted completion in one of the segment's top slots for the queried prefix, and the slot must matter in the merged top
n. In the finder's harness (3,000 random indexes of at most 6 documents, about a third of them with one deleted document; 4,680,000 lookups over all of them) 798 lookups missed a hit and 96 returned a lower-scored hit from another segment (the harness labels these 96 "unexplained"; all go away with only theMath.ceilchange); a run without deletions had neither kind. Merges reclaim deletions over time. - Masked by filters. With a
BitsProducerfilter the queue getsnumDocs / 2extra slots; in the probe's filter cases that masked the rounding (the same results with and without the fix), though a restrictive filter can still over-prune (6 of 176 filter lookups short both ways). - How common in production was not measured.
The test shows that the document suggester returns too few suggestions from a segment with few deletions: NRTSuggester's deleted-document queue slack (long)(topN / liveDocsRatio) rounds back down to topN (here (long)(1 / 0.9) = 1), so a deleted completion takes the only queue slot and nothing replaces it.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.codecs.PostingsFormat;
import org.apache.lucene.codecs.lucene104.Lucene104Codec;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.IntPoint;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestNRTSuggesterOneDeletion extends LuceneTestCase {

  public void testDeletedTopCompletionIsReplaced() throws Exception {
    Analyzer analyzer = new MockAnalyzer(random());
    IndexWriterConfig iwc = new IndexWriterConfig(analyzer);
    iwc.setCodec(
        new Lucene104Codec() {
          final PostingsFormat completion = new Completion104PostingsFormat();

          @Override
          public PostingsFormat getPostingsFormatForField(String field) {
            return completion;
          }
        });
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (int i = 0; i < 10; i++) {
          Document doc = new Document();
          doc.add(new IntPoint("id", i));
          doc.add(new SuggestField("suggest", "abc_" + i, 100 - i));
          w.addDocument(doc);
        }
        w.deleteDocuments(IntPoint.newExactQuery("id", 0));
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        PrefixCompletionQuery query =
            new PrefixCompletionQuery(analyzer, new Term("suggest", "abc_"));
        List<String> keys = new ArrayList<>();
        for (TopSuggestDocs.SuggestScoreDoc hit :
            new SuggestIndexSearcher(reader).suggest(query, 1, false).scoreLookupDocs()) {
          keys.add(hit.key.toString());
        }
        // one segment, abc_0 (best of 10) deleted: expected [abc_1], actual []
        assertEquals(List.of("abc_1"), keys);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-242/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.document.TestNRTSuggesterOneDeletion
- Expected vs actual
- Expected for one segment abc_0..abc_9 (weights 100..91) with abc_0 deleted,
suggest(prefix "abc_", num=1):[abc_1]; actual:expected:<[abc_1]> but was:<[]>, with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<[abc_1]> but was:<[]>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.document.TestNRTSuggesterOneDeletion.testDeletedTopCompletionIsReplaced(TestNRTSuggesterOneDeletion.java:67)- The sizing javadoc says the queue "has to be increased by some factor, to account for the filtered out suggestions"; the cast makes the increase zero.
- The documented caveat is "too many deletions"; here one deletion triggers it.
suggest"Returns top n completion hits", and the searcher itself flags such a search as incomplete.
The full argument235 words
- The method's own promise.
NRTSuggester.java:281-284: "Since suggestion entries can be rejected if they belong to a deleted document, the length of the TopNSearcher queue has to be increased by some factor, to account for the filtered out suggestions." - The public contract.
SuggestIndexSearcher.suggest: "Returns top <code>n</code> completion hits for <code>query</code>" (SuggestIndexSearcher.java:49). - The caveat covers the opposite case. Class NOTE (
NRTSuggester.java:58-60): "having too many deletions or using a very restrictive filter can make the search inadmissible due to over-pruning of potential paths". One deletion in 10 or in 1,000 triggers this bug; 5 of 10 deleted does not. - Incomplete by the searcher's own test.
isComplete = rejectCount + topN <= maxQueueDepth(Util.java:409): a queue of exactlytopNhas no room for one rejection. - Sibling code sizes for rejections.
FreeTextSuggester.java:605-608: "Must do num+seen.size() for queue depth because we may reject up to seen.size() paths in acceptResult()". - Precedent. LUCENE-4481 / #5547 (2012), a bounded TopNSearcher queue with rejected results in another suggester, was fixed as a bug.
- Why tests missed it.
TestSuggestField.testNRTDeletedDocFilteringdeletes every other document and asks for all live ones;testSuggestOnAllDeletedDocumentsandtestSuggestOnMostlyDeletedDocumentsdelete all or all but one. None is in the zero-slack range. - History. The LUCENE-6339 issue thread discussed the filter heuristic, a
longoverflow and nearly-all-deleted tests, not rounding or few deletions (its patch attachments were not read). No CHANGES or MIGRATE entry mentions it.
The devil's-advocate check247 words
The case for "intended" (the cross-model reviews rated it moderate; the independent reproduction, the intended-behaviour check and the adjudication examined it): the class NOTE says the search can over-prune; the javadoc calls the sizing "Simple heuristics" and says "the search can still lead to over-pruning"; lookup deliberately does not assert isComplete ("search admissibility is not guaranteed"); the package is @lucene.experimental; the collector "Collects at most <code>num</code> completions".
Why it fails:
- The caveat names too many deletions or a very restrictive filter; the trigger is a single deletion, and spare room appears only once about half the segment is deleted (
num = 1: 5 of 10 works, 4 of 10 still fails). - The heuristic is not imperfect here, it is switched off: the documented increase is zero.
@lucene.experimentalmeans "This API is experimental and might change in incompatible ways in the next release"; it says nothing about wrong results. "At most num" is an upper bound, not permission to return fewer when more exist.
What a maintainer could still raise: best-effort admissibility is documented and the javadoc's caveat ("the search can still lead to over-pruning") is unconditional, so the change may read as an improvement to a heuristic; the 5000 cap bounds the work by design; and the one-line fix is partial: a deleted document with several top completions still empties the lookup, which is defensible as best effort. The updateDocument case (a worse hit, not just a short list) is the hardest to defend.
Recommended A: round the deleted-document slack up
Round the slack up: (long) Math.ceil(maxQueueSize / liveDocsRatio) in NRTSuggester.getMaxTopNSearcherQueueSize, one line. The repro then passes, and so do all 241 suggest-module tests. It covers one deleted completion per segment; a deleted document with two top completions still empties the lookup, which needs a re-search while the result is incomplete.
// NRTSuggester.getMaxTopNSearcherQueueSize, line 297
-    maxQueueSize = (long) (maxQueueSize / liveDocsRatio);
+    // round up: truncating returns maxQueueSize unchanged whenever liveDocsRatio >
+    // maxQueueSize / (maxQueueSize + 1), leaving no room for a rejected (deleted) completion
+    maxQueueSize = (long) Math.ceil(maxQueueSize / liveDocsRatio);
All options and trade-offs3 options · 639 words
Option A was validated with gradle in scratch worktrees at ea57360912ed (JDK 25.0.3), with assertions off and with -Ptests.asserts=true, and through the repro runner with -ea and -da; options B and C were not run.
Change the cast in getMaxTopNSearcherQueueSize to Math.ceil. A segment with any deletion then gets at least one spare slot (while the 5000 cap does not bind): ceil(1 / 0.9) = 2 keeps abc_0 and abc_1, abc_0 is rejected and abc_1 is returned. The same code change as the finder's patch; the comment was reworded to state the rule with k.
// NRTSuggester.getMaxTopNSearcherQueueSize, line 297
-    maxQueueSize = (long) (maxQueueSize / liveDocsRatio);
+    // round up: truncating returns maxQueueSize unchanged whenever liveDocsRatio >
+    // maxQueueSize / (maxQueueSize + 1), leaving no room for a rejected (deleted) completion
+    maxQueueSize = (long) Math.ceil(maxQueueSize / liveDocsRatio);
Trade-offs
- Partial. One spare slot covers one rejected completion. A deleted document with two completions that both outrank every live one still empties a
num=1lookup (TestSuggestFewDeletionsLimit:[]instead of[abc_1/99], on stock and with the fix). The finder's harness with only this change still finds 60 of 4,680,000 lookups that miss, all where the deleted document has two or more matching completions. - Cost. At most one extra queue entry per segment lookup when the segment has deletions; nothing changes without deletions (
k / 1.0is exact). The 5000 cap stays. Not benchmarked. - Behaviour. Only lookups that were short or wrong change; no index format change.
- Coverage. The JUnit tests use one prefix path and one analyzed path per entry; several prefix paths (fuzzy queries) were exercised only by the randomized harness, and several analyzed paths per entry (graph analyzers, synonyms) by no test.
What the checks validated
- The repro: 4 of 5 fail on stock, 5 of 5 pass with the fix (gradle with assertions off and with
-Ptests.asserts=true; the repro runner with-eaand-da). :lucene:suggest:test --tests 'org.apache.lucene.search.suggest.document.*': 7 suites, 63 tests (58 upstream + 5 new), 0 failed, through gradle with assertions off (seeds 1A2B3C4D and 77AA77AA) and through the repro runner with-ea(seed 5EED1234).- All of
:lucene:suggest:test: 241 tests (236 upstream + 5 new), 7 skipped, 0 failed, seed 1A2B3C4D, with assertions off and with-Ptests.asserts=true. :lucene:suggest:checkGoogleJavaFormatpasses with the fix and the new test (re-run after the comment rewording).- Earlier stages: the finder's, the independent reproduction's (370-case sweep: 0 misses), the cross-model review's and the intended-behaviour check's tests pass with it; 5.1.0 with the line changed passes the finder's scenario.
When search() reports isComplete == false, repeat with a larger queue (for example doubled), up to the 5000 cap and a bounded number of retries. LUCENE-4481 discussed the same idea for another suggester. Not implemented or run.
Trade-offs
acceptResult collects hits and records surface forms for skipDuplicates as side effects, so a retry must buffer a segment's hits until its search is complete, or reset that state; otherwise hits are collected twice. A heavily deleted or filtered segment can cost several searches, bounded by the cap and the retry limit. By the searcher's own completeness test it would also cover A's limit case (by reading); beyond the cap the documented over-pruning remains.
Use k + (maxDoc - numDocs), capped, instead of dividing by the ratio. Not run.
Trade-offs
Covers several deleted documents among the top results, but in A's limit case (one deleted document with two top completions) it also gives a queue of 2 and would miss the same way (by reading). Gives large queues to segments with many deletions.
An AI tool compared the document suggester on the main jar with an independent reference of the documented top-n results over random indexes of at most 6 documents. One unexplained missing completion, in a 3-document segment with one deletion, led to the rounding. Verifiers and an adjudication reproduced it with their own tests.
The method in full237 words
Method: randomized bounded translation validation (the hunt's semi-formal tier: the harness's mismatch gave the first signal; no model checker, SMT solver or prover was involved).
- The finder's harness (
NrtTV.java) comparesPrefixCompletionQuery,FuzzyCompletionQueryandContextQueryoverSuggestFieldandContextSuggestField, with several segments, deletions andskipDuplicateson and off, against an independent reference of the documented top-n semantics, over random indexes of at most 6 documents. Its first run reported an unexplained missing live completion in a 3-document segment with one deletion; tracing it led to the truncating line. - At scale, 3,000 random indexes, about a third of them with one deleted document (4,680,000 lookups over all of them), gave 798 missing-hit mismatches plus 96 where a lower-scored hit from another segment took the slot, and 0 such mismatches in a run without deletions. The harness samples randomly and is not exhaustive.
- The finder wrote a public-API JUnit (fails 2 of 3 with
-eaand-da). Claude verifiers wrote their own: the independent reproduction (outside the suggest package; 1 of 1,000 deleted,updateDocument, a 370-case sweep that misses exactly where the queue equalsn) and anupdateDocumentcase,num=5in 100 documents. Reviews by an independent reviewer from another model family (OpenAI GPT-5.6) read the code only; a separate run re-ran the finder's test for each and ran a further test for the second. An adjudication re-ran the tests with fresh seeds.
No report found (searched 2026-10-26: 101 queries over GitHub, JIRA, the mailing lists, downstream code and the web, plus the changed files of all 413 open PRs). Closest: #10038 / LUCENE-8995, where a custom collector cannot signal rejections, a different trigger and fix site.
Searches5 searches
Novelty new (confidence moderate-high): 19 hits read and classified, none the same bug. Related: #10038 / LUCENE-8995 and its unmerged apache/lucene-solr#913 (removing the TopNSearcher last-path shortcut does not fix this bug, executed), where jimczi wrote in an inline review comment that with the current queue-size heuristics "there is no guarantee of admissibility"; #5547 / LUCENE-4481 (bounded queues with rejections in another suggester, fixed); #7400 / LUCENE-6339 (the introducing change). Gaps: GitHub search reads only the first page of broad queries, list search is keyword-based, and private security reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, migrated JIRA issues) | 2026-10-26 | the scripted prior-report search (20 issue/PR and 4 commit queries such as NRTSuggester deleted, getMaxTopNSearcherQueueSize, liveDocsRatio, TopNSearcher isComplete, suggester updateDocument missing) and manual searches (every issue and PR naming NRTSuggester) | no report; #10038 / LUCENE-8995 and #7400 / LUCENE-6339 are related, not the same |
| Open PRs | 2026-10-26 | changed files of all 413 open apache/lucene PRs, for suggest/document/ or util/fst/Util.java | #16847 renames methods in NRTSuggester.java only; the rounding is untouched |
| JIRA archive (LUCENE, SOLR) | 2026-10-26 | 8 tool queries plus manual ones (NRTSuggester, TopNSearcher, SuggestIndexSearcher, admissible AND suggest); comments of 11 related issues read | LUCENE-4481, LUCENE-5519, LUCENE-6459, LUCENE-7686 and others: background, none reports this |
| Downstream (Elasticsearch, OpenSearch, Solr) | 2026-10-26 | code and issue searches | missing-suggestion issues with other causes (several paths to one document, dedup order, size counting); no deletion-slack report |
| Mailing lists (dev@, java-user@, issues@, commits@, solr lists) and the web | 2026-10-26 | 20 tool list queries, manual list queries, 6 tool and several manual web queries, Q&A threads read | nothing describing this mechanism |
Introduced with the document suggester itself, LUCENE-6339 (b7adb6ac770, 2015-03-27), first released in 5.1.0. The same scenario fails on 13 releases from 5.1.0 to 10.5.2 and on main, and the line is the same in every release tag checked; 5.0.0 has no document suggester.
Versions tested6 rows
Introduced by b7adb6ac7704a7e6364ee0d831bf77cf849f2090, "LUCENE-6339: Added Near-real time Document Suggester via custom postings format" (2015-03-27; an svn-era JIRA patch, now issue #7400, no pull request; branch_5x backport 40e94c39ad3). The commit created the whole suggest/document package, including the truncating line; git blame of NRTSuggester.java:297 returns this commit, and so does git log -S 'maxQueueSize / liveDocsRatio' on main's history (with --all it also lists the backport and a 2021 commit that emptied an old branch). Later edits to the method all kept the formula: be4d58c7740 (LUCENE-6459, 5.3.0) changed its parameters and moved the live-docs ratio into lookup, 1b9d98d6ec0 (#11923) widened the multiplication to long, and 2cbf261032d (LUCENE-9570) reformatted it; LUCENE-6459 and LUCENE-6858 (5.4.0) also changed what topN is. The TopNSearcher bounded queue (LUCENE-3714, LUCENE-4481, 2012) is older and correct on its own.
Releases up to 7.7.3 ran on JDK 25 with a JUnit 4 runner, not the JVM they targeted (the control passes in each run); releases not run rest on the code: the truncating line is the same in every release tag checked (5.1.0 to 8.8.1, all of 9.x and 10.x); 8.8.2 to 8.11.x are not tagged in the history clone, and 8.11.4 rests on execution only. Not fixed upstream as of 2026-10-26.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | this page's repro fails 4 of 5 with assertions on and off (gradle and the repro runner); the finder's fails 2 of 3 |
| 9.12.3, 10.5.2 | affected | this page's repro fails 4 of 5 (same messages); the finder's fails 2 of 3 |
| 5.1.0, 5.2.1, 5.3.0, 5.5.5, 6.0.0, 6.4.2, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 10.0.0 | affected | the finder's scenario fails 2 of 3 with the same messages; the control passes |
| 5.0.0 (last before) | no API | no suggest.document package: the repro does not compile |
| 5.1.0 with only the Math.ceil line changed | A/B | the finder's scenario passes 3 of 3: the loss comes from the rounding |
| main with fix A | fix | the repro passes 5 of 5; the suggest module's 241 tests pass (7 skipped), with assertions on and off |
Reproduced on main with and without assertions and on 10.5.2 and 9.12.3. Independent verifiers, an adjudication and a cross-model review confirmed it; a second, read-only review could not run code and returned a procedural "not real" while agreeing on the cause. Fact checks of this page agreed; the one-line fix passes the whole suggest module.
Checks and verdicts474 words
Each check worked from the code or its own runs.
| Check | Verdict | What it found |
|---|---|---|
| Finder's JUnit | candidate | TestNRTSuggesterFewDeletions: 2 of 3 fail on main with -ea and -da, on 10.5.2, 9.12.3, 8.11.4 and 6.6.6; passes 3 of 3 with the fix, and 49 tests of four upstream suggester suites pass with it. |
| Cross-model refute review (OpenAI GPT-5.6, reading only) | not real, low confidence (procedural) | Could not run Java, and the refute review voted not real on procedure only; it agreed with the root cause and found the inputs in contract. A separate run re-ran the finder's JUnit: 2 of 3 fail. |
| Independent reproducer | real | Own JUnit outside the suggest package: 5 of 6 fail on main, 10.5.2 and 9.12.3 with -ea and -da; the 370-case sweep misses in 360 cases, exactly where the queue equals n; the one-line change passes 6 of 6. |
| Works-as-designed review (OpenAI GPT-5.6, reading only) | real, medium confidence | Intended-behaviour argument moderate; a separate test fails 3 of 4 on main and passes with the fix. |
| Intended-behaviour devil's advocate | real, moderate-high | Own JUnit fails 3 of 5 on main and 10.5.2; found that a rank-3 deletion at num=5 is handled and that FreeTextSuggester sizes its queue for every rejection. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with a fresh seed (5 of 6 fail, -ea and -da; 6 of 6 pass with the fix) and the finder's (2 of 3 fail). |
| Security screen | none | Fails closed: 880 lookups per run over five ways of hiding documents returned no hidden document; the bug adds no work. |
| Brief runs | fails 4 of 5 on main, 10.5.2, 9.12.3; fix passes | This page's repro through the repro runner and gradle, the limit test, and the fix with the suggest module's tests and format check; gradle with -Ptests.asserts=true was added after the fact checks. |
| Fact check of this page (re-ran the tests and the harness) | real, reproduced; 5 wording fixes | Re-ran this page's test on main (4 of 5 fail, -ea and -da), 10.5.2 and 9.12.3, the fix (5 of 5 pass), the limit test, the document-package tests with the fix and -ea (63, 0 failed) and the finder's harness (the same counts). Five precision errors, all fixed. |
| Cross-model fact check (OpenAI GPT-5.6, reading only) | bug real; wording and scope findings | Agreed on the mechanism, the failures, the release range and the security rating. 9 errors (one refuted), 7 overclaims and 7 missing caveats, on the fix's scope, the general formula, the harness and history wording and the evidence labels: fixed or answered. |
| Diagram check | pass; 3 minor items fixed | Every value, API name, line number and order of events matched the code and the probe. Three optional wording items were fixed and the visuals re-rendered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 465 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,355 words
- Registry title
- NRTSuggester returns too few or wrongly ranked suggestions in a segment with only a few deleted documents, because its deleted-document queue slack (long)(topN / liveDocsRatio) rounds back down to topN
- Area
- suggest / document (NRT) suggester (NRTSuggester.getMaxTopNSearcherQueueSize via SuggestIndexSearcher and CompletionQuery; Util.TopNSearcher queue depth)
- Priority
- Medium, rank 30: The document suggester silently returns missing or worse suggestions after ordinary updateDocument calls since 5.1, which is broad but module-only.
- Impact class
- silent wrong results
- Impact note
- Applications that use the document suggester (SuggestField or ContextSuggestField with a completion postings format; by code reading the Elasticsearch and OpenSearch completion suggesters call it with the segment's live docs) on any release from 5.1.0 through 10.5.2 or on main get fewer suggestions than requested, or a lower-ranked one in place of a live better one, with no error, whenever a segment has only a small fraction of deleted documents (liveDocsRatio > k/(k+1) with k = num x prefix paths x maxAnalyzedPathsPerOutput, that is under 50% deleted for num=1 and under about 9% for num=10) and a deleted completion lands in one of that segment's top result slots for the queried prefix; an ordinary deleteDocuments or updateDocument is enough, no further setting is needed, and index size does not matter (one deletion in a 1,000-document segment empties a num=1 lookup).
- Summary
- You index suggestions with SuggestField, delete one document or update it (which deletes the old version), and ask SuggestIndexSearcher.suggest for the top n completions; you expect the top n live completions, because NRTSuggester enlarges its bounded search queue 'to account for the filtered out suggestions' of deleted documents. With few deletions that enlargement, (long)(topN / liveDocsRatio), rounds back down to topN (for one deletion in ten documents, (long)(1 / 0.9) = 1), so a deleted completion that takes a result slot is thrown away and nothing replaces it: with abc_0, the best of abc_0..abc_9 in one segment, deleted, suggest('abc_', 1) returns [] instead of [abc_1], and after updateDocument lowers the best entry's weight from 1000 to 1, suggest(num=1) returns that entry at weight 1 instead of the live entry at weight 999. Deleting more documents (5 of 10) gives the queue enough room and the same lookup works.
- Introduced
- b7adb6ac7704a7e6364ee0d831bf77cf849f2090 (LUCENE-6339 'Added Near-real time Document Suggester via custom postings format' by areek, an svn-era JIRA patch now tracked as GitHub issue #7400, committed to trunk on 2015-03-27 with no pull request; branch_5x backport 40e94c39ad3b0f018ae9647b7d30bd0cfe341d86 on 2015-03-28) [read: git blame of NRTSuggester.java:297 and git log -S 'maxQueueSize / liveDocsRatio' in the full-history clone return only this commit; exec: the repro fails 2 of 3 on the 5.1.0 jars and passes 3 of 3 with the one-line Math.ceil change shadowed]. The commit created the whole suggest/document package, including the truncating line. Later edits to getMaxTopNSearcherQueueSize are type-only or formatting (1b9d98d6ec0, #11923, a (long) widening; 2cbf261032d, LUCENE-9570, reformat); LUCENE-6459 (5.3.0) and LUCENE-6858 (5.4.0) changed what topN is and kept the formula. The TopNSearcher bounded queue and its maxQueueDepth == topN last-path shortcut are older (LUCENE-3714 a519b630eea and LUCENE-4481 dc49949558d, 2012) and are correct on their own (2015-03-27)
- First affected version
- 5.1.0 [exec] (the first release with the org.apache.lucene.search.suggest.document package, from the branch_5x backport; the repro fails 2 of 3 there, and passes 3 of 3 with the Math.ceil line shadowed); 5.0.0 has no such package, so the repro does not compile [exec, read]
- Affected versions
- every release from 5.1.0 through 10.5.2 and main ea57360912ed; not fixed in any release or on upstream main as of 2026-10-26 [exec: the finder's scenario fails 2 of 3 with the same messages, and its control passes, on 5.1.0, 5.2.1, 5.3.0, 5.5.5, 6.0.0, 6.4.2, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (main also with -da); the independent reproduction's own test fails 5 of 6 on main, 10.5.2 and 9.12.3 with -ea and -da; the intended-behaviour check's test fails 3 of 5 on main (-ea, -da) and 10.5.2; read: the truncating line is present in every checked tag]. Caveats: releases up to 7.7.3 were run on JDK 25 with a JUnit 4 runner, not the JVM they targeted (the control passes in each run); 8.11.4 is not tagged in the history clone and rests on execution only; release branches after 10.5.2 were not checked
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 101 recorded queries, namely the scripted prior-report search with 62 queries over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr code, the dev@, java-user@, issues@ and commits@ lists, the LUCENE JIRA archive and the web, plus manual GitHub, JIRA (comments of 11 related issues read), mailing-list and web searches; the changed files of all 413 open apache/lucene PRs; local git history; 19 hits read and classified, none the same bug; the finder, the independent reproduction, the intended-behaviour check and the adjudication found nothing either); not fixed upstream (the line is unchanged on upstream main, no CHANGES entry covers it, and the only open PR touching NRTSuggester.java, #16847, only renames); closest items, not reports: #10038 / LUCENE-8995 (open since 2019: a custom TopSuggestDocsCollector cannot signal a rejection, so the search may stop early; a different trigger and fix site) and its unmerged apache/lucene-solr#913, whose review includes a committer's general remark that the queue heuristics give no guarantee of admissibility; its TopNSearcher change does not fix this bug (executed); #5547 / LUCENE-4481 (2012, bounded TopNSearcher queues are inadmissible when results are rejected; a retry-with-a-larger-queue idea); #7400 / LUCENE-6339 (the introducing feature; its review covered the filter heuristic, long overflow and nearly-all-deleted tests, not rounding or few deletions)
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26) on JDK 25.0.3: the repro through the repro runner with -ea and -da (seeds 1A2B3C4D and 0BADC0DE) and through gradle in scratch worktrees, stock and with the fix, with assertions off (as seed 1A2B3C4D picks) and with -Ptests.asserts=true, plus the suggest module's tests with the fix (the worktrees were removed after the runs); the same repro on the 10.5.2 and 9.12.3 jars; the finder's scenario on 13 releases from 5.1.0 to 10.5.2 (history step); fresh-seed re-runs of the finder's and the independent reproduction's tests (registration check); and fact checks, one of which re-ran the repro, the fix and the harness.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:55-67 (at ea57360912ed) (class NOTE: 'having too many deletions or using a very restrictive filter can make the search inadmissible due to over-pruning'; @lucene.experimental), :92 (MAX_TOP_N_QUEUE_SIZE = 5000), :126-144 (liveDocsRatio = numDocs/maxDoc, topN = getCountToCollect() x prefix paths, queue size), :207-209 (scorer.accept rejects deleted documents before collect), :254-259 (search() result and isComplete ignored, '// assert search.isComplete;'), :280-302 (getMaxTopNSearcherQueueSize javadoc 'the length of the TopNSearcher queue has to be increased by some factor, to account for the filtered out suggestions'; :297 'maxQueueSize = (long) (maxQueueSize / liveDocsRatio);'; :298-300 numDocs/2 slack only when a filter is set; :301 cap)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:49-50 (at ea57360912ed) ('Returns top <code>n</code> completion hits for <code>query</code>'); TopSuggestDocsCollector.java:74 ('Collects at most num completions')lucene/core/src/java/org/apache/lucene/util/fst/Util.java:307 (at ea57360912ed) (rejectCount), :340-342 (last path taken without the queue when maxQueueDepth == topN), :397 (rejected result only counted), :409 (isComplete = rejectCount + topN <= maxQueueDepth)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:55-67, 92, 123-144, 190-228, 254-259, 280-306lucene/core/src/java/org/apache/lucene/util/fst/Util.java:209-252, 294-410lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionScorer.java:82-92lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:64-86
- Who is affected
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:142-144, 292-302
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:55-67, 254-259, 280-302lucene/suggest/src/java/org/apache/lucene/search/suggest/document/SuggestIndexSearcher.java:49lucene/suggest/src/java/org/apache/lucene/search/suggest/document/TopSuggestDocsCollector.java:74lucene/core/src/java/org/apache/lucene/util/fst/Util.java:409lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FreeTextSuggester.java:605-608lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestSuggestField.java:434-471, 508, 537build-tools/build-infra/src/main/java/org/apache/lucene/gradle/plugins/java/RenderJavadocPlugin.java:502
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/NRTSuggester.java:205-228, 292-302; lucene/core/src/java/org/apache/lucene/util/fst/Util.java:409
- TestNRTSuggesterOneDeletion.java (JUnit test):
repro/LFV-242/src/org/apache/lucene/search/suggest/document/TestNRTSuggesterOneDeletion.java(71 lines)
A summary diagram (PNG), produced separately from this text from executed probe runs on main.
assets/LFV-242/bug.png(465 KB)