Lucene answers two questions for a query: which documents match (the scorer) and, for one document, did it match and where (Weight#matches, used by highlighters). For queries rewritten with DocValuesRewriteMethod the first answer comes from doc values and the second from the postings, so on a doc-values-only field they disagree.
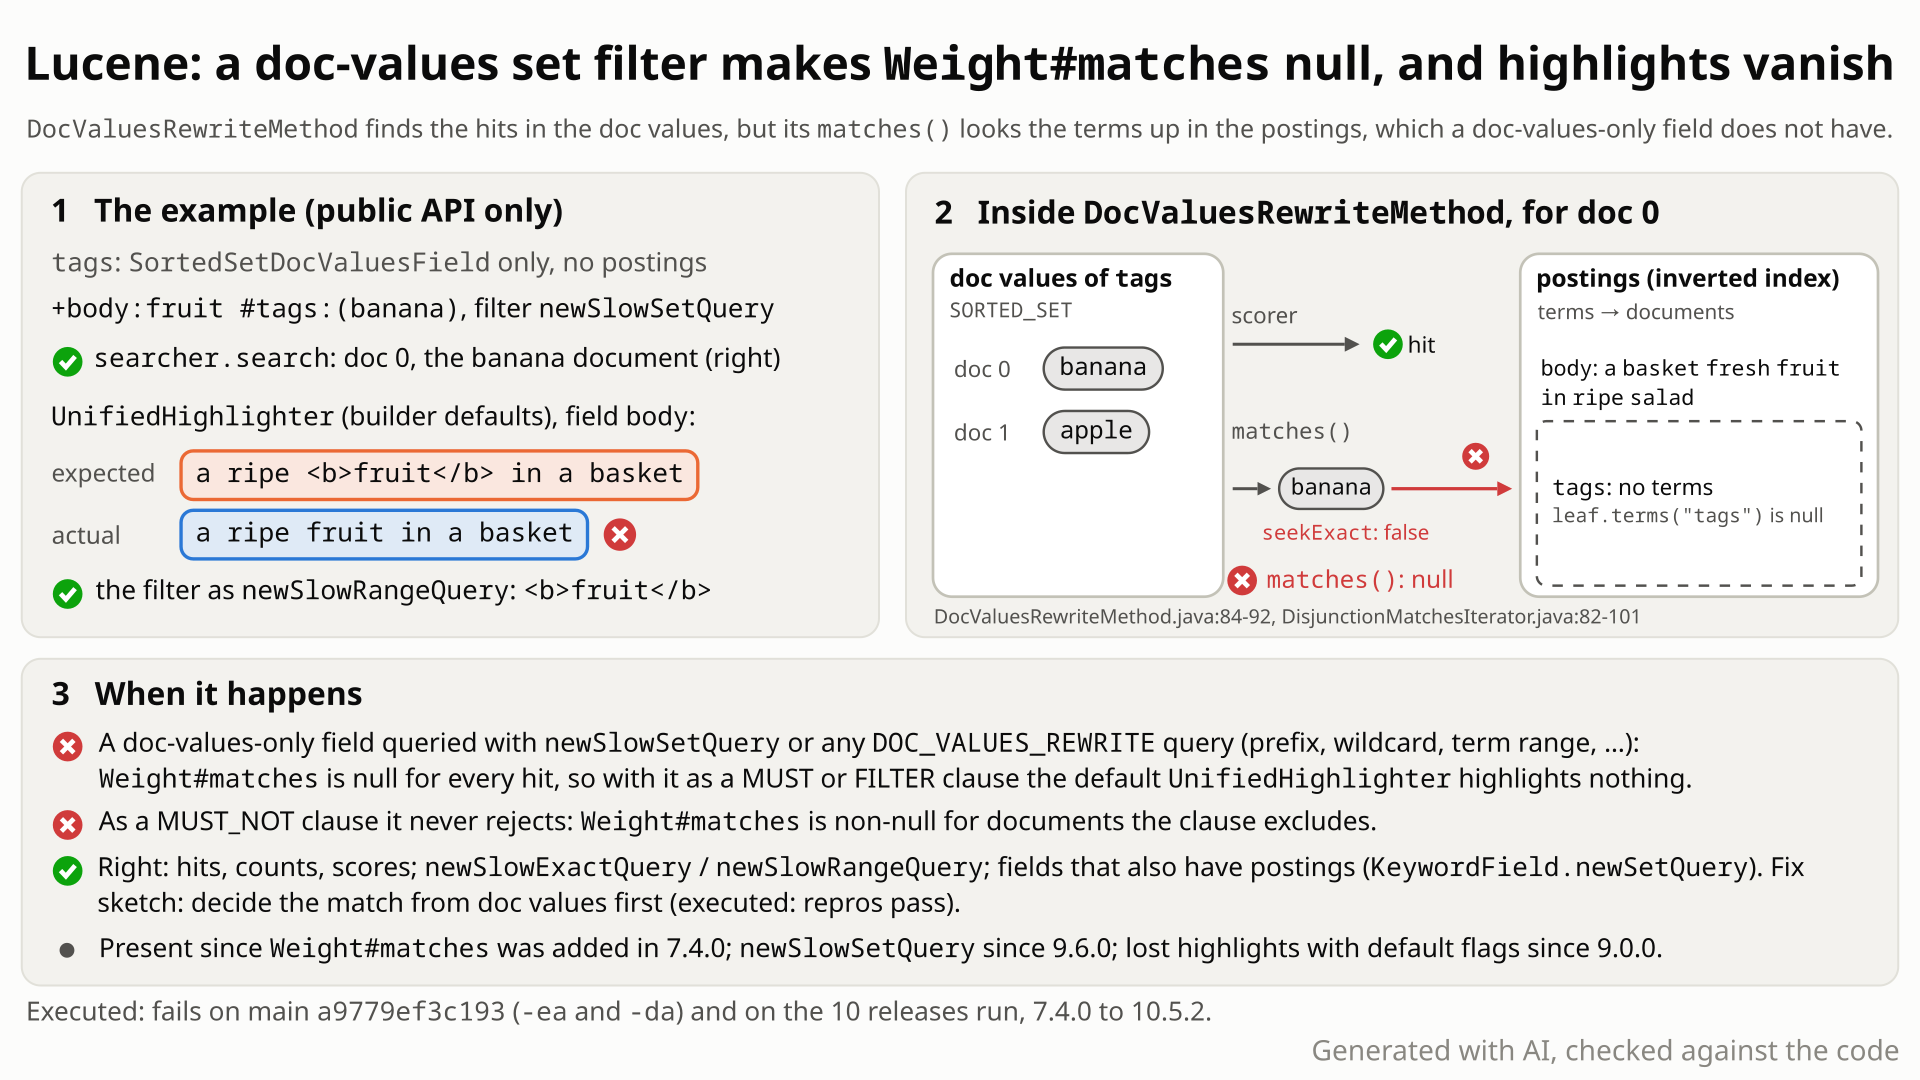
matches() looks "banana" up in the postings, where tags has no terms, and returns null, so the highlighter returns the passage with nothing highlighted. Select the still to open it at full size. Generated with AI, checked against the code.- You index 3 documents with
body= "fruit" and atagsfield kept only as doc values (SortedSetDocValuesField: apple, banana, cherry), and search+body:fruit #tags:(banana)with the filter fromSortedSetDocValuesField.newSlowSetQuery. The search is right: 1 hit, the banana document (doc 1). - You ask whether doc 1 matched with
Weight#matches, as the UnifiedHighlighter does by default. You expect a non-null answer: the javadoc says a DocValues query match returnsMATCH_WITH_NO_TERMS, andnewSlowExactQueryon the same field gives one. - Instead you get null. The filter found doc 1 in the doc values, but its
matches()looks "banana" up in the postings, which this field does not have. So it says "no match" for every hit, and one required clause saying no makes the whole query say no. - With a text body "a ripe fruit in a basket" and the same filter, the default UnifiedHighlighter returns
a ripe fruit in a basket, nothing highlighted; withnewSlowRangeQueryas the filter it returnsa ripe <b>fruit</b> in a basket. - As a MUST_NOT clause it fails the other way:
+body:fruit -tags:(banana)correctly returns docs 0 and 2, butWeight#matchesis non-null for the excluded doc 1. Hits, counts and scores are never wrong.
Applications that keep a field as doc values only and filter on it with newSlowSetQuery or a DOC_VALUES_REWRITE prefix, wildcard, regexp, range or set query, and that read Weight#matches: mostly highlighting with the default UnifiedHighlighter (9.0.0 on) or monitor's HighlightsMatch. For them it happens on every hit, at any index size.
Mechanism, terms and numbers774 words
Queries rewritten with DocValuesRewriteMethod (SortedSetDocValuesField.newSlowSetQuery, SortedDocValuesField.newSlowSetQuery, and any MultiTermQuery with MultiTermQuery.DOC_VALUES_REWRITE) find their hits from doc values, as the rewrite's javadoc promises for "an unindexed docvalues field". But the weight's matches() hands the matching doc-values terms to DisjunctionMatchesIterator.fromTermsEnum, which looks them up in the field's postings. A doc-values-only field has none, so Weight#matches returns null for every hit, although its javadoc reserves null for documents that do not match and says a DocValues query match returns MATCH_WITH_NO_TERMS. A BooleanQuery with such a MUST or FILTER clause then has null Matches for all its hits, so the UnifiedHighlighter, which uses Weight#matches with its default flags since 9.0.0, highlights nothing; as a MUST_NOT clause the same null never excludes anything. Hits, counts and scores are correct. The code dates from LUCENE-8229 (7.4.0); newSlowSetQuery has been affected since it first shipped in 9.6.0.
- Doc values vs postings: a field can be stored as doc values (a per-document column, used for sorting, faceting and the "slow" doc-values queries) and/or as postings (the inverted index, term to documents with positions).
SortedSetDocValuesFieldalone writes only doc values. DocValuesRewriteMethod(MultiTermQuery.DOC_VALUES_REWRITE): runs a term, set, prefix, wildcard, regexp, range or fuzzy query against the doc values, "against an unindexed docvalues field".SortedSetDocValuesField.newSlowSetQueryandSortedDocValuesField.newSlowSetQueryuse it.Weight#matches(context, doc): for one document, returnsMatches(which fields and term positions matched) or null if the document does not match. A match without positions, such as a DocValues query, returnsMATCH_WITH_NO_TERMS. The UnifiedHighlighter (by default since 9.0.0),MatchHighlighterand monitor'sHighlightsMatchuse it.
newSlowSetQueryisnew TermInSetQuery(MultiTermQuery.DOC_VALUES_REWRITE, field, values)(SortedSetDocValuesField.java:130-132,SortedDocValuesField.java:126-128on maina9779ef3c193), rewritten to aConstantScoreQueryoverDocValuesRewriteMethod's wrapper (DocValuesRewriteMethod.java:38-40).- Hits come from doc values: the weight's
scorerSupplierreads theSORTED_SETdoc values and iterates the ordinals of the query's terms (DocValuesRewriteMethod.java:149-184). Doc 1 is found. matches()comes from the postings: the override (DocValuesRewriteMethod.java:84-92) builds the same doc-values terms enum and passes it toDisjunctionMatchesIterator.fromTermsEnum, which opensTerms.getTerms(reader, field), the postings (DisjunctionMatchesIterator.java:86). For a doc-values-only field that isTerms.EMPTY(Terms.java:40-46), everyseekExactfails (:90), it returns null (:100), andMatchesUtils.forFieldturns that into null Matches (MatchesUtils.java:113-116). The defaultWeight#matches, which advances the scorer and returnsMATCH_WITH_NO_TERMS(Weight.java:78-95), is never used.- Boolean queries pass it on: a required clause with null Matches makes the whole query's Matches null (
BooleanWeight.java:147-151); a prohibited clause excludes a document only when its Matches is non-null (:142-146), so a MUST_NOT clause of this kind never excludes anything. A SHOULD clause counts only when its Matches is non-null (:153-158): it is left out of its hits' Matches, the whole query's Matches is null for a hit that no other clause matches (MatchesUtils.java:63-66), and withminimumNumberShouldMatchit is not counted (:160) (read, not executed). - The highlighter trusts it:
WEIGHT_MATCHESis on by default (UnifiedHighlighter.java:110; it is added whenMULTI_TERM_QUERY,PHRASESandPASSAGE_RELEVANCY_OVER_SPEEDare on, as they are by default, and the caller has not turned it off,:518-527), andFieldOffsetStrategycollects no offsets whenWeight#matchesof the whole query is null (FieldOffsetStrategy.java:143-150). - Why other shapes work:
newSlowExactQuery/newSlowRangeQueryhave nomatches()override and get the scorer-based default.KeywordField.newSetQuerybuilds anIndexOrDocValuesQuerywhosematches()delegates to the doc-valuesTermInSetQuery(IndexOrDocValuesQuery.java:154-157,TermInSetQuery.java:104-110), so it runs this very override, and works only because aKeywordFieldalso has postings (DOCSonly: terms, no positions).
3 documents in one segment, body = "fruit" (StringField), tags doc values only (apple, banana, cherry). tags:(banana), +body:fruit #tags:(banana) and tags:ban* with DOC_VALUES_REWRITE each hit doc 1, and Weight#matches is null for doc 1; +body:fruit -tags:(banana) hits docs 0 and 2, and Weight#matches is non-null for doc 1. CheckHits.checkMatches fails: "Unexpected null Matches object in doc1 for query tags:(banana)". newSlowExactQuery on the same field passes all of it. Highlighting "a ripe fruit in a basket" for +body:fruit #tags:(banana) gives no highlight; with a newSlowRangeQuery filter it gives "a ripe <b>fruit</b> in a basket".
Wider form, same root cause: when one field name has postings and doc values with different contents (a tokenized TextField plus a raw SortedDocValuesField for sorting), the postings decide matches(). With doc 0 "red apple" and doc 1 "red": for newSlowSetQuery("title", ["red apple"]) the hit doc 0 gets null Matches, and for ["red"] the non-hit doc 0 gets non-null Matches, because its tokenized postings contain "red".
Exposure and likelihood357 words
- Who. Applications with a
SortedSetDocValuesFieldorSortedDocValuesFieldthat has no postings under the same name, queried withnewSlowSetQuery(9.6.0 on) or with anyMultiTermQueryusingDOC_VALUES_REWRITE/DocValuesRewriteMethod(7.4.0 on), and that readWeight#matches. - Highlighting. The UnifiedHighlighter uses
Weight#matcheswith its default flags since 9.0.0 (opt-inWEIGHT_MATCHESfrom 7.5.0 to 8.11.4). Any query with such a MUST or FILTER clause gets no highlights, silently, with offsets in the postings and with analysis-time offsets (executed for anewSlowSetQueryfilter on main, and for aPrefixQueryfilter withDocValuesRewriteMethodin the hunt's 8.11.4 and 9.0.0 runs; the wildcard, regexp, range and fuzzy forms go through the samematches()override, read).MatchHighlighter/MatchRegionRetrieverandNamedMatchesget the same null (read, not executed). - Monitor.
HighlightsMatch.MATCHERreports a stored query as matching exactly whenWeight#matchesis non-null (HighlightsMatch.java:44-62). A stored+body:fruit -label:(restricted)with the MUST_NOT clause on a doc-values-only field is reported as matching a document labelled "restricted" (QueryMatch.SIMPLE_MATCHERcorrectly reports 0); with a FILTER clause instead, a real match is missed. Executed on main and 10.5.2. The MUST_NOT direction rarely shows in highlighters, which askWeight#matchesonly about hits they already have (TopDocsor caller-supplied ids,MatchRegionRetriever.java:216-275, 405); it matters where non-null Matches is itself the match decision, as here. - Default vs opt-in. Default
IndexWriterConfig, codec, searcher and highlighter settings. The opt-in part is the layout and the query: a doc-values-only field queried through the slow doc-values set or multi-term path. - Scale. Every hit, at any index size, deterministic: the hunt's independent test failed the same 5 of its 7 tests in each of 10 derived seeds with randomized codecs and
IndexWriterConfigs. - Not affected. Search hits, counts, scores and scorer-based filters; fields whose values are also in the postings (
KeywordField.newSetQuery,IndexOrDocValuesQueryover an indexed field);newSlowExactQueryandnewSlowRangeQuery; the numericnewSlowSetQuerymethods, which use a different class. - How likely. Rare: the
newSlowSetQueryjavadoc steers users to pair it with a postings query, and the recorded prior-report search found no report. Downstream engines route some doc-values-only keyword queries throughDOC_VALUES_REWRITE; whether any highlights them throughWeight#matcheswas not checked.
The test shows that Weight#matches of SortedSetDocValuesField.newSlowSetQuery (DOC_VALUES_REWRITE) on a doc-values-only field returns null for a hit, because it looks the term up in postings that do not exist.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.SortedSetDocValuesField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestDocValuesSetQueryMatches extends LuceneTestCase {

  public void testMatchesOfHitOnDocValuesOnlyField() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new SortedSetDocValuesField("tags", new BytesRef("apple")));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query =
            SortedSetDocValuesField.newSlowSetQuery("tags", List.of(new BytesRef("apple")));
        assertEquals(1, searcher.count(query));
        Weight weight =
            searcher.createWeight(searcher.rewrite(query), ScoreMode.COMPLETE_NO_SCORES, 1);
        // expected: non-null Matches (MATCH_WITH_NO_TERMS) for the hit doc 0; actual: null
        assertNotNull(
            "expected non-null Matches for hit doc 0 of " + query + ", got null",
            weight.matches(reader.leaves().get(0), 0));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-243/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestDocValuesSetQueryMatches
- Expected vs actual
- Expected non-null Matches (MATCH_WITH_NO_TERMS, per the Weight#matches javadoc) for hit doc 0; actual: null, with
-eaand-da.
More files, environment, full output41 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected non-null Matches for hit doc 0 of tags:(apple), got null
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
       org.junit.Assert.assertNotNull(Assert.java:713)
org.apache.lucene.search.TestDocValuesSetQueryMatches.testMatchesOfHitOnDocValuesOnlyField(TestDocValuesSetQueryMatches.java:47)Weight#matchesjavadoc: null only "if the document does not match"; a "DocValues query" match returnsMATCH_WITH_NO_TERMS. The rewrite is documented for "an unindexed docvalues field".- Lucene's own oracle
CheckHits.checkMatchesfails;newSlowExactQueryon the same field passes. - 9.5.0's
DocValuesTermsQuerypassed that check; its 9.6.0 replacement,newSlowSetQuery, fails it.
The full argument321 words
- The contract.
Weight.java:67-77: "ReturnsMatchesfor a specific document, ornullif the document does not match the parent query. A query match that contains no position information (for example, a Point or DocValues query) will returnMatchesUtils#MATCH_WITH_NO_TERMS." - The rewrite advertises this layout.
DocValuesRewriteMethod.java:28-34: "This can be used to perform these queries against an unindexed docvalues field."MultiTermQuery.java:111-121sends users without doc values to "the other rewrite methods that rely on postings alone". - Lucene's own oracle.
CheckHits.checkMatches(CheckHits.java:352-373,MatchesAsserter:640-688), run byQueryUtils.check(random, q, searcher)(QueryUtils.java:148), requires non-null Matches for every hit; it fails here. - Siblings comply.
newSlowExactQuery/newSlowRangeQueryon the same field returnMATCH_WITH_NO_TERMS.TestMatchesIterator#testPointQuery(TestMatchesIterator.java:444-468) asserts that a required point/doc-values clause next to aTermQuerystill yields the term's positions. - Why tests missed it.
TestDocValuesRewriteMethodhas a doc-values-only field (_with-skip,:70) but compares hit lists only (:117-133); itsQueryUtils.check(a1)(:157) checks equals/hashCode.TestMatchesIteratorhas noDocValuesRewriteMethodcase. AddingCheckHits.checkMatchestoTestDocValuesRewriteMethodfails on stock main ("Unexpected null Matches object in doc11 for query _with-skip://") and passes with the fix once that test's random deletions are turned off. - History. The override came with
Weight#matchesin LUCENE-8229 (2018), whose discussion proposed a Matches object meaning "a match in this doc, but no term hits" whenever the scorer matched (nowMATCH_WITH_NO_TERMS); nobody discussed this layout. The same commit gave the postings-basedMultiTermQueryConstantScoreWrappera fallback tosuper.matches()for fields indexed without positions; this override got none. - Regression for users (9.6.0). On 9.5.0 the sandbox
DocValuesTermsQuery, which had nomatches()override, passesCheckHits.checkMatcheson a doc-values-only field; #12129 (@rmuir, merged 2023-02-06) graduated it tonewSlowSetQueryon a newSortedSetDocValuesSetQuery, and #12175 (@gsmiller, merged 2023-03-01) movednewSlowSetQueryontoDOC_VALUES_REWRITE. Both first shipped in 9.6.0, and on 9.6.0 it fails. #12175 calls the change removing "mostly redundant code" and says nothing about Matches.
The devil's-advocate check132 words
The strongest works-as-designed case, built by the intended-behaviour verifier and a review by a model from another family: Weight#matches, Matches and DocValuesRewriteMethod are @lucene.experimental; Matches is a positions API, so a field without postings has no matches; and the newSlowSetQuery javadoc recommends wrapping it in an IndexOrDocValuesQuery with a postings query.
Why it fails: experimental status allows the API to change, not to break its own documented contract. The javadoc names DocValues queries explicitly and reserves null for non-matching documents, while "no positions for this field" is what Matches#getMatches(field) == null expresses. The IndexOrDocValuesQuery note is speed advice, and the same note offers the other remedy, ANDing it "with a selective query", which is exactly the failing FILTER shape. Every verifier and the cross-model reviews rated the intended argument weak.
Recommended Decide from doc values, add postings term matches when present
In DocValuesRewriteMethod's matches(), decide the match with the scorer-based super.matches() first, then add the postings' term matches when there are any (+13/-5, one method). The repro and the highlighter test pass with assertions on and off, and 62 nearby test classes in core, highlighter and monitor (848 tests) pass.
final Matches docValuesMatch = super.matches(context, doc);
if (docValuesMatch == null) {
  return null;
}
final SortedSetDocValues values = DocValues.getSortedSet(context.reader(), query.field);
final Matches termMatches =
    MatchesUtils.forField(
        query.field,
        () -> DisjunctionMatchesIterator.fromTermsEnum(
            context, doc, query, query.field, getTermsEnum(values)));
return termMatches != null ? termMatches : docValuesMatch;
All options and trade-offs4 options · 713 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF); the plain super.matches() variant was run only as a root-cause probe in the hunt, the other options were not run.
Decide from doc values, add postings term matches when present (validated by the checks) (recommended)
Replace the body of the weight's matches() in DocValuesRewriteMethod (+13/-5): return null when the scorer-based super.matches() is null; otherwise return the postings-based term Matches if there are any, else the MATCH_WITH_NO_TERMS from super.matches(). For live documents matches() is then non-null exactly for the hits (like every Weight#matches it does not look at deletions), so this fixes the doc-values-only, MUST_NOT and mixed-field forms at once, and fields that also have postings keep their postings-based term Matches (KeywordField.newSetQuery, whose DOCS-only postings have terms but no positions; fields indexed with positions keep their positions). A second diff adds the two repro tests as new tests in lucene/core and lucene/highlighter (+279/-5 in total).
final Matches docValuesMatch = super.matches(context, doc);
if (docValuesMatch == null) {
  return null;
}
final SortedSetDocValues values = DocValues.getSortedSet(context.reader(), query.field);
final Matches termMatches =
    MatchesUtils.forField(
        query.field,
        () -> DisjunctionMatchesIterator.fromTermsEnum(
            context, doc, query, query.field, getTermsEnum(values)));
return termMatches != null ? termMatches : docValuesMatch;
Trade-offs
- Each
matches()call now also runs the scorer path: it enumerates every query term that is in the segment's doc-values dictionary into an ordinal set (an array grown as needed, then aLongHashSetunless the ordinals are contiguous;DocValuesRangeIterator.java:151-183) and advances a fresh doc-values iterator to the document; for a hit it then enumerates the terms a second time for the postings lookup.Weight#matchesis normally called per highlighted hit; no benchmark was run, and #13391 already reportsmatches()of largeTermInSetQuerys as slow. - When postings and doc values differ, the term matches still come from whichever query term the postings have for the document; only the match decision is fixed.
What the checks validated
- Stock main
a9779ef3c193: the repro fails 5 of 6 with assertions on and off; the highlighter test fails 2 of 4. - With the fix: the repro passes 6 of 6 with assertions on and with assertions off; the highlighter test passes 4 of 4.
- With the fix, the closest suites pass: in core
TestDocValuesRewriteMethod,TestTermInSetQuery,TestMatchesIterator,TestIndexOrDocValuesQuery,TestPrefixQuery,TestWildcardQuery,TestRegexpQuery,TestTermRangeQuery,TestFuzzyQuery,TestDocValuesQueries,TestMultiTermQueryRewrites,TestKeywordField,TestSortedSetDocValuesSetQuery; all ofuhighlightandmatchhighlight; all oflucene/monitor: 62 classes, 848 tests, 3 skipped, 0 failures. ecjLintandcheckGoogleJavaFormatpass for core and highlighter with both repro tests in place.- Earlier, with the fix shadowed onto the stock jars: the finder's tests, the independent reproducer's tests including the mixed-field form, the GPT-stage test and the MUST_NOT plus monitor probe (10 of 10) pass.
- Not run: the full core and highlighter suites; no benchmark.
Let the scorer-based default answer: MATCH_WITH_NO_TERMS or null.
Trade-offs
Simplest and always consistent with the hits (for live documents), but every field that also has postings gets MATCH_WITH_NO_TERMS with no term detail, and fields indexed with positions lose their positions; that includes KeywordField.newSetQuery, whose IndexOrDocValuesQuery asks this weight (its postings are DOCS only). Whether this changes any highlighter's output was not tested. Run only as a root-cause probe in the hunt (7 of 7 pass, membership only).
If terms(field) is null, return super.matches(); otherwise keep today's code.
Trade-offs
Smaller, but postings still decide the match, so the mixed-field form (postings with different contents than the doc values) stays wrong.
Call CheckHits.checkMatches in TestDocValuesRewriteMethod#assertSame for the doc-values queries, and/or add a DocValuesRewriteMethod case to TestMatchesIterator.
Trade-offs
Probed: the added checks fail on stock main ("Unexpected null Matches object in doc11 for query _with-skip://") and pass with the recommended fix, but only with the test's random deletions turned off. As written the test deletes documents, and the non-hit half of checkMatches then fails on stock main too ("Unexpected non-null Matches object in non-matching doc121", on the field that also has postings, with or without the fix), so the check needs an index without deletions or a separate test method.
Code that uses Weight#matches to decide whether a query matches, such as monitor's HighlightsMatch.MATCHER, reports documents that a MUST_NOT clause of this kind should exclude, which matters downstream only where such a match enforces an exclusion. A code search (not exhaustive; security plugins and private products not checked) found no use of HighlightsMatch in Elasticsearch, OpenSearch or Solr.
Bounded-exhaustive translation validation of every MultiTermQuery rewrite method on the real jar: an independent reference computed each query's hits, and one check required Weight#matches to be non-null exactly for the hits. It fired only for DOC_VALUES_REWRITE on the doc-values-only field; the hypothesis came from reading the code while modelling.
The method in full204 words
Method: bounded-exhaustive translation validation on the stock jar (semi-formal tier), in a hunt unit on multi-term query rewrites.
- The harness gives every
MultiTermQuery(term range, prefix, set, wildcard, regexp, fuzzy) an independent reference semantics for its term language and its hits, generated from the document layout rather than read from the index, and checks it on real multi-segment indexes with a field that has postings plusSORTED_SETdoc values and a field with doc values (and a skip index) only, under every rewrite method. - One of its checks (MATCH:
Weight#matchesnon-null if and only if the document is a reference hit, for every live document) fired only forDOC_VALUES_REWRITEon the doc-values-only field: 511,327 cases at each of the threemaxClauseCountsettings, and no other rewrite or field. - The hypothesis was first seen while reading
DocValuesRewriteMethodduring modelling and checked with a scratch probe before the harness ran, so this is a hypothesis formed while modelling and witnessed by a tool, not the output of a model checker, SMT solver or prover. - Found 2026-10-26 on main
ea57360912ed; then checked by an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by a model from another family (OpenAI GPT-5.6), an adjudication and a skeptical-committer audit.
No prior report found (2026-10-26) in 212 recorded queries over GitHub, the mailing lists, JIRA, Elasticsearch, OpenSearch, Solr and the web, plus the changed files of all 413 open PRs. Related: #13391 (open: slow matches() for large TermInSetQuery, same helper).
Searches4 searches
Verdict new: 27 hits read and classified, none the same bug. Keyword search cannot prove absence; GitHub search was rate-limited for one variant, and private channels cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; dev@, java-user@, issues@, commits@; JIRA archive; Elasticsearch, OpenSearch, Solr; the web | 2026-10-26 | the hunt's prior-report tool: the finder's run, variants A, B and C (C finished 6 of 8 GitHub phrasings, the rest re-run manually), ASF-only runs and a web run | no report; related only: #13391, #12686 / #13902, #10479 (LUCENE-9439), LUCENE-9462, #10649 (LUCENE-9609) |
| GitHub (apache/lucene, Elasticsearch, OpenSearch, Solr) | 2026-10-26 | 35 manual searches: DocValuesRewriteMethod, DOC_VALUES_REWRITE, newSlowSetQuery, MultiTermQueryDocValuesWrapper, DocValuesTermsQuery, fromTermsEnum, MATCH_WITH_NO_TERMS, Weight#matches null, checkMatches, doc-values-only highlight | no report; downstream DOC_VALUES_REWRITE use on doc-values-only fields (Elasticsearch #137536, #149420) without any Matches or highlight discussion |
| lists.apache.org, JIRA (LUCENE, SOLR) | 2026-10-26 | 21 manual list searches, 7 JIRA queries | no report; background only (dev@ "Slow DV equivalent of TermInSetQuery", 2021) |
| open apache/lucene PRs | 2026-10-26 | changed files of all 413 open PRs | #13140 (visit() only), #13693 (scorer only), #16851 (iterator constructor only): none changes matches() |
Present since Weight#matches was added (LUCENE-8229, 040a9601b1b, 2018; first release 7.4.0). newSlowSetQuery joined in 9.6.0 (#12129, #12175), and highlights are lost by default since 9.0.0. Executed: releases from 7.4.0 to 10.5.2 and main fail; not fixed upstream.
Versions tested9 rows
Introduced by 040a9601b1b on master and its branch_7x backport 502fd4bf12b (2018-04-11), "LUCENE-8229: Add Weight.matches() to iterate over match positions" (@romseygeek; GitHub issue #9276; apache/lucene-solr#345 was closed unmerged and the change went in from the JIRA patch). That commit created Weight#matches, its javadoc, the scorer-based default, CheckHits.checkMatches and this override, so the defect is as old as the API. Later commits on the two methods (git log -L: the LUCENE-8229 follow-up e6b65151b6f, LUCENE-8270, LUCENE-8306, LUCENE-8422, LUCENE-8941, LUCENE-9570, LUCENE-10398, #1020) never consult doc values.
Exposure grew twice: in 9.0.0 WEIGHT_MATCHES became the UnifiedHighlighter default (LUCENE-9431), and in 9.6.0 newSlowSetQuery arrived on DOC_VALUES_REWRITE: #12129 (@rmuir, merged 2023-02-06) graduated the sandbox DocValuesTermsQuery, which used the scorer-based default, to newSlowSetQuery on a new SortedSetDocValuesSetQuery (no matches() override either), and #12175 (@gsmiller, merged 2023-03-01) moved it onto DOC_VALUES_REWRITE; both first shipped in 9.6.0. No commit on main changed this code. 10.6.0 was released on 2026-10-29; on branch_10_6 (2763db11b0a, 2026-10-24) DocValuesRewriteMethod.java and BooleanWeight.java are identical to main and fromTermsEnum is unchanged (source diff only, not run).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | compact JUnit 5 of 6 fail through gradle, assertions on and off; highlighter test 2 of 4; controls pass |
main ea57360912ed | affected | the finder's test 4 of 5, the independent test 5 of 7, the highlighter tests fail; -ea and -da |
| 10.5.2, 10.0.0, 9.12.3 | affected | the finder's test fails 4 of 5 (this doc's test 5 of 6 on 10.5.2 and 9.12.3); 10.5.2 also with -da, the highlighter test and the monitor probe |
| 9.6.0 | newSlowSetQuery arrives | the newSlowSetQuery variant fails 4 of 5, -ea and -da; the range-query control passes |
| 9.5.0 | DocValuesTermsQuery clean | DocValuesRewriteMethod fails; the sandbox DocValuesTermsQuery that newSlowSetQuery replaced passes CheckHits.checkMatches |
| 9.0.0 | highlights lost by default | fails; the default UnifiedHighlighter loses the highlight |
| 7.4.0, 7.7.3, 8.0.0, 8.11.4 | highlighting opt-in | DocValuesRewriteMethod fails (7.4.0 also -da), controls pass; on 8.11.4 default highlighting works and forced WEIGHT_MATCHES fails |
| 7.3.1 and older | no Matches API | compile error: Weight#matches does not exist |
fix (scratch worktree at a9779ef3c193) | not affected | the repro 6 of 6 and the highlighter test 4 of 4 pass, assertions on and off; 62 nearby classes (848 tests) pass |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing. Reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; an adjudication and a skeptical-committer audit confirmed it, and this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts455 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Translation-validation harness plus a public-API JUnit: 4 of 5 fail on main (-ea, -da), 10.5.2 and 9.12.3; the highlighter JUnit 2 of 4; with the fix both pass and 43 upstream tests pass. |
| independent reproducer | real | Own JUnit (non-null Matches if and only if hit, every document): 5 of 7 fail on main, 10.5.2 and 9.12.3, 50 of 70 over 10 seeds; found the mixed-field form; a plain super.matches() shadow passes 7 of 7. |
| cross-model reviews (refute, intended) | not real (low, procedural); real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6) could only read code. The lenses agreed on the root cause and rated the intended argument weak; the refute lens's point that the first fix still let postings decide was taken and the fix revised. A separate run re-ran the repro: 4 of 5 fail. |
| intended-behaviour devil's advocate | real, high | Rebutted each intended reading and ran the regression check: 9.5.0's DocValuesTermsQuery passes, 9.6.0's newSlowSetQuery fails. |
| adjudication | confirmed, high | Re-ran the independent test (5 of 7, -ea and -da), the finder's repro and the highlighter test. |
| skeptical-committer audit | keep | Re-ran with fresh seeds (4 of 5 fail; the fix passes 5 of 5; highlighter 2 of 4) and confirmed the mechanism from the code. |
| Follow-up and main refresh | reproduces; keep | Version matrix from 7.3.1 to main, the MUST_NOT and monitor probe, re-runs with new seeds; the refresh to a9779ef3c193 gives identical failures. |
| this doc's gradle runs | reproduces; fix validated | The compact JUnit and the highlighter test fail on stock main and pass with the fix, assertions on and off; 62 nearby classes (848 tests), lint and format pass with the fix. |
| independent fact check of this doc | 4 text errors, fixed | Re-checked every file:line and quote at a9779ef3c193, re-ran the gradle command in a fresh worktree (5 of 6 fail, assertions on and off; highlighter 2 of 4) and the classpath runner on main, 10.5.2, 9.12.3 and 9.10.0 with new seeds; the fix passes. Found four text errors (the #12129 attribution, the 9.10.0 overload, the second diff's content, the mixed-field wording), all fixed. |
| cross-model fact check (OpenAI GPT-5.6) | sound; 6 errors (0 high), 3 overclaims, 5 missing caveats, all taken; intended argument weak | A reading-only review by a model from another family, on a reference pack of raw command outputs. It found the brief sound and the intended argument weak; its corrections (live documents, KeywordField has no positions, SHOULD clauses, highlighter flag gating, fix cost, branch_10_6, bounded prior-art wording) are in this doc. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 477 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,461 words
- Registry title
- DocValuesRewriteMethod's Weight#matches looks the matched terms up in the postings, so on a doc-values-only field it returns null for every hit of newSlowSetQuery or any DOC_VALUES_REWRITE query (highlights are silently lost, and a MUST_NOT clause of this kind fails open in Weight#matches)
- Area
- core / search: MultiTermQuery rewrite methods (DocValuesRewriteMethod, DOC_VALUES_REWRITE) and the Matches API (Weight#matches)
- Priority
- Medium, rank 209: On doc-values-only fields, Matches are null for every DOC_VALUES_REWRITE or newSlowSetQuery hit, so the default UnifiedHighlighter silently loses highlights, which makes it head the Matches and highlighting rows after LFV-236.
- Impact class
- silent wrong results
- Impact note
- Applications on Lucene 7.4.0 through 10.6.0 (10.6.0 by reading) or main that query a doc-values-only field (a SortedSetDocValuesField or SortedDocValuesField with no postings under that name) with SortedSetDocValuesField/SortedDocValuesField.newSlowSetQuery (9.6.0 on) or with any MultiTermQuery that uses DOC_VALUES_REWRITE (prefix, wildcard, regexp, range, fuzzy, TermInSetQuery), and that read Weight#matches, get null Matches for every hit, with the default IndexWriterConfig, codec and searcher and at any index size; a BooleanQuery with such a MUST or FILTER clause then has null Matches for all its hits, so the UnifiedHighlighter in its default WEIGHT_MATCHES mode (9.0.0 on) returns the passage with nothing highlighted (executed), and as a MUST_NOT clause Weight#matches becomes non-null for documents the clause excludes, which makes Lucene monitor's HighlightsMatch.MATCHER report excluded documents as matches (executed); search hits, counts and scores are correct, and fields that also have postings (KeywordField.newSetQuery, IndexOrDocValuesQuery over an indexed field) are not affected.
- Summary
- You keep a keyword field as doc values only, filter on it with SortedSetDocValuesField.newSlowSetQuery or a PrefixQuery with DOC_VALUES_REWRITE (DocValuesRewriteMethod says it 'can be used to perform these queries against an unindexed docvalues field'), and expect Weight#matches to return non-null Matches (MATCH_WITH_NO_TERMS) for every hit, as its javadoc promises for DocValues queries and as newSlowExactQuery on the same field does. Instead matches() looks the matched terms up in the field's postings, which do not exist, so it returns null for every hit; for +body:fruit #tags:(banana) the UnifiedHighlighter with default settings returns 'a ripe fruit in a basket' with no highlighted term, while the same query with newSlowRangeQuery as the filter highlights '<b>fruit</b>'. As a MUST_NOT clause the same null makes Weight#matches non-null for documents the clause excludes; hits, counts and scores stay correct.
- Introduced
- 040a9601b1b346391ad37e5a0a4f2f598e72d26e on master and its branch_7x backport 502fd4bf12b (the commit that 7.4.0 contains), 'LUCENE-8229: Add Weight.matches() to iterate over match positions' by romseygeek, committed from the JIRA patch (apache/lucene-solr#345 was closed unmerged; LUCENE-8229 is GitHub issue #9276) [read: git log -L and git blame on DocValuesRewriteMethod#matches and DisjunctionMatchesIterator#fromTermsEnum, git tag --contains in the full-history clone; exec: 7.3.1 cannot compile the scenario because Weight#matches does not exist, 7.4.0 fails with -ea and -da and its controls pass]: the commit created Weight#matches, its javadoc, the scorer-based default that returns MATCH_WITH_NO_TERMS, CheckHits.checkMatches and DocValuesRewriteMethod's matches() override on top of the postings-only fromTermsEnum helper, so the defect is as old as the API; later commits on the two methods (LUCENE-8306, LUCENE-8422, LUCENE-8941, LUCENE-9570, LUCENE-10398, #1020) never consult doc values. Entry-point regression: #12129 and #12175 (gsmiller, merged 2023-03-01, first released in 9.6.0) moved newSlowSetQuery from SortedSetDocValuesSetQuery / the sandbox DocValuesTermsQuery, which had no matches() override, onto TermInSetQuery with DOC_VALUES_REWRITE [exec: the sandbox DocValuesTermsQuery passes CheckHits.checkMatches on 9.5.0, newSlowSetQuery fails it on 9.6.0] (2018-04-11 (DocValuesRewriteMethod#matches, LUCENE-8229); 2023-03-01 (#12175 merged: newSlowSetQuery moved onto DOC_VALUES_REWRITE))
- First affected version
- 7.4.0 [exec] (release tag 2018-06-22; any MultiTermQuery with setRewriteMethod(new DocValuesRewriteMethod())); 7.3.1 and earlier have no Weight#matches API [exec: the port does not compile]; by entry point: newSlowSetQuery, MultiTermQuery.DOC_VALUES_REWRITE and TermInSetQuery(DOC_VALUES_REWRITE, ...) since 9.6.0 [exec; these APIs do not exist in 9.5.0, whose sandbox DocValuesTermsQuery passes], and lost highlights with default UnifiedHighlighter flags since 9.0.0 [exec; WEIGHT_MATCHES became the default with LUCENE-9431; 8.11.4 highlights correctly with default flags and loses the highlight with WEIGHT_MATCHES forced on]
- Affected versions
- every release from 7.4.0 through 10.5.2, 10.6.0 (by reading) and main ea57360912ed [read: all 58 release tags from 7.4.0 to 10.5.2 in the history clone contain 040a9601b1b or 502fd4bf12b, 8.8.2 to 8.11.4 are outside the clone; exec: fails on 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.5.0, 9.6.0, 9.12.3, 10.0.0, 10.5.2 and main, with -da as well on 7.4.0, 9.6.0, 10.5.2 and main, controls pass]; not affected: 7.3.1 and earlier (the API does not exist); not fixed on main; 10.6.0 (released 2026-10-29) was not run, but branch_10_6 (2763db11b0a, 2026-10-24) has DocValuesRewriteMethod.java and BooleanWeight.java identical to main [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 212 recorded queries, namely scripted prior-report searches (the finder's spec, variants A, B and C, ASF-only runs and a web run) over apache/lucene issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive, downstream repositories (Elasticsearch, OpenSearch, Solr) and the web, plus 35 manual GitHub searches across apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr, 21 manual list searches, 7 manual JIRA queries over LUCENE and SOLR, the changed-file lists of all 413 open apache/lucene PRs and local git history; 27 hits read and classified, none the same bug; the finder, the independent reproduction and the intended-behaviour check found nothing either); not fixed upstream (main ea57360912ed has the same matches(), unchanged since LUCENE-8229; the latest upstream commit on DocValuesRewriteMethod.java, #15989, is in the tested commit; the open PRs that touch the two files leave it alone: #13140 changes visit() only (registry LFV-038), #13693 the scorer only, #16851 the DisjunctionMatchesIterator constructor only); related items, not reports: #13391 (open, 2024: Weight#matches of a large TermInSetQuery is slow; same fromTermsEnum helper, postings path, performance only), #12686 / #13902 (IndexOrDocValuesQuery not highlighted by the plain Highlighter's WeightedSpanTermExtractor; different highlighter and code), #10479 / LUCENE-9439 and LUCENE-9462 (Matches for fields that have postings but no positions), #10649 / LUCENE-9609 (8.x TermInSetQuery hid its terms from highlighters), #9276 / LUCENE-8229 (origin of the code), #12129 and #12175 (newSlowSetQuery moved onto DOC_VALUES_REWRITE in 9.6.0; no Matches discussion)
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the compact JUnit and the highlighter test through gradle in a clean worktree, stock and with the fix, assertions on and off, plus 62 nearby test classes in core, highlighter and monitor with the fix (2026-10-27); the compact JUnit also through the hunt's classpath runner on main, 10.5.2 and 9.12.3. Hunt runs on mainea57360912edand on releases from 7.4.0 to 10.5.2; the main refresh toa9779ef3c193reproduces with identical messages.
- Finding record
lucene/core/src/java/org/apache/lucene/search/DocValuesRewriteMethod.java:28-33 (at ea57360912ed) (class javadoc: 'This can be used to perform these queries against an unindexed docvalues field', @lucene.experimental), :84-92 (matches(): MatchesUtils.forField(query.field, () -> DisjunctionMatchesIterator.fromTermsEnum(context, doc, query, query.field, getTermsEnum(values))))lucene/core/src/java/org/apache/lucene/search/DisjunctionMatchesIterator.java:82-101 (at ea57360912ed) (fromTermsEnum: Terms.getTerms(context.reader(), field), the postings, Terms.EMPTY for a doc-values-only field; seekExact per term; returns null when no postings term hits doc)lucene/core/src/java/org/apache/lucene/search/Weight.java:68-76 (at ea57360912ed) (matches javadoc: null only 'if the document does not match the parent query'; 'a Point or DocValues query' match 'will return MatchesUtils#MATCH_WITH_NO_TERMS'; @lucene.experimental), :78-95 (scorer-based default)lucene/core/src/java/org/apache/lucene/search/BooleanWeight.java:134-160 (at ea57360912ed) (matches(): a prohibited clause rejects only when its Matches is non-null, :142-146; a required clause with null Matches makes the whole query null, :147-151)lucene/core/src/java/org/apache/lucene/document/SortedSetDocValuesField.java:120-131 (at ea57360912ed) and SortedDocValuesField.java:118-127 (newSlowSetQuery = new TermInSetQuery(MultiTermQuery.DOC_VALUES_REWRITE, field, values); NOTE: 'best used wrapped in an IndexOrDocValuesQuery' or 'ANDed with a selective query')lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldOffsetStrategy.java:143-150 (at ea57360912ed) (WEIGHT_MATCHES path: null Matches -> no offsets for the document); UnifiedHighlighter.java:110 (DEFAULT_ENABLE_WEIGHT_MATCHES = true)lucene/test-framework/src/java/org/apache/lucene/tests/search/CheckHits.java:359 (at ea57360912ed) (checkMatches), :670 ('Unexpected null Matches object in doc')lucene/monitor/src/java/org/apache/lucene/monitor/HighlightsMatch.java:38-62 (at ea57360912ed) (MATCHER calls Weight#matches for every document and reports a match exactly when it is non-null)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/document/SortedSetDocValuesField.java:120-132; SortedDocValuesField.java:118-128lucene/core/src/java/org/apache/lucene/search/DocValuesRewriteMethod.java:28-34, 38-40, 84-92, 98, 149-184lucene/core/src/java/org/apache/lucene/search/DisjunctionMatchesIterator.java:82-101; lucene/core/src/java/org/apache/lucene/index/Terms.java:40-46; lucene/core/src/java/org/apache/lucene/search/MatchesUtils.java:63-66, 106-116lucene/core/src/java/org/apache/lucene/search/Weight.java:67-95; BooleanWeight.java:133-164lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:110, 518-527; FieldOffsetStrategy.java:72-74, 114-160lucene/core/src/java/org/apache/lucene/search/IndexOrDocValuesQuery.java:154-157; TermInSetQuery.java:104-110; lucene/core/src/java/org/apache/lucene/document/KeywordField.java:174-179
- Who is affected
lucene/monitor/src/java/org/apache/lucene/monitor/HighlightsMatch.java:44-62lucene/core/src/java/org/apache/lucene/document/SortedNumericDocValuesField.java:125-127
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/Weight.java:67-77; DocValuesRewriteMethod.java:28-34; MultiTermQuery.java:111-122lucene/test-framework/src/java/org/apache/lucene/tests/search/CheckHits.java:352-373, 640-688; QueryUtils.java:148lucene/core/src/test/org/apache/lucene/search/TestDocValuesRewriteMethod.java:62-73, 117-133, 157; TestMatchesIterator.java:444-468lucene/core/src/java/org/apache/lucene/document/SortedSetDocValuesField.java:120-129 (NOTE: "ANDed with a selective query")
- TestDocValuesSetQueryMatches.java (JUnit test):
repro/LFV-243/src/org/apache/lucene/search/TestDocValuesSetQueryMatches.java(53 lines)
Made in parallel with this doc from a probe run on main a9779ef3c193 (stock and with the fix); the values on screen come from the probe. The diagram uses two documents (doc 0 banana, doc 1 apple), the compact repro three; the mechanism and the outcome are the same.
assets/LFV-243/bug.png(477 KB)