The copier behind addIndexes(CodecReader) hands the codec a field with zero terms. The default term-vector writer then stores per-field floats that its reader does not expect when no term of the chunk has offsets, and the reader lists the field but returns no terms for it, so the next merge counts one field too many.
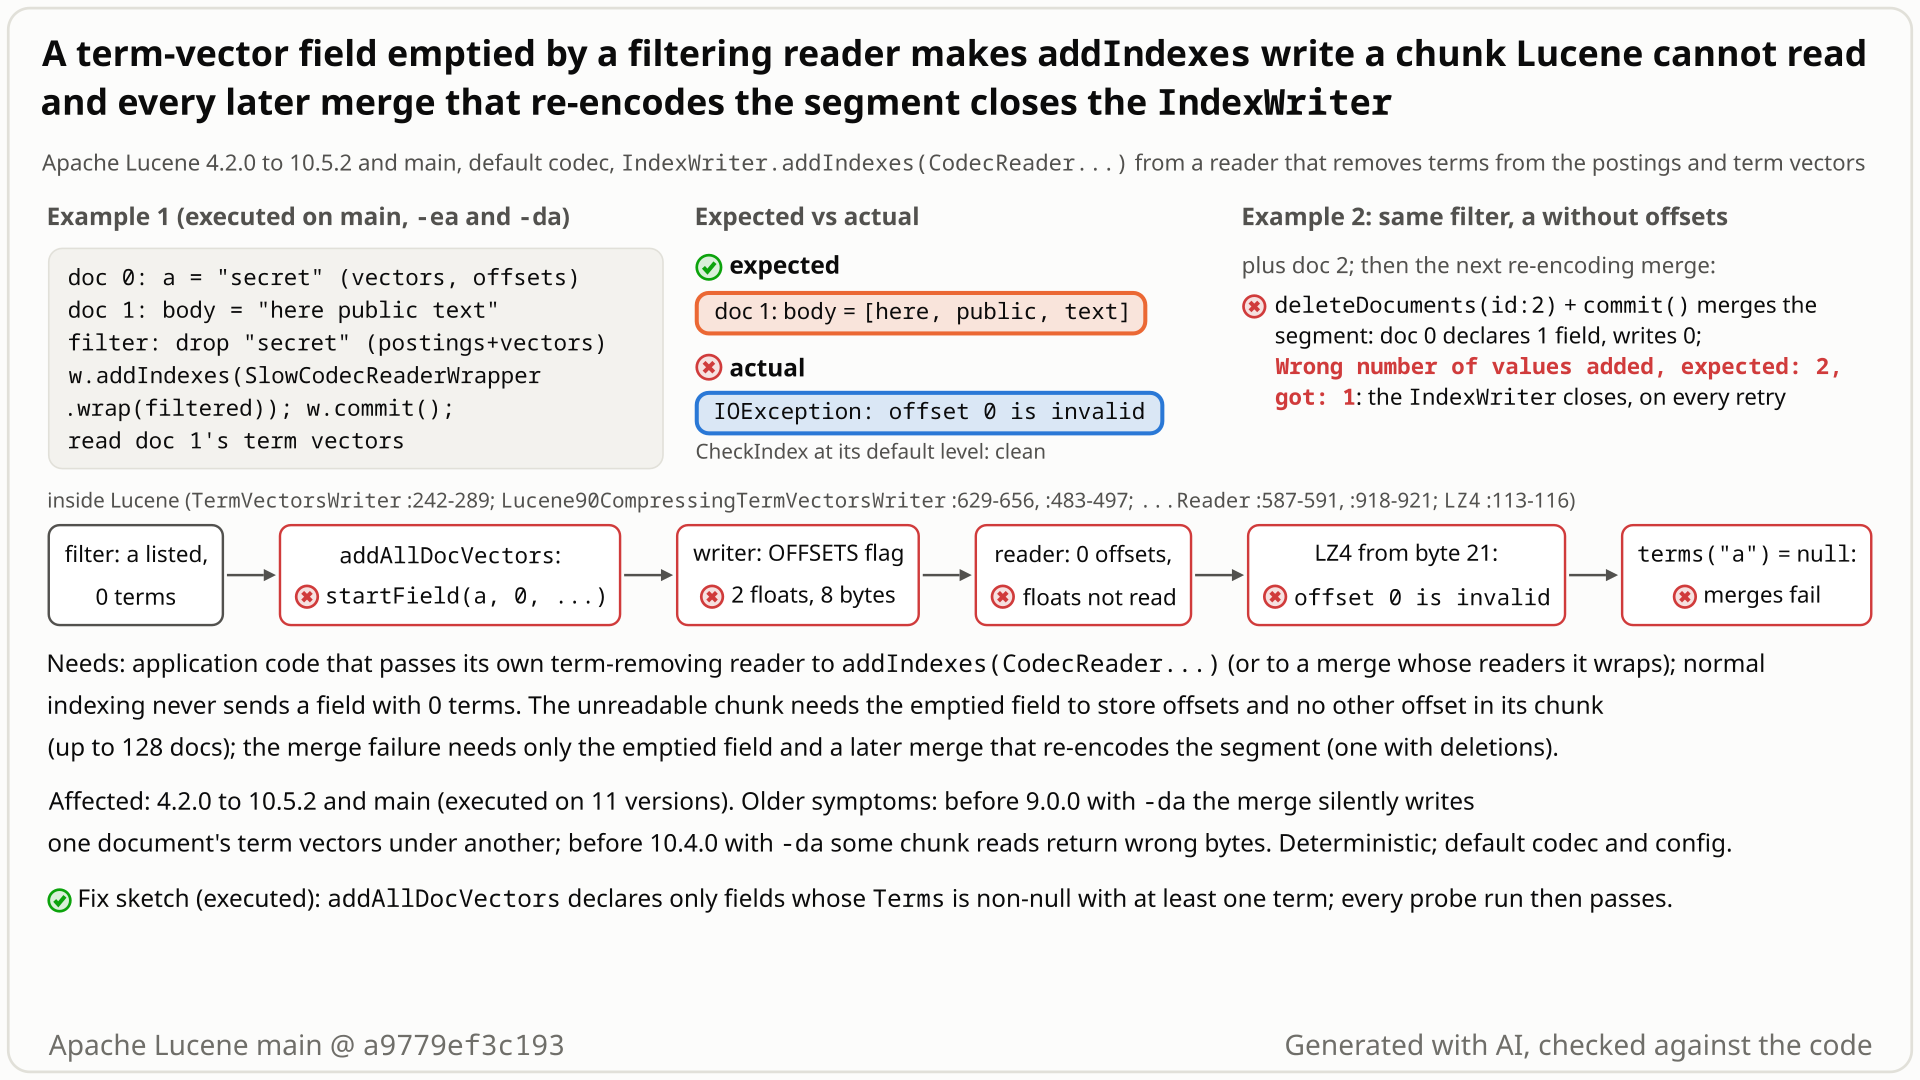
a listed with 0 terms, the copier forwards it, the writer adds 8 bytes of floats that the reader does not skip, the read of doc 1 fails, and the next merge counts 2 fields but writes 1. Select the still to open it at full size. Generated with AI, checked against the code.- Copy a 2-document index with
addIndexes(SlowCodecReaderWrapper.wrap(r)), whererremoves the term "secret" from fieldain both the postings and the term vectors. Doc 0'saheld only "secret" and stores offsets, so its term vectors now listawith 0 terms. - You expect doc 1's term vectors to read back as
body=[here, public, text]. Instead the read throwsIOException: offset 0 is invalid: the writer stored 8 bytes (one float per field of the chunk) that the reader does not expect, so it decodes the term bytes from the wrong place. A chunk holds up to 128 documents; its other documents with term vectors fail the same way. - Copy again with
anot storing offsets, plus a doc 2. Delete doc 2 andcommit(). You expect the merge to succeed. Instead it throwsWrong number of values added, expected: 2, got: 1and the IndexWriter closes; every fresh writer whose merge re-encodes the segment fails the same way. - Why the merge fails: the copied segment lists
afor doc 0 but returns no terms for it, and the merge copier counts the field before it skips it. Normal indexing never writes a zero-term field, so ordinary indexes are not affected. - No warning:
addIndexesandcommitsucceed, andCheckIndexat its default level reports the index clean (here levels 2 and 3 report the segment broken; without offsets only level 3 does).
Applications that copy or rewrite an index through addIndexes(CodecReader) with their own reader that removes terms from term-vector fields: default codec and config, any size, 4.2.0 to 10.6.0 (10.6.0 by reading) and main. One document whose term-vector field holds only removed terms is enough. Normal indexing never produces it.
Mechanism, terms and numbers805 words
IndexWriter.addIndexes(CodecReader...) copies the term vectors of a reader that is not a same-format segment through the codec-agnostic copier TermVectorsWriter.addAllDocVectors. If the reader removes terms (a FilterLeafReader that drops a term from the postings and, consistently, from the term vectors), a document whose term-vector field held only removed terms reaches the codec as a field with numTerms = 0. The default Lucene90 term-vector writer then writes one 4-byte AvgCharsPerTerm float per field of the chunk because the field has the OFFSETS flag, while its reader reads those floats only when the chunk has at least one offset, so the chunk's other documents with term vectors (a chunk holds up to 128 documents) cannot be read. The same reader lists the zero-term field but returns null from terms(), so the next merge that re-encodes the segment (a deletion rules out the bulk copy once the merge policy picks the segment) declares a field it never writes and, on 9.0.0 and later, closes the IndexWriter, again for every new writer. CheckIndex at its default level reports the index clean. Normal indexing never produces a zero-term term-vector field; the trigger is an application-written term-removing reader. Confirmed on 11 versions from 4.2.0 (2013) to 10.5.2 and main. Before 9.0.0 (merges) and 10.4.0 (chunk reads), runs without assertions could fail silently: a merge wrote one document's term vectors under another, and chunk reads returned wrong bytes or threw ArrayIndexOutOfBoundsException.
- Term vectors: an optional per-document copy of a field's terms (with positions, offsets, payloads), stored by the default codec in compressed chunks of up to 128 documents, flushed once their term bytes reach 4 KB (
Lucene90TermVectorsFormat.java:68,:170). - The copier:
TermVectorsWriter.addAllDocVectors, the codec-agnostic path that writes one document's term vectors from anyFields.addIndexes(CodecReader...)throughSlowCodecReaderWrapperuses it, and so does any merge of a segment with deletions (Lucene90CompressingTermVectorsWriter.java:915-931, bulk-merge test:953-967). - A zero-term field: a document's term vectors list field
a, but itsTermshas no terms. A term-removingFilterLeafReaderproduces it when a document's field held only removed terms. The indexing chain never does:TermVectorsConsumerPerField.finish()skips fields with no terms (TermVectorsConsumerPerField.java:69-71).
- The copier declares before it looks. It calls
startDocument(vectors.size())(TermVectorsWriter.java:242-251; the javadoc at:64-69promisesstartFieldwill then be called that many times), forwards an emptyTermsasstartField(numTerms = 0)(:278-289), and skips a nullTermswithcontinue("FieldsEnum shouldn't lie...",:267-271). - Writer and reader disagree about one chunk section. The writer's
flushOffsetssetshasOffsets |= fd.hasOffsetsfor every field instance (Lucene90CompressingTermVectorsWriter.java:629) and, if set, writes one AvgCharsPerTerm float per distinct field (:643-657). The reader computestotalOffsetsfrom the term frequencies of OFFSETS fields, to which a zero-term field adds nothing (Lucene90CompressingTermVectorsReader.java:551-561), and reads the floats onlyif (totalOffsets > 0)(:587-591). - So the chunk is shifted. With a zero-term OFFSETS field and no other offset in the chunk, the reader starts decoding the LZ4-compressed term bytes 4 bytes per field too early. It sees a zero match offset and throws
IOException("offset 0 is invalid")(LZ4.java:113-116, since #15570 in 10.4.0). The zero-term document itself reads back; the other documents of the chunk that have term vectors do not. - And the next merge miscounts. The same reader lists the zero-term field in
iterator()andsize()(Lucene90CompressingTermVectorsReader.java:879-902,:948-950) but returnsnullfromterms()("no term",:918-921). A merge that re-encodes the segment gives thatFieldsto the copier, which declares the field and skips it. The writer sizes its packed field table for the declared total (Lucene90CompressingTermVectorsWriter.java:436-450,:483-498), andDirectWriter.finish()throwsWrong number of values added(:495); with no other field in the chunk,flushFieldNumsfails first (:465-466).IndexWritertreats it as tragic.
The independent reproduction's documents, default codec, main a9779ef3c193: doc 0 a = "secret" (term vectors with offsets), doc 1 body = "here public text" (no offsets). After the filtered addIndexes, the chunk's sections end at byte 21; the writer put 2 floats (fields a and body) as 8 zero bytes at [21, 29) and the compressed terms at 29; the reader starts decoding at 21. Decoding from 29 gives "herepublictext"; from 21 it throws. Without offsets and with a doc 2 that is then deleted, the commit's merge sees 2 declared fields (doc 0 a, doc 1 body) and 1 written: expected: 2, got: 1. CheckIndex: level 1 (default) clean; level 2 test: term vectors ERROR [offset 0 is invalid]; level 3 a NullPointerException on the null Terms; both report the whole segment as broken. Without offsets (the intended-behaviour check's probe), level 2 is clean and only level 3 fails.
Exposure and likelihood456 words
- Who is exposed. Applications that copy, prune or rewrite an index through
IndexWriter.addIndexes(CodecReader...)with their own reader that removes terms from fields that store term vectors (for example stripping a blocked vocabulary while copying an index without re-analysing the source). By reading, the same copier serves merges whose readers the application wraps (MergePolicy.OneMerge#wrapForMerge) and custom codec merges (not executed). Default codec andIndexWriterConfig, any index size. - The pattern is used. Lucene's own
TestFilterLeafReaderpasses a term-filteringFilterLeafReader(only terms containing 'e') toaddIndexes(SlowCodecReaderWrapper.wrap(reader)); it filters postings only. A 2016 java-user thread passes a filtering reader toaddIndexesto archive part of an index. No Lucene-shipped reader produces the zero-term shape from an ordinarily written segment, and no downstream engine checked does. - What it takes. Once such a copy runs, ordinary content triggers it. The merge failure needs only the emptied field and a later merge that re-encodes the segment; a deletion rules out the bulk copy once the merge policy picks the segment; in the test, one deletion of three and a
commit()with the default merge policy were enough. The unreadable chunk also needs the emptied field to store offsets and no other offset in its chunk. - What breaks. Up to 127 other documents of the chunk (those with term vectors) have unreadable term vectors (term-vector highlighting, term-vector "more like this" and term-vector APIs fail for them). On 9.0.0 and later every merge that re-encodes the segment closes the IndexWriter, and a fresh writer fails again, so indexing stops and the segment's partial deletions cannot be reclaimed by such a merge (a segment whose documents are all deleted is still dropped without one). A merge without deletions copies the bad chunk unchanged into the merged segment.
- Silent until then.
addIndexesandcommitsucceed;CheckIndexat its default level reports clean. With offsets, levels 2 and 3 report the whole segment broken; without offsets, level 2 is clean and level 3 fails. When it reports the segment broken,-exorcisewould remove all its documents. - Older releases, without assertions. Before 9.0.0 the merge "succeeds" and writes one document's term vectors under another document; before 10.4.0 some chunk reads return wrong bytes and others throw
ArrayIndexOutOfBoundsException(on 9.12.3 the security probe counted 30,572 exceptions and 10,388 silent wrong reads). With assertions on, these releases throwAssertionError. - What stays intact. The bug adds no damage to postings, stored fields or doc values beyond what the filter itself does (it removes the term from the postings on purpose; the postings writer drops the emptied field). One side effect: when the merge fails inside
commit(), that commit's deletion is not committed. - How likely. Rare: an expert pattern, and the searches found no report since 2013.
The test shows that addIndexes(CodecReader) from a reader whose term vectors list a field with zero terms (but offsets) writes a term-vector chunk that the default codec cannot read back, which damages another document of the chunk.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestTermVectorsZeroTermField extends LuceneTestCase {

  public void testOtherDocumentOfChunkReadsBack() throws Exception {
    FieldType offsets = new FieldType(TextField.TYPE_NOT_STORED);
    offsets.setStoreTermVectors(true);
    offsets.setStoreTermVectorOffsets(true);
    FieldType plain = new FieldType(TextField.TYPE_NOT_STORED);
    plain.setStoreTermVectors(true);
    try (Directory src = new ByteBuffersDirectory();
        Directory dst = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(src, new IndexWriterConfig())) {
        Document d0 = new Document();
        d0.add(new Field("a", "x", offsets));
        w.addDocument(d0);
        Document d1 = new Document();
        d1.add(new Field("b", "y", plain));
        w.addDocument(d1);
      }
      try (DirectoryReader r = DirectoryReader.open(src);
          IndexWriter w =
              new IndexWriter(dst, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
        LeafReader emptyVectorA =
            new FilterLeafReader(getOnlyLeafReader(r)) {
              @Override
              public TermVectors termVectors() throws IOException {
                TermVectors tv = in.termVectors();
                return new TermVectors() {
                  @Override
                  public Fields get(int doc) throws IOException {
                    return new FilterFields(tv.get(doc)) {
                      @Override
                      public Terms terms(String field) {
                        Terms t = in.terms(field);
                        if (field.equals("a") == false) {
                          return t;
                        }
                        return new FilterTerms(t) {
                          @Override
                          public TermsEnum iterator() {
                            return TermsEnum.EMPTY;
                          }

                          @Override
                          public long size() {
                            return 0;
                          }

                          @Override
                          public long getSumTotalTermFreq() {
                            return 0;
                          }

                          @Override
                          public long getSumDocFreq() {
                            return 0;
                          }

                          @Override
                          public int getDocCount() {
                            return 0;
                          }
                        };
                      }
                    };
                  }
                };
              }

              @Override
              public CacheHelper getCoreCacheHelper() {
                return null;
              }

              @Override
              public CacheHelper getReaderCacheHelper() {
                return null;
              }
            };
        w.addIndexes(SlowCodecReaderWrapper.wrap(emptyVectorA));
      }
      try (DirectoryReader r = DirectoryReader.open(dst)) {
        String doc1;
        try {
          doc1 = r.termVectors().get(1, "b").iterator().next().utf8ToString();
        } catch (IOException e) {
          doc1 = e.toString();
        }
        // expected: doc 1's term vector "y" reads back; actual: IOException "offset 0 is invalid"
        assertEquals("y", doc1);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-244/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.TestTermVectorsZeroTermField
- Expected vs actual
- Expected: doc 1's term vector for field
breads back asy. Actual:expected:<[y]> but was:<[java.io.IOException: offset 0 is invalid]>.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[y]> but was:<[java.io.IOException: offset 0 is invalid]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.index.TestTermVectorsZeroTermField.testOtherDocumentOfChunkReadsBack(TestTermVectorsZeroTermField.java:117)TermVectorsWriter.startDocumentpromisesstartFieldwill be callednumVectorFieldstimes; the copier in the same class declares a field, then skips it.- No javadoc forbids an empty
Terms;CheckIndex's slow-level postings and term-vector checks report no error on the filtered reader, and the postings writer simply drops the emptied field. - The default codec writes a segment it cannot read.
The full argument341 words
- Lucene's own contract.
startDocument: "startField(...)will be callednumVectorFieldstimes" (TermVectorsWriter.java:64-69).addAllDocVectorsdeclaresvectors.size()(:251) and skips a nullTerms(:268-271). - No
numTerms >= 1anywhere.startField: "startTermwill be callednumTermstimes" (:74-80).Fields,Terms,TermVectors,addIndexes(CodecReader...)(only "empty segments are dropped",IndexWriter.java:3254-3275) andSlowCodecReaderWrapper("Wraps arbitrary readers for merging",SlowCodecReaderWrapper.java:37-40) state no such rule. The test framework'sAssertingTermVectorsFormatchecks that the declared counts match, not that terms exist. - Empty
Termsfrom filtering are anticipated.Terms.getMax(): "empty: only possible from a FilteredTermsEnum..." (Terms.java:157,:174, both ingetMax());getMin()"returns null when there are no terms" (:139-141).CheckIndextolerates the postings "ghost field" (CheckIndex.java:2244-2249) and has the TODO "really the codec should not return a field from FieldsEnum if it has no Terms... but we do this today" (:1519-1522). - The format expected zero-term fields. The reader's
numTerms == 0branch ("no term",Lucene90CompressingTermVectorsReader.java:918-921) dates from the format's first commit in 2013, yet the reader keeps listing the field. - Lucene's own checks accept the input.
CheckIndex.testPostingsandtestTermVectorsatMIN_LEVEL_FOR_SLOW_CHECKSreport no error on the filtered reader (they are not a complete validator of arbitrary readers); the postings path drops the same emptied field and stays clean. - Input versus output. The filter lists the field and returns a non-null, empty
Terms, which nothing forbids. After the copy, the Lucene90 reader lists the field and returnsnullfromterms(), which conflicts withFields.terms: "This will return null if the field does not exist" (Fields.java:38). The shape the merge copier then mishandles is Lucene's own output. - Tests and precedent.
TestParallelReaderEmptyIndex.testEmptyIndexWithVectors: "Adding this index to another index should not throw any exception" (weak precedent: ordinary indexing has already omitted the empty field there). LUCENE-1918 (#2993, 2009) fixed anaddAllDocVectorscrash on unusualaddIndexesinput as a bug. 4.1.0, and 4.2.0 with the older Lucene40 term-vector format, handle the same input.
The devil's-advocate check212 words
The strongest case for "not supported" (built by the devil's-advocate checker and the cross-model reviewer): the codec SPI and Fields are @lucene.experimental; the indexing chain and MemoryIndex enforce numTerms > 0 on purpose (TermVectorsConsumerPerField.java:69-71; MemoryIndex filters numTokens > 0 in its Fields iterator and size(), MemoryIndex.java:1834, :1898; a comment there, "ensure infos.numTokens > 0 invariant; needed for correct operation of terms()", stood from 2005 until LUCENE-7091 removed it in 2016); the copier's comment "FieldsEnum shouldn't lie..." shows its author assumed a listed field has terms; and in #9450 / LUCENE-8403 maintainers declined "filtered" term vectors. So "your reader should hide a field once it has no terms left". The cross-model reviewer rated this argument moderate.
Why it fails: the restriction is written nowhere; Lucene's own Lucene90 reader produces exactly such a listing, which its own copier and CheckIndex (level 3) then cannot handle; LUCENE-8403 was about term vectors that disagree with the postings, while this filter keeps them identical; and the result is not a rejected input but a segment the default codec cannot fully read and that closes every writer whose merge re-encodes it. An IllegalArgumentException at addIndexes time would be a defensible answer; silent corruption is not. Verdict: a defect (adjudication: confirmed, high confidence).
Recommended The copier forwards only fields with at least one term, and declares exactly that many
In TermVectorsWriter.addAllDocVectors, first collect the fields that have at least one term, call startDocument with that count, and write only those (+32/-26, one file). The codec never sees a zero-term field and the declared count always matches. The test and the closest suites pass; a chunk already written with offsets stays unreadable.
final List<String> fieldNames = new ArrayList<>();
final List<Terms> fieldTerms = new ArrayList<>();
final List<Integer> fieldNumTerms = new ArrayList<>();
for (String fieldName : vectors) {
  final Terms terms = vectors.terms(fieldName);
  if (terms == null) continue;
  int numTerms = (int) terms.size();   // counted with the iterator when -1
  if (numTerms == 0) continue;
  fieldNames.add(fieldName); fieldTerms.add(terms); fieldNumTerms.add(numTerms);
}
final int numFields = fieldNames.size();
startDocument(numFields);
// then write exactly these fields
All options and trade-offs4 options · 759 words
One fix was built and validated in a scratch worktree of main a9779ef3c193; a codec-side hardening was run and is not enough alone; two more options are listed.
Workaround until fixed: a term-removing reader should hide a term-vector field whose remaining Terms is empty (leave it out of the per-document Fields iterator and size()). Not executed.
The copier forwards only fields with at least one term, and declares exactly that many (validated by the checks) (recommended)
In TermVectorsWriter.addAllDocVectors (TermVectorsWriter.java:235-328), first collect the fields whose Terms is non-null and has at least one term (counting with the iterator when size() is -1, as the code already does), call startDocument with that count, then write those fields. This is what the indexing chain already guarantees (TermVectorsConsumerPerField.java:69-71) and what the postings writer does with an emptied field. It is the common copier of Lucene's shipped non-bulk term-vector merge paths (a third-party codec that overrides merge(MergeState) would need its own check). It removes both symptoms: no zero-term instance is written, and a later merge of a segment whose reader lists a null-Terms field no longer miscounts. The finder's patch, with its now-unused java.util.Iterator import removed.
final List<String> fieldNames = new ArrayList<>();
final List<Terms> fieldTerms = new ArrayList<>();
final List<Integer> fieldNumTerms = new ArrayList<>();
for (String fieldName : vectors) {
  final Terms terms = vectors.terms(fieldName);
  if (terms == null) continue;
  int numTerms = (int) terms.size();   // counted with the iterator when -1
  if (numTerms == 0) continue;
  fieldNames.add(fieldName); fieldTerms.add(terms); fieldNumTerms.add(numTerms);
}
final int numFields = fieldNames.size();
startDocument(numFields);
// then write exactly these fields
Trade-offs
- Terms are counted in the first loop instead of the second, so the number of passes is unchanged; it keeps one document's field names,
Termsobjects and term counts in three small lists. Not benchmarked; this is already the slow per-document path. - Already-written segments (two-phase probe: written by stock main, merged with the fix): without offsets the merge now succeeds and
CheckIndexat level 3 is clean; with offsets the chunk is already unreadable, so the merge still fails reading it (offset 0 is invalid, tragic). The fix cannot repair those bytes; rebuilding the segment from the source documents avoids it, and salvage with a tolerant reader was not investigated.
What the checks validated
- Gradle in the scratch worktree,
-Ptests.seed=DEADBEEF: the new test passes 3 of 3 with assertions on and off. - The closest suites, gradle with the fix, seed DEADBEEF: core
*TermVector*,TestAddIndexes,TestFilterLeafReader,TestParallelReaderEmptyIndex,TestParallelLeafReader,TestCheckIndexand the new test, 19 classes and 151 tests, 0 failures with assertions on and off; codecs*TermVector*(SimpleText, whose merges use the same copier), 20 tests, 0 failures, 1 skipped;:lucene:core:check -x test(google-java-format, ecjLint, forbiddenApis) passes. - Repro harness with the fix shadowed: the new test 3/0 with
-eaand-da; the independent reproduction's test 3/0 with-eaand-da(registration check). Earlier, on a separate build host: 92 upstream tests (TestTermVectors,TestTermVectorsWriter,TestTermVectorsReader,TestAddIndexes,TestLucene90TermVectorsFormat) pass with-ea.
In Lucene90CompressingTermVectorsWriter.flushOffsets, hasOffsets |= fd.hasOffsets && fd.numTerms > 0; (+2/-1), so the floats are written only when the reader will read them (totalOffsets > 0).
// the reader reads AvgCharsPerTerm only if the chunk has an offset (totalOffsets > 0)
hasOffsets |= fd.hasOffsets && fd.numTerms > 0;
Trade-offs
Run with the new test (-ea and -da): doc 1 now reads back as [here, public, text], but CheckIndex (level 3) still fails on the listed zero-term field and both merge tests fail as before. It only changes what the writer emits for zero-term OFFSETS instances, which normal indexing never produces. Useful next to the recommended fix, so that no other caller of the codec API can produce the mismatched layout.
Throw IllegalArgumentException from addAllDocVectors (or the Lucene90 startField) on numTerms == 0 or on a listed field with null Terms.
Trade-offs
Defensible, but it turns a valid filtered copy into an error the application must work around, and it leaves an already-written segment with a null-Terms listing permanently unmergeable. Not run.
Skip numTerms == 0 instances in TVFields.iterator() and size().
Trade-offs
Fixes the merge miscount for existing segments too, but not the layout mismatch, and touches the read path. Not run. Separately, CheckIndex.testTermVectors could report a listed field with null Terms instead of throwing a NullPointerException (CheckIndex.java:4360-4362).
Only an application's own term-removing reader can trigger it (no Lucene-shipped reader, and none of the Elasticsearch, OpenSearch or Solr merge and addIndexes paths read for this check, removes term-vector terms), and on releases before 10.4.0 run without assertions the misreads are silent and can carry fragments of neighbouring documents' terms.
An AI tool's SMT model (Z3) of which optional sections the Lucene90 term-vector writer emits and its reader expects found one disagreement: an OFFSETS field with zero terms. The AI tool then found a public-API path that produces such a field, addIndexes with a term-removing reader, and found the merge failure by running it.
The method in full190 words
Method: SMT model checking with Z3 4.12.2 (the hunt's formal tier), by an AI tool working the hunt's unit on the compressing term-vector format, on main ea57360912ed.
- The model encodes, per field instance of one chunk, the flags (positions, offsets, payloads), the term count and the term frequencies, and for each optional section of the chunk when the writer emits it and when the reader reads it, each mapped to file:line.
- Obligation L1, "AvgCharsPerTerm presence agrees for every chunk the codec API accepts", is satisfiable for 1 to 4 field instances; the counterexample is an OFFSETS instance with
numTerms == 0. L2, the same undernumTerms >= 1(what the indexing chain guarantees), and L3, the block value counts, are unsatisfiable. - The AI tool then searched for a public-API path that delivers
numTerms == 0to the writer, foundaddIndexes(CodecReader)with a term-filtering reader thatCheckIndexaccepts, and found the second symptom, the poisoned merge, by running it. - Independent checks followed: a reproducer with its own filter and tests, a cross-model review, a devil's-advocate checker, an adjudication, a history sweep and a security probe (see the checks below).
No prior report found (two automated runs of 51 queries, 73 GitHub searches, JIRA, four mailing lists, downstream projects, all 413 open PRs; 2026-10-26). Closest: LUCENE-8403, a declined request for filtered term vectors; LUCENE-8277, open, about validating addIndexes input; LUCENE-1918, a fixed 2009 crash in the same copier.
Searches5 searches
Verdict: new. 30 hits were read; none is this bug. Not fixed upstream: no commit changes the conditions, and no open PR changes flushOffsets, the AvgCharsPerTerm conditions, the numTerms handling or TermVectorsWriter.java.
Closest items: #9450 / LUCENE-8403 "Support 'filtered' term vectors" (closed Won't Fix, 2019: another contributor's uncommitted patch there hit reader and CheckIndex trouble with fields emptied by its own modified writer, a different malformed shape; maintainers declined term vectors that disagree with the postings; nobody reports stock Lucene writing an unreadable chunk or a segment whose merges fail). #9324 / LUCENE-8277 "Better validate CodecReaders in addIndexes" (open; its check runs without slow checks and would not reject this input). #2993 / LUCENE-1918 (fixed 2009: an addAllDocVectors crash on unusual addIndexes input, pre-4.0 code). #15570 (2026-01) introduced the offset 0 is invalid message this bug now shows.
Gaps: GitHub search reads only the first page per query; the mailing lists were searched through the archive API; one web query was refused (HTTP 429); private security reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | two prior-art runs (16 issue/PR and 3 commit queries each) and 73 GraphQL searches: addAllDocVectors, flushOffsets, charsPerTerm, AvgCharsPerTerm, "offset 0 is invalid", "Wrong number of values added", empty or ghost term-vector fields, SlowCodecReaderWrapper term vectors | no report; related #9450, #9324, #2993, #15570 |
| Open PRs (apache/lucene) | 2026-10-26 | the touched files of all 413 open PRs | none touches TermVectorsWriter.java; #1003, #14397, #14716, #15194 and #16480 touch the Lucene90 term-vector files without changing these conditions |
| JIRA archive | 2026-10-26 | 4 archive queries per run and 9 REST queries (AvgCharsPerTerm, empty term vector, FilterCodecReader); resolutions of LUCENE-8403, 8277, 1918 | no report |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-26 | 20 queries per run through the archive API | no report; a 2016 java-user thread uses a filtering reader with addIndexes (documents, not terms) |
| Downstream projects and the web | 2026-10-26 | Elasticsearch, OpenSearch, Solr, lucene-solr, Lucene.NET; 14 web queries | no relevant hit |
Introduced in 4.2.0 (2013) by LUCENE-4599, the compressing term-vector format, which LUCENE-4733 made the default: 4.1.0 passes, 4.2.0 fails, and 4.2.0 with the older Lucene40 format passes. Every executed release from 4.2.0 to 10.5.2 and main fails. Not fixed upstream.
Versions tested7 rows
Introduced by 5837fe83bd8 (2013-01-21, @jpountz, "LUCENE-4599: New compressed TVF impl: CompressingTermVectorsFormat", issue #5664; Subversion era, no pull request; branch_4x backport 4a62a579a70, the commit in the 4.2.0 tag): the AvgCharsPerTerm write and read conditions and the reader's numTerms == 0 -> null branch all date from it. Made the default by 94b17a28de5 (2013-02-02, LUCENE-4733, #5798; branch_4x e3710747d87). The copier's declare-first, skip-null behaviour is older (873f1999244, 2011, LUCENE-2621) and was harmless with the Lucene40 format, whose reader returns an empty Terms for such a field.
Only the versions below were run. Git pickaxe shows the same code fragments (hasOffsets |= fd.hasOffsets, totalOffsets > 0, charsPerTerm) carried through the format's copies and refactors (LUCENE-5969, LUCENE-9705, #15712), so the releases in between appear affected.
Symptom changes, not fixes: 873ac5f162a (LUCENE-9907, #72, 9.0.0) moved the field tables to DirectWriter, whose count check makes the poisoned merge throw instead of silently writing one document's term vectors under another; #15570 (473dd7b5865, 10.4.0) made LZ4 reject offset 0, so the shifted read throws instead of returning wrong bytes.
All runs on Linux aarch64 with JDK 25.0.3; release jars SHA-1 checked; each with assertions on and off.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 3 of 3 fail (gradle and harness, assertions on and off; 30/30 over random seeds) |
| 10.5.2 | affected | this doc's test 3 of 3 fail: offset 0 is invalid, Wrong number of values added |
| 9.0.0, 9.4.2, 9.12.3 | affected | chunk read: AssertionError with assertions, ArrayIndexOutOfBoundsException or wrong bytes without; merge: Wrong number of values added, tragic |
| 4.2.0, 4.10.4, 5.5.5, 6.6.6, 7.0.0, 8.11.4 | silent without -ea | with assertions both fail; without, doc 1 reads wrong bytes (4.2.0: 6 NUL bytes), doc 2 throws ArrayIndexOutOfBoundsException, and the merge "succeeds" but writes one document's term vectors under another |
| 4.2.0 with the destination's term-vector format set to Lucene40 | control | passes: the failure follows the compressing format |
| 4.1.0 | not affected | passes (Lucene40 term-vector format is the default) |
fix on main a9779ef3c193 | not affected | the test 3/3 pass; closest suites pass |
An independent reproducer, a devil's-advocate checker and an adjudication confirmed it with their own runs; an OpenAI GPT-5.6 review (reading only, it could not run code) agreed on the root cause. This doc re-ran it on a9779ef3c193 with a new single-file test and validated the fix.
Checks and verdicts514 words
The verifier checks ran on main ea57360912ed; this doc and the main-refresh re-runs used a9779ef3c193 (none of the 7 commits in between touches the term-vector, LZ4, DirectWriter, CheckIndex or IndexWriter files). The cross-model review ran reading only, because its runner could not execute code.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Z3 model L1 SAT; JUnit fails 2 of 3 on main (-ea, -da) and 10.5.2, and 2 of 2 (its 9.x variant without the control) on 9.12.3 and 9.5.0; its control (CheckIndex on the filtered reader) passes. Its own CheckIndex assertion ran at level 0 and was vacuous. |
| cross-model review | no verdict | 5 attempts failed (reading only). |
| Independent reproducer | real | Own filter and tests written from the claim: 3 of 3 fail on main (-ea, -da), 10.5.2 and 9.12.3; 30 of 30 over random seeds; control passes at the slow CheckIndex level; two fresh writers fail again; CheckIndex by level 1/2/3. |
| Refute review (OpenAI GPT-5.6, reading only) | not real (procedural), medium | It could not run Java, and it voted not real on procedure only; it agreed on the root cause ("strongly corroborates both reported failure mechanisms"). Its one concrete objection (the finder's filter did not override prepareSeekExact) was re-tested with a filter that does: still fails. |
| Intended-behaviour devil's advocate | real | Built the strongest misuse case and rebutted it; re-ran on main and 10.5.2; its probe shows docs 1 and 2 unreadable and the 3-document segment broken at CheckIndex levels 2 and 3. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with a fresh seed: 3 of 3 fail with -ea and -da; asked for the CheckIndex level, the symptom conditions and the version wording to be stated. |
| History sweep | introduced in 4.2.0 | Fails on 4.2.0, 4.10.4, 5.5.5, 6.6.6, 7.0.0, 8.11.4, 9.0.0, 9.4.2, 9.12.3, 10.5.2 and main; passes on 4.1.0 and on 4.2.0 with the Lucene40 format. |
| Security screen | not security-sensitive | Application-only trigger, out of scope of SECURITY.md; probe of 1,000 random chunk layouts: silent cross-document misreads only on releases before 10.4.0 without assertions. |
| Main refresh | still reproduces | The finder's and the independent reproduction's tests fail on a9779ef3c193 as on ea57360912ed. |
| This doc's runs | reproduced on a9779ef3c193; fix validated | New 3-test JUnit: 3/3 fail through gradle and the harness (assertions on and off), 30/30 over random seeds, 3/3 on 10.5.2 and 9.12.3; with the fix 3/3 pass and the closest suites pass; the codec-side alternative fixes only the read; a segment already written with offsets stays unreadable. |
| Doc fact checks | wording fixed | An independent fact check (it re-ran the test, the fix and the model), a cross-model fact check (OpenAI GPT-5.6, reading only) and a diagram check confirmed the bug, the mechanism and the fix, and found wording that went beyond the evidence: the headline's merge scope, the version notes, the chunk bounds, the CheckIndex levels without offsets, a quote from a comment that no longer exists, and two summary-card and step-5 labels. All were fixed in this doc, the brief and the diagrams. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 489 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,574 words
- Registry title
- addIndexes(CodecReader) from a reader whose term vectors list a field with zero terms writes a term-vector chunk that the default codec cannot read back, and every later merge that re-encodes the segment closes the IndexWriter
- Area
- core / codecs: term vectors (TermVectorsWriter.addAllDocVectors merge copier; Lucene90 compressing term-vector writer and reader), reached through IndexWriter.addIndexes(CodecReader)
- Priority
- Low, rank 319: Needs an expert, application-written term-removing reader fed to addIndexes(CodecReader); normal indexing never produces the zero-term term-vector field.
- Impact class
- data corruption
- Impact note
- Applications that pass their own term-removing reader (a FilterLeafReader or FilterCodecReader that drops terms from the postings and term vectors, an expert pattern) to IndexWriter.addIndexes(CodecReader...) or to a merge whose readers they wrap are hit, with the default codec and IndexWriterConfig, at any index size and in every release since 4.2.0, as soon as one document's term-vector field is left listed with zero terms: every later merge that re-encodes that segment (a plain delete plus commit is enough) closes the IndexWriter tragically, on every retry (before 9.0.0 with assertions off it instead silently writes one document's term vectors under another document), and when that field stores offsets and nothing else in its chunk of up to 128 documents has offsets, the other documents' term vectors in the chunk are unreadable, while CheckIndex at its default level reports the index clean; normal indexing never produces such a field.
- Summary
- You copy an index with IndexWriter.addIndexes(CodecReader...) through a reader that removes some terms consistently from the postings and the term vectors (CheckIndex at its strictest level accepts this reader), so one document's term-vector field is left with zero terms. You expect the new segment to read back and merge like any other, as the postings do (the postings writer simply drops the emptied field). Instead the default term-vector format writes per-field AvgCharsPerTerm floats that its own reader does not expect, so when the emptied field stores offsets the other documents of the chunk throw 'offset 0 is invalid' on read, and because the reader lists the emptied field but returns null for it, the next merge that re-encodes the segment fails with 'Wrong number of values added' and closes the IndexWriter, on every retry.
- Introduced
- 5837fe83bd813b021d133c9f806cbcf215d24f67 ('LUCENE-4599: New compressed TVF impl: CompressingTermVectorsFormat', Adrien Grand (jpountz), 2013-01-21, Subversion r1436556, no pull request; LUCENE-4599 = apache/lucene#5664; branch_4x backport 4a62a579a70): the writer writes AvgCharsPerTerm when any field instance of the chunk has the OFFSETS flag while the reader reads it only when the chunk has an offset occurrence, and the reader returns null from terms() for a listed zero-term field; made the default term-vector format by 94b17a28de5 (LUCENE-4733 = apache/lucene#5798, 2013-02-02; branch_4x e3710747d87). Latent precondition: 873f1999244 (LUCENE-2621 = apache/lucene#3695, rmuir, 2011-11-16) added the codec-agnostic merge copier TermVectorsWriter.addAllDocVectors with startDocument(Fields.size()) before the fields are inspected, the null-Terms skip and startField(numTerms = 0) for an empty Terms, harmless with Lucene40TermVectorsFormat [exec: 4.1.0 and the 4.2.0 control]. Symptom change, not the bug: 873ac5f162a (LUCENE-9907, apache/lucene#72, 2021-04-15, first released in 9.0.0) moved flushFields/flushFlags to DirectWriter, whose count check makes the poisoned merge throw instead of silently writing wrong-document term vectors [read: git blame -w -C -C -M and git log -S in the full-history clone; exec: follow-up history probes] (2013-01-21 (compressing term-vector format, LUCENE-4599); 2013-02-02 (made the default, LUCENE-4733); the merge-copier part dates from 2011-11-16 (LUCENE-2621))
- First affected version
- 4.2.0 [exec] (tag 2013-03-11; the first release whose default term-vector format is the compressing one; on the 4.x API the trigger is addIndexes(IndexReader...) with a FilterAtomicReader, from 5.0.0 addIndexes(CodecReader...) with SlowCodecReaderWrapper); 4.1.0 is not affected [exec], and the 4.2.0 jars with only the destination term-vector format switched back to Lucene40TermVectorsFormat are not affected either [exec]
- Affected versions
- every release from 4.2.0 through 10.5.2, 10.6.0 (by reading) and main ea57360912ed. [exec] with a filter that removes the term from both the postings and the term vectors: 4.2.0, 4.10.4, 5.5.5, 6.6.6, 7.0.0, 8.11.4, 9.0.0 and 9.4.2 (follow-up history probes, -ea and -da), 9.5.0 and 9.12.3 (finder src-9x), 10.5.2 and main (-ea and -da): all fail; the independent reproduction's independent test fails on main (-ea, -da), 10.5.2 (-ea) and 9.12.3 (-ea, -da); the security probe also ran 10.3.2 and 10.4.0 (-da). Symptoms differ by version: before 9.0.0 with -da the re-encoding merge succeeds but writes one document's term vectors under another document (4.2.0-8.11.4), from 9.0.0 it throws 'Wrong number of values added' and closes the writer; chunk reads before 10.4.0 with -da return silently wrong bytes (including other documents' term bytes on 9.12.3 and 10.3.2) or throw ArrayIndexOutOfBoundsException, from 10.4.0 (#15570) they throw IOException 'offset 0 is invalid'. [read] every release in between has the same lines by blame; 5.0.0-5.2.x not executed (older Terms#iterator API). Not affected: 4.1.0 and older [exec 4.1.0; no compressing format before 4.2.0]. Not fixed on main [exec 2026-10-29: main 645d4fe14a2 fails with -ea and -da, same messages; #16919 changed only the reader's unknown-flags branch, which no variant reaches]; branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b have the same TermVectorsWriter and reader files [read]. All runs on aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code and voted “not real” while agreeing with the root cause (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- formal: Z3
- Upstream and prior reports
- none found (2026-10-26, plus the finder's interrupted scripted prior-report search; the prior-report record verdict new: two scripted prior-report searches of 51 queries each over apache/lucene issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web, 73 GitHub GraphQL searches including downstream repositories, 9 JIRA REST queries, the touched files of all 413 open apache/lucene PRs and a local git pickaxe; 30 hits listed, none is this bug); related prior items, not duplicates: #9450 / LUCENE-8403 (closed Won't Fix 2019: a feature request for term vectors that omit terms; another contributor's uncommitted patch there hit reader and CheckIndex trouble with fields emptied by its own modified writer, which declared all terms and then skipped some, and maintainers declined term vectors that disagree with the postings, which this trigger avoids), #9324 / LUCENE-8277 (open since 2018: validate CodecReaders in addIndexes; its proposed check runs without slow checks and would not reject this input), #2993 / LUCENE-1918 (fixed 2009: a precedent, the same kind of addAllDocVectors crash on unusual addIndexes input in pre-4.0 code), #15570 (merged 2026-01: introduced the 'offset 0 is invalid' message this bug now shows); not fixed upstream: ea57360912ed is the upstream main HEAD of 2026-10-26, and no open PR changes flushOffsets, the AvgCharsPerTerm conditions, the numTerms handling or TermVectorsWriter.java
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): this doc's JUnit through gradle in a scratch worktree (assertions on and off) and through the hunt repro harness (assertions on and off, 30 of 30 over 10 random-seed iterations); the 10.5.2 and 9.12.3 release jars; the recommended fix with the closest core and codecs suites, a codec-side alternative, and a two-phase probe over a segment written by stock main. The verifiers, the history sweep (4.1.0 to 10.5.2) and the security probe ran on mainea57360912ed; none of the 7 commits in between touches the term-vector, LZ4,DirectWriter,CheckIndexorIndexWriterfiles (one adds a vector-values override toSlowCodecReaderWrapper, which moves its cited javadoc by one line), and the main-refresh step re-ran the finder's and the independent reproduction's tests ona9779ef3c193with the same failures.
- Finding record
a Lucene main checkout @ ea57360912ed: lucene/core/src/java/org/apache/lucene/codecs/TermVectorsWriter.java:235-289 (startDocument at 251, null-Terms skip at 268-270); lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:629 (hasOffsets |= fd.hasOffsets), 643-656 (AvgCharsPerTerm written), 464-465 (flushFieldNums assert and fieldNums[numDistinctFields - 1]), 495 (DirectWriter finish in flushFields); lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsReader.java:587-591 (read only if totalOffsets > 0), 918-921 (numTerms == 0 -> null); lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumerPerField.java:69-74 (the indexing chain skips zero-term fields); lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java (chunk of 1 << 12 bytes or 128 documents)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/TermVectorsWriter.java:64-69 (startDocument javadoc), :74-80 (startField javadoc), :235-328 (addAllDocVectors; :242-251 count and startDocument, :259 loop, :267-271 null skip, :278-289 numTerms and startField, :326 assert)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:318-340 (startDocument, startField), :383-421 (flush), :436-450 (flushNumFields), :465-466 (flushFieldNums), :483-498 (flushFields, :495 finish), :623-657 (flushOffsets; :629, :643, :654-657), :915-931 (merge, :929 addAllDocVectors), :953-967 (canPerformBulkMerge)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsReader.java:551-561 (totalOffsets), :587-591 (AvgCharsPerTerm read), :879-902 (iterator), :918-921 (terms returns null), :948-950 (size)lucene/core/src/java/org/apache/lucene/util/compress/LZ4.java:113-116; lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:170; lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumerPerField.java:69-71
- Who is affected
lucene/core/src/test/org/apache/lucene/index/TestFilterLeafReader.java:35-53, :156-161lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:4128-4141, :6429-6434 (fully deleted segments are dropped)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/TermVectorsWriter.java:64-80, :251, :267-271lucene/core/src/java/org/apache/lucene/index/Fields.java:22-46 (:38 terms javadoc); lucene/core/src/java/org/apache/lucene/index/Terms.java:98-103, :157, :174; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3254-3275; lucene/core/src/java/org/apache/lucene/index/SlowCodecReaderWrapper.java:37-40lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:1519-1522, :2244-2249lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsReader.java:918-921lucene/test-framework/src/java/org/apache/lucene/tests/codecs/asserting/AssertingTermVectorsFormat.java:119-144lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:71-74
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/CheckIndex.java:4360-4362
- TestTermVectorsZeroTermField.java (JUnit test):
repro/LFV-244/src/org/apache/lucene/index/TestTermVectorsZeroTermField.java(121 lines)
Made from an executed tracing probe of the independent reproduction's documents on main a9779ef3c193 (chunk sections, byte ranges, reader reads, merge exceptions, retries, and the fix shadowed in). Re-rendered on 2026-10-27 after the diagram check: the summary card labels its two examples, and step 5 states what the fix does for segments written before it (without offsets they merge again; a chunk written with offsets stays unreadable) and what the codec-side change alone does. The alt text follows the final PNG.
assets/LFV-244/bug.png(489 KB)