AnalyzingSuggester keeps up to 256 spellings (surface forms) of texts that its analyzer turns into the same thing (the analyzed form), and it drops repeated copies of a spelling. But each dropped copy still uses up one of the 256 slots, so a rarer spelling disappears once another one repeats 256 times.
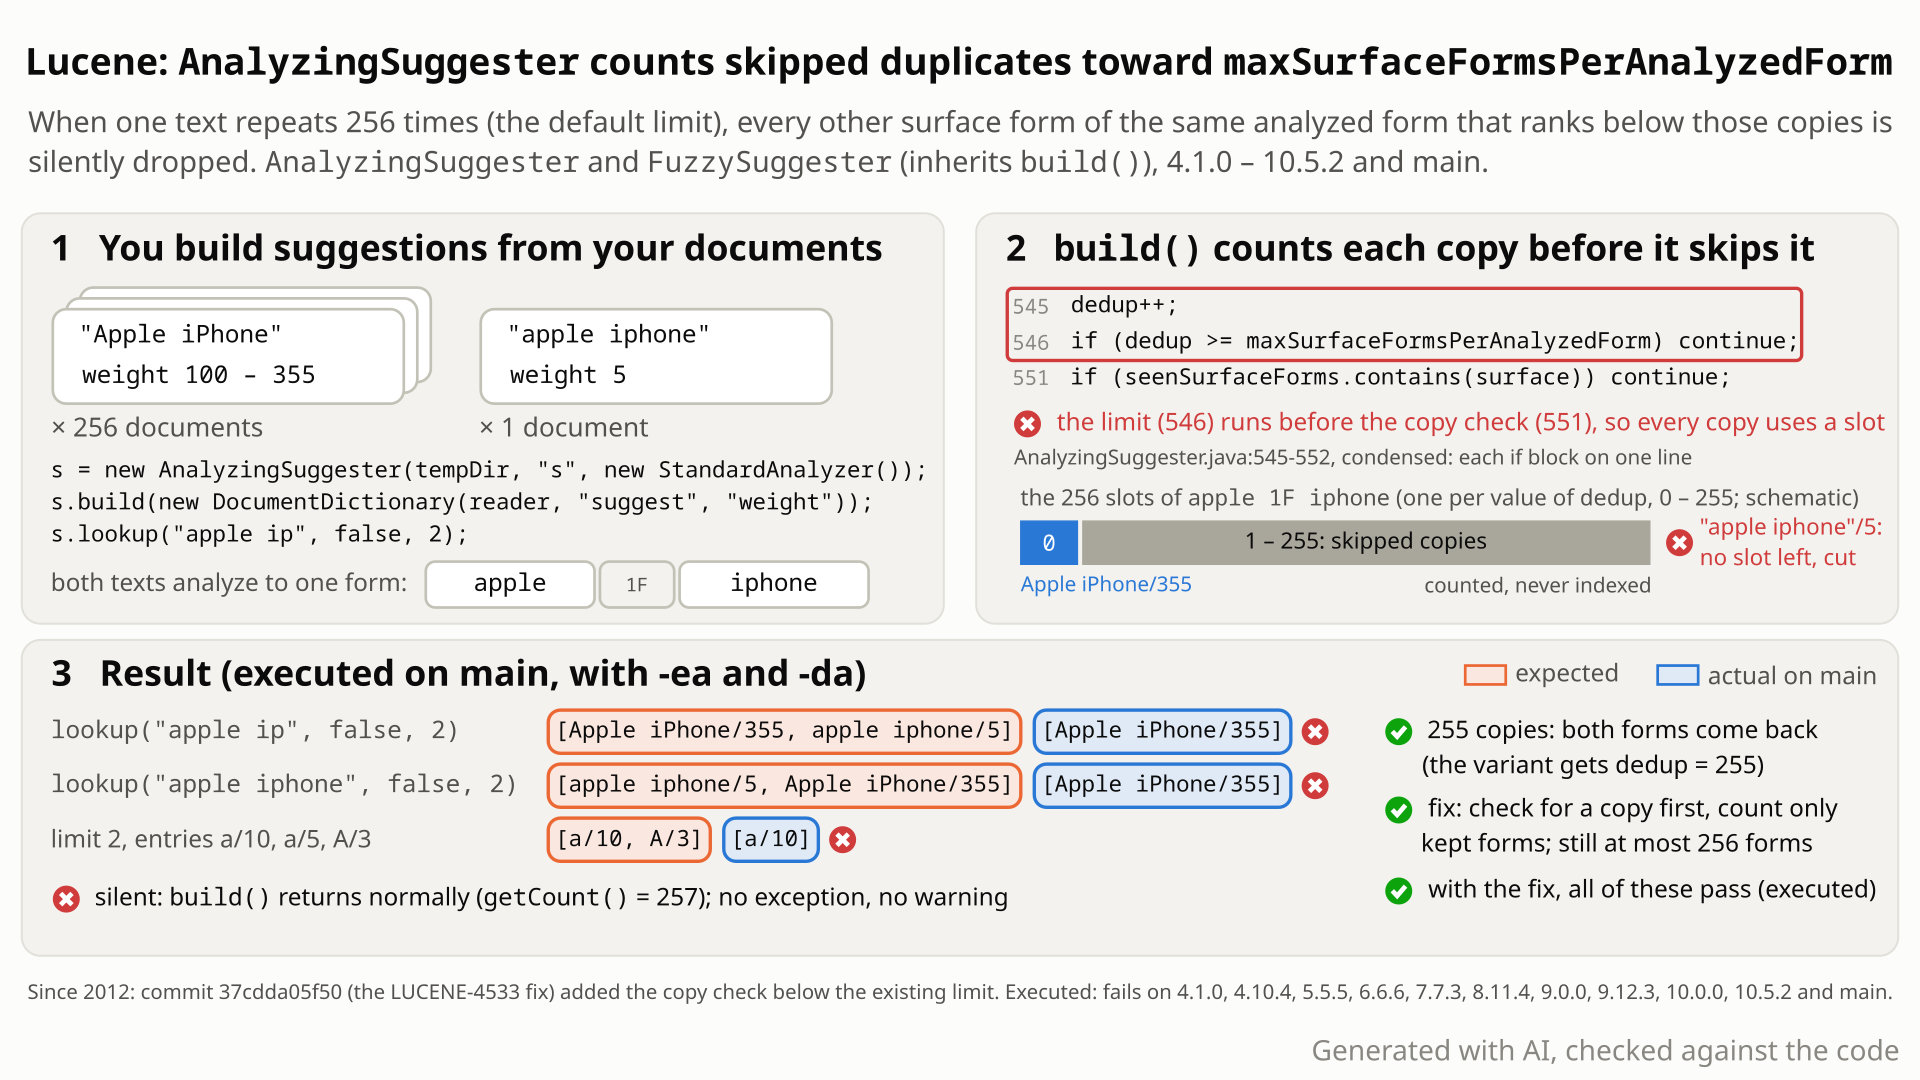
build() gives each skipped copy one of the 256 slots so apple iphone is cut, and the three lookups, expected against actual on main. Select the still to open it at full size. Generated with AI, checked against the code.- Index 256 documents whose suggestion field is
Apple iPhone(weights 100 to 355) and one whose field isapple iphone(weight 5). Build the defaultAnalyzingSuggesterwithStandardAnalyzerfrom aDocumentDictionary, which here yields one entry per document (one stored value each). Both texts analyze toapple iphone. - You expect
lookup("apple ip", false, 2)to return both. The limit,maxSurfaceFormsPerAnalyzedForm(default 256), counts distinct surface forms per analyzed form, and here there are 2. Repeated copies are meant to be dropped, keeping the highest weight. - You get only
[Apple iPhone/355]. Typingapple iphoneexactly does not return it either (EXACT_FIRST is on by default), andFuzzySuggesterdoes the same. With 255 documents both come back. - Why:
build()walks the entries of one analyzed form best first. For each entry it raises a counter, applies the limit, and only then skips a repeated copy. The first copy is kept; the other 255 are skipped but still take slots, soapple iphonegets counter 256 and is cut. - Smallest case: with the limit set to 2, the entries
a/10, a/5, A/3give[a/10]instead of[a/10, A/3]. Checking for the repeat before counting fixes it; with that change the whole suggest module passes (243 tests, 0 failures, 7 skipped by their own markers).
Applications that build AnalyzingSuggester or FuzzySuggester, default settings included, from input where one text repeats at least 256 times (a DocumentDictionary over a field such as a product name, brand or tag) and a less popular variant analyzes to the same form, such as a case or accent variant. With a lowered limit k, k copies suffice.
Mechanism, terms and numbers574 words
AnalyzingSuggester and FuzzySuggester keep at most maxSurfaceFormsPerAnalyzedForm surface forms (default 256) for texts that the analyzer maps to the same analyzed form, and they remove repeated copies of a surface form, keeping the highest-weighted one. build() applies the limit before it checks for a repeat (AnalyzingSuggester.java:544-554), so every skipped copy still uses up a slot. With StandardAnalyzer, the default constructor and a DocumentDictionary over 256 documents Apple iPhone (weights 100 to 355) plus one apple iphone (weight 5), lookup("apple ip", false, 2) returns only [Apple iPhone/355], and the exact text apple iphone is not returned either; 255 documents return both. With the limit set to 2, a/10, a/5, A/3 gives [a/10]. Nothing throws. 4.1.0 to 10.5.2 and main are affected (10 releases and main run; the same code order in every release tag of that range that was read), and checking for the repeat before counting fixes it.
- Surface form: the suggestion text as given, for example
Apple iPhone. Analyzed form: what the analyzer makes of it, hereapple iphonefor bothApple iPhoneandapple iphone. Lookups match on the analyzed form and return surface forms. maxSurfaceFormsPerAnalyzedForm(constructor argument, default 256, at most 256): how many surface forms are kept per analyzed form; the javadoc says the lowest-weighted ones are discarded beyond that.- Repeated copies: the same surface form given more than once, for example by a
DocumentDictionary, which yields one entry per stored value of the field in each live document (one per document for a single-valued field).build()keeps the highest-weighted copy and skips the rest.
build()sorts all entries by analyzed form, then by weight (highest first), then by surface bytes (AnalyzingComparator,AnalyzingSuggester.java:337-385).- It walks them with a counter
dedupper analyzed form. The counter is also a one-byte suffix that keeps each kept form's FST key unique (:570-571), which is why the limit is capped at 256 (:229-238). - For each further entry of the same analyzed form it runs
dedup++(:545), then cuts the entry ifdedup >= maxSurfaceFormsPerAnalyzedForm(:546-550), and only then skips it if the surface form was already kept (:551-553). A skipped copy is never added to the FST, but it has already raised the counter. - A new analyzed form resets the counter and the seen-set (
:555-559).FuzzySuggesterextendsAnalyzingSuggesterand does not overridebuild()(FuzzySuggester.java:66).
| entry | counter | what build() does | correct |
|---|---|---|---|
a/10 | 0 | first entry: kept | kept |
a/5 | 1 | 1 < 2; a copy of a: skipped | skipped, not counted |
A/3 | 2 | 2 >= 2: cut | kept: only 2 distinct forms |
lookup("a", false, 5) returns [a/10] instead of [a/10, A/3].
256 documents Apple iPhone (weights 100 to 355) and one apple iphone (weight 5), StandardAnalyzer, default constructor, DocumentDictionary: the 256 copies take counter values 0 to 255, apple iphone gets 256 and is cut. lookup("apple ip", false, 2) returns [Apple iPhone/355], and lookup("apple iphone", false, 2) returns [Apple iPhone/355] instead of [apple iphone/5, Apple iPhone/355] (the exact-match-first pass, :716-781, cannot find a form that is not in the FST). With 255 documents the variant gets counter 255 and both are returned. FuzzySuggester gives the same results.
Exposure and likelihood313 words
- Who. Users of
AnalyzingSuggesterandFuzzySuggester(both@lucene.experimental).DocumentDictionaryyields one entry per stored value of the field in each live document, so a field whose values repeat (product names, brands, categories, tags, popular titles) reaches 256 copies easily; aFileDictionarywith repeated lines does too. - What else it takes. A distinct variant of the same analyzed form that ranks below the copies (a lower weight, or the same weight and later in byte order,
AnalyzingSuggester.java:369-384; the equal-weight case was read, not executed): in practice a case, accent or punctuation variant under a lowercasing or folding analyzer. By reading (not executed), also texts that a stop-word or synonym analyzer maps to the same bytes. - Default settings. The 3-argument constructors (limit 256, EXACT_FIRST and PRESERVE_SEP) and
StandardAnalyzerare enough. With a lowered limit k, k copies are enough. - Silent. No exception and no log; the suggester is valid, just smaller. The lookup returns fewer results than asked for (or, by reading, the next suggestion moves up into the variant's place), and a user who types the variant exactly does not see it.
- The threshold is exact. A distinct form is dropped once at least
limitentries of its analyzed form, copies included, sort ahead of it: 255 copies keep it, 256 drop it. Distinct forms that rank above the copies, and other analyzed forms, are not affected. - Downstream (read, not tested): Solr's
FuzzyLookupFactoryandAnalyzingLookupFactorybuild these suggesters with this limit (default 256, configurable). The Elasticsearch completion suggester uses the separatesuggest.documentpackage, which this bug does not touch; for OpenSearch the search found no production use of these two classes, but it was not exhaustive. - How likely. Rated rare: the variant must share the analyzed form and rank below 256 copies, the main spelling is still suggested, so the loss is easy to miss, and nothing has been reported since 2013.
The test shows that AnalyzingSuggester with maxSurfaceFormsPerAnalyzedForm=2 and the entries a/10, a/5, A/3 (a lowercasing analyzer maps all three to a) counts the skipped duplicate copy a/5 toward the limit and drops the distinct surface form A/3.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.analyzing;

import java.io.StringReader;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.search.suggest.FileDictionary;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestAnalyzingSuggesterDuplicateCopyTakesSlot extends LuceneTestCase {

  public void testDuplicateCopyDoesNotUseSurfaceFormSlot() throws Exception {
    try (Directory tempDir = new ByteBuffersDirectory();
        Analyzer analyzer = new StandardAnalyzer()) {
      AnalyzingSuggester suggester =
          new AnalyzingSuggester(tempDir, "suggest", analyzer, analyzer, 0, 2, -1, true);
      suggester.build(new FileDictionary(new StringReader("a\t10\na\t5\nA\t3\n")));
      // expected: both surface forms of "a" fit in maxSurfaceFormsPerAnalyzedForm=2; actual: [a/10]
      assertEquals("[a/10, A/3]", suggester.lookup("a", false, 5).toString());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-248/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.analyzing.TestAnalyzingSuggesterDuplicateCopyTakesSlot
- Expected vs actual
- Expected:
lookup("a")=[a/10, A/3]. Actual:[a/10], with-eaand-da.
More files, environment, full output33 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[a/10[, A/3]]> but was:<[a/10[]]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.suggest.analyzing.TestAnalyzingSuggesterDuplicateCopyTakesSlot.testDuplicateCopyDoesNotUseSurfaceFormSlot(TestAnalyzingSuggesterDuplicateCopyTakesSlot.java:36)- The javadoc caps surface forms, not entries: "Maximum number of surface forms to keep for a single analyzed form".
- #5599 added the dedup to "de-dup the user's input ... before adding to the FST", below an older counter; the limit was not discussed.
- Skipped copies never use the one-byte suffix the limit protects. No test asserts today's behaviour.
The full argument356 words
- Contract. Constructor javadoc (
AnalyzingSuggester.java:205-206, the same inFuzzySuggester.java:138-139): "Maximum number of surface forms to keep for a single analyzed form. When there are too many surface forms we discard the lowest weighted ones." Field javadoc (:141): "Maximum number of dup surface forms (different surface forms for the same analyzed form)." Comment above the seen-set (:511-514): "Used to remove duplicate surface forms (but we still index the highest-weight one)." The repro has 2 distinct surface forms. - Intent. #5599 (LUCENE-4533, 2012, "if you pass dups (same surface form) to AnalyzingSuggester it can fail to return enough results"), by @mikemccand: "I think we should de-dup the user's input (keeping highest weight for each surface form) before adding to the FST." Their fix comment bounds the seen-set ("worst case is it holds 256 keys") but does not discuss how copies count toward the limit.
- History. The counter and the cut date from LUCENE-3842 (
f2f91bae46c, 2012-09-28), when every counted entry was indexed with its own suffix. The LUCENE-4533 fix (37cdda05f50, 2012-11-05) put the seen-set check below the existing cut. - Tests. No test asserts the current behaviour.
testMaxSurfaceFormsPerAnalyzedFormuses 3 distinct forms and no copies;testDupSurfaceFormsMissingResults3feeds repeated entries on purpose, with 5 entries;testRandomavoids repeated surface forms. A weaker analogy: the sibling document suggester'stestExtremeDeduplicationindexes at least 500 copies ofabcplus oneabdand expects both, so copies are not meant to crowd out a different suggestion there; but it is different code, andabcandabdare different analyzed forms, so it does not test a per-form cap. - Legal input. Nothing in
InputIterator,Lookup.build,DocumentDictionary,FileDictionary, CHANGES or MIGRATE requires unique input. - The exact-match comment. A comment in
lookup(:737-741) says the cap may have "pruned our exact match": the authors accepted that the cap can remove a form someone types exactly. That fits a cap on distinct forms and does not say identical copies count; here the cut happens with only 2 distinct forms, so the exact-match loss is a consequence of the wrong cut, not a separate defect.
The devil's-advocate check262 words
The strongest case for "works as designed" (the cross-model reviews, the reproducers and the adjudication looked for it): the limit is also an implementation bound, the one-byte suffix ("this is just an implementation limitation"), and the cut's comment reads "More than maxSurfaceFormsPerAnalyzedForm dups: skip the rest", so the counter could be read as a cap on raw entries; the classes are @lucene.experimental; callers could be expected to pre-aggregate (strongest for a FileDictionary or a custom iterator, weakest for a DocumentDictionary, whose entries come from the index); the authors knew the cap can prune an exact match (:737-741); today's order also skips the seen-set lookup for every entry after the cut; and the lost forms are low-ranked variants.
Why it fails: skipped copies never use a suffix byte, so counting them protects nothing the bound exists for, and the fix keeps the suffixes below the limit and the seen-set bounded by it; the saved lookups are not a documented contract; the javadoc defines the capped items as different surface forms; #5599 asked for dedup before the FST; the exact-match comment fits a cap on distinct forms, and here the cut happens with only 2 of them; and the outcome flips at an arbitrary copy count (255 kept, 256 lost). The cross-model reviews and the independent reproduction rated the intended-behaviour argument weak explicitly, and the intended-behaviour check and the adjudication rejected it; a later cross-model fact check of this doc rated it moderate for exact repeats from a FileDictionary or custom iterator and weak for DocumentDictionary. Verdict: a defect.
Recommended A: skip copies before counting; count only kept forms
Check for a repeated copy before counting, and count only the forms that are kept (cut when dedup + 1 >= limit, then dedup++). The repro passes 5 of 5, a new limit check 2 of 2, and the whole suggest module passes (243 tests, 0 failures, 7 skipped); the 256-form and seen-set bounds stay.
} else if (analyzed.get().equals(previousAnalyzed.get())) {
  if (seenSurfaceForms.contains(surface)) {
    // a lower weighted copy of a surface form we already kept: it does not count
    continue;
  }
  if (dedup + 1 >= maxSurfaceFormsPerAnalyzedForm) {
    // More than maxSurfaceFormsPerAnalyzedForm
    // dups: skip the rest:
    continue;
  }
  dedup++;
  seenSurfaceForms.add(BytesRef.deepCopyOf(surface));
All options and trade-offs4 options · 801 words
Option A was built and checked in a scratch worktree; B, a smaller variant, was checked on the repro, the fix check and the analyzing tests; D is a workaround for released versions.
The finder's change, +6/-5 in AnalyzingSuggester.build. A copy of a kept surface form is skipped first and does not count; a new distinct form is cut if it would exceed the limit, otherwise it takes the next counter value. Its comment should say "lower- or equal-weighted", since equal-weight copies are skipped too.
} else if (analyzed.get().equals(previousAnalyzed.get())) {
  if (seenSurfaceForms.contains(surface)) {
    // a lower weighted copy of a surface form we already kept: it does not count
    continue;
  }
  if (dedup + 1 >= maxSurfaceFormsPerAnalyzedForm) {
    // More than maxSurfaceFormsPerAnalyzedForm
    // dups: skip the rest:
    continue;
  }
  dedup++;
  seenSurfaceForms.add(BytesRef.deepCopyOf(surface));
Trade-offs
- Behaviour change on rebuild: repeated input now keeps up to
limitdistinct forms per analyzed form, as documented; the FST grows by at mostlimit - 1entries per analyzed form, the same bound as for unique input. Input whose analysis yields no repeated (analyzed form, surface form) record builds exactly as before. Distinct input alone does not guarantee that: a graph analyzer can yield repeated analyzed paths (builddoes not determinize, andFiniteStringsIteratormay return duplicates for a non-determinized automaton), and fix A stops counting those too (read, not executed). - No format change:
store/loadare untouched; kept forms get contiguous suffix bytes 0 to k-1 instead of gaps. Stored suggesters load as before and keep their old content until rebuilt. - Bounds kept: the seen-set holds only kept forms (at most
limit) and suffixes stay below the limit. - Cost: the seen-set lookup now runs for every entry of an analyzed form, also past the limit, where stock code skips it (the cut at
:546-549comes first): more hash lookups for analyzed forms with more thanlimitentries. The set stays bounded; the offline sort has already handled every entry. Not benchmarked. - Payloads as today: the sort and the seen-set compare surface bytes, not payloads (
:369-384,:551), so when equal-weight copies of one surface form carry different payloads, which payload is kept depends on the sorted order. Fix A does not change that.
What the checks validated
- The repro: 4 of 5 fail on stock, 5 of 5 pass with the fix (gradle with assertions on and off; the repro runner with -ea and -da).
- The fix check: 2 of 2 fail on stock, 2 of 2 pass (-ea and -da).
:lucene:suggest:test --tests 'org.apache.lucene.search.suggest.analyzing.*': 96 tests (89 upstream + 7 new), 0 failed, 1 skipped, with assertions on (seed 5EED7248) and off (seed 77AA2480).- All of
:lucene:suggest:test: 243 tests (236 upstream + 7 new), 0 failed, 7 skipped (6@Ignore, 1@Nightly, so 229 upstream tests ran), in both modes, repeated by the fact check at a fresh seed;:lucene:suggest:check -x test(format, ecjLint, forbiddenApis) passes. - Earlier checks: the finder's and the reproducers' tests pass with it, also in a separate re-run; the bounded-exhaustive harness finds 0 mismatches in its 3-entry lowercase scope; the 4.1.0 source with the fix passes the finder's repro.
Swap the two if blocks (+3/-3). The repro passes 5 of 5 and the fix check 2 of 2 (-ea, and -da in the fact check), and the 96 analyzing tests with assertions on; format passes.
} else if (analyzed.get().equals(previousAnalyzed.get())) {
  if (seenSurfaceForms.contains(surface)) {
    continue;
  }
  dedup++;
  if (dedup >= maxSurfaceFormsPerAnalyzedForm) {
    continue;
  }
  seenSurfaceForms.add(BytesRef.deepCopyOf(surface));
Trade-offs
Past the limit the counter keeps growing for every entry that is not a copy of a kept form (further distinct forms, and copies of cut forms, which never enter the seen-set; copies of kept forms are still skipped without counting), so it no longer equals the number of kept forms; by reading, it could misbehave only after about 2^31 entries of one analyzed form (int overflow). A keeps the counter exact. The whole suggest module was not run with B.
Change the javadoc instead of the code.
Trade-offs
Keeps today's output but contradicts the field javadoc and the intent of #5599, and leaves the 255/256 cliff that depends on how often another text repeats.
Wrap the InputIterator so each text is passed once with its highest weight, which is what build() keeps anyway. Validated on main, 10.5.2 and 9.12.3.
Trade-offs
Memory proportional to the number of distinct texts. The sketch drops payloads and contexts; a real wrapper must keep the payload of the highest-weighted copy. Alternatively aggregate at indexing time, one document per suggestion.
An AI tool compared the real class with a reference model written from its javadoc on every dictionary of up to 3 entries (bounded-exhaustive translation validation). Every mismatch traced to this one cause; with the fix, the rerun AnalyzingSuggester scope had none. The suspicion came from reading the code; no model checker or prover was used.
The method in full212 words
Method: bounded-exhaustive translation validation (the hunt's "semi-formal" tier), a hunt unit (suggesters), 2026-10-26, main ea57360912ed.
- The finder wrote a reference from the javadoc: per analyzed form, keep the
maxSurfaceFormsPerAnalyzedFormhighest-weighted distinct surface forms; repeated copies keep their highest weight. The hypothesis came from readingbuild()while writing it, and a probe confirmed it. - On separate build machines the harness compared the real
AnalyzingSuggesterandFuzzySuggesterwith the reference for every dictionary of at most 3 entries over 12 strings and weights {0, 1, 2}, every key of up to 3 characters and num 1 to 7: 330,258 mismatches in 161,239,680 lookups (lowercasing analyzer, 12 AnalyzingSuggester configurations), 29,184 with a plain analyzer, and 409,488 in 644,958,720 (plain analyzer, 48 FuzzySuggester configurations). All were of this one class and none unexplained; there were none with 2 or fewer entries. - 20,000 random dictionaries of up to 6 entries: 1,746,904 (lowercase) and 469,544 (plain) mismatches, all of this class. With the fix shadowed: 0 mismatches in the 3-entry lowercasing AnalyzingSuggester scope; the FuzzySuggester scope was not re-run with the fix. A seeded mutant of the reference (a flipped tie-break) was caught (31,752 unexplained mismatches), so the comparison is not vacuous.
- Exhaustive only within these bounds. The failing case was then written as a public-API JUnit.
No prior report found: 98 queries over GitHub, JIRA, the mailing lists, downstream projects, Stack Overflow and the web, plus the changed files of all 413 open PRs (2026-10-26). The closest item, #5599 (2012), is where the dedup code came from; it never discusses the limit.
Searches4 searches
No report of this defect was found; novelty is "new". #5599 / LUCENE-4533 is the origin of the dedup code.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; Elasticsearch, OpenSearch, Solr; dev@, java-user@, issues@, commits@; LUCENE JIRA; the web | 2026-10-26 | 81 queries with a scripted prior-report search (class names, maxSurfaceFormsPerAnalyzedForm, seenSurfaceForms, surface/analyzed form, duplicate/dedup, missing suggestions, case-insensitive, DocumentDictionary); comments of the top 20 candidates read | 333 distinct hits; none is this bug |
| GitHub-wide, SOLR and LUCENE JIRA, Stack Overflow, git history | 2026-10-26 | 17 manual searches; the comment threads of 12 related LUCENE issues read and grepped for maxSurface, dedup, dups, 256 and limit | no report |
| Open apache/lucene PRs | 2026-10-26 | the changed files of all 413 open PRs | none touches AnalyzingSuggester.java or FuzzySuggester.java |
| Related items (read) | 2026-10-26 | 23 hits read in full | #5599 / LUCENE-4533 (origin of the dedup; limit not discussed), #4915 / LUCENE-3842 (introduced the limit), elastic/elasticsearch#7170 (a fork that keeps one copy per document by design), elastic/elasticsearch#10406 (the limit working as documented) |
Introduced in 2012 by 37cdda05f50, the fix for #5599 (LUCENE-4533), which put the duplicate check below an older counter; first released in 4.1.0, the first release with these classes. All 10 releases run, from 4.1.0 to 10.5.2, and main fail the repro; none of them kept the variant.
Versions tested6 rows
Introduced by 37cdda05f50 (2012-11-05, by @mikemccand; branch_4x backport d9a88eb0e12), the fix for #5599 / LUCENE-4533 (its message says LUCENE-4534, which is the 0-byte fix committed just before). It added the seen-set check below the counter and cut, which came with AnalyzingSuggester itself in f2f91bae46c (LUCENE-3842, 2012-09-28), when every counted entry was indexed. Subversion era, no PR.
Isolation is partial: the 4.1.0 source with only the dedup lines removed also loses the variant on these inputs, but there the copy that took the slot was itself indexed as a duplicate result (the LUCENE-4533 bug). All 120 release tags from 4.1.0 to 10.5.2 in the history clone keep the count-then-cut-then-dedup order (the clone has no 8.x tags after 8.8.1, so later 8.x maintenance tags were not read; 8.11.4 was run), and upstream main still has it. The trunk hashes give the main-line origin; 4.1.0 got the code through branch_4x backports (of the commits named here only d9a88eb0e12 is an ancestor of the 4.1.0 tag).
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | this doc's repro 4 of 5 fail with -ea and -da; the finder's 2 of 3 |
| 10.5.2, 9.12.3 | affected | this doc's repro 4 of 5 fail (10.5.2 -ea, 9.12.3 -da); the finder's repro fails too |
| 10.0.0, 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5, 4.10.4 | affected | the finder's repro (or its API port) fails 2 of 3 with identical messages |
| 4.1.0 | first release | fails 2 of 3 (also with -da); passes 3 of 3 with the fix shadowed |
| 4.0.0 | API absent | no analyzing package; the repro does not compile |
| fix A / fix B on main | not affected | the repro and the fix check pass; the whole suggest module passes with fix A (243 tests, 0 failures, 7 skipped) |
The finder's harness, independent reproducers (one with a realistic DocumentDictionary test), reviews by a model from another family, an adjudication with a fresh seed and a re-run step: confirmed, high confidence. One review returned not real only because it could not run code; it agreed with the root cause.
Checks and verdicts472 words
Each check ran or read independently; a separate run and the later steps re-ran the tests with fresh seeds.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Harness: every mismatch of this one class, 0 unexplained, 0 with the fix. JUnit fails 2 of 3 on main (-ea, -da), 10.5.2, 9.12.3, 8.11.4 and 6.6.6; with the fix 3 of 3 and the 37 upstream TestAnalyzingSuggester and TestFuzzySuggester tests pass. |
| cross-model review, refute lens | not real (low), procedural | OpenAI GPT-5.6, read-only, could not run Java, so it voted not real on procedure only; root cause agrees, inputs in contract, intended-behaviour argument weak, 10 of 11 evidence items support the bug. A separate run re-ran the repro: 2 of 3 fail. |
| Independent reproducer | real | Own 7-test JUnit: 5 of 7 fail on main (-ea, -da), 10.5.2 and 9.12.3, including FuzzySuggester, a DocumentDictionary and an exact duplicate; the 255-copy control passes; 7 of 7 pass with the fix. |
| cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, read-only; intended-behaviour argument weak; 11 of 12 evidence items support the bug, among them testExtremeDeduplication. A separate run re-ran the repro with seed 1234ABCD: main and 10.5.2 fail, the fix passes. |
| Devil's advocate | real (high) | DocumentDictionary + StandardAnalyzer + default constructors: 3 of 4 fail on main (-ea, -da) and 10.5.2, 4 of 4 pass with the fix; rebutted four works-as-designed readings. |
| adjudication | confirmed (high), silent wrong results | Re-ran the independent reproduction's test with seed 7A11C0DE: 5 of 7 fail with -ea and -da; 7 of 7 pass with the fix. |
| Follow-up and registration check | holds | History sweep over 12 targets, prior-report search (new), security (none); fresh seeds 5EED6411 to 5EED6418 for the finder's, the independent reproduction's and the intended-behaviour check's tests: all fail on stock and pass with the fix. |
| this doc's runs | reproduced, fix validated | New repro 4 of 5 fail on main, 10.5.2 and 9.12.3; fix A validated on the whole suggest module in a scratch worktree; fix B and the workaround checked. |
| Fact check of this doc (re-ran everything) | holds; one command comment fixed | Re-ran the doc's gradle command on main (4 of 5 fail, both modes), the repro on main, 10.5.2 and 9.12.3 at fresh seeds, both fixes, the fix check, the workaround and the whole suggest module with fix A (243 tests, 0 failures, 7 skipped). Found that the gradle command cannot run on 10.5.x or 9.12.x with JDK 25; fixed. |
| Cross-model fact check (OpenAI GPT-5.6, reading only) | core bug real; 18 accuracy findings | Root cause, first release and fix A confirmed; 6 wording errors, 6 overclaims and 6 missing caveats, all handled: 16 fixed, 1 left open, 1 declined with reasons. |
| Diagram check | correct; no errors | Every value on screen re-run and matched; optional polish only. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 469 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,437 words
- Registry title
- AnalyzingSuggester and FuzzySuggester count skipped duplicate copies of a surface form toward maxSurfaceFormsPerAnalyzedForm, so distinct lower-weighted surface forms are silently dropped
- Area
- suggest / analyzing suggester (AnalyzingSuggester.build, inherited by FuzzySuggester)
- Priority
- Low, rank 268: Default suggester settings, but it needs 256 copies of one text plus a lower-ranked variant of the same analyzed form, and the dominant form is still suggested.
- Impact class
- silent wrong results
- Impact note
- Applications that build an AnalyzingSuggester or FuzzySuggester (default constructors and the default limit of 256 suffice; every release from 4.1.0 through 10.5.2 and main) from input that repeats one suggestion text at least maxSurfaceFormsPerAnalyzedForm times, for example a DocumentDictionary over 256 or more documents with the same suggestion text, silently lose every distinct surface form of the same analyzed form that ranks below those copies (a case, accent or punctuation variant, or another text the analyzer maps to the same bytes), including its EXACT_FIRST exact match, with no error; a lowered limit makes it easy to hit, while distinct forms that rank above the copies are unaffected.
- Summary
- You build an AnalyzingSuggester or FuzzySuggester from entries in which one text repeats, for example 256 documents with 'Apple iPhone' and one with 'apple iphone', which a lowercasing analyzer maps to the same analyzed form, and you expect both surface forms back, because maxSurfaceFormsPerAnalyzedForm (default 256) is documented as the 'maximum number of surface forms to keep for a single analyzed form' and repeated copies are documented as removed. build() increments its per-analyzed-form counter and applies the limit before it checks whether the surface form was already seen, so every skipped copy still uses up a slot: lookup('apple ip') returns only [Apple iPhone], and with a limit of 2 the entries a/10, a/5, A/3 give [a/10] instead of [a/10, A/3]. With 255 copies, or without the repeated copy, both forms are returned.
- Introduced
- 37cdda05f50b1c544efc5aaac4135dbcd7a28cba (mikemccand, trunk svn r1405977, 2012-11-05; branch_4x backport d9a88eb0e12ea157c2092e51ab39b878788c0dfd, r1405978; no pull request, Subversion era). Its message says 'LUCENE-4534: dedup same surface form in Analyzing/FuzzySuggester', but it is the fix for LUCENE-4533 / #5599 (LUCENE-4534 is the 0-byte-key fix 2537836d4ab committed just before). It added the seenSurfaceForms check below the existing counter and cut [read: git blame of main lines 545-554 names exactly this commit and f2f91bae46cb; git log -L 540,560 lists only f2f91bae46c, 2537836d4ab, 37cdda05f50 and the mechanical 94d1b7f5a64 (LUCENE-5864, BytesRef to BytesRefBuilder)]. The counter (dedup++) and the cut come from f2f91bae46cbc4a883324521767e4701fbbbc14a (LUCENE-3842 'add AnalyzingSuggester', 2012-09-28), when there was no surface-form dedup and every counted entry was indexed. Isolation is partial [exec, follow-up history]: the 4.1.0 source with only the dedup lines removed also loses the distinct form on these inputs (with -da; with -ea a TopNSearcher assertion fires, the LUCENE-4533 symptom), but there the copy that took the slot was itself indexed as a duplicate result; 37cdda05f50 removed the copy from the FST and left it counted. Both commits predate the first release of the API (2012-11-05 (the dedup check placed below the cut; the counter and cut date from 2012-09-28))
- First affected version
- 4.1.0 [exec] (the first release that has AnalyzingSuggester and FuzzySuggester at all; the repro fails 2 of 3 there and passes 3 of 3 with the fix shadowed); 4.0.0 has no analyzing package, so the repro does not compile [exec]
- Affected versions
- every release from 4.1.0 through 10.5.2 and main ea57360912ed; not fixed on upstream main as of 2026-10-26 [exec: the finder's 3-test repro, or its API port, fails 2 of 3 with identical messages and a passing control on 4.1.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (main with -ea and -da; 4.1.0 also with -da); the independent reproduction's own 7-test JUnit fails 5 of 7 on main (-ea and -da), 10.5.2 and 9.12.3; the intended-behaviour check's DocumentDictionary/StandardAnalyzer test fails 3 of 4 on main (-ea and -da) and 10.5.2; read: all 120 release tags from 4.1.0 to 10.5.2 keep the count-then-cut-then-dedup order, and the upstream main file read on 2026-10-26 still has it]. Caveats: releases before 10.x were run on JDK 25 with API ports of the same test (TermFreqIterator in 4.1-4.5, no temp Directory before 6.0, pre-9.1 test-framework packages); FuzzySuggester was executed on main, 10.5.2 and 9.12.3 only (it does not override build() in 4.1.0 or main); unreleased maintenance branches were not checked
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 98 recorded queries, namely the scripted prior-report search with 81 queries over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web, plus 17 manual GitHub-wide, JIRA (comment threads of 12 related issues read), Stack Overflow, web and git-history searches; the changed files of all 413 open apache/lucene PRs; 23 hits read and classified, none the same bug; the finder, the independent reproduction and the intended-behaviour check found nothing either); not fixed upstream (upstream main still has the 2012 order, read 2026-10-26, last commit touching the file 54283150a816 of 2026-06-14, a build-tooling change; no open PR touches AnalyzingSuggester.java or FuzzySuggester.java); closest items, not reports: #5599 / LUCENE-4533 (closed 2012, 'if you pass dups (same surface form) to AnalyzingSuggester it can fail to return enough results'; its fix added the dedup check that this bug places too late, and neither the issue nor the commit discusses the limit), #4915 / LUCENE-3842 (introduced the limit; 'duplicates' there means different surface forms with the same analyzed form), and elastic/elasticsearch#7170 (2014, a downstream fork that keeps one copy per document by design, where a reviewer asked what happens when many same-value documents exceed the limit; a different design in a different codebase)
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26) on JDK 25.0.3: the brief's JUnit repro through the repro runner with -ea and -da and through gradle in a scratch worktree, stock and with fixes A and B (the worktree was removed after the runs), plus the whole suggest module with fix A in both assertion modes; the same repro on the 10.5.2 and 9.12.3 jars (SHA-1 checked); the workaround on main, 10.5.2 and 9.12.3; the history step's runs of the finder's repro on 4.0.0 (API absent), 4.1.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:98 (at ea57360912ed) (@lucene.experimental), :141 (field javadoc 'Maximum number of dup surface forms (different surface forms for the same analyzed form).'), :169-175 (default constructor: EXACT_FIRST | PRESERVE_SEP, 256), :205-206 (constructor javadoc 'Maximum number of surface forms to keep for a single analyzed form. When there are too many surface forms we discard the lowest weighted ones.'), :229-239 (limit 1..256, one-byte suffix), :511-517 (seen-set comment 'Used to remove duplicate surface forms (but we still index the highest-weight one)' and the counter), :544-554 (dedup++ and the cut run before seenSurfaceForms.contains), :556 (counter reset on a new analyzed form), :571-586 (suffix byte and FST add)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:66 (at ea57360912ed) (final class FuzzySuggester extends AnalyzingSuggester, no build override), :138-139 (same limit javadoc)lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggester.java:804 (at ea57360912ed) (testRandom: 'Don't add same surface form more than once'), :976 (testMaxSurfaceFormsPerAnalyzedForm: 3 distinct forms, no copies), :1226 (testDupSurfaceFormsMissingResults3: repeated entries, limit 256); lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestSuggestField.java:267 (testExtremeDeduplication)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:229-238, (at ea57360912ed) 337-385, 511-517, 540-560, 570-587, 716-781lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:66 (at ea57360912ed)lucene/suggest/src/java/org/apache/lucene/search/suggest/DocumentDictionary.java:147-153, (at ea57360912ed) 205-224
- Who is affected
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:98, (at ea57360912ed) 169-176, 205-206; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:64lucene/suggest/src/java/org/apache/lucene/search/suggest/DocumentDictionary.java:36-43 (at ea57360912ed)lucene/suggest/src/java/org/apache/lucene/search/suggest/DocumentDictionary.java:147-153, (at ea57360912ed) 205-224
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:141, (at ea57360912ed) 205-206, 229-232, 511-514, 547-548; lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/FuzzySuggester.java:138-139lucene/suggest/src/test/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggester.java:804, (at ea57360912ed) 976-991, 1226-1243; lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestSuggestField.java:267-300https://github.com/apache/lucene/issues/5599 (body and comments, read 2026-10-26 with gh issue view)lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:737-741 (at ea57360912ed)
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:511-517, (at ea57360912ed) 540-560, 570-571, 600-621lucene/suggest/src/java/org/apache/lucene/search/suggest/analyzing/AnalyzingSuggester.java:369-384, (at ea57360912ed) 415-419, 864-883; lucene/core/src/java/org/apache/lucene/util/automaton/FiniteStringsIterator.java:33
- TestAnalyzingSuggesterDuplicateCopyTakesSlot.java (JUnit test):
repro/LFV-248/src/org/apache/lucene/search/suggest/analyzing/TestAnalyzingSuggesterDuplicateCopyTakesSlot.java(39 lines)
A summary diagram (PNG), produced separately from this text from its own probe runs of the DocumentDictionary case above and the limit-2 miniature a/10, a/5, A/3. The slot bar is schematic. The alt text was written from the PNG; check it again if the diagram changes.
assets/LFV-248/bug.png(469 KB)