SharedTermsUniformSplit stores the terms of all fields of its group in one shared block per segment. Its merge assumes each old segment holds the group's fields in one such block: it reads the block of the first field it finds and skips the rest. After a mapping change some group fields sit elsewhere, so their old postings are dropped.
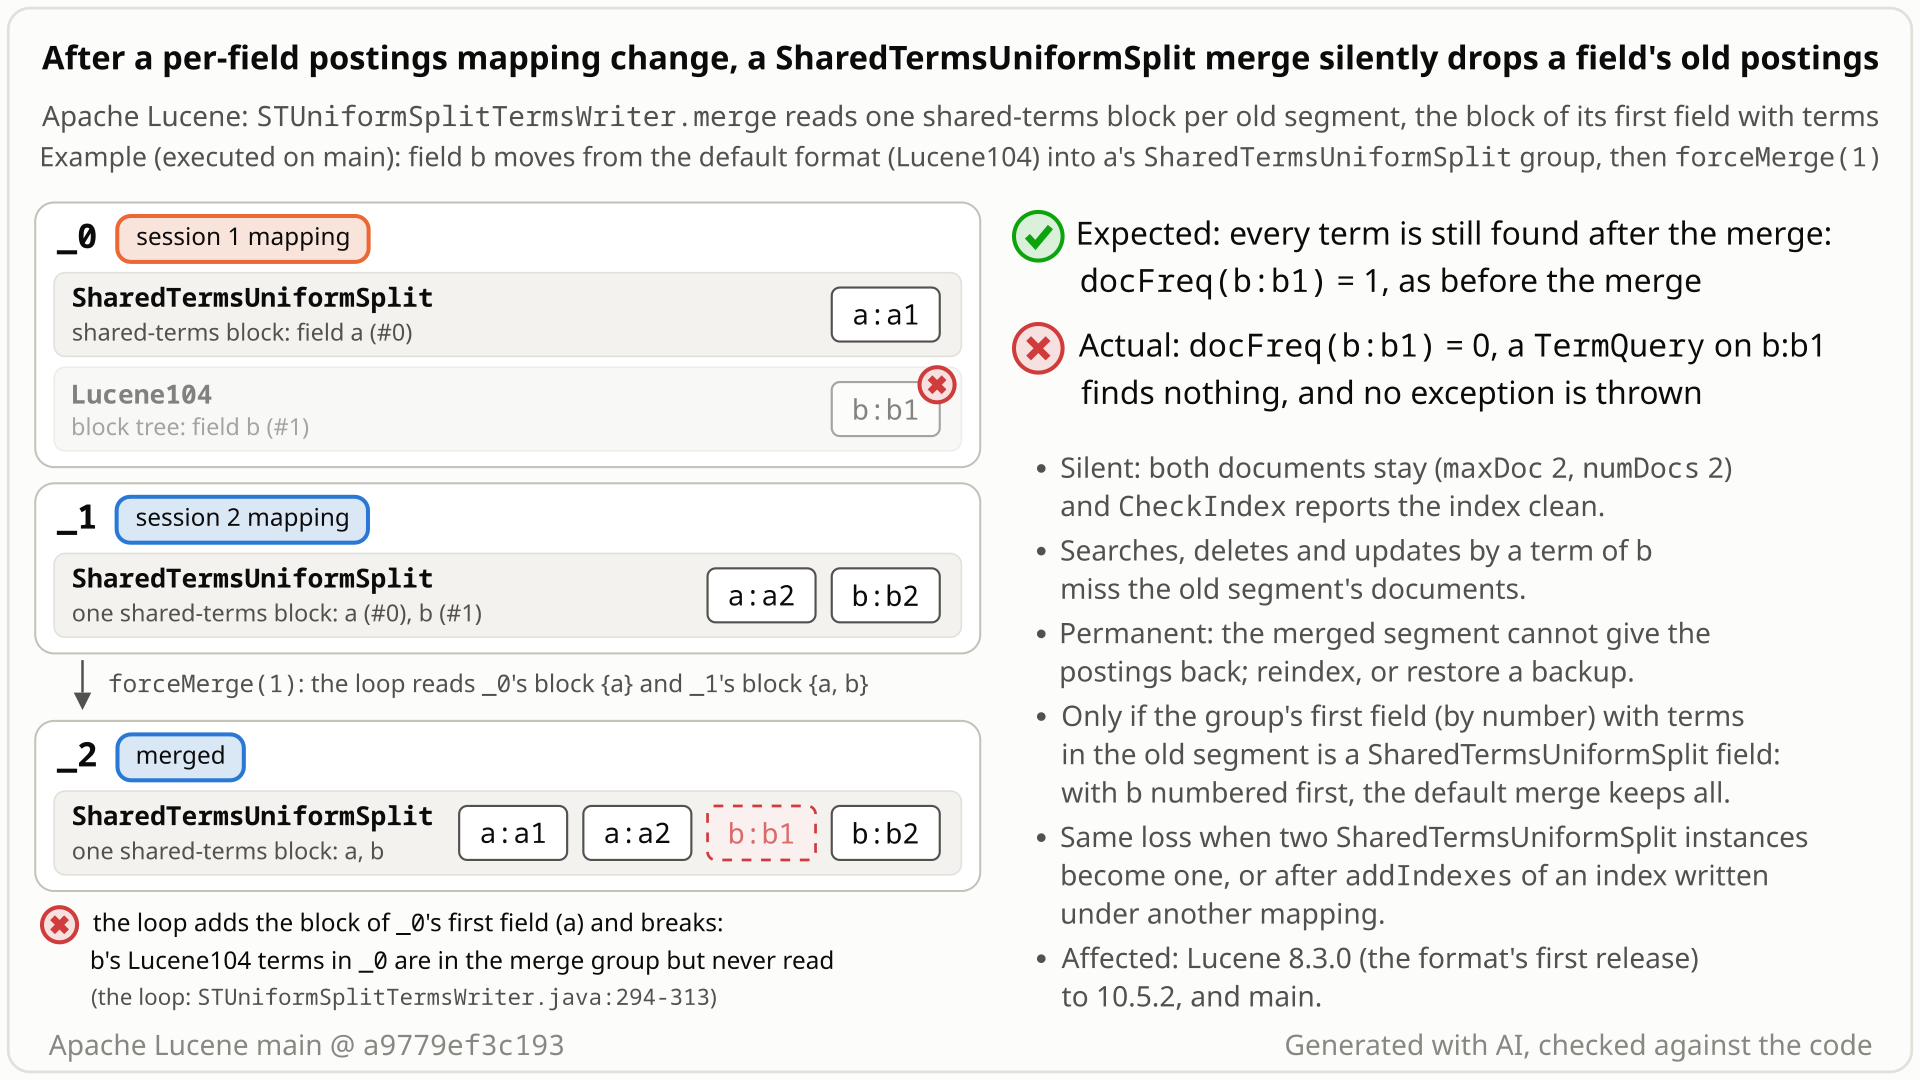
a in a shared-terms block and b in a separate terms dictionary, and the merge reads only the shared block, so b:b1 never reaches the merged segment. Select the still to open it at full size. Generated with AI, checked against the code.- Session 1: a
Lucene104Codecsubclass puts fieldain SharedTermsUniformSplit and fieldbin the default postings format. Add doc 1 (a=a1,b=b1). The segment keepsain a shared-terms block andbin a separate terms dictionary. - Session 2: a new writer maps both
aandbto SharedTermsUniformSplit. Add doc 2 (a=a2,b=b2) andforceMerge(1). This is allowed: every segment records its own field-to-format mapping. - You expect all 4 terms to be found once after the merge, as before it:
docFreq1 for a:a1, a:a2, b:b1 and b:b2. - Instead the merge reads only the old segment's shared-terms block, which holds
aalone, and never readsb's old postings:docFreq(b:b1)is 0 and aTermQueryfinds 0 hits, although both documents are still in the index. - No error, and
CheckIndexreports the index clean. The same loss happens when two SharedTermsUniformSplit instances become one, or throughaddIndexes; nothing is lost whenbhas the lower field number.
Only applications that use the experimental, non-default SharedTermsUniformSplit format and then change the per-field mapping of an existing index, or addIndexes from an index with another mapping. Default codecs are not affected. Two documents are enough. The merged segment cannot give the lost postings back: reindex from source, or restore a pre-merge commit or backup.
Mechanism, terms and numbers665 words
PerFieldPostingsFormat records in every segment which postings format, and which instance of it, holds each field, and it reads each segment back with that segment's own mapping, so the mapping for new segments may change. On merge, the merged segment's fields are grouped by the current mapping, and each format merges its group from a merge state that is restricted to the group's field names but still returns each old segment's own terms. The experimental SharedTermsUniformSplit format (lucene/codecs) keeps the terms of all fields of its group in one shared block, and its custom merge reads, in each old segment, only the block of the first group field it finds. When the group now holds a field that the old segment stored elsewhere (in another format, or in another SharedTermsUniformSplit instance), that field's old postings are never read. The documents stay, but searches, docFreq, deletes and updates by a term of that field miss them; there is no exception, and CheckIndex reports the index clean. It needs a mapping change on an existing index (or an addIndexes from an index with another mapping) and a field-order condition, so it is rare; it has been in every release since the format was added in 8.3.0. A small fix keeps the fast path only when all group fields of a segment share one block.
- Per-field postings. A codec can give each field its own postings format by overriding
getPostingsFormatForField(the default codec routes throughPerFieldPostingsFormat). Each segment records the format, and which instance of it (a file-group suffix), for every field, and is read back with its own record (PerFieldPostingsFormat.java:295-321). The javadoc: "The field to format mapping is written to the index, so this method is only invoked when writing, not when reading." (:379-385). - SharedTermsUniformSplit. An experimental postings format in
lucene/codecs(STUniformSplitPostingsFormat, SPI nameSharedTermsUniformSplit): "the terms of all fields are stored in the same block file" (STUniformSplitPostingsFormat.java:36). All fields that one instance writes in a segment form a group that shares one block and one dictionary. - Its custom merge. For efficiency the writer merges the source segments' shared blocks directly instead of field by field (
STUniformSplitTermsWriter.java:70-74).
- On merge,
PerFieldPostingsFormatgroups the merged segment's fields by the current mapping and gives each format a merge state restricted to its group (PerFieldPostingsFormat.java:171-191,PerFieldMergeState.java:44-72). - The restriction filters field names only: for each field it still returns the old segment's own terms, from whatever format that segment used (
PerFieldMergeState.java:246-256). One target group can therefore span several groups of an old segment. STUniformSplitTermsWriter.mergewalks each old segment's group fields in field-number order and stops at the first one with terms ("Iterate all fields only the get the first Terms instanceof STUniformSplitTerms",:295-296). If those terms are not SharedTermsUniformSplit terms, it falls back to the regular merge (:299-304). Otherwise it reads that field's shared block andbreaks (:305-313).- That block holds only the fields of one old group (
STUniformSplitTermsReader.java:109-127). Group fields the old segment stored in another format or another instance are never read, and nothing checks that every field was.
Two documents, fields a (number 0) and b (number 1). Session 1: a in SharedTermsUniformSplit, b in the default format. Session 2: both in one SharedTermsUniformSplit instance, then forceMerge(1). Before the merge every term has docFreq 1; after it, a:a1, a:a2 and b:b2 still have 1 and b:b1 has 0 (a TermQuery finds 0 hits), the index has 1 segment and 2 live documents, and CheckIndex is clean. The merged segment's field b holds only b2.
Condition: the lowest-numbered group field with terms in the old segment must itself be a SharedTermsUniformSplit field; with b numbered first the fallback runs and nothing is lost. The opposite direction (one group split in two) is safe: the merge skips block fields outside the group (:412-419).
Exposure and likelihood449 words
- Who uses the format. It is opt-in,
@lucene.experimentaland lives inlucene/codecs; it is chosen per field by a codec subclass overridinggetPostingsFormatForField(the patterncodecs/package-info.java:59-64documents) or, by code reading, by a Solr schemapostingsFormat. A 2020 dev@ mail by the committer who added it says it "is used in production at a massive scale"; no deployment was checked, and no use was found in two other common search servers. - What triggers it. An index that already stores a field in SharedTermsUniformSplit, then one of: a mapping change that moves another, higher-numbered field into that group; two SharedTermsUniformSplit instances (two groups) becoming one;
addIndexes(CodecReader...), oraddIndexes(Directory...)plus a merge, from an index written with another mapping. Then any merge of an old segment:forceMergeandaddIndexes(CodecReader...)were executed; background merges take the same merge code (read). - What does not trigger it. No mapping change; a segment written before the field existed (it has no postings of the field to lose);
addIndexesfrom an index with the same per-field grouping (by reading: each old block then holds the whole group); moving every field of a group into the format at once; the group's lowest-numbered field in the old segment not being a SharedTermsUniformSplit field; an index-sorted merge that interleaves documents (it falls back). An index-sorted index whose segments are already in order still loses postings. - What is lost. The postings of live documents for the moved field, from each old segment that stored the field outside the block the loop reads in that segment (if any old segment's first group field with terms is not a SharedTermsUniformSplit field, the whole merge falls back and nothing is lost). Stored fields and doc values stay; searches,
docFreq, filters,deleteDocuments(Term)andupdateDocument(Term, ...)by a term of that field miss those documents. The merged segment cannot give the postings back andCheckIndexreports the index clean. With the default deletion policy the old segment files are deleted at commit, so recovery means reindexing from source, or restoring a pre-merge commit that a deletion policy kept (for example a snapshot) or a backup. - No scale or timing. Two documents, with assertions on and off. The outcome does not depend on the seed: the test framework randomizes the directory and
CheckIndexsettings, and the 3 bug tests failed 30 of 30 times over 10 random-seed iterations. - How likely. Rare: mapping changes on existing indexes are infrequent, the field-order condition must hold, and no report of it since 8.3.0 (2019) was found in the searched public sources. Tests never caught it because
RandomCodecnever picks a UniformSplit format and the UniformSplit suites use one format for every field (TestUniformSplitPostingFormat.java:37).
The test shows that a SharedTermsUniformSplit merge drops the old postings of a field that an earlier segment wrote under another postings format, after a per-field mapping change puts that field into the shared-terms group.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.uniformsplit.sharedterms;

import org.apache.lucene.codecs.Codec;
import org.apache.lucene.codecs.PostingsFormat;
import org.apache.lucene.codecs.lucene104.Lucene104Codec;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestSTUniformSplitMergeMappingChange extends LuceneTestCase {

  private static Codec codec(PostingsFormat forA, PostingsFormat forB) {
    return new Lucene104Codec() {
      @Override
      public PostingsFormat getPostingsFormatForField(String field) {
        return field.equals("a") ? forA : forB;
      }
    };
  }

  private static Document doc(String a, String b) {
    Document doc = new Document();
    doc.add(new StringField("a", a, Field.Store.NO));
    doc.add(new StringField("b", b, Field.Store.NO));
    return doc;
  }

  public void testMergeTakesFieldFromAnotherFormat() throws Exception {
    PostingsFormat st = new STUniformSplitPostingsFormat();
    try (Directory dir = new ByteBuffersDirectory()) {
      Codec before = codec(st, TestUtil.getDefaultPostingsFormat());
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setCodec(before))) {
        w.addDocument(doc("a1", "b1"));
      }
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setCodec(codec(st, st)))) {
        w.addDocument(doc("a2", "b2"));
        w.forceMerge(1);
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        // b:b1 was written under the default format: expected docFreq 1 after the merge, actual 0
        assertEquals("docFreq(b:b1) after forceMerge", 1, r.docFreq(new Term("b", "b1")));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-249/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.codecs.uniformsplit.sharedterms.TestSTUniformSplitMergeMappingChange
- Expected vs actual
- Expected
docFreq(b:b1)to be 1 afterforceMerge(1); actual 0 (expected:<1> but was:<0>), with-eaand-da; the document stays but cannot be found throughb.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: docFreq(b:b1) after forceMerge expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.codecs.uniformsplit.sharedterms.TestSTUniformSplitMergeMappingChange.testMergeTakesFieldFromAnotherFormat(TestSTUniformSplitMergeMappingChange.java:65)FieldsConsumer.merge"Merges in the fields from the readers"; the custom merge is documented as a faster path, and its own fallback keeps every term.- Mappings may change: "The field to format mapping is written to the index" (no upstream test covers this transition).
- The loop's comment expects per-field use; it guards against foreign terms, but only for the first field.
The full argument283 words
- The merge contract.
FieldsConsumer.merge: "Merges in the fields from the readers inmergeState. ... Implementations can override this method for more sophisticated merging" (FieldsConsumer.java:66-71). An override may be faster, not lossy. - The custom merge is an optimization. The class javadoc: the writer "requires a custom merge ... for efficiency. The regular merge would scan all the fields sequentially ... Whereas the custom merge directly scans the internal shared-terms dictionary of all segments to merge" (
STUniformSplitTermsWriter.java:70-74). The regular merge, which the existing fallback reaches, keeps every term (control test). - Mappings may change between segments.
getPostingsFormatForField"Returns the postings format that should be used for writing new segments ... The field to format mapping is written to the index, so this method is only invoked when writing, not when reading." (PerFieldPostingsFormat.java:379-385; theLucene104Codechook warns only about back-compat,Lucene104Codec.java:170-180). Upstream tests show per-field segments as supported shapes, but not this transition:TestPerFieldPostingsFormat2.testChangeCodecAndMergecarries the comment "Test that heterogeneous index segments are merged successfully" (:126-131), although both of its writer sessions now use the same mapping, andtestSameCodecDifferentInstance(:262) treats two instances of one format as two valid groups. Neither test moves a field between formats or groups. - The code expects per-field use. The loop's comment expects
FieldInfos"filtered by PerFieldMergeState" (STUniformSplitTermsWriter.java:292-293), and the loop already falls back for foreign terms, but only looks at the first field. - No acceptance found. No test, javadoc, CHANGES or MIGRATE entry, JIRA or list thread found in the searched sources accepts the loss or says a field's postings format must not change; the feature thread calls the custom merge "the only tricky part" (#9798).
The devil's-advocate check191 words
The strongest case for "intended or unsupported": the format's javadoc says "the terms of all fields are stored in the same block file" (STUniformSplitPostingsFormat.java:36), so its merge may assume one block per old segment; the format is @lucene.experimental; and changing a field's postings format on a live index is unusual.
Why it fails: no such precondition is stated anywhere, and per-field use is expected by the loop's own comment and by the codecs package docs; the sentence describes how one segment is written, not a promise about older segments. Experimental status allows format and API changes between versions, not silent loss of live postings within one version. Nothing forbids a mapping change, the per-field javadoc records the mapping per segment because it may change, and the addIndexes path loses postings with no change inside the destination writer at all. Verdict: not intended, a defect. Every checker (the independent reproduction, the intended-behaviour check, the adjudication and the OpenAI GPT-5.6 reviews, one of them the cross-model review's) rejected the intended reading; the intended-behaviour check and the reviews, which grade it, call it weak. What survives is reach, which bounds priority.
Recommended Use the fast path only when a segment's group fields share one block (validated)
In STUniformSplitTermsWriter.merge, keep the fast path only when all group fields with terms in a segment share one shared-terms block (the same unionFieldMetadata); otherwise fall back to the regular merge (+18/-14, one file). With it the repro and the whole lucene/codecs suite (697 tests) pass.
STUniformSplitTerms segmentSharedTerms = null;
for (FieldInfo fieldInfo : mergeState.fieldInfos[segmentIndex]) {
  Terms terms = fieldsProducer.terms(fieldInfo.name);
  if (terms != null) {
    if (!(terms instanceof STUniformSplitTerms sharedTerms)
        || (segmentSharedTerms != null
            && sharedTerms.unionFieldMetadata != segmentSharedTerms.unionFieldMetadata)) {
      super.merge(mergeState, normsProducer); // another format or another block
      return;
    }
    if (segmentSharedTerms == null) segmentSharedTerms = sharedTerms;
  }
}
// then add segmentSharedTerms.createMergingBlockReader() once, as before
All options and trade-offs4 options · 591 words
One fix was built and validated in a scratch worktree of a9779ef3c193 (option A, written by the finder; an independent checker wrote an equivalent patch). The other options are untested alternatives.
In STUniformSplitTermsWriter.merge (:281-321), drop the early break: look at every group field of each segment, and fall back to the regular FieldsConsumer.merge as soon as a field's terms are not SharedTermsUniformSplit terms or belong to another shared-terms block than the segment's first such field. One shared-terms reader creates one unionFieldMetadata and hands it to every field of its block (STUniformSplitTermsReader.java:109-127), so an identity check tells blocks apart.
STUniformSplitTerms segmentSharedTerms = null;
for (FieldInfo fieldInfo : mergeState.fieldInfos[segmentIndex]) {
  Terms terms = fieldsProducer.terms(fieldInfo.name);
  if (terms != null) {
    if (!(terms instanceof STUniformSplitTerms sharedTerms)
        || (segmentSharedTerms != null
            && sharedTerms.unionFieldMetadata != segmentSharedTerms.unionFieldMetadata)) {
      super.merge(mergeState, normsProducer); // another format or another block
      return;
    }
    if (segmentSharedTerms == null) segmentSharedTerms = sharedTerms;
  }
}
// then add segmentSharedTerms.createMergingBlockReader() once, as before
Trade-offs
- One mixed old segment sends the whole merge (every segment and every group field) through the regular merge, which the class javadoc calls slower for many fields (it scans the shared dictionary once per field). The merged segment holds the group in one block, so merges take the fast path again once no old mixed segment is left in them and the mapping does not change again.
- Merges without a mapping change keep the fast path; the loop now visits every group field of a segment instead of stopping at the first. Not benchmarked.
- Open PR #16851 edits other methods of the same file; a fix PR may need a rebase.
What the checks validated
- Gradle,
-Ptests.seed=DEADBEEF: the new test 4/4 with assertions on and off, 40/40 over 10 random-seed iterations; the closest suitesorg.apache.lucene.codecs.uniformsplit.*(8 classes with the new test) 86 tests, 0 failures, 4 skipped, assertions on and off (stock: the same 86 with the new test's 3 failures). - The hunt's other JUnit repros (the finder's, the independent reproduction's, the cross-model review's and the intended-behaviour check's, 17 tests) 0 failures; the whole
:lucene:codecs:testsuite with the new test: 697 tests, 0 failures (78 skipped);:lucene:codecs:check -x test(google-java-format, ecjLint, forbiddenApis, license checks) passes;tidyleaves the patch unchanged. - Repro harness on
a9779ef3c193with the fix shadowed: the new test 4/0 with-eaand-da. Earlier, onea57360912ed: the 729-pair check went from 176 lossy pairs to 0 (that run's JUnit still reports a failure, on purpose: its predictor encodes the stock defect and still predicts the 176), and the fail-open probe passes 3/3.
Add one merging block reader per distinct unionFieldMetadata in the segment, and fall back only for terms of another format.
Trade-offs
Keeps the fast path when two shared-terms groups become one. Needs a check that the merge handles two block readers of one segment (their fields are disjoint). Not run.
Skip the custom merge whenever the merge state is restricted by PerFieldMergeState.
Trade-offs
Simplest, but the format is normally reached through PerFieldPostingsFormat, so this removes the fast path the class javadoc justifies. Not recommended; not run.
Never hand a delegate a group whose fields span several groups of one source segment.
Trade-offs
Larger, and it changes every per-field format's merge for the only postings consumer besides PerFieldPostingsFormat that overrides merge. Not run.
Downstream relevance: deletes, updates and MUST_NOT exclusions by a term of the affected field also miss the old segments' documents (executed), so an application that keys deletions or access exclusions on such a field could show deleted or excluded documents; only the application's own codec configuration or addIndexes call can set this up.
Semi-formal. An AI tool reviewing how per-field postings formats merge suspected the SharedTermsUniformSplit loop. A bounded-exhaustive harness on the real IndexWriter then tried all 729 mapping pairs of 3 fields over two writer sessions: 176 lose postings, all predicted by the root cause, and none with the fix. No model checker or proof.
The method in full195 words
Method: code reading, then bounded-exhaustive translation validation (the hunt's "semi-formal" tier: a hypothesis formed while modelling and witnessed by a tool; no model checker, SMT solver or prover).
- The hunting AI tool of the hunt's unit on per-field formats was building a per-field routing harness and read which postings writers override
FieldsConsumer.mergeand how they read the restricted merge state. The SharedTermsUniformSplit loop that takes the first field andbreaks stood out. - The harness ran the real
IndexWriterand codecs on the stock main jars: fields f0 to f2, each mapped to one of {two SharedTermsUniformSplit instances, the default format} in each of two writer sessions, one document per session, all 27 x 27 = 729 mapping pairs. Oracle: every term of both documents hasdocFreq1 afterforceMerge(1). - Result: 176 of 729 pairs lose postings; a predictor written from the root cause gives the exact lost-field set in 729 of 729; with the fix 0 of 729 lose postings. A separate probe showed the loss is silent (
CheckIndexclean, stored fields and doc values intact). - Then a deterministic public-API JUnit; independent checkers reproduced it with their own tests (section "Independent checks").
No prior report found (2026-10-26): four automated search runs (about 130 queries over GitHub, JIRA, four mailing lists and downstream projects), 48 manual GitHub searches, web searches and all 413 open PRs. Closest: LUCENE-8753, which added the format and calls its merge "the only tricky part".
Searches5 searches
Verdict new: no report or discussion of this bug by anyone was found in the searched public sources. The closest items are the feature itself and general cautions, not reports of this defect.
| Where | When | How | Found |
|---|---|---|---|
| Automated search tool, three variants plus the finder's run | 2026-10-26 | about 130 queries: identifiers (STUniformSplit*, STMergingBlockReader, createMergingBlockReader, unionFieldMetadata, SharedTermsUniformSplit), triggers and symptoms (PerFieldMergeState, mapping change, addIndexes, terms missing after merge), the LUCENE-8753 family, over GitHub issues, PRs and commits, dev@, java-user@, issues@, commits@, JIRA and downstream repositories | no report; 0 high-relevance hits, every medium hit triaged |
| GitHub (manual, GraphQL) | 2026-10-26 | 48 queries over apache/lucene, apache/lucene-solr, all of GitHub and three downstream projects; the changed files of all 413 open apache/lucene PRs | no report; open PRs #16851 (same file, other methods) and #16890 (PerFieldMergeState lookup speed) do not change which fields the merge reads |
| Related threads (read in full) | 2026-10-26 | #9798 / LUCENE-8753 and lucene-solr #828, #676, #633 with their review threads; #8508 / LUCENE-7456; #13208; PR #432 / LUCENE-10228; the java-user@ 2021-04-19 and dev@ 2020-11-17 threads | context only: "the only tricky part" (LUCENE-8753), a general warning about "sneaky future bugs" (LUCENE-7456), the vectors per-field suffix precedent (LUCENE-10228) |
| JIRA, mailing lists, web | 2026-10-26 | manual JQL and lists.apache.org queries (UniformSplit, SharedTerms, PerFieldMergeState); 7 web queries | no report |
| Gaps | - | GitHub's search rate limit was saturated, so free-form searches went through GraphQL | private trackers and private security reports are not visible |
Introduced in 8.3.0 with the format itself (LUCENE-8753, b963b7c3dbe, 2019): 8.2.0 has no such format, and every executed release from 8.3.0 to 10.5.2 and main fails. The merge loop is unchanged since, apart from a reformat. Not fixed upstream.
Versions tested7 rows
Introduced by LUCENE-8753, committed as "New UniformSplit and SharedTermsUniformSplit PostingsFormats" (now #9798; PR apache/lucene-solr#828, which absorbed #676; committed by @dsmiley): b963b7c3dbe on the main line and b8a1857b0bd on branch_8x, both 2019-09-06, first released in 8.3.0 (2019-11-02). The commit created the format and the "first Terms, then break" loop, so the defect is as old as the format; not a regression.
Since then git log -L on the merge method lists only the LUCENE-9570 reformat (7f8b7ffbcad, 2021). PerFieldMergeState dates from LUCENE-7456 (2016); its rework #13208 neither introduced nor fixed this (the repro fails before and after). Not fixed on main or branch_10x; 10.6.0 (released 2026-10-29) was not checked.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 3 of 4 fail (gradle and harness, assertions on and off; the 3 bug tests 30 of 30 over random seeds) |
| 10.5.2 | affected | this doc's test 3 of 4 fail (-ea and -da); the finder's test 3 of 3 (-ea and -da) |
main ea57360912ed | affected | the finder's test 3 of 3 and the independent reproduction's 3 of 5 (controls pass), -ea and -da |
| 8.3.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 | affected | the finder's JUnit (era-adapted before 9.1) fails 3 of 3; 8.3.0 also with -da |
| 8.2.0 | no format | the format does not exist (the repro does not compile); the BlockTreeOrds control passes 3 of 3 |
| BlockTreeOrds (8.2.0, main), UniformSplit (8.3.0, main) | control | the same three scenarios with these formats pass 3 of 3: only the shared-terms custom merge loses postings |
fix on a9779ef3c193 | not affected | this doc's test 4 of 4; lucene/codecs 697 tests, 0 failures |
An independent reproducer, a devil's-advocate checker, an adjudication and an audit confirmed it with their own runs; OpenAI GPT-5.6 reviews (reading only) agreed on the root cause and rated the intended reading weak. This doc re-ran it on a9779ef3c193 with a new 4-test JUnit and validated the fix.
Checks and verdicts397 words
Each checker took a lens and ran its own tests where it could; the cross-model reviewers could read but not run Java.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | 729-pair check: 176 lossy, the root-cause predictor agrees 729/729, 0 with the fix; JUnit fails 3/3 on main (-ea, -da), 10.5.2, 9.12.3, 8.11.4 and 8.3.0; silent-loss probe: CheckIndex clean, docCount(b)=1. |
| review, intended-behavior lens (OpenAI GPT-5.6, reading only) | real, medium | Intended reading weak, root cause agrees. It could not run Java; a separate run re-ran the finder's repro alongside it (3 of 3 fail). |
| review, refute prompt (OpenAI GPT-5.6, reading only) | real, high | Trigger legal, root cause agrees, fix plausible, intended reading weak. Its corrections: the title overstated the field search and the silence of the loss was not yet shown; the title was reworded and a silence check was added. It also called the score high; the score was kept at the rubric value, with the opt-in deduction and the rarity stated in the reach. |
| Independent reproducer | real | Own 5-test JUnit fails 3/5 on main (-ea, -da), 10.5.2 and 9.12.3, every iteration of a second seed; both controls pass (no mapping change; b numbered first); its own patch passes 5/5. |
| Root-cause lens (OpenAI GPT-5.6, reading only) and separate tests | real, medium | Root cause agrees, inputs in contract. Separate tests confirm the field-order condition, and refute the side claim that index-sorted merges always fall back (already-sorted segments still lose b:b1); addIndexes(Directory) plus forceMerge loses it too. With the fix all pass, and TestSTUniformSplitPostingFormat 28/28. |
| Devil's advocate | real | Reproduced it through a Lucene104Codec subclass with the format resolved by its SPI name (2 of 3 fail, the control passes); rebutted the one-block, experimental and do-not-change-formats readings. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test (3/5, -ea and -da, fresh seed), the finder's (3/3) and the independent reproduction's with the finder's fix (5/5); class data corruption; advised stating the narrow reach and the field-order condition. |
| Security re-evaluation | not security-sensitive | Checkers (2026-10-27): trusted configuration, and untrusted queries or documents cannot trigger it. The executed fail-open probe stays as a downstream note. |
| This doc | reproduced, fix validated | New 4-test JUnit on a9779ef3c193: 3/4 fail with gradle and the harness, -ea and -da, and on 10.5.2; the fix passes it, the uniformsplit suites and lucene/codecs (697 tests). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 499 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,384 words
- Registry title
- SharedTermsUniformSplit merges silently drop the postings of fields that a source segment stored under another postings format or another shared-terms group (after a per-field postings mapping change, or addIndexes from an index with another mapping), because STUniformSplitTermsWriter.merge reads only the shared-terms block of the first field with terms in each source segment
- Area
- codecs / SharedTermsUniformSplit postings format (STUniformSplitTermsWriter.merge under PerFieldPostingsFormat and PerFieldMergeState)
- Priority
- Medium, rank 158: Merges of the experimental SharedTermsUniformSplit format silently drop whole fields' postings after a per-field mapping change.
- Impact class
- data corruption
- Impact note
- Applications that index a group of fields with the experimental, non-default SharedTermsUniformSplit postings format (STUniformSplitPostingsFormat in lucene/codecs, chosen per field through a per-field codec or, by code reading, a Solr schema postingsFormat) on any release from 8.3.0 through 10.5.2 or on main, and that change the per-field postings mapping of an existing index so that a SharedTermsUniformSplit group takes a field which older segments stored under another format or another SharedTermsUniformSplit instance (or that call addIndexes with an index written under another mapping), permanently lose that field's postings from the older segments at the next merge (executed: forceMerge, addIndexes(CodecReader...), and forceMerge after addIndexes(Directory...); natural merges take the same SegmentMerger path [read]) whenever the group's first field, by field number, with terms in the older segment is itself a SharedTermsUniformSplit field: the documents stay, but TermQuery hits, docFreq, deletes and updates by a term of that field miss them, with no exception, after commit and with CheckIndex reporting the index clean; no scale or concurrency is needed, an index sort protects only merges that interleave documents, and the lost postings cannot be recovered from the merged segment (reindex from source).
- Summary
- You index fields a and b with a per-field codec, a in SharedTermsUniformSplit and b in the default postings format, then open a new writer whose codec maps both a and b to one SharedTermsUniformSplit instance (PerFieldPostingsFormat records the mapping per segment, and merging segments written under different mappings is supported), add a document and force-merge. You expect every term to be found after the merge, as with any other postings format. Instead the merge reads only a's shared-terms block from the old segment, so b's old postings are never copied: docFreq(b:b1) is 0 instead of 1, the document stays in the index but cannot be found through b, and CheckIndex reports the index clean.
- Introduced
- b963b7c3dbecda86c2917ad341caee63b93815ac (LUCENE-8753 'New UniformSplit and SharedTermsUniformSplit PostingsFormats', committed by dsmiley; CHANGES.txt credits Bruno Roustant, Juan Rodriguez and David Smiley; apache/lucene-solr#828 per the issue thread, which absorbed #676; the JIRA issue is now apache/lucene#9798) and its branch_8x cherry-pick b8a1857b0bd235bc9d4833276b1e60c9865aa04b (the commit 8.3.0 contains) [read: git log -L on STUniformSplitTermsWriter.merge lists only b963b7c3dbe and the LUCENE-9570 reformat 7f8b7ffbcad; the file does not exist in the parent of either commit] [exec: 8.2.0 lacks the format, so the repro does not compile there, and a BlockTreeOrds control passes 3 of 3 on 8.2.0; 8.3.0 fails 3 of 3]: the commit created the format and its custom merge with the 'first Terms, then break' loop, so the defect is as old as the format and not a regression; PerFieldMergeState dates from LUCENE-7456 (796ed508f39, 2016) and its rework #13208 neither introduced nor fixed it (the repro fails before and after) (2019-09-06 (b963b7c3dbe and the branch_8x cherry-pick b8a1857b0bd, same day))
- First affected version
- 8.3.0 [exec] (tag 2019-10-24, the first release with SharedTermsUniformSplit; 8.2.0 has no uniformsplit classes [exec: the repro does not compile]); main line 9.0.0 [exec]
- Affected versions
- every release from 8.3.0 to 10.5.2 (the last before 10.6.0) and main ea57360912ed [exec: the finder's JUnit fails 3 of 3 on 8.3.0 (-ea and -da), 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da); the independent reproduction's JUnit fails 3 of 5 on main, 10.5.2 and 9.12.3 with both controls passing; the same three scenarios with BlockTreeOrds or the non-shared UniformSplit format pass 3 of 3 on 8.2.0, 8.3.0 and main] [read: with whitespace removed the merge loop is identical at b963b7c3dbe, b8a1857b0bd, 8.3.0, 8.8.1, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and the history head; the 8.9 to 8.11 tags are not in the history clone]; not a regression; not fixed upstream (the loop is unchanged on main and branch_10x and no open PR changes it, read-only check 2026-10-26); 10.6.0 (released 2026-10-29) was not checked; executed on aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-26, read-only; follow-up prior-report record verdict new): scripted prior-report search three times (v1: 16 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list queries over dev@, java-user@, issues@ and commits@, 4 JIRA; v2 and v3: 20 list and 4 JIRA queries each) plus the finder's earlier run (43 queries); 48 manual GitHub GraphQL searches over apache/lucene, apache/lucene-solr and all of GitHub; 6 downstream searches (Elasticsearch, OpenSearch, Solr GitHub, JIRA and lists); manual JIRA JQL and lists.apache.org queries; 7 manual web searches; the changed-file lists of all 413 open apache/lucene PRs; the git history of the merge loop; and the independent reproduction's and the intended-behaviour check's own searches. Nearest items, none a report of this bug: LUCENE-8753 / #9798 and apache/lucene-solr#828 (introduced the format; its author called the custom merge 'the only tricky part'), LUCENE-7456 / #8508 (2016, introduced PerFieldMergeState, with a general warning about 'sneaky future bugs for codecs that rely on this'), the open PR #16851 (touches STUniformSplitTermsWriter.java, but only createFieldTermsQueue and createSegmentTermsQueue) and the open PR #16890 (PerFieldMergeState lookup performance). Not fixed upstream: the loop is unchanged since b963b7c3dbe apart from reformatting, on main and branch_10x, and no open PR changes it. Gaps: GitHub's search rate limit was saturated, so free-form searches went through GraphQL; private trackers of users of the format, forums outside the searched indexes and private reports to security@lucene.apache.org are not visible.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): this doc's 4-test JUnit through gradle in a scratch worktree (assertions on and off, 10 random-seed iterations) and through the hunt repro harness; the 10.5.2 release jars; the fix with the uniformsplit suites, the hunt's other repros and the whole lucene/codecs suite. The verifiers, the history sweep (8.2.0 to 10.5.2) and the security probe ran on mainea57360912ed; none of the 7 commits in between touches the files involved.
- Finding record
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitTermsWriter.java:70-74 (class javadoc: the custom merge exists 'for efficiency'), :281-321 (merge: needsIndexSort fallback :282-287, PerFieldMergeState comment :292-293, 'first Terms' comment :295-296, fallback check :299-304, one block then break :305-313), :412-419 (block fields absent from the target group are skipped)lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitPostingsFormat.java:36 ('the terms of all fields are stored in the same block file'), :41 (@lucene.experimental), :53 (SPI name SharedTermsUniformSplit); STUniformSplitTermsReader.java:110-124 (one unionFieldMetadata per reader, shared by all its fields)lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldMergeState.java:44-72 (restrictFields filters field names only), :246-256 (FilterFieldsProducer.terms delegates to the source segment's producer); PerFieldPostingsFormat.java:379-385 (getPostingsFormatForField javadoc); codecs/FieldsConsumer.java:66-71 (merge javadoc) and :72-95 (default merge over all source producers)lucene/core/src/test/org/apache/lucene/codecs/perfield/TestPerFieldPostingsFormat2.java:127-131 (testChangeCodecAndMerge, 'heterogeneous index segments are merged successfully') and :262 (testSameCodecDifferentInstance)
- The finding in 30 seconds
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitTermsWriter.java:70-74, 281-321 (fallbacks :282-287, :299-304; comments :292-293, :295-296; block reader and break :305-313), 412-419lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitTermsReader.java:109-127; STUniformSplitPostingsFormat.java:36, 41, 53lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldPostingsFormat.java:171-191, 199-260, 295-321, 336-339, 379-385; PerFieldMergeState.java:44-72, 93-114, 146-148, 246-256
- Who is affected
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitPostingsFormat.java:41, 53; lucene/core/src/java/org/apache/lucene/codecs/package-info.java:59-64lucene/codecs/src/test/org/apache/lucene/codecs/uniformsplit/TestUniformSplitPostingFormat.java:37; RandomCodec (lucene/test-framework) lists no UniformSplit formatlucene/core/src/java/org/apache/lucene/index/IndexDeletionPolicy.java:26-30 (the default policy removes old commits at each commit); SnapshotDeletionPolicy.java:28-31, 134-136 (a held snapshot keeps its files, also across forceMerge)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/FieldsConsumer.java:66-71, 72-95lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitTermsWriter.java:70-74, 292-293, 299-304; STUniformSplitPostingsFormat.java:36, 41lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldPostingsFormat.java:379-385; lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java:170-180lucene/core/src/test/org/apache/lucene/codecs/perfield/TestPerFieldPostingsFormat2.java:127-131, 262lucene/core/src/test/org/apache/lucene/codecs/perfield/TestPerFieldPostingsFormat2.java:131-225 (testChangeCodecAndMerge uses one MockCodec mapping in both sessions)
- Suggested fix
lucene/codecs/src/java/org/apache/lucene/codecs/uniformsplit/sharedterms/STUniformSplitTermsWriter.java:70-74, 281-321; STUniformSplitTermsReader.java:109-127
- History
dev-tools/doap/lucene.rdf:458-459 (lucene-8.3.0 created 2019-11-02)
- TestSTUniformSplitMergeMappingChange.java (JUnit test):
repro/LFV-249/src/org/apache/lucene/codecs/uniformsplit/sharedterms/TestSTUniformSplitMergeMappingChange.java(69 lines)
Drawn from a segment-level tracing probe of the repro's first scenario on main a9779ef3c193; made in parallel with this doc.
assets/LFV-249/bug.png(499 KB)