Top-k search skips documents that cannot beat the current k-th hit, using each clause's maximum possible score. CombinedFieldQuery computes that maximum from an infinite term frequency, which AxiomaticF2LOG and AxiomaticF2EXP turn into NaN. The pruning code then treats the query as never good enough on its own.
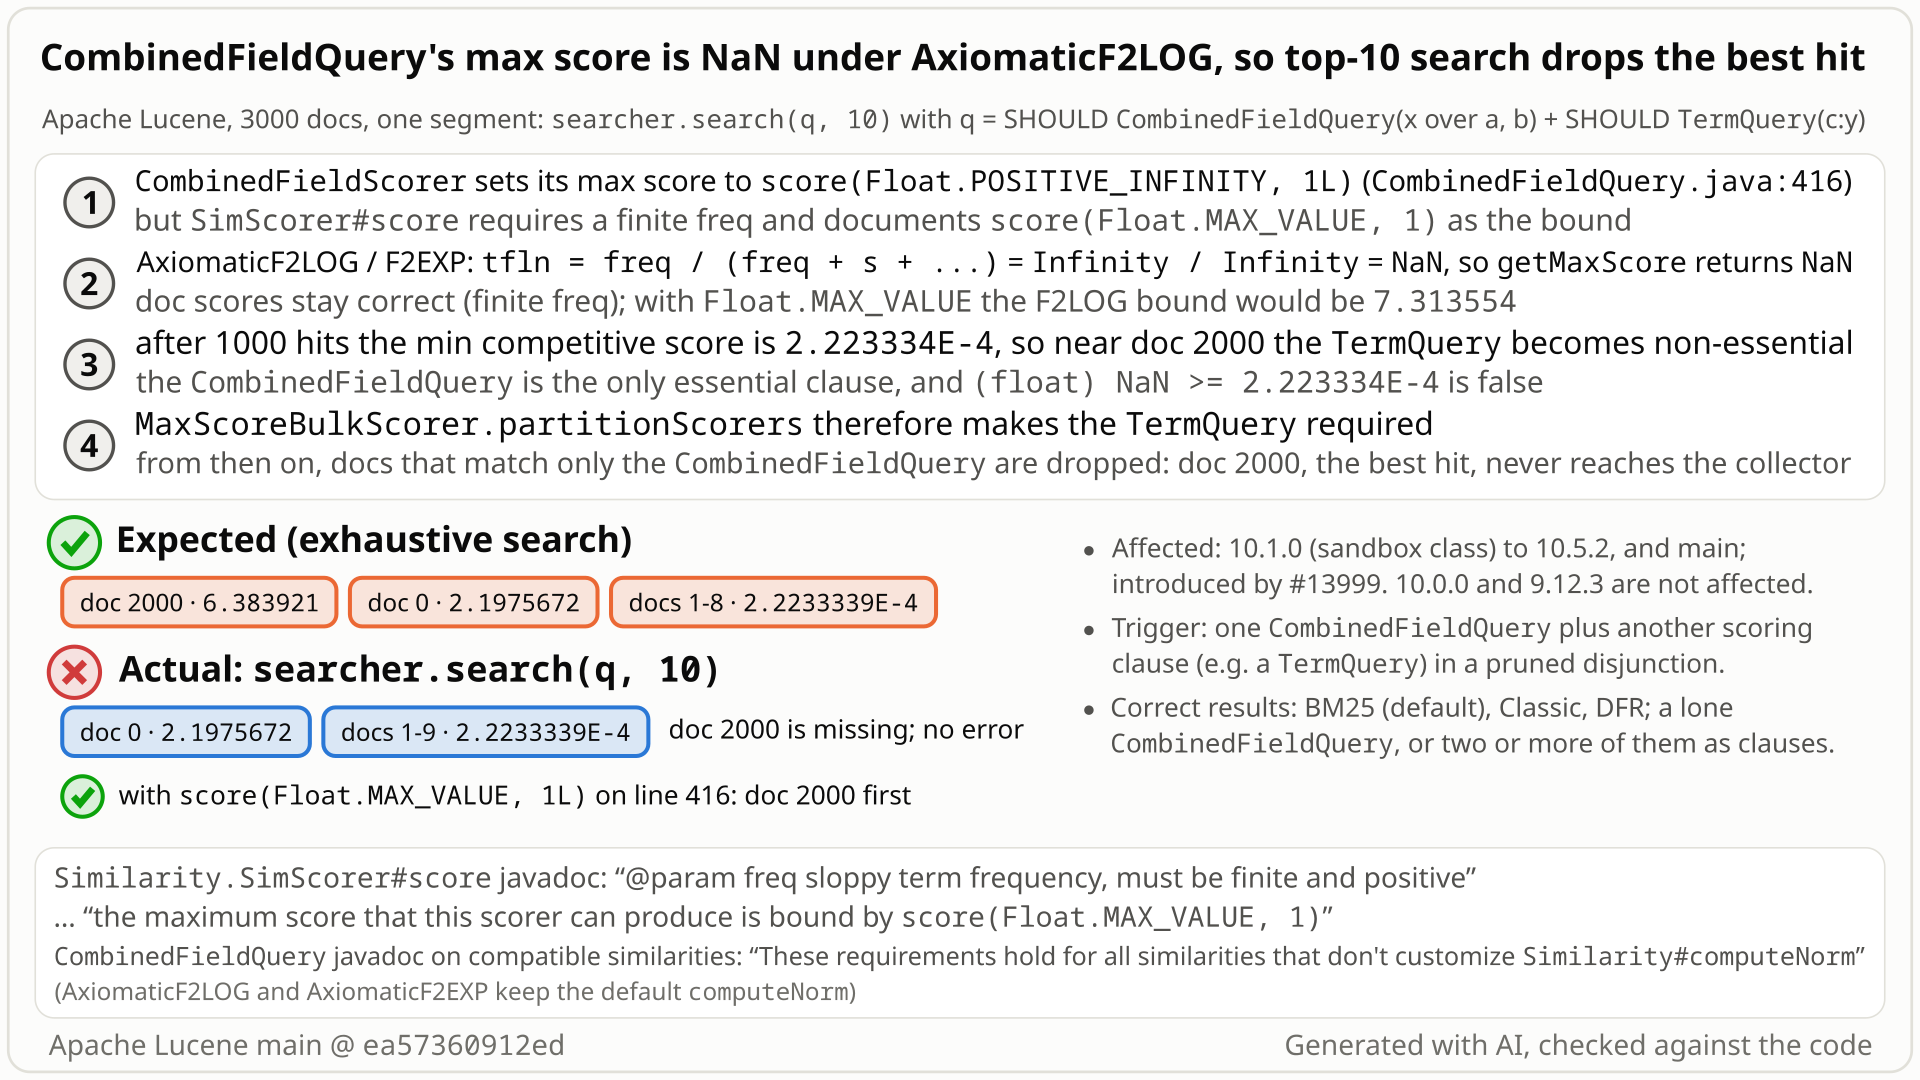
c:y required, and doc 2000 (6.383921), which has no c:y, never reaches the collector. Select the still to open it at full size. Generated with AI, checked against the code.- Index 3,000 documents with AxiomaticF2LOG. Doc 2000 has the word
xfour times in short fieldsaandb, doc 0 once in long fields, and the other 2,998 documents onlyc:y. SearchSHOULD CombinedFieldQuery(x on a, b)+SHOULD TermQuery(c:y)withsearcher.search(q, 10). - You expect doc 2000 first: the exhaustive search scores it 6.383921, doc 0 2.1975672 and every
c:ydocument 0.00022. You get doc 0 first, then ninec:ydocuments; doc 2000 is not in the top 10. No error. - Why: to let top-k skip documents, CombinedFieldQuery reports its maximum score as the score of a term that occurs infinitely often,
score(+Infinity, 1). The similarity API forbids an infinite frequency; these two similarities computefreq / (freq + ...), and Infinity / Infinity is NaN. - After 1,000 hits the collector only accepts scores above the
c:yscore, 0.00022233339. The pruning scorer asks whether the CombinedFieldQuery alone can still beat that:NaN >= 0.0002223334is false. So from then on it makesc:yrequired and skips the documents that have onlyx, including doc 2000. - Fix: use
score(Float.MAX_VALUE, 1), the bound the API documents (7.31 on this index). One line in each copy of the class; the test and the 2,336 tests of the search package pass.
Applications that build a CombinedFieldQuery in code and score with AxiomaticF2LOG or AxiomaticF2EXP, on 10.1.0 to 10.6.0 (10.6.0 by reading) or main, when exactly one CombinedFieldQuery sits next to another scoring clause, such as a TermQuery or a FeatureField boost. Plain search(q, n) on 3,000 documents is enough, once 1,000 hits are passed. BM25, a lone CombinedFieldQuery and one-per-term disjunctions are fine.
Mechanism, terms and numbers761 words
CombinedFieldQuery's scorer reports simScorer.score(Float.POSITIVE_INFINITY, 1) as the highest score it can produce (CombinedFieldQuery.java:416). SimScorer#score requires a finite, positive freq and documents score(Float.MAX_VALUE, 1) as the bound. For the core similarities AxiomaticF2LOG and AxiomaticF2EXP, which the class javadoc counts as compatible, the infinite freq gives Infinity / Infinity = NaN, so getMaxScore returns NaN. When such a query is one SHOULD clause next to another scoring clause, MaxScoreBulkScorer reads the NaN as "this clause alone can never reach the minimum competitive score", makes the other clause required, and skips every document that matches only the CombinedFieldQuery. On 3,000 documents IndexSearcher#search(q, 10) returns doc 0 (2.1975672) first while the exhaustive search ranks doc 2000 (6.383921) first, and Lucene's own oracle CheckHits.checkTopScores fails. Returned scores are correct and nothing throws with assertions off. Introduced by #13999 (10.1.0, then in the sandbox module); every release from 10.1.0 to 10.6.0 (10.6.0 by reading) and main is affected; the fix is to pass Float.MAX_VALUE, as MaxScoreCache does. No upstream report was found.
- CombinedFieldQuery (BM25F): scores a term over several fields as if they were one combined field, with the searcher's similarity.
@lucene.experimental, in core since 10.2.0 (a sandbox class in 10.1.0). - Max score:
Scorer#getMaxScore(upTo)is "the maximum score that documents between the last target ... and upTo" can get (Scorer.java:75-79). Top-k scorers use it to skip documents. - Minimum competitive score: once
IndexSearcher#search(q, n)has counted more than 1,000 hits (IndexSearcher.java:100), the collector tells the scorer to skip documents scoring belowMath.nextUpof the n-th best score so far (TopScoreDocCollector.java:154-164). - Essential and required clauses (MAXSCORE): clauses whose summed max scores stay below the minimum are non-essential; a competitive document must match an essential clause. With a single essential clause, if the others cannot add enough, the best non-essential clause becomes required.
CombinedFieldScorersetsthis.maxScore = simScorer.getSimScorer().score(Float.POSITIVE_INFINITY, 1L);(CombinedFieldQuery.java:416) and returns it fromgetMaxScorefor everyupTo(:446-448). Documents are scored with their real, finite freq, so returned scores are right.- AxiomaticF2LOG and AxiomaticF2EXP compute
tfln = freq / (freq + s + s * docLen / avgFieldLength)(AxiomaticF2LOG.java:62,AxiomaticF2EXP.java:72): Infinity / Infinity = NaN, andMath.max(0, NaN)stays NaN (Axiomatic.java:107-116). - A TOP_SCORES disjunction of 2 or more SHOULD clauses with
minimumShouldMatch <= 1runs onMaxScoreBulkScorer(BooleanScorerSupplier.java:308-328), and so does one with FILTER clauses andminimumShouldMatchexactly 1 (:233,:345,:364). With FILTER clauses andminimumShouldMatch0 it runs onReqOptSumScorer(:176); the security probe found that shape wrong too (mechanism not traced). partitionScorersmakes a clause non-essential only while(float) sumUpperBound(sum, n) < minCompetitiveScore(MaxScoreBulkScorer.java:500-502). A sum with NaN is never less, so the CombinedFieldQuery stays essential; in the window of doc 2000 the TermQuery's max score, 0.00022233339 (from the block impacts), is below the minimum, so there it becomes non-essential. Its bound over the whole segment, 0.0003335001, is above the minimum, and from doc 2818 on it is essential again.- With a single essential clause the loop tests
(float) maxPossibleScoreWithoutPreviousClause >= scorable.minCompetitiveScore(:540). For NaN that is false, so the TermQuery becomes required and, in those windows, documents that match only the CombinedFieldQuery are skipped.
| quantity | value |
|---|---|
getMaxScore of the CombinedFieldQuery | NaN (TermQuery c:y: 0.0003335001 over the segment, 0.00022233339 in the window of doc 2000) |
score of every c:y-only document | 0.00022233339 |
| minimum competitive score after 1,001 hits (doc 1000) | 0.0002223334 |
| partition in the window that holds doc 2000 (range trace: the same bulk scorer called on the doc range [2000, 2001)) | CombinedFieldQuery essential (NaN), TermQuery non-essential and REQUIRED; 0 documents collected |
| exhaustive top 10 | doc 2000 (6.383921), doc 0 (2.1975672), docs 1-8 |
search(q, 10) | doc 0 (2.1975672), docs 1-9; 1207+ hits counted |
score(Float.MAX_VALUE, 1), the fixed bound | 7.313554 |
Doc 0 is returned only because it is the first document, collected before pruning starts. AxiomaticF2EXP behaves the same: doc 0 (3.8859417) instead of doc 2000 (11.288641); fixed bound 12.932503.
A lone CombinedFieldQuery (it uses its own bulk scorer, CombinedFieldQuery.java:397); two or more CombinedFieldQuery clauses, one per term as in the search package docs (all NaN and all essential, so no CombinedFieldQuery hit is lost; a third clause with a finite bound can still be pruned); a CombinedFieldQuery as a FILTER or MUST_NOT clause (scored with COMPLETE_NO_SCORES, BooleanWeight.java:57-59); a DisjunctionMaxQuery parent (it collected every match: pruning off). All executed.
Exposure and likelihood368 words
- Who is exposed. Applications that build a
CombinedFieldQueryin code (no stock Lucene query parser creates one) and score with AxiomaticF2LOG or AxiomaticF2EXP, on 10.1.0 (sandbox class), 10.2.0 to 10.5.2, or main. The open PR #14262 would makeQueryBuilderbuild CombinedFieldQuery instances without touching the max-score line, so if merged more applications could reach this (not tested). - Which queries. In every executed wrong case exactly one CombinedFieldQuery was among the scoring clauses of a pruned query, next to another scoring clause. That is necessary, not sufficient: hits are lost only where the other clauses' window max score falls below the minimum competitive score, and a
DisjunctionMaxQueryparent or aminimumShouldMatch=2disjunction returned correct hits with-da. Executed wrong: one CombinedFieldQuery as a SHOULD clause next to aTermQueryor aFeatureFieldquery, also with FILTER or MUST_NOT clauses or nested in a MUST conjunction (the security probe: 7 of its 11 shapes gave a wrong top hit with a total-hits threshold of 1). Executed correct: a lone CombinedFieldQuery, one per term (2 or more clauses), a FILTER CombinedFieldQuery, a plain conjunction, aDisjunctionMaxQuery, aminimumShouldMatch=2disjunction (-da). - Default or opt-in. Opt-in on both sides: the default BM25 gives a finite bound, and CombinedFieldQuery is
@lucene.experimental. Nothing else is special: default codec, plainIndexSearcher,IndexSearcher#search(q, n). - Scale. No large index is needed: 3,000 documents with the default API, which must count more than 1,000 hits before pruning starts (the lost document comes after that); 301 with a total-hits threshold of 1. Single- and multi-segment indexes fail the same way under AxiomaticF2LOG (AxiomaticF2EXP ran on one segment only).
- What you see. The wrong best hits, correct scores for what is returned, no exception with assertions off. With assertions on, a
minimumShouldMatch=2disjunction tripsassert Float.isNaN(maxScore) == falseinWANDScorer(WANDScorer.java:91); with-dathat shape only loses pruning. - Downstream (code reading only): Elasticsearch's
combined_fieldsquery rejects every similarity but BM25; OpenSearch's has no similarity check, but no Axiomatic similarity was found in stock OpenSearch; Solr does not use the query. - How likely. Plausible (registry likelihood): the pairing is rare, but once chosen the failure is deterministic with ordinary data. Registry priority: Medium.
The test shows that CombinedFieldQuery under AxiomaticF2LOG reports a NaN max score (score(+Infinity, 1)), so top-k pruning in a SHOULD CombinedFieldQuery + SHOULD TermQuery disjunction skips the best hit.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.similarities.AxiomaticF2LOG;
import org.apache.lucene.search.similarities.Similarity;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestCombinedFieldQueryNaNMaxScore extends LuceneTestCase {

  public void testPrunedTopHit() throws Exception {
    Similarity sim = new AxiomaticF2LOG();
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setSimilarity(sim).setCodec(TestUtil.getDefaultCodec());
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        for (int i = 0; i < 256; i++) {
          Document doc = new Document();
          doc.add(new TextField("c", "y", Field.Store.NO));
          if (i == 0) {
            doc.add(new TextField("a", "x", Field.Store.NO));
          }
          w.addDocument(doc);
        }
        Document best = new Document();
        best.add(new TextField("a", "x x x", Field.Store.NO));
        w.addDocument(best);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        searcher.setSimilarity(sim);
        Query query =
            new BooleanQuery.Builder()
                .add(
                    new CombinedFieldQuery.Builder("x").addField("a").build(),
                    BooleanClause.Occur.SHOULD)
                .add(new TermQuery(new Term("c", "y")), BooleanClause.Occur.SHOULD)
                .build();
        TopDocs exhaustive =
            searcher.search(query, new TopScoreDocCollectorManager(1, Integer.MAX_VALUE));
        TopDocs pruned = searcher.search(query, new TopScoreDocCollectorManager(1, 1));
        // expected: pruning keeps the top hit (doc 256, a:x only); actual: doc 0, getMaxScore is NaN
        assertEquals(
            "top hit with pruning", exhaustive.scoreDocs[0].doc, pruned.scoreDocs[0].doc);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-253/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestCombinedFieldQueryNaNMaxScore
- Expected vs actual
- Expected the pruned search (
TopScoreDocCollectorManager(1, 1)) to return the exhaustive top hit, doc 256; actual: doc 0 (top hit with pruning expected:<256> but was:<0>), with-eaand-da.
More files, environment, full output37 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: top hit with pruning expected:<256> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.search.TestCombinedFieldQueryNaNMaxScore.testPrunedTopHit(TestCombinedFieldQueryNaNMaxScore.java:67)SimScorer#scorerequires a freq that is "finite and positive" and namesscore(Float.MAX_VALUE, 1)as the bound; every other max-score computation uses it.- The class javadoc counts Axiomatic as compatible (default
computeNorm); the change that added the line promised "non-infinite maximum scores". AssertingSimilarityasserts a finite freq, and trips on this line even with BM25.
The full argument253 words
The contract, in its own words (at ea57360912ed):
SimScorer#score(Similarity.java:201-221): "freqis the document-term sloppy frequency and must be finite and positive"; "the maximum score that this scorer can produce is bound byscore(Float.MAX_VALUE, 1)".MaxScoreCache.java:48, the sandboxTermAutomatonScorer.java:364andBaseSimilarityTestCase.java:382all useFloat.MAX_VALUE.Scorer#getMaxScore(Scorer.java:75-79) returns "the maximum score" of the documents in range; NaN is not a maximum of finite scores.CombinedFieldQueryjavadoc (CombinedFieldQuery.java:60-64): compatibility requires additive norms, which "hold for all similarities that don't customizeSimilarity#computeNorm"; Axiomatic extendsSimilarityBaseand keeps it. The query "allows other similarities besides BM25Similarity" (:72-75).- CHANGES for #13999 (
lucene/CHANGES.txt:2087-2088): "CombinedFieldQuery now returns non-infinite maximum scores, making it eligible to dynamic pruning."
Tests. AssertingSimilarity asserts Float.isFinite(freq) (AssertingSimilarity.java:76-77); a probe that wraps the default BM25 in it fails at CombinedFieldQuery.java:416 on every scored search. BaseSimilarityTestCase asserts that score(Float.MAX_VALUE, 1) is not NaN and bounds the score for every core similarity, F2LOG and F2EXP included (BaseSimilarityTestCase.java:382-391), and RandomSimilarity rotates both into random tests (RandomSimilarity.java:126-127).
Why the tests miss it. #13999 added no test, and TestCombinedFieldQuery.randomCompatibleSimilarity() picks only BM25, Boolean, Classic, LMDirichlet and LMJelinekMercer (TestCombinedFieldQuery.java:392-401); for those score(+Infinity, 1) is finite or +Infinity, never NaN.
History. #13999's description: "returning the maximum score that the sim scorer can return, which in the case of BM25 is bounded by the IDF". Its discussion covers a benchmark and a slowdown; nothing about non-finite freqs or other similarities.
The devil's-advocate check209 words
The strongest case for "works as designed": both CombinedFieldQuery and the Axiomatic similarities are @lucene.experimental; the upstream test only covers BM25, Boolean, Classic and the LM similarities; and in 2017, in LUCENE-8083 (#9131), a committer wrote that AxiomaticF2EXP and AxiomaticF2LOG "can't work with maxScore" and should be removed or moved out (#9058).
Why it fails:
@lucene.experimentalallows API changes, not wrong top hits.- The upstream test list is test scope, not a documented exclusion; the javadoc's only rule includes Axiomatic.
- The 2017 remark was superseded: #9058 (LUCENE-8010) was resolved as fixed in 2018 and the similarities stayed in core, #9131 was closed as invalidated by the indexing of impacts, and today
BaseSimilarityTestCaseasserts a non-NaNscore(Float.MAX_VALUE, 1)bound for them, whichTermQueryalready prunes with. - The caller breaks the documented precondition, not the similarity.
Conceded: for the 21 probed configurations where score(+Infinity, 1) is +Infinity (Classic, LM, DFI, AxiomaticF1/F3, IB with the log-logistic distribution) the bound is conservative and results stay correct; only pruning is lost, and no pruning ratio is promised. That is a performance remark, not this bug; the bug is the NaN, which is not an upper bound and loses hits.
The devil's advocate, the OpenAI GPT-5.6 reviewers and the adjudication found the case weak.
Recommended Use score(Float.MAX_VALUE, 1L), in core and in the sandbox copy
Use the documented bound: score(Float.MAX_VALUE, 1L) instead of score(Float.POSITIVE_INFINITY, 1L), as MaxScoreCache does, in core CombinedFieldQuery.java:416 and in the deprecated sandbox copy. The test passes 6 of 6, and so do the closest suites, the sandbox tests and all 2,336 tests of the core search package.
// CombinedFieldQuery.CombinedFieldScorer (core :416 and sandbox :459)
// was: this.maxScore = simScorer.getSimScorer().score(Float.POSITIVE_INFINITY, 1L);
this.maxScore = simScorer.getSimScorer().score(Float.MAX_VALUE, 1L);
All options and trade-offs4 options · 592 words
One option was validated with gradle in a scratch worktree at ea57360912ed (removed after the runs); the others were not run.
Use score(Float.MAX_VALUE, 1L), in core and in the sandbox copy (validated by the checks) (recommended)
One line in each copy of CombinedFieldScorer's constructor (core :416, sandbox :459). SimScorer#score promises that this value bounds every score, BaseSimilarityTestCase checks the promise for every core similarity, and MaxScoreCache relies on it for TermQuery.
// CombinedFieldQuery.CombinedFieldScorer (core :416 and sandbox :459)
// was: this.maxScore = simScorer.getSimScorer().score(Float.POSITIVE_INFINITY, 1L);
this.maxScore = simScorer.getSimScorer().score(Float.MAX_VALUE, 1L);
Trade-offs
- No bound change for BM25 and the 40 DFR configurations: their
score(+Infinity, 1)andscore(Float.MAX_VALUE, 1)are equal in the finder's probe of 75 configurations, which uses one synthetic set of statistics (an observation, not a proof). - For the 21 configurations whose
score(+Infinity, 1)is+Infinity(Classic, the 3 LM similarities, the 3 DFI ones, AxiomaticF1/F3, the 10 IB ones with the log-logistic distribution) the bound becomes finite, so pruning can apply to them too; for Classic it is still huge (6.08e19), so little changes there. No benchmark was run. - Not covered:
CombinedFieldScorer.freq()multiplies term frequencies by field weights in float (:426-428), and weights are only checked to be at least 1, so a weight nearFloat.MAX_VALUEcan make a document's freq+Infinity; thefreq < 0overflow check (:429) cannot catch that. A separate edge, untested.
What the checks validated
- Gradle, stock: the test fails 5 of 6 with assertions on and off.
- Gradle with the fix: the test passes with assertions on and off;
TestCombinedFieldQuery,TestMaxScoreBulkScorer,TestBooleanQuery, the 7TestAxiomatic*classes and the new test: 11 classes, 80 tests, 0 failures (seed DEADBEEF); the new test andTestCombinedFieldQuerywith assertions off (seed CAFEBABE): 20 tests, 0 failures. - Gradle with the fix: all of
org.apache.lucene.search.*in:lucene:core, 214 classes, 2,336 tests, 0 failures, 49 skipped;./gradlew :lucene:core:check -x testpasses. - Sandbox:
TestCombinedFieldQuery(14 tests) passes; the sandbox-class variant passes 5 of 5 with the fix and fails 5 of 5 with only the sandbox line reverted. - The repro runner with only the core class shadowed by the fixed one (the sandbox hunk is covered by the gradle runs): the finder's, the independent reproducer's and the devil's advocate's tests pass, and this doc's test passes 6 of 6. In the query-shape probe all 6 AxiomaticF2LOG shapes give the correct top hits; the probe run is recorded as failing, as intended, because its own check that the stock bug is still observable fails under the fix.
- Not run: other modules, a performance benchmark, x86.
After computing the bound, fall back to Float.POSITIVE_INFINITY when it is NaN, so a custom similarity that breaks the score(Float.MAX_VALUE, 1) contract gets an unpruned but correct clause.
Trade-offs
One comparison per scorer. Defends against a contract violation that BaseSimilarityTestCase already rules out for core similarities; optional.
For example in MaxScoreBulkScorer.updateMaxWindowScores and WANDScorer.
Trade-offs
Would also cover other scorers that might return NaN, but touches the hot path of every disjunction and hides a broken bound instead of fixing it. The rounding fix proposed for the same loop in LFV-060 (MathUtil.sumUpperBound at :540) does not help here: (1 + 2b) * NaN is NaN (MathUtil.java:177-193).
The 10.0.0 behaviour; the one-hunk revert on 10.1.0 passes the finder's test.
Trade-offs
Removes the #13999 pruning for every similarity, BM25 included.
Code reading. While modelling the score bounds of three query classes, an AI tool checked each bound against the SimScorer#score contract and saw the infinite freq. A probe of 75 similarity configurations gave NaN for AxiomaticF2LOG and F2EXP, and a JUnit test on the stock jar then showed the wrong top hit. The unit's proofs covered other classes.
The method in full151 words
Method: code reading (the hunt's non-formal tier), a hunt unit (DisjunctionMax, Synonym and CombinedField queries), 2026-10-26.
- The finder, an AI tool, listed every max-score expression in the three classes and checked each against the
SimScorer#scorecontract ("finite and positive" freq; boundscore(Float.MAX_VALUE, 1)).CombinedFieldScorerpassesFloat.POSITIVE_INFINITY. - A probe of
score(+Infinity, 1),score(Float.MAX_VALUE, 1)and the maximum over finite freqs for 75 core similarity configurations gave NaN for AxiomaticF2EXP and AxiomaticF2LOG and+Infinityfor 21 others (a conservative bound: correct results, only no pruning of that clause). - A deterministic public-API JUnit test on the stock main jar then showed the NaN bound and the wrong pruned top hit (2 of 2 fail, 100 of 100 over 50 iterations).
- The candidate record says it was not found by SMT. The unit's SMT proofs and bounded-exhaustive harnesses covered the DisjunctionMaxQuery bound and SynonymQuery impact merging, not CombinedFieldQuery. Independent checks followed (below).
No prior report found (2026-10-26): 219 recorded queries over GitHub issues, PRs and commits, downstream code, four mailing lists, the JIRA archive and the web, plus the files of 259 open PRs; 24 hits read. Not fixed upstream. Closest: #13999, which added the line, and a 2017 remark about these similarities, since superseded.
Searches4 searches
No report of this bug was found, and upstream main, branch_10x and branch_10_6 still have the line; the open PRs that touch CombinedFieldQuery.java (#14262, #16542) do not change it. Closest items, none of them this bug: #13999 (introduced the line; its discussion covers BM25 and performance only), #9131 / LUCENE-8083 (2017: "can't work with maxScore", superseded by #9058 / LUCENE-8010), #10764 / LUCENE-9725 (opened the query to non-BM25 similarities), #11099 / #418 (older block-max pruning request and stale PR), #14854 (BatchScoreBulkScorer for the query), #16137 / #16139 (a different similarity edge case that breaks pruning). Gaps: GitHub's search rate limit was reached, list search is keyword-based, and private security reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | three runs of the scripted prior-report search and 59 GraphQL phrasings: CombinedFieldQuery, CombinedFieldsQuery, CombinedFieldScorer, BM25F, AxiomaticF2LOG/F2EXP and MaxScoreBulkScorer crossed with NaN, infinity, POSITIVE_INFINITY, MAX_VALUE, maxScore, pruning, wrong results; code fragments such as "score(Float.POSITIVE_INFINITY" and "finite and positive" | no report; 24 related hits read |
| Open PRs | 2026-10-26 | all 413 open PRs listed; changed files of the 259 that could contain a fix | #14262 and #16542 touch the file, not the line |
| Mailing lists and JIRA | 2026-10-26 | 24 list queries over dev@, java-user@, issues@ and commits@; 5 LUCENE JIRA clauses | no report |
| Downstream code and the web | 2026-10-26 | 11 GraphQL searches over Elasticsearch, OpenSearch and Solr; 9 web queries | no report; Elasticsearch's combined_fields only allows BM25 |
Introduced in 10.1.0 by #13999 (de1feea4013, merged 2024-11-22), which replaced return Float.POSITIVE_INFINITY with score(Float.POSITIVE_INFINITY, 1L). Every release from 10.1.0 to 10.5.2 and main fails; 10.0.0 and 9.12.3 pass; reverting only that hunk on 10.1.0 passes. Not fixed upstream.
Versions tested7 rows
Introduced by #13999 "Make CombinedFieldQuery eligible for WAND/MAXSCORE." (de1feea4013, by jpountz, merged 2024-11-22, milestone 10.1.0; branch_10x backport b12404b09b3), then in the sandbox module. On the main line, git log -S 'score(Float.POSITIVE_INFINITY' over both copies of the class finds #13999, which introduced the line, and #14236 (239059e69cf), which copied it into core; git blame -C -C of core :416 leads to #13999. #14236 (2025-02-19) moved the class, with the line, into core for 10.2.0; it is not the cause. branch_10x and branch_10_6 still carry the line (read).
| Version or commit | Verdict | Result |
|---|---|---|
| 9.12.3, 10.0.0 | not affected | getMaxScore returns +Infinity; the finder's test passes 2 of 2 (sandbox class) |
| 10.1.0 | sandbox class | fails 2 of 2; the independent reproducer's sandbox test fails 5 of 5 |
| 10.1.0 with only the #13999 hunk reverted | revert | passes 2 of 2 |
| 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1 | affected | fails 2 of 2 each, identical messages (core class); this doc's test fails 5 of 6 on each (fact check) |
| 10.5.2 | affected | fails 2 of 2 with -ea and -da; this doc's test fails 5 of 6 |
main ea57360912ed | affected | fails with -ea and -da, core and sandbox copies; this doc's test fails 5 of 6 |
| main + the fix | not affected | the test passes 6 of 6; the core search package (2,336 tests) and the sandbox tests pass |
An independent reproducer, a devil's advocate, an OpenAI GPT-5.6 reviewer with the intended-behaviour lens and an adjudication all say real; a refute-lens GPT-5.6 review said "not real" on procedure only, as it could not run code. Fresh-seed re-runs and a query-shape probe agree; fact checks and a diagram check found only count and wording errors, now fixed.
Checks and verdicts802 words
All checks ran on main ea57360912ed unless noted, with fixed seeds recorded in their result files.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | Its 2-test JUnit fails 2 of 2 with -ea and -da, 100 of 100 over 50 iterations; passes with the one-line fix. |
| Refute review (OpenAI GPT-5.6, reading only) | not real (low), procedural | Could not run Java, and the refute review voted not real on procedure only; 9 of its 11 evidence items support real, root cause agrees, inputs in contract. A separate run re-ran the repro: 2 of 2 fail. |
| Independent reproducer | real | Own 3,000-document test: 6 of 6 fail on main (-ea, -da; 120 of 120 over 20 iterations), on 10.5.2 and 10.2.0; sandbox variant 5 of 5 on 10.1.0, passes on 10.0.0 and 9.12.3; BM25, Classic and DFR controls pass; its fix passes 6 of 6. |
| Intended-behaviour review (OpenAI GPT-5.6, reading only) | real (medium) | Intended-behaviour argument weak; 10 of 12 evidence items support real. A separate run re-ran the repro: 2 of 2 fail. |
| Devil's advocate | real | No by-design or won't-fix record survives; the 2017 remark was superseded. Its probe fails 3 of 4 on main -ea and 10.5.2, 2 of 4 with -da (search(q, 10) returns docs 0-9 instead of 2020-2029), and BM25 wrapped in AssertingSimilarity trips the finite-freq assertion at line 416; passes 4 of 4 with the fix. |
| Adjudication | confirmed (high), silent wrong results | Re-ran the independent reproduction's test with seed C0FFEE01 (6 of 6 fail, -ea and -da; controls 3 of 3 pass; 6 of 6 pass with the fix) and the finder's test (2 of 2 fail). |
| Registry re-runs and query-shape probe | reproduced | Fresh seeds 5EED5901-5EED5906: the finder's and the independent reproduction's tests fail with -ea and -da and pass with the fix. The shape probe: wrong top 10 under AxiomaticF2LOG only for one CombinedFieldQuery + a TermQuery or a FeatureField query; all 6 shapes correct with the fix. |
| Security screen | none | 11 query shapes (AxiomaticF2LOG single- and multi-segment, AxiomaticF2EXP single-segment): no filtered, excluded or non-matching document returned, scores equal to the exhaustive ones within the probe's 1e-4 relative tolerance, and no run collected more documents than the exhaustive search matches. Assumes no downstream product makes access decisions from the ranked top hits. |
| Fact check of this doc (independent AI tool) | real; 3 count/table errors, fixed | Re-ran the gradle command in a scratch worktree (5 of 6 fail, assertions on and off; 6 of 6 and TestCombinedFieldQuery 14 of 14 pass with the fix), the repro runner on main and on every release from 10.2.0 to 10.5.2 (5 of 6 fail on each), the tracing probe and the similarity probe. Bug, mechanism, history and fix hold; 3 errors fixed: 21 (not 33) configurations with an infinite bound, 11 (not 12) security-probe shapes, and Classic's bound is +Infinity, not finite. |
| Cross-model fact check (OpenAI GPT-5.6) | real; 11 text errors, fixed or answered | Read-only review against the code and the run logs: the bug is real and the Float.MAX_VALUE fix fits the contract. 11 errors (0 high), 9 overclaims and 4 missing caveats, among them the git log -S result, the 8.9.0 rename, the shape-probe result under the fix and the wording of the trigger and security claims; all taken in this doc; the items that concern only the registry row are listed in the correction below. It rated the intended-behaviour case weak for the NaN and strong for the +Infinity bounds of other similarities, which this doc now concedes. |
| Diagram check | 0 errors; 5 of 8 minor items applied and re-rendered | Every on-screen value, code line and line number matched the code and the probe logs. Re-rendered with: "from then on" and "near doc 2000" on the summary card, the probe's range [2000, 2001) named in step 4, TopScoreDocCollector.java:116, :160-162, and darker grey labels (4.98:1 contrast). |
| Correction to the registry row | 5 wordings out of date | The registry row (shown in the fact strip and in the registry card under Sources) has five wordings that the checks corrected in this doc: found_by and one registry source say +Infinity "for 33 others" (21 is right); introduced_commit says git log -S "finds only this commit adding the line" (it finds #13999, which added it, and #14236, which copied it into core); verification says the security probe ran "12 query shapes" with "scores exact, no extra work" (11 shapes; scores within a 1e-4 relative tolerance; no run collected more than the exhaustive matches); the priority note describes LFV-190 as "a core similarity whose NaN max-score bound makes top-k pruning silently drop the best hits since 10.1" (LFV-190 is IndriDirichlet negative scores dropped by BatchScoreBulkScorer since 10.3.0). This doc's text is the corrected account. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 571 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,472 words
- Registry title
- CombinedFieldQuery computes its max score as score(+Infinity, 1), which is NaN under AxiomaticF2LOG/F2EXP, so top-k pruning silently drops the best hits
- Area
- search / CombinedFieldQuery (BM25F) max-score bound under dynamic pruning (CombinedFieldScorer.getMaxScore as used by MaxScoreBulkScorer)
- Priority
- Medium, rank 63: It has the same profile as LFV-190 (a core similarity whose NaN max-score bound makes top-k pruning silently drop the best hits since 10.1), but only for the rare AxiomaticF2 plus CombinedFieldQuery pairing.
- Impact class
- silent wrong results
- Impact note
- Applications that pair CombinedFieldQuery (@lucene.experimental) with the non-default AxiomaticF2LOG or AxiomaticF2EXP similarity, on 10.1.0 (sandbox class) through 10.6.0 (10.6.0 by reading) or on main, get wrong top hits with no error when exactly one CombinedFieldQuery sits next to another scoring clause in a pruned disjunction (for example SHOULD CombinedFieldQuery plus SHOULD TermQuery or FeatureField query, also with filters or nested in a conjunction): a plain IndexSearcher#search(q, n) is enough once the default total-hits threshold of 1000 is passed, and documents that match only the CombinedFieldQuery are skipped; the default BM25 (and Classic and DFR) is not affected, a lone CombinedFieldQuery and disjunctions of two or more CombinedFieldQuery clauses (the multi-term pattern of the search package docs) gave correct results, and no special scale is needed (3000 documents suffice).
- Summary
- You score a query with CombinedFieldQuery under the core AxiomaticF2LOG (or AxiomaticF2EXP) similarity, which the class javadoc counts as compatible because it keeps the default computeNorm, put it in a BooleanQuery next to another scoring clause such as a TermQuery, and expect IndexSearcher#search(q, 10) to return the same top hits as an exhaustive search. CombinedFieldScorer reports score(Float.POSITIVE_INFINITY, 1) as its max score, although SimScorer#score requires a finite freq and documents score(Float.MAX_VALUE, 1) as the bound; for the F2 similarities that is Inf/Inf = NaN, and MaxScoreBulkScorer, for which NaN is never below the minimum competitive score, then makes the other clause required. Documents that match only the CombinedFieldQuery are skipped: in a 3000-document index the default search returns doc 0 (score 2.1975672) as the top hit instead of doc 2000 (6.383921), and the upstream oracle CheckHits.checkTopScores fails.
- Introduced
- de1feea4013a74ab63a94155d9724b0b1892390c (apache/lucene#13999 'Make CombinedFieldQuery eligible for WAND/MAXSCORE.' by jpountz, merged 2024-11-22, milestone 10.1.0; branch_10x backport b12404b09b3a744323ceddff841dc2e39f1d5024, the commit contained in the 10.x release tags) [read: git log -S 'score(Float.POSITIVE_INFINITY' over the full-history clone finds only this commit adding the line, and git blame -C -C of core CombinedFieldQuery.java:416 leads to it; exec: reverting only the #13999 hunk on the stock 10.1.0 jars makes the finder's repro pass 2 of 2]. #13999 replaced getMaxScore's 'return Float.POSITIVE_INFINITY' with score(Float.POSITIVE_INFINITY, 1L). apache/lucene#14236 (239059e69cf main / cddee429c70 branch_10x, 2025-02-19) moved the class, with the line, into lucene/core; it is not the cause (2024-11-22)
- First affected version
- 10.1.0 [exec] (the sandbox class org.apache.lucene.sandbox.search.CombinedFieldQuery: the repro fails 2 of 2, and passes 2 of 2 with only the #13999 hunk reverted); the core class org.apache.lucene.search.CombinedFieldQuery first shipped in 10.2.0 and is affected from the start [exec]; 10.0.0 and 9.12.3 are not affected [exec] (getMaxScore returned +Infinity there)
- Affected versions
- 10.1.0 (sandbox class), 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2, 10.6.0 (by reading) and main ea57360912ed [exec: the finder's JUnit fails 2 of 2 with identical messages on each with -ea, and also with -da on 10.5.2 and main; the sandbox copy fails the same way on 10.2.0, 10.5.2 and main; the independent reproduction's own JUnit fails 6 of 6 on main and 10.5.2 (-ea and -da) and on 10.2.0, and its sandbox variant 5 of 5 on 10.1.0; the intended-behaviour check's probe fails on main and 10.5.2]; not affected: 10.0.0 and 9.12.3 [exec], 9.12.0-9.12.2 and 8.x (then BM25FQuery) [read]; the branch_10x and branch_10_6 heads still contain the line [read, not executed]; not fixed upstream as of 2026-10-26 (the line is still at CombinedFieldQuery.java:416 on apache/lucene main and at :420 on branch_10x and branch_10_6). Caveats: each release was run with one seed on JDK 25.0.3 aarch64; x86 and a concurrent searcher with an executor were not run
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 219 recorded queries, namely three runs of the scripted prior-report search over apache/lucene issues, PRs and commits, Elasticsearch, OpenSearch and Solr code, the dev@, java-user@, issues@ and commits@ lists, the LUCENE JIRA archive and the web, plus 70 read-only GitHub GraphQL searches, web and Q&A searches, upstream file and commit reads and local git history; the changed files of the 259 open apache/lucene PRs that could contain a fix, out of 413 listed; 24 hits read and classified, none the same bug; the finder, the intended-behaviour check and the adjudication found nothing either); not fixed upstream (the line is unchanged on apache/lucene main, branch_10x and branch_10_6; the only open PRs touching core CombinedFieldQuery.java, #14262 and #16542, do not change the max-score line); closest items, not reports: #13999 (introduced the line; its discussion covers BM25 and performance only), #9131 / LUCENE-8083 (2017; rmuir remarked that the F2 similarities 'can't work with maxScore', before LUCENE-8010 / #9058 fixed them and kept them in core and before LUCENE-8119 set the score(maxFreq, 1) convention), #10764 / LUCENE-9725 (opened the query to non-BM25 similarities), #11099 / #418 (older dynamic-pruning feature request and stale PR), #14854 (BatchScoreBulkScorer on the query), #16137 / #16139 (a different similarity-edge pruning bug in IBSimilarity)
- Lucene commit tested
- main
ea57360912ed(commit 2026-10-24; tested 2026-10-26): the JUnit repro with gradle in a scratch worktree, stock (assertions on and off) and with the fix, plus the closest suites, the wholeorg.apache.lucene.searchtest package of:lucene:core(2,336 tests) and:lucene:core:check -x testwith the fix (the worktree was removed after the runs); the repro through the repro runner on main (-ea,-da) and on the 10.5.2 and 10.2.0 jars (and, in the fact check, on every release from 10.2.0 to 10.5.2); the finder's test on the Maven Central jars of every release from 10.1.0 to 10.5.2 and on 10.0.0 and 9.12.3 (SHA-1 checked), and on 10.1.0 with only the #13999 hunk reverted. Upstream main, branch_10x and branch_10_6 still had the line on 2026-10-26 (read).
- Finding record
lucene/core/src/java/org/apache/lucene/search/CombinedFieldQuery.java:60-64 (at ea57360912ed) (compatibility: additive norms encoded with intToByte4, 'hold for all similarities that don't customize computeNorm'), :77 (@lucene.experimental), :403-404 (not cacheable), :416 ('this.maxScore = simScorer.getSimScorer().score(Float.POSITIVE_INFINITY, 1L);'), :446-448 (getMaxScore returns it for every upTo)lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:201-221 (at ea57360912ed) (SimScorer#score: freq 'must be finite and positive'; 'the maximum score that this scorer can produce is bound by score(Float.MAX_VALUE, 1)')lucene/core/src/java/org/apache/lucene/search/similarities/AxiomaticF2LOG.java:62 (at ea57360912ed) and AxiomaticF2EXP.java:72 (tfln = freq / (freq + s + s * docLen / avgFieldLength), Inf/Inf = NaN); similarities/Axiomatic.java:107-116 (Math.max(0, score) keeps NaN)lucene/core/src/java/org/apache/lucene/search/MaxScoreCache.java:48 (at ea57360912ed) ('globalMaxScore = scorer.score(Float.MAX_VALUE, 1L)')lucene/core/src/java/org/apache/lucene/search/MaxScoreBulkScorer.java:474-548 (at ea57360912ed) (partitionScorers; :502 a NaN sum is never below the minimum competitive score, so the clause stays essential; :530-548 single-essential-clause loop, check at :540, makes the other clauses required)lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:100 (at ea57360912ed) (TOTAL_HITS_THRESHOLD = 1000); package-info.java:290-302 (one CombinedFieldQuery per term as SHOULD clauses)lucene/core/src/java/org/apache/lucene/search/WANDScorer.java:91 (at ea57360912ed) ('assert Float.isNaN(maxScore) == false', the -ea symptom for minimumShouldMatch >= 2)lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/AssertingSimilarity.java:77 (at ea57360912ed) ('assert Float.isFinite(freq)'); RandomSimilarity.java:126-127 (rotates AxiomaticF2EXP/F2LOG)lucene/core/src/test/org/apache/lucene/search/TestCombinedFieldQuery.java (at ea57360912ed) (randomCompatibleSimilarity uses BM25, Boolean, Classic, LMDirichlet and LMJelinekMercer only)lucene/sandbox/src/java/org/apache/lucene/sandbox/search/CombinedFieldQuery.java:459 (at ea57360912ed) (same line in the deprecated sandbox copy; out of hunt scope)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/search/CombinedFieldQuery.java:51-58, (at ea57360912ed) 60-64, 77, 397, 413-417, 424-440, 446-448lucene/core/src/java/org/apache/lucene/search/similarities/AxiomaticF2LOG.java:62; (at ea57360912ed) similarities/AxiomaticF2EXP.java:72; similarities/Axiomatic.java:107-116lucene/core/src/java/org/apache/lucene/search/MaxScoreBulkScorer.java:430-444, (at ea57360912ed) 474-551 (500-502, 524, 530-548, 540); BooleanScorerSupplier.java:308-328, 364; BooleanWeight.java:57-59lucene/core/src/java/org/apache/lucene/search/Scorer.java:75-79; (at ea57360912ed) IndexSearcher.java:100, 599; TopScoreDocCollector.java:154-164
- Who is affected
lucene/core/src/java/org/apache/lucene/search/WANDScorer.java:91; (at ea57360912ed) IndexSearcher.java:100; search/CombinedFieldQuery.java:77
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/search/similarities/Similarity.java:201-221; (at ea57360912ed) search/MaxScoreCache.java:48; search/Scorer.java:75-79; search/CombinedFieldQuery.java:60-64, 72-75, 416lucene/sandbox/src/java/org/apache/lucene/sandbox/search/TermAutomatonScorer.java:364; (at ea57360912ed) lucene/CHANGES.txt:2087-2088lucene/test-framework/src/java/org/apache/lucene/tests/search/similarities/AssertingSimilarity.java:76-77, (at ea57360912ed) BaseSimilarityTestCase.java:382-391, RandomSimilarity.java:126-127; lucene/core/src/test/org/apache/lucene/search/TestCombinedFieldQuery.java:392-401
- Suggested fix
lucene/core/src/java/org/apache/lucene/search/CombinedFieldQuery.java:426-431; (at ea57360912ed) util/MathUtil.java:177-193; lucene/sandbox/src/java/org/apache/lucene/sandbox/search/CombinedFieldQuery.java:459 (at ea57360912ed)
- TestCombinedFieldQueryNaNMaxScore.java (JUnit test):
repro/LFV-253/src/org/apache/lucene/search/TestCombinedFieldQueryNaNMaxScore.java(72 lines)
The PNG is the summary card: setup, the max score each clause reports, Infinity / Infinity = NaN, the collector raising the bar after 1,000 hits, the partition that makes the TermQuery required, and doc 2000 never reaching the collector. Every value on screen comes from a tracing probe run on the main jar (ea57360912ed; public API, plus reads of MaxScoreBulkScorer's package-private partition fields from the same package for the trace), or from the repro and the code.
assets/LFV-253/bug.png(571 KB)