A ContextQuery filters with one rule and boosts with another. The filter treats an exact context as exact; the boost lookup only checks that the indexed context starts with it.
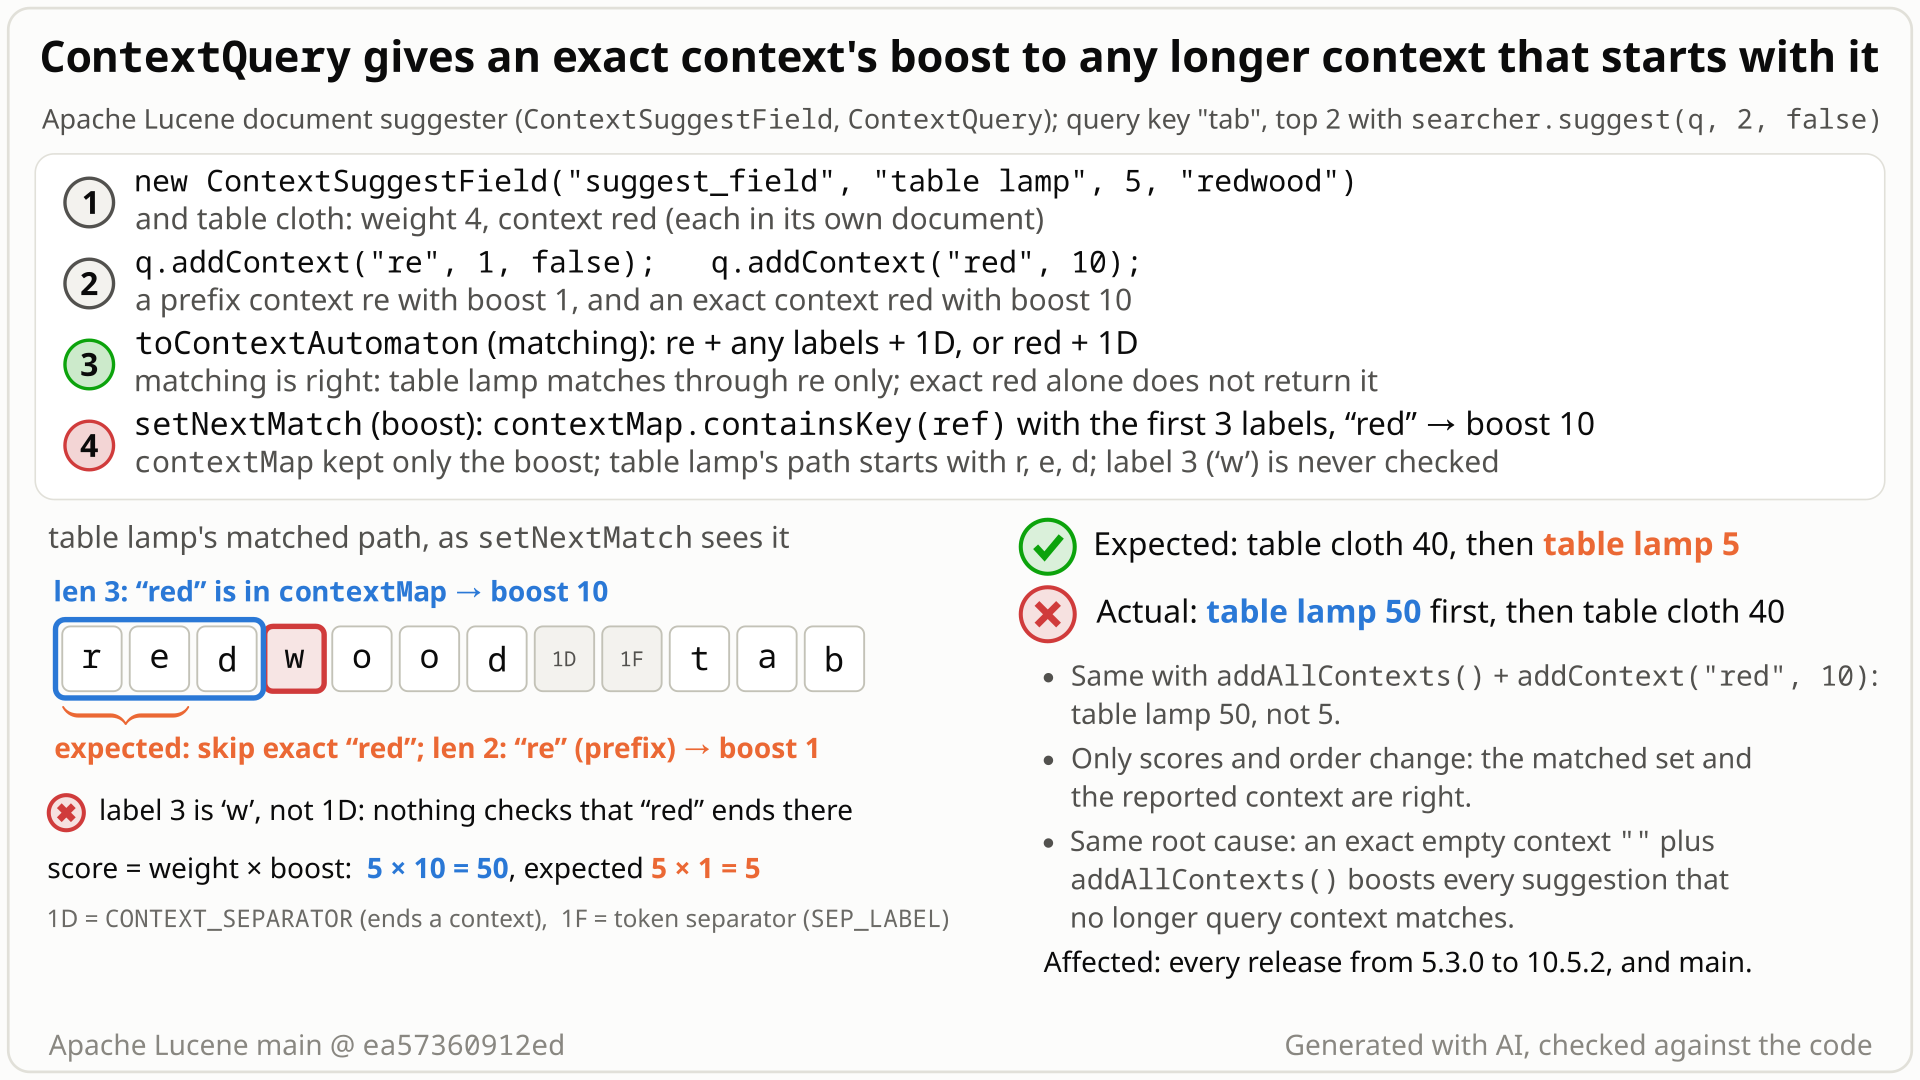
re (prefix, boost 1) and red (exact, boost 10). table lamp's path redwood matches only through re, but the boost lookup stops at its first 3 letters, finds red, and never checks for the separator: 5 x 10 = 50 instead of 5 x 1 = 5. Select the still to open it at full size. Generated with AI, checked against the code.- Index two suggestions with
ContextSuggestField:table lamp(weight 5) under the contextredwoodandtable cloth(weight 4) underred. - Suggest for
tabwith aContextQuerythat boosts the exact contextredby 10 and also lets every context in:addContext("red", 10)plusaddAllContexts(), or plus a prefix contextrewith boost 1. - You expect
table clothfirst with 4 x 10 = 40, andtable lampat its plain weight 5:redwoodis notred, and exactredon its own does not returntable lamp. - Instead
table lampscores 5 x 10 = 50 and comes first. To find the boost, Lucene takes the longest query context equal to the start of the indexed context (redofredwood) and never checks that the indexed context ends there. - Same cause, wider: an exact empty context,
addContext("", 10)plusaddAllContexts(), gives boost 10 to every suggestion that has a context (table cloth40 instead of 4). No error; the matched set and each hit's context stay right.
Users of the opt-in document suggester whose ContextQuery mixes a boosted exact context with addAllContexts() or a shorter prefix context, while some indexed context starts with the exact one and the boosts give different scores (red/redwood, type1/type10, 12/123). Every release from 5.3.0 to 10.5.2 and main; two suggestions suffice, and it is deterministic.
Mechanism, terms and numbers775 words
A ContextQuery in the document suggester decides which suggestions match with one rule and how much to boost them with another. Matching honours exact contexts: exact red admits only suggestions indexed under red. The boost lookup does not: it keeps only the boost of each query context, drops the exact flag, and takes the longest query context whose characters equal the start of the matched indexed context, without checking that the indexed context ends there. So when another clause of the same query, addAllContexts() or a shorter prefix context, lets a longer context such as redwood in, that suggestion gets the boost of exact red: table lamp (weight 5) scores 50 instead of 5 and ranks above table cloth (40). An exact empty context with addAllContexts() gives its boost to every suggestion with a context. No error is raised; the set of suggestions the context filter admits and the reported contexts are right; only scores are wrong, and so the order and which admitted suggestions make the top N. The code dates from LUCENE-6459 (2015); every release from 5.3.0 to 10.5.2 and main are affected.
- Document suggester: suggestions indexed with
ContextSuggestField(key, weight, optional contexts) and a completion postings format, queried throughSuggestIndexSearcher. A suggestion scoresweight * boost; with boost 0 it scores its plain weight, and with weight 0 the boost (CompletionScorer.java:98-106). ContextQuery(@lucene.experimental) wraps a completion query:addContext(c, boost)adds an exact context,addContext(c, boost, false)a prefix context,addAllContexts()lets every context in "with a boost of 1f".- In the index each suggestion path is
context + CONTEXT_SEPARATOR (\u001D) + key; with the defaultpreserveSepaSEP_LABEL(0x1F) follows the separator.
- Filtering is right.
toContextAutomatonputs the separator directly after an exact context, andany characters + separatorafter a prefix context or foraddAllContexts()(ContextQuery.java:228-250,:241-244). Exactredalone never returnsredwood. - The boost table forgets
exact.createWeightstores only the boost per context:contextMap.put(entry.getKey(), contextMetaData.boost)(:208), and sorts the context lengths longest first (:211-212). - The lookup checks only a prefix. For each matched path prefix,
setNextMatchcuts the path to each length, longest first, and takes the first key found (:285-300). Forredwood\u001Dtable lampand the query contextsredandre, length 3 givesred, so boost 10. Nothing checks that the separator follows at position 3. - The score.
table lampgets 5 x 10 = 50 instead of 5 x 1 = 5. Its reported context is stillredwood, becausesetInnerWeightcopies the whole indexed context (:308-331). - Empty exact context. A key of length 0 equals the start of every path, so exact
""(meant for suggestions without a context) boosts every path that no longer key matches. With only exact""plusaddAllContexts(), suggestions without a context get the boost rightly (table mat30) and suggestions with a context wrongly (table lamp50,table cloth40).
Probe on main, key prefix tab; table lamp 5 under redwood, table cloth 4 under red, table mat 3 without a context:
| query contexts | expected (main with the fix) | got on main |
|---|---|---|
exact red^10 only (control) | table cloth 40 | the same |
prefix re^1 + exact red^10 | table cloth 40, table lamp 5 | table lamp 50, table cloth 40 |
addAllContexts() + exact red^10 | table cloth 40, table lamp 5, table mat 3 | table lamp 50, table cloth 40, table mat 3 |
addAllContexts() + exact ""^10 | table mat 30, table lamp 5, table cloth 4 | table lamp 50, table cloth 40, table mat 30 |
prefix re^2 + exact redwood^3 (control) | table lamp 15, table cloth 8 | the same |
It shows only when the stolen boost gives a different score from the right one (the boost of the longest query context that really matches, or none under addAllContexts()). The scorer sees the context boost plus the inner query's boost (ContextQuery.java:339-341). With a prefix inner query, as here, boosts 0 and 1 both leave the plain weight, so an exact boost of 1 or 0 is hidden under addAllContexts() or a boost-1 prefix context; a fuzzy inner query adds its own boost, so there exact red^1 with addAllContexts() shows (table lamp 15 instead of 10, ranked first). It is also hidden when a longer query context matches. The wrong boost can lower a score too (addContext accepts boost 0): prefix re^2 + exact red^0 gives table lamp 5 instead of 10.
Exposure and likelihood192 words
- The pattern is upstream-tested.
addAllContexts()plus boosted exact contexts is whatTestContextQuery.testMixedContextQuerydoes (addAllContexts()plus exacttype1^7 andtype2^6). Index one more context,type10, and its suggestion (weight 5) scores 35 instead of 5. - Ordinary names trigger it. Category sets where one name starts with another: numbered or hierarchical names, numeric ids.
- Downstream (code reading only, not run): Elasticsearch and OpenSearch build
ContextQueryfrom category contexts withaddContext(typeId + context, boost, !isPrefix)and require at least one context, so they never calladdAllContexts(); there it takes one request that mixes an exact category and a shorter prefix category whose boosts give different scores. - What it costs users. Silent wrong scores (the stolen boost replaces the right one), so a wrong order, and an admitted suggestion can be pushed below the top N (with
num = 1the example returnstable lampinstead oftable cloth). The set of suggestions the query admits and each hit's reported context do not change. - What it takes. The document suggester and
ContextQueryare opt-in; nothing else is: the default codec with the completion format, assertions on or off, no scale.
The test shows that an exact ContextQuery context ('red', boost 10) lends its boost to a suggestion indexed under a longer context that starts with it ('redwood') when that suggestion is matched through addAllContexts().
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.suggest.document;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestContextQueryExactContextBoost extends LuceneTestCase {

  public void testExactContextBoostNotAppliedToLongerContext() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        Analyzer analyzer = new StandardAnalyzer()) {
      IndexWriterConfig iwc = new IndexWriterConfig(analyzer);
      iwc.setCodec(TestUtil.alwaysPostingsFormat(new Completion104PostingsFormat()));
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        Document doc = new Document();
        doc.add(new ContextSuggestField("suggest", "lamp", 5, "redwood"));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        ContextQuery query =
            new ContextQuery(new PrefixCompletionQuery(analyzer, new Term("suggest", "la")));
        query.addContext("red", 10, true);
        query.addAllContexts();
        TopSuggestDocs top = new SuggestIndexSearcher(reader).suggest(query, 1, false);
        // "redwood" is not the exact context "red": expected the plain weight 5, actual 5 * 10
        assertEquals("score of lamp/redwood", 5f, top.scoreLookupDocs()[0].score, 0f);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-254/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/suggest/build/libs/lucene-suggest-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.suggest.document.TestContextQueryExactContextBoost
- Expected vs actual
- Expected the 'lamp' suggestion (context 'redwood', weight 5) to score its plain weight 5; actual 50 (
expected:<5.0> but was:<50.0>), with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: score of lamp/redwood expected:<5.0> but was:<50.0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
org.apache.lucene.search.suggest.document.TestContextQueryExactContextBoost.testExactContextBoostNotAppliedToLongerContext(TestContextQueryExactContextBoost.java:50)addContext(c, boost)"Adds an exact context with boost"; the class javadoc says to share one boost across a prefix you setexactto false.- The same query treats
redas exact when filtering: exactredalone does not returnredwood. addAllContexts()adds "all contexts with a boost of 1f", yetredwoodgets 10.
The full argument246 words
- Contracts (
ContextQuery.java): "Adds an exact context with boost" (:115); "setexactto false if the context is a prefix of any indexed contexts" (:120-123); class javadoc: "To apply the same boost to multiple contexts sharing the same prefix, Use addContext(CharSequence, float, boolean) with the common context prefix, boost and setexactto false" (:64-66);addAllContexts(): "Add all contexts with a boost of 1f" (:146);ContextMetaData.exact: "whether the context value should be treated as an exact value or a context prefix" (:256-257). - Upstream tests.
testMixedContextQuery(TestContextQuery.java:311) andtestEmptyContextWithBoosts(:236) expect contexts without a configured boost to keep their plain weight underaddAllContexts().testContextPrecedenceBoost(:177) gives each indexed context the boost of the query context equal to it, and queries exacttypewhiletypetypeis indexed, so that usage is legal. No upstream test indexes a longer context that an exact query context starts with and that another clause lets in; many tests use boost 1, which hides the bug. - History. The lookup came with
ContextQueryin LUCENE-6459 (2015). Its only recorded boost intent is "added test to ensure longer context takes precedence for boosting", i.e.testContextPrecedenceBoost. No issue, CHANGES or MIGRATE text calls the behaviour intended. - Under any reading that respects
exact,redwoodis matched only byre^1 or byaddAllContexts(), so 50 is wrong whatever tie-break among matching contexts is chosen.
The devil's-advocate check213 words
The intended-behaviour checker built the strongest case: (a) the lookup is deliberately "longer context first" (code comment, LUCENE-6459's precedence test), so the longest query context that starts the indexed context supplies the boost whatever its flag; (b) read literally, "set exact to false if the context is a prefix of any indexed contexts" is a precondition, so exact red with redwood indexed is misuse; (c) the class is @lucene.experimental; (d) the code can be read as admission by the automaton, then a boost overlay by string prefix, unchanged since 2015.
Why it fails: (a) the precedence rule picks among query contexts that match, and the fix keeps it (the controls with prefix re^2 + exact redwood^3 and with two prefix contexts pass with and without the fix); (b) upstream's own testContextPrecedenceBoost queries exact type with typetype indexed, and filtering honours exactness in that case; (c) experimental allows API changes, not wrong scores; (d) nothing documents a prefix overlay for exact contexts, and the age of the behaviour argues for a release note, not for keeping the scores. The literal reading (b) is the strongest point; a maintainer who prefers it would document the behaviour instead (option D). Verdict: a defect. Not security: only ranking within the admitted set changes.
Recommended A: keep exact and check for the separator
Keep each query context's exact flag next to its boost, and in setNextMatch accept an exact context only where the indexed context ends, that is where CONTEXT_SEPARATOR follows (+12/-6 lines, ContextQuery.java only). Prefix contexts and the longest-first rule are unchanged. The test and the whole suggest module (241 tests) pass, assertions on and off.
// createWeight: keep the exact flag (contextMap is now Map<IntsRef, ContextMetaData>)
contextMap.put(entry.getKey(), contextMetaData); // was: contextMetaData.boost

// setNextMatch: an exact context only matches when the indexed context ends right here
ContextMetaData metaData = contextMap.get(ref);
if (metaData != null
    && (metaData.exact == false
        || (contextLength < pathPrefix.length
            && pathPrefix.ints[pathPrefix.offset + contextLength]
                == ContextSuggestField.CONTEXT_SEPARATOR))) {
  currentBoost = metaData.boost;
All options and trade-offs4 options · 599 words
One fix was built and validated in a scratch worktree at ea57360912ed; the other options were not run.
createWeight stores ContextMetaData (boost and exact) in contextMap instead of the boost alone; setNextMatch accepts a key of length N that is exact only when the path has CONTEXT_SEPARATOR at position N. +12/-6 lines in ContextQuery.java; contextMap and ContextCompletionWeight are private, so no API change. The finder wrote it, and the independent reproducer wrote the same fix on its own.
// createWeight: keep the exact flag (contextMap is now Map<IntsRef, ContextMetaData>)
contextMap.put(entry.getKey(), contextMetaData); // was: contextMetaData.boost

// setNextMatch: an exact context only matches when the indexed context ends right here
ContextMetaData metaData = contextMap.get(ref);
if (metaData != null
    && (metaData.exact == false
        || (contextLength < pathPrefix.length
            && pathPrefix.ints[pathPrefix.offset + contextLength]
                == ContextSuggestField.CONTEXT_SEPARATOR))) {
  currentBoost = metaData.boost;
Trade-offs
- Cost. The map is probed once per context length tried, as before, and the second lookup on a hit (
containsKeythenget) is gone; an exact key that is found adds a bounds check and one array read. The loop runs once per matched path prefix, not per document. No benchmark was run. - Behaviour change only where an exact query context is a proper prefix of the matched indexed context: that path now gets the boost of the longest query context that really matches it, or none (plain weight). Exact keys equal to the indexed context, and all prefix keys, behave as before.
- The exact empty context then boosts only suggestions without a context, as its filtering already does.
- Ranking change. Affected queries get different scores and order; the behaviour dates from 2015, so a
CHANGES.txtentry is advisable.
What the checks validated
- Stock: the test fails 3 of 5 with assertions on and off; both controls pass.
- Fix: the test and the closest suites (
TestContextQuery15,TestContextSuggestField6,TestFuzzyCompletionQuery3, the new test 5) pass 29 of 29, assertions on and off. - Fix,
:lucene:suggest:test: 32 classes, 241 tests, 0 failures, 7 skipped (@Nightlyand benchmark tests), assertions on and off, and with a second seed. :lucene:suggest:tidyleft the fix unchanged;:lucene:suggest:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Also passes the finder's, the independent reproducer's and the devil's advocate's tests. The random harness, run with this fix and the separate NRTSuggester fix (LFV-242) shadowed in, finds no mismatch of this class on 3,000 indexes with deletions where main has 8,808 (a combined-fix run; the tests above isolate this fix).
Find the separator once (the indexed context is the path up to it), look up the whole context with any flag, and otherwise take the longest shorter key whose exact is false.
Trade-offs
Same results as A, since an exact key can only equal the whole context; states the intent more directly, at the cost of reshaping the loop.
Store each exact key with CONTEXT_SEPARATOR appended, so a plain prefix comparison can only match where the indexed context ends.
Trade-offs
No flag check in the loop, but the matched length then includes the separator, so the offset handed to setInnerWeight needs adjusting; more invasive than A.
State that an exact context's boost also applies to longer contexts that start with it.
Trade-offs
Contradicts "Adds an exact context", the class javadoc's advice to use exact=false for a shared prefix boost, and the filter, which treats the same context as exact in the same query.
Code reading. An AI tool writing an independent reference model of the document suggester noticed that the boost lookup ignores exact, and a JUnit test on the stock jar confirmed it. A random harness against that model then found 17,310 mismatches in 4,680,000 lookups on main, all of this kind.
The method in full179 words
A hunt unit (suggesters). The harness compares the stock suggester with the reference on random indexes of at most 6 documents over an alphabet of a, b and space, contexts from {a, b, ab, aa, ba, aba}, random exact and prefix query contexts with boosts and addAllContexts(), every key of length up to 3, 1 to 5 results, duplicates skipped or kept. On main, 3,000 indexes without deletions gave 17,310 mismatches, all "exact context boost applied to a longer context"; on 3,000 indexes with deletions, 8,808 of this class on main and none with this fix and the separate NRTSuggester fix (LFV-242) shadowed in (a combined-fix run; the JUnit and probe runs isolate this fix). The harness samples randomly and is not exhaustive; no model checker or prover was involved.
Then: a cross-model refute review (an independent reviewer from another model family, OpenAI GPT-5.6, reading only), an independent reproducer, a second GPT-5.6 review arguing "works as designed", a devil's advocate, an adjudication, a release sweep from 5.2.1 to main, a prior-report search and a security assessment.
No prior report (2026-10-26): 124 recorded queries and operations over GitHub issues, PRs and commits, downstream trackers, four mailing lists, the JIRA archive and the web; the files of all 413 open PRs; the introducing JIRA threads read. Closest: #9335 (LUCENE-8288), a different ContextQuery defect.
Searches4 searches
14 hits were read and classified; none is this bug. #9335 / LUCENE-8288 (open) is a regex assertion in setInnerWeight; #9334 / LUCENE-8287 and #7569 / LUCENE-6510 are other ContextQuery defects, fixed (the random scoring test of LUCENE-6510 cannot reach this bug); #7518 / LUCENE-6459 and #7760 / LUCENE-6702 are the introducing changes; #14169 (2025) builds each context's automaton and unions them once at the end instead of repeatedly, and does not touch the boost lookup. No open PR touches ContextQuery.java. Limits: token-based GitHub search, keyword-based list and JIRA search, one Q&A page not fetchable, private security reports not searchable.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene, apache/lucene-solr) | 2026-10-26 | 49 issue/PR queries over apache/lucene (6 of them hand-written to also cover the Elasticsearch and OpenSearch repositories) and 6 commit queries from the scripted prior-report search (ContextQuery, setNextMatch, addContext, addAllContexts, "exact context", "context boost", "wrong score", ...), plus 2 manual searches of apache/lucene-solr | only the introducing changes and other ContextQuery defects (#9335, #9334, #7569, #14169) |
| Open PRs | 2026-10-26 | the changed files of all 413 open apache/lucene PRs | 7 touch lucene/suggest/, none touches ContextQuery.java, ContextSuggestField.java or TestContextQuery.java |
| Mailing lists and JIRA archive | 2026-10-26 | 32 queries over dev@, java-user@, issues@ and commits@; 12 LUCENE JIRA queries; the JIRA comments of LUCENE-6459, LUCENE-6702, LUCENE-6510 and LUCENE-8288 read | no report; no by-design statement |
| Downstream trackers and the web | 2026-10-26 | 5 generated queries over Elasticsearch, OpenSearch and Solr issues and PRs (the 6 hand-written downstream queries are counted under GitHub above); 12 web queries (78 pages) | documentation and usage questions only |
In ContextQuery since it was added (LUCENE-6459, 2015), so not a regression. The same failure on 17 releases from 5.3.0, the first with the API, to 10.5.2 and on main; the one-site fix ported to 5.3.0 turns it green. Not fixed upstream as of the last check (2026-10-26).
Versions tested9 rows
Introduced with the API by be4d58c7740 (LUCENE-6459, 2015-05-28, by Areek Zillur (@areek), committed by Mike McCandless (@mikemccand); an svn-era patch, issue now apache/lucene#7518). f8ae631751a (LUCENE-6702, #7760, 2015-07-30, on trunk; 5.3.0 got it through the branch_5x backport 4a44bd9a509 the same day, with an identical ContextQuery.java) rewrote the lookup into today's form, added addAllContexts(), and kept both defective pieces. The whitespace-normalized setNextMatch body and the boost-only contextMap.put are identical in all 94 release tags from 5.3.0 to 10.5.2. 8.8.2 to 8.11.3 are not tagged in the history clone; releases up to 7.7.3 ran on JDK 25 with a JUnit 4 runner, and the controls pass in each run.
| Version or commit | Verdict | Result |
|---|---|---|
| 5.2.1 | not affected | no ContextQuery: the test does not compile |
| 5.3.0 | first affected | 2 of 4 fail (apple 21.0 instead of 3.0), assertions on and off |
| 5.5.5, 6.0.0, 6.4.2, 6.5.0, 6.6.6, 7.0.0, 7.7.3 | affected | 2 of 4 fail, same numbers |
| 8.0.0, 8.3.1, 8.4.0, 8.11.4 | affected | 2 of 4 fail, same numbers |
| 9.0.0, 9.1.0, 9.12.3 | affected | 2 of 4 fail, same numbers (9.12.3 also with assertions off) |
| 10.0.0, 10.5.2 | affected | 2 of 4 fail, same numbers (10.5.2 also with assertions off) |
main ea57360912ed | affected | this doc's test 3 of 5 fail; the portable test 2 of 4 fail; assertions on and off |
| 5.3.0 + the fix ported | commit level | 4 of 4 pass; 5.3.0's own TestContextQuery passes with and without it |
| main + the fix | not affected | this doc's test 5 of 5; the whole suggest module passes (241 tests) |
An independent reproducer, a GPT-5.6 reviewer arguing "works as designed" (reading only), a devil's advocate and an adjudication say real. An earlier GPT-5.6 refute review said "not real" on procedure because it could not run code, while agreeing with the root cause. This doc's test was re-run, and the fix validated.
Checks and verdicts514 words
Unless noted, checks ran on main ea57360912ed with fixed seeds, assertions on and off; the GPT-5.6 reviews could read code but not run it, and separate runs ran the finder's test.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | Its JUnit fails 2 of 3 on main (assertions on and off), 10.5.2, 9.12.3, 8.11.4 and 6.6.6 (table lamp 50.0 instead of 5.0); with its fix 3 of 3 pass, and 24 upstream suggester tests pass. |
| Refute review (OpenAI GPT-5.6) | not real, low (procedural) | Could not execute, so it voted not real on procedure only; it agreed with the root cause, found the inputs in contract and rated the intended-behaviour argument weak. A separate run of the finder's test failed 2 of 3. |
| Independent reproducer | real | Own public-API test outside Lucene's packages: 2 of 4 fail on main, 10.5.2, 9.12.3 and 8.11.4 (apple 21.0 instead of 3.0), controls pass; its own fix at the same site passes 4 of 4 and upstream TestContextQuery 15 of 15. |
| 'works as designed' reviewer (OpenAI GPT-5.6) | real, medium | Reading only: intended-behaviour argument weak, root cause agrees, the fix fixes it. A separate run ran the finder's test with a second seed (2 of 3 fail; 3 of 3 pass with the fix). |
| Devil's advocate | real, high | Built the best 'intended' case and refuted it; its test (upstream's mixed-context pattern plus type10) fails on main and 10.5.2 (35.0 instead of 5.0) and found the empty-context variant (10.0 instead of 1.0); passes with the fix; its precedence control passes with and without it. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with its own seed (2 of 4 fail, assertions on and off; 4 of 4 pass with the fix). Class: silent wrong results; security: none. |
| Follow-up re-runs | reproduced | Fresh seeds: the finder's test 2 of 3 fail, the independent reproduction's 2 of 4, the intended-behaviour check's claim tests both fail; all pass with the fix. |
| This doc | re-run and fix validated | A new upstream-style test fails 3 of 5 on main through gradle with assertions on and off; with the fix it passes, and so does the whole suggest module (241 tests) with assertions on and off and a second seed. |
| Fact check of this doc (re-ran the tests and probes) | real, reproduced; 6 wording fixes | Re-ran this doc's test on main (3 of 5 fail, assertions on and off) and with the fix (5 of 5), the probe, the portable test on 10.5.2 and main, and an isolated score-lowering case; six precision errors, all fixed. |
| Cross-model fact check (OpenAI GPT-5.6, reading only) | bug real; 19 accuracy findings | Agreed with the mechanism and the fix; its findings on wording, visibility conditions, scope and caveats were fixed or answered; its visibility claims were executed. |
| Diagram check | pass; 3 minor items fixed | Every value, API name and line number on screen matched the code and a re-run of the probe; the three optional items were fixed and the visuals re-rendered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 489 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,520 words
- Registry title
- ContextQuery gives an exact context's boost to any longer indexed context that starts with it (exact 'red' boosts a suggestion indexed under 'redwood') when that longer context is matched through a shorter prefix context or addAllContexts(), so document-suggester hits get wrong scores and a wrong order
- Area
- suggest / document (NRT) suggester (ContextQuery: ContextCompletionWeight.setNextMatch boost lookup over ContextSuggestField contexts)
- Priority
- Medium, rank 51: In the opt-in document suggester, prefix-overlapping contexts with a boost silently give wrong scores and order while filtering stays correct, so it goes with the narrower score-only rows.
- Impact class
- silent wrong results
- Impact note
- Applications that use the document suggester (ContextSuggestField with a completion postings format) on any release from 5.3.0 through 10.5.2 or on main get wrong suggestion scores, and so a wrong order or a different top n, with no error, whenever one ContextQuery has an exact context C with a boost other than 1 (addContext(C, boost) or exact=true) together with addAllContexts() or a shorter prefix context, and an indexed context is longer than C and starts with it ('red'/'redwood', 'type1'/'type10', numeric ids such as '12'/'123'); an exact empty context with addAllContexts() gives its boost to every suggestion that no longer query context matches; filtering, the returned set and the reported context are correct, and no index size or non-default setting beyond the suggester itself is needed.
- Summary
- You index 'table lamp' (weight 5) under context 'redwood' and 'table cloth' (weight 4) under 'red' with ContextSuggestField, and query 'tab' with addAllContexts() (or a prefix context 're') plus the exact context 'red' with boost 10; you expect 'table cloth' to score 4 x 10 = 40 and 'table lamp' its plain weight 5, because an exact context matches only an indexed context equal to it. Instead 'table lamp' scores 50 and ranks first: the boost lookup takes the longest query context whose characters equal the start of the indexed context and never checks that the indexed context ends there, so exact 'red' lends its boost to 'redwood'. Filtering is still right (exact 'red' alone does not return 'table lamp'); only scores and order are wrong.
- Introduced
- be4d58c7740bea4e797eb1acff6355eb260e7c93 (LUCENE-6459 'add common suggest API for document based NRT suggester', by Areek Zillur (@areek), committed by Mike McCandless (@mikemccand), trunk, svn era with no pull request; issue now apache/lucene#7518; branch_5x backport 380bb29f39595de1c3947075296d1d0a36f02fd8 the same day) [read: git blame -w -M -C of ContextQuery.java on main and git log -S in the full-history clone; exec: the repro fails on 5.3.0, the first release with the API, and passes with the one-site fix ported to 5.3.0]. The commit that added ContextQuery already had the longest-prefix boost lookup over a boost-only map, so the defect is as old as the API; not a regression. LUCENE-6702 (f8ae631751ae98ca770d8f387793d9846db62c48, apache/lucene#7760, 2015-07-30, also in 5.3.0) rewrote createWeight and setNextMatch into today's form and kept both defective pieces (2015-05-28)
- First affected version
- 5.3.0 [exec] (the first release with ContextQuery; the repro fails 2 of 4 with -ea and -da, and passes 4 of 4 with the fix ported); 5.2.1 has no ContextQuery, ContextSuggestField or PrefixCompletionQuery, so the repro does not compile [exec]. Correction to the finder's first take ('code since 5.2'): the backport reached branch_5x after branch_5_2 was cut
- Affected versions
- every release from 5.3.0 through 10.5.2 and main ea57360912ed; not fixed in any release or on upstream main or branch_10x as of 2026-10-26 [exec: the independent reproduction's public-API test fails 2 of 4 with identical numbers (apple|fruitcake 21.0, expected 3.0) and both controls pass on 5.3.0 (-ea, -da), 5.5.5, 6.0.0, 6.4.2, 6.5.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.3.1, 8.4.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3 (-ea, -da), 10.0.0, 10.5.2 (-ea, -da) and main (-ea, -da); the finder's test fails 2 of 3 on main, 10.5.2, 9.12.3, 8.11.4 and 6.6.6; read: the whitespace-normalized setNextMatch body and the boost-only contextMap.put line are identical in all 94 release tags 5.3.0 to 10.5.2 of the history clone]. Caveats: 8.8.2 to 8.11.3 are not tagged in the clone and are listed as affected because 8.8.1 [read] and 8.11.4 [exec] are; releases up to 7.7.3 ran on JDK 25 with a JUnit 4 runner, not the JVM they targeted (the controls pass in each run)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 124 recorded queries, namely the scripted prior-report search over apache/lucene issues and PRs (49), commits (6), downstream Elasticsearch, OpenSearch and Solr issues (5 generated plus 6 hand-written), the dev@, java-user@, issues@ and commits@ lists (32), the LUCENE JIRA archive (12) and the web (12), plus manual GitHub searches of apache/lucene and apache/lucene-solr; the changed files of all 413 open apache/lucene PRs (none touches ContextQuery.java, ContextSuggestField.java or TestContextQuery.java); local git history, CHANGES.txt and MIGRATE.md; 14 hits read and classified, none the same bug; the intended-behaviour check read the JIRA comments of LUCENE-6459, LUCENE-6702, LUCENE-6510 and LUCENE-8288 and the adjudication ran its own GitHub searches, also with no report); not fixed upstream (contextMap is still Map<IntsRef, Float> and the unconditional containsKey lookup is unchanged on upstream main; the last commits touching ContextQuery.java, 378ca8d1bbf on main and bf72c21a1c0 on branch_10x, do not touch the lookup); closest items, not reports: #9335 / LUCENE-8288 (open since 2018: regex '.' assertion in ContextCompletionWeight.setInnerWeight, a different defect and fix site), #9334 / LUCENE-8287 (empty RegexCompletionQuery assertion, fixed), #7569 / LUCENE-6510 (random context scoring test failure, a TopNSearcher queue fix; that test gives every indexed context an equal exact query context, so it cannot reach this bug), #7518 / LUCENE-6459 and #7760 / LUCENE-6702 (the introducing changes), #14169 (merged 2025-01, builds the context automaton once, does not touch the boost lookup)
- Lucene commit tested
- main
ea57360912ed(commit of 2026-10-24; tested 2026-10-26): this doc's test through gradle with seed DEADBEEF and-Ptests.asserts=trueandfalse; a plain-Java probe that prints every hit, on stock main and with the fix shadowed in; the fix in a scratch worktree atea57360912ed(the test, the closest suites, the whole suggest module with assertions on and off and a second seed, tidy andcheck -x test), removed afterwards. An independent test (public suggester API, lucene-test-framework helpers) on the Maven Central jars of 17 releases from 5.3.0 to 10.5.2 (5.3.0, 9.12.3 and 10.5.2 also with assertions off), on 5.3.0 with the fix ported, and on main; the follow-up re-ran the finder's, the independent reproducer's and the devil's advocate's tests with fresh seeds.
- Finding record
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:64-66 (at ea57360912ed) (class javadoc: 'To apply the same boost to multiple contexts sharing the same prefix, Use addContext(CharSequence, float, boolean) with the common context prefix, boost and set exact to false'), :71 (@lucene.experimental), :110-118 ('Adds an exact context with default boost of 1', 'Adds an exact context with boost'), :120-124 ('set exact to false if the context is a prefix of any indexed contexts')lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:204-210 (at ea57360912ed) (createWeight: contextMap.put(entry.getKey(), contextMetaData.boost) at :208 keeps only the boost, the exact flag is dropped), :211-212 (context lengths sorted descending)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:228-250 (at ea57360912ed) (toContextAutomaton: an exact context is followed directly by CONTEXT_SEPARATOR, :241-244, so filtering honours exactness), :252-259 (ContextMetaData: exact 'should be treated as an exact value or a context prefix')lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:285-306 (at ea57360912ed) (setNextMatch: 'longer context first' at :288-289; takes the longest contextMap key equal to pathPrefix[0:len] at :294-299 and never checks that CONTEXT_SEPARATOR follows; unknown context boost 0 at :302-305), :308-314 (setInnerWeight copies the whole indexed context, so the reported context is right), :339-341 (boost())lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionScorer.java:98-106 (at ea57360912ed) (score = weight * boost; boost 0 returns weight)lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestContextQuery.java:177 (at ea57360912ed) (testContextPrecedenceBoost: exact 'type' and 'typetype', each indexed context gets the boost of its equal query context), :236 (testEmptyContextWithBoosts), :311 (testMixedContextQuery: addAllContexts() plus exact boosts, unboosted contexts keep their weight), :524 (testRandomContextQueryScoring)
- The finding in 30 seconds
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:64-66, (at ea57360912ed) 110-124, 125-127 (boost >= 0), 140-149, 192-196 (optional SEP_LABEL), 204-212, 228-250, 252-259, 285-306, 308-331, 339-341lucene/suggest/src/java/org/apache/lucene/search/suggest/document/CompletionScorer.java:98-106; (at ea57360912ed) ContextSuggestField.java:49, 89-100, 151-156 (PrefixTokenFilter: context + separator); NRTSuggester.java:131-132, 221, 230-231, 245-252; CompletionWeight.java:80-82; FuzzyCompletionQuery.java:267-290 (fuzzy inner boost)
- Who is affected
lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestContextQuery.java:311 (at ea57360912ed) (testMixedContextQuery)lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:71 (at ea57360912ed) (@lucene.experimental)
- Why it looks unintended
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:64-66, (at ea57360912ed) 110-124, 146-149, 241-244, 252-259, 288-289lucene/suggest/src/test/org/apache/lucene/search/suggest/document/TestContextQuery.java:177 (at ea57360912ed) (testContextPrecedenceBoost), :236 (testEmptyContextWithBoosts), :311 (testMixedContextQuery), :524 (testRandomContextQueryScoring)
- Suggested fix
lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextQuery.java:128-139 (at ea57360912ed) (query contexts cannot contain CONTEXT_SEPARATOR); lucene/suggest/src/java/org/apache/lucene/search/suggest/document/ContextSuggestField.java:67, (at ea57360912ed) 82, 166-176 (indexed values and contexts neither)
- TestContextQueryExactContextBoost.java (JUnit test):
repro/LFV-254/src/org/apache/lucene/search/suggest/document/TestContextQueryExactContextBoost.java(54 lines)
The summary card (bug.png) walks table lamp's matched path through the boost lookup, shows expected against actual and the wider cases. The numbers come from probe runs on ea57360912ed.
assets/LFV-254/bug.png(489 KB)