The javadoc that documents the default term-vectors data file says three things about each chunk that the writer does the opposite of.
- Term vectors store, per document and field, the field's terms with their frequencies and, if enabled, positions, offsets and payloads. The default format buffers documents and writes them in chunks to the
.tvdfile; the.tvxindex points at each chunk. - A chunk starts with a small header: the first document, the document count, the number of fields per document, the field numbers present, which field each entry belongs to, and the Flags (positions, offsets, payloads) of the fields. Terms, frequencies, positions, offsets and the compressed term bytes follow.
- The class javadoc of
Lucene90TermVectorsFormatgives this layout as a grammar plus notes, and the default codec's file-format overview links it as the term-vector format. Lucene's own writer and reader do not read the javadoc; in normal indexing they agree with each other.
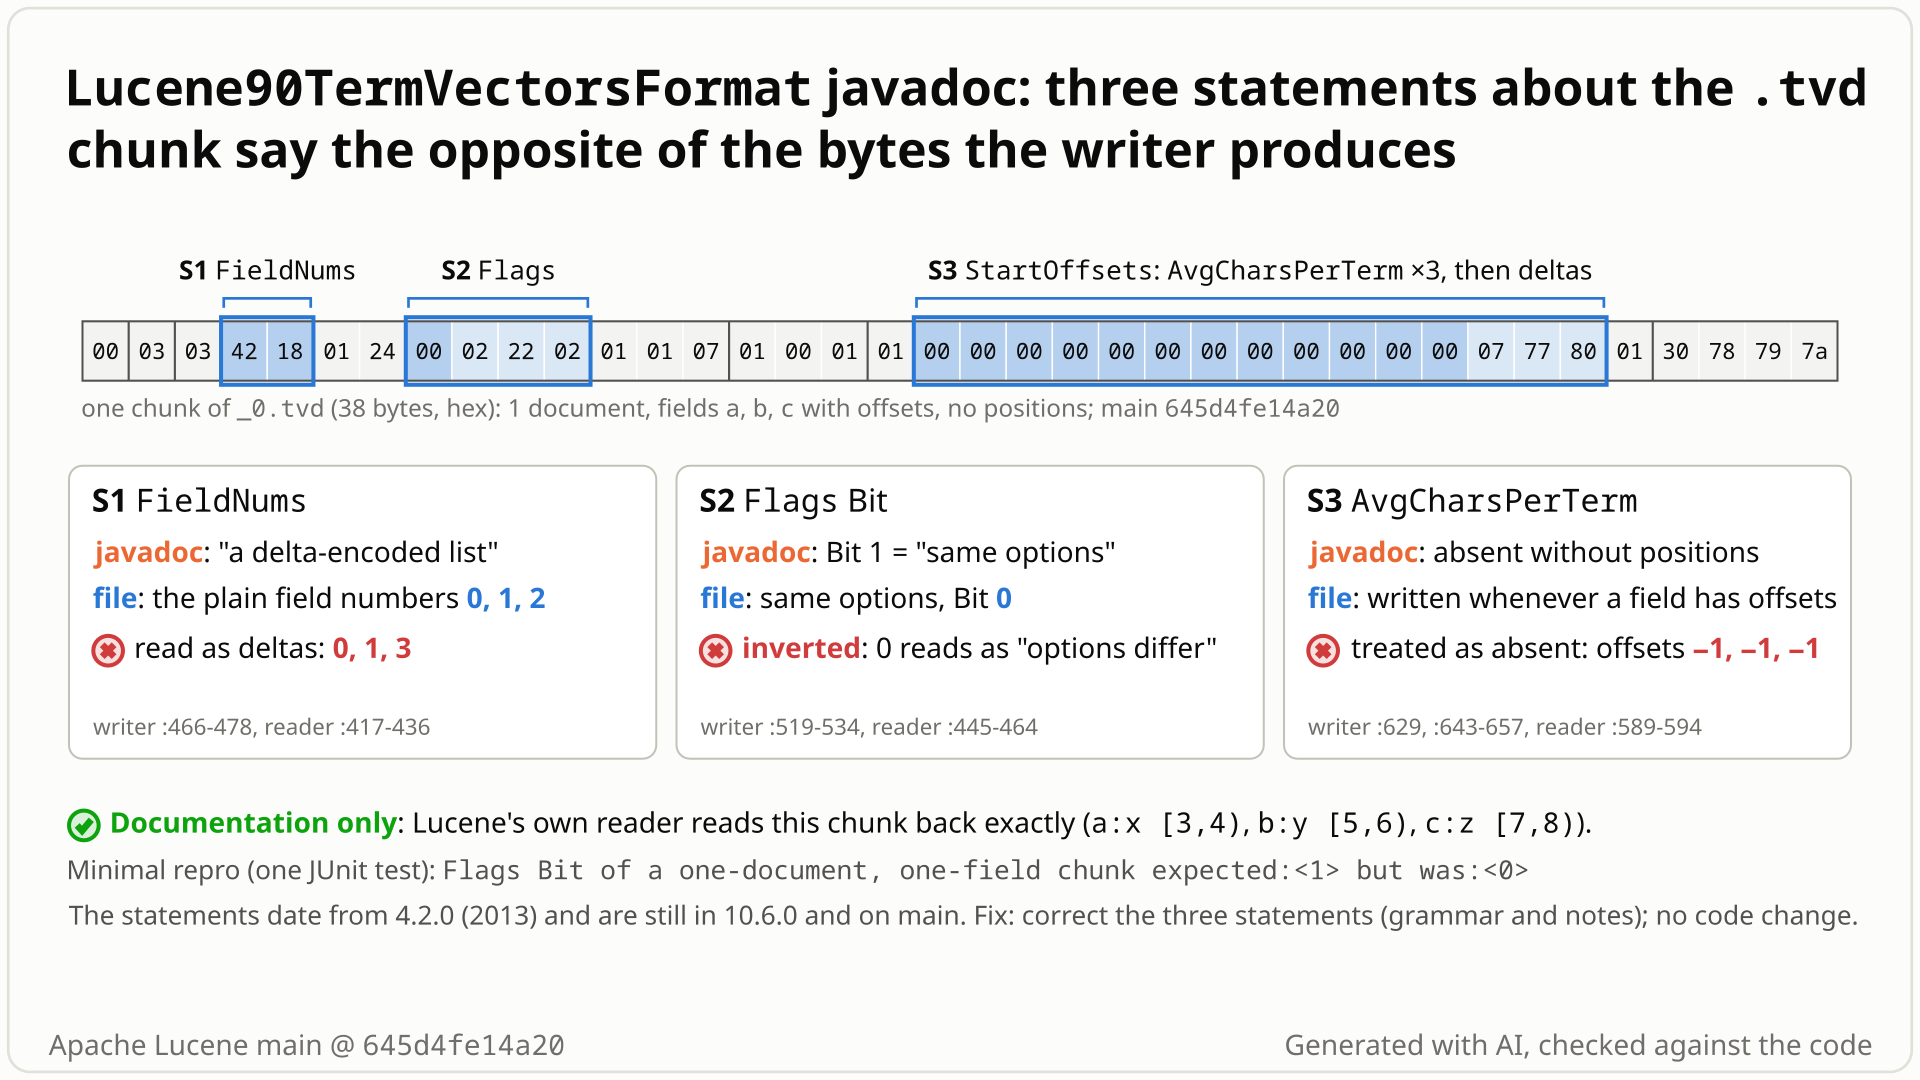
.tvd chunk next to the bytes the default codec writes, at the three places where they disagree. Select the still to open it at full size. Generated with AI, checked against the code.- You index one document with one term-vector field (
f= "x") with the default codec, and decode the one chunk of the 84-byte_0.tvdby following theLucene90TermVectorsFormatjavadoc, the format description the default codec's file-format docs link to. - The javadoc says the Flags Bit is 1 when every field has the same options in every document of the chunk (then one Flag per distinct field follows). One field in one document trivially qualifies, so you expect 1.
- Byte 56, the Flags Bit, is 0. The writer writes 0 for "same options" and 1 for "options change" (then one Flag per field instance), and Lucene's own reader agrees with the writer.
- Two more statements are wrong the same way: field numbers 1, 3, 6 are stored as 1, 3, 6, not as deltas (summed: 1, 4, 10); and offsets-only fields get AvgCharsPerTerm values the text says are absent (read without them, start offsets 3, 5, 7 come out as -1, -1, -1).
- In normal indexing Lucene reads its own files correctly. Only a person or tool decoding
.tvdfrom the javadoc is misled, in every release since 4.2.0 (2013).
People who read or re-implement the .tvd format from this javadoc. Contradicted by every chunk with term vectors (Flags), any chunk with two or more term-vector field numbers above 0 (FieldNums), and any chunk where some field has offsets and none has both positions and offsets (AvgCharsPerTerm). In normal indexing Lucene's writer and reader agree, so Lucene itself is unaffected.
Mechanism, terms and numbers841 words
The class javadoc of Lucene90TermVectorsFormat, the term-vectors format of the default codec, presents itself as "a more detailed description of the field data file format" (Lucene90TermVectorsFormat.java:80 on main 645d4fe14a20), and the default codec's file-format overview links it as the term-vector format. Three of its statements say the opposite of what Lucene90CompressingTermVectorsWriter writes and Lucene90CompressingTermVectorsReader reads: the Flags Bit is documented as 1 for "fields have the same options" (:90-92, :125-126) but the writer writes 0 for that and 1 otherwise (writer :519-534); FieldNums are documented as "a delta-encoded list" (:89, :119-120) but are the plain sorted field numbers (writer :466-478); and AvgCharsPerTerm is documented as absent "if no field has both positions and offsets enabled" (:143-144) but is written whenever any field of the chunk has offsets (writer :629, :643-657). In normal indexing the reader matches the writer on all three, so the wrong text breaks nothing at runtime (their one known disagreement, on the AvgCharsPerTerm condition, is the separate code bug LFV-244). The text came with LUCENE-4733 in 2013 for a writer that already did all three things the way it does today, and it has been in every release from 4.2.0 to 10.6.0 and on main.
| # | the javadoc says | what is on disk (writer, reader) |
|---|---|---|
| 1 | FieldFlags --> if Bit==1: Flag^TotalDistinctFields else Flag^TotalFields; "Bit in Flags is a single bit which when true means that fields have the same options for every document in the chunk" (:90-92, :125-126) | inverted: VInt 0 and one Flag per distinct field when the options do not change, VInt 1 and one Flag per field instance otherwise (writer :519-534; reader :445-461) |
| 2 | FieldNums --> FieldNumDelta^TotalDistincFields; "FieldNums is a delta-encoded list of the sorted unique field numbers present in the chunk" (:89, :119-120) | a token byte, then the plain sorted field numbers, packed (writer :466-478); no prefix sum on read (reader :417-436) |
| 3 | AvgCharsPerTerm values "are not present if no field has both positions and offsets enabled" (:143-144) | one value per distinct field whenever any field of the chunk has offsets (writer :629, :643-657), 0 for a field without both positions and offsets, and also when a field's position or start-offset sums are 0 (:630-639, :648-652); read whenever TotalOffsets > 0 (reader :589-594) |
One document, field f = "x", term vectors without positions or offsets, decoded with the reader's rules (_0.tvd is 84 bytes):
bytes 0-48   IndexHeader (codec "Lucene90TermVectorsData")
byte  49     DocBase 0
byte  50     ChunkDocs VInt 3 = (1 doc << 1) | dirty bit 1
byte  51     NumFields 1
byte  52     FieldNums token 0x01 (1 distinct field, 1 bit per field number)
byte  53     FieldNums: 00 (field number 0)
bytes 54-55  FieldNumOffs slice: length 1, 00
byte  56     Flags Bit = 0      <- the javadoc says 1 for "same options"
bytes 57-58 flags slice: length 1, 00 (one Flag per distinct field)- FieldNums: term-vector fields with field numbers 1, 3 and 6 are stored as
[1, 3, 6]; delta-decoding as the javadoc says gives[1, 4, 10]. - AvgCharsPerTerm: a document with three fields that have offsets but no positions (
xat 3-4,yat 5-6,zat 7-8). The javadoc says no AvgCharsPerTerm values are present; the file holds three 4-byte values. Decoding without them gives start offsets[-1, -1, -1]; skipping them gives the indexed[3, 5, 7].
flushFlagssetsnonChangingFlagswhen every field number has the same flags in every document of the chunk (writer:502-517), then writeswriteVInt(0)with the comment "write one flag per field num" (:520-531), elsewriteVInt(1), "write one flag for every field instance" (:532-545). The reader'scase 0reads one Flag per distinct field and expands it per field instance (:447-458);case 1reads one per instance (:459-461).flushFieldNumswrites a token byte(min(n - 1, 7) << 5) | bitsRequired(max)(:466-468), a VInt whenn - 1 >= 7(:469-471), thenwriter.add(fieldNum)for each sorted distinct field number (:472-478). The reader assignsfieldNums[i] = (int) it.next()(:435).flushOffsetssetshasOffsets |= fd.hasOffsetsover every field instance (:629), returns only when no field has offsets (:643-646), and writes oneFloat.floatToRawIntBits(charsPerTerm[i])per distinct field (:655-657). The reader reads them when TotalOffsets, the sum of term frequencies of fields with offsets, is > 0 (:553-566,:589-594). In normal indexing a term-vector field with no terms is not written (TermVectorsConsumerPerField.java:70), so the two conditions agree; they are shown to differ for a zero-term field fromaddIndexes(CodecReader...), the separate code bug LFV-244 (other ways to hand the writer a zero-term offsets field were not ruled out exhaustively).
Exposure and likelihood260 words
- Who is hit. Anyone who decodes a
.tvdfile without Lucene, or checks a codec change against the description, by following the class javadoc. The default codec's overview (lucene104/package-info.java) says it "defines the index file formats used in this version of Lucene" (:50), links this class for term vectors (:168,:293,:298) and says "Details on each of these are provided in their linked pages" (:188). - Default vs opt-in. The default codec writes this format (
Lucene104Codec.java:71); term vectors are opt-in per field. Which chunks contradict which statement: Flags, every chunk that holds term-vector fields (a chunk with none writes no Flags, writer:401-403); FieldNums, any chunk with two or more distinct term-vector field numbers above 0 (with one field, or field 0 and one other, the plain list and its delta encoding are the same bytes, as in the minimal repro's chunk); AvgCharsPerTerm, any chunk where some field has offsets and no field has both positions and offsets, e.g. one whose term-vector fields have offsets but no positions, a documented option thatBaseTermVectorsFormatTestCaseexercises (Options.OFFSETS). - Scale. The wrong text itself has no runtime effect. A parser that follows the text reads the Flags with the wrong layout, sums plain field numbers as deltas, and loses alignment on chunks with offsets but no positions (all executed). The audience is small and no earlier report was found in the recorded searches, which keeps the impact minor.
- Rating. Impact class minor, likelihood plausible, priority low.
One JUnit test, no reflection: index one document with one term-vector field (f = "x"), walk the .tvd chunk with the reader's rules up to the Flags Bit, and compare it with the javadoc. It checks the plainest of the three statements. Single thread, seed fixed, about 1.4 s; the same with assertions off and on 10.6.0.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.lucene90;

import org.apache.lucene.codecs.CodecUtil;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.SegmentInfos;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.store.IOContext;
import org.apache.lucene.store.IndexInput;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;
import org.apache.lucene.util.packed.PackedInts;

public class TestTermVectorsFormatJavadocFlagsBit extends LuceneTestCase {

  public void testSameOptionsChunkHasFlagsBitOne() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      IndexWriterConfig iwc =
          new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()).setUseCompoundFile(false);
      try (IndexWriter w = new IndexWriter(dir, iwc)) {
        FieldType ft = new FieldType(TextField.TYPE_NOT_STORED);
        ft.setStoreTermVectors(true);
        Document doc = new Document();
        doc.add(new Field("f", "x", ft));
        w.addDocument(doc);
      }
      String segment = SegmentInfos.readLatestCommit(dir).info(0).info.name;
      try (IndexInput in = dir.openInput(segment + ".tvd", IOContext.READONCE)) {
        in.seek(CodecUtil.indexHeaderLength("Lucene90TermVectorsData", ""));
        in.readVInt();
        in.readVInt();
        in.readVInt();
        int token = in.readByte() & 0xFF;
        in.skipBytes(
            PackedInts.Format.PACKED.byteCount(
                PackedInts.VERSION_CURRENT, (token >>> 5) + 1, token & 0x1F));
        in.skipBytes(in.readVLong());
        // javadoc: Flags Bit is 1 when all fields have the same options in the chunk; written: 0
        assertEquals("Flags Bit of a one-document, one-field chunk", 1, in.readVInt());
      }
    }
  }
}
cp TestTermVectorsFormatJavadocFlagsBit.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestTermVectorsFormatJavadocFlagsBit -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
- The javadoc says the Flags Bit is 1 when all fields have the same options, so a one-document, one-field chunk holds Bit 1.
- Observed
Flags Bit of a one-document, one-field chunk expected:<1> but was:<0>; the same with assertions off and on 10.6.0.
More files, environment, full output285 words
The default codec is pinned, compound files are off, and the test builds a plain IndexWriterConfig and a ByteBuffersDirectory rather than the framework's randomized ones, so the bytes under test are fixed by the test itself; the test framework still randomizes unrelated state such as the locale and time zone, and the commands fix the seed. Besides the test framework, the test uses the @lucene.internal PackedInts helper, only to compute how many bytes to skip. The three readVInt() calls skip DocBase, ChunkDocs and NumFields; the next lines skip the FieldNums token and packed field numbers, then the length-prefixed FieldNumOffs slice. The codec name Lucene90TermVectorsData is the one the format passes to its superclass (Lucene90TermVectorsFormat.java:170).
The other two statements (FieldNums, AvgCharsPerTerm) are shown by the earlier, longer tests of the finder and the independent reproducer, which fail on main 645d4fe14a20 with assertions on and off; they are left out of the repro on purpose.
On 9.0.0 the test-framework imports are org.apache.lucene.util.LuceneTestCase and org.apache.lucene.util.TestUtil (moved to org.apache.lucene.tests.* in 9.1.0).
As a regression test: none is needed for a javadoc-only fix, and this test cannot guard the javadoc (it transcribes the text). If a reviewer wants the corrected statement pinned down, it is this same test with expected value 0.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the same test also fails on the published 10.6.0 jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestTermVectorsFormatJavadocFlagsBit.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/lucene90/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.lucene90.TestTermVectorsFormatJavadocFlagsBit -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
TestTermVectorsFormatJavadocFlagsBit > testSameOptionsChunkHasFlagsBitOne FAILED
    java.lang.AssertionError: Flags Bit of a one-document, one-field chunk expected:<1> but was:<0>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:CCC0AE82C6CD4BB0]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:647)
        at org.apache.lucene.codecs.lucene90.TestTermVectorsFormatJavadocFlagsBit.testSameOptionsChunkHasFlagsBitOne(TestTermVectorsFormatJavadocFlagsBit.java:60)

1 test completed, 1 failed- The javadoc states bit-level facts (
if Bit==1: Flag^TotalDistinctFields), and the writer does the reverse; its own comments say "one flag per field num" for 0. - It never matched: the writer it describes was committed 12 days earlier with today's encoding for all three points.
- "High-level" and
@lucene.experimentalallow omissions and future changes, not a wrong description of the current bytes.
The full argument178 words
- Inverted, not simplified.
if Bit==1: Flag^TotalDistinctFieldsand "when true means that fields have the same options" (:91-92,:125-126) state the opposite of the writer, whose comments read "write one flag per field num" for 0 (:520) and "write one flag for every field instance" for 1 (:533). - Wrong from the start. LUCENE-4599 (
5837fe83bd8, 2013-01-21) wrote the writer; LUCENE-4733 (94b17a28de5/e3710747d87, 2013-02-02) added the description; the writer file is byte-identical between the two, so the text never described a committed encoding. Not a regression. - The page presents itself as the detailed description: "Here is a more detailed description of the field data file format" (
:80); the default codec's overview sends readers there for the details (package-info.java:50,:188). - Precedent. LUCENE-713 (#1788, 2006, "File Formats Documentation is not correct for Term Vectors") fixed an error in the old term-vector format docs; #129 (2021) re-synced this javadoc with a format change. No test, CHANGES or MIGRATE entry or discussion calls these statements known or non-normative.
The devil's-advocate check221 words
Strongest case for "intended" (the devil's-advocate verifier and the cross-model reviewers): the overview "attempts to provide a high-level definition of the Apache Lucene file formats" (package-info.java:54); the class is @lucene.experimental (Lucene90TermVectorsFormat.java:164); the description is incomplete anyway (no FieldNums token byte, no DirectWriter slice length prefixes, no dirty bit in ChunkDocs), so nobody could write a reader from it alone; the author of #130 remarked that "few people care about the format documentation"; and in normal indexing the writer and reader agree. The refute-lens reviewer rated this moderate, for the encoding only.
Why it fails: "high-level" covers leaving details out, not a statement whose polarity is inverted. @lucene.experimental permits incompatible future changes, "not inaccurate documentation of the current release" (the intended-lens reviewer, who rated the argument weak). "Few people care" explains why nobody noticed; it does not make the text right. Writer/reader agreement in normal indexing is why this is a documentation defect, not a code bug (their one known disagreement, LFV-244, is a separate code bug). The incompleteness argument does shape the claim: it is only that these three statements are wrong, not that a reader built from the javadoc must fail. The reproducer, the devil's advocate and the adjudication all kept the defect, and the separate re-runs of the finder's test for the cross-model reviews failed.
Recommended A. Correct the three statements and the TotalDistincFields typo on the edited line (validated: build and tests only; the new text checked by reading)
Javadoc only: if Bit==0: Flag^TotalDistinctFields, Bit 0 meaning the options do not change; FieldNums are the plain sorted field numbers; AvgCharsPerTerm is present if any field has offsets. Built and tested (the test with expected 0 and TestLucene90TermVectorsFormat pass, check -x test is clean); no test reads the javadoc, so the text was checked by reading the code.
All options and trade-offs3 options · 966 words
One option was written, built and tested (no test reads the javadoc); a wider cleanup is listed as option B. The AvgCharsPerTerm sentence depends on LFV-244, the code bug on the same condition: if its fix makes the writer follow the reader, the sentence should say "present when TotalOffsets is greater than 0" instead (in normal indexing both say the same). Open PR #16480 (per-chunk checksums) changes the term-vectors writer and reader but not this javadoc; open PR #1003 touches only the file's import and constructor.
A. Correct the three statements and the TotalDistincFields typo on the edited line (validated: build and tests only; the new text checked by reading) (recommended)
Javadoc only, one file, 7 lines in and 7 out: FieldNums --> FieldNum^TotalDistinctFields; FieldFlags --> if Bit==0: ...; "FieldNums is the list of the sorted unique field numbers present in the chunk"; "Bit in Flags is 0 when fields have the same options for every document in the chunk, and 1 otherwise"; "They are present if any field of the chunk has offsets enabled, and are 0 for a field that does not have both positions and offsets". The new text matches what normal indexing writes and reads and the writer's presence condition; on the LFV-244 path the writer and reader disagree on that condition. The last clause states when the value is certainly 0, not every case: the writer also writes 0 when a field's sum of positions or of start offsets is 0 (writer :648-652, e.g. one token at position 0, start offset 0); it agrees with the existing StartOffsetDelta note ("AvgCharsPerTerm is 0 if the field has no positions"), a sufficient condition in the same way. If a reviewer wants the exact rule, drop the clause or say "for example".
diff --git a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java
index e19168ff95d..d45a9fbfda2 100644
--- a/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java
+++ b/lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java
@@ -86,9 +86,9 @@ import org.apache.lucene.util.packed.PackedInts;
* TermFreqs >, < Positions >, < StartOffsets >, < Lengths >, <
* PayloadLengths >, < TermAndPayloads >
* <li>NumFields --> DocNumFields<sup>ChunkDocs</sup>
- * <li>FieldNums --> FieldNumDelta<sup>TotalDistincFields</sup>
+ * <li>FieldNums --> FieldNum<sup>TotalDistinctFields</sup>
* <li>Flags --> Bit < FieldFlags >
- * <li>FieldFlags --> if Bit==1: Flag<sup>TotalDistinctFields</sup> else
+ * <li>FieldFlags --> if Bit==0: Flag<sup>TotalDistinctFields</sup> else
* Flag<sup>TotalFields</sup>
* <li>NumTerms --> FieldNumTerms<sup>TotalFields</sup>
* <li>TermLengths --> PrefixLength<sup>TotalTerms</sup>
@@ -116,14 +116,13 @@ import org.apache.lucene.util.packed.PackedInts;
* <li>DocBase is the ID of the first doc of the chunk.
* <li>ChunkDocs is the number of documents in the chunk.
* <li>DocNumFields is the number of fields for each doc.
- * <li>FieldNums is a delta-encoded list of the sorted unique field numbers present in the
- * chunk.
+ * <li>FieldNums is the list of the sorted unique field numbers present in the chunk.
* <li>FieldNumOffs is the array of FieldNumOff; array size is the total number of fields in
* the chunk.
* <li>FieldNumOff is the offset of the field number in FieldNums.
* <li>TotalFields is the total number of fields (sum of the values of NumFields).
- * <li>Bit in Flags is a single bit which when true means that fields have the same options
- * for every document in the chunk.
+ * <li>Bit in Flags is 0 when fields have the same options for every document in the chunk,
+ * and 1 otherwise.
* <li>Flag: a 3-bits int where:
* <ul>
* <li>the first bit means that the field has positions
@@ -141,7 +140,8 @@ import org.apache.lucene.util.packed.PackedInts;
* difference with the previous positions for following positions.
* <li>TotalOffsets is the sum of frequencies of terms of all fields that have offsets.
* <li>AvgCharsPerTerm is the average number of chars per term, encoded as a float on 4
- * bytes. They are not present if no field has both positions and offsets enabled.
+ * bytes. They are present if any field of the chunk has offsets enabled, and are 0 for
+ * a field that does not have both positions and offsets.
* <li>StartOffsetDelta is the (startOffset - previousStartOffset - AvgCharsPerTerm *
* PositionDelta). previousStartOffset is 0 for the first offset and AvgCharsPerTerm is
* 0 if the field has no positions.
Trade-offs
None at runtime: no bytes, behaviour or format version change. It corrects only these three statements and is not a complete correction of the .tvd description: the other stale lines (option B) stay as they are.
What the checks validated
Scratch worktree of 645d4fe14a20, seed DEADBEEF, 2026-11-01, removed afterwards:
- stock: the minimal repro fails with assertions on and off;
- with the fix: the same test with expected value 0 passes with assertions on and off; the verbatim repro still fails with the same message, as it must (the fix changes no bytes);
TestLucene90TermVectorsFormat: 21 tests, 0 failures;:lucene:core:check -x test(google-java-format, ecj lint, forbidden APIs) succeeds with only the javadoc file changed.- no test reads the javadoc, so these runs show only that the edit is clean and changes no bytes; that the new text is right is a code-reading conclusion; the javadoc was not rendered to HTML (
renderJavadocnot run).
ChunkDocs is written as (docs << 1) | dirtyBit since LUCENE-9935 (#140; a 2-document chunk stores 5); FieldNumOffs, Flags and FieldNumTerms are DirectWriter slices with a length prefix since LUCENE-9907 (#72), not PackedInts arrays or "blocks of 64 packed ints"; FieldNums is preceded by a token byte (min(n - 1, 7) << 5) | bitsRequired(max) (plus a VInt when n - 1 >= 7); "DocNumFields (with ChunkDocs>=1)" should say >1 (typo from #130); Bit is written as a VInt; AvgCharsPerTerm is listed as an Int but holds raw float bits.
Trade-offs
A byte-accurate description, but a larger diff for reviewers to check against more code. Not written as a diff and not built or tested here.
It keeps three sentences that state the opposite of the bytes.
Trade-offs
No work, but the page would still mislead the people it is written for.
Not security-sensitive; it matters only to third-party tools that decode .tvd files themselves from this javadoc.
Code reading: while a file:line table was written for an SMT (Z3) model of the term-vector offsets encoding, the javadoc read next to the writer showed three mismatches; one written chunk was then parsed byte by byte to confirm them. The model encodes the code, not the javadoc, so it gave no signal itself.
The method in full126 words
- The hunt unit modelled the term-vector offsets encoding of the default format in Z3 and listed, for each modelled step, the code line it came from. Reading the javadoc next to the writer for that table showed the three statements.
- The finder's JUnit indexes one document with three fields that have offsets but no positions (one term each), parses the single
.tvdchunk byte by byte and checks all three statements; its implicit control is that skipping the AvgCharsPerTerm values decodes the indexed start offsets[3, 5, 7]. It failed on main with assertions on and off, on 10.5.2 and on 9.12.3. - This is a documentation check against real output, not model checking or a proof: the formal model gave no signal on the javadoc.
No prior public report was found in GitHub issues, PRs and commits, the JIRA archive, the mailing lists, downstream projects or the web (searched 2026-10-26, rechecked 2026-11-01). Nearest: LUCENE-4733 (#5798), which wrote the text, and the 2021 edits #129 and #130, which kept it. Not fixed upstream.
Searches2 searches
- Related, not this bug: #5798 (LUCENE-4733, wrote the text; nobody questioned it); #129 (LUCENE-9456) and #130, the 2021 edits that kept the statements; #1788 (LUCENE-713, a different term-vector format doc error, fixed in 2006: precedent); #5664 (LUCENE-4599, the writer's design discussion, "flag stored only once per distinct field", which matches the code); #10744 / apache/lucene-solr#2334 (LUCENE-9705, copied the text into
Lucene90TermVectorsFormat); #72 and #140, the origin of the secondary staleness. - Coordination, not prior art: open PR #16480 (another contributor's per-chunk CRC32C) changes the term-vectors writer and reader, not this javadoc; open #10120 (LUCENE-9078) would remove per-document term-vector options; open PR #1003 touches only the file's import and constructor, not the javadoc.
- Not fixed upstream: on 2026-11-01 the file is byte-identical on upstream main,
branch_11x,branch_10_6andbranch_9_12; its last change is #130 (2021). Tracking issue #16937 does not name it.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene and apache/lucene-solr issues, PRs and commits; the JIRA archive; downstream repositories; dev@, java-user@, issues@ and commits@ | 2026-10-26 | two scripted prior-report searches plus two list and JIRA runs (469 hits, every medium hit read); about 60 manual GitHub searches on the identifiers and exact javadoc phrases; the changed files of all 413 open PRs; git log -S on every phrase in the full history; 4 web searches | no report; only the commits that wrote, copied or re-laid out the text |
| apache/lucene (recheck) | 2026-11-01 | the file's blob on upstream main, branch_11x, branch_10_6 and branch_9_12; issues and PRs updated since 2026-10-26 for 7 terms; open PRs by changed files (the first 200 in the brief's recheck, then all 409, the three with over 100 files in full); tracking issue #16937 | nothing new; the file is unchanged, and no open PR changes its javadoc (open PR #1003 touches only its import and constructor) |
Wrong since it was written: LUCENE-4733 (2013-02-02) added the text for a writer that already wrote today's encoding. First release 4.2.0; copied into the Lucene50 (5.0.0) and Lucene90 (9.0.0) formats and kept by the 2021 edits; affects every release to 10.6.0 and main.
Versions tested9 rows
- Writer: LUCENE-4599 (
5837fe83bd8trunk /4a62a579a70branch_4x, #5664, 2013-01-21), with today's behaviour for all three points and no detailed format javadoc. - Text: LUCENE-4733 (
94b17a28de5trunk, svn r1441732 /e3710747d87branch_4x, svn r1441760, #5798, 2013-02-02, by jpountz; a JIRA patch, no PR) added the description toLucene42TermVectorsFormat. The writer file is byte-identical between the two commits. The nameFieldNumDeltais older: it is in the term-vector format docs of 2004 (12eee6df5a9), from a format that did delta-encode field numbers; that it was inherited is an inference from the code. - Copied:
Lucene50TermVectorsFormat(LUCENE-5969,33bdf278cba, 5.0.0) andLucene90TermVectorsFormat(LUCENE-9705,f8be421ae1f, apache/lucene-solr#2334, 9.0.0). Re-laid out without correction by #129 (LUCENE-9456,891b192dcff) and #130 (6ebf959502c) in May 2021, sogit blameon main points at #130 for most of these lines (:89,:119-126,:143-144); the Flags grammar (:90-92) blames to the 2020 reformatting2d6ad2fee6d(LUCENE-9570). - Later code changes that also left the text behind (not part of the claim): LUCENE-9907 (#72) length-prefixed DirectWriter slices; LUCENE-9935 (#140) the dirty bit in ChunkDocs.
- Read: all 119 release tags from 4.2.0 to 10.5.2 carry the three statements and the unchanged writer lines (the writer lines read at all 119 by the 2026-11-01 fact check); 8.8.2-8.11.3 are inferred from 8.8.1 and 8.11.4. The javadoc file is byte-identical on 9.0.0, 10.5.2, 10.6.0 and main.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails with assertions on and off (in a separate re-run and through gradle); the finder's test fails; the reproducer's test fails 4 of 6, controls pass |
10.6.0 (published jars, 4ae946e5a9b) | affected | the minimal test fails |
main a9779ef3c193, ea57360912ed | affected | the finder's and the reproducer's tests fail |
| 10.5.2, 9.12.3 | affected | the finder's and the reproducer's tests fail |
| 10.0.0, 9.0.0 | affected | the finder's test fails (9.0.0 with the 9.0 imports) |
8.11.4 (Lucene50TermVectorsFormat) | affected | the history probe: all 3 statements contradicted, reader-rule control passes |
4.10.4, 4.2.0 (Lucene42TermVectorsFormat) | affected | the history probe: all 3 contradicted, control passes |
| 4.1.0 | not affected | not affected: no compressing term-vectors format, nothing to describe |
| main with fix A | fix | the test with expected value 0 passes; TestLucene90TermVectorsFormat passes |
Confirmed (high confidence) by an independent reproducer, an intended-behaviour devil's advocate and an adjudication. Of the cross-model reviews (OpenAI GPT-5.6), the works-as-designed review called it real; the refute review could not run Java and returned a procedural "not real". Re-verified on main 645d4fe14a20; this doc re-ran the repro and built and tested the fix.
Checks and verdicts330 words
Every check either re-ran a test on main or read the same lines; none found a reading under which the three statements are right.
| Check | Verdict | What it found |
|---|---|---|
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real, low confidence, procedural | The reviewer could not run Java and called its verdict "not a substantive refutation": the source evidence "strongly supports a genuine documentation-only defect". Intended argument moderate, for the encoding only. A re-run of the finder's test failed. |
| independent reproducer | real (doc) | Its own test (no reflection or shadow classes) decodes one chunk with the reader's rules except the element under test: 6 run, 4 failed on main (assertions on and off), 10.5.2 and 9.12.3 (Flags both directions, FieldNums [1, 3, 6] vs [1, 4, 10], AvgCharsPerTerm, and an extra ChunkDocs check); both controls pass. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6, reading only) | real, medium | Intended argument weak: "experimental status permits later incompatible changes, not inaccurate documentation of the current release". A separate run re-ran the finder's test with assertions on and off: fail. |
| intended-behaviour devil's advocate | real (doc, minor, high) | Re-ran the finder's test on main; examined and rejected the "high-level", @lucene.experimental, "few people care" and writer/reader-agreement readings. |
| adjudication | confirmed, high confidence (doc) | Re-ran the reproducer's test with assertions on and off (4 of 6 failed each, controls pass) and checked the writer, reader and javadoc lines. |
re-verification on main 645d4fe14a20 | still reproduces | After #16919 touched the reader's flags switch: the finder's test fails 1 of 1 and the reproducer's 4 of 6, with assertions on and off, same messages. |
| this doc (2026-11-01) | reproduced; fix built and tested | The minimal test fails on main (assertions on and off, in a separate re-run and through gradle) and on 10.6.0; a byte probe shows the chunk layout; fix A built and tested (no test reads the javadoc, so the new text was checked by reading). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 351 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,359 words
- Registry title
- The file-format javadoc of the default term-vectors format (Lucene90TermVectorsFormat) contradicts the .tvd bytes in three places: the Flags bit meaning is inverted, FieldNums are called delta-encoded but are the plain field numbers, and AvgCharsPerTerm is called absent without positions but is written whenever a field has offsets (documentation defect; the writer and reader agree)
- Area
- codecs / term vectors (Lucene90TermVectorsFormat .tvd file-format javadoc vs Lucene90CompressingTermVectorsWriter / Reader)
- Priority
- Low, rank 1287: The default term-vectors format javadoc contradicts the .tvd bytes while the writer and reader agree, a documentation-only defect for format re-implementers.
- Impact class
- minor
- Impact note
- Documentation only: in normal indexing Lucene's writer and reader agree and round-trip exactly, so indexing, merging, CheckIndex and term-vector retrieval are unaffected by the wrong text (their one known disagreement, on a zero-term field from addIndexes, is the separate code bug LFV-244); the people misled are those who read, inspect or re-implement the .tvd format from the javadoc of the default term-vectors format (the default codec's package docs link to it as the format description), and a parser that follows the text reads the Flags with the wrong layout, sums plain field numbers as deltas and loses alignment on chunks with offsets but no positions (all executed); the text has been in every release since 4.2.0 (2013), no scale or special setting is needed.
- Summary
- You decode a .tvd chunk of the default term-vectors format by following its javadoc, which says the Flags Bit is 1 when all fields of the chunk have the same options, that FieldNums is a delta-encoded list, and that AvgCharsPerTerm is absent unless some field has both positions and offsets. The writer does the opposite on all three: it writes 0 for 'same options' (then one flag per distinct field) and 1 otherwise, it stores the plain sorted field numbers (fields 1, 3, 6 are stored as 1, 3, 6, which summed as deltas give 1, 4, 10), and it writes one AvgCharsPerTerm value per distinct field whenever any field has offsets, so a parser built from the text misreads the chunk. Lucene's own reader matches the writer, so nothing breaks at runtime; only the documentation is wrong, and it has been since it was written in 2013.
- Introduced
- 94b17a28de5280a2963ed70a8f5d3a8ee0590cd6 (trunk, svn r1441732) / e3710747d87ad6b89341d1f7de57577c0b301a89 (branch_4x, svn r1441760), LUCENE-4733 'Make CompressingTermVectorsFormat the new default term vectors format' (now apache/lucene#5798; JIRA patch LUCENE-4733-javadocs.patch, no GitHub PR), by jpountz [read: git log -S and git diff in the full-history clone; exec: 4.1.0 has no such class, 4.2.0 fails]. The writer it describes came 12 days earlier (5837fe83bd8 trunk / 4a62a579a70 branch_4x, LUCENE-4599, apache/lucene#5664) and is byte-identical at 94b17a28de5, with today's encoding for all three statements, so the text never matched a committed encoding; not a regression. The text was copied unchanged into Lucene50TermVectorsFormat (33bdf278cba, LUCENE-5969, 5.0.0) and Lucene90TermVectorsFormat (f8be421ae1f, LUCENE-9705, apache/lucene-solr#2334, 9.0.0), and re-laid out without correction by 891b192dcff (apache/lucene#129, LUCENE-9456) and 6ebf959502c (apache/lucene#130), so git blame on main points at #130. 'FieldNumDelta' predates LUCENE-4733 (term-vector format docs of 12eee6df5a9, 2004); that the name was inherited is an inference from the code (2013-02-02)
- First affected version
- 4.2.0 [exec] (Lucene42TermVectorsFormat: the version-specific byte-level probe finds all 3 statements contradicted and its reader-rule control passes; 4.1.0 has neither CompressingTermVectorsFormat nor Lucene42TermVectorsFormat [exec], so the format and its description did not exist); 9.0.0 [exec] for Lucene90TermVectorsFormat
- Affected versions
- every release from 4.2.0 through 10.6.0 and main ea57360912ed through 645d4fe14a2 [exec 2026-10-29 on 645d4fe14a2, -ea and -da; exec 2026-11-01: the minimal test fails on the published 10.6.0 jars, -ea]; not fixed upstream [exec: follow-up probes fail on 4.2.0 and 4.10.4 (Lucene42TermVectorsFormat) and 8.11.4 (Lucene50TermVectorsFormat), the finder's JUnit fails on 9.0.0 (import variant), 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), the independent reproduction's JUnit fails 4 of 6 (2 controls pass) on main (-ea and -da), 10.5.2 and 9.12.3; read: all 119 release tags 4.2.0-10.5.2 in the history clone carry all three statements and the unchanged writer decision lines, and the 8.11.4 sources jar does too]. Caveats: 8.8.2-8.11.3 are not in the clone and are counted as affected by inference from 8.8.1 [read] and 8.11.4 [exec]; upstream main, branch_10x, branch_10_6 and branch_9_12 hold the same file blob as main ea57360912ed (GitHub API, 2026-10-26); all runs used JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (searched 2026-10-26: a scripted prior-report search over GitHub issues, PRs and commits, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and downstream repositories (2 runs plus 2 list/JIRA runs; 469 hits, all medium hits read), about 60 manual GitHub searches on identifiers and exact javadoc phrases, all 413 open PRs enumerated by changed files, git log -S on every phrase in the history clone, 4 web searches; the intended-behaviour check's and the finder's earlier searches found nothing either). Nearest items, not the same bug: #5798 / LUCENE-4733 (introduced the text, nobody questioned it), #129 and #130 (2021 edits that kept the statements), #1788 / LUCENE-713 (a different term-vector format doc error, fixed 2006; precedent). Coordination, not prior art: open PR #16480 (by others) adds a per-chunk CRC32C to term-vector chunks without touching this javadoc; open #1003 touches only the file's import and constructor; open #10120 / LUCENE-9078 would remove per-document term-vector options, which would change the Flags section. Not fixed on upstream main or branch_10x.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28) with assertions on and off, in a separate re-run and through gradle, and the published 10.6.0 jars (this doc's runs, 2026-11-01); earlier runs of the finder's and the independent reproducer's tests on main645d4fe14a20,a9779ef3c193andea57360912ed, 10.5.2, 10.0.0, 9.12.3 and 9.0.0, and of the history probes on 8.11.4, 4.10.4 and 4.2.0 (4.1.0: the format does not exist).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java:80 ('a more detailed description of the field data file format'), :89 (FieldNumDelta, typo TotalDistincFields), :90-92 (if Bit==1: Flag^TotalDistinctFields), :105-111 (encodings, 'ChunkDocs>=1'), :117 (ChunkDocs is the number of documents), :119-120 (delta-encoded list), :125-126 (Bit true means same options), :143-147 (AvgCharsPerTerm presence rule), :164 (@lucene.experimental), :166-172 (constructor-only class body)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java:396-398 (ChunkDocs written as (chunkDocs << 1) | dirtyBit), :464-478 (token byte, then the plain sorted field numbers), :519-534 (writeVInt(0) and one flag per distinct field when flags do not change, else writeVInt(1) and one flag per field instance), :629 (hasOffsets |= fd.hasOffsets), :643-657 (AvgCharsPerTerm written per distinct field whenever hasOffsets)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsReader.java:381 (ChunkDocs >>> 1), :417-436 (field numbers read without prefix sum), :445-461 (case 0 per distinct field, case 1 per instance), :587-592 (AvgCharsPerTerm read when totalOffsets > 0)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java:168, :293, :298 (the default codec's package docs link Lucene90TermVectorsFormat as the term-vector format) and Lucene104Codec.java:71 (the default codec uses it)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsReader.java:445-464 on main 645d4fe14a2 (flags VInt :445, case 0 :447-458 per distinct field, case 1 :459-461 per instance, default :462-464 IllegalStateException since #16919), :589-594 (AvgCharsPerTerm read)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java (lines 80, 82-99, 105-111, 117-126, 142-147, 164, 170)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java (lines 385-427, 454-481, 483-498, 500-546, 623-657)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsReader.java (lines 380-381, 417-436, 445-464, 553-566, 589-594)lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumerPerField.java (line 70)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 54, 168, 188, 293, 298)lucene/core/src/java/org/apache/lucene/codecs/lucene104/Lucene104Codec.java (line 71)lucene/test-framework/src/java/org/apache/lucene/tests/index/BaseTermVectorsFormatTestCase.java (lines 93-94: Options.OFFSETS)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/lucene90/Lucene90TermVectorsFormat.java (lines 80, 89-92, 119-120, 125-126, 143-144, 164)lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java (lines 519-534: comments at 520 and 533)lucene/core/src/java/org/apache/lucene/codecs/lucene104/package-info.java (lines 50, 54, 188)
- Suggested fix
lucene/core/src/java/org/apache/lucene/codecs/lucene90/compressing/Lucene90CompressingTermVectorsWriter.java (lines 397-398, 466-471, 496, 521, 530, 534, 655-657)
- TestTermVectorsFormatJavadocFlagsBit.java (JUnit, one class, one method):
repro/LFV-255/src/org/apache/lucene/codecs/lucene90/TestTermVectorsFormatJavadocFlagsBit.java(64 lines)
Made from the code at 645d4fe14a20, the byte probe of the repro's index and the executed tests, in parallel with this doc.
assets/LFV-255/bug.png(351 KB)