The highlighter keeps a field's best passages in a java.util.PriorityQueue. Once the queue holds maxPassages entries, each new passage is compared with the weakest one, peek(). For 0 that test is already true while the queue is empty, and peek() is null.
- The UnifiedHighlighter cuts a field's text into passages (by default, sentences), scores each passage that contains a query match, and joins the best ones into the snippet.
maxPassagesis how many of those passages a snippet may use.highlight,highlightFields(one count per field) andhighlightWithoutSearchertake it as a plainintwith no documented range.
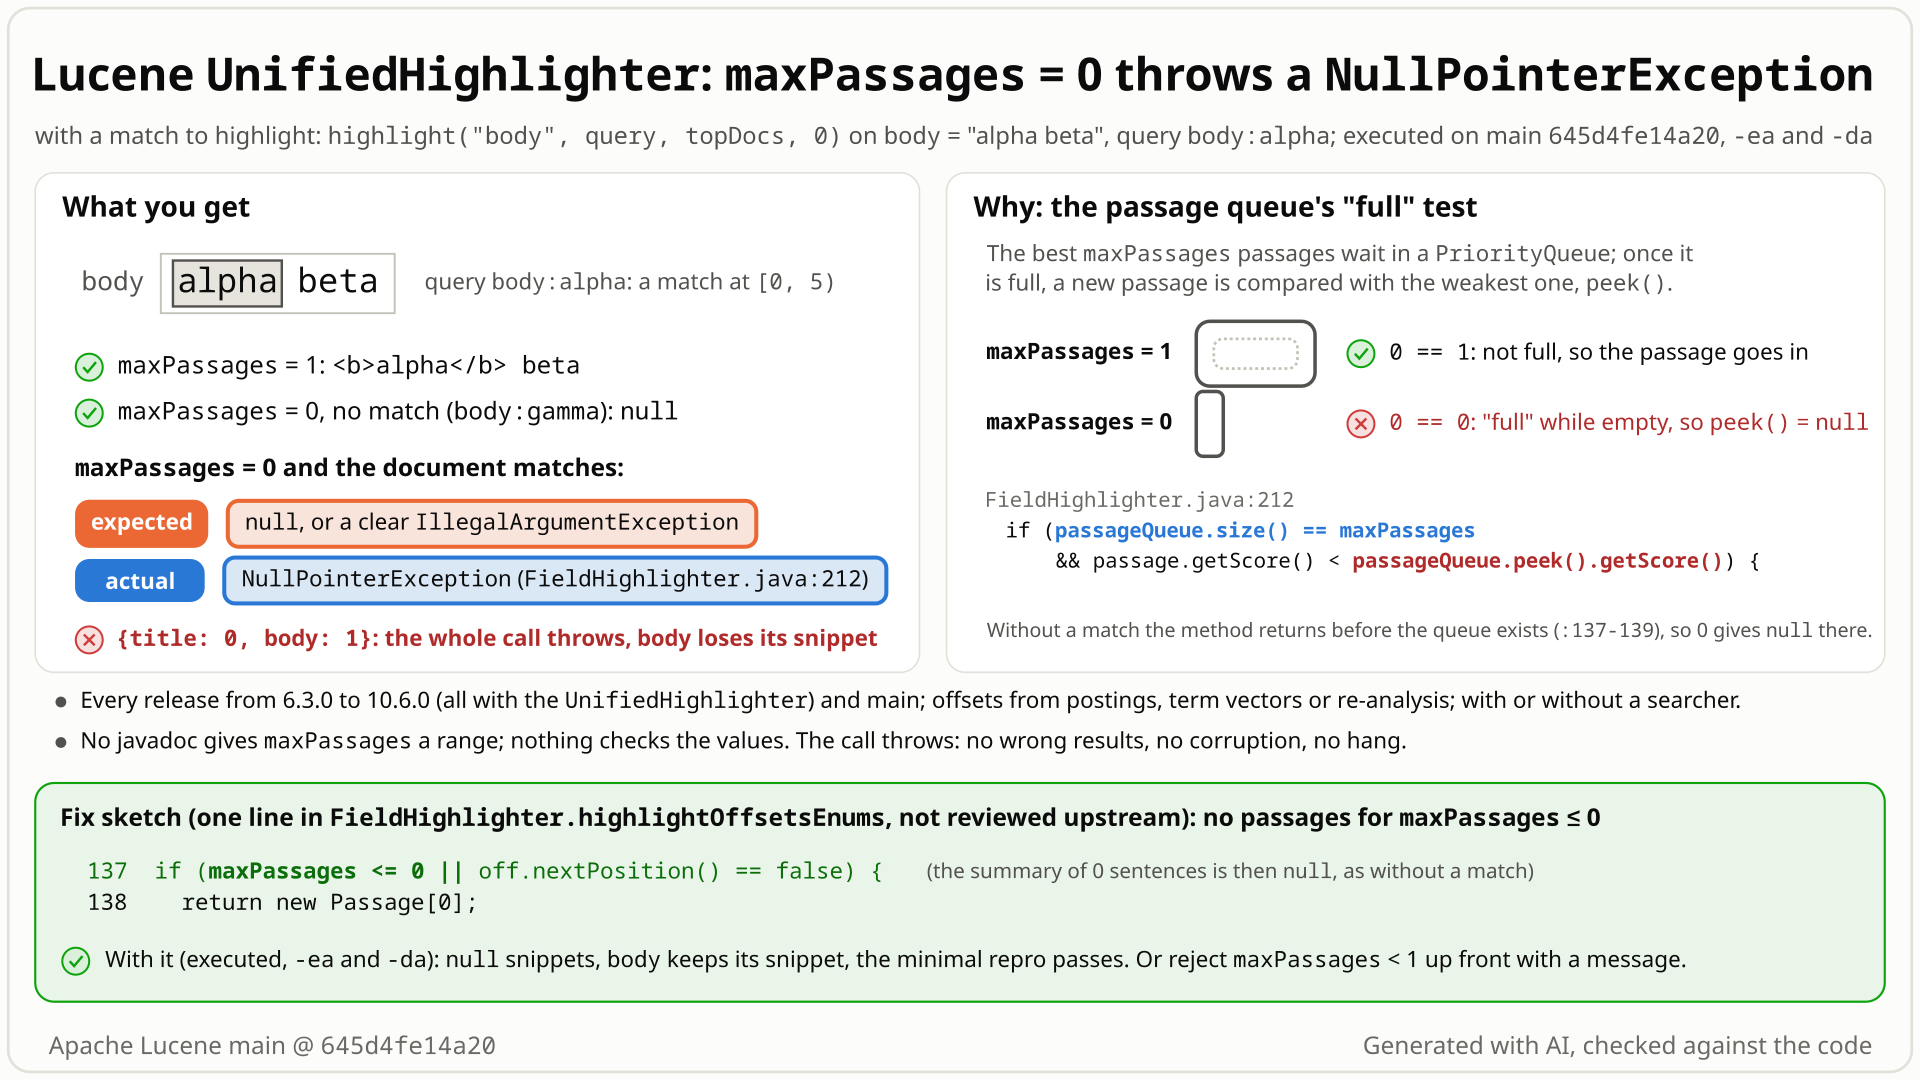
maxPassages = 0, the empty passage queue that already counts as full at line 212, expected vs actual for each call, and the one-line fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document,
body = "alpha beta", searchbody:alphaand callhighlight("body", query, topDocs, 1): you get<b>alpha</b> beta. - Call it with
maxPassages = 0. You expectnull: that is what 0 already returns for a document without a match (querybody:gamma). A clearIllegalArgumentExceptionwould also be fine. - You get a
NullPointerException("the return value ofPriorityQueue.peek()is null") fromFieldHighlighter.java:212, with assertions on and off. - Why: the best passages sit in a queue that counts as full when
size() == maxPassages. With 0 the empty queue is already full (0 == 0), so the new passage is compared with the weakest entry,peek(), which isnull. - With two fields,
title = "alpha"andbody = "alpha beta", and per-field counts{0, 1}, the wholehighlightFieldscall throws:bodyloses the<b>alpha</b> betait gets with{1, 1}.
Code that passes maxPassages = 0 for a field, typically by forwarding a client's snippet count unchecked. Every document with a match to highlight fails, and a multi-field call loses all its snippets. Default settings; all three offset sources tested. It fails loudly: no wrong snippet, no index change, no residue.
Mechanism, terms and numbers580 words
The UnifiedHighlighter keeps a field's best maxPassages passages in a java.util.PriorityQueue. When a passage is finished, FieldHighlighter.maybeAddPassage treats the queue as full when passageQueue.size() == maxPassages and then compares the passage with the lowest-scoring entry, passageQueue.peek() (FieldHighlighter.java:212 on main 645d4fe14a20). For maxPassages = 0 the still empty queue counts as full (0 == 0), peek() returns null, and .getScore() throws.
That happens for every document with a match inside the highlighted text of the field (a match past the first maxLength characters, 10,000 by default, counts as no match), through highlight, highlightFields and highlightWithoutSearcher, with offsets from postings, term vectors or re-analysis, with assertions on and off. A document without a match returns before the queue is built and gets null, so 0 works or fails depending only on whether the document matches. With per-field counts {0, 1}, when the 0 field has such a match, the whole call throws and the other field loses its snippet. Nothing checks the values. The check dates from the first UnifiedHighlighter commit (LUCENE-7438, 2016), so every release from 6.3.0 to 10.6.0 and main is affected.
- No value check.
highlight(field, query, topDocs, maxPassages)wraps the value in an array and callshighlightFields(UnifiedHighlighter.java:766-770).highlightFieldsAsObjectschecks the field list and the array lengths (:892-897) but never the values, and builds oneFieldHighlighterper field with its own count (:922-924).highlightWithoutSearcherdoes the same for one string (:1096-1107). - No match: no queue,
null.highlightOffsetsEnumsreturnsnew Passage[0]before the queue exists when the field has no term occurrence (FieldHighlighter.java:137-139). The fallback summary then asks formaxPassagessentences whenmaxNoHighlightPassagesis at its default -1 (:89-94), that is 0, and the result isnull(:96-100). A match beyond the highlighted text counts as no match: with a searcher the stored text is cut tomaxLengthcharacters (10,000 by default,UnifiedHighlighter.java:100,:1443-1447), and an offset at or past that length ends the loop before any passage is scored (FieldHighlighter.java:164-173), so such a document also getsnull(executed: a 12,005-character document whose only match starts after character 10,000). - Match: an empty queue that counts as full. The queue gets capacity
Math.min(64, maxPassages + 1), 1 for 0, so creating it works (:141-143). When the first scored passage is finished,maybeAddPassageevaluatespassageQueue.size() == maxPassages && passage.getScore() < passageQueue.peek().getScore()(:212):0 == 0is true,peek()of the empty queue isnull, and.getScore()throws. - Why only 0. For every
maxPassages >= 1the queue is non-empty wheneversize() == maxPassages. Negative values never get there: a capacity below 1 is rejected by the JDK constructor first (:143), with anIllegalArgumentException. Nor doesInteger.MAX_VALUE: itsmaxPassages + 1overflows at:143first, a separate bug.
| call | today | expected |
|---|---|---|
maxPassages = 1, document with a match | <b>alpha</b> beta | same |
maxPassages = 0, document without a match | null | same |
maxPassages = 0, document with a match (postings, term vectors or re-analysis; with or without a searcher) | NullPointerException | null, or a clear IllegalArgumentException |
highlightFields with {0, 1} | NullPointerException; the second field's snippet is lost | null and <b>alpha</b> beta, or a clear rejection |
maxPassages = -1 | IllegalArgumentException from the JDK | a clear IllegalArgumentException (not claimed) |
Exposure and likelihood198 words
- What goes wrong. The call throws on the first document with a match to highlight, so the request gets no snippets; in a multi-field call every field loses its snippets. The error is an internal
NullPointerException, not a clear argument error (the javadoc documents only anIllegalArgumentExceptionfor fields without offsets), so a server is likely to report it as its own failure rather than as a bad request. - Easy to miss in tests. With 0, a document without a match returns
null, so tests on non-matching data pass. - Scale. None needed: one document, one term; deterministic.
- Downstream (code reading only, not run). Solr's unified highlighter copies the per-field
hl.snippetsintomaxPassageswithout a range check, sohl.method=unified&hl.snippets=0, orf.<field>.hl.snippets=0next to another field, would reach this code with 0 (no Solr request was run). Elasticsearch and OpenSearch map 0 fragments toInteger.MAX_VALUE - 1and do not reach it. - Workaround. Leave a field that should get no snippet out of the request instead of passing 0.
- How likely: rare. It needs an explicit 0; Lucene's own tests pass only 1, 2, 3 or 10 (never 0), and no report was found in ten years.
One JUnit method on the public API: index one document alpha beta, search body:alpha, highlight with maxPassages = 0. It accepts null or an up-front IllegalArgumentException and fails on the NullPointerException. Deterministic, single thread, assertions on or off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.uhighlight;

import org.apache.lucene.analysis.standard.StandardAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TermQuery;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestZeroMaxPassages extends LuceneTestCase {

  public void testZeroMaxPassagesWithMatch() throws Exception {
    StandardAnalyzer analyzer = new StandardAnalyzer();
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new TextField("body", "alpha beta", Field.Store.YES));
        w.addDocument(doc);
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(r);
        Query query = new TermQuery(new Term("body", "alpha"));
        UnifiedHighlighter highlighter = UnifiedHighlighter.builder(searcher, analyzer).build();
        String[] snippets;
        try {
          snippets = highlighter.highlight("body", query, searcher.search(query, 1), 0);
        } catch (IllegalArgumentException e) {
          return; // rejecting maxPassages 0 up front is fine
        } catch (NullPointerException e) {
          throw new AssertionError("maxPassages 0: expected a null snippet, got " + e, e);
        }
        assertNull(snippets[0]);
      }
    }
  }
}
cp $REPRO/TestZeroMaxPassages.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/
cd $LUCENE && ./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.uhighlight.TestZeroMaxPassages -Ptests.seed=DEADBEEF
- Expected
[null], what 0 already returns for a document without a match (or an up-frontIllegalArgumentException).- Observed
NullPointerException: the return value ofPriorityQueue.peek()is null, atFieldHighlighter.java:212.
More files, environment, full output260 words
The test sits in the uhighlight test package like the upstream tests and uses a fixed StandardAnalyzer and an in-memory ByteBuffersDirectory; by code reading the failing logic does not depend on the codec, similarity or locale the test framework randomizes, and every recorded seed fails the same way. It turns the NullPointerException into an AssertionError that states what was expected (the cause keeps the FieldHighlighter frames). It passes unchanged with either fix, so it is also the regression test.
It needs UnifiedHighlighter.builder and the lucene.tests packages, so it compiles on 9.1.0 and later. Older releases (6.3.0 to 9.0.0) were checked with a separate history probe that uses the public constructor. The test's line numbers in the output include the 16-line license header.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; also fails on the 10.6.0, 10.5.2 and 9.12.3 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (plain Java logic, nothing platform-specific) |
cp $REPRO/TestZeroMaxPassages.java $LUCENE/lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/
cd $LUCENE && ./gradlew :lucene:highlighter:test --tests org.apache.lucene.search.uhighlight.TestZeroMaxPassages -Ptests.seed=DEADBEEF
TestZeroMaxPassages > testZeroMaxPassagesWithMatch FAILED
    java.lang.AssertionError: maxPassages 0: expected a null snippet, got java.lang.NullPointerException: Cannot invoke "org.apache.lucene.search.uhighlight.Passage.getScore()" because the return value of "java.util.PriorityQueue.peek()" is null
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:AEC4630373516A5C]:0)
        at org.apache.lucene.search.uhighlight.TestZeroMaxPassages.testZeroMaxPassagesWithMatch(TestZeroMaxPassages.java:54)

        Caused by:
        java.lang.NullPointerException: Cannot invoke "org.apache.lucene.search.uhighlight.Passage.getScore()" because the return value of "java.util.PriorityQueue.peek()" is null
            at org.apache.lucene.search.uhighlight.FieldHighlighter.maybeAddPassage(FieldHighlighter.java:212)
            at org.apache.lucene.search.uhighlight.FieldHighlighter.highlightOffsetsEnums(FieldHighlighter.java:194)
            at org.apache.lucene.search.uhighlight.FieldHighlighter.highlightFieldForDoc(FieldHighlighter.java:86)
            at org.apache.lucene.search.uhighlight.UnifiedHighlighter.highlightFieldsAsObjects(UnifiedHighlighter.java:988)
            at org.apache.lucene.search.uhighlight.UnifiedHighlighter.highlightFields(UnifiedHighlighter.java:858)
            at org.apache.lucene.search.uhighlight.UnifiedHighlighter.highlightFields(UnifiedHighlighter.java:836)
            at org.apache.lucene.search.uhighlight.UnifiedHighlighter.highlight(UnifiedHighlighter.java:769)
            at org.apache.lucene.search.uhighlight.TestZeroMaxPassages.testZeroMaxPassagesWithMatch(TestZeroMaxPassages.java:50)

:lucene:highlighter:test (FAILURE): 1 test, 1  failure

# the same failure, 1 of 1, with the standalone runner (seed DEADBEEF): main 645d4fe14a20 with -ea and -da,
# and the 10.6.0, 10.5.2 and 9.12.3 release jars- The javadoc gives
maxPassagesno range, and its only documentedIllegalArgumentExceptionis for fields without offsets. - 0 already has a meaning: a document without a match gets "the first
maxPassagessentences",nullfor 0. Only documents with a match crash. - The module's other highlighters accept 0: the classic
Highlighterturns it into 1; theFastVectorHighlighterandmatchhighlightreturn nothing.
The full argument285 words
- Contract. Every overload documents
maxPassagesonly as "The maximum number of top-N ranked passages [per-field] used to form the highlighted snippets" (UnifiedHighlighter.java:757-758,:819-820,:845-846,:881-882,:1089-1090), with no range; the values are never checked (:892-897). - 0 has a documented meaning nearby. The no-match summary is "the first
maxPassagessentences" (:759-761),nullfor 0 (executed), andgetMaxNoHighlightPassagessays "If this is 0 then the resulting highlight is null (not formatted)" (:634-638). - 0 is the only int that ends in a
NullPointerException. 1 toInteger.MAX_VALUE - 1work (Integer.MAX_VALUEfails earlier, with a message-lessIllegalArgumentExceptionatFieldHighlighter.java:143, a separate overflow); -1 already fails with anIllegalArgumentException(executed). - Sibling highlighters. The classic
Highlightercoerces the count (Math.max(1, maxNumFragments); // sanity check,Highlighter.java:138); theFastVectorHighlighterrejects only negative counts (BaseFragmentsBuilder.java:145-148) and returns no fragments for 0 (:161); thematchhighlightPassageSelectorcuts its result tomaxPassages(PassageSelector.java:213) and returns no passages for 0 (executed). - Tests. The
uhighlighttests pass 1, 2, 3 or 10, never 0 (3 fromTestUnifiedHighlighterRanking:maxTopN = 3at:60,highlight(..., n + 1)at:137); the only 0 is the separatewithMaxNoHighlightPassages(0)(TestUnifiedHighlighter.java:843). With a check that rejects values below 1, all existing highlighter tests still pass (executed), so none relies on 0. - History. No commit ever validated
maxPassages. The predecessorPostingsHighlighterhad the same unguarded check, but itsnew PriorityQueue<>(n, ...)threw the JDK's message-lessIllegalArgumentExceptionfor 0 first (executed on 6.2.1, 6.3.0 and 6.6.6): an accident, not a check. The UnifiedHighlighter'sMath.min(64, maxPassages + 1)removed the accident and exposed the old check.
The devil's-advocate check102 words
The strongest case for "works as designed": UnifiedHighlighter is @lucene.experimental and FieldHighlighter @lucene.internal; "top-N" suggests N > 0; a caller who wants no snippet can leave the field out; no upstream test uses 0; and other Lucene top-N APIs reject 0 ("numHits must be > 0", TopScoreDocCollectorManager.java:64).
Why it fails: that supports at most an explicit IllegalArgumentException with a message (fix B), not a NullPointerException from an empty internal queue that appears only when the document matches. @lucene.experimental allows API changes, not an undocumented crash on an accepted argument, and the module's other highlighters treat 0 as a valid count.
Recommended Treat 0 as "no highlighted passages" (one line in highlightOffsetsEnums)
Return no passages for maxPassages <= 0 before the queue is built, the early return a document without a match already takes (one line at FieldHighlighter.java:137). Then 0 gives null, and {0, 1} keeps the second field's snippet. The minimal test and all 723 highlighter tests pass.
-    if (off.nextPosition() == false) {
+    if (maxPassages <= 0 || off.nextPosition() == false) {
       return new Passage[0];
     }
All options and trade-offs2 options · 489 words
Two options were validated with gradle in a clean worktree at 645d4fe14a20: the minimal test and ./gradlew :lucene:highlighter:test (723 tests: the module's 722 plus the new one). They differ in what 0 means. Maintainers may prefer either; both remove the NullPointerException.
Treat 0 as "no highlighted passages" (one line in highlightOffsetsEnums) (validated by the checks) (recommended)
Return new Passage[0] for maxPassages <= 0, before the queue is created (FieldHighlighter.java:137). A matching document asked for 0 passages then takes the same path as a non-matching one: null with default settings; with {0, 1} the first field is null and the second keeps <b>alpha</b> beta. Every value of 1 or more is unchanged.
-    if (off.nextPosition() == false) {
+    if (maxPassages <= 0 || off.nextPosition() == false) {
       return new Passage[0];
     }
Trade-offs
- With
withMaxNoHighlightPassages(1), a matching text asked for 0 passages gets the unhighlighted one-sentence summary (alpha beta. gamma alpha.), as a non-matching text already does (executed). If maintainers wantnullthere, the check belongs inhighlightFieldForDocand must keep the summary for non-matching documents. - Negative values: with
<= 0, -1 on a matching document now fails with "Illegal Capacity: -1" from the summary path (as for non-matching documents today) instead of a message-less exception. WritingmaxPassages == 0leaves negative values exactly as today (executed: the minimal test and the five-test suite pass).
What the checks validated
- Gradle, clean worktree at
645d4fe14a20, seed DEADBEEF: the minimal test fails before the change (1 test, 1 failure) and passes after it;:lucene:highlighter:testpasses 723 tests, 0 failures. - On the stock main jars with the class replaced: the minimal test passes with assertions on and off, and an independent five-test suite (each offset source, without a searcher,
{title: 0, body: 1}) passes 5 of 5. - Earlier, a 476-test highlighter run changed only this repro's result.
Throw IllegalArgumentException("maxPassages must be >= 1, got: " + maxPassages) in the FieldHighlighter constructor (the class has only one, so every UnifiedHighlighter entry point, UnifiedHighlighter.java:1152, and any subclass's FieldHighlighter goes through it), or next to the existing argument checks at :892-897.
    if (maxPassages < 1) {
      throw new IllegalArgumentException("maxPassages must be >= 1, got: " + maxPassages);
    }
Trade-offs
Turns a call that works today into an error: 0 on a document without a match returns null now and would throw. Servers that forward a client's count (Solr's hl.snippets=0, by code reading) would answer with an error instead of an empty highlight. Rejecting only negative values and applying the guard for 0 is a middle way (not run).
What the checks validated
Gradle, same setup: the minimal test passes (it accepts the up-front rejection); :lucene:highlighter:test passes 723 tests, 0 failures. 0 and -1 then give "maxPassages must be >= 1" for matching and non-matching documents alike (executed).
By code reading only (not run), Solr's unified highlighter passes hl.snippets to maxPassages unchecked, so hl.snippets=0 would reach this code with 0 (no Solr request was run); Elasticsearch and OpenSearch map 0 fragments to Integer.MAX_VALUE - 1 and do not reach it.
Found by reading the UnifiedHighlighter's passage code during a review of the highlighter's offset sources, then confirmed with a public-API test. The review's random test driver only tried 1 to 3 passages, so no tool produced the first signal.
The method in full99 words
- Method: code reading (not a formal method). While modelling how
FieldHighlighterforms passages for each offset source, an AI tool noticed thatmaybeAddPassagetreats the queue as full atsize() == maxPassagesand dereferencespeek()without a null check, and asked what happens for 0. - It wrote a public-API JUnit test, which failed on main with assertions on and off and on 10.5.2 and 9.12.3, and passed with the one-line guard.
- The review's random differential driver drew
maxPassagesfrom 1 to 3 only, and the upstream tests pass 1, 2, 3 or 10, which is why neither caught it.
No earlier report found (searched 2026-10-26, re-checked 2026-10-30) in GitHub issues and PRs including the JIRA archive, Solr's JIRA, the mailing lists, downstream projects or the web. Closest, not this bug: #8895 (the shape of the maxPassages API) and #11113 (a different empty-queue NPE).
Searches5 searches
No issue, PR, commit, JIRA entry, list thread, downstream issue or web page reports a NullPointerException (or any error) for maxPassages = 0, or proposes validating maxPassages. 20 hits were read and classified; none is this bug.
- #8895 / LUCENE-7844 (open): simplifying the
maxPassagesinput API; the body and comments never mention 0. - #11113 / LUCENE-10075 (open): a different empty-queue NPE, in the intervals path, with a normal
maxPassages; neither fix covers the other. - #8490 / LUCENE-7438: the introducing change. #5970 / LUCENE-4905: per-field
int[]counts. #5921 / LUCENE-4856: the no-match summary.
Gaps: part of the GitHub queries hit a search quota and were re-run another way; list search matches subjects and leading text only; private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch, solr-ocrhighlighting; all of GitHub for exact identifiers) | 2026-10-26 | about 120 queries: class and method names, the NPE message, maxPassages 0/zero, snippets 0, hl.snippets, number_of_fragments 0; the changed files of all 413 open apache/lucene PRs | no report; closest #8895, #11113, #8490, #5970, #5921 |
| JIRA (LUCENE and SOLR projects) | 2026-10-26 | 20 queries (12 SOLR, 8 LUCENE); 17 issues read | no report; SOLR-10941 is a different NPE |
| Mailing lists (Lucene dev@, java-user@, issues@; Solr users, dev, issues) | 2026-10-26 | 78 queries in two tools | no report |
| Web | 2026-10-26 | 17 queries | generic NPE pages and pre-2016 highlighter questions only |
| GitHub apache/lucene (re-check) | 2026-10-30 | maxPassages, maxPassages 0, UnifiedHighlighter NullPointerException, FieldHighlighter NullPointerException, UnifiedHighlighter NPE, passageQueue; open PRs mentioning FieldHighlighter | nothing new; FieldHighlighter.java:212 unchanged on upstream main |
Present since the UnifiedHighlighter was added (LUCENE-7438, 722e8271243 on master and 4b6794368df on branch_6x, 2016-10-04), first released in 6.3.0. Every release from 6.3.0 to 10.6.0 and main fails; not a regression.
Versions tested4 rows
Introduced by LUCENE-7438 "New UnifiedHighlighter" (#8490), committed by dsmiley on 2016-10-04 as 722e8271243 (master) and 4b6794368df (branch_6x). Its first highlightOffsetsEnums already sized the queue Math.min(64, maxPassages + 1) and had the unguarded passageQueue.size() == maxPassages && passage.score < passageQueue.peek().score.
Later commits only renamed or moved the check: LUCENE-7559 (6.4.0, .getScore()), LUCENE-8145 (7.3.0, moved unchanged into maybeAddPassage, which is why git blame on main names that commit), LUCENE-9570 (9.0.0, reformatted the surrounding code; the check line itself is unchanged since LUCENE-8145). The predecessor PostingsHighlighter had the same check but failed earlier for 0, with the JDK's PriorityQueue capacity check. Old releases were run on JDK 25, not the JDK of their time.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails with gradle and with the standalone runner, assertions on and off |
| 10.6.0, 10.5.2, 9.12.3 | affected | the minimal test fails (release jars), frame FieldHighlighter.java:212 |
| 6.3.0 - 10.5.2 (87 releases) | affected | the history probe fails on every one (assertions off too on 6.3.0, 9.12.3, 10.5.2); the failing frame moves with the line: highlightOffsetsEnums:178 before 7.3.0, maybeAddPassage after |
| 6.2.1 and earlier | no API | no UnifiedHighlighter; the PostingsHighlighter threw a message-less IllegalArgumentException for 0 instead (6.2.1, 6.3.0, 6.6.6) |
An independent reproducer with its own five tests, a devil's advocate, an adjudication and a fresh-seed re-run confirm it; reviewers from another model family, reading only, agreed on the root cause. The history sweep ran all 87 releases from 6.3.0, and both fixes pass the highlighter tests.
Checks and verdicts267 words
Each executing check ran tests against the stock jars; the cross-model reviewers could not run Java, so a separate run re-ran the repro for them.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Code reading, then a public-API JUnit test that fails on main (-ea, -da), 10.5.2 and 9.12.3 and passes with the guard. |
| cross-model review, refute lens (OpenAI GPT-5.6) | not real (low), procedural | Read only; the refute review votes not real when it cannot run the repro. It agreed with the root cause, found the inputs in contract and the intended-behaviour argument weak. |
| Independent reproducer | real | Its own five tests (each offset source, without a searcher, {title: 0, body: 1}) fail 5 of 5 on main, 10.5.2 and 9.12.3 and pass with the guard; re-run on 645d4fe14a20: same. |
| Cross-model adversary, intended lens (OpenAI GPT-5.6) | real (medium) | Intended-behaviour argument moderate; the behaviour matrix: NPE for 0 with a match, null without, an IllegalArgumentException for -1, null for 0 everywhere with the guard. |
| Devil's advocate | real (low severity) | Built the works-as-designed case and rejected it; its claim tests fail on main, 10.5.2 and 9.12.3 and pass with the guard. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's and the finder's tests; class wrong error; not security-sensitive. |
| history sweep and security probe | since 6.3.0 | 87 releases and main; 1,000 failing calls leave no residue. |
| this doc | reproduced; both fixes validated | Gradle on a clean 645d4fe14a20 (fails), each fix with the module's 723 tests (pass), the minimal test on the 9.12.3, 10.5.2 and 10.6.0 jars (fails). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 429 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,280 words
- Registry title
- UnifiedHighlighter with maxPassages=0 throws NullPointerException for every document that has a match (a per-field 0 makes the whole multi-field call fail)
- Area
- highlighter / UnifiedHighlighter passage selection (FieldHighlighter.maybeAddPassage; maxPassages is never range-checked by UnifiedHighlighter.highlightFieldsAsObjects)
- Priority
- Low, rank 647: UnifiedHighlighter throws an NPE instead of a clean error only for an explicit maxPassages of 0, so this rare-input crash ends the crash group.
- Impact class
- wrong error
- Impact note
- Applications on any release from 6.3.0 through 10.6.0 or on main that call UnifiedHighlighter (highlight, highlightFields, highlightWithoutSearcher; the POSTINGS, TERM_VECTORS and ANALYSIS offset sources were run; default settings) with maxPassages 0 for a field get an internal NullPointerException instead of a null snippet or a clear IllegalArgumentException, for every document that matches in that field, and with per-field counts such as {1, 0} the whole call fails, so the other fields lose their snippets too; there are no wrong results, no corruption and no hang, no index size is needed, and by code reading (not executed) Solr's hl.snippets=0 with hl.method=unified reaches it, while Elasticsearch and OpenSearch map 0 to Integer.MAX_VALUE - 1 and do not.
- Summary
- You call UnifiedHighlighter.highlight(field, query, topDocs, 0), or highlightFields with a per-field count of 0, and expect what the same call already does for a document without a match: a null snippet (or, if 0 is not allowed, an IllegalArgumentException that says so). Instead, for every document that has a match in the field, FieldHighlighter.maybeAddPassage tests passageQueue.size() == maxPassages (0 == 0) while the passage queue is still empty and then calls passageQueue.peek().getScore(), so a NullPointerException escapes the call. With {title: 0, body: 1} the body field, which asked for one passage, loses its snippet too, because the whole call throws.
- Introduced
- 722e82712435ecf46c9868137d885484152f749b on master and its branch_6x twin 4b6794368df373df1f68ccf27f7556914efeb95e (LUCENE-7438 'New UnifiedHighlighter' by dsmiley, 2016-10-04; JIRA issue now GitHub #8490, reviewed in apache/lucene-solr#79, which was closed without a GitHub merge; the commits were made directly) [read: git log -G, git blame and git tag --contains in the full-history clone; exec: the history probe fails on 6.3.0, the first release with the API, and does not compile on 6.2.1, where the API is absent]. The first version of FieldHighlighter.highlightOffsetsEnums already sized the queue Math.min(64, maxPassages + 1) and had the unguarded check 'passageQueue.size() == maxPassages && passage.score < passageQueue.peek().score'. Later commits only renamed or moved it: LUCENE-7559 (c51e89014ac / 23b8bb66935, 6.4.0) switched to getScore(), LUCENE-8145 (9422609a5d4 / aa5c3a5c222, 7.3.0) moved the check unchanged into maybeAddPassage (git blame on main names this commit for line 212), and LUCENE-9570 (6faa4f98e04) reformatted it. The predecessor PostingsHighlighter had the same unguarded check, but its new PriorityQueue<>(n, ...) threw the JDK's message-less IllegalArgumentException for n = 0 first [exec on 6.2.1, 6.3.0 and 6.6.6], so the NullPointerException is new with the UnifiedHighlighter's queue sizing; not a regression within the UnifiedHighlighter (2016-10-04)
- First affected version
- 6.3.0 [exec] (first release with the UnifiedHighlighter, from branch_6x commit 4b6794368df; 7.0.0 is the first release of the master commit and is affected [exec]); 6.2.1 has no org.apache.lucene.search.uhighlight package (the probe does not compile there) [exec]
- Affected versions
- every release that has the UnifiedHighlighter: all 87 Maven Central releases from 6.3.0 to 10.5.2 (13 in 6.x, 14 in 7.x, 27 in 8.x, 21 in 9.x, 12 in 10.x), 10.6.0 [exec: the minimal test fails on its release jars] and main ea57360912ed [exec: the history probe, a public-API main(), fails on every one with -ea, and with -da on 6.3.0, 9.12.3, 10.5.2 and main; the finder's JUnit fails on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main; the independent reproduction's and the intended-behaviour check's tests fail on 9.12.3, 10.5.2 and main]; not affected: releases up to 6.2.1, which have no UnifiedHighlighter; not fixed on main (FieldHighlighter.java:212 unchanged, and no open PR touches FieldHighlighter.java or the handling of maxPassages); release branches after 10.5.2 were not checked apart from the 10.6.0 release jars
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record: 281 recorded queries, namely the scripted prior-report search (30 GitHub issue and PR queries planned, 13 answered before GitHub's search rate limit ran out; 32 queries over the dev@, java-user@, issues@ and commits@ lists; 8 JIRA-archive and 8 web queries), 107 read-only GitHub GraphQL searches over apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, dbmdz/solr-ocrhighlighting and all of GitHub for exact identifiers, 20 JIRA queries (12 SOLR, 8 LUCENE), 46 lists.apache.org queries over the Lucene and Solr lists, 9 web searches and local git-history searches; the changed files of all 413 open apache/lucene PRs; 20 hits read and classified, none the same bug; the finder, the independent reproduction, the cross-model review and the intended-behaviour check found nothing either); not fixed upstream (FieldHighlighter.java:212 unchanged on main ea57360912ed, the newest commit touching FieldHighlighter.java is dbf0d1426f1 (#16056, a toArray modernization), and no open PR touches FieldHighlighter.java or maxPassages handling); closest items, not reports: #8895 / LUCENE-7844 (open since 2017; the shape of the maxPassages API, nothing about 0), #8490 / LUCENE-7438 (the introducing change), #11113 / LUCENE-10075 (open; a different empty-queue NullPointerException in the WEIGHT_MATCHES intervals path with a normal maxPassages), #5970 / LUCENE-4905 (the per-field int[] API) and #5921 / LUCENE-4856 (the no-match summary path)
- Lucene commit tested
- main
645d4fe14a20(gradle in a clean scratch worktree, and the standalone runner with assertions on and off); the 9.12.3, 10.5.2 and 10.6.0 release jars; both fixes with the highlighter module's tests (2026-10-30). The history probe ran all 87 releases from 6.3.0 to 10.5.2 and mainea57360912ed(2026-10-26).
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:83-94 (at ea57360912ed) (highlightFieldForDoc: try-with-resources OffsetsEnum, :86 highlightOffsetsEnums, :89-94 no passages -> getSummaryPassagesNoHighlight(maxNoHighlightPassages == -1 ? maxPassages : maxNoHighlightPassages)), :136-138 (no term occurrence -> new Passage[0] before the queue exists), :140-143 (new PriorityQueue<>(Math.min(64, maxPassages + 1), ...)), :194 (maybeAddPassage call), :205-218 (maybeAddPassage: :212 'passageQueue.size() == maxPassages && passage.getScore() < passageQueue.peek().getScore()')lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:94 (at ea57360912ed) (@lucene.experimental), :633-638 (getMaxNoHighlightPassages javadoc: 'If this is 0 then the resulting highlight is null'), :752-770 (highlight(field, query, topDocs, maxPassages): '@param maxPassages The maximum number of top-N ranked passages used to form the highlighted snippets', no range, only an IllegalArgumentException for fields without offsets), :891-897 (highlightFieldsAsObjects checks 'fieldsIn must not be empty' and 'invalid number of maxPassagesIn', never the values)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:83-100, :109-127, :137-143, :164-173, :194, :201-224 (:212 the check)a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:100 (DEFAULT_MAX_LENGTH), :116, :282 (maxNoHighlightPassages default -1), :766-770, :858, :892-897, :922-924, :988, :1096-1107, :1443-1447 (stored text cut to maxLength)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:94 (@lucene.experimental), :634-638, :757-764, :819-820, :845-846, :881-882, :892-897, :1089-1090a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldHighlighter.java:32 (@lucene.internal)a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/highlight/Highlighter.java:138; a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/vectorhighlight/BaseFragmentsBuilder.java:145-148, :161; a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/java/org/apache/lucene/search/matchhighlight/PassageSelector.java:93, :213a Lucene main checkout (645d4fe14a20) lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/TestUnifiedHighlighter.java:843; TestUnifiedHighlighterTermIntervals.java:673; TestUnifiedHighlighterRanking.java:60, :111, :136-137 (maxPassages 1, 2 and 3)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/TopScoreDocCollectorManager.java:64
- TestZeroMaxPassages.java (lucene/highlighter, package org.apache.lucene.search.uhighlight, 1 test):
repro/LFV-265/src/org/apache/lucene/search/uhighlight/TestZeroMaxPassages.java(60 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and an executed probe on the stock main jars and with the one-line guard.
assets/LFV-265/bug.png(429 KB)