To highlight a field without offsets, the UnifiedHighlighter re-analyzes the stored text into a one-document MemoryIndex and asks the query where it matches. Whether that copy keeps payloads is decided by a helper that the default WEIGHT_MATCHES mode switches off, so the copy has none.
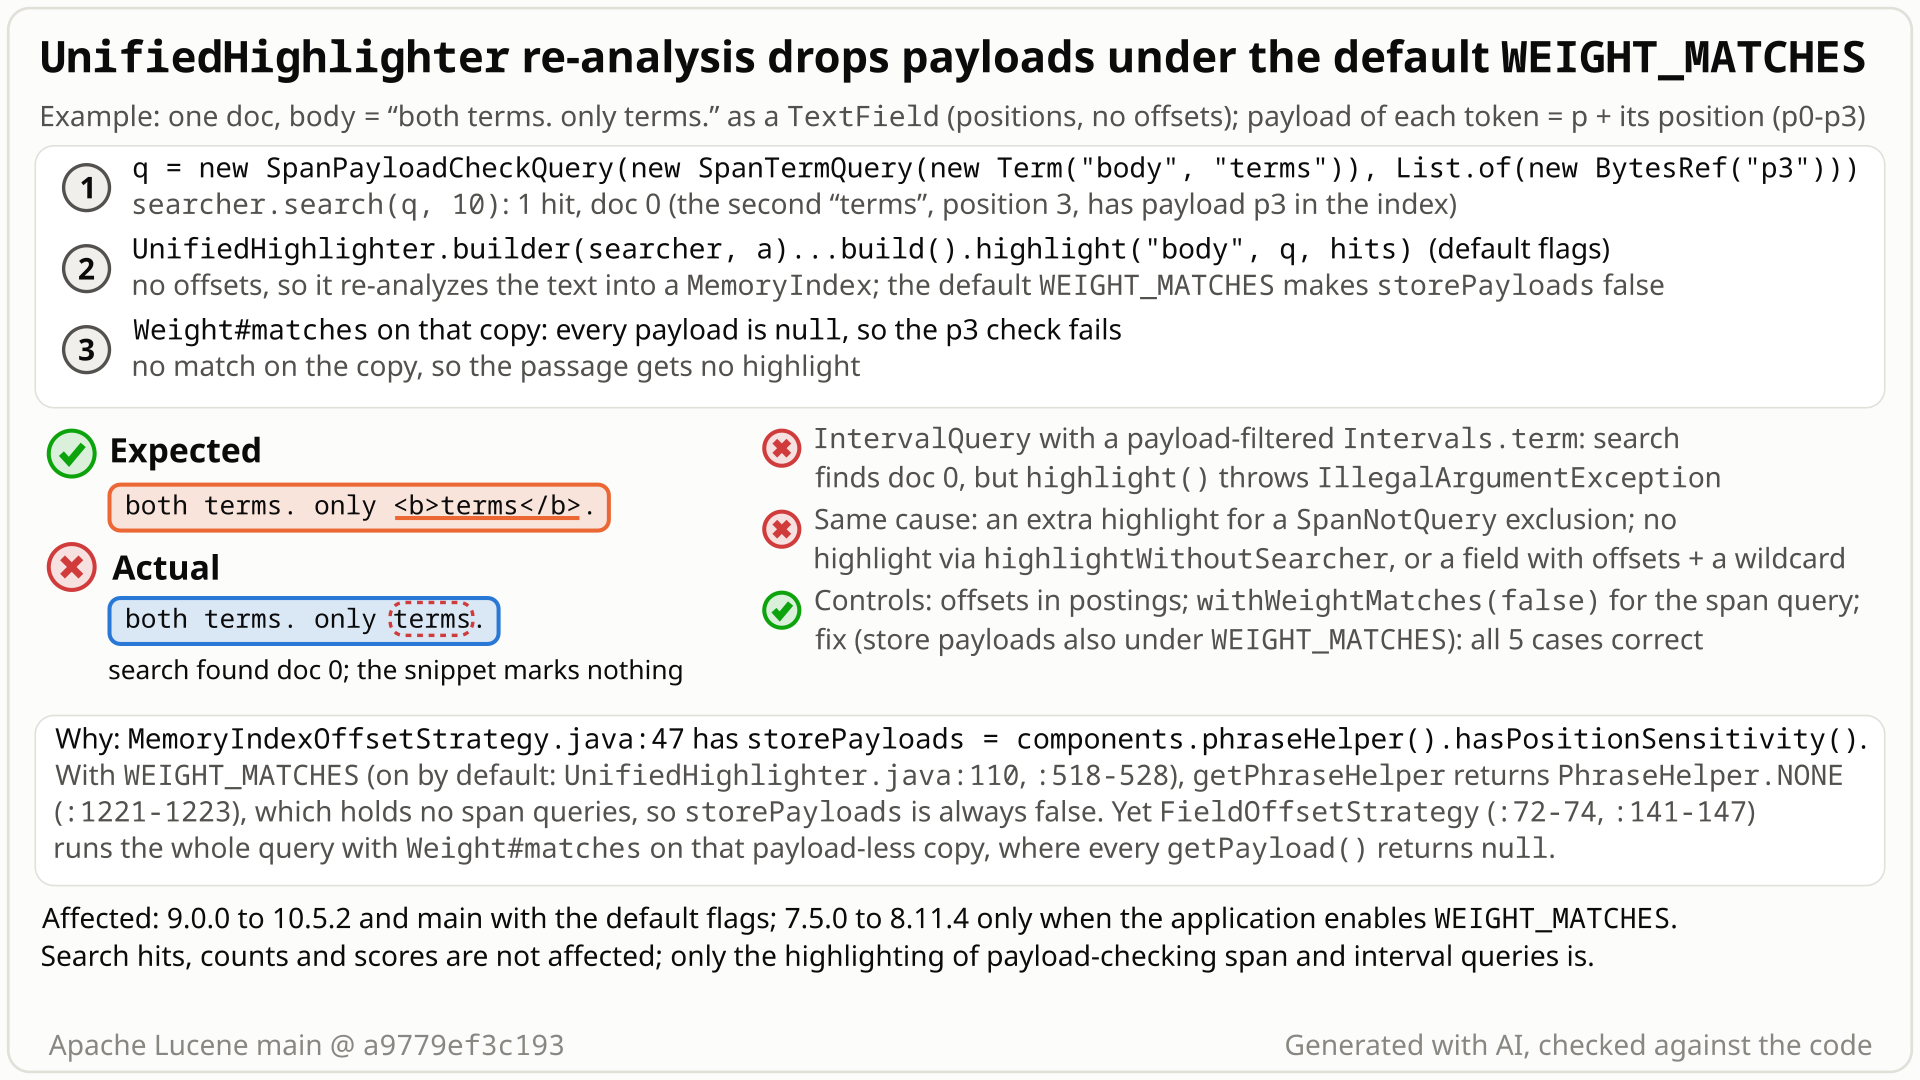
both terms. only terms. with payloads p0 to p3, the query "terms with payload p3", the payload-less copy the highlighter builds, the snippet with no highlight, then the interval form that throws. Select the still to open it at full size. Generated with AI, checked against the code.- You index one document,
both terms. only terms., as a plainTextField(no offsets), with an analyzer that gives each token the payloadp+ its position:bothp0,termsp1,onlyp2,termsp3. - You search
SpanPayloadCheckQuery(terms, [p3]), "thetermswhose payload is p3": 1 hit. You highlight it with the UnifiedHighlighter's default flags, the whole text as one passage. - You expect
both terms. only <b>terms</b>.: the same highlighter returns that when the field has offsets in postings, or withwithWeightMatches(false). - Instead you get
both terms. only terms.. Without offsets the highlighter re-analyzes the text into a one-documentMemoryIndex, and under the defaultWEIGHT_MATCHESthat copy stores no payloads, so the p3 check fails on it. - The same gap gives an extra highlight for a payload exclusion (
SpanNotQuery), makeshighlight()throwIllegalArgumentExceptionfor a payload-filteredIntervalQuery, and also hits a field with offsets when the query has a wildcard part.
Applications that highlight payload-checking queries (SpanPayloadCheckQuery, a payload-filtered Intervals.term, a payload check inside SpanNotQuery) with the UnifiedHighlighter's default flags, on a field it re-analyzes: no offsets indexed, any highlightWithoutSearcher call, or offsets plus a query part that makes it switch (a multi-term part, for example). Default since 9.0.0; search results are unaffected.
Mechanism, terms and numbers710 words
When the UnifiedHighlighter cannot read offsets from the index (a plain TextField, every highlightWithoutSearcher call, or a field with offsets in postings whose query has a multi-term part or another part that makes it switch), it re-analyzes the stored text into a one-document MemoryIndex and evaluates the query there. MemoryIndexOffsetStrategy stores payloads in that copy only when the span PhraseHelper is position-sensitive, and under WEIGHT_MATCHES, the default since 9.0.0, the helper is always PhraseHelper.NONE. So the copy never has payloads, yet the whole query runs on it with Weight#matches: SpanPayloadCheckQuery gets no highlight, a payload exclusion in a SpanNotQuery gets an extra one, and a payload-filtered Intervals.term makes highlight() throw IllegalArgumentException. Search is correct. With offsets in postings the same highlighter highlights all three forms correctly; withWeightMatches(false) fixes the span forms, but the interval form then ignores the payload filter and highlights every terms (an older, separate limit). The fix is one condition: also store payloads when WEIGHT_MATCHES is set.
- Offset source: to mark a match, the UnifiedHighlighter needs the character offsets of the matching tokens. It reads them from postings indexed with offsets, from term vectors, or, as the fall-back, by re-analysis: it runs the analyzer over the stored text again and indexes the tokens into a one-document
MemoryIndex, a private in-memory copy of the document. WEIGHT_MATCHES: the highlighter's default mode since 9.0.0. It asks the query itself where it matches (Weight#matches) on the offset source's reader; with re-analysis that reader is theMemoryIndexcopy.- Payload-checking queries: queries whose match depends on the bytes a token filter attached to each position:
SpanPayloadCheckQuery,Intervals.term(term, payloadFilter), or a payload check nested in another span query, such as the exclusion of aSpanNotQuery.
WEIGHT_MATCHESis on by default (UnifiedHighlighter.java:110;getFlagsadds it at:518-528because its three required flags are defaults too).- The highlighter re-analyzes when the field has neither offsets in postings nor term vectors (
getOffsetSource,:696-709), for everyhighlightWithoutSearchercall (:1078-1081), and also for a field with offsets whenmtqOrRewriteholds (getOptimizedOffsetSource,:1257-1261, switch at:1269-1273): the query has a multi-term part, its span phrase helper needs a rewrite, or it has a part the highlighter does not recognize. Re-analysis then usesMemoryIndexOffsetStrategy(:1294-1302), because the defaultPASSAGE_RELEVANCY_OVER_SPEEDorWEIGHT_MATCHESis set (either is enough; so thewithWeightMatches(false)baselines use it too). - Under
WEIGHT_MATCHES,getPhraseHelperreturnsPhraseHelper.NONE, "will be handled by Weight.matches which always considers phrases" (:1219-1224). MemoryIndexOffsetStrategy.java:47-48stores payloads only if that helper is position-sensitive:storePayloads = components.phraseHelper().hasPositionSensitivity(); // might be needed.NONEis not, so the copy stores no payloads (MemoryIndex.java:1033-1042) and reports none (:1888-1891).FieldOffsetStrategythen evaluates the whole query withWeight#matcheson that copy (FieldOffsetStrategy.java:72-74,:114-147; with a searcher, through anOverlaySingleDocTermsLeafReaderthat takes only the highlighted field's terms from the copy,MemoryIndexOffsetStrategy.java:116-119). Every payload there is null: a payload check fails, a payload exclusion excludes nothing, andPayloadFilteredTermIntervalsSource.matchesthrows because the field "has no indexed payloads" (PayloadFilteredTermIntervalsSource.java:163-167).
With WEIGHT_MATCHES off, the helper is position-sensitive for span queries, the copy stores payloads, and the span query is highlighted correctly.
One document, body = both terms. only terms., every token with the payload p + its position (both p0, terms p1, only p2, terms p3); each query matches the document in search. Executed on main a9779ef3c193, assertions on and off:
| case (default flags unless stated) | correct baseline (passes) | default flags, re-analysis |
|---|---|---|
SpanPayloadCheckQuery(terms, [p3]), plain TextField | both terms. only <b>terms</b>. (offsets in postings; also withWeightMatches(false)) | both terms. only terms. (no highlight) |
SpanPayloadCheckQuery over SpanMultiTermQueryWrapper(te*), [p3], field with offsets in postings | both terms. only <b>terms</b>. (withWeightMatches(false)) | both terms. only terms. |
SpanNotQuery(terms, SpanPayloadCheckQuery(terms, [p3])), plain TextField | both <b>terms</b>. only terms. (offsets in postings) | both <b>terms</b>. only <b>terms</b>. (extra highlight) |
IntervalQuery("body", Intervals.term("terms", p3::equals)), plain TextField | both terms. only <b>terms</b>. (offsets in postings) | IllegalArgumentException: Cannot create a payload-filtered iterator over field body because it has no indexed payloads |
highlightWithoutSearcher, SpanPayloadCheckQuery(terms, [p3]) | both terms. only <b>terms</b>. (withWeightMatches(false)) | both terms. only terms. |
Exposure and likelihood427 words
- Who. Applications that highlight payload-checking queries with the UnifiedHighlighter on its default flags:
SpanPayloadCheckQuery(and itsPayloadType/MatchOperationvariants),Intervals.term(term, payloadFilter), and payload checks nested in other span queries such as aSpanNotQueryexclusion. No Lucene query parser builds these queries, so the application or a downstream product does. - Which fields. Every field highlighted by re-analysis: fields without offsets in postings or term vectors (a plain
TextField), everyhighlightWithoutSearchercall, and fields with offsets in postings when the query also has a multi-term part (executed) or another part that makes the highlighter switch, such as a span rewrite or an unrecognized query part (read). Correct sources: offsets in postings when the highlighter keeps that source (executed for the plain span, exclusion and interval cases), and term vectors that store positions, offsets and payloads (checked for a span query without a multi-term part). Term vectors stored without payloads cannot answer a payload check in either mode (read); that is a configuration limit, not this bug, and the fix does not change that strategy. - Default vs opt-in. Default from 9.0.0 (LUCENE-9431); in 7.5.0 to 8.11.4 only when the application enables
WEIGHT_MATCHESby overridinggetFlags(executed on ports of the test). Downstream, Solr's unified highlighter turned it on by default earlier: SOLR-12754 addedhl.weightMatches, default false in Solr 7.6.0 and true from 8.0.0, which also ships thepayload_checkparser, so Solr users of that highlighter were exposed by default before Lucene 9.0 (read in the history, not run). - Effect. Silent wrong highlights in both directions: a matching occurrence is not marked, or an occurrence that a payload condition excludes is marked. The interval form makes
highlight()throw for a query that searched without error, so the whole highlight call fails; the same highlighter instance still highlights later queries correctly. Search hits, counts and scores are not affected, and the index is not touched. - Scale. Deterministic at any index size: one document is enough. On the copy every payload is null, so the highlight is wrong whenever the right answer depends on the payload values: a check that requires a payload never matches, and a check for "no payload" (a
nullentry) matches every occurrence (executed by the reach probe); the interval form throws. A query whose answer does not depend on the discarded payloads is highlighted correctly. - How likely. Rare: payload-checking queries are an expert feature, and the prior-report search (213 queries, 2026-10-26) found no report in the nearly five years since
WEIGHT_MATCHESbecame the default. Solr looks like the main downstream channel (read, not run).
The test shows that the UnifiedHighlighter on its default flags (WEIGHT_MATCHES) re-analyzes a positions-only field without payloads, so a matching SpanPayloadCheckQuery gets no highlight.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search.uhighlight;

import java.util.List;
import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.queries.payloads.SpanPayloadCheckQuery;
import org.apache.lucene.queries.spans.SpanTermQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.search.TopDocs;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockPayloadAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.util.BytesRef;

public class TestUnifiedHighlighterReanalysisPayloads extends LuceneTestCase {

  public void testSpanPayloadCheckQueryOnPositionsOnlyField() throws Exception {
    Analyzer analyzer = new MockPayloadAnalyzer();
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig(analyzer))) {
        Document doc = new Document();
        doc.add(new TextField("body", "word", Field.Store.YES));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query query =
            new SpanPayloadCheckQuery(
                new SpanTermQuery(new Term("body", "word")), List.of(new BytesRef("pos: 0")));
        TopDocs topDocs = searcher.search(query, 1);
        UnifiedHighlighter highlighter = UnifiedHighlighter.builder(searcher, analyzer).build();
        // "word" has payload "pos: 0" and is the hit: expected "<b>word</b>", actual "word" (no highlight)
        assertEquals("<b>word</b>", highlighter.highlight("body", query, topDocs, 1)[0]);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-268/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/highlighter/build/libs/lucene-highlighter-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.uhighlight.TestUnifiedHighlighterReanalysisPayloads
- Expected vs actual
- Expected "<b>word</b>" (the token "word" has payload "pos: 0" and is the hit); actual "word" (
expected:<[<b>word</b>]> but was:<[word]>).
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[<b>word</b>]> but was:<[word]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.uhighlight.TestUnifiedHighlighterReanalysisPayloads.testSpanPayloadCheckQueryOnPositionsOnlyField(TestUnifiedHighlighterReanalysisPayloads.java:57)- Re-analysis is a documented offset source and fall-back, and the UnifiedHighlighter tests run over all sources alike.
- With
WEIGHT_MATCHESoff the same code stores payloads ("might be needed") and highlights correctly. WEIGHT_MATCHESis documented as "more accurate to the query"; here it breaks a correct highlight.
The full argument268 words
- Re-analysis is a documented, interchangeable offset source. Class javadoc (
UnifiedHighlighter.java:68-71): "A Highlighter that can get offsets from either postings (...), term vectors (...), or via re-analyzing text."getOffsetSource(:689): "Fall-back:OffsetSource#ANALYSISis returned."highlightWithoutSearcher(:1078-1081): "Naturally, the mode of operation will beOffsetSource#ANALYSIS." - The tests treat the sources alike.
UnifiedHighlighterTestBaseruns the suites over postings, term-vector, postings-with-term-vector and re-analysis field types (UnifiedHighlighterTestBase.java:44-63,:105-118). No UnifiedHighlighter test uses a payload query, so nothing pins the current behaviour. WEIGHT_MATCHESpromises more accuracy.Builder#withWeightMatches(:340-348): "It's more accurate to the query"; CHANGES for LUCENE-8286: "This mode will highlight more accurately than any other highlighter". Here the flag turns a correct highlight into a wrong one or an exception.- The same code stores payloads without the flag. The line's comment says payloads "might be needed"; with
WEIGHT_MATCHESoff the phrase helper is position-sensitive for span queries, payloads are stored and the highlight is right (executed). - History: an unhandled interaction, not a decision. The condition was written in 2016 for the span-only phrase-helper path (LUCENE-7438, moved by LUCENE-7526). LUCENE-8286 (2018) added the
PhraseHelper.NONEbranch and aWEIGHT_MATCHESterm to the re-analysis routing (the defaultPASSAGE_RELEVANCY_OVER_SPEEDalready chose this strategy), but only renamed the accessor in the condition. Neither its threads nor those of LUCENE-9431 (which made the flag the default) mention payloads. - Payload highlighting is a module capability.
TestHighlighter#testPayloadQuery: "We can highlight based on payloads. It's supported both via term vectors and MemoryIndex since Lucene 5." - Legal trigger. Public analyzer API (
PayloadAttribute), public payload queries, the default highlighter.
The devil's-advocate check290 words
The verifiers and reading-only reviews by a model from another family built the strongest case: the three-argument highlight() javadoc says the field must "be indexed with offsets" and documents an IllegalArgumentException otherwise (UnifiedHighlighter.java:734-746); "// might be needed" reads as a memory trade-off; the classic QueryScorer keeps MemoryIndex payloads opt-in (setUsePayloads); the UnifiedHighlighter is @lucene.experimental; payload queries are expert.
Why it fails: the @throws clause is stale, since the highlighter does not throw for a field without offsets but falls back to re-analysis as getOffsetSource documents; the bug is also reached on a field that does have offsets and through highlightWithoutSearcher, which has no such precondition. The cost argument would justify a switch, but the UnifiedHighlighter has none and documents no limitation, and the cost is per highlight call and grows with the kept tokens (one int per kept token, the payload bytes with their offsets, and one 32 KiB block per highlighted field and call; not measured). @lucene.experimental is about API stability, not wrong output or an exception escaping highlight(). The reviews rated the intended argument moderate and agreed on the root cause; all verifiers judged it real, the devil's advocate with high confidence that it is not intended.
What the rebuttal does not settle: no UnifiedHighlighter API promises that re-analysis keeps payloads, and the withWeightMatches javadoc hedges: the snippets "can be a little different for phrases", the passage relevancy "can be different (maybe worse?)" and it is "slower when highlighting many fields" (UnifiedHighlighter.java:340-347). Those hedges are about markup and passage scoring, not about matches that are lost or invented, but together with the memory cost they make a gated fix or a documented limit a reasonable choice for the maintainers.
Recommended Store payloads also under WEIGHT_MATCHES (validated)
Also store payloads in the re-analysis MemoryIndex when WEIGHT_MATCHES is set: one condition in MemoryIndexOffsetStrategy (+7/-1). With it the repro passes with assertions on and off and over 10 iterations, the whole highlighter module passes (727 tests), and lint, format and javadoc checks pass.
// Payloads might be needed: by span queries in the PhraseHelper, or, with WEIGHT_MATCHES, by
// any payload-aware query, because Weight#matches then evaluates the whole query here.
boolean storePayloads =
    components.phraseHelper().hasPositionSensitivity()
        || components
            .highlightFlags()
            .contains(UnifiedHighlighter.HighlightFlag.WEIGHT_MATCHES);
memoryIndex = new MemoryIndex(true, storePayloads); // true==store offsets
All options and trade-offs4 options · 688 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle; the other options were not run.
Workarounds today: withWeightMatches(false) (span payload checks then highlight correctly; the interval form then ignores the payload filter); index offsets in postings (helps only when the highlighter keeps that source: no multi-term part, span rewrite or unrecognized query part); or store term vectors with positions, offsets and payloads (correct in a check with a span query without a multi-term part).
A separate, known item to expect after the fix: a payload-filtered term inside positional interval combinations (ordered, unordered, maxgaps, atLeast, ...) still throws UnsupportedOperationException from getQuery() in WEIGHT_MATCHES highlighting even with payloads present (another registry row, partly covered by upstream #10074). The fix here does not touch that; a single payload-filtered term passes with it.
In MemoryIndexOffsetStrategy's constructor, add || components.highlightFlags().contains(UnifiedHighlighter.HighlightFlag.WEIGHT_MATCHES) to the storePayloads condition (+7/-1 with the comment). It keeps the line's intent (its comment is // might be needed) of storing payloads whenever evaluating the query might need them: under WEIGHT_MATCHES the consumer is the query's own Weight#matches. A second diff adds the repro as a regression test; a PR also needs a CHANGES entry.
// Payloads might be needed: by span queries in the PhraseHelper, or, with WEIGHT_MATCHES, by
// any payload-aware query, because Weight#matches then evaluates the whole query here.
boolean storePayloads =
    components.phraseHelper().hasPositionSensitivity()
        || components
            .highlightFlags()
            .contains(UnifiedHighlighter.HighlightFlag.WEIGHT_MATCHES);
memoryIndex = new MemoryIndex(true, storePayloads); // true==store offsets
Trade-offs
- Cost (read, not measured), for each copy built under
WEIGHT_MATCHES: one extra int per kept token position (-1 when the token has no payload); each non-empty payload copied into aBytesRefArraywith one offset int per payload; and that array's first 32 KiB byte block, allocated when theMemoryIndexis created, i.e. once per highlighted field per highlight call (reset()keeps it for the next document). Only tokens kept by the query-term pre-filter count. On the searcher paths the stored text is cut tomaxLength(default 10,000 chars);highlightWithoutSearcherre-analyzes the whole string the caller passes, as it already does for the rest of the copy. The same costs are already paid withWEIGHT_MATCHESoff whenever the phrase helper holds span queries. - Payload-free fields pay these costs too; option B avoids them at the price of plumbing.
What the checks validated
- Stock main
a9779ef3c193: the repro fails 5 of 5 with assertions on and off and 50 of 50 over 10 iterations, every failure at the default-flags assertion; the whole highlighter module has 727 tests with 5 failures, exactly the repro. - With the fix: the repro passes 5 of 5 with assertions on and off, and 50 of 50 over 10 iterations.
- With the fix, the whole
lucene/highlightermodule (classic, unified, match and vector highlighters, incl. the repro): 35 classes, 727 tests, 0 failures. ecjLint(main and test),checkGoogleJavaFormatandrenderJavadocfor the highlighter module pass; both diffs apply cleanly to a cleana9779ef3c193tree.- Earlier, by the hunt, the same condition shadowed in: the finder's, the independent reproducer's, the devil's advocate's, the review-stage check's and the reach probe's tests all pass; shadowed into 7.5.0 and 8.1.0 it makes the history ports pass.
- Not run: other modules' suites (the change is in
lucene/highlighteronly); no benchmark.
Use FieldInfo#hasPayloads() of the indexed field, as Solr's hl.payloads does for the original Highlighter, and always store them for highlightWithoutSearcher, which has no FieldInfo.
Trade-offs
Saves these costs for payload-free fields, but MemoryIndexOffsetStrategy only receives UHComponents, so getOffsetStrategy or UHComponents must carry the information.
Store payloads only when the query reads them.
Trade-offs
No generic marker exists for "this query reads payloads" (span payload checks, payload-filtered intervals, custom queries), so it is fragile and misses third-party queries.
State that payload-checking queries are not supported by re-analysis under WEIGHT_MATCHES.
Trade-offs
No code change, but the silent wrong highlights and the exception stay for anyone who misses the sentence.
Downstream, Solr's payload_check parser builds SpanPayloadCheckQuery and its unified highlighter turns WEIGHT_MATCHES on by default (since Solr 8.0.0), so Solr users highlighting a re-analyzed payload field would likely see missing highlights (read in Solr's source, not run).
A bounded-exhaustive model ran every UnifiedHighlighter offset source and flag set of the stock jars against an exact reference and the Matches API (about 2.6e8 checks) and flagged the re-analysis copy as unfaithful. Its documents had no payloads, so this case was then found by reading the storePayloads condition and confirmed with a JUnit.
The method in full161 words
Method: bounded-exhaustive translation validation on the real jars, then code reading (semi-formal tier), in a hunt unit on highlighter offset sources.
- An exact reference semantics written from the javadoc, plus the Matches API as a second oracle, was compared with every UnifiedHighlighter offset source (postings, term vectors, both, re-analysis) and flag set, and with the other highlighters, on every document of a small enumerated document language and a 121-query catalogue: about 2.6e8 checks on the stock main jars. It flagged the re-analysis
MemoryIndexas an unfaithful copy of the document (the class of the known #10466). - The model's document language has no payloads, so it could not express this case. Reading
MemoryIndexOffsetStrategy'sstorePayloadscondition next togetPhraseHelperfound it, and a JUnit on the stock jar witnessed it end to end. - Found 2026-10-26 on main
ea57360912ed; then checked by an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by a model from another family (OpenAI GPT-5.6) and an adjudication.
No prior report found (2026-10-26, 213 queries: GitHub issues, PRs and commits, the LUCENE and SOLR JIRA projects, the Lucene and Solr mailing lists, downstream repositories, the web, and all 413 open PRs). Closest: open #10466, the same re-analysis copy failing another way.
Searches5 searches
Verdict new: 24 hits judged, none the same bug. #10466 / LUCENE-9426 (open, 2020): the re-analysis copy's term pre-filter drops excluded terms, so SpanNot and MUST_NOT over-highlight; different mechanism and fix site, payloads not mentioned. Context only: #8577 / LUCENE-7526 (moved the storePayloads line into MemoryIndexOffsetStrategy, 2016), #9333 / LUCENE-8286 and #10471 / LUCENE-9431 with PR #362 (added and defaulted the flag; no payload discussion), #8735 / LUCENE-7684 (open: per-field payload flag in MemoryIndex), SOLR-6916 (hl.payloads for the original Highlighter). Keyword search cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits; downstream repositories; the dev@, java-user@, issues@ and commits@ lists; the JIRA archive; the web | 2026-10-26 | the hunt's prior-report tool: 30 GitHub issue/PR, 3 commit, 2 downstream, 32 mailing-list, 10 JIRA and 6 web queries | no report; context only: #8577, #9333, #10471 |
| GitHub (apache/lucene, apache/solr, Elasticsearch, OpenSearch, two Solr plugin repositories, all of GitHub) | 2026-10-26 | 54 GraphQL searches (GitHub's search rate limit was being used up) | no report; closest #10466 (sibling), #8735 (context) |
| SOLR JIRA project and Solr mailing lists | 2026-10-26 | 8 JQL queries; list searches | no report; SOLR-6916 (payloads for the original Highlighter) |
| Open apache/lucene PRs and full history | 2026-10-26 | changed files of all 413 open PRs, diffs of the 6 that touch the highlighter; git log -S / --grep | none changes payload handling, storePayloads or getPhraseHelper |
| mailing lists and JIRA (the finder's earlier run) | 2026-10-26 | 20 mailing-list and 4 JIRA queries | no report |
Introduced by LUCENE-8286 (b19ae942f154, 2018, first in 7.5.0), which added WEIGHT_MATCHES but kept a 2016 payload condition the flag makes always false; default since 9.0.0 (LUCENE-9431). Executed: 7.4.0 correct; 7.5.0 to 8.11.4 fail with the flag on; 9.0.0 to 10.5.2 and main fail by default.
Versions tested8 rows
Introduced by LUCENE-8286 "UnifiedHighlighter: new HighlightFlag.WEIGHT_MATCHES for MatchesIterator API" (@dsmiley; committed as b19ae942f154 on master and bf7d1078e4ef on branch_7x, both 2018-08-29, closing apache/lucene-solr#409; JIRA now apache/lucene#9333), first released in 7.5.0 with the flag opt-in. It added the PhraseHelper.NONE branch and a WEIGHT_MATCHES term to the routing to MemoryIndexOffsetStrategy (under the default PASSAGE_RELEVANCY_OVER_SPEED that strategy was already chosen), but only renamed the accessor in the older storePayloads condition, written by LUCENE-7438 (722e8271243) and moved by LUCENE-7526 (7af454ad767), both 2016 and correct then.
Default since LUCENE-9431 (2719cf6630eb, 2021-10-22, PR #362), first in 9.0.0. The exception form needs payload-filtered intervals, LUCENE-8694 (13aac3becde, authored 2019-02-15, committed 2019-03-18; in 8.1.0 in the sandbox module, in lucene/queries from 8.2.0). Not fixed anywhere: the heads of branch_10x, branch_10_6 and branch_9_12 carry the same condition, branch_9_12 through the older getPhraseHelper() accessor (read 2026-10-26). No commit-level bisect: the 2018 trees build with ant, so 7.4.0 and 7.5.0 are the nearest released pair. Releases before 9.1.0 ran main() ports of the test.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | compact JUnit 5 of 5 fail via gradle, assertions on and off; the finder's test still fails 2 of 2 |
main ea57360912ed | affected | the finder's test 2 of 2; the independent test 3 of 6 and the devil's advocate's 3 of 5, controls passing |
| 10.5.2, 10.0.0, 9.12.3, 9.1.0 | affected | fail with the stock flags (release jars, SHA-1 checked) |
| 9.0.0 | default flip | port fails with the stock flags; passes with WEIGHT_MATCHES removed |
| 7.5.0, 7.7.3, 8.0.0, 8.1.0, 8.11.4 | opt-in | fail when WEIGHT_MATCHES is enabled; 7.5.0, 7.7.3 and 8.11.4 are correct with their stock flags; the interval form from 8.1.0 |
| 7.4.0 | not affected | correct: no WEIGHT_MATCHES flag exists |
10.6.0 (branch_10_6, released 2026-10-29) | not run | same condition (read only) |
fix (scratch worktree at a9779ef3c193; shadowed into 7.5.0 and 8.1.0) | not affected | the repro 5 of 5 and the highlighter module (727 tests) pass; the history ports pass |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing, the latter on a field with offsets. Reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause. An adjudication confirmed it with high confidence, and this doc's gradle runs reproduce it on a9779ef3c193.
Checks and verdicts367 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Equivalence model plus code reading; its JUnit fails 2 of 2 with assertions on and off and on 10.5.2 and 9.12.3; the one-condition fix passes, and in 476 UnifiedHighlighter suite tests it removes only the repro's failures. |
| independent reproducer | real | Own test from the claim only (another text, payload encoding, break iterator and searcher): 3 of 6 fail on main, 10.5.2 and 9.12.3, 60 of 120 over 20 iterations, exactly the claim tests; the 3 controls pass; 6 of 6 pass with the fix. |
| intended-behaviour devil's advocate | real; high that it is not intended | Rejected every intended-behaviour argument; reproduced on a field indexed with offsets (wildcard and interval-or-prefix queries) and through highlightWithoutSearcher: 3 of 5 fail on main, 10.5.2 and 9.12.3; 5 of 5 pass with the fix. |
| cross-model reviews (refute, intended) | not real (low, procedural); real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6) reviewed by reading only, since it could not run Java. The lenses agreed on the root cause, found the inputs in contract and rated the intended argument moderate; the refute lens's "not real" only means not reproduced by the reviewer. Separate runs failed as claimed, and the intended-stage check (highlightWithoutSearcher) failed on main and 10.5.2 and passed with the fix. |
| adjudication | confirmed, high | Re-ran the independent test with a new seed (3 of 6 fail, assertions on and off; 6 of 6 with the fix) and the devil's advocate's test (3 of 5 fail). |
| Follow-up and main refresh | reproduces; keep | History matrix from 7.4.0 to main; a reach probe found the extra-highlight direction; re-runs with new seeds; the main refresh to a9779ef3c193 still fails 2 of 2 with identical messages. |
| this doc's gradle runs | reproduces; fix validated | The compact JUnit through gradle on stock main (5 of 5 fail, assertions on and off, 50 of 50 over 10 iterations) and with the fix (all pass); the whole highlighter module: 5 failures stock (the repro), 0 with the fix (727 tests); lint, format and javadoc pass. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 560 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,362 words
- Registry title
- UnifiedHighlighter re-analysis under the default WEIGHT_MATCHES flag builds its MemoryIndex without payloads, so payload-checking queries get missing or extra highlights or make highlight() throw IllegalArgumentException
- Area
- highlighter / UnifiedHighlighter re-analysis offset source (MemoryIndexOffsetStrategy under WEIGHT_MATCHES)
- Priority
- Low, rank 356: Wrong highlights only for payload-checking span or interval queries, an expert feature that no Lucene query parser builds.
- Impact class
- silent wrong results
- Impact note
- Applications that highlight payload-checking queries (SpanPayloadCheckQuery and its variants, or IntervalQuery over Intervals.term with a payload filter) with the UnifiedHighlighter on its default flags (WEIGHT_MATCHES, on by default since 9.0.0) get wrong highlights, at any index size, whenever the field is highlighted by re-analysis: fields indexed without offsets in postings or term vectors (a plain TextField), every highlightWithoutSearcher call, and fields with offsets in postings when the query also has a multi-term part; the matching occurrence gets no highlight, an occurrence that a payload condition should exclude gets an extra one, or (interval form) highlight() throws IllegalArgumentException for a query that searched without error; search results are not affected; exposed by default from 9.0.0 through 10.6.0 (10.6.0 by reading) and main, and from 7.5.0 through 8.11.4 only when the application enables WEIGHT_MATCHES.
- Summary
- You index a field whose tokens carry payloads as a plain TextField (no offsets), search with SpanPayloadCheckQuery or with IntervalQuery(Intervals.term(term, payloadFilter)), which matches the document, and highlight the hit with the UnifiedHighlighter on its default flags. You expect the snippet the highlighter gives with offsets in postings or with WEIGHT_MATCHES off, 'both terms. only <b>terms</b>.' for a check on the second 'terms'. Instead re-analysis builds its one-document MemoryIndex without payloads (MemoryIndexOffsetStrategy stores payloads only when the span PhraseHelper is position-sensitive, and WEIGHT_MATCHES replaces that helper with PhraseHelper.NONE), so Weight#matches on that copy finds nothing and the snippet is 'both terms. only terms.', while the interval query makes highlight() throw IllegalArgumentException 'Cannot create a payload-filtered iterator over field body because it has no indexed payloads'.
- Introduced
- b19ae942f154 (LUCENE-8286 'UnifiedHighlighter: new HighlightFlag.WEIGHT_MATCHES for MatchesIterator API', closes apache/lucene-solr#409, JIRA now apache/lucene#9333; the branch_7x backport bf7d1078e4ef shipped in 7.5.0): it made getPhraseHelper return PhraseHelper.NONE under WEIGHT_MATCHES and evaluated the whole query with Weight#matches against the re-analysis MemoryIndex, but only renamed the accessor in the older storePayloads condition (written by LUCENE-7438 722e8271243 and moved into MemoryIndexOffsetStrategy by LUCENE-7526 7af454ad767 in 2016, correct then), so that condition is always false under the new flag [read: git blame and git log -L on both lines; exec: release pair 7.4.0 correct / 7.5.0 fails with WEIGHT_MATCHES, and the one-line fix shadowed into 7.5.0 passes; no commit-level bisect, the 2018 trees build with ant]; default exposure: 2719cf6630eb (LUCENE-9431, apache/lucene#362) turned WEIGHT_MATCHES on by default for 9.0.0 without touching the defect [read]; the exception form needs payload-filtered intervals from LUCENE-8694 (13aac3becde on branch_8x, 8.1.0) [read; exec: 8.0.0 port does not compile, 8.1.0 throws] (2018-08-29 (b19ae942f154, LUCENE-8286); default exposure 2021-10-22 (2719cf6630eb, LUCENE-9431))
- First affected version
- 7.5.0 (tagged 2018-09-22) when the application enables WEIGHT_MATCHES itself (overriding getFlags); 9.0.0 (tagged 2021-12-06) with the default configuration [exec: 7.4.0 correct, 7.5.0 fails with WEIGHT_MATCHES; 8.11.4 correct with its stock flags, 9.0.0 fails with its stock flags]
- Affected versions
- with WEIGHT_MATCHES enabled by the application: 7.5.0 through 8.11.4 [exec: 7.5.0, 7.7.3, 8.0.0, 8.1.0 and 8.11.4 fail; with their stock flags 7.5.0, 7.7.3 and 8.11.4 are correct]; with the default configuration: 9.0.0 through 10.5.2, 10.6.0 (by reading) and main ea57360912ed [exec: 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main fail; -ea and -da on 7.5.0, 8.11.4, 9.0.0, 9.12.3, 10.5.2 and main]; the missing-highlight form exists from 7.5.0, the exception form from 8.1.0; releases before 9.1.0 ran ports of the canonical test (main() programs with StandardTokenizer, flags set by overriding the protected getFlags) because UnifiedHighlighter.Builder and the org.apache.lucene.tests packages first shipped in 9.1.0; not affected: 7.4.0 and earlier (no WEIGHT_MATCHES flag; exec on 7.4.0: re-analysis highlights correctly); the heads of branch_10x, branch_10_6 and branch_9_12 carry the same two lines [read: GitHub contents API]; 10.6.0 (released 2026-10-29) was not run; not fixed anywhere as of ea57360912ed
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check; also reached by code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record verdict new, 213 queries: a scripted prior-report search (30 GitHub issue/PR, 3 commit, 2 downstream-repo, 32 mailing-list over dev@, java-user@, issues@ and commits@, 10 JIRA-archive and 6 web queries), 54 GitHub GraphQL searches over apache/lucene, apache/solr, Elasticsearch, OpenSearch, two Solr plugin repositories and all of GitHub, 8 SOLR-project JIRA queries, Solr mailing lists, the changed files of all 413 open PRs with diffs of the 6 that touch the highlighter, git pickaxe; the finder's earlier run added 20 mailing-list and 4 JIRA queries); nearest items, none reporting this bug: #10466 / LUCENE-9426 (open: the same re-analysis MemoryIndex drops excluded terms through its token pre-filter, so SpanNot and MUST_NOT over-highlight; different mechanism and fix site), #8577 / LUCENE-7526 (wrote the storePayloads line, 2016), #9333 / LUCENE-8286 and #10471 / LUCENE-9431 with PR #362 (added WEIGHT_MATCHES and made it the default; no payload discussion), #8735 / LUCENE-7684 (open: per-field payload flag in MemoryIndex), SOLR-6916 (the same need met for the original Highlighter with hl.payloads); upstream main ea57360912ed and the branch_10x, branch_10_6 and branch_9_12 heads still have the code, and no open PR changes it
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): a compact public-API JUnit through gradle in a scratch worktree, stock and with the fix, assertions on and off and 10 iterations, plus the wholelucene/highlightermodule stock and with the fix (2026-10-27). Hunt runs on mainea57360912edand the 10.5.2 and 9.12.3 jars; history runs (ports of the test before 9.1.0) on 7.4.0, 7.5.0, 7.7.3, 8.0.0, 8.1.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2; the main-refresh re-run ona9779ef3c193still reproduces.
- Finding record
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:47-48 (storePayloads = components.phraseHelper().hasPositionSensitivity(); // might be needed; new MemoryIndex(true, storePayloads)), :102-120 (getOffsetsEnum, memoryIndex.reset() at :111)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:110 (DEFAULT_ENABLE_WEIGHT_MATCHES = true), :518-528 (WEIGHT_MATCHES added when MULTI_TERM_QUERY, PHRASES and PASSAGE_RELEVANCY_OVER_SPEED are set), :341-349 (withWeightMatches javadoc: 'more accurate to the query'), :68-71 (class javadoc: offsets from postings, term vectors or re-analysis), :680-708 (getOffsetSource, fall-back ANALYSIS), :737-745 (three-argument highlight() javadoc asks for offsets), :1079-1081 (highlightWithoutSearcher: 'the mode of operation will be ANALYSIS'), :1219-1224 (getPhraseHelper returns PhraseHelper.NONE under WEIGHT_MATCHES), :1253-1273 (getOptimizedOffsetSource switches POSTINGS to ANALYSIS for a multi-term part), :1291-1301 (getOffsetStrategy picks MemoryIndexOffsetStrategy under WEIGHT_MATCHES)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldOffsetStrategy.java:74 and :114-147 (createOffsetsEnumsWeightMatcher evaluates the whole query with Weight#matches on the given reader)lucene/queries/src/java/org/apache/lucene/queries/intervals/PayloadFilteredTermIntervalsSource.java:163-167 (throws IllegalArgumentException when the field has no indexed payloads)
- The finding in 30 seconds
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:68-71, 110, 518-528, 696-709, 1078-1081, 1219-1224, 1163-1173, 1253-1273, 1291-1302lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:45-53, 101-121lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/OverlaySingleDocTermsLeafReader.java:51-57lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/FieldOffsetStrategy.java:62-112, 114-147lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:1033-1042, 1888-1891lucene/queries/src/java/org/apache/lucene/queries/intervals/PayloadFilteredTermIntervalsSource.java:163-167
- Who is affected
lucene/queryparser (no builder of SpanPayloadCheckQuery or payload-filtered intervals)lucene/queries/src/java/org/apache/lucene/queries/payloads/SpanPayloadCheckQuery.java:53-91lucene/queries/src/java/org/apache/lucene/queries/payloads/SpanPayloadCheckQuery.java:220-224 (a null expected entry matches a null payload)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:1163-1173, 1257-1261 (mtqOrRewrite: unknown or non-empty automata, rewrite, unrecognized part)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/TermVectorOffsetStrategy.java:41-50
- Why it looks unintended
lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/UnifiedHighlighter.java:68-71, 340-348, 689, 734-746, 1078-1081lucene/highlighter/src/test/org/apache/lucene/search/uhighlight/UnifiedHighlighterTestBase.java:44-63, 105-118lucene/highlighter/src/test/org/apache/lucene/search/highlight/TestHighlighter.java:2190-2193lucene/highlighter/src/java/org/apache/lucene/search/highlight/QueryScorer.java:54, 262-264lucene/CHANGES.txt:7159-7164 (LUCENE-8286), 4770-4771 (LUCENE-9431)
- Suggested fix
lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:498 (BytesRefArray created when storePayloads), 1033-1042 (one int per position when storePayloads), 2313-2314 (reset clears it); lucene/core/src/java/org/apache/lucene/util/BytesRefArray.java:40-45 (first 32 KiB block), 64-72 (offset int per payload)lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:107-110 (pre-filter); UnifiedHighlighter.java:100 (DEFAULT_MAX_LENGTH), 1409-1411 (stored values cut to maxLength), 1096-1107 (highlightWithoutSearcher passes the whole string)
- History
lucene/CHANGES.txt:4770-4771, 7159-7164
- TestUnifiedHighlighterReanalysisPayloads.java (JUnit test):
repro/LFV-268/src/org/apache/lucene/search/uhighlight/TestUnifiedHighlighterReanalysisPayloads.java(61 lines)
Made in parallel with this doc from a probe run on main a9779ef3c193 (stock, and with the fix shadowed in); the values on screen come from the probe's log. The diagram uses the span query on a plain field and the interval form; the compact repro adds the field-with-offsets, exclusion and highlightWithoutSearcher cases on the same text.
assets/LFV-268/bug.png(560 KB)