Each segment notes, per indexed field, which postings format and file group hold its postings. A merge copies the old notes and then rewrites them only for fields the source segments list. A segment written by a non-per-field postings codec does not list a field whose documents were all deleted, so that field's note goes stale.
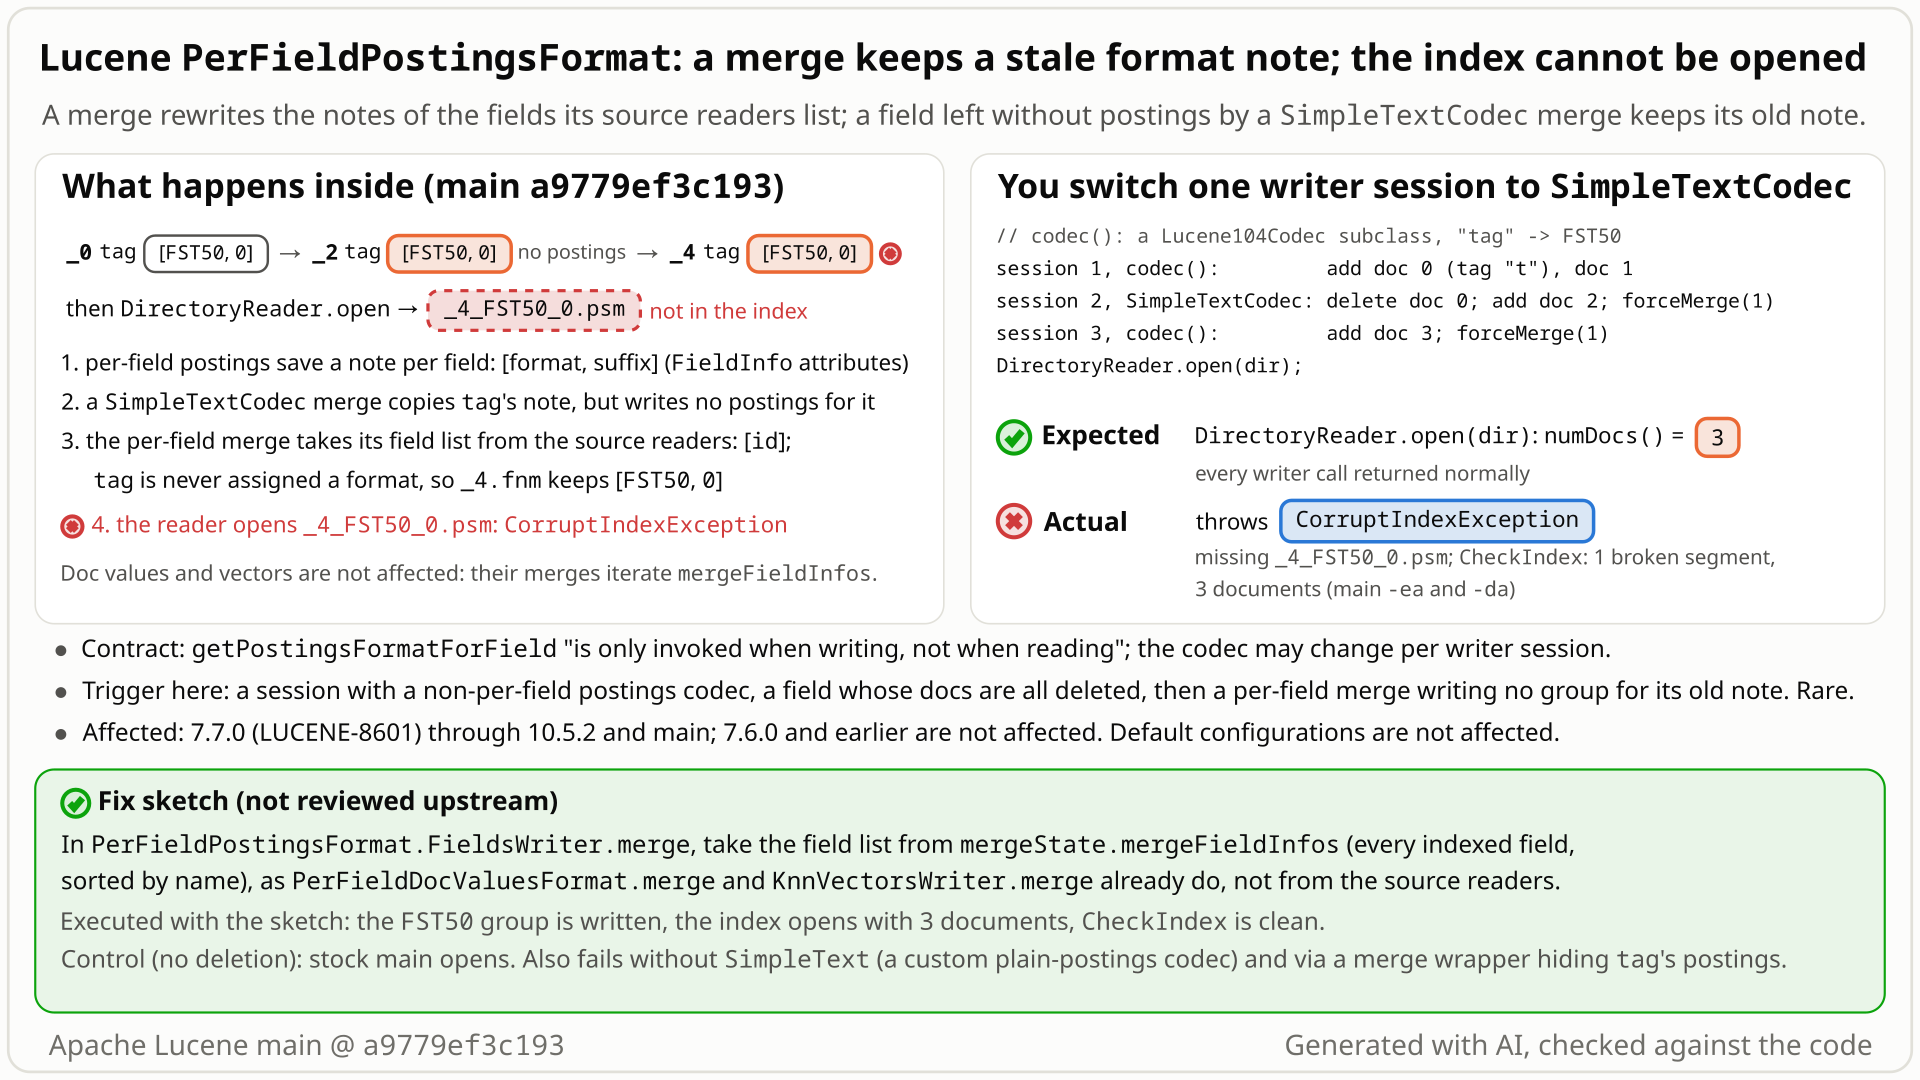
tag survives the SimpleText merge and points at _4_FST50_0, which the final merge never writes. Select the still to open it at full size. Generated with AI, checked against the code.- Session 1: index 2 documents with a
Lucene104Codecsubclass that gives fieldtagits own postings format, FST50. Only doc 0 hastag. The segment notestag= FST50, file group 0. - Session 2 uses
SimpleTextCodec, whose postings format is not per-field: delete doc 0, add doc 2,forceMerge(1). Notagpostings are left, but the merged segment still carries the notetag= FST50/0. - Session 3 is per-field again: add doc 3,
forceMerge(1). The sources list onlyid, so the merge writes only the_4_Lucene104_0.*postings files and rewrites onlyid's note.tagstill says FST50/0. - You expect the committed index to open with 3 documents: every call returned normally. Instead
DirectoryReader.openthrowsCorruptIndexExceptioncaused by the missing_4_FST50_0.psm, andCheckIndexreports 1 broken segment holding all 3 documents. - Every executed release from 7.7.0 to 10.5.2 fails. The same happens with the test framework's plain-postings
CheapBastardcodec in session 2, with the stock codec alone when the final merge has no indexed field left, and, with the per-field codec in every session, when a merge-reader wrapper hidestag's postings.
Indexes where some writer sessions use a non-per-field postings codec (in-tree SimpleTextCodec, "for recreational use only", the test framework's CheapBastardCodec, or a custom codec), or whose merges use a custom reader wrapper that hides a field's postings. Default configurations are not affected. The whole merged segment becomes unreadable.
Mechanism, terms and numbers747 words
PerFieldPostingsFormat records, per indexed field of a segment, which postings format and file group (suffix) hold the field's postings, as two FieldInfo attributes, and the reader opens exactly those groups. Since LUCENE-8601 (7.7.0) merged FieldInfos inherit the source attributes, and the per-field postings merge rewrites them only for the fields that the source postings readers list. A segment written by a codec whose postings format is not per-field (in-tree SimpleTextCodec, the test framework's CheapBastardCodec, or any custom codec with a plain postings format) does not list a field whose documents were all deleted, so that field keeps its inherited format and suffix; a custom merge-reader wrapper (FilterCodecReader through addIndexes or OneMerge.wrapForMerge) that hides an indexed field's postings does the same with the per-field codec in every session. When the next per-field merge writes no group with that pair (the field's format has a name no merged field uses, or no indexed field is left), the committed segment names postings files that do not exist: DirectoryReader.open and NRT open throw CorruptIndexException and CheckIndex reports the segment broken, while every writer call returned normally and an open writer keeps committing on top. Every executed release from 7.7.0 to 10.5.2 and main is affected; default configurations are not. The fix takes the merge's field list from mergeFieldInfos, as the doc-values and vectors merges already do.
- Per-field postings: the default codec's postings format is a
PerFieldPostingsFormat. It lets each field use its own postings format (getPostingsFormatForField, the documented way to customise postings) and writes each format's fields into a file group named<segment>_<format>_<suffix>.*, for example_4_Lucene104_0.psmor_4_FST50_0.psm. - The note: two
FieldInfoattributes per indexed field,PerFieldPostingsFormat.formatandPerFieldPostingsFormat.suffix. On reading, they are the only routing record: the reader opens the group of every indexed field that has them (PerFieldPostingsFormat.java:295-321). - Non-per-field postings codec: a codec whose
postingsFormat()is a plain format. In-tree:SimpleTextCodec(lucene/codecs, "FOR RECREATIONAL USE ONLY") and the test framework'sCheapBastardCodec; otherwise a custom codec. The codec can differ per writer session (IndexWriterConfig.setCodec).
- On merge, the merged
FieldInfoscopy every source field's attributes (SegmentMerger.java:232-239;FieldInfos.java:775-777and:801; documented at:731-732and:756-757). - The per-field postings merge builds its field list from the source postings readers' iterators only (
PerFieldPostingsFormat.java:171-181) and writes fresh attributes only for those fields (:248-253; TODO at:210: "This should check current format from the field attribute?"). - A per-field source lists every field that has the note (
:318,:331-332). A plain source lists only the fields it wrote postings for. In the probe ona9779ef3c193, the SimpleText segment lists[id]while itsFieldInfoshold[id, tag], withtag= FST50/0.MergeStatetakes a source'sFieldInfosand its postings reader separately (MergeState.java:133,:155), so a reader wrapper whosegetPostingsReader()leaves out an indexed field has the same effect (executed, see Who is affected). - So
tagkeeps FST50/0 through the final merge, which writes only_4_Lucene104_0.*. The reader then tries_4_FST50_0.psmand fails (the comment at:305: "null formatName means the field is in fieldInfos, but has no postings!"). - Necessary condition: the stale pair is not a group the final merge writes. That holds when the field's format has a name no field of the final merge uses (
FST50here), or, with the default codec alone, when no indexed field is left to merge. For a second instance of a format name that another field also uses, it depends on the suffix order: groups are keyed by format instance, suffixes are counted per format name in field order (:202-230). When the pair coincides with a written group, the segment opens and the field reads as absent. - Doc values and vectors are not affected: their merges iterate
mergeState.mergeFieldInfosand rewrite every field (PerFieldDocValuesFormat.java:135-140,KnnVectorsWriter.java:135).
Segment _0 (session 1): id = Lucene104/0, tag = FST50/0, files _0_Lucene104_0.* and _0_FST50_0.*. Segment _2 (SimpleText, session 2): 2 documents, terms(tag) null, attributes unchanged. Segment _4 (session 3): 3 documents, postings files _4_Lucene104_0.* only, tag = FST50/0. DirectoryReader.open: CorruptIndexException caused by FileNotFoundException: No sub-file with id _FST50_0.psm found in compound file "_4.cfs". CheckIndex (which reports, it does not throw): 1 broken segment containing 3 documents. The session-2 segment must keep a live document: a fully deleted segment is dropped with its notes.
Exposure and likelihood415 words
- Who is hit. Applications that mix writer sessions of a per-field codec with sessions of a codec whose postings format is not per-field. A uniquely named, SPI-registered custom codec with a plain
Lucene104PostingsFormattriggers it too, in a public-APImain()onFSDirectorywithout SimpleText.lucene/benchmark'sCreateIndexTaskcan install aFilterCodecwith any named plain postings format (codec.postingsFormat,CreateIndexTask.java:150-161), a benchmark setting. Solr ships aSimpleTextCodecFactoryan operator can select, documented as never for production (read, not executed); the shipped codecs of two other common search servers build per-field postings (read). - A second route: merge-source reader wrappers.
OneMerge.wrapForMergeexists to "Wrap a reader prior to merging in order to add/remove fields or documents" (MergePolicy.java:302), andaddIndexes(CodecReader...)takes anyCodecReader(IndexWriter.java:3275). AFilterCodecReaderwhosegetPostingsReader()leaves out an indexed field but keeps itsFieldInforeaches the same stale note with the per-field codec in every session, no deletion and no SimpleText needed: 2 of 2 fail (one test per route) on main with-eaand-daand on 10.5.2, the same wrapper hiding nothing passes, and the fix passes. In-tree wrappers do not hide postings this way (SlowCodecReaderWrapperlists every indexedFieldInfo,SortingCodecReaderpasses the field list through). - Opt-in, not default. With a per-field codec in every session and no wrapper that hides postings it cannot happen (by reading: a per-field source lists every field that has a note). With the default codec plus a SimpleText session it needs the "no indexed field left" case.
- The other ingredients of the codec route are ordinary. Deleting every document that has some field, then merges. Deterministic with 4 documents (the independent reproduction: 20 of 20 random seeds; this doc: 30 of 30).
- What is lost. The whole merged segment, not just the field:
DirectoryReader.open, NRT open andopenIfChangedthrow; an open writer is not stopped and keeps committing, so under the defaultKeepOnlyLastCommitDeletionPolicyno older readable commit is left; a new writer that must merge the segment closes with a tragicCorruptIndexException;CheckIndexreports it and-exorcisedrops all of its documents (3 of 4 in the security probe on mainea57360912ed). Recovery: reindex or exorcise, unless an older commit (for example kept by a snapshot deletion policy) or a backup exists (not tested). - Fails closed. No hang, no wrong hits, no other field's data, no deleted documents coming back (security probe,
-eaand-da). - Unreported since 7.7.0 (2019), consistent with the narrow trigger.
The test shows that after a SimpleTextCodec session deletes the only doc with field g and force-merges, a later default-codec merge keeps g's stale per-field postings attributes and the committed index cannot be opened.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs.perfield;

import org.apache.lucene.codecs.simpletext.SimpleTextCodec;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestPerFieldPostingsStaleAttributes extends LuceneTestCase {

  public void testMergeAfterSimpleTextSegmentDroppedTheField() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
        Document doc = new Document();
        doc.add(new StringField("g", "y", Field.Store.NO));
        w.addDocument(doc);
        w.addDocument(new Document());
      }
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setCodec(new SimpleTextCodec()))) {
        w.deleteDocuments(new Term("g", "y"));
        w.forceMerge(1);
      }
      try (IndexWriter w =
          new IndexWriter(dir, new IndexWriterConfig().setCodec(TestUtil.getDefaultCodec()))) {
        w.addDocument(new Document());
        w.forceMerge(1);
      }
      // expected: the committed index opens with 2 docs; actual: CorruptIndexException (no .psm file)
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        assertEquals(2, r.numDocs());
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-280/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.codecs.perfield.TestPerFieldPostingsStaleAttributes
- Expected vs actual
- Expected
DirectoryReader.opento succeed with 2 docs; actualCorruptIndexExceptioncaused byNo sub-file with id _Lucene104_0.psm found in compound file "_3.cfs"(-ea and -da).
More files, environment, full output64 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.apache.lucene.index.CorruptIndexException: Problem reading index from ByteBuffersDirectory@1999b25c lockFactory=org.apache.lucene.store.SingleInstanceLockFactory@405e4620 (resource=ByteBuffersDirectory@1999b25c lockFactory=org.apache.lucene.store.SingleInstanceLockFactory@405e4620)
       org.apache.lucene.index.SegmentCoreReaders.<init>(SegmentCoreReaders.java:142)
       org.apache.lucene.index.SegmentReader.<init>(SegmentReader.java:95)
       org.apache.lucene.index.StandardDirectoryReader.createOrReuseSegmentReader(StandardDirectoryReader.java:296)
       org.apache.lucene.index.StandardDirectoryReader.createSegmentReaders(StandardDirectoryReader.java:239)
       [...]
     Caused by: java.io.FileNotFoundException: No sub-file with id _Lucene104_0.psm found in compound file "_3.cfs" (fileName=_3_Lucene104_0.psm files: [.fnm, .fdx, .fdt, .fdm])
       org.apache.lucene.codecs.lucene90.Lucene90CompoundReader.openInput(Lucene90CompoundReader.java:184)
       org.apache.lucene.store.Directory.openChecksumInput(Directory.java:156)
       org.apache.lucene.codecs.lucene104.Lucene104PostingsReader.<init>(Lucene104PostingsReader.java:85)
       org.apache.lucene.codecs.lucene104.Lucene104PostingsFormat.fieldsProducer(Lucene104PostingsFormat.java:423)
       org.apache.lucene.codecs.perfield.PerFieldPostingsFormat$FieldsReader.<init>(PerFieldPostingsFormat.java:316)
[...]- The javadoc says the field-to-format mapping "is written to the index" and read back; here it names files that were never written.
- Codecs may change per writer session; Lucene's own
TestMixedCodecsmixes SimpleText into default-codec indexes on purpose. - The doc-values and vectors merges rewrite every field; the vectors analogue was fixed as a bug (LUCENE-9992).
The full argument264 words
- The contract.
getPostingsFormatForField: "The field to format mapping is written to the index, so this method is only invoked when writing, not when reading." (PerFieldPostingsFormat.java:379-385). The attributes are the reader's only routing record. - Codecs may differ per session.
IndexWriterConfig.setCodec: "Only takes effect when IndexWriter is first created." (IndexWriterConfig.java:292-297).TestMixedCodecssets SimpleText on random writer sessions ("Make sure we aggressively mix in SimpleText since it has different impls for all codec formats",TestMixedCodecs.java:49-52), but its only field never loses all of its documents. The test framework picksSimpleTextCodecorCheapBastardCodecas a test's random default codec (SetupAndRestoreStaticEnv.java:185-197). - Nothing requires per-field postings. The codecs package documentation describes writing a full custom codec as well as extending the default codec via
getPostingsFormatForField(codecs/package-info.java:40-64). - The sibling merges handle this case. Doc values and vectors iterate
mergeFieldInfos; LUCENE-9992 (#11031, a deleted-away vector field kept its FieldInfo with no vector files) and LUCENE-10228 (PR #432, an inherited per-field suffix in the vectors merge) were fixed as bugs, for vectors only. - History. Before 7.7.0, merged FieldInfos started with empty attributes, so such a field had no note and the reader skipped it. LUCENE-8601 made them inherit attributes and turned the per-field formats' "found existing value" checks into overwrites; its thread (#9647) says the formats "expect it to be null and generate new values during merge" and does not discuss fields the postings merge never visits (our reading).
- No test, CHANGES or MIGRATE entry, javadoc or discussion accepts the behaviour (the intended-behaviour check's 40 intent queries; the follow-up's 115 queries).
The devil's-advocate check276 words
The strongest case for "intended or unsupported": SimpleTextCodec is "FOR RECREATIONAL USE ONLY" and @lucene.experimental, so mixing it into a production index is unsupported; PerFieldPostingsFormat is itself @lucene.experimental (PerFieldPostingsFormat.java:63), its two attributes are private codec bookkeeping, and nothing promises that any codecs can be alternated or that a wrapper's postings may disagree with its FieldInfos; FieldInfo.putAttribute says that "If the value of the attributes for a same field is changed between the documents, the behaviour after merge is undefined" (FieldInfo.java:669-671); and the finder's first repro uses an anonymous FilterCodec that borrows the default codec's name, although FilterCodec asks for "a unique name" (FilterCodec.java:53).
Why it fails: the recreational and experimental labels bound the support promise, not the outcome: every writer call succeeds and commits a segment that the same codec cannot read, and the reader already has a representation for an indexed field without postings, no note (:305), which the merge could write. SimpleText is not needed: the test framework's CheapBastard codec and a uniquely named custom codec with a plain postings format fail the same way. The putAttribute sentence covers conflicting values for one field; here the value never changes and only one source segment carries the field. This doc's test uses a Lucene104Codec subclass, the documented extension point, with no name trick. Every verifier rejected the intended reading; the intended-behaviour check and the cross-model reviews rated it weak (the independent reproduction gave no rating), and a later cross-model fact check of this doc rated it moderate and still judged it a bug. What partly survives is reach: a maintainer may call it low priority.
Recommended Merge every indexed field of mergeFieldInfos (validated)
Build the merge's field list from mergeState.mergeFieldInfos (every indexed field, sorted by name), as the doc-values merge does, instead of from the source readers (+11/-12 lines, one file). With it the repro and the whole lucene/core (8,892 tests), lucene/codecs and lucene/backward-codecs suites pass.
// Assign a format to every indexed field of the merged segment, not only to the fields the
// source postings readers list: the merged FieldInfos inherit the source attributes, so a
// field left out here (for example one whose postings a non-per-field format dropped) would
// keep attributes that name files this merge never writes. Sorted for a stable suffix order.
List<String> indexedFieldNames = new ArrayList<>();
for (FieldInfo fi : mergeState.mergeFieldInfos) {
  if (fi.getIndexOptions() != IndexOptions.NONE) {
    indexedFieldNames.add(fi.name);
  }
}
indexedFieldNames.sort(null);
Map<PostingsFormat, FieldsGroup> formatToGroups = buildFieldsGroupMapping(indexedFieldNames);
All options and trade-offs4 options · 674 words
One fix was built and validated on a scratch worktree of main a9779ef3c193; three alternatives are listed with their trade-offs.
Workaround until fixed: keep every writer session of a per-field index on a per-field postings codec, and do not wrap merge sources so that their postings leave out an indexed field. No workaround was tested for an index that already holds a plain-postings segment: any later per-field merge of it can hit the bug, also with the default codec alone. Reindexing with a per-field codec avoids it; CheckIndex only detects it after the merge was committed.
In PerFieldPostingsFormat.FieldsWriter.merge, replace the MergedIterator over the source readers' iterators (PerFieldPostingsFormat.java:171-181) with the merged segment's indexed fields, so buildFieldsGroupMapping writes a current format and suffix for every one of them. This is the rule PerFieldDocValuesFormat.merge already follows (:135-140). The now-unused imports Arrays, Objects and MergedIterator go.
// Assign a format to every indexed field of the merged segment, not only to the fields the
// source postings readers list: the merged FieldInfos inherit the source attributes, so a
// field left out here (for example one whose postings a non-per-field format dropped) would
// keep attributes that name files this merge never writes. Sorted for a stable suffix order.
List<String> indexedFieldNames = new ArrayList<>();
for (FieldInfo fi : mergeState.mergeFieldInfos) {
  if (fi.getIndexOptions() != IndexOptions.NONE) {
    indexedFieldNames.add(fi.name);
  }
}
indexedFieldNames.sort(null);
Map<PostingsFormat, FieldsGroup> formatToGroups = buildFieldsGroupMapping(indexedFieldNames);
Trade-offs
- A field with no postings left joins its format's group, which is written (the independent reproduction's fix check:
_4_FST50_0.*exists,CheckIndexclean); the field reads as absent. A format whose only fields were deleted away therefore gets a file group with no terms: a few small files. That a group with no terms is written and readable was shown forFST50andLucene104; a custom postings format would need the same check. - Suffix numbers can differ from today's when such a field sorts between others; deterministic either way, and every field's attributes are rewritten.
- Cost: one pass over the merged
FieldInfos. Not benchmarked.
What the checks validated
- Gradle,
-Ptests.seed=DEADBEEF: the new test 3/3 with assertions on and off, 30/30 over 10 random-seed iterations; the closest suites (codecs.perfield.*,TestMixedCodecs,TestAddIndexes,TestSegmentMerger,TestIndexWriterMerging,TestIndexWriterForceMerge,TestFieldInfos) 317 tests, 0 failures (17 skipped), assertions on and off. - With assertions on only: the whole
:lucene:core:testsuite with the new test, 8,892 tests, 0 failures (322 skipped);:lucene:codecs:test693 tests (78 skipped) and:lucene:backward-codecs:test2,339 tests (184 skipped), 0 failures;:lucene:core:check -x test(google-java-format, ecjLint, forbiddenApis) passes. - Repro harness with the fix shadowed on
a9779ef3c193: this test 3/0 (-ea,-da), the finder's repro 2/0, the independent reproduction'sLucene104Codec-subclass test 1/0, the reader-wrapper probe 2/0 (-ea,-da). Earlier, onea57360912ed: the finder's exhaustive harness T6 and T6b went from 1716 failures each to 0.
Keep the reader-derived field list and remove the two attributes from every other indexed field of the merged segment. This writes the reader's own representation of an indexed field without postings, no note ("null formatName means the field is in fieldInfos, but has no postings!", :305), and creates no empty file groups.
Trade-offs
Does not depend on how each format writes a group with no terms, and a maintainer may well prefer it; but FieldInfo has no way to remove an attribute, so it needs a new internal API. Not run.
Open a group only if its files exist.
Trade-offs
Hides real corruption, and leaves wrong notes in the index. Not recommended. Not run.
Merged FieldInfos start with no codec attributes again, as before 7.7.0.
Trade-offs
7.7.0 with that hunk reverted passes the repro, but the carry-over is intended and documented since 9.0 and user attributes rely on it. Not recommended.
Downstream relevance: a service is exposed only if an operator can switch an index to a plain-postings codec (for example Solr's SimpleTextCodecFactory, documented as never for production) or its own code wraps merge readers so that a field's postings are hidden. It fails closed: the index stops opening, with no wrong results.
Semi-formal. An AI tool modelled how per-field postings attributes travel through merges and saw the gap; a bounded-exhaustive harness on the real IndexWriter then failed in exactly the cases the model predicted: 1,716 of 10,935 in the "per-field, SimpleText with deletes, per-field" template and 1,716 of 5,832 in its addIndexes(CodecReader) variant. No model checker or proof.
The method in full184 words
The hunt's hunt unit on per-field formats built a bounded-exhaustive translation-validation harness (TestH58PerFieldExhaustive) on the stock main jars: real IndexWriter and codecs, 3 postings, 3 doc-values and 3 vector fields, 3 format slots per field (two instances of the default format and one with another name) and 8 writer-session templates T1-T7 and T6b (remaps, deletes, addIndexes, doc-values updates, NRT, mixed codecs).
While writing the harness's attribute-bookkeeping model (merge field set = the source postings readers' fields; merged FieldInfos = union of the source attributes), the AI tool saw that a field outside the merge field set keeps an inherited format and suffix. The run then confirmed it: template T6 (per-field, then SimpleText with deletes and a merge, then a per-field merge) failed 1,716 of 10,935 cases, and T6b (the same through addIndexes(CodecReader)) 1,716 of 5,832; every failure was predicted and every predicted case failed; the other 6 templates had 0 failures. The reader-wrapper route was found later, by the cross-model fact check of this doc reading the code, and then executed. No model checker, SMT solver or prover was involved.
No prior report found (115 logged queries of GitHub, JIRA, five mailing lists, downstream projects and the web, 2026-10-26). Closest: LUCENE-9992 and LUCENE-10228 fixed the same kind of mistake for vectors in 2021; LUCENE-8601 introduced this one.
Searches5 searches
Verdict: new (no report of the same bug, by anyone). Not fixed upstream: no commit has touched PerFieldPostingsFormat.java since b6ca26f1212 (2026-06-30), and none of the 412 open PRs touches it.
Closest items: #11031 / LUCENE-9992 (vectors: a deleted-away field kept its FieldInfo after a merge with no vector files written), PR #432 / LUCENE-10228 (the vectors merge read an inherited per-field suffix), #9098 / LUCENE-8050 (the doc-values merge iterates mergeFieldInfos). Context: #9647 / LUCENE-8601 (introduced the carry-over), #8508 / LUCENE-7456 (the producer-driven postings merge, 2016), #11393 / LUCENE-10357 (ghost fields), LUCENE-7562 (same delete-merge-add-merge shape, another root cause), #11327 / LUCENE-10291, #13353 (same missing-file symptom from IndexingChain).
Gaps: two manual GitHub queries hit GitHub's search rate limit and one was not retried (its terms are covered by other queries); one web query was throttled; the list search matches whole words only; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene and downstream projects) | 2026-10-26 | two automated runs plus manual searches: PerFieldPostingsFormat attributes, stale per-field suffix, SimpleText forceMerge FileNotFoundException, the attribute keys, the LUCENE-8601 TODO | no report; precedent LUCENE-9992 and LUCENE-10228 (vectors) |
| Open PRs (apache/lucene) | 2026-10-26 | the changed files of all 412 open PRs | none touches PerFieldPostingsFormat.java |
| JIRA archive (LUCENE, SOLR) | 2026-10-26 | JQL and the old keys LUCENE-7456, 8050, 8601, 9992, 10228, 10291, 10357, 7562, each read | no report |
| Mailing lists (dev@, java-user@, issues@, commits@, builds@) | 2026-10-26 | symptom strings and attribute keys | no report |
| Web and git history | 2026-10-26 | 8 web searches; git log of PerFieldPostingsFormat.java and PerFieldDocValuesFormat.java; -S for the TODO | no report; only LUCENE-8601 matched the TODO |
Introduced in 7.7.0 by LUCENE-8601 (2019), which made merged FieldInfos keep the source attributes: 7.6.0 passes, 7.7.0 fails, and 7.7.0 with only that hunk reverted passes. Every executed release from 7.7.0 to 10.5.2 and main fails. Not fixed upstream.
Versions tested6 rows
Introduced by LUCENE-8601 "Adding attributes to IndexFieldType" (now #9647; a JIRA patch series, no pull request; patch by @muralikpbhat, committed by @mikemccand): master 63dfba4c7d81 (2019-01-03, first released in 8.0.0) and branch_7x e8bfa6771636 (2019-01-04), first released in 7.7.0 (2019-02-11). FieldInfos.Builder.add started passing fi.attributes() where 7.6.0 used an empty map, and the per-field formats' "found existing value" checks became plain overwrites. The producer-driven field list is older (LUCENE-7456, 796ed508f39, 2016) and was harmless while merged attributes were dropped.
Later: LUCENE-9334 (d03662c48bf, 9.0) rewrote Builder.add and documented the carry-over; #13331 (thread-safe attribute updates in FieldInfo) and #15457 (attribute-map handling) changed the surrounding code and kept the carry-over. So the fix belongs in the postings merge, not in FieldInfos.
All runs on Linux aarch64 with JDK 25.0.3; release jars from Maven Central, SHA-1 checked.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 3 of 3 fail (gradle and harness, assertions on and off; 30/30 over random seeds); the reader-wrapper probe 2 of 2 (-ea, -da) |
| 10.5.2 | affected | this doc's test 3 of 3 fail (-ea and -da); the finder's test 2 of 2; the reader-wrapper probe 2 of 2 (-ea) |
| 7.7.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 | affected | the finder's era-adapted JUnit fails 2 of 2 (missing per-field postings files: .doc in the 7.7.0, 8.11.4 and 9.0.0 runs) |
| 7.7.0 with only the LUCENE-8601 carry-over hunk reverted | bisect | passes 2 of 2 |
| 6.6.6, 7.5.0, 7.6.0 | not affected | the index opens; the SimpleText segment has no per-field attributes |
fix on main a9779ef3c193 | not affected | the test 3/3, lucene/core 8,892 tests, lucene/codecs and lucene/backward-codecs pass |
An independent reproducer, a devil's-advocate checker, an adjudication and an audit confirmed it with their own runs; OpenAI GPT-5.6 reviews (reading only) agreed on the root cause. This doc re-ran it on a9779ef3c193 and validated the fix; its fact checks added the reader-wrapper route, executed.
Checks and verdicts437 words
The verifier checks ran on main ea57360912ed; this doc and the main-refresh re-runs used a9779ef3c193 (none of the 7 commits in between touches the files involved). The GPT-5.6 reviews ran reading only, because their runner could not execute code.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Exhaustive harness: T6 1,716/10,935 and T6b 1,716/5,832 failures, all predicted; JUnit fails 2/2 on main (-ea, -da), 10.5.2, 9.12.3, 8.11.4, 7.7.3, 7.7.0; passes on 7.6.0; the fix turns T6/T6b to 0. |
| review (OpenAI GPT-5.6, reading only) | real, high | Trigger legal, root cause agrees, fix plausible, intended reading weak; its corrections (the 'not a written group' condition, wording, unused imports) were taken. |
| Independent reproducer | real | Own tests fail on main (-ea, -da), 10.5.2 and 9.12.3, 20/20 over random seeds; the Lucene104Codec-subclass variant shows tag={format=FST50, suffix=0} with only _4_Lucene104_0.* files; 3 controls pass 30/30; the fix turns every test green. |
| Root-cause review (OpenAI GPT-5.6, reading only) | real, high | Root cause agrees, fix plausible. The refute and works-as-designed lenses returned no verdict. A separate run re-ran the repro itself: 2/2 fail, 2/2 pass with the fix. |
| Intended-behaviour devil's advocate | real, intended reading weak | Public-API main() on FSDirectory fails for three mappings; reproduced without SimpleText through an SPI-registered custom codec with a plain postings format; 40 intent queries found no by-design discussion. |
| Adjudication | confirmed, high | Re-ran the independent reproduction (fresh seed, -ea and -da), the intended-behaviour check's custom codec (-da), the controls (pass) and the fix (pass). |
| History follow-up | introduced in 7.7.0 | Fails on 8 releases from 7.7.0 to 10.5.2 and on main; passes on 6.6.6, 7.5.0, 7.6.0; 7.7.0 with only the carry-over hunk reverted passes. |
| Security screen | not security-sensitive | Executed probe: fails closed (no hang, no wrong hits, no data exposure); operator-only trigger, out of scope of SECURITY.md. |
| Main refresh | still reproduces | The finder's test (-ea, -da) and the independent reproduction's Lucene104Codec-subclass test fail on a9779ef3c193 as on ea57360912ed. |
| This doc's runs | reproduced on a9779ef3c193; fix validated | New 3-test JUnit: 3/3 fail through gradle (assertions on and off), 30/30 over random seeds, 3/3 on 10.5.2; with the fix 3/3 pass and the lucene/core, lucene/codecs and lucene/backward-codecs suites pass. |
| Fact checks of this doc | no error in the mechanism; corrections taken | An independent re-run (main -ea/-da, 10.5.2, the fix) found no error. A cross-model fact check (OpenAI GPT-5.6, reading only) found that a merge-reader wrapper reaches the bug with per-field codecs throughout; executed: 2/2 fail on main and 10.5.2, 2/0 hiding nothing, 2/0 with the fix. Its other corrections (suffix order, workaround, template count, wording) were taken. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 526 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,326 words
- Registry title
- PerFieldPostingsFormat merge leaves stale inherited format attributes on a field that has no postings left after a segment written by a non-per-field postings codec (for example SimpleTextCodec), so the merged segment cannot be opened
- Area
- codecs / per-field postings format merge (PerFieldPostingsFormat attribute bookkeeping)
- Priority
- Medium, rank 157: Like LFV-199, a commit cannot be opened, here after a merge that mixes in a non-per-field postings codec plus a fully deleted field, which is rare but severe.
- Impact class
- index unusable
- Impact note
- Only applications that mix a writer session with a non-per-field postings codec (in-tree only SimpleTextCodec, 'FOR RECREATIONAL USE ONLY', or a custom codec whose postingsFormat() is a plain format) into an index that otherwise uses per-field postings are exposed, on every release from 7.7.0 through 10.5.2 and on main, with no scale needed and default configurations unaffected; it further needs a field whose every document is deleted before that segment is merged and a later per-field merge that writes no group with the field's inherited (format name, suffix) (a field with its own per-field format or format instance, or no indexed field left), and then every writer call succeeds but the committed merged segment cannot be opened, an open writer keeps committing on top of it, and CheckIndex -exorcise drops every document of that segment.
- Summary
- You index a field with a per-field postings codec (for example a Lucene104Codec subclass that maps the field to its own postings format), then, in a writer session whose codec's postings format is not per-field (SimpleTextCodec or a custom codec), delete every document that has the field and force-merge, and then go back to the per-field codec and merge again. You expect the committed index to open, because every call returned normally. Instead the merged segment still records the field's old format name and suffix although the merge wrote no files for that group, so DirectoryReader.open and CheckIndex fail with CorruptIndexException caused by a missing <segment>_<format>_<suffix>.psm (for example _4_FST50_0.psm).
- Introduced
- 63dfba4c7d81a019a4008777beace0d391987ceb on master and its branch_7x commit e8bfa67716368ff3ad670a63d4a8935c6a989cac (the one 7.7.0 shipped), LUCENE-8601 'Adding attributes to IndexFieldType' (now apache/lucene#9647; a JIRA patch series, no pull request; patch by muralikpbhat, committed by mikemccand): merged FieldInfos started to keep the source attributes (FieldInfos.Builder.add passes fi.attributes() where 7.6.0 used an empty map) and the per-field formats' 'found existing value' checks became plain overwrites, while the postings merge kept choosing its fields from the source producers (logic from the default FieldsConsumer.merge and LUCENE-7456, 796ed508f39, 2016), so a field that no source postings reader lists keeps its inherited attributes [read: git show in the history clone and the #9647 thread; exec: 7.6.0 passes, 7.7.0 fails, and 7.7.0 with only the merge carry-over hunk reverted passes] (2019-01-03 (master 63dfba4c7d8) and 2019-01-04 (branch_7x e8bfa677163, released in 7.7.0))
- First affected version
- 7.7.0 (released 2019-02-11), with -ea and -da [exec]; the master commit first shipped in 8.0.0 (2019-03-14); 7.6.0 and earlier are not affected [exec 6.6.6, 7.5.0, 7.6.0]
- Affected versions
- 7.7.0 through 10.5.2 (the last release before 10.6.0) and main ea57360912ed, with -ea and -da [exec, the canonical 2-test JUnit, 2 of 2 fail each: 7.7.0 (-ea, -da), 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3 (-ea, -da), 10.0.0, 10.5.2 (-ea, -da), main (-ea, -da); the independent reproduction's own tests also fail on 10.5.2 and 9.12.3]; [read] every release tag in the history clone from 7.7.0 on contains 63dfba4c7d8 or e8bfa677163 (the clone lacks the 8.8.2 to 8.11.4 tags; 8.11.4 was executed); not affected: every release up to and including 7.6.0 [exec 6.6.6 and 7.5.0 (attribute probe), 7.6.0 (-ea, -da); read 4.10.4 and 5.5.5]; not fixed upstream: no commit has touched PerFieldPostingsFormat.java since b6ca26f1212 (upstream main e1c4184cb983 at search time) and none of the 412 open PRs touches it; executed on aarch64 with JDK 25, release jars checksum-verified against Maven Central
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that agreed, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (follow-up prior-report record verdict new, searched 2026-10-26, read-only: 115 query lines, among them two scripted prior-report searches (55 queries over GitHub issues, PRs and commits, the downstream repositories, the dev@, java-user@, issues@ and commits@ lists and JIRA; 24 more list and JIRA queries), manual GitHub searches over apache/lucene, Elasticsearch, OpenSearch and Solr, manual list-archive and JQL searches, 8 web searches, the changed-file lists of all 412 open apache/lucene PRs, and the git history of PerFieldPostingsFormat.java and PerFieldDocValuesFormat.java; the finder's run (51 queries) and the intended-behaviour check's intent run (40 queries) found nothing either); related, not this bug: #9647 / LUCENE-8601 (the change that introduced it; its thread says the per-field formats relied on attributes being dropped on merge, and never discusses fields the postings merge does not visit), #11031 / LUCENE-9992 (the vectors analogue: a field whose documents were all deleted kept its FieldInfo after a merge with no vector files written; fixed for vectors only in 2021), PR #432 / LUCENE-10228 (the vectors merge read an inherited per-field suffix; fixed in PerFieldKnnVectorsFormat only), #9098 / LUCENE-8050 (the doc-values merge iterates mergeFieldInfos), #8508 / LUCENE-7456 (added the producer-driven postings merge), #11393 / LUCENE-10357 (ghost fields), LUCENE-7562 and testLevel2Ghosts (the same delete-merge-add-merge shape with one codec, another root cause), #11327 / LUCENE-10291, #13353 (the same missing-file symptom from IndexingChain); not fixed upstream
- Lucene commit tested
- main
a9779ef3c193(2026-10-26): this doc's JUnit through gradle in a scratch worktree (assertions on and off) and through the standalone JUnit runner (assertions on and off, 10 random-seed iterations); the 10.5.2 release jars; the reader-wrapper probe (main-eaand-da, 10.5.2-ea); the fix with the whole lucene/core suite, lucene/codecs and lucene/backward-codecs (assertions on). The verifiers and the security probe ran on mainea57360912ed, and the history sweep on the release jars of 6.6.6 to 10.5.2 plus mainea57360912ed; none of the 7 commits between the two mains touches the files involved.
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldPostingsFormat.java:171-181 (merge field list from the producers' iterators), 199-253 (buildFieldsGroupMapping; 210 TODO; 248 putAttributes), 295-321 (FieldsReader; 305 'null formatName means the field is in fieldInfos, but has no postings!'; 318 and 331-332 iterator over the fields that carry the attribute), 379-385 (getPostingsFormatForField javadoc)lucene/core/src/java/org/apache/lucene/index/SegmentMerger.java:232-239 (every source FieldInfo added to the merged builder)lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:731-732, 756-757 (javadoc: attributes added on merge), 771-801 (attribute copy)lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldDocValuesFormat.java:135 and lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:135 (doc-values and vectors merges iterate mergeFieldInfos)lucene/codecs/src/java/org/apache/lucene/codecs/simpletext/SimpleTextCodec.java:35 ('FOR RECREATIONAL USE ONLY')lucene/core/src/test/org/apache/lucene/index/TestMixedCodecs.java:49 ('Make sure we aggressively mix in SimpleText')
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldPostingsFormat.java:171-181 (merge field list from the producers), :199-253 (buildFieldsGroupMapping; :210 TODO; :248-253 putAttributes), :295-321 (FieldsReader; :305 comment; :316 fieldsProducer; :318 fields.put), :331-332 (iterator), :379-385 (getPostingsFormatForField javadoc)lucene/core/src/java/org/apache/lucene/index/SegmentMerger.java:232-239 (mergeFieldInfos)lucene/core/src/java/org/apache/lucene/index/FieldInfos.java:731-732, :756-757 (javadoc), :771-801 (add; :775-777 putAttributes, :801 new HashMap<>(fi.attributes()))lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldDocValuesFormat.java:135-140; lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:135lucene/codecs/src/java/org/apache/lucene/codecs/simpletext/SimpleTextCodec.java:35; lucene/test-framework/src/java/org/apache/lucene/tests/codecs/cheapbastard/CheapBastardCodec.java:26-37lucene/core/src/java/org/apache/lucene/index/MergeState.java:133, :155; lucene/core/src/java/org/apache/lucene/index/FilterCodecReader.java:84
- Who is affected
lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:302; lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3275; lucene/core/src/java/org/apache/lucene/index/SlowCodecReaderWrapper.java:385-397; lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:521-523lucene/benchmark/src/java/org/apache/lucene/benchmark/byTask/tasks/CreateIndexTask.java:150-161
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldPostingsFormat.java:305, :379-385lucene/core/src/java/org/apache/lucene/index/IndexWriterConfig.java:292-297lucene/core/src/test/org/apache/lucene/index/TestMixedCodecs.java:49-52lucene/test-framework/src/java/org/apache/lucene/tests/util/SetupAndRestoreStaticEnv.java:185-197lucene/core/src/java/org/apache/lucene/codecs/package-info.java:40-64lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:669-671; lucene/core/src/java/org/apache/lucene/codecs/FilterCodec.java:53lucene/core/src/java/org/apache/lucene/codecs/perfield/PerFieldPostingsFormat.java:63 (@lucene.experimental)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/FieldInfo.java:655-698 (getAttribute, putAttribute, putAttributes, attributes(); no remove)
- TestPerFieldPostingsStaleAttributes.java (JUnit test):
repro/LFV-280/src/org/apache/lucene/codecs/perfield/TestPerFieldPostingsStaleAttributes.java(59 lines)
Made in parallel with this doc from an executed tracing probe of the same scenario on main a9779ef3c193 (segment names, attributes, files and the CheckIndex result); every value on screen is asserted against the probe traces and every code line against the source. Re-rendered after the checks: the summary card names the shown trigger as one of two routes and mentions the reader-wrapper route, and the missing file is labelled "not in the index" / "missing" (the probe used an in-memory directory).
assets/LFV-280/bug.png(526 KB)