Lucene rejects a custom term frequency that the field cannot index, which is correct. But the check runs while the token is being written into the in-memory index, a step where an exception aborts the in-memory segment and closes the writer. So one rejected document costs everything since the last commit.
- Custom term frequencies. Normally Lucene counts how often a term occurs in a document. With
TermFrequencyAttributean analyzer sets the frequency itself;DelimitedTermFrequencyTokenFilterturnsred|2into the termredwith frequency 2. The field must index frequencies (DOCS_AND_FREQS). - Per-document rejection. When a document is invalid, for example its offsets go backwards,
addDocumentthrows and only that document is skipped. The writer stays open and earlier buffered documents are kept. - Aborting exceptions. An exception in the middle of writing the in-memory index is "aborting": the in-memory index may be inconsistent, so the writer drops it, closes itself and rolls back to the last commit.
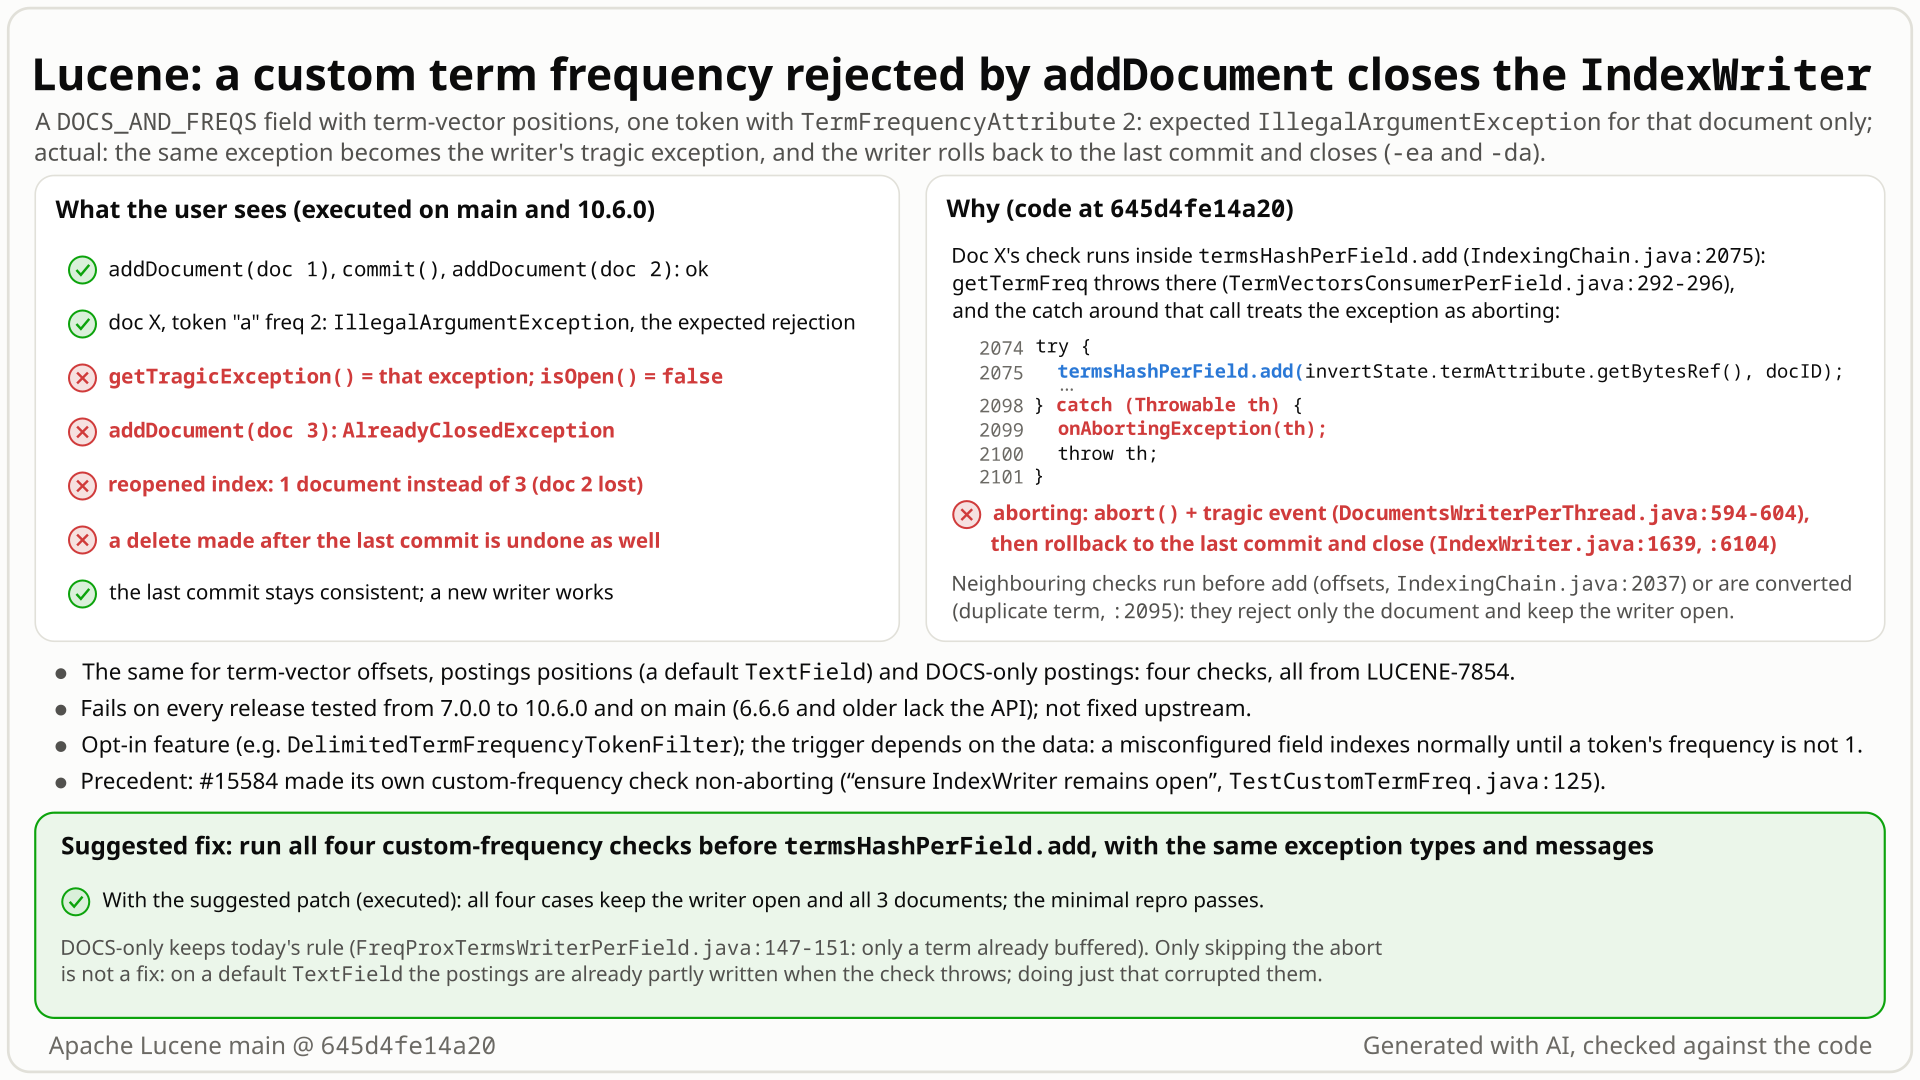
- A field indexes term frequencies (
DOCS_AND_FREQS, asTermFrequencyAttributerequires) and also stores term vectors with positions. You commit doc 1, add doc 2 (buffered, not committed), then add a document whose only tokenahas custom frequency 2. - You expect
addDocumentto reject just that document (IllegalArgumentException: cannot index term vector positions while using custom TermFrequencyAttribute) and the writer to stay open: add doc 3, commit, and the index has 3 documents. - Instead the rejection becomes the writer's tragic exception: the writer closes itself, adding doc 3 throws
AlreadyClosedException, and the index has 1 document. Doc 2 is gone. - Why: the frequency check runs inside
termsHashPerField.add, andIndexingChaintreats every exception from that call as aborting (the in-memory index may be half-written), except two it converts into ordinary rejections. - Term-vector offsets, positions in the postings (any default
TextField) and DOCS-only fields behave the same. Checking the frequency beforeaddkeeps the writer open.
Applications that index custom term frequencies (their own TermFrequencyAttribute or DelimitedTermFrequencyTokenFilter) into a field that also stores term-vector positions or offsets, indexes positions (any default TextField) or is DOCS-only. Default config, no codec configured, any scale. The trigger depends on the data: a misconfigured field works until the first token with a frequency other than 1.
Mechanism, terms and numbers606 words
Lucene lets analysis set a per-token term frequency through TermFrequencyAttribute, for example with DelimitedTermFrequencyTokenFilter, which turns red|2 into the term red with frequency 2. When the field also stores term-vector positions or offsets, indexes postings positions (any default TextField), or is DOCS-only and the term repeats, addDocument rejects the document, as upstream tests assert. But the four checks run inside termsHashPerField.add, which IndexingChain treats as aborting, so the rejection also becomes the writer's tragic exception: the IndexWriter closes itself, every add, update and delete since the last commit is rolled back, and every later indexing change or commit throws AlreadyClosedException until a new writer is opened. The neighbouring offset and position checks, and the duplicate-term rejection #15584 added for the same feature in the same try, only reject the document. The bug came in with the feature (LUCENE-7854, 7.0.0) and is in every release up to 10.6.0 and on main.
- The token loop.
IndexingChain.invertTokenStreamhandles one token at a time. Its position, offset and length checks (IndexingChain.java:1996-2064) throw plainIllegalArgumentExceptions outside the abortingtry, so they only reject the document (the comment at:1989-1994says the same of analyzer exceptions). - The aborting call.
IndexingChain.java:2068-2073: "If we hit an exception in here, we abort all buffered documents since the last flush, on the likelihood that the internal state of the terms hash is now corrupt". ThentermsHashPerField.add(...)(:2074-2075). OnlyMaxBytesLengthExceededException(:2076-2094) and #15584'sDuplicateTermException(:2095-2097) are converted to non-abortingIllegalArgumentExceptions; everything else reachescatch (Throwable th) { onAbortingException(th); throw th; }(:2098-2101). - Where the checks are.
TermsHashPerField.add(TermsHashPerField.java:190-209) adds the term to the hash, then callsnewTermoraddTermof the postings writer and then of the term-vector writer. The four checks sit inside those calls; three of them run after state was changed, the DOCS-only one before anything is written:- postings positions:
FreqProxTermsWriterPerField.getTermFreq(:208-219,IllegalStateException"cannot index positions while using custom TermFrequencyAttribute"), called fromnewTerm(:125) andaddTerm(:177,:196); - DOCS-only:
FreqProxTermsWriterPerField.addTerm(:145-152,IllegalStateException"must index term freq while using custom TermFrequencyAttribute"); it runs only when the term is already in the in-memory segment, becausenewTermhas no such check (:119-122), and it throws at the top ofaddTerm, before any write (for an existing termbytesHash.addonly returns its id); - term-vector positions and offsets:
TermVectorsConsumerPerField.getTermFreq(:286-307,IllegalArgumentException), called fromnewTerm(:270) andaddTerm(:281).
- postings positions:
- Abort and close.
DocumentsWriterPerThread.maybeAbort(:594-605, called at:310) aborts the in-memory segment and fires the tragic event;IndexWriter.updateDocuments(IndexWriter.java:1625-1642, used byaddDocument) then callsmaybeCloseOnTragicEvent(:1639), which rolls the writer back (:6098-6106).
The study's four-case test commits doc 1, buffers doc 2, adds the rejected document, then adds doc 3 and commits. Expected for every case: tragic=null isOpen=true nextAddAndCommit=ok committedDocs=3. Actual on main, for term-vector positions, term-vector offsets, postings positions and DOCS-only: tragic=<the rejection> isOpen=false nextAddAndCommit=AlreadyClosedException committedDocs=1. Its controls pass: backwards offsets on the same field type keep the writer open with 3 documents, and frequency 3 on a DOCS_AND_FREQS field without term vectors is indexed and reads back 3.
With the shipped filter on a field with term-vector positions, 5 committed and 5 buffered documents, one document red|2 green makes the rejection tragic. On a default TextField, documents without a delimiter index normally for the whole session; the first words|2 closes the writer and the 5 buffered documents are lost.
Exposure and likelihood281 words
- Who. Users of the opt-in custom-term-frequency feature, through their own
TokenStreamor the shippedDelimitedTermFrequencyTokenFilter(factory namedelimitedTermFrequency), on a field that stores term-vector positions or offsets (allowed byTermFrequencyAttribute's stated precondition; the filter's javadoc, "no positions or offsets", may be read as ruling these out too), indexes postings positions (any defaultTextField; the filter's javadoc forbids it) or is DOCS-only (the attribute's javadoc asks forDOCS_AND_FREQS). - What it costs. One such document closes the writer. Every add, update and delete since the last commit is rolled back: in the study's probe a document deleted after the last commit was live again in the reopened index, and an update was undone. Other threads' buffered documents go too; that follows from the rollback but was not executed (all runs were single-threaded). The application must open a new writer and re-index everything since the last commit.
- Not affected. The committed index stays consistent and a new writer works; an NRT reader opened earlier keeps its view.
FeatureField, the core field that usesTermFrequencyAttribute, has no positions and no term-vector positions or offsets, so it never reaches these checks (code reading). - Conditions. Default
IndexWriterConfigwith no codec configured (the gradle runs used the test framework's randomizedAsserting(Lucene104)codec; the core-only probe runs with Lucene's default codec), assertions on and off, ordinary scale, one thread. Data-dependent: with the filter, the firstword|Nwith N != 1 fires it. - How likely: rare. It needs the opt-in feature plus a field setting the javadoc rules out or an unusual term-vector choice, and the failure is loud; but a misconfigured field can run for a long time before the first such token.
One JUnit test, one thread, deterministic, public API: one document whose only token has term frequency 2, on a DOCS_AND_FREQS field with term-vector positions; addDocument must throw, then the writer must have no tragic exception.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.FieldType;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.CannedTokenStream;
import org.apache.lucene.tests.analysis.Token;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestCustomTermFreqRejectionKeepsWriterOpen extends LuceneTestCase {

  public void testTermVectorPositionsRejectionKeepsWriterOpen() throws Exception {
    FieldType ft = new FieldType();
    ft.setIndexOptions(IndexOptions.DOCS_AND_FREQS);
    ft.setStoreTermVectors(true);
    ft.setStoreTermVectorPositions(true);
    Token token = new Token("a", 0, 1);
    token.setTermFrequency(2);
    Document doc = new Document();
    doc.add(new Field("f", new CannedTokenStream(token), ft));
    try (Directory dir = newDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      expectThrows(IllegalArgumentException.class, () -> w.addDocument(doc));
      // expected: only the document is rejected; actual: its exception closes the writer as tragic
      assertNull("tragic exception", w.getTragicException());
    }
  }
}
cd $LUCENE && ./gradlew :lucene:core:test --tests TestCustomTermFreqRejectionKeepsWriterOpen -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
addDocumentthrowsIllegalArgumentExceptionfor this document only, andgetTragicException()isnull.- Observed
- The same
IllegalArgumentExceptionis the writer's tragic exception:AssertionError: tragic exception expected null, with assertions on and off.
More files, environment, full output286 words
The field meets TermFrequencyAttribute's precondition (DOCS_AND_FREQS). The token comes from the test framework's CannedTokenStream with one Token whose term frequency is 2; the writer uses the default IndexWriterConfig. The test sits in org.apache.lucene.index, as Lucene's own tests do, but uses no package-private API. Line 40 of the file (expectThrows, counting the license header) passes, so the documented rejection is unchanged; only line 42 fails. No commit or extra documents are needed: the tragic exception alone shows the writer closed, and the rollback of uncommitted work follows from it (shown by the study's longer test, in the collapsed explanation above).
The other three cases (term-vector offsets, postings positions, DOCS-only) share the root cause and were executed by the study's longer test; they are not part of this repro.
Regression test: this same test; it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; with the fix: passes. Also fails on the 10.6.0 and 10.5.2 release jars |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; the code path is pure Java) |
cp $REPRO/TestCustomTermFreqRejectionKeepsWriterOpen.java $LUCENE/lucene/core/src/test/org/apache/lucene/index/
cd $LUCENE && ./gradlew :lucene:core:test --tests TestCustomTermFreqRejectionKeepsWriterOpen -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
TestCustomTermFreqRejectionKeepsWriterOpen > testTermVectorPositionsRejectionKeepsWriterOpen FAILED
    java.lang.AssertionError: tragic exception expected null, but was:<java.lang.IllegalArgumentException: field "f": cannot index term vector positions while using custom TermFrequencyAttribute>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:EED294BF6AE05155]:0)
        at org.junit.Assert.assertNull(Assert.java:738)
        at org.apache.lucene.index.TestCustomTermFreqRejectionKeepsWriterOpen.testTermVectorPositionsRejectionKeepsWriterOpen(TestCustomTermFreqRejectionKeepsWriterOpen.java:42)
> Task :lucene:core:test FAILED

# the study's four-case test on the same stock build (gradle, seed DEADBEEF): 6 tests completed, 4 failed
testTermVectorPositions  expected:<tragic=[null isOpen=true nextAddAndCommit=ok committedDocs=3]> but was:<tragic=[IllegalArgumentException isOpen=false nextAddAndCommit=AlreadyClosedException committedDocs=1]>
testTermVectorOffsets    same, IllegalArgumentException
testPostingsPositions    same, IllegalStateException
testExtraDocsOnlyRepeatedTerm same, IllegalStateException- #15584's duplicate-term rejection, for the same feature and in the same
try, keeps the writer open on purpose ("ensure IndexWriter remains open and doc was skipped"). - The repro's field meets the documented precondition (
DOCS_AND_FREQS); nothing documents that this rejection closes the writer. - LUCENE-5662 fixed the same pattern as a bug: missing checks let a null stored value abort the writer.
The full argument297 words
- Same feature, same
try, opposite outcomes. #15584 (10.5.0) added a custom-frequency rejection (a duplicate term on aDOCS_AND_CUSTOM_FREQSfield) in this verytryand made it non-aborting (IndexingChain.java:2095-2097);TestCustomTermFreq.java:125says "ensure IndexWriter remains open and doc was skipped". The PR's author, msokolov, wrote in the PR conversation that they "found that the exception I raised for duplicate terms in termdoc fields would cause the writer to crash, so added some exception handling that merely skips the doc being indexed (same as for a too-large term)". With the same index options (DOCS_AND_CUSTOM_FREQS; the duplicate-term case without term vectors), the duplicate term keeps the writer open with 3 documents committed, while frequency 2 with term-vector positions closes it with 1. - The precondition is met.
TermFrequencyAttributeasks only forDOCS_AND_FREQS(TermFrequencyAttribute.java:23-27); theDOCS_AND_CUSTOM_FREQSjavadoc says nothing about term vectors (IndexOptions.java:52-56). Upstream's own test of the term-vector rejection usesDOCS_AND_CUSTOM_FREQS+ term-vector positions (TestCustomTermFreq.java:471-496). - Nothing documents the close. The
IndexWriterjavadoc names "an Error, or disaster strikes during a checkpoint" (IndexWriter.java:162-165);addDocumentsays after an exception "the index will be consistent, but this document may not have been added" (:1465-1466); LUCENE-5987 describes aborting exceptions as ones "that would otherwise cause silent data loss". - Precedent. LUCENE-5662 is listed under "Bug fixes" in 4.8.1;
testNullStoredFieldandtestCrazyPositionIncrementGapassertgetTragicException() == nullafter a rejected document, and LUCENE-5611'stestNoAbortOnBadTVSettingschecks "the exc didn't lose our first document". - Why upstream tests never noticed. The four rejection tests end with
IOUtils.close(w, dir)and never look at the writer, andclose()after a tragic close does nothing (close(),IndexWriter.java:1363-1369, callsshutdown()orrollback(), which stop atshouldClose,:1374-1392). The LUCENE-7854 discussion (34 comments) never mentions aborting.
The devil's-advocate check197 words
The strongest case: this is misuse, because TermFrequencyAttribute requires DOCS_AND_FREQS and DelimitedTermFrequencyTokenFilter says "no positions or offsets"; and every exception from add is aborting on purpose, because the terms hash may be corrupt. The study confirmed that part for the postings-positions check: a shadow that only skips the abort, run on a default TextField, corrupts the in-memory postings (AssertionError with assertions on; docs out of order or cannot write negative vLong at flush with assertions off). It was not run for the term-vector or DOCS-only checks; the DOCS-only check throws before anything is written.
Why it fails: for TermFrequencyAttribute (the repro's API) the misuse argument covers only the postings-positions and DOCS-only cases (it lowers their severity); the term-vector cases are inside the attribute's stated precondition. The filter's javadoc can be read as also ruling out term-vector positions and offsets. The second half explains why the abort is needed once a check fires mid-write, not why a deterministic check of the token against the field type must run there: moving it before add keeps the exception types and messages, keeps the writer open and passes upstream's tests. A maintainer may still label the change an improvement.
Recommended Validate the custom frequency before termsHashPerField.add (validated)
Check the custom frequency in IndexingChain before termsHashPerField.add: the same four conditions, exception types, messages and DOCS-only rule, thrown before anything is written, so only the document is rejected (+50 lines in two files). The repro, the four-case test, the closest suites and the whole core module pass.
if (invertState.termFreqAttribute.getTermFrequency() != 1) {
  // Check here, not inside termsHashPerField.add below: an exception thrown from there
  // aborts all buffered documents, while this one only rejects the current document.
  validateCustomTermFrequency(field);
}
All options and trade-offs4 options · 842 words
Option A was built and run. B, a simpler variant, was run too and breaks an upstream test. C is the study's earlier, partial fix. D is not recommended.
In IndexingChain.invertTokenStream, right after the offset checks (IndexingChain.java:2051), a token whose frequency is not 1 goes through a new validateCustomTermFrequency(field). In the order the old checks fire, it throws IllegalStateException "must index term freq ..." for a DOCS-only field when the term is already buffered (a new TermsHashPerField.containsTerm, bytesHash.find(termBytes) >= 0, true exactly when add would call addTerm), IllegalStateException "cannot index positions ..." when postings have positions, and IllegalArgumentException "cannot index term vector positions / offsets ..." when the field stores term vectors with positions or offsets.
if (invertState.termFreqAttribute.getTermFrequency() != 1) {
  // Check here, not inside termsHashPerField.add below: an exception thrown from there
  // aborts all buffered documents, while this one only rejects the current document.
  validateCustomTermFrequency(field);
}
Trade-offs
- Old checks. The checks inside
addstay; with the fix they are no longer reached fromIndexingChain. They could become assertions. - Which exception wins. A document with two problems may report a different one first (for example the term-vector check before #15584's duplicate-term check; both reject only the document). It also runs before the field-length overflow check (
IndexingChain.java:2053-2064): a term repeated on a DOCS-only field whose frequency would also overflow the field length gets the DOCS-onlyIllegalStateExceptioninstead of "too many tokens"; both reject only the document. - Cost. One
intcomparison per token; for ordinary fields the frequency is already read for the field length (IndexingChain.java:2057-2059), forDOCS_AND_CUSTOM_FREQSfields it is one extra attribute read. The field checks, and for DOCS-only fields one hash lookup, run only for frequencies other than 1. No benchmark was run. - Conflicts. Open PR #16269 ("Lazily build the term-vectors per-field", states no behaviour change) also edits
IndexingChain.javaandTermsHashPerField.java, in other hunks; it leaves the checks and the abort handling unchanged, so at most a textual rebase is needed.
What the checks validated
Applied to a scratch worktree of 645d4fe14a20 and run through gradle with OpenJDK 25.0.3, seed DEADBEEF (2026-10-30):
- stock: the minimal test fails with assertions on and off; the study's four-case test fails 4 of 6;
- with the fix: the minimal test passes with assertions on and off; the four-case test passes 6 of 6 with assertions on and off (all four cases keep the writer open with 3 committed documents);
- the closest suites
TestCustomTermFreq,TestTermVectorsWriter,TestTermVectors,TestIndexWriterExceptionsandTestFeatureFieldpass (88 tests, 0 failures, 3 skipped), and so doesTestDelimitedTermFrequencyTokenFilter(3 tests); - the whole
:lucene:core:testpasses (748 classes, 8,897 tests, 0 failures, 322 skipped; run after the two copied tests were removed, so it checks upstream core with the patch);checkGoogleJavaFormat,ecjLintMainandforbiddenApisMainfor core pass. - assertions on and off were run for the minimal and the four-case test; the closest suites, the filter's tests and the whole core module ran with assertions on.
Variant: reject a custom frequency on a DOCS-only field at its first occurrence (run, breaks a test)
The same check without the hash lookup (+42 lines, IndexingChain.java only). It matches the attribute's javadoc and the comment "you can't index DOCS_ONLY with custom term freq" (TestCustomTermFreq.java:373).
Trade-offs
Changes behaviour an upstream test relies on: the minimal test, the four-case test and the filter's tests pass, but TestCustomTermFreq.testOverflowInt, which indexes frequencies 3 and Integer.MAX_VALUE on a DOCS field and expects the length-overflow IllegalArgumentException, now gets IllegalStateException: ... must index term freq .... It was the only failure in the org.apache.lucene.index package (1402 tests). Its lint run is incomplete: checkGoogleJavaFormat failed on a formatting nit in the copied four-case test, not in the patch. A stricter DOCS-only rule would be a separate change.
Moves the postings-positions and term-vector checks before add, not the DOCS-only check.
Trade-offs
The repro passes, and so do upstream TestCustomTermFreq (15 tests) and the term-vector, exception and addIndexes suites the study ran (56 and 92 tests); but a DOCS-only field with a repeated term still closes the writer (the four-case test fails 1 of 6).
Convert them in the catch chain, as #15584 did for DuplicateTermException.
Trade-offs
Unsafe for the postings-positions check: it fires after the postings were partly written, and the study's shadow that skips the abort corrupts the in-memory postings (AssertionError with assertions on; CorruptIndexException: docs out of order or cannot write negative vLong at flush with assertions off). The term-vector checks also fire after state was written (not tested with a shadow), and moving them to the top of newTerm is not enough, because for a new term the hash and stream slices were already updated. The DOCS-only check throws before anything is written, so a targeted non-aborting catch might be safe there, but that was not tested; checking all four before add avoids the question.
OpenSearch exposes this filter as delimited_term_freq; by code reading only, a tragic writer exception there fails the shard copy.
While modelling the term-vector encoding, the finder read TermVectorsConsumerPerField and noticed that its custom-frequency rejection runs inside the aborting add call. A public-API JUnit on the stock jars confirmed that the rejection closes the writer; independent checkers then found the fourth (DOCS-only) case.
The method in full144 words
Method: code reading, then executed public-API tests (the hunt classes it as non-formal). The finder was building a Z3 (SMT) model of the term-vector encoding; the model covers the encoding, not this exception path, and no formal tool witnessed the bug.
- First test. Commit one document, buffer one, add a document whose token stream sets
TermFrequencyAttributeto 3, then add and commit another: all three of its bug cases closed the writer, and its control (offsets going backwards, rejected beforeadd) kept it open. - Widening. An independent reproducer, writing its own test from the claim only, found the DOCS-only case; a devil's-advocate verifier showed the data dependence with the shipped filter and that a non-aborting catch would corrupt the postings of a default
TextField(postings with positions). - The minimal repro above is the term-vector-positions case cut down to one token and one assertion.
None found: no issue, PR, list thread or downstream report says a custom-frequency rejection closes the writer (searched 2026-10-22/23, 2026-10-26 and 2026-10-30). Closest: #15584, which made its own new check non-aborting for this reason, and #8905, which introduced the four checks.
Searches3 searches
- #15584 (merged 2026-04-24): its author found that their new duplicate-term check closed the writer and made it skip the document instead; the body and comments never mention the four older checks.
- #8905 (LUCENE-7854): introduced the checks; 34 comments, none about aborting or the writer closing.
- #8917 (LUCENE-7866): documents the filter's no-positions precondition, not what happens when a field breaks it.
- #16269 (open): refactors the term-vector per-field writer and leaves the checks and abort handling unchanged.
- Design and precedents: #7049 (LUCENE-5987, aborting exceptions close the writer), #6673 (LUCENE-5611), #6724 (LUCENE-5662), #2189 (LUCENE-1112), #9252 (LUCENE-8205).
- Downstream: Elasticsearch #28803 and #27552, OpenSearch #9479, Solr: expose or document the filter; none reports the writer closing.
- Same family in the registry: LFV-121, a float vector field routed to
HnswBitVectorsFormatrejected inside an aborting indexing step (different check and fix site). - Limits: keyword search; inline review threads and private channels are not fully covered.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene incl. the migrated JIRA archive; Elasticsearch, OpenSearch and its docs, Solr) | 2026-10-30 | three prior-art runs (messages, mechanism, downstream; 22 GitHub, 3 commit and 2 downstream queries each) and 66 direct searches: the four exception messages, TermFrequencyAttribute, DelimitedTermFrequencyTokenFilter, DOCS_AND_CUSTOM_FREQS, onAbortingException, AlreadyClosedException, tragic; all 408 open apache/lucene PRs, and the changed files of the 407 updated since 2025-01-01 | related items only (#15584, #8905, #8917, #16269 and the aborting-design issues); none the same bug |
| Mailing lists (dev@, java-user@, issues@, general@ and the Solr lists), JIRA archive, web | 2026-10-30 | 20 list queries per run plus 5 direct queries on each of 8 lists; 7 JQL queries; 24 web queries | no report |
| Earlier searches | 2026-10-22/23 and 2026-10-26 | the study's search and the follow-up's five prior-art runs and 35 direct GitHub searches | no report (verdict new) |
Introduced with the feature itself by d276acfbbcb (LUCENE-7854, 2017-06-06), first released in 7.0.0. Fails on every release line from 7.0.0 to 10.6.0 and on main; 6.6.6 and older lack the API.
Versions tested6 rows
Introduced by d276acfbbcb8ea6124fe486e35cea9eb928e4702, "LUCENE-7854: enable indexing custom term frequencies" (Mike McCandless, 2017-06-06; a JIRA patch, issue migrated to #8905). It created TermFrequencyAttribute and all four checks. In its parent the indexing chain already wrapped the add call as aborting (catch (Throwable th) { throw AbortingException.wrap(th); }), and LUCENE-5987 (5.0.0) had made aborting exceptions close the writer, so the feature never worked any other way. git log -S on the messages finds only this commit; all 66 release tags from 7.0.0 to 10.6.0 contain it. LUCENE-8205 later replaced AbortingException.wrap with onAbortingException, with the same effect.
Not fixed: upstream main 2f424fd428da (2026-10-30) has no later commit to the check sites. #15584 (10.5.0) added the non-aborting duplicate-term rejection beside them.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off (gradle and standalone); all four cases fail; passes with the fix |
| 10.6.0 | affected | minimal test fails, assertions on and off; all four cases fail |
| 9.1.0, 9.12.3, 10.0.0, 10.5.2 | affected | minimal test or the four-case test fails |
| 7.7.3, 8.0.0, 8.11.4, 9.0.0 | affected | the minimal test (test-framework imports adapted before 9.1.0) or a core-only probe of the cases fails |
| 7.0.0 | first affected | minimal test fails, assertions on and off; all four cases fail |
| 6.6.6 and older | no such API | the test does not compile: TermFrequencyAttribute does not exist |
Reproduced by an independent reproducer with its own test, a devil's-advocate verifier, an adjudication, a re-verification and a tie-breaker on current main; reviews by OpenAI GPT-5.6 (reading only) split, both agreeing on the root cause. Controls pass, and every fix check passed the repro.
Checks and verdicts325 words
Each check ran its own tests or re-ran an earlier one on stock jars; the cross-model reviewers could only read code.
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Three cases close the writer with assertions on and off; the backwards-offsets control stays open; a filter variant fails; its fix passes the repro and 15 + 56 + 92 upstream tests. |
| Independent reproducer | real | Own test written from the claim only: 4 of 6 fail on main, 10.5.2 and 9.12.3; found the DOCS-only case; both controls pass; the filter test fails. |
| Works-as-designed lens (OpenAI GPT-5.6, reading only) | real (medium) | Intended-behaviour argument moderate and rebutted; root cause and fix agree; inputs in contract. |
| Intended-behaviour devil's advocate | real | Scope probes: DOCS-only, DOCS_AND_CUSTOM_FREQS with offsets, data dependence with the filter; a non-aborting catch corrupts the postings of a default TextField, so the check must move before add. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test with seed 5EED1234: 4 of 6 fail with assertions on and off, controls pass; the filter test fails. |
| Re-verification on main 645d4fe14a20 | real | The minimal test fails on main and 10.5.2 with assertions on and off; the earlier fix rebased on this main passes it. |
| Refute lens (OpenAI GPT-5.6, reading only) | not real (medium) | Could not run code, so it could not reproduce; agreed on the root cause, rated the intended case moderate, and argued misuse and a deliberate abort (answered under "Why it is a bug"). |
| Tie-breaker | real (high) | Minimal test, four-case test and a core-only probe on main, 10.6.0 and 10.5.2, new seed; the same feature's duplicate-term rejection keeps the writer open; the fix passes. |
| This doc's fix validation | real | Gradle in a scratch worktree: the minimal test and the four-case test fail on stock main and pass with the recommended fix, as does the whole core module; a stricter variant breaks one upstream test. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 546 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,502 words
- Registry title
- A document rejected for a custom TermFrequencyAttribute on a field with term-vector positions or offsets, postings positions or DOCS-only postings is rejected inside an aborting step of the indexing chain, so it closes the IndexWriter and rolls back every change since the last commit
- Area
- index / IndexingChain inversion with custom term frequencies (TermVectorsConsumerPerField, FreqProxTermsWriterPerField) x aborting-exception classification
- Priority
- Low, rank 672: Like LFV-121, a documented rejection inside an aborting indexing step closes the IndexWriter, but only for opt-in custom term frequencies on a field setting the javadoc rules out, and the failure is loud.
- Impact class
- crash
- Impact note
- Applications on every release since 7.0.0 and on main that index custom term frequencies (their own TokenStream setting TermFrequencyAttribute, or the shipped DelimitedTermFrequencyTokenFilter) into a field that also stores term-vector positions or offsets, indexes postings positions (any default TextField) or is DOCS-only with a repeated term: the first token with a frequency other than 1 is rejected as documented, but the rejection also closes the IndexWriter as a tragic event, so every add, update and delete since the last commit is rolled back and every later call throws AlreadyClosedException until a new writer is opened; default IndexWriterConfig and codec, -ea and -da, ordinary scale; the committed index stays consistent and a new writer works, and with the shipped filter a misconfigured field indexes normally until the first 'word|N' token with N != 1.
- Summary
- You index a document whose analysis chain sets a custom term frequency (TermFrequencyAttribute, for example DelimitedTermFrequencyTokenFilter with a token like 'red|2') on a field that also stores term-vector positions or offsets, indexes postings positions (a default TextField), or is DOCS-only and repeats the term. You expect addDocument to reject only that document with its usual IllegalArgumentException or IllegalStateException and the writer to stay open, as it does for the neighbouring offset checks and for the duplicate-term check that #15584 made non-aborting. Instead the four checks run inside termsHashPerField.add, which IndexingChain treats as aborting, so the rejection also becomes the writer's tragic exception: IndexWriter closes itself, the next call throws AlreadyClosedException, and everything since the last commit is lost (the repro ends with 1 committed document instead of 3).
- Introduced
- d276acfbbcb8ea6124fe486e35cea9eb928e4702, 'LUCENE-7854: enable indexing custom term frequencies' by mikemccand (JIRA-patch workflow, issue migrated to #8905; no GitHub PR), which created TermFrequencyAttribute together with all four rejection checks: TermVectorsConsumerPerField.getTermFreq (term-vector positions, term-vector offsets), FreqProxTermsWriterPerField.getTermFreq (postings positions) and the !hasFreq check in FreqProxTermsWriterPerField.addTerm (DOCS-only, repeated term) [read: git log -S 'while using custom TermFrequencyAttribute' and -S 'must index term freq while using custom' over the full history return only this commit; git blame -w -C -C on the check lines]. All four run inside termsHashPerField.add, which DefaultIndexingChain already wrapped as aborting in the parent commit (catch (Throwable th) { throw AbortingException.wrap(th); }), and LUCENE-5987 (5.0.0) had made aborting exceptions close the writer; LUCENE-8205 later replaced AbortingException.wrap with onAbortingException with identical behaviour [read: git show of DefaultIndexingChain at d276acfbbcb^, 6.6.0, 7.0.0, 7.3.0 and 7.4.0; exec: same failure on 7.0.0 and 7.7.3]. The defect is the placement of the checks, present since the feature was created; isolation is by API absence (the probe cannot compile on 6.6.0 or 6.6.6, TermFrequencyAttribute being the only missing symbol) (2017-06-06 (d276acfbbcb committed; #8905 / LUCENE-7854 opened 2017-05-26, closed 2017-06-06); 7.0.0 tagged 2017-09-08)
- First affected version
- 7.0.0 [exec: all four cases close the writer with -ea and -da, both controls pass]; 6.6.6 and older lack the API [exec: compile error on 6.6.0 and 6.6.6]
- Affected versions
- every release from 7.0.0 to 10.5.2 and main ea57360912ed (11.0.0-SNAPSHOT) [exec, follow-up history runs with a core-only main() probe covering all four cases plus two controls: 7.0.0 (-ea and -da), 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da) fail; the independent reproduction's JUnit fails 4 of 6 on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main; the finder's repro (three cases) fails on 10.5.2, 9.12.3 and main and its core-only variant on 9.0.0, 8.11.2, 8.0.0 and 7.0.0]; every release tag 7.0.0..10.5.2 in the history clone contains d276acfbbcb [read: git tag --contains]; on 10.5.0 and later (#15584) also with the purpose-built IndexOptions.DOCS_AND_CUSTOM_FREQS plus term-vector offsets [exec on main only: the intended-behaviour check probe P2]; branch_10x and branch_10_6 not checked; not affected: 6.6.6 and older (API absent) [exec]; not fixed upstream as of main ea57360912ed (no upstream commit to the four files after it, checked 2026-10-26) [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code and voted “not real” while agreeing with the root cause (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record verdict new, read-only: five scripted prior-report searches, three of them with 16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list (dev@, java-user@, issues@, commits@), 4 JIRA-archive and web queries and two with the list and JIRA queries only, 0 errors or truncations; the finder's and the intended-behaviour check's scripted prior-report searches; 35 direct GitHub REST searches over apache/lucene, apache/lucene-solr, elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr issues, PRs, commits and code; direct lists.apache.org queries on the Lucene and Solr lists; JQL searches; web searches; upstream commits by path for the four files; local git history). Related prior items, none of them this bug: #8905 (LUCENE-7854, introduced the four checks; 34 comments, none about aborting or the writer closing); #15584 (merged 2026-04-24: its author made the PR's own new duplicate-term custom-frequency check non-aborting after it closed the writer, with TestCustomTermFreq#testRepeatedTerms 'ensure IndexWriter remains open', and left these four checks aborting); #8917 (LUCENE-7866, documented the no-positions precondition of DelimitedTermFrequencyTokenFilter); #7049 (LUCENE-5987), #6673 (LUCENE-5611), #6724 (LUCENE-5662), #2189 (LUCENE-1112) and #9252 (LUCENE-8205) (aborting/non-aborting design and precedents); #9990, #11086, #9547 and #9801 (other custom-frequency issues); open #16269 (refactors TermVectorsConsumerPerField, states no behaviour change, may conflict textually with a fix); downstream elastic/elasticsearch#28803 and #27552 and opensearch-project/OpenSearch#9413 and #9479 (expose custom frequencies; mention only that positions are rejected)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, together with the study's four-case test and the closest suites. Also fails on the 10.6.0 and 10.5.2 release jars; the version sweep covers 7.0.0 to 10.6.0. Upstream main2f424fd428da(2026-10-30) has no later commit to the check sites.
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2013-2018 (comment: an exception in add aborts all buffered documents because the terms hash may be corrupt), :2020 (termsHashPerField.add), :2021-2039 (MaxBytesLengthExceededException converted to a non-aborting IllegalArgumentException), :2040-2042 (DuplicateTermException, #15584, non-aborting), :2043-2045 (catch (Throwable th) { onAbortingException(th); throw th; })lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumerPerField.java:286-307 (getTermFreq throws IllegalArgumentException for a custom freq with term-vector positions or offsets)lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:118-125 (newTerm: no check when !hasFreq; getTermFreq when hasFreq), :146-152 (addTerm: IllegalStateException 'must index term freq while using custom TermFrequencyAttribute' for DOCS-only), :208-218 (getTermFreq: IllegalStateException for postings positions)lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:594-604 (maybeAbort: abort() and onTragicEvent)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:162-165 (class javadoc: closes itself on an Error or a checkpoint disaster; not an exhaustive list) and :1465-1466 (addDocument: after an Exception the index is consistent 'but this document may not have been added')lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:23-26 (the field 'must be indexed with IndexOptions#DOCS_AND_FREQS'); lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DelimitedTermFrequencyTokenFilter.java:31-32 ('DOCS_AND_FREQS but no positions or offsets')lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:106-133 (testRepeatedTerms, :125 'ensure IndexWriter remains open and doc was skipped'), :348, :374, :471, :498 (testInvalidProx, testInvalidDocsOnly, testInvalidTermVectorPositions, testInvalidTermVectorOffsets: type and message only, writer state never checked)lucene/core/src/test/org/apache/lucene/index/TestTermVectorsWriter.java:680 (testNoAbortOnBadTVSettings, LUCENE-5611) and TestIndexWriterExceptions.java:1593 (testNullStoredField, LUCENE-5662, assertNull(getTragicException())) and :1785 (testCrazyPositionIncrementGap)lucene/CHANGES.txt:11544-11546 (LUCENE-5987: IndexWriter forcefully closes itself on an aborting exception)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:176-180, (at 645d4fe14a20) :1987-2101 (:1989-1994, :1996-2064, :2068-2073, :2074-2075, :2076-2097, :2098-2101)lucene/core/src/java/org/apache/lucene/index/TermsHashPerField.java:150-178, (at 645d4fe14a20) :190-209, :211-218lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:113-138 (at 645d4fe14a20) (:119-122, :125), :141-206 (:145-152, :169-177, :196), :208-219lucene/core/src/java/org/apache/lucene/index/TermVectorsConsumerPerField.java:267-284 (at 645d4fe14a20) (:270, :281), :286-307lucene/core/src/java/org/apache/lucene/index/DocumentsWriterPerThread.java:245-312 (at 645d4fe14a20) (:310), :594-605lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:1491-1492, (at 645d4fe14a20) :1912-1913, :1625-1642 (:1639), :6098-6106
- Who is affected
lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:23-27 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DelimitedTermFrequencyTokenFilter.java:29-33; (at 645d4fe14a20) DelimitedTermFrequencyTokenFilterFactory.java:42lucene/core/src/java/org/apache/lucene/document/FeatureField.java:108-120 (at 645d4fe14a20)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2095-2097; (at 645d4fe14a20) IndexOptions.java:52-56; IndexWriter.java:162-165, :1465-1466, :1363-1369, :1312-1319, :1374-1392lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:23-27 (at 645d4fe14a20)lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:106-134 (at 645d4fe14a20) (:125), :137-141, :348-371, :373-398, :471-496 (:495), :498lucene/core/src/test/org/apache/lucene/index/TestIndexWriterExceptions.java:1592-1609, (at 645d4fe14a20) :1785-1811; TestTermVectorsWriter.java:679-706lucene/CHANGES.txt:919 (at 645d4fe14a20) (GITHUB#15584, 10.5.0), :11577-11579 (LUCENE-5987, 5.0.0 Bug Fixes), :12384-12385 (LUCENE-5662, 4.8.1 Bug fixes)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2051, (at 645d4fe14a20) :2057-2059; TermsHashPerField.java:190-209, :339-341; FreqProxTermsWriterPerField.java:119-122, :145-152lucene/core/src/java/org/apache/lucene/util/BytesRefHash.java:347-357 (at 645d4fe14a20) (find)lucene/core/src/test/org/apache/lucene/index/TestCustomTermFreq.java:373-398, (at 645d4fe14a20) :400-429lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2053-2064 (at 645d4fe14a20) (length overflow check, after fix A's insertion point), :2054-2055
- TestCustomTermFreqRejectionKeepsWriterOpen.java (one test, public API):
repro/LFV-281/src/org/apache/lucene/index/TestCustomTermFreqRejectionKeepsWriterOpen.java(45 lines)
Made in parallel with this doc from the code at 645d4fe14a20, the minimal repro, the four-case test's numbers and the fix diff.
assets/LFV-281/bug.png(546 KB)