By default the classic QueryParser analyses consecutive plain words as one run, but keeps the word right before AND/OR out of it, so the operator binds to that word. Since #16446 the run is a single clause. When that word is dropped by the analyzer, AND/OR binds to the whole run.
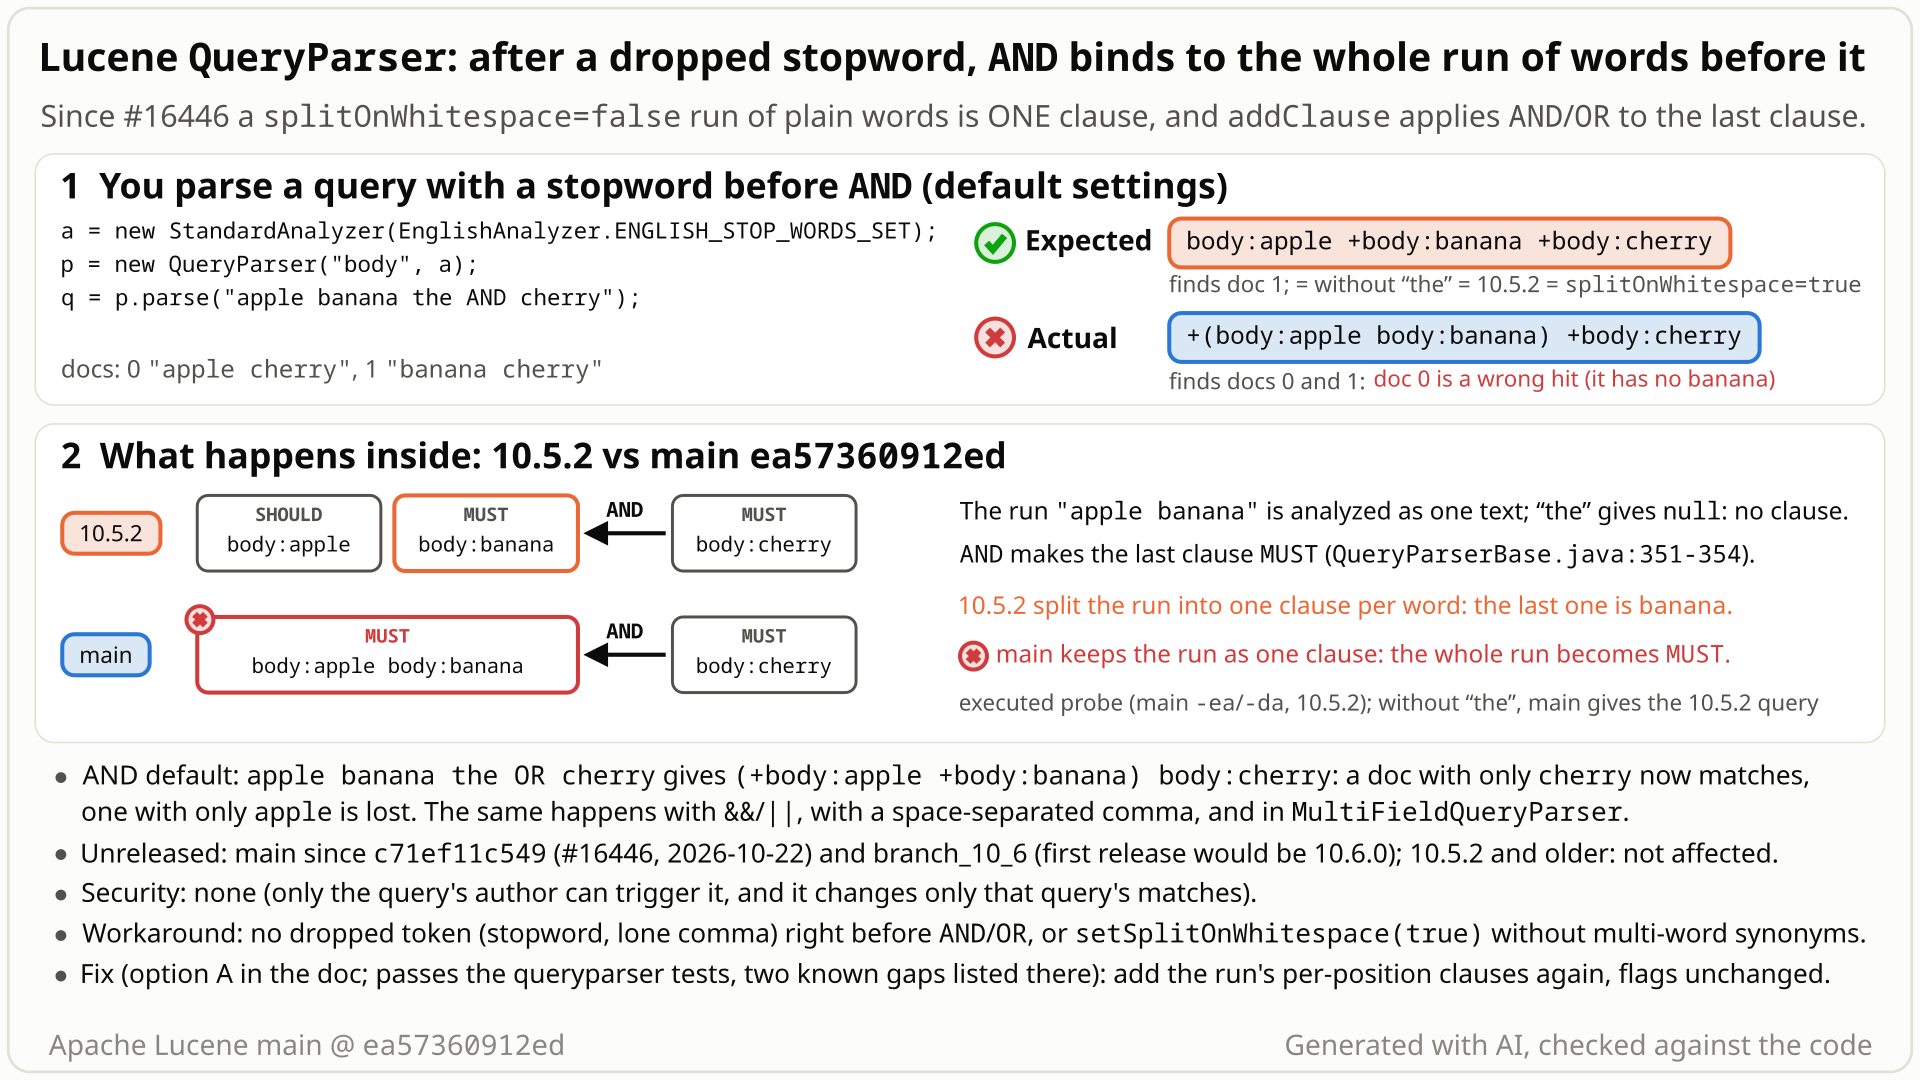
apple banana the AND cherry on 10.5.2 and on main since #16446, and which documents match. Select the still to open it at full size. Generated with AI, checked against the code.- Index five documents: "apple cherry", "apple banana cherry", "banana cherry", "cherry" and "apple banana", with an analyzer that drops "the". Parse
apple banana AND cherrywith the classicQueryParserat its defaults:body:apple +body:banana +body:cherry, 2 hits. - Type the stopword before AND:
apple banana the AND cherry. You expect the same 2 hits; 10.5.2 gives them, and so does main withsplitOnWhitespace=true. - Main gives 3 hits:
+(body:apple body:banana) +body:cherry. "apple cherry" now matches although it has no banana. - Why: by default the parser analyses
apple bananatogether, and since #16446 adds it as one clause.theadds nothing, so AND's "make the preceding clause required" step hits the whole group instead of banana. - With AND as the default operator,
apple banana the OR cherrygoes wrong both ways: a document with only "cherry" now matches, one with only "apple" no longer does. No error in either case.
Users who parse query strings with the classic QueryParser or MultiFieldQueryParser at default settings, with an analyzer that drops a token (any stop filter, or the default StandardAnalyzer for a lone ,), can be affected when a query has two or more words, then the dropped token, then AND (OR default) or OR (AND default). Rare shape; 10.6.0 and newer code only.
Mechanism, terms and numbers693 words
With the default splitOnWhitespace=false, the classic QueryParser sends a run of consecutive plain words to the analyzer as one string, but keeps a word that is followed by AND/OR out of the run, so that the operator binds to that one word. #16446 (merged 2026-10-22, milestone 10.6.0) changed how the run is added: one clause for the whole run instead of one clause per word position. When the word right before AND/OR is dropped by the analyzer (a stopword, or with the default StandardAnalyzer a lone , or en dash), it adds no clause, and the operator's "make the preceding clause required (or optional)" step lands on the whole run.
So apple banana the AND cherry parses to +(body:apple body:banana) +body:cherry instead of body:apple +body:banana +body:cherry: on five documents it matches 3 instead of 2. Under the AND default, apple banana the OR cherry becomes (+body:apple +body:banana) body:cherry instead of +body:apple body:banana body:cherry, which gains and loses documents. 10.5.2 and splitOnWhitespace=true give the stopword-free parse. MultiFieldQueryParser is affected the same way. No error is raised. Only 10.6.0, main and branch_10_6 contain it; a fix that adds a run's positions as separate clauses again, without changing their flags, passes the whole queryparser suite but has two known gaps (per-field analyzers, and subclasses that return alternatives).
- Run: two or more consecutive plain words with no operator between them. With
splitOnWhitespace=false, the default since 7.0.0, the parser analyses a run as one string. - Dropped token: a word for which the analyzer emits no token (a stopword, or a lone
,withStandardAnalyzer), so it produces no clause. - Default operator: OR unless set to AND; it decides whether plain words are optional (SHOULD) or required (MUST).
MultiTermtakes a following word only if the token after it is not:,*,~,^,ANDorOR(disallowedPostMultiTerm,QueryParser.jj:167-171, lookaheads:389-391). Inapple banana the AND cherrythe run isapple banana;thestays out because AND follows it.- The run is analysed once (
QueryParser.jj:398,:404);newFieldQuerypasses the default operator's occur, so the result is aBooleanQuerywith one clause per position (QueryParserBase.java:405-411). - Since #16446 it is added as one clause,
addClause(clauses, CONJ_NONE, MOD_NONE, firstQuery)(QueryParser.jj:405). Before,addMultiTermClausesadded the positions one by one: unchanged when all wereTermQuerys, otherwise each child with the default operator's occur (10.5.2QueryParserBase.java:421-448). theanalyses to nothing:addClausereturns atif (q == null) return;(QueryParserBase.java:369) and adds no clause.AND cherry: "If this term is introduced by AND, make the preceding term required" sets the last clause in the list to MUST (QueryParserBase.java:349-355); under the AND default, OR sets it to SHOULD (:357-365). That last clause is now the whole run, sobananaloses its own MUST. In 10.5.2 it wasbanana.- MultiFieldQueryParser builds one field disjunction per position and, since #16446, combines them with the default operator (
MultiFieldQueryParser.java:205); the run is again one clause, with the same result.
| default operator | query | 10.5.2, or splitOnWhitespace=true | main, default settings |
|---|---|---|---|
| OR | apple banana AND cherry | body:apple +body:banana +body:cherry: d1, d2 | the same |
| OR | apple banana the AND cherry | the same: d1, d2 | +(body:apple body:banana) +body:cherry: d0, d1, d2 |
| AND | apple banana OR cherry | +body:apple body:banana body:cherry: d0, d1, d4 | the same |
| AND | apple banana the OR cherry | the same: d0, d1, d4 | (+body:apple +body:banana) body:cherry: d0-d4 |
Documents: d0 "apple cherry", d1 "apple banana cherry", d2 "banana cherry", d3 "cherry", d4 "apple banana". && and || behave like AND and OR. A document with only "apple" is lost under the AND default (security probe).
Not affected: a stopword that is not next to the operator, a single word before the stopword (apple the AND cherry), splitOnWhitespace=true, and the operator that equals the default (only the structure changes). A run that analyses to one unit, such as one multi-word synonym, was already bound as a unit on 10.5.2.
Exposure and likelihood304 words
- Who is exposed. Users can be affected with default parser settings (
splitOnWhitespace=false, either default operator) with any analyzer that drops a token: a stop filter (EnglishAnalyzer, orStandardAnalyzerwith a stop set), and the defaultStandardAnalyzerwith an empty stop set for a space-separated,or en dash:apple banana , AND cherrygives+(apple banana) +cherryon main andapple +banana +cherryon 10.5.2. - What it takes. Two or more plain words that survive analysis, then the dropped token, then
AND/&&(OR default) orOR/||(AND default). A field-qualified or modified dropped word (apple banana title:the AND cherry,apple banana -the AND cherry) gives the same wrong parse for both parsers and both default operators (run by the fact check). Code that joins a user's text withANDproduces the shape whenever the text ends with a stopword after two real words, though the package docs say the parser "is designed for human-entered text, not for program-generated text" (package-info.java:82-85). - What goes wrong. A query of the wrong structure, silently. OR default with AND: it can only add documents. AND default with OR: it can gain and lose documents (both were observed). On the same build,
splitOnWhitespace=trueandfalsenow disagree for analyzers that emit one token per word. - Scale. Deterministic; no index size or data shape is involved (40 of 40 runs fail). No prevalence was measured; the registry rates it rare.
- Release status. 10.6.0 (released 2026-10-29), main (11.0.0-SNAPSHOT) and
branch_10_6.branch_10xdoes not contain #16446. - Downstream (by code reading, not run). Elasticsearch's and OpenSearch's
query_stringparsers extend the classic parser with the defaultsplitOnWhitespaceand would inherit the change on a Lucene with #16446 (both use 10.5.2 today). Solr keeps its own grammar copy and is not affected.
The test shows that with the classic QueryParser's defaults, a stopword between a run of plain terms and AND changes the parsed query (since #16446; 10.5.2 parses both strings the same).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.classic;

import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.analysis.MockTokenFilter;
import org.apache.lucene.tests.analysis.MockTokenizer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestStopwordBeforeAnd extends LuceneTestCase {

  public void testStopwordBeforeAndDoesNotChangeQuery() throws Exception {
    MockAnalyzer analyzer =
        new MockAnalyzer(random(), MockTokenizer.WHITESPACE, true, MockTokenFilter.ENGLISH_STOPSET);
    QueryParser qp = new QueryParser("body", analyzer);
    // expected: body:apple +body:banana +body:cherry; actual: +(body:apple body:banana) +body:cherry
    assertEquals(qp.parse("apple banana AND cherry"), qp.parse("apple banana the AND cherry"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-284/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:$LUCENE/lucene/queryparser/build/libs/lucene-queryparser-$V.jar
CP=$CP:$LUCENE/lucene/sandbox/build/libs/lucene-sandbox-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.queryparser.classic.TestStopwordBeforeAnd
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected
apple banana the AND cherryto parse likeapple banana AND cherry(body:apple +body:banana +body:cherry); actual:+(body:apple body:banana) +body:cherry, with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<body:apple +body:banana +body:cherry> but was:<+(body:apple body:banana) +body:cherry>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.queryparser.classic.TestStopwordBeforeAnd.testStopwordBeforeAndDoesNotChangeQuery(TestStopwordBeforeAnd.java:31)- The grammar ends a run before a word followed by AND/OR, so the operator binds to that word, never to a run; a test asserts
guinea pig AND dogs->guinea +pig .... - #16446's own test says a stopword next to a term must not change the parse.
- 10.5.2 and
splitOnWhitespace=truegive the stopword-free parse; no change was announced.
The full argument272 words
- The code's own rule.
addClause: "If this term is introduced by AND, make the preceding term required" (QueryParserBase.java:349) and "If this term is introduced by OR, make the preceding term optional" (:358). The grammar makes sure that preceding clause is never a run of plain words by ending runs before AND/OR (QueryParser.jj:167-171); it can still be a field-qualified term, a phrase or a parenthesized group (:297-372). - The docs. "The AND operator matches documents where both terms exist" (
package-info.java:300); "The OR operator links two terms" (:284).setSplitOnWhitespaceonly says "Whether query text should be split on whitespace prior to analysis" (QueryParser.jj:152). - Upstream tests. LUCENE-2605's test: "Operators should interrupt multiword analysis of adjacent words if they associate", with
guinea pig AND dogs->guinea +pig +Synonym(dog dogs)(TestQueryParser.java:656,:679). #16446'stestDefaultOperatorAppliesStopwordNextToTerm:+foo bar themust parse like+foo bar(TestMultiFieldQueryParser.java:439-456). No test covers a run, a dropped token, then AND/OR. - History. #16446 fixed two MultiFieldQueryParser bugs (#16441, #16443). In its thread the changed expectations were called "cosmetic", producing "exactly same results", and the author, after re-running the #10355 boolean precedence cases (
A AND B OR C AND D, ...) on 8.11.3, 10.5.1 and the PR, said "the general clause handling isn't affected"; a maintainer noted it would be a breaking change before merging and backporting it to 10.6.CHANGES.txt(under 11.0.0 on main) lists only the removal ofaddMultiTermClausesand the two MultiFieldQueryParser fixes;MIGRATE.mdhas nothing, and onbranch_10_6(10.6.0, released 2026-10-29) the backport adds noCHANGES.txtentry at all.
The devil's-advocate check268 words
The strongest "works as designed" case (review, the independent reproduction, the intended-behaviour check, adjudication): no document says how AND/OR binds next to a dropped token, and the package docs say "the query parser syntax may change from release to release" (package-info.java:74); addClause's rule (adjust the last surviving clause) is old and unchanged, and main's result equals the long-standing parse of the explicit (apple banana) the AND cherry; the flexible StandardQueryParser already gives a third answer (appl banana +cherri) on both versions; committers have called odd classic AND/OR results expected before (#8535); the package docs say the parser "is designed for human-entered text, not for program-generated text" (package-info.java:82-85), which weakens the case of code that joins text with AND (not a person typing it); and grouping the run is coherent in itself ((apple OR banana) AND cherry), most of all for MultiFieldQueryParser, where #16446 deliberately combines a run's positions into one unit.
Why it fails: the change was described as not changing results and nothing announces it; it makes splitOnWhitespace true and false disagree on one build; the grammar and the upstream tests bind an operator to the word before it; and #16446's own test says a stopword next to a term must not change the parse. Which reading applies depends only on whether a dropped word was typed. The independent reproduction, the intended-behaviour check and the adjudication classify it as real (the intended-behaviour check and the adjudication with medium confidence, because the contract is implicit; the independent reproduction records none); the runs show the change, not intent.
Recommended A. Add a run's positions as separate clauses again, without re-flagging them (two known gaps)
Add a run's per-position clauses one by one again, as 10.5.2 did, when all carry the default occur and cover the same fields, so nothing is re-flagged. The repro and the whole queryparser suite (536 tests) pass. Two known gaps: per-field analyzers that drop a word in only some fields keep the bug; a subclass returning alternatives gets them split.
All options and trade-offs6 options · 1,063 words
One fix was built and validated in a scratch worktree at ea57360912ed (option A), together with a simpler variant that has a known corner (A1). A probe after the fact check found two shapes option A gets wrong (below), so an upstream fix may need a different test of what a term position is. Any fix must keep #16441 (a per-field disjunction must not be re-flagged MUST under the AND default), #16443 (positions combined with the default operator) and multi-word synonym grouping.
A. Add a run's positions as separate clauses again, without re-flagging them (two known gaps) (validated by the checks) (recommended)
A package-private QueryParserBase.addMultiTermRunClauses replaces the addClause call in MultiTerm (QueryParser.jj:405; QueryParser.java and the checksum file regenerated). If the run's query is a BooleanQuery without minimumNumberShouldMatch whose clauses all have the default operator's occur and all cover the same fields (one clause per position), the clauses are added as they are; any other query is added as one clause, as on main. The same-occur guard keeps #16441 fixed (+foo bar the still parses like +foo bar); the same-fields guard keeps a one-position MultiFieldQueryParser field disjunction in one piece.
  void addMultiTermRunClauses(List<BooleanClause> clauses, Query q) {
    if (q instanceof BooleanQuery bq
        && bq.getMinimumNumberShouldMatch() == 0
        && bq.clauses().isEmpty() == false) {
      Occur defaultOccur = operator == OR_OPERATOR ? Occur.SHOULD : Occur.MUST;
      Set<String> fields = fieldsOf(bq.clauses().get(0).query());
      boolean positions = true;
      for (BooleanClause clause : bq.clauses()) {
        if (clause.occur() != defaultOccur || fields.equals(fieldsOf(clause.query())) == false) {
          positions = false;
          break;
        }
      }
      if (positions) {
        clauses.addAll(bq.clauses());
        return;
      }
    }
    addClause(clauses, CONJ_NONE, MOD_NONE, q);
  }
  // fieldsOf(q): the fields that q.visit(...) reports through QueryVisitor#acceptField
Trade-offs
- Output strings go back to 10.5.2's. Ordinary runs print flat again (
motley crue motl* cru*instead of(motley crue) motl* cru*), so the fix reverts #16446's expectation changes inTestQueryParser(themultiTermGroupoverrides, 14 synonym and 5 ASCII-folding strings). Matches of those queries do not change. #16446 knowingly accepted and tested the grouping; option B keeps it. - Two guards decide what a position is, and they can be wrong both ways. Gap 1, per-field analyzers (executed):
MultiFieldQueryParserovertandb, wherebalso dropsbanana;apple banana the AND cherrygives+((t:apple b:apple) (t:banana)) +(t:cherry b:cherry)on main and with the fix (the positions cover different fields, so the guard declines), while 10.5.2,splitOnWhitespace=trueand the stopword-free query give(t:apple b:apple) +(t:banana) +(t:cherry b:cherry): the bug remains. Gap 2, a subclass whosegetFieldQueryreturns two same-field SHOULD alternativesbody:x body:yfor the run (executed): main gives+(body:x body:y) +body:zfora b the AND z, the fixbody:x +body:y +body:z(as 10.5.2 did), so a document with only x and z is lost against main. Also by reading:fieldsOfignores MUST_NOT children (QueryVisitor.getSubVisitorreturnsEMPTY_VISITOR,QueryVisitor.java:79-82) and gives an empty set for a query that reports no field. - Scores, rewritten queries and query-cache keys of the flattened queries were not compared; the tests and probes compare parses and match sets only.
- Not run on
branch_10_6(the code usesinstanceofpatterns andBooleanClauserecord accessors, both on 10.x), on x86, or in a benchmark (the check runs once per run, at parse time).
What the checks validated
- Gradle, scratch worktree at
ea57360912ed, JDK 25: the finder's and the independent tests go from 5 of 7 failing to 7 of 7 passing; with the fix as shadow sources over the stock jars they pass with assertions on and off, and the security probe's 4 tests pass. - Whole
lucene/queryparsersuite with the fix and its tests: 30 classes, 536 tests, 0 failures, 1 skipped;:lucene:queryparser:check -x testpasses (google-java-format, ecj, forbidden APIs, generated-file checksums).regenerateClassicQueryParsergives aQueryParser.javaidentical to the hand edit. The 2 new tests fail on the stock sources. - Translation-validation harness: two words and a stopword, every query of up to 5 symbols (434,688 evaluations): 48 + 48 mismatches on stock, 0 with the fix. All six analyzer families up to 4 symbols (6,366,096 evaluations): identical counts with and without the fix.
- Not covered by these runs: per-field analyzers and
getFieldQueryoverrides; the gap probe (a public-APImain()class) ran them on stock main, with the fix as shadow sources and on 10.5.2.
Flatten whenever every clause has the default occur.
Trade-offs
Passes the repro and the whole module suite, but re-breaks a corner that main gets right: MultiFieldQueryParser, OR default, apple the the AND cherry gives t:apple +b:apple +(t:cherry b:cherry) instead of +(t:apple b:apple) +(t:cherry b:cherry), which is what main and splitOnWhitespace=true give (10.5.2 had the same flaw as A1).
What the checks validated
Module suite with the finder's, the independent and a probe test: 33 classes, 541 tests, 0 failures; the corner shown by a parse probe.
Remember the clause MultiTerm added; when addClause is about to apply AND/OR to it (which only happens when the tokens in between were dropped), replace it by its per-position clauses first.
Trade-offs
Keeps every toString() and test expectation of #16446 and changes only the buggy shape; needs parser state across addClause calls and the same position guards. Not built.
Skip the previous-clause adjustment when the clause just before the operator was dropped.
Trade-offs
Tried as an addClause override on main (not as a patch): it gives (apple banana) +cherry, which matches neither 10.5.2 nor splitOnWhitespace=true, and keeps the long-standing drop AND stop AND roll -> +drop +roll, because the first AND still makes drop required. A wider variant that also ignores the AND that introduces a dropped token gives the same (apple banana) +cherry and changes that test to drop +roll. Both live in addClause, so they also change splitOnWhitespace=true (by reading). Not recommended.
Restore addMultiTermClauses.
Trade-offs
Makes the repro pass (executed in the history check) but brings back the re-flagging that #16441 fixed: the old method re-added non-TermQuery clauses with the default occur. Not acceptable.
setSplitOnWhitespace(true) gives the 10.5.2 parse, but changes multi-word synonym handling; or leave out any dropped token (a stopword, a lone ,) before an explicit operator.
Trade-offs
Application-side only.
Formal first signal: an AI tool modelled the parser's clause step in the Z3 SMT solver to prove that splitting on whitespace or not gives the same matches. Within the model it held up to 3 clauses and failed at 4 with a b <stopword> AND +c (the same as ... AND c). Exhaustive checks and a JUnit confirmed it.
The method in full219 words
Method: SMT (Z3) proof attempt, then bounded-exhaustive translation validation on the stock jar (the hunt's "formal" tier: the solver produced the first signal).
- In a hunt unit (classic query parser, 2026-10-26) the finder, an AI tool, transcribed
QueryParserBase.addClauseand theMultiTermrule into a Z3 model and asked whethersplitOnWhitespace=falseandtruegive the same match set for every clause sequence of up to 6 items, both operators, all modifiers and conjunctions, stopwords anywhere. The model is a single-field Boolean abstraction of bare clauses (no real token streams, synonyms, fields, MultiFieldQueryParser, scoring or subclasses). Within it: proved (unsat) up to length 3; counterexample at length 4:a b <stopword> AND +cunder the OR default (the+is redundant after AND, so it equalsa b <stopword> AND c, the JUnit's shape). - Controls: without stopwords the equivalence is proved up to length 7; a mutant without the grammar's "no AND/OR right after a run" rule fails from length 3 (vacuity check).
- An independent reference grammar and match-set semantics, checked against the real
QueryParserandMultiFieldQueryParseron every query of up to 5 symbols over two words and a stopword, found only mismatches of the shapew w <stopword> AND|OR x. The finder then wrote the public-API JUnit; the independent checks, history, prior-report search and security assessment followed.
No prior report found (2026-10-26): 59 tool queries and about 30 manual searches over Lucene issues, PRs, commits, mailing lists, the JIRA archive, downstream trackers and the web. The closest item is #16446 itself, whose thread discussed a different stopword case.
Searches4 searches
Verdict new: nobody has reported or discussed this bug. Not fixed upstream: no commit after #16446 touches the classic package on main or branch_10_6, and no open PR touches its parser files. Limits: GitHub search returns at most 50 results per query (2 broad queries were truncated), only 4 JIRA-archive queries ran, and a report worded without the searched words could be missed; the threads where a report would most likely appear were read in full.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues, PRs and commits | 2026-10-26 | a scripted prior-report search (16 issue/PR and 3 commit queries) plus manual GitHub searches; every issue and PR opened since 2026-10-10; commit history of the classic package on main, branch_10_6, branch_10x and branch_10_5 | #16446 (the cause; its thread discussed the trailing stopword in +small hello the, which it fixed), #16443, #16441 (closed on 2026-10-26 as fixed by #16446; still open when searched), #16442, #16667, and older stopword-and-operator items #1181, #1113, #8255, #8535 with other mechanisms |
| Open PRs | 2026-10-26 | the changed files of the 188 open PRs updated since 2026-07-01; title searches over all open PRs | none touches QueryParser.jj, QueryParser.java, QueryParserBase.java or MultiFieldQueryParser.java |
| Mailing lists | 2026-10-26 | 28 queries over dev@, java-user@, issues@ and commits@; archives since 2026-08-01 read | only review requests for #16446, with no discussion of semantics |
| JIRA archive, downstream and web | 2026-10-26 | 4 JIRA-archive, 2 downstream-repository and 6 web queries; two Solr JIRA issues read | no report; Solr issues have other mechanisms |
Introduced on 2026-10-22 by #16446 (commit c71ef11c549, backported to branch_10_6 as 88c0bd4c346), which made a run of words one clause. First released in 10.6.0 (2026-10-29); 10.5.2, 10.0.0, 9.12.3, 8.11.4 and 7.0.0 pass; main and branch_10_6 fail.
Versions tested7 rows
Introduced by #16446 "MultiFieldQueryParser: default operator is not honored between term positions" (by @OlivierJaquemet, co-author @epotyom; merged 2026-10-22 by @msokolov as c71ef11c549 on main, backport 88c0bd4c346 on branch_10_6; milestone 10.6.0). One line of MultiTerm went from addMultiTermClauses(clauses, firstQuery) to addClause(clauses, CONJ_NONE, MOD_NONE, firstQuery), and addMultiTermClauses was removed. addClause's order (adjust the previous clause, then return on a dropped term) dates from the 2001 initial import.
The splitOnWhitespace=false path came with LUCENE-2605 in 6.2.0 (opt-in) and became the default in 7.0.0; from 6.2.0 to 10.5.2 the run was flattened, one clause per position. No build was made at the exact commits; the queryparser module is unchanged between c71ef11c549 and ea57360912ed.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed, a9779ef3c193 | affected | finder's test 2 of 2 and the independent test 3 of 5 fail, assertions on and off |
branch_10_6 from 88c0bd4c346 (10.6.0, released 2026-10-29) | source over 10.5.2 jars | the classic package at the backport fails 2 of 2; at its parent aac3c7ae947 it passes |
main + parent's parser sources / MultiTerm call reverted | bisect | both pass (the revert also needs the parent's QueryParserBase, since main removed the old method): the MultiTerm call of #16446 causes it |
| 10.5.2, 10.0.0, 9.12.3 | not affected | pass (release jars) |
| 8.11.4, 7.0.0 | not affected | pass (release jars; test-framework imports adapted) |
| 6.2.0 - 6.6.6 | read | opt-in path, run flattened the same way |
| fix (scratch worktree) | not affected | repro tests pass; queryparser suite 536 tests, 0 failures |
An independent reproducer, a devil's advocate and an adjudication, all running tests on main, and a "works as designed" review from another model family (OpenAI GPT-5.6, reading only) say real. A refute review that could not run code said "not real" mainly procedurally. The fix passed the queryparser suite; a later probe found two gaps.
Checks and verdicts331 words
Every check ran on main ea57360912ed; the GPT-5.6 reviews could read code but not run it, and the harness that drove them re-ran the finder's repro.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Z3 counterexample at length 4, translation-validation mismatches only of this shape, JUnit 2 of 2 fail on main (assertions on and off), 40 of 40 over 20 iterations, passes on 10.5.2. |
| works-as-designed review (GPT-5.6, reading only) | real, medium | Agreed on the root cause and the inputs; rated the intended case moderate, not persuasive. A separate run re-ran the repro: fails. |
| Independent reproducer | real | Own 5-test JUnit from the claim alone: 3 of 5 fail on main, 5 of 5 pass on 10.5.2, 10.0.0 and 9.12.3; restoring per-position clauses makes all pass. |
| Refute review (GPT-5.6, reading only) | not real, low (mainly procedural) | it agreed with the root cause. Its one substantive contrary item: the package docs warn that the syntax may change and that the parser targets human-entered text (answered in the devil's-advocate case). A separate check with new words: 6 of 6 cases differ on main, 0 of 12 on 10.5.2. |
| Devil's advocate | real, medium | Built the strongest works-as-designed case and showed why it fails; an 80-parse probe added the , trigger with the default StandardAnalyzer and the MultiFieldQueryParser form. |
| adjudication | confirmed, medium | Re-ran the independent reproduction's test: 3 of 5 fail on main, 0 of 5 on 10.5.2. Medium because the contract is implicit. |
| history, prior art, security | introduced by #16446; new; security none | 11 executed history runs pin the one line; no prior report; a 4-test security probe shows a separately added restriction always holds. |
| re-runs and fix | still reproduces; fix passes the suite, two gaps | Follow-up re-runs and newer main a9779ef3c193 reproduce; the recommended fix passes the repro, the module suite and check; a probe after the fact checks shows two shapes it gets wrong (per-field analyzers, subclass alternatives). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 499 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,356 words
- Registry title
- Classic QueryParser with the default splitOnWhitespace=false: since #16446 an AND/OR that directly follows a token the analyzer drops (such as a stopword) binds to the whole preceding run of plain terms instead of the last term, so typing the stopword changes which documents match (regression new in 10.6.0, also on main and branch_10_6)
- Area
- queryparser / classic QueryParser and MultiFieldQueryParser (QueryParser.jj MultiTerm run grouping, QueryParserBase.addClause conjunction step)
- Priority
- Medium, rank 91: A regression in the default classic QueryParser shipped in 10.6.0 that silently changes matches, but it needs the rare shape of a stopword right before an explicit AND/OR, so it leads the 10.6.0 wrong-match group below the data-corruption rows.
- Impact class
- silent wrong results
- Impact note
- Applications that parse query strings with the classic QueryParser or MultiFieldQueryParser at default settings (splitOnWhitespace=false) and an analyzer that drops a token (a stop filter such as EnglishAnalyzer's, or even the default StandardAnalyzer for a space-separated ',' or en dash) get different matches with no error whenever a query has two or more plain terms, then the dropped token, then AND/&& under the default OR operator (extra documents match) or OR/|| under the AND default (matches change in both directions); no scale or special index is needed, but the query shape is uncommon, and only 10.6.0 (released 2026-10-29) and newer code are affected (main since c71ef11c549 and branch_10_6; 10.5.2 and every earlier release are not).
- Summary
- You parse 'apple banana the AND cherry' with the classic QueryParser at its default settings and an analyzer that drops 'the', and expect the same query as for 'apple banana AND cherry', namely body:apple +body:banana +body:cherry, which is what Lucene 10.5.2 returns and what main returns with splitOnWhitespace=true. On main you get +(body:apple body:banana) +body:cherry, so a document containing only 'apple cherry' now matches; with the AND default operator, 'apple banana the OR cherry' becomes (+body:apple +body:banana) body:cherry instead of +body:apple body:banana body:cherry, so a document with only 'cherry' matches and one with only 'apple' no longer does. The cause is #16446, which now adds the analysed run 'apple banana' as one clause: the stopword yields no clause, so the following conjunction's 'make the preceding clause required (or optional)' step in addClause changes the whole run instead of 'banana'.
- Introduced
- c71ef11c549d4fcf4126936ddc0066e60029cab2 ('MultiFieldQueryParser: default operator is not honored between term positions (#16446)'; PR apache/lucene#16446 by OlivierJaquemet with co-author epotyom, which fixes #16443 and supersedes PR #16442 for #16441; merged 2026-10-22 by msokolov, milestone 10.6.0), backported to branch_10_6 as 88c0bd4c346 (2026-10-22, parent aac3c7ae947). It changed one line of the MultiTerm production (QueryParser.jj:405, generated QueryParser.java:747) from addMultiTermClauses(clauses, firstQuery), which put each position of an all-TermQuery run into the clause list, to addClause(clauses, CONJ_NONE, MOD_NONE, firstQuery), and removed QueryParserBase.addMultiTermClauses; addClause itself, which applies a conjunction's adjustment to the last clause before returning on a null query, has had that order since the 2001 initial import bd3948c539e. [exec: main's jars with the parent's (7cecf795236) QueryParser, QueryParserBase and MultiFieldQueryParser shadowed pass, with main's sources, that call changed back to addMultiTermClauses and the parent's QueryParserBase (main removed the method) pass, stock main fails; the branch_10_6 classic package at aac3c7ae947 passes and at 88c0bd4c346 fails over 10.5.2 jars; read: git blame and git log -L of MultiTerm. No build at the exact commits; git diff c71ef11c549 ea57360912ed -- lucene/queryparser is empty] (2026-10-22 (c71ef11c549 on main; backport 88c0bd4c346 on branch_10_6 the same day))
- First affected version
- 10.6.0 (released 2026-10-29; 10.5.2, the last release before it, passes [exec]; the backport 88c0bd4c346 is on branch_10_6 and the PR milestone is 10.6.0; on main, CHANGES lists #16441/#16443 under 11.0.0)
- Affected versions
- main (11.0.0-SNAPSHOT) from c71ef11c549 through ea57360912ed [exec, -ea and -da: finder, the independent reproduction, the intended-behaviour check, adjudication, the version-history runs and this follow-up]; 10.6.0 (released 2026-10-29) [exec: RC1 4ae946e5a9b fails 2 of 2 with -ea and -da]; branch_10_6 from 88c0bd4c346 [exec: that branch's classic-package source shadowed over 10.5.2 jars, no full branch build; the package is the same at the branch tip 2763db11b0a]. Not affected: 7.0.0, 8.11.4, 9.12.3, 10.0.0 and 10.5.2 [exec, release jars; 7.0.0 and 8.11.4 with a copy of the test that only changes five test-framework imports]; 6.2.0 .. 6.6.6 [read: splitOnWhitespace=false was opt-in and addMultiTermClauses flattened the run the same way]; before 6.2.0 the splitOnWhitespace=false path did not exist; branch_10x (10.7.0 in development) does not contain #16446 [read]. Not fixed upstream as of 2026-10-26. All runs on JDK 25.0.3, aarch64 Linux; x86 not checked (no vector or platform-dependent code is involved).
- Status
- filed (an upstream issue or pull request was filed)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- formal: Z3; also reached by exhaustive check
- Upstream and prior reports
- filed upstream as #16950 on 2026-10-29 (open, type:bug; links the umbrella #16937); before filing no report was found (follow-up prior-report record verdict new, 2026-10-26)
- Lucene commit tested
- 2026-10-26 on main
ea57360912ed(commit of 2026-10-24) through gradle and the standalone harness, with assertions on and off; again on maina9779ef3c193(2026-10-26); the 10.5.2, 10.0.0, 9.12.3, 8.11.4 and 7.0.0 release jars; main with the parent commit's parser sources, and with theMultiTermcall reverted (plus the parent'sQueryParserBase, since main removed the old method); thebranch_10_6classic package before and at the backport, over the 10.5.2 jars; the fix in a scratch worktree atea57360912ed(whole queryparser suite and checks).
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:376-409 (at ea57360912ed) (MultiTerm: with splitOnWhitespace=false the run is analysed as one string and added by addClause(clauses, CONJ_NONE, MOD_NONE, firstQuery) at :405), :167-171 (disallowedPostMultiTerm = {COLON, STAR, FUZZY_SLOP, CARAT, AND, OR}: a term followed by AND/OR ends the run)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.java:745-748 (at ea57360912ed) (generated MultiTerm, addClause at :747)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:346-369 (at ea57360912ed) (addClause: AND makes clauses.get(size-1) MUST, comment 'If this term is introduced by AND, make the preceding term required' at :349; OR under the AND default makes it SHOULD; then 'if (q == null) return;' at :369)lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/package-info.java:74 (at ea57360912ed) ('the query parser syntax may change from release to release')lucene/queryparser/src/test/org/apache/lucene/queryparser/classic/TestMultiFieldQueryParser.java:439-456 (at ea57360912ed) (testDefaultOperatorAppliesStopwordNextToTerm, added by #16446: '+foo bar the' must parse like '+foo bar')lucene/queryparser/src/test/org/apache/lucene/queryparser/util/QueryParserTestBase.java:532 (at ea57360912ed) ('drop AND stop AND roll' -> '+drop +roll': a conjunction after a stopword applies to the last surviving clause)lucene/queryparser/src/test/org/apache/lucene/queryparser/classic/TestQueryParser.java:656, (at ea57360912ed) 679 ('Operators should interrupt multiword analysis of adjacent words if they associate'; 'guinea pig AND dogs' -> 'guinea +pig +Synonym(dog dogs)')lucene/CHANGES.txt:132, (at ea57360912ed) 262, 264 (#16441 and #16443 entries under 11.0.0; no entry announces a change for the plain QueryParser)
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:112, 167-171, 264-293, 376-409 (MultiTerm; addClause at :405)Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:346-389 (addClause: :349-355 AND step, :357-365 OR step, :369 return on null), :405-411 (newFieldQuery)Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/MultiFieldQueryParser.java:143-209 (getFieldQuery; :205 getMultiTermPositionQuery)git show c71ef11c549 (the MultiTerm change and the removed addMultiTermClauses)git show releases/lucene/10.5.2:lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:421-448 (addMultiTermClauses: :437-438 all-TermQuery runs added unchanged, :439-448 otherwise each child with the default occur)
- Who is affected
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/package-info.java:82-85 (designed for human-entered text)
- Why it looks unintended
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParserBase.java:349, 358Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:152, 167-171, 297-372 (Clause and Term)Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/package-info.java:74, 82-85, 284, 300Lucene main ea57360912ed: lucene/queryparser/src/test/org/apache/lucene/queryparser/classic/TestQueryParser.java:656, 679; lucene/queryparser/src/test/org/apache/lucene/queryparser/classic/TestMultiFieldQueryParser.java:439-456; lucene/queryparser/src/test/org/apache/lucene/queryparser/util/QueryParserTestBase.java:532Lucene main ea57360912ed: lucene/CHANGES.txt:6, 132, 262-264git show --stat 88c0bd4c346 (no CHANGES.txt); a Lucene clone origin/branch_10_6 (2763db11b0a) lucene/CHANGES.txt has no #16441/#16443/#16446 entry
- Suggested fix
git show c71ef11c549 (the removed addMultiTermClauses re-flags non-TermQuery clauses)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/QueryVisitor.java:79-82 (getSubVisitor: EMPTY_VISITOR for MUST_NOT)
- TestStopwordBeforeAnd.java (JUnit test):
repro/LFV-284/src/org/apache/lucene/queryparser/classic/TestStopwordBeforeAnd.java(33 lines)
A summary diagram (PNG), made in parallel with this doc from an executed probe on main and 10.5.2. The picture uses its own two-document index (doc 0 "apple cherry", doc 1 "banana cherry"), numbered differently from the table above.
assets/LFV-284/bug.png(499 KB)