addIndexes admits its inputs by live documents, but since 9.9.0 it first builds a combined view of them for an optional reorder step, and that view counts deleted documents against the limit.
IndexWriter.addIndexes(CodecReader...)copies documents from readers you pass, such as the segments of other indexes, possibly filtered, into this index. Deleted documents are dropped; only live documents are copied.- An index holds at most
IndexWriter.MAX_DOCS= 2,147,483,519 documents. A reader'smaxDoc()counts every doc ID, deleted ones included;numDocs()counts only the live ones. - Since 9.9.0 a merge may renumber documents first through
OneMerge#reorder, whichBPReorderingMergePolicyuses. To offer that, Lucene glues the merge's inputs into one temporary combined reader. By defaultreorder()does nothing and returns null.
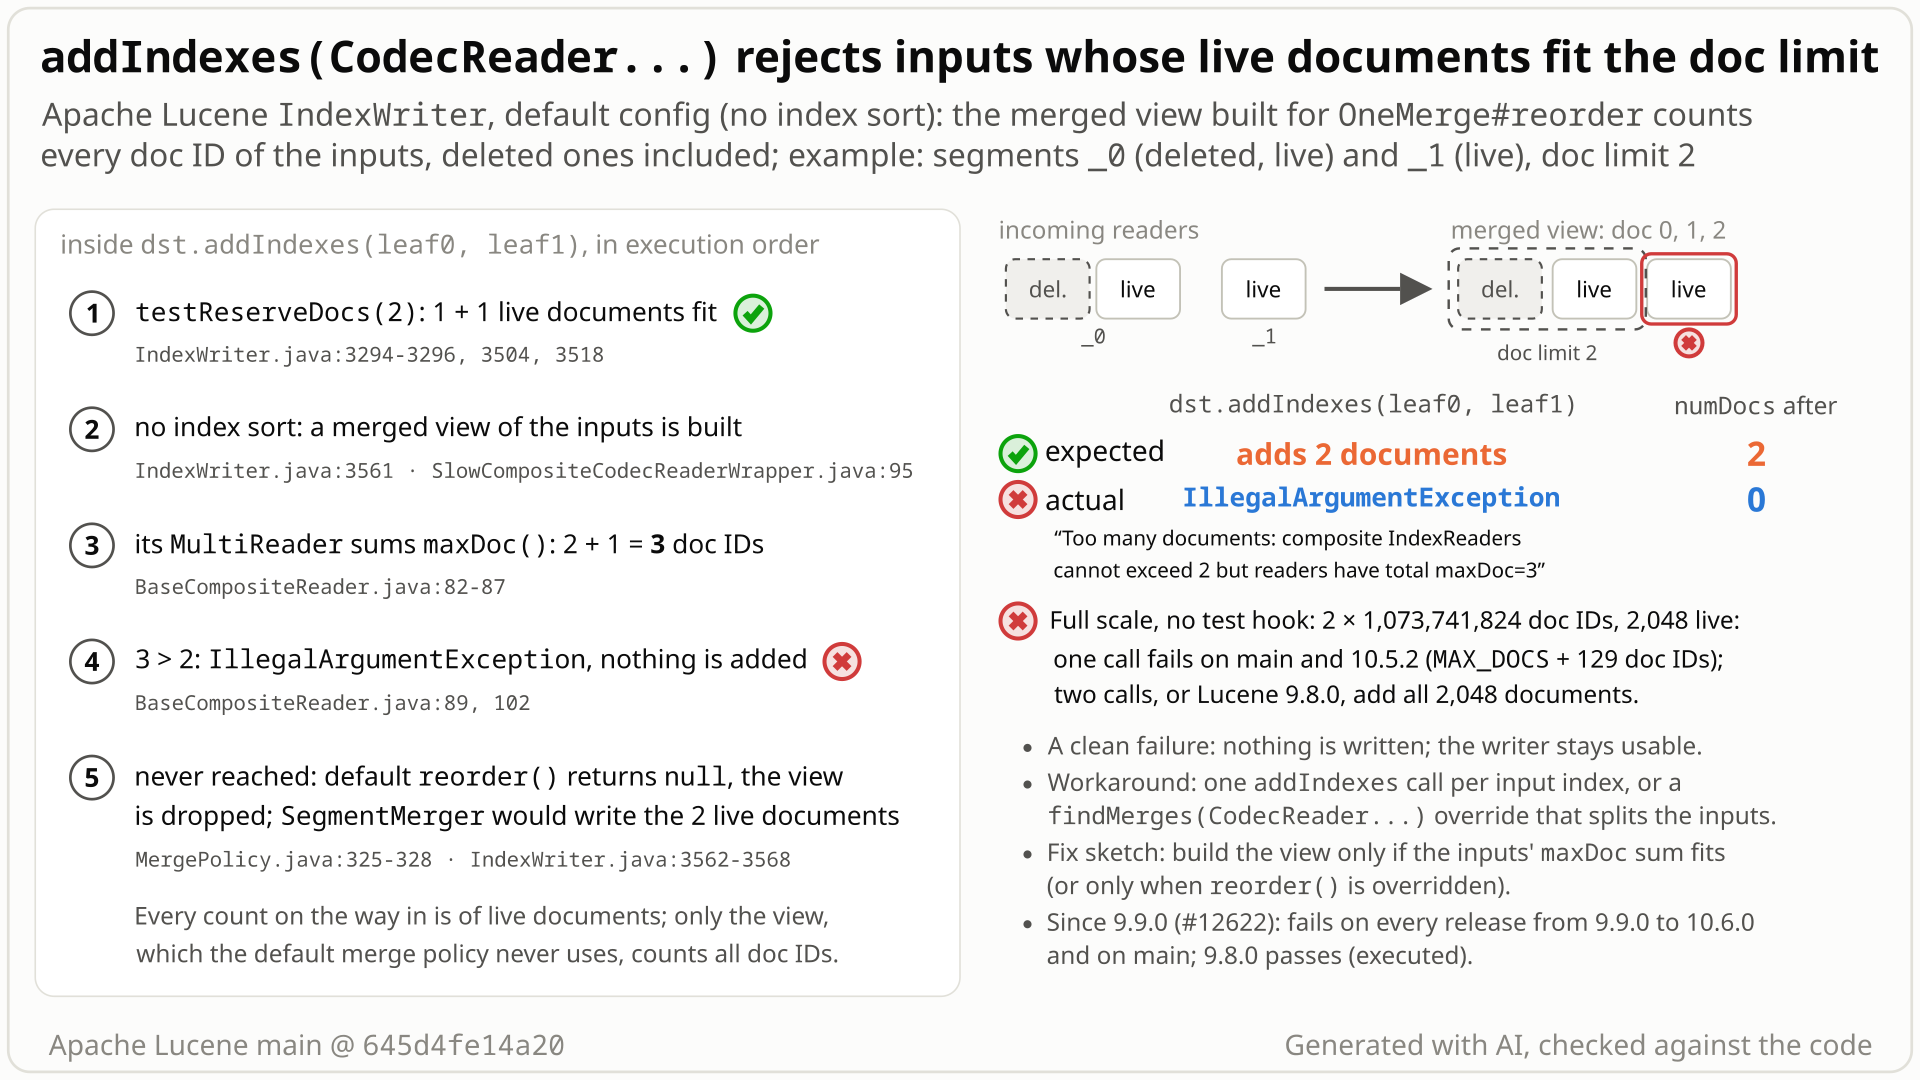
_0 (one deleted, one live document) and _1 (one live), doc limit 2. addIndexes admits the 2 live documents, but the merged view built for reorder() numbers all 3 doc IDs (2 + 1 > 2) and is refused. Full scale fails the same way: 2 x 1,073,741,824 doc IDs, 2,048 live. Select the still to open it at full size. Generated with AI, checked against the code.- Two indexes, A and B, have 1,073,741,824 doc IDs each but only 1,024 live documents each (the rest deleted). You pass all their segments to one
addIndexes(CodecReader...)call on a writer with the defaultIndexWriterConfig. - You expect 2,048 documents added: far below the limit of 2,147,483,519 (
MAX_DOCS), and every document-limit checkaddIndexesmakes counts live documents. 9.8.0 adds them. - Instead it first glues the inputs into one temporary reader for
OneMerge#reorder. That reader counts all 2,147,483,648 doc IDs, deleted ones included, and refuses:IllegalArgumentException: Too many documents: composite IndexReaders cannot exceed 2147483519 but readers have total maxDoc=2147483648. Nothing is added. - The temporary reader was not needed: the default
reorder()returns null. Two calls (A, then B) add the 2,048 documents.
Applications that add several very large inputs in one addIndexes(CodecReader...) call with the default config, when their doc IDs, deleted or filtered-out ones included, pass 2,147,483,519 while their live documents fit: for example consolidating heavily deleted views of two billion-document indexes. The call fails cleanly and writes nothing; splitting the inputs over several calls works around it. Rare.
Mechanism, terms and numbers798 words
IndexWriter.addIndexes(CodecReader...) copies only the live documents of its inputs and checks the doc limit (MAX_DOCS, 2,147,483,519) against live documents only. Since 9.9.0, when no index sort is configured, addIndexesReaderMerge first wraps all inputs of the merge in a SlowCompositeCodecReaderWrapper so that OneMerge#reorder can renumber documents. The wrapper builds a MultiReader, which counts every doc ID, deleted ones included, and throws IllegalArgumentException: Too many documents: composite IndexReaders cannot exceed ... when they add up to more than the limit. The default reorder() returns null, so the view is built and thrown away.
So a call whose inputs fit by live documents but not by maxDoc() fails cleanly and adds nothing: at full scale with no test hook, two indexes of 1,073,741,824 doc IDs with 1,024 live documents each fail in one call on main and 10.5.2, succeed in two calls, and succeed in one call on 9.8.0. It needs more than 2^31 doc IDs across the inputs of one call, so it is rare. Introduced by #12622 (9.9.0); every release from 9.9.0 to 10.6.0 and main is affected. Building the view only when the inputs' maxDoc() sum fits fixes it; that fix passes the reduced-scale repro, the closest core suites, TestBPReorderingMergePolicy and core lint (not run at full scale), but it silently skips a custom reorder() for such an oversized merge.
- Admission counts live documents.
addIndexes(CodecReader...)(IndexWriter.java:3275) sumsleaf.numDocs()(:3294) and callstestReserveDocs(numDocs)(:3296). The defaultMergePolicy.findMerges(CodecReader...)puts all readers into oneOneMerge(MergePolicy.java:627-631), whosetotalMaxDocis the sum ofnumDocs()(MergePolicy.java:245-254); after successaddIndexesreserves that sum (IndexWriter.java:3344,:3356).addIndexesReaderMergechecks live documents once more (:3504,:3518). - The eager view. With no index sort and no input that has blocks without a parent field (
:3548-3556),addIndexesReaderMergerunsCodecReader mergedReader = SlowCompositeCodecReaderWrapper.wrap(readers);(:3561) and only thenmerge.reorder(mergedReader, directory, intraMergeExecutor)(:3562). Ifreorderreturns null, the input readers are merged as they are (afterOneMerge#wrapForMerge,:3542-3546, which by default returns each reader unchanged). - The view counts deleted documents.
wrapreturns a single reader as is (SlowCompositeCodecReaderWrapper.java:54); for two or more it builds the wrapper, which adds upreader.maxDoc()intointdoc starts (:73) and createsnew MultiReader(...)over the inputs (:95).BaseCompositeReadersumsmaxDoc()as along(BaseCompositeReader.java:86) and aboveIndexWriter.getActualMaxDocs()(:89) throwsIllegalArgumentException("Too many documents: composite IndexReaders cannot exceed ...")for a reader that is not aDirectoryReader(:99-107). - The view was not needed. The default
OneMerge#reorderreturns null (MergePolicy.java:325-328; javadoc "will be called when index sorting is disabled on a merged view of the OneMerge",:311-324).SegmentMerger(IndexWriter.java:3569) gets those input readers and drops deleted documents: without the view, 9.8.0 writes the merged segment at full scale, and the proposed fix passes the reduced-scale tests (it was not run at full scale). - How it fails. The exception is thrown before
SegmentMergerexists, so nothing is written; with the defaultConcurrentMergeSchedulerthe merge fails on the merge thread, which also reports it as an uncaughtMergeException, andaddIndexesrethrows the merge's exception (:3382); withSerialMergeScheduler(the minimal test) it comes straight out ofhandleMergeException(:5056). Either way only anErroris treated as tragic (:3390). Each failed call leaves its merge in the writer's merge-exception list (:5040-5041,:5819-5824) until the nextforceMergeclears it (:2250) or the writer is closed: a probe counted 20 retained entries after 20 failing calls. - Who reaches it. One index's own
maxDocis capped atMAX_DOCS(aDirectoryReaderabove it is rejected as corrupt,BaseCompositeReader.java:90-98), and a single input never builds aMultiReader, so at real scale one merge needs two or more input readers whosemaxDoc()sum exceeds the limit: for example the leaves of two indexes (the executed runs), or the leaves of one index passed twice, asTestIndexWriterMaxDocs.testAddTooManyIndexesCodecReaderrepeats one reader (read, not run). The ordinary merge path builds the same view (IndexWriter.java:5557), but there the writer has reserved every input document, so itsmaxDocsum stays within the limit.
| target | inputs (no test hook) | one call | two calls |
|---|---|---|---|
| main | 2 indexes x 1,073,741,824 doc IDs, 1,024 live each; maxDoc sum 2,147,483,648 = MAX_DOCS + 129 | IllegalArgumentException, nothing added | 2,048 added |
| 10.5.2 | the same | IllegalArgumentException | 2,048 added |
| 9.8.0 | the same | 2,048 added | 2,048 added |
| main (separate run) | 2 indexes x 1,073,741,760 doc IDs filtered to 32 live each; maxDoc sum MAX_DOCS + 1 | IllegalArgumentException | 64 added |
Exposure and likelihood242 words
- Who is hit. Callers of
addIndexes(CodecReader...)with the default configuration (no index sort) that pass two or more inputs (for example the segments of two indexes) holding more than 2,147,483,519 doc IDs in total, deleted or filtered-out ones included, while their live documents fit: for example heavily deleted, orFilterCodecReader-filtered, views of two indexes of about a billion documents each. - What goes wrong. The call is refused with a misleading message (the result would hold a fraction of the limit) and adds nothing. It fails cleanly: in a probe of 20 failing calls in a row (assertions on and off) no file was written, no document reservation leaked, the inputs were untouched, the writer stayed open and not tragic, and
CheckIndexwas clean afterwards. Each failed call does leave one entry in the writer's merge-exception list until the nextforceMergeor close. - Workarounds. Split the inputs so that each merge's
maxDoc()sum fits: oneaddIndexescall per input index (executed at full scale), or afindMerges(CodecReader...)override that splits them into groups (executed at small scale). An index sort on the destination is not a general workaround: it skips the view, but a sorted destination accepts only inputs that already have a congruent index sort and rejects unsorted ones withcannot change index sort(IndexWriter.java:3245-3251). - Likelihood: rare. Few deployments combine more than 2^31 doc IDs in one call, and the recorded searches found no public report since 9.9.0 (2023).
One JUnit test in lucene/core: a source index with two segments, maxDoc 2 with one deleted document and maxDoc 1, so 2 live documents and a maxDoc sum of 3. The test framework's setIndexWriterMaxDocs(2) lowers the limit for the destination, as TestIndexWriterMaxDocs does. One addIndexes call with both segments should add 2 documents; it throws.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index;

import java.util.List;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.StringField;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestAddIndexesDeletedDocsLimit extends LuceneTestCase {

  public void testOnlyLiveDocsCountTowardsLimit() throws Exception {
    try (Directory src = new ByteBuffersDirectory();
        Directory dst = new ByteBuffersDirectory()) {
      try (IndexWriter w =
          new IndexWriter(src, new IndexWriterConfig().setMergePolicy(NoMergePolicy.INSTANCE))) {
        w.addDocument(List.of(new StringField("id", "deleted", Field.Store.NO)));
        w.addDocument(List.of(new StringField("id", "live", Field.Store.NO)));
        w.commit();
        w.addDocument(List.of(new StringField("id", "live", Field.Store.NO)));
        w.deleteDocuments(new Term("id", "deleted"));
      }
      try (DirectoryReader r = DirectoryReader.open(src);
          IndexWriter w =
              new IndexWriter(
                  dst, new IndexWriterConfig().setMergeScheduler(new SerialMergeScheduler()))) {
        setIndexWriterMaxDocs(2);
        try {
          w.addIndexes(
              (CodecReader) r.leaves().get(0).reader(), (CodecReader) r.leaves().get(1).reader());
        } catch (IllegalArgumentException e) {
          fail("expected: 2 live docs added under a limit of 2; actual: " + e.getMessage());
        } finally {
          restoreIndexWriterMaxDocs();
        }
        assertEquals(2, w.getDocStats().numDocs);
      }
    }
  }
}
cd $LUCENE   # an apache/lucene checkout at 645d4fe14a20 (or upstream main, branch_10_6, 10.6.0)
cp $REPRO/TestAddIndexesDeletedDocsLimit.java lucene/core/src/test/org/apache/lucene/index/
./gradlew :lucene:core:test --tests org.apache.lucene.index.TestAddIndexesDeletedDocsLimit -Ptests.seed=DEADBEEF
# assertions off fails the same way: add -Ptests.asserts=false
- Expected
- 2 documents added: the limit is 2 and the inputs hold 2 live documents.
- Observed
IllegalArgumentException: Too many documents: composite IndexReaders cannot exceed 2 but readers have total maxDoc=3; nothing added, with assertions on and off.
More files, environment, full output304 words
Public API plus the test framework's setIndexWriterMaxDocs, ByteBuffersDirectory, SerialMergeScheduler so the merge runs on the test thread; deterministic, single thread. The limit is lowered only after the source index is built. At real scale one index cannot exceed the limit, so one merge needs two or more readers whose maxDoc() sum does, such as the leaves of two indexes; the full-scale runs with no test hook (in the observed output) show the same failure.
With the default ConcurrentMergeScheduler the test fails the same way, and the merge thread's uncaught MergeException is reported as well. As the regression test it can be used as is: it has the license header and passes core lint.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): affected; the same test also fails on the 10.6.0 and 9.9.0 jars and passes on 9.8.0 |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux, aarch64 |
TestAddIndexesDeletedDocsLimit > testOnlyLiveDocsCountTowardsLimit FAILED
    java.lang.AssertionError: expected: 2 live docs added under a limit of 2; actual: Too many documents: composite IndexReaders cannot exceed 2 but readers have total maxDoc=3
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:827B29374A95FE3C]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.apache.lucene.index.TestAddIndexesDeletedDocsLimit.testOnlyLiveDocsCountTowardsLimit(TestAddIndexesDeletedDocsLimit.java:48)

:lucene:core:test (FAILURE): 1 test, 1  failure

# the same with -Ptests.asserts=false. Where it is thrown (default ConcurrentMergeScheduler, main 645d4fe14a20):
org.apache.lucene.index.MergePolicy$MergeException: java.lang.IllegalArgumentException: Too many documents: composite IndexReaders cannot exceed 2 but readers have total maxDoc=3
    at __randomizedtesting.SeedInfo.seed([DEADBEEF]:0)
    at org.apache.lucene.index.ConcurrentMergeScheduler.handleMergeException(ConcurrentMergeScheduler.java:761)
    at org.apache.lucene.index.ConcurrentMergeScheduler$MergeThread.run(ConcurrentMergeScheduler.java:753)
Caused by: java.lang.IllegalArgumentException: Too many documents: composite IndexReaders cannot exceed 2 but readers have total maxDoc=3
    at org.apache.lucene.index.BaseCompositeReader.<init>(BaseCompositeReader.java:104)
    at org.apache.lucene.index.MultiReader.<init>(MultiReader.java:76)
    at org.apache.lucene.index.MultiReader.<init>(MultiReader.java:50)
    at org.apache.lucene.index.SlowCompositeCodecReaderWrapper.<init>(SlowCompositeCodecReaderWrapper.java:95)
    at org.apache.lucene.index.SlowCompositeCodecReaderWrapper.wrap(SlowCompositeCodecReaderWrapper.java:56)
    at org.apache.lucene.index.IndexWriter.addIndexesReaderMerge(IndexWriter.java:3561)
    at org.apache.lucene.index.IndexWriter$AddIndexesMergeSource.merge(IndexWriter.java:3463)
    at org.apache.lucene.index.ConcurrentMergeScheduler.doMerge(ConcurrentMergeScheduler.java:661)
    at org.apache.lucene.index.ConcurrentMergeScheduler$MergeThread.run(ConcurrentMergeScheduler.java:726)

# full scale, no test hook, main ea57360912ed (same four files), assertions off:
inputs: leaves=2048 sum maxDoc=2147483648 (MAX_DOCS+129) sum numDocs=2048
CONTROL two calls: OK numDocs=2048
ONE CALL: FAILED java.lang.IllegalArgumentException: Too many documents: composite IndexReaders cannot exceed 2147483519 but readers have total maxDoc=2147483648
# 10.5.2: the same; 9.8.0: ONE CALL: OK numDocs=2048- Every document-limit check and reservation on this path counts live documents; the javadoc throws only "if addIndexes would cause the index to exceed MAX_DOCS".
- The combined reader only feeds
OneMerge#reorder, whose default returns null; the same inputs split over two calls succeed. - 9.8.0 accepted the call; the 9.9.0 change never discussed doc limits, and nothing announces the restriction.
The full argument260 words
- Live documents everywhere. The up-front check (
IndexWriter.java:3294-3296),OneMerge(CodecReader...)'stotalMaxDoc(MergePolicy.java:245-254), the merge's own check (:3504,:3518) and the final reservation (:3344,:3356) all count live documents. The javadoc's only doc-limit failure is "if addIndexes would cause the index to exceed MAX_DOCS" (:3272-3273), andMAX_DOCSis the limit on documents "added to the index" (:201-203). The view is the one place that counts deleted documents. - Unused by default. The default
reorder()returns null and the view is discarded; the same inputs succeed in two calls or with one merge per reader. For inputs that are already index-sorted, the destination's index sort alone decides: two sorted inputs fail into an unsorted destination and succeed into one with the same sort, which skips the view (executed at small scale). Unsorted inputs cannot take that route, since a sorted destination rejects them. - A regression. 9.8.0 accepts the identical full-scale call. #12622, which added the view, never discusses doc limits,
addIndexesorMAX_DOCSin its 45 comments and reviews; its author describes the view as "the reordering logic that works on a merged view of the input segments and doesn't care about deletes". NoCHANGES.txt,MIGRATE.md, javadoc or test entry announces a limit on the inputs'maxDoc()sum. - Deleted and filtered inputs are normal here.
TestAddIndexes.testFakeAllDeletedadds an all-deleted filtered reader;MultiPassIndexSplitter("the input data comes from the input index with artificially applied deletes") andPKIndexSplitterpass filtered leaves.TestIndexWriterMaxDocstests theaddIndexeslimit only with all-live inputs.
The devil's-advocate check212 words
The strongest case for "works as designed", rated moderate by the independent reproducer and cross-model reviews (root-cause and intended lenses); the refute lens rated it weak and the intended-behaviour devil's advocate found it does not survive: a composite reader has one int doc-ID space, OneMerge#reorder is documented to receive a merged view whenever index sorting is off, so a merge whose inputs cannot be addressed as one reader is arguably unrepresentable; findMerges(CodecReader...) (whose javadoc mentions one merge per reader) or separate calls are the documented knobs. It also needs more than about 2.1 billion input doc IDs and fails loudly before anything is written, with an easy workaround, so maintainers may see a surprising limitation rather than a contract violation.
Why it fails: with the default configuration nothing uses the view, every document-limit check counts live documents, for already index-sorted inputs the destination's index sort alone decides whether the limit applies, and the call worked in 9.8.0 with no announcement of the change. Where it does hold: a merge policy that really overrides reorder(), such as BPReorderingMergePolicy, needs the view, so a fix must decide what that policy gets for an oversized group. Maintainers may also prefer a javadoc change, since the @throws clause does not literally say "only if".
Recommended Build the merged view only when the inputs' maxDoc sum fits (+7/-1 in IndexWriter.java)
Build the merged view only when the inputs' maxDoc() sum fits the limit (+7/-1 in IndexWriter.java); otherwise the merge runs on the input readers, which drop deleted documents. Caveat: a custom reorder() is then silently skipped for such a merge. Validated at reduced scale only: the minimal test, the closest core suites and TestBPReorderingMergePolicy pass.
// addIndexes only reserves live docs, so the inputs' maxDoc (deleted docs included) may add up
// to more than a single (composite) reader can address: then do not offer a merged view
final long totalMaxDoc = readers.stream().mapToLong(CodecReader::maxDoc).sum();
if (hasIndexSort == false
    && hasBlocksButNoParentField == false
    && readers.isEmpty() == false
    && totalMaxDoc <= getActualMaxDocs()) {
  CodecReader mergedReader = SlowCompositeCodecReaderWrapper.wrap(readers);
  ...
All options and trade-offs4 options · 495 words
One fix was built and validated on 645d4fe14a20 with gradle; the alternatives come from the adjudication and the checks and were not run.
Build the merged view only when the inputs' maxDoc sum fits (+7/-1 in IndexWriter.java) (validated by the checks) (recommended)
In addIndexesReaderMerge, add the inputs' maxDoc() sum to the condition that builds the view. When it does not fit, the merge runs on the input readers, exactly as without reordering, and drops deleted documents. A custom reorder() is then silently not called for that group (see the trade-offs).
// addIndexes only reserves live docs, so the inputs' maxDoc (deleted docs included) may add up
// to more than a single (composite) reader can address: then do not offer a merged view
final long totalMaxDoc = readers.stream().mapToLong(CodecReader::maxDoc).sum();
if (hasIndexSort == false
    && hasBlocksButNoParentField == false
    && readers.isEmpty() == false
    && totalMaxDoc <= getActualMaxDocs()) {
  CodecReader mergedReader = SlowCompositeCodecReaderWrapper.wrap(readers);
  ...
Trade-offs
- For an oversized group a merge policy that overrides
reorder()is not called, so that group is merged without reordering, silently (a probe countedreorderCalls=0).BPReorderingMergePolicyalready treats reordering as best-effort: it skips it onNotEnoughRAMExceptionand recordsreordered=falsein the segment diagnostics whenreorder()was not called. AninfoStreammessage for the skipped case would make it visible (not run). - Cost: one pass over the inputs'
maxDoc()per merge.
What the checks validated
- Scratch worktree of
645d4fe14a20, OpenJDK 25.0.3, seedDEADBEEF: stock, the minimal test fails with assertions on and off; with the fix it passes, on and off. - With the fix:
TestAddIndexes39 of 39,TestIndexWriterMaxDocs(19 run, 2 skipped),TestIndexWriterMergePolicy(18 run, 3 skipped),TestOneMergeWrappingMergePolicyandTestGetVectorCountCodecWrapperspass: 83 tests, 5 skipped, 0 failures. - With the fix:
TestBPReorderingMergePolicypasses (1 run, 2 nightly tests skipped; an earlier check ran the nightly tests with the fix: 3 of 3 pass). - Core lint (google-java-format, ecj, forbidden APIs) passes with the fix and the test in place.
- Not run at full scale: every fix run lowered the limit with the test hook.
For example a OneMerge method that says whether it reorders, or a view built lazily; give a clear error only when a reordering policy meets an oversized group (the adjudication's preference).
Trade-offs
Keeps the default configuration free of the view and makes the oversized case explicit, but needs a small API change or an override check; not run.
Group the readers so that each OneMerge's maxDoc() sum fits.
Trade-offs
Reordering still runs per group, but one call then produces several segments, unlike the documented default of one, and custom findMerges overrides still hit the limit; not run.
State that, without an index sort, the inputs of one merge must fit MAX_DOCS by maxDoc(), deleted documents included.
Trade-offs
No code change, but keeps the 9.9.0 regression and makes the limit depend on index sorting; not run.
Solr's MERGEINDEXES core-admin action passes the segments of several source indexes to one addIndexes(CodecReader...) call, so merging very large, heavily deleted cores there can hit it (read, not tested). Solr's shard split adds one filtered segment per call, so it never builds the view and is not affected.
Semi-formal. While modelling the doc-ID arithmetic of the merged view in Z3 with exact Java int semantics, the AI-assisted hunt asked whether inputs can fit the limit by live documents but not by maxDoc(): satisfiable for addIndexes, impossible on the ordinary merge path. A JUnit on the stock jar then hit the exception.
The method in full166 words
Method: semi-formal (an SMT query encoding a hypothesis formed while modelling, then executed tests).
- In a hunt unit (
CodecReaderwrappers) the finder modelledSlowCompositeCodecReaderWrapper's doc-ID arithmetic in Z3 (quantifier-free bit-vectors, exact Javaintsemantics). - Query Q5a, with the ordinary merge path's precondition (the inputs'
maxDoc()sum withinMAX_DOCS, which the writer guarantees for its own segments), showed that the view's doc starts never wrap (unsat). - Query Q5b encoded
addIndexes(CodecReader...)'s actual precondition (live documents withinMAX_DOCS) and asked for amaxDoc()sum above it: sat, with a concrete witness. So the view'sMultiReadercheck is reachable from a legal call. - The finder bridged that to the stock jar with a JUnit at reduced scale and a full-scale run with no test hook; independent checks reproduced it (see the checks below).
- Recorded as semi-formal rather than formal: the query encodes a hypothesis and its sat answer is plain arithmetic; the exception path itself was found by reading the code and confirmed by execution.
No public report of this bug found in the recorded searches (2026-10-26, refreshed 2026-10-31): three search-tool runs over GitHub, the JIRA archive, the mailing lists and the web, 33 manual GitHub searches and a list phrase search; 25 items read. Closest: the open draft #16847 (long doc IDs), which changes the limit behind this exception.
Searches4 searches
Verdict new (no public report found in the recorded searches; absence cannot be proven); not fixed upstream. Closest items, none this bug: #12622 (introduced the view); #6905 / LUCENE-5843 and #7360 / LUCENE-6299 (2014-2015, the limit checks and this message, for indexes that really exceed the limit); #11253 / #633 (LUCENE-10216, the live-document accounting of OneMerge(CodecReader...)); #14994, #15025, #15120 (other defects in addIndexesReaderMerge); #16879 (open, edits the wrapper for HNSW reuse, not this code).
Open draft #16847 (jimczi, "Support more than 2^31 documents per index (long global doc ids)"): it makes IndexReader.maxDoc() a long, checks composite totals against a new 2^37 limit, and its MergePolicy javadoc says merge inputs "may, together, hold more than Integer.MAX_VALUE documents (only the merged result is bounded by MAX_DOCS once deletions are dropped)", which is this bug's premise. It keeps the eager wrap(readers) and the view's int docStart += reader.maxDoc(); if it lands unchanged, this clean exception may turn into a view with wrapped doc starts (read from the diff, not run).
Gaps: only public, indexed sources; private reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| a scripted prior-report search: GitHub (apache/lucene issues, PRs, commits), downstream repositories, dev@, java-user@, issues@, commits@, JIRA archive, web | 2026-10-26 | two runs (class and method names, maxDoc/numDocs/deleted/live docs, both symptom messages; the reorder angle) plus the finder's earlier run | 1,274, 399 and 1,262 distinct hits; none is this bug |
| GitHub (manual): apache/lucene, apache/solr and other downstream repositories; all 412 open apache/lucene PRs | 2026-10-26 | 33 searches; the changed files of every open PR | only the related items listed above |
| JIRA archive (LUCENE, SOLR), lists.apache.org, web | 2026-10-26 | "composite IndexReaders cannot exceed", "readers have total maxDoc", "Too many documents" with addIndexes or mergeindexes; 9 web queries | 35 mails and 6 JIRA issues, all about indexes that really exceed the limit |
| GitHub refresh | 2026-10-31 | the symptom message and method names, updated since 2026-10-20; commits on main since 2026-10-26 to the four files; #16847 state | nothing new; #16847 still an open draft (two of its queries were re-run the same day, nothing new) |
Introduced by #12622 (f7cab1645017, 2023-11-23), which added OneMerge#reorder and the merged view; first released in 9.9.0. Executed: all 23 releases from 9.9.0 to 10.6.0 and main fail; 8.11.4, 9.0.0, 9.7.0 and 9.8.0 pass. Not fixed.
Versions tested8 rows
Introduced by #12622 "Add a merge policy wrapper that performs recursive graph bisection on merge." (jpountz), merged 2023-11-23 as f7cab1645017 on main, with the branch_9x backport 6b1538b3313 the same day. It added SlowCompositeCodecReaderWrapper, OneMerge#reorder (default null) and the view in addIndexesReaderMerge and on the ordinary merge path. Found with git blame, git log -L and a pickaxe for SlowCompositeCodecReaderWrapper.wrap(readers), which finds only these two commits; isolated by execution: 9.8.0 plus only the backport's core diff fails, 9.9.0 with only the view block removed passes.
Later changes, not fixes: #13128 (9.11.0) also skips the view when inputs have blocks but no parent field; #13289 (9.12.0) passes an executor to reorder(). The doc-limit check itself (LUCENE-6299, 2015) is older and unchanged. No later commit touches the defect lines on main (upstream main 2f424fd428da, 2026-10-30).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | the minimal test fails (gradle and the standalone runner, assertions on and off) |
| 10.6.0 | affected | the minimal test fails at reduced scale, assertions on and off (no full-scale run) |
main ea57360912ed, 10.5.2 | full scale | no test hook: maxDoc sum 2,147,483,648 with 2,048 live documents fails in one call, works in two |
| 9.9.0 to 10.5.2 (22 releases) | 9.9.0: first affected | the hunt's two test classes fail 3 of 7 at reduced scale; assertions off too on 9.9.0, 9.12.3, 10.5.2; the minimal test fails on 9.9.0 |
| 9.8.0 | last unaffected | passes at reduced and full scale (one call adds 2,048 documents); the minimal test passes |
| 8.11.4, 9.0.0, 9.7.0 | not affected | pass (no merged view before #12622); 8.11.4 and 9.0.0 with a copy of the test classes whose only change is the test-framework import |
| 9.8.0 + only the backport's core diff; 9.9.0 minus only the view block | bisect | the first fails, the second passes |
fix on 645d4fe14a20 | not affected | the minimal test passes, assertions on and off; 83 core tests (5 skipped) and TestBPReorderingMergePolicy pass (reduced scale only) |
An independent reproducer, a root-cause check, an intended-behaviour devil's advocate and an adjudication confirmed it with their own tests, at small and full scale. Reading-only reviews by another model family (OpenAI GPT-5.6) agreed on the root cause; one gave a procedural "not real" because it could not run code. Still reproduces on main.
Checks and verdicts310 words
Neither GPT review executed code; the finder, the independent reproducer, the root-cause check's separate runs, the devil's advocate, the adjudication, the follow-up and this doc did.
| Check | Verdict | What it found |
|---|---|---|
| Finder (Z3 model, then JUnit) | candidate, executed | Fails on main, 10.5.2, 10.0.0, 9.12.3, 9.9.0; passes on 9.8.0 and with the fix; full scale on a separate host: maxDoc sum MAX_DOCS + 1, 64 live documents, one call fails. |
| Cross-model reviews, refute and intended lenses (OpenAI GPT-5.6, reading only) | not real (low, procedural); real (medium) | Could not run code; both agreed on the root cause and that the inputs are in contract; the refute lens rated the intended argument weak, the intended lens moderate. |
| Independent reproducer | real | Own 5-test class fails 2 of 5 on main, 10.5.2, 9.12.3, 9.9.0; own full-scale run with no hook fails on main and 10.5.2, passes on 9.8.0; the writer stays usable. |
| Root-cause adversary (OpenAI GPT-5.6, reading only) and separate runs | real, medium | Root cause is the eager view, not the composite check; 7-test class: 3 fail, including maxDoc sum = limit + 1 while = limit passes; with the fix 7 of 7 pass and a custom reorder() is skipped for an oversized group. |
| Intended-behaviour devil's advocate | real, medium-high | Only the unsorted destination fails (index-sorted inputs); a destination with the same sort (same inputs) and one merge per reader (unsorted inputs) succeed; 9.8.0 passes all three. It concludes the works-as-designed argument does not survive. |
| Adjudication | confirmed, high | Re-ran the independent test with a new seed: 2 of 5 fail, assertions on and off. |
| Current-main re-runs | still reproduces | Main a9779ef3c193 (three replays) and 645d4fe14a20 (the minimal test, assertions on and off). |
| This doc | still reproduces; fix validated | Gradle on a scratch worktree of 645d4fe14a20; the 10.6.0, 9.9.0 and 9.8.0 jars. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 509 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,309 words
- Registry title
- addIndexes(CodecReader...) with the default config rejects inputs whose maxDoc() sum, deleted documents included, exceeds MAX_DOCS although only their live documents are added, because it always builds a merged view of the inputs for OneMerge#reorder (regression since 9.9.0)
- Area
- index / IndexWriter addIndexes(CodecReader...) (addIndexesReaderMerge merged view: SlowCompositeCodecReaderWrapper over a MultiReader, BaseCompositeReader doc limit)
- Priority
- Low, rank 978: IndexWriter.addIndexes() rejects inputs whose doc IDs, deleted ones included, add up to more than 2^31; the failure is clean, the writer stays usable and splitting the call works around it.
- Impact class
- wrong error
- Impact note
- Hits an application that adds several very large inputs in one addIndexes(CodecReader...) call with the default IndexWriterConfig (no index sort) when the inputs' maxDoc() sum, deleted or filtered-out documents included, exceeds 2^31-129 while their live documents fit (for example consolidating heavily deleted or filtered views of two indexes of about a billion documents each): the call fails cleanly with IllegalArgumentException and adds nothing, the writer stays open and usable and nothing is written, the default ConcurrentMergeScheduler also reports the exception as an uncaught MergeException, and one call per input (or a findMerges(CodecReader...) override that splits the inputs) works around it.
- Summary
- You call IndexWriter.addIndexes(CodecReader...) with readers that have many deleted or filtered-out documents, so their live documents fit under IndexWriter.MAX_DOCS but their maxDoc() values (deleted documents included) add up to more. You expect the call to succeed, since addIndexes counts and reserves only live documents, its javadoc throws IllegalArgumentException only if the index would exceed MAX_DOCS, and 9.8.0 accepted the same call. Instead, with the default configuration it throws IllegalArgumentException 'Too many documents: composite IndexReaders cannot exceed ...' and adds nothing, because since 9.9.0 addIndexesReaderMerge always wraps the inputs in a SlowCompositeCodecReaderWrapper (a MultiReader over the uncompacted inputs) for OneMerge#reorder, whose default returns null and discards the view.
- Introduced
- f7cab1645017d863331b42900581b67d3591e2da on main and its branch_9x backport 6b1538b33136a4737ad0d22b3633e62f3d7f362b, PR #12622 'Add a merge policy wrapper that performs recursive graph bisection on merge.' (jpountz): it added SlowCompositeCodecReaderWrapper and OneMerge#reorder and made addIndexesReaderMerge build the merged view whenever no index sort is configured [read: git blame, git log -L and a pickaxe for 'SlowCompositeCodecReaderWrapper.wrap(readers)', which finds only these two commits; exec: 9.8.0 plus only the backport's core diff fails, 9.9.0 with only the merged-view block removed passes] (2023-11-23 (f7cab1645017 on main and the branch_9x backport 6b1538b3313, same day))
- First affected version
- 9.9.0 [exec] (tagged 2023-12-04, through the branch_9x backport 6b1538b3313; fails with -ea and -da); on the 10.x line 10.0.0 [exec]; 9.8.0 is the last unaffected release [exec: -ea and -da at reduced scale, and -da at full scale with no test hook]
- Affected versions
- Every release from 9.9.0 through 10.6.0 (23 releases: 9.9.0-9.9.2, 9.10.0, 9.11.0, 9.11.1, 9.12.0-9.12.3, 10.0.0, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0, 10.5.0-10.5.2, 10.6.0) and main ea57360912ed [exec: the finder's and the independent reproduction's tests at reduced scale (limit 10 via the test framework's setIndexWriterMaxDocs) fail 3 of 7 on each of the 22 releases from 9.9.0 to 10.5.2 and on main; -da also at 9.9.0, 9.12.3, 10.5.2 and main]; at full scale with no test hook (inputs' maxDoc sum 2^31, 2048 live documents) main and 10.5.2 fail and 9.8.0 passes [exec, -da]. Not affected: 8.11.4, 9.0.0, 9.7.0 and 9.8.0 [exec]; every release from 5.0.0 to 9.8.0 by reading (no merged view before #12622). Not fixed upstream: no later commit touches the defect code on main (head e1c4184cb98, 2026-10-26) or branch_10x [read]; 10.6.0 (released 2026-10-29): the minimal test fails on the 10.6.0 release jars (SHA-1 checked against Maven Central) with -ea and -da [exec 2026-10-31]. All runs on aarch64 Linux, JDK 25 (plain Java logic, no vector code).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3; also reached by code reading
- Upstream and prior reports
- none found (2026-10-26, read-only; verdict new): two scripted prior-report searches over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (1274 and 399 distinct hits), the finder's earlier run (1262 hits), 33 read-only GitHub searches on apache/lucene and downstream repositories, JIRA REST queries on LUCENE and SOLR, a lists.apache.org phrase search for 'composite IndexReaders cannot exceed' (35 mails, all about indexes that really exceed the limit), web searches, and the file lists of all 412 open apache/lucene PRs (finder); 25 items read, none the same bug. Related, not reports: #12622 (the introducing PR; its comments and reviews never discuss the doc limit), #6905 / LUCENE-5843 and #7360 / LUCENE-6299 (2014-2015, the doc-limit checks and this message, about indexes that really exceed the limit), #11253 / #633 (LUCENE-10216, the live-doc OneMerge accounting), the open draft #16847 (jimczi, long global doc IDs: it changes the limit behind this exception and keeps the view's int docStart, so if it lands unchanged this clean exception may become a silently wrapped view; read from the diff, not executed) and the open PR #16879 (touches SlowCompositeCodecReaderWrapper, not this code). Not fixed: no later commit to the defect code on main or branch_10x, and no CHANGES or MIGRATE entry.
- Lucene commit tested
- main
645d4fe14a20(gradle in a scratch worktree and the standalone runner, assertions on and off); the minimal test on the 10.6.0 jars (fails, assertions on and off), 9.9.0 (fails) and 9.8.0 (passes); the hunt's two test classes on the 22 releases from 9.9.0 to 10.5.2, on 8.11.4, 9.0.0, 9.7.0 and 9.8.0 (8.11.4 and 9.0.0 with a copy whose only change is the test-framework import) and on mainea57360912ed; full scale with no test hook only on mainea57360912ed, 10.5.2 and 9.8.0 (assertions off); the recommended fix in a scratch worktree of645d4fe14a20, at reduced scale only. The four defect files are identical atea57360912ed,645d4fe14a20and upstream main2f424fd428da(2026-10-30).
- Finding record
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3272-3273 (at ea57360912ed) (addIndexes(CodecReader...) javadoc: '@throws IllegalArgumentException if addIndexes would cause the index to exceed MAX_DOCS'), :3289-3296 (sums leaf.numDocs(), testReserveDocs(numDocs)), :3500-3518 (addIndexesReaderMerge: numDocs sum, testReserveDocs), :3560-3566 (merged view built when there is no index sort, before merge.reorder(); discarded when reorder returns null), :5557 (the same view on the ordinary merge path), :201-204 (MAX_DOCS javadoc: documents 'added to the index')lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:54-56 (at ea57360912ed) (wrap: a single reader is returned as is), :66-75 (int docStarts += reader.maxDoc()), :95 (new MultiReader over the inputs)lucene/core/src/java/org/apache/lucene/index/BaseCompositeReader.java:82-104 (at ea57360912ed) (long maxDoc sum; IllegalArgumentException 'Too many documents: composite IndexReaders cannot exceed' for a non-DirectoryReader above getActualMaxDocs())lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:245-254 (at ea57360912ed) (OneMerge(CodecReader...) totalMaxDoc = sum of numDocs), :311-327 (OneMerge#reorder javadoc 'called when index sorting is disabled on a merged view'; default returns null)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-208 (at 645d4fe14a20) (MAX_DOCS), 3272-3275, 3294-3296, 3344, 3356, 2250, 3039-3042, 3245-3251, 3382, 3390, 3504, 3518, 3542-3546, 3548-3566, 3569, 5040-5041, 5056, 5555-5558, 5819-5824; MergePolicy.java:301-309 (wrapForMerge); lucene/core/src/test/org/apache/lucene/index/TestIndexWriterMaxDocs.java:433-481lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:49-58, (at 645d4fe14a20) 66-75, 95lucene/core/src/java/org/apache/lucene/index/BaseCompositeReader.java:74-107 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:245-254, (at 645d4fe14a20) 311-328, 615-631a Lucene clone git diff ea57360912ed 645d4fe14a20 and 645d4fe14a20 origin/main (2f424fd428da) on the four files: empty
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:201-203, (at 645d4fe14a20) 3272-3273, 3294-3296, 3344, 3356, 3504, 3518; MergePolicy.java:245-254, 311-328, 615-626lucene/core/src/test/org/apache/lucene/index/TestAddIndexes.java:1585-1604; (at 645d4fe14a20) lucene/misc/src/java/org/apache/lucene/misc/index/MultiPassIndexSplitter.java:42-45; PKIndexSplitter.java:120-129
- Suggested fix
lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:133-158 (at 645d4fe14a20)
- History
a Lucene clone git show releases/lucene/10.6.0:lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3601-3602 (the same view)
- TestAddIndexesDeletedDocsLimit.java (one test):
repro/LFV-285/src/org/apache/lucene/index/TestAddIndexesDeletedDocsLimit.java(56 lines)
Made separately from this text, from the code at 645d4fe14a20 and runs executed for the diagrams; the PNG is the summary still.
assets/LFV-285/bug.png(509 KB)