- HTML can write any character as a numeric reference:
é(decimal) andé(hex) both mean é. Leading zeros are allowed, soéandémean é too. HTMLStripCharFilterdecodes these references before the tokenizer runs, sobadreaches the index as the wordbad.- The largest code point, U+10FFFF, needs six hex digits or seven decimal digits. The scanner is meant to cap references at exactly these lengths; longer ones are left as text on purpose.
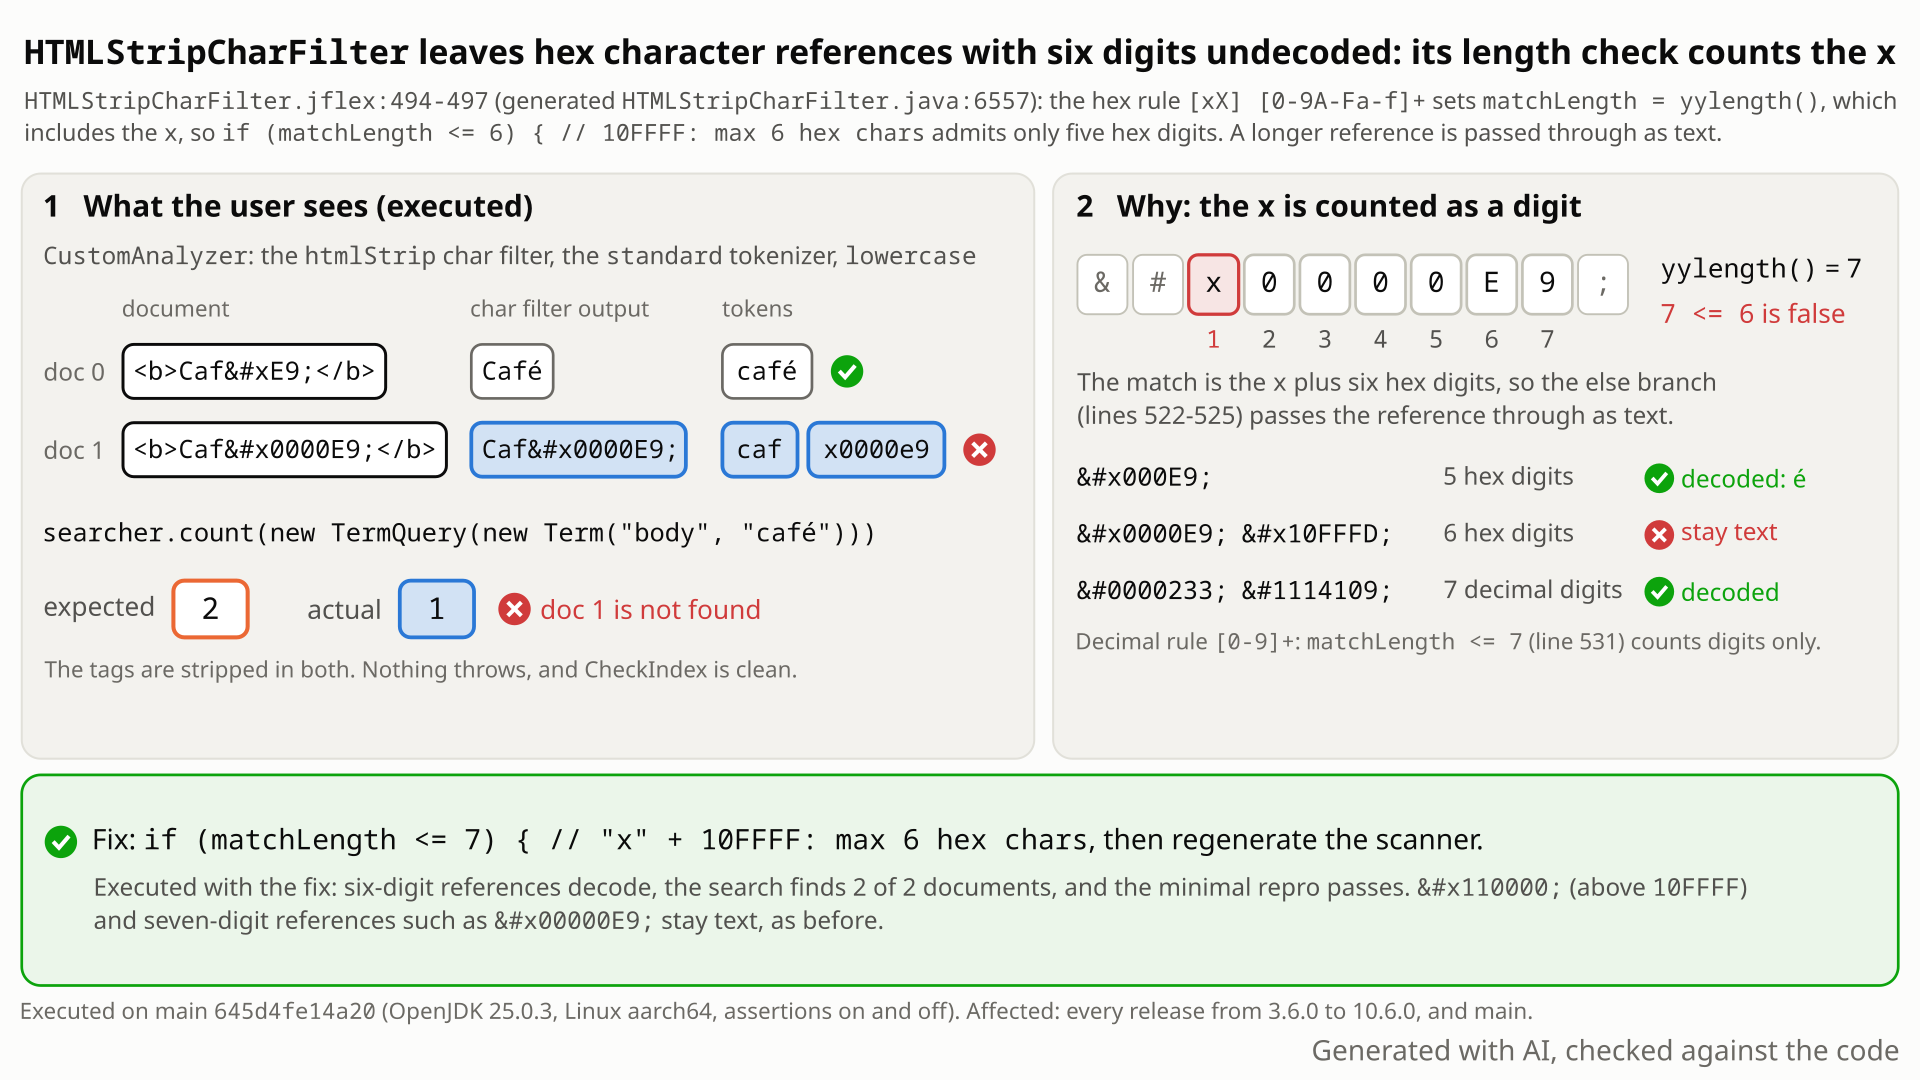
café finds <b>Café</b> but not <b>Café</b>: HTMLStripCharFilter leaves the six-hex-digit reference as text, which is tokenized as caf and x0000e9, because its length check counts the x (yylength() = 7 fails <= 6). Select the still to open it at full size. Generated with AI, checked against the code.- Strip HTML with
HTMLStripCharFilter(or thehtmlStripchar filter) in front ofStandardTokenizer, and indexbad: the word "bad" with itsawritten as a zero-padded six-hex-digit reference, which is valid HTML. - You expect the token
bad, as you get forbad(2 hex digits),bad(5 hex digits) andbad(7 decimal digits). The scanner's comment allows hex references of "max 6 hex chars". - Instead the reference stays literal and is indexed as three tokens:
b,x000061,d. ATermQueryforbadfinds the 2-digit, 5-digit and decimal versions (3 hits) but not this one. - Why: the hex rule matches the
xplus the digits, and the checkmatchLength <= 6counts thex. Six digits make 7, so the reference is passed through unchanged. The decimal rule beside it counts only digits and is right. - Only references with exactly six hex digits are hit: zero-padded ones such as
éand plane-16 characters (U+100000 to U+10FFFD). Offsets stay correct and nothing throws.
Applications that strip HTML with HTMLStripCharFilter or the htmlStrip factory, at default settings. Only hex references with exactly six digits are hit: zero-padded ones (é) and plane-16 private-use characters (U+100000 to U+10FFFD). A word containing one is indexed in pieces and not found by its decoded form. Rare; no error, no index damage.
Mechanism, terms and numbers405 words
HTMLStripCharFilter turns numeric character references back into the characters they name before the text is tokenized. Its hexadecimal rule is meant to accept up to six hex digits, enough for the largest code point 10FFFF, as the comment next to the check says ("10FFFF: max 6 hex chars"). But the length it checks is the length of the whole match, x included, so only five digits get through.
A reference with exactly six hex digits, such as the zero-padded é (é) or the plane-16 􀀀 and , is therefore emitted unchanged, as literal text, while é, é and  are decoded. With StandardTokenizer, bad is indexed as b, x000061, d, and a TermQuery for bad misses the document. It has been this way since the JFlex scanner shipped in 3.6.0. The fix is one character in the grammar plus regenerating the scanner.
After &# the scanner enters the state NUMERIC_CHARACTER (HTMLStripCharFilter.jflex:351). Its hex rule (:494-527):
[xX] [0-9A-Fa-f]+ {                       // the match is the x plus every digit
  int matchLength = yylength();             // :495, counts the x
  ...
  if (matchLength <= 6) { // 10FFFF: max 6 hex chars        :497
    String hexCharRef
        = new String(zzBuffer, zzStartRead + 1, matchLength - 1);   // skips the x
    ...
    if (codePoint <= 0x10FFFF) { ... decode ... }            :506
    else { pass through as text }                            :517-521
  } else { pass through as text }                            :522-526
Six hex digits make matchLength 7, so the reference takes the last branch and its original characters are emitted unchanged. The decimal rule (:528-531, [0-9]+) matches digits only and checks matchLength <= 7 // 0x10FFFF = 1114111: max 7 decimal chars, which is right. The generated scanner has the same two checks (HTMLStripCharFilter.java:6557 and :6327).
reference digits output
a 2 hex a decoded
a 5 hex a decoded
a 6 hex a NOT decoded <- the bug
a 7 hex a literal by design, also after the fix
a 7 dec a decoded
a 8 dec a literal by designEnd to end (StandardTokenizer + LowerCaseFilter): bad gives the tokens b (offsets 0-1), x000061 (3-10) and d (11-12); TermQuery(body:bad) finds the 2-digit, 5-digit and 7-decimal-digit documents (3 hits) and misses the six-digit one; CheckIndex is clean. a  z gives a, x10ffff, z.
Exposure and likelihood148 words
- Trigger. A hex reference with exactly six hex digits whose value is at most
0x10FFFF: a plane-16 character (U+100000 to U+10FFFD, Supplementary Private Use Area-B; U+10FFFE and U+10FFFF are noncharacters) or a smaller code point zero-padded to six digits (HTML allows leading zeros). Reached throughnew HTMLStripCharFilter(reader)or the factory (SPI namehtmlStrip), with no option to set. - Effect. The reference is indexed as text, for example the token
x000061orx10ffff, so a word that contains it is not found by its decoded form. The text around it is tokenized normally, offsets point at the original text, nothing throws, CheckIndex is clean. - Not affected. Every code point below U+100000 in its shortest hex form (at most five digits), decimal references of up to seven digits, and named entities.
- Likelihood. Rare: the recorded searches found no public report of it since it shipped in 2012.
One JUnit class, one test method, one input (é), public API only, analysis-common only. It reads the filter's output and expects é.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.charfilter;

import java.io.Reader;
import java.io.StringReader;
import java.io.StringWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHTMLStripHexCharRefSixDigits extends LuceneTestCase {

  public void testSixHexDigitReference() throws Exception {
    StringWriter out = new StringWriter();
    try (Reader r = new HTMLStripCharFilter(new StringReader("é"))) {
      r.transferTo(out);
    }
    // expected the six-hex-digit reference decoded to "é"; actual: it stays literal "é"
    assertEquals("é", out.toString());
  }
}
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests TestHTMLStripHexCharRefSixDigits -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
éstrips toé, likeéandé.- Observed
expected:<[é]> but was:<[é]>: the reference comes back unchanged; assertions on and off.
More files, environment, full output191 words
new HTMLStripCharFilter(new StringReader("é")) is read to the end with Reader.transferTo and the output is compared with é. Deterministic, single thread; LuceneTestCase is only the base class. é is an ordinary BMP character, so the expected value needs no surrogate pair; plane-16 references such as 􀀀 take the same branch.
Regression test: this same class (or its one method added to TestHTMLStripCharFilter); it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; release 10.6.0: fails; 3.6.0 to 10.5.2: the same literal output with the history probe (this test needs 9.0 or later); with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform run; plain Java string handling) |
cp $REPRO/TestHTMLStripHexCharRefSixDigits.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests TestHTMLStripHexCharRefSixDigits -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
> org.junit.ComparisonFailure: expected:<[é]> but was:<[é]>
> at __randomizedtesting.SeedInfo.seed([DEADBEEF:54CBF2DB236B7CEA]:0)
> at app/junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:117)
> at app/junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:146)
> at app//org.apache.lucene.analysis.charfilter.TestHTMLStripHexCharRefSixDigits.testSixHexDigitReference(TestHTMLStripHexCharRefSixDigits.java:32)
:lucene:analysis:common:test (FAILURE): 1 test, 1 failure
# standalone runner, seed DEADBEEF: main 645d4fe14a20 (-ea and -da) and 10.6.0 (-da) fail with the same message- The check's comment says "10FFFF: max 6 hex chars", and the next line skips the
xto parse the digits; the check counts it. - The decimal rule beside it counts only digits:
édecodes,édoes not. - With five digits the hex rule's own out-of-range branch is dead code; no checked document states a five-digit limit.
The full argument190 words
- The stated limit.
HTMLStripCharFilter.jflex:497: "10FFFF: max 6 hex chars": six hex digits, the length of the largest code point. The implementation admits five. - The code knows the
xis in the match.:498-499parsesnew String(zzBuffer, zzStartRead + 1, matchLength - 1). - The sibling is right.
:531admits seven decimal digits for1114111;andédecode,andédo not (executed). - Dead code. With at most five digits the largest value is
0xFFFFF, so thecodePoint <= 0x10FFFFelse-branch (:517-521) is unreachable. - No checked document states five digits. Not the class javadoc (
:31), the factory or the package docs, no CHANGES or MIGRATE entry, and not the LUCENE-3690 discussion (#4764). Upstream tests assert that numeric references decode (TestHTMLStripCharFilter.java:115-119testEntities,:601-634testUTF16Surrogates) but never use more than four hex digits. - Partly a regression, in lineage only. The Solr class that LUCENE-3690 replaced read up to 10 hex digits and decoded
é(executed on the Solr 3.5.0 jar). It is not a regression between Lucene releases: Lucene 3.5.0 had no LuceneHTMLStripCharFilter. Neither version ever decoded six-digit supplementary references correctly.
The devil's-advocate check102 words
The strongest case for "intended": the class only "attempts to strip out HTML constructs" (HTMLStripCharFilter.jflex:31); it does not follow HTML5's numeric-reference rules anyway (values above 0x10FFFF and long zero padding stay literal), so a digit cap is an implementation choice; and six-digit references are uncommon. A cross-model reviewer rated this "moderate".
Why it fails: the cap's intended value is written next to the check, and the code misses its own stated limit by one. That is an implementation slip, not a choice about HTML5 conformance, and "uncommon" is about impact, not intent. Every reviewer and the adjudication rejected the argument.
Recommended Allow seven characters: the x plus six digits (validated)
Count the x: change matchLength <= 6 to <= 7 in HTMLStripCharFilter.jflex and regenerate the scanner (one generated line changes). The repro, the 64 charfilter tests and the whole analysis-common module pass. Six-digit references then decode like their shorter spellings (old documents keep their tokens until reindexed); seven-digit hex and out-of-range values stay literal.
   [xX] [0-9A-Fa-f]+ {
     int matchLength = yylength();
     inputSegment.write(zzBuffer, zzStartRead, matchLength);
-    if (matchLength <= 6) { // 10FFFF: max 6 hex chars
+    if (matchLength <= 7) { // "x" + 10FFFF: max 6 hex chars
       String hexCharRef
           = new String(zzBuffer, zzStartRead + 1, matchLength - 1);
All options and trade-offs3 options · 491 words
One fix was written and validated in a scratch worktree of 645d4fe14a20; the alternatives are described but not run.
Change the bound in the grammar and run ./gradlew :lucene:analysis:common:regenerateHTMLStripCharFilter, which rewrites HTMLStripCharFilter.java:6557 the same way (the only change in the generated file) and updates src/generated/checksums/regenerateHTMLStripCharFilter.json: 3 files, +4/-4. The regenerated scanner is byte-identical to the finder's hand-edited copy.
   [xX] [0-9A-Fa-f]+ {
     int matchLength = yylength();
     inputSegment.write(zzBuffer, zzStartRead, matchLength);
-    if (matchLength <= 6) { // 10FFFF: max 6 hex chars
+    if (matchLength <= 7) { // "x" + 10FFFF: max 6 hex chars
       String hexCharRef
           = new String(zzBuffer, zzStartRead + 1, matchLength - 1);
Trade-offs
- A visible analysis change for every hex reference with exactly six digits, not only the headline examples. Each now decodes the way its shorter spelling already does (executed):
�becomes U+0000 like�; the zero-padded surrogate�becomes U+FFFD like�(HTMLStripCharFilter.jflex:509-511; the paired-surrogate rules at:355-489match only adjacent unpadded pairs); an unterminatedؚt the end of the input becomesalikea. - The tokens of such text change, so documents indexed before the fix keep the old tokens until they are reindexed. Worth a CHANGES entry under Bug Fixes.
- Unchanged: seven or more hex digits and eight or more decimal digits stay literal (the stated limits); values above
0x10FFFFsuch as�stay literal through the range check.
What the checks validated
Gradle --no-daemon in a scratch worktree of 645d4fe14a20, OpenJDK 25.0.3 (2026-10-31). Stock: the repro fails with assertions on and off. With the fix:
- the repro passes with assertions on and off;
org.apache.lucene.analysis.charfilter.*: 64 tests (TestHTMLStripCharFilter 36, TestHTMLStripCharFilterFactory 7, TestMappingCharFilter 18, its factory 2, the repro 1), 0 failures, seeds DEADBEEF and CAFEBABE;- the whole
:lucene:analysis:common:test, seed DEADBEEF: 340 test classes, 1,910 tests, 18 skipped, 0 failures (counted from the test-result XML; an independent fact check's own run got the same totals); regenerateHTMLStripCharFilterChecksumCheckpasses;- end to end (the same change on the earlier main):
badbecomes the tokenbadandTermQuery(body:bad)finds it (4 hits instead of 3); an independent 7-test check also passes, including�staying literal.
int hexDigits = matchLength - 1; if (hexDigits <= 6), and use hexDigits in the substring.
Trade-offs
Same behaviour as the recommended fix and reads more clearly; a slightly larger diff.
Skip leading zeros, then cap at six significant hex digits (and seven decimal), as HTML5 decoders do.
Trade-offs
Also decodes a, but changes the stated limits for seven or more digits: a behaviour change beyond this bug. Dropping the cap alone is not an option: Integer.parseInt throws for values of 0x80000000 and above, and its catch block only asserts (HTMLStripCharFilter.jflex:501-505): with assertions off codePoint stays 0 and the reference would become U+0000.
The Lucene.NET port carries the same matchLength <= 6 check (read, not run), so its users would see the same undecoded references.
Found by reading the hex branch of the scanner's grammar while building a fuzzer for HTMLStripCharFilter; the fuzzer's offset and chunking checks cannot see an undecoded reference. A public-API test then confirmed it on main and on releases back to 3.6.0.
The method in full129 words
Method: non-formal (code reading, then an executed test).
- Finder. The hunt unit for analysis char filters and stemmers was building a grammar fuzzer for
HTMLStripCharFilterwhose fragment list includesand. Reading the hex rule showed the check counts thex. The fuzzer's oracles (offset range and order, final offset, chunking independence) reported 0 violations over 2,000,000 documents, because an undecoded reference breaks none of them. - Confirmation. A public-API JUnit (3 six-digit cases fail, the five-digit and decimal controls pass) on main with assertions on and off and on 9.12.3, and a
main()probe on 9 releases back to 4.0.0. - Hunt. Independent reproduction, cross-model reviews, an adjudication, the version-history runs, a prior-art search, a security screen and a one-test minimal repro followed (see the checks below).
No prior report: 116 queries and reads on 2026-10-26 over GitHub (Lucene and downstream), the mailing lists, JIRA and the web, and a re-check on 2026-10-31. Upstream main still has the check, and no open PR touches the file.
Searches3 searches
Verdict new: in the recorded searches, no issue, PR, JIRA entry, list thread, commit or downstream report says that HTMLStripCharFilter leaves six-hex-digit references undecoded or that its check counts the x. Closest, none of them this bug: LUCENE-3690 / #4764 (introduced the check; its discussion covers only unpaired surrogates), LUCENE-5763 / #6825 (open, HTML5 named entities), SOLR-2819 and SOLR-882 (the removed pre-JFlex code), #15754 / #15756 and #13157 (attribute parsing; #13157, open since 2024, changes only TestHTMLStripCharFilter.java). The Lucene.NET port has the same check, unreported. Limits: GitHub's search rate limit was reached, and list search matches poorly on fragments such as &#x.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene; Elasticsearch, OpenSearch, Solr, Lucene.NET) | 2026-10-26 | a scripted prior-report search (18 issue/PR, 3 commit, 2 downstream queries), 10 direct searches, 13 item reads, the changed paths of all 411 open apache/lucene PRs | background only: #4764, #6825, #6796, #15754/#15756, #13157, #11556, #4986 |
| Mailing lists, JIRA and the web | 2026-10-26 | 24 list queries (dev@, java-user@, issues@, commits@), 25 JIRA queries and reads (LUCENE and SOLR), 8 web queries | SOLR-2819, SOLR-882, LUCENE-3690: other defects or the introducing change |
| Upstream source and open PRs | 2026-10-31 | the .jflex on upstream main (2f424fd428da), branch_11x and branch_10_6; open-PR and issue searches for HTMLStripCharFilter | the check is unchanged; no open PR touches HTMLStripCharFilter.jflex or HTMLStripCharFilter.java (open PR #13157 of 2024 changes only TestHTMLStripCharFilter.java, a test about the earlier fix #11724) |
Introduced by LUCENE-3690 (f3a363708ff, sarowe, 2012-01-22), the JFlex rewrite of HTMLStripCharFilter, first released in 3.6.0 via its branch_3x backport; the check has not changed since. Every release run from 3.6.0 to 10.6.0 fails; 3.5.0 has no such class.
Versions tested6 rows
Introduced by f3a363708ff "LUCENE-3690: Re-implemented HTMLStripCharFilter as a JFlex-generated scanner" (Steven Rowe, GitHub sarowe, trunk, 2012-01-22; a JIRA patch, no PR; the issue is now #4764) and its branch_3x backport d387ae60fcf (2012-01-24). The rule, the check and its comment were written together: git blame of HTMLStripCharFilter.jflex:494-499 gives f3a363708ff, and git log -L 494,527 lists only that commit and 059410d4248 (2012-01-23, the surrogate follow-up, which did not touch the check).
The line is in all 127 release tags that contain the .jflex, 3.6.0 through 10.6.0 (the 3.6.x contrib path included). 4.0.0-alpha and 4.0.0-beta contain it but were not run.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0 | affected | minimal repro fails (main with assertions on and off) |
| 10.0.0, 10.5.2, 9.0.0, 9.12.3, 8.11.4 | affected | 4 of 4 six-digit cases stay literal; 5 of 5 controls OK |
| 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3 | affected | the same |
| 3.6.0, 3.6.2 (first release: the branch_3x backport) | affected | the same |
| 3.5.0 | no class | no Lucene HTMLStripCharFilter (the repro does not compile); the Solr class it replaced decoded é |
main 645d4fe14a20 with the fix | not affected | repro passes; the whole analysis-common module passes |
An independent reproducer, an intended-behaviour devil's advocate and an adjudication each re-ran it and confirmed it; a cross-model works-as-designed review judged it real. The one dissent, a read-only refute review, said "not real" only because it could not run Java, and agreed on the root cause. This doc's gradle runs validated the fix.
Checks and verdicts309 words
Every verdict below re-ran a repro on stock main jars or release jars, except the reading-only cross-model reviews, for which separate runs re-ran the repro (fails 3 of 4).
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Public-API JUnit: 3 of 4 fail on main with assertions on and off and on 9.12.3; a main() probe fails on 9 releases back to 4.0.0; the fix sketch passes 43 upstream tests. |
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only; it had no executed repro of its own. It agreed on the root cause and the legal inputs and rated the intended argument weak. |
| Independent reproducer | real | Own 7-test JUnit with other inputs (􀀀, 􏿽, é): 3 of 7 fail on main with assertions on and off, 10.5.2 and 9.12.3; own main() fails on 8.11.4; with <= 7 all 7 pass. |
| Works-as-designed review (the cross-model review, OpenAI GPT-5.6) | real (medium) | Reading only; rated the intended argument moderate, outweighed by the comment, the decimal sibling and the upstream tests. |
| Intended-behaviour devil's advocate | real | No documented five-digit limit anywhere; the replaced filter read up to 10 hex digits; re-runs fail on main (assertions on and off) and 10.5.2. |
| Adjudication | confirmed (high), minor | Re-ran the independent reproduction's JUnit with a new seed: 3 of 7 fail with assertions on and off. |
| Minimal repro and main refresh | verified | The one-test class fails on 645d4fe14a20 with assertions on and off and passes with the fix; on main a9779ef3c193 all 4 recorded replays failed as before. |
| This doc | real; fix validated | Gradle in a scratch worktree: stock fails with assertions on and off; the fix passes the repro, 64 charfilter tests (2 seeds) and the whole analysis-common module; 10.6.0 fails. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 434 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,370 words
- Registry title
- HTMLStripCharFilter leaves hexadecimal character references with six hex digits (􏿽 􀀀 the zero-padded é) undecoded, because its length check counts the leading 'x' and so lets only five hex digits through
- Area
- analysis / HTMLStripCharFilter (JFlex grammar, numeric character references; also the 'htmlStrip' char filter SPI)
- Priority
- Low, rank 777: HTMLStripCharFilter leaves only six-hex-digit character references undecoded, and nothing throws while the index stays well formed.
- Impact class
- minor
- Impact note
- Applications that strip HTML with HTMLStripCharFilter (directly or through the 'htmlStrip' SPI factory), at its default settings and any index size: a hexadecimal character reference with exactly six hex digits, that is a plane-16 private-use code point (U+100000 to U+10FFFD) or a zero-padded smaller one such as é is passed through as literal text with its original offsets and indexed as a token such as 'x0000e9', so a word that contains it is not found by its decoded form; hex references of up to five digits and decimal references of up to seven digits are decoded, nothing throws, and the index stays well formed (CheckIndex clean).
- Summary
- You run HTML through HTMLStripCharFilter and expect every numeric character reference up to U+10FFFF to be decoded, as the scanner's own comment says ('10FFFF: max 6 hex chars') and as its decimal branch does for  and the zero-padded é. Instead a hex reference with six hex digits, such as 􏿽 􀀀 or é stays in the output as literal text: the length that is checked includes the leading 'x', so only five hex digits pass. Through StandardTokenizer, 'bad' is indexed as the tokens b, x000061 and d, and a TermQuery for 'bad' does not find the document.
- Introduced
- f3a363708ff95f28b5f29fe2cc27c1cd9fd0fca9 (trunk, svn r1234452; LUCENE-3690 / GitHub #4764 'JFlex-based HTMLStripCharFilter replacement', by sarowe; pre-GitHub, a JIRA patch, no PR) and its branch_3x backport d387ae60fcf7ecb65596b756a0f8fc79923d0370 (svn r1235308), which shipped in 3.6.0; the commit wrote the hex rule, the 'matchLength <= 6' check and its comment together [read: git blame of HTMLStripCharFilter.jflex:494-499 on main gives f3a363708ff; git log -L 494,527 (the whole hex branch) lists only f3a363708ff and 059410d4248 (2012-01-23, surrogate handling, length check untouched); git tag --contains d387ae60fcf gives 3.6.0, 3.6.1, 3.6.2; exec: 3.5.0 has no such Lucene class (compile error) and 3.6.0 fails] (2012-01-22 (trunk commit f3a363708ff); 2012-01-24 (branch_3x backport d387ae60fcf))
- First affected version
- 3.6.0 [exec] (via the branch_3x backport; 3.5.0, the last release before, has no Lucene HTMLStripCharFilter [exec: compile error]); on the 4.x line 4.0.0-alpha [read], first GA release 4.0.0 [exec]
- Affected versions
- every release from 3.6.0 to 10.5.2 (the last release before 10.6.0) and main ea57360912ed: 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main with -ea and -da [exec: the follow-up's public-API history probe, 4 of 4 six-digit cases literal and 5 of 5 controls OK on each]; main, 10.5.2 and 9.12.3 also [exec: the finder's, the independent reproduction's and the intended-behaviour check's JUnits], and 8.11.4 [exec: the independent reproduction's main()]; the buggy line is present at all 126 release tags that contain HTMLStripCharFilter.jflex [read]; 4.0.0-alpha and 4.0.0-beta were not executed (the harness takes x.y.z versions only) but contain the line [read]; not fixed upstream: apache/lucene main, branch_10x and branch_10_5 still have the check (read 2026-10-26; the last commit to the .jflex, 02014a6245d of 2026-03-03, does not touch it) and no open PR touches HTMLStripCharFilter.java or .jflex. Context: the replaced Solr class (org.apache.solr.analysis.HTMLStripCharFilter, Solr 3.5.0) decoded the zero-padded é [exec], so for zero-padded BMP references the 2012 rewrite was a regression; six-digit supplementary references were never decoded correctly by either implementation (the Solr class returned them from read() as one int above 0xFFFF)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (searched 2026-10-26, read-only; the prior-report record: 116 recorded queries and reads, namely the scripted prior-report search (18 GitHub issue/PR, 3 commit, 2 downstream-repo, 24 mailing-list over dev@, java-user@, issues@ and commits@, 9 JIRA and 6 web queries), 10 direct GitHub searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr and apache/lucenenet, 4 open-PR searches plus a scan of the changed paths of all 411 open apache/lucene PRs, 16 direct JIRA queries and reads over LUCENE and SOLR, 13 GitHub item reads, the upstream .jflex on main, branch_10x and branch_10_5, the local history and CHANGES.txt; the finder's, the independent reproduction's and the intended-behaviour check's own searches found nothing either). Not fixed upstream: the check is unchanged on main, branch_10x and branch_10_5, and no open PR touches HTMLStripCharFilter.java or .jflex. Nearest items, none a report of this bug: LUCENE-3690 / #4764 (introduced the scanner and the check; its 41 comments discuss only the unpaired-surrogate follow-up), LUCENE-5763 / #6825 (open: HTML5 named entities only), SOLR-2819 and SOLR-882 (the removed pre-JFlex implementation: isHex accepting G-Z, and hex-entity offset padding), #15754 / #15756 (an attribute value ending in '='; the last change to the .jflex), #13157 (open PR, a test for attribute values). The Lucene.NET port has the same check, unreported. Gaps: GitHub's search rate limit was reached, and the mailing-list full-text search matches poorly on fragments such as '&#x'
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the one-line fix (scanner regenerated by gradle) it passes, as do the 64 charfilter tests (seeds DEADBEEF and CAFEBABE) and the whole analysis-common test module (1,910 tests, seed DEADBEEF). Release 10.6.0 fails the same way; 12 releases from 3.6.0 to 10.5.2, run by the version-history runs, all fail.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:31 (at ea57360912ed) (class javadoc: 'attempts to strip out HTML constructs'), :493-526 (NUMERIC_CHARACTER hex rule '[xX] [0-9A-Fa-f]+': 'int matchLength = yylength();' includes the 'x'; 'if (matchLength <= 6) { // 10FFFF: max 6 hex chars'; the substring below skips the 'x' with zzStartRead + 1, matchLength - 1; then 'if (codePoint <= 0x10FFFF)'; else-branches pass the reference through as literal text), :528-560 (decimal rule '[0-9]+': 'if (matchLength <= 7) { // 0x10FFFF = 1114111: max 7 decimal chars', digits only)lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.java:6557 (at ea57360912ed) (generated copy of the hex check), :6327 (generated decimal check)lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilterFactory.java:42 (at ea57360912ed) (SPI NAME = "htmlStrip")lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java (at ea57360912ed) testEntities and testUTF16Surrogates (decimal and hex references of at most 4 hex digits are asserted to decode; no test uses 5 or 6 hex digits)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:351, :493-560a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.java:6327, :6557
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilterFactory.java:42 (NAME = "htmlStrip")
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:31, :494-531a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:115-119, :601-634
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:501-505, :509-511
- Prior reports
GitHub (read-only, 2026-10-31): apache/lucene contents of HTMLStripCharFilter.jflex at main, branch_11x, branch_10_6; commits?path= (last: 02014a6245d3, #15756); gh search prs/issuesGitHub (read-only, 2026-10-31): gh pr view 13157 (OPEN, 2024-03-05, 'Test case that exposes bug in PR #11724', one file: TestHTMLStripCharFilter.java +10); gh issue view 11724 ('LUCENE-10520 / #11556 HTMLStripCharFilter bugfix', merged)
- Diagrams
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:327, :351, :494-499, :522-526, :531
- TestHTMLStripHexCharRefSixDigits.java (one test class):
repro/LFV-289/src/org/apache/lucene/analysis/charfilter/TestHTMLStripHexCharRefSixDigits.java(34 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and a probe executed for the diagram on main, with assertions on and off and with the fix shadowed in: the two café documents through CustomAnalyzer (htmlStrip, standard, lowercase), their tokens (caf [3,6) and x0000e9 [8,15) for doc 1), count(body:café) 1 instead of 2, CheckIndex clean, and the five-, six- and seven-digit rows of the table. The affected range in the footnote also rests on the 10.6.0 runs of the minimal repro.
assets/LFV-289/bug.png(434 KB)