An IntervalQuery can carry a scoring curve set by its pivot (and exponent). Lucene drops "duplicate" clauses of a BooleanQuery by equals, and IntervalQuery.equals ignores the curve.
- An
IntervalQueryscores a document from its sloppy frequency S (1 for one occurrence of a single term) as S / (S + pivot), so pivot 1 (the default) gives 0.5 and pivot 100 gives 0.0099. The pivot, and optionally an exponent for a sigmoid curve, come from the public constructors(field, source, pivot)and(field, source, pivot, exp). - A
BooleanQuerywith SHOULD clauses scores a document by adding up the scores of the clauses that match it. - While rewriting,
BooleanQuerymerges clauses that areequalsinto one clause with a combined boost (2 for two copies), soa OR aruns one scorer instead of two. That is only right if equal queries score the same.
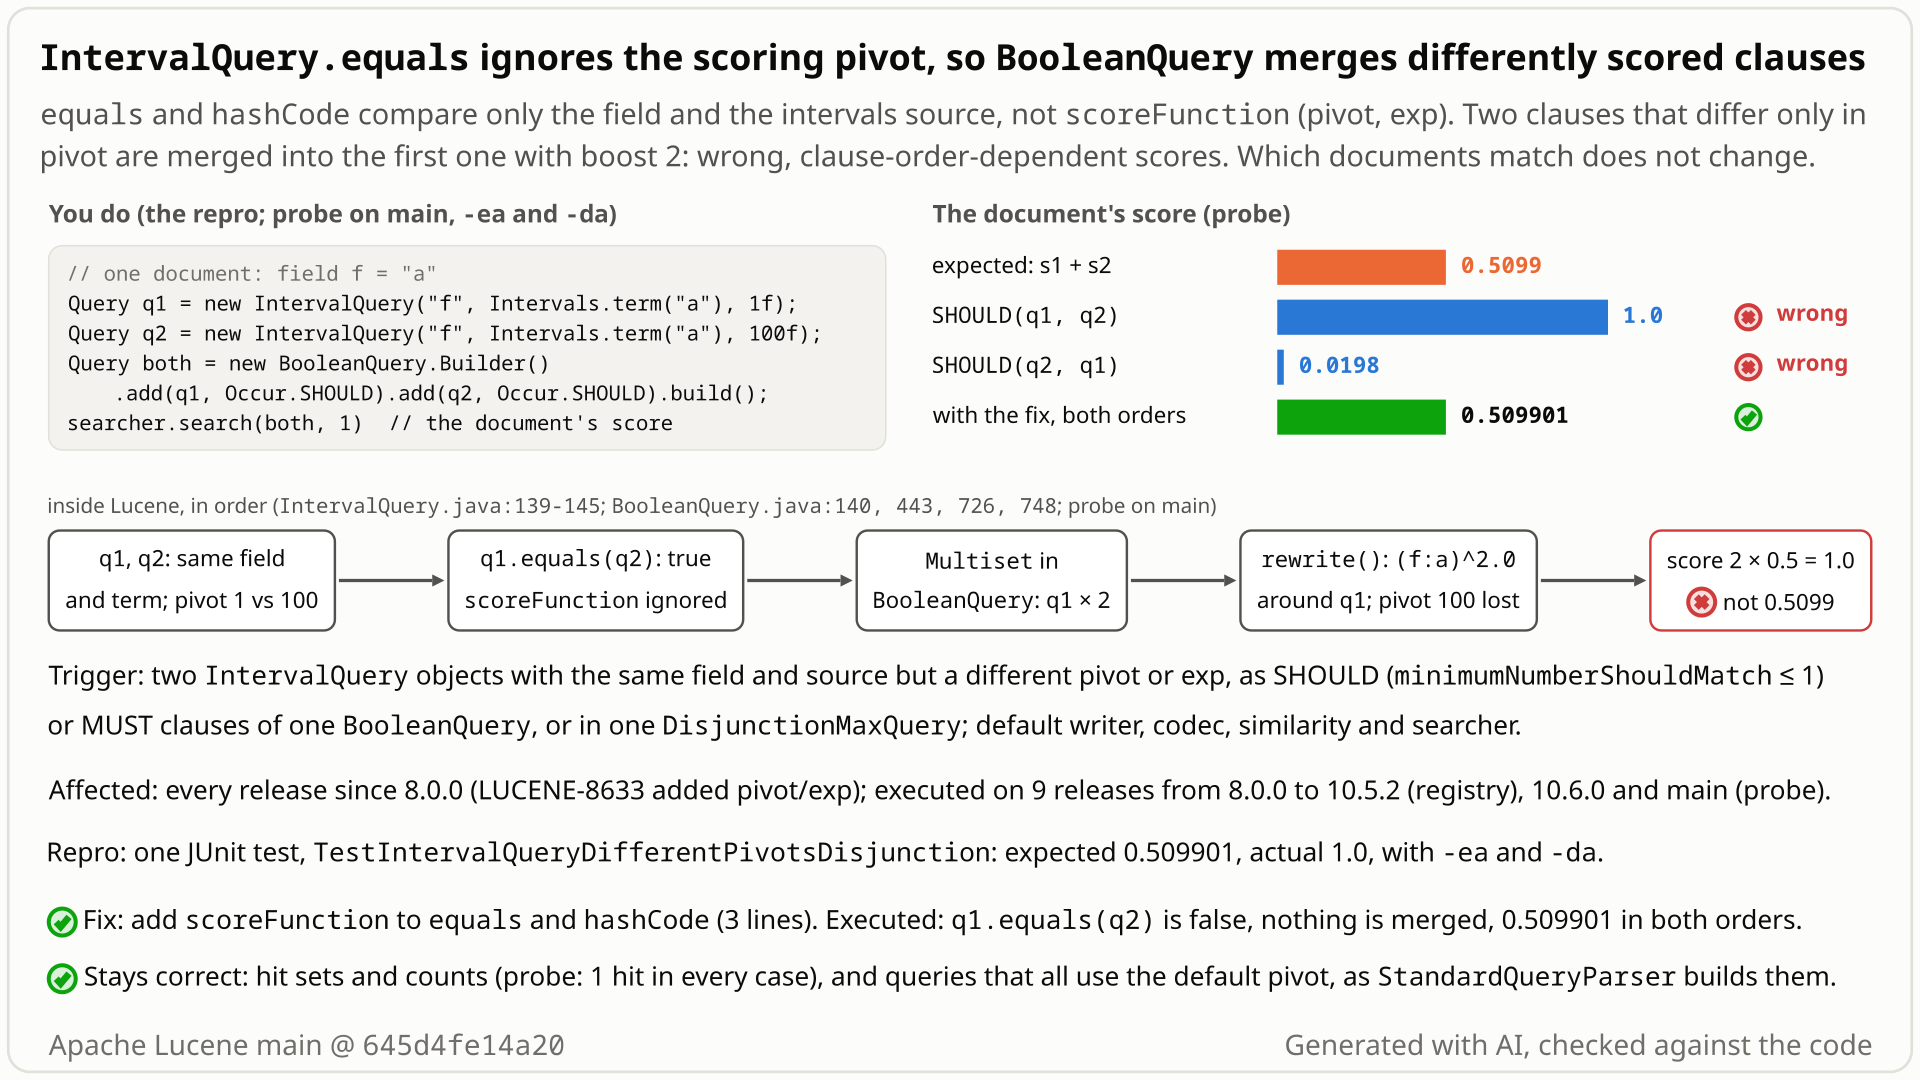
IntervalQuery clauses with pivots 1 and 100 compare equal, so BooleanQuery merges them into one clause with boost 2 and the first pivot, and the document scores 1.0 instead of 0.5 + 0.0099. Select the still to open it at full size. Generated with AI, checked against the code.- Index one document whose field
fis the single worda.new IntervalQuery("f", Intervals.term("a"), 1f)scores it 0.5 and the same query with pivot100fscores it 0.0099 (score = freq / (freq + pivot), freq 1). - Put the two queries as SHOULD clauses into one
BooleanQuery. You expect the sum of the clause scores: 0.5 + 0.0099 = 0.5099. - You get 1.0.
equalsandhashCodelook only at the field and the intervals source, so the two queries are equal, and the rewrite merges them into one clause(f:a)^2.0that keeps the first clause's pivot. - Swap the two clauses and the same document scores 0.0198 (twice the pivot-100 score). Two MUST clauses also give 1.0, and
DisjunctionMaxQuery(q2, q1)gives 0.0099 instead of the max, 0.5. Which documents match never changes; only scores do, and with another scoring clause in the query the ranking changes too.
Applications that build IntervalQuery with the pivot or pivot/exp constructors and combine two of them, same field and same source, differing only in pivot/exp, in one BooleanQuery (SHOULD or MUST) or DisjunctionMaxQuery. Default settings, any index size. Lucene's query parser and the Elasticsearch, OpenSearch and Solr builders use only the default curve.
Mechanism, terms and numbers702 words
IntervalQuery can carry its own scoring curve: the public constructors (field, source, pivot) and (field, source, pivot, exp) set a saturation or sigmoid function that scores every matching document. IntervalQuery.equals and hashCode compare only the field and the intervals source, so two queries that differ only in pivot or exp are equal and have the same hash code.
BooleanQuery merges equal SHOULD clauses (with minimumNumberShouldMatch at most 1) and equal MUST clauses into one clause with boost 2, keeping the clause that was added first, and DisjunctionMaxQuery builds both of its weights from the first of two equal disjuncts. The second clause's curve is lost: on a one-word document, SHOULD(pivot 1, pivot 100) scores 1.0 instead of 0.509901, and SHOULD(pivot 100, pivot 1) scores 0.0198. Hit sets, counts and exclusions stay correct, but matching documents are scored with the first clause's curve, so scores are wrong and ranking can change, with default settings.
The scoring state came with LUCENE-8633 (8.0.0, 2019), which did not update equals/hashCode. Affected: 8.0.0 to 10.6.0 and main. Only applications that set pivot/exp themselves are hit: Lucene's query parser and the Elasticsearch, OpenSearch and Solr interval builders use the default curve only. Adding the score function to equals and hashCode fixes it.
- The curve drives every score. The pivot constructor calls
IntervalScoreFunction.saturationFunction(pivot)and the pivot/exp constructorsigmoidFunction(pivot, exp)(IntervalQuery.java:83-85,:97-99); the two-argument constructor usessaturationFunction(1)(:71-73).scorerSupplierhandsscoreFunctiontoIntervalScorer(IntervalQuery.java:189-197), which scores every document with it (IntervalScorer.java:36-42,:50-53); the saturation score isweight * (1.0f - pivot / (pivot + freq))(IntervalScoreFunction.java:72).explainuses it too (IntervalQuery.java:158-168). - Equality ignores it.
equalsends inObjects.equals(field, that.field) && Objects.equals(intervalsSource, that.intervalsSource)andhashCodeisObjects.hash(field, intervalsSource)(IntervalQuery.java:134-146).IntervalScoreFunctionhas value-basedequals/hashCodeon pivot (IntervalScoreFunction.java:90-101) and on pivot and exponent (:149-160), but nothing calls them.toStringprints only field and source (IntervalQuery.java:116-119), so both queries printf:a. BooleanQuerymerges equal clauses and keeps the first. SHOULD and MUST clauses live inMultisets (BooleanQuery.java:133-135), aHashMapwhoseaddof an equal element only bumps the count (Multiset.java:33,:80-84), so the clause added first is the surviving key (for clauses without aBoostQuerywrapper).rewritede-duplicates SHOULD clauses whenminimumNumberShouldMatch <= 1(BooleanQuery.java:442-447) and MUST clauses (:450-455), and SHOULD clauses whoseminimumNumberShouldMatchequals their count become MUST first (:570-588);deduplicateClausesmerges them withboosts.merge(query, boost, Double::sum)(:726) and re-adds the survivor with boostcomputeQueryTermWeight(2)(:743-749), which is 2 for the defaultBM25Similarity. Result:(f:a)^2.0scored with the first clause's curve.DisjunctionMaxQuerydoes the same. Its disjuncts are aMultiset(DisjunctionMaxQuery.java:47) and it creates one weight per element (:115-117), so both weights come from the first disjunct; with tie-breaker 1 it rewrites to a SHOULDBooleanQuery(:273-279).
Adding scoreFunction to equals/hashCode, and nothing else, makes the repro and every shape below give the right value, so the equality is the cause.
| query | expected | actual |
|---|---|---|
q1.equals(q2) (pivot 1 vs pivot 100), equal hashCode | false | true, true |
| SHOULD(q1, q2) | 0.509901 | 1.0 (2 x q1) |
| SHOULD(q2, q1) | 0.509901 | 0.019801974 (2 x q2) |
| MUST(q1, q2) | 0.509901 | 1.0 |
DisjunctionMaxQuery([q2, q1], 0) | 0.5 (the max) | 0.009900987 |
DisjunctionMaxQuery([q1, q2], 0) gives 0.5, right only because q1 is the larger. The exponent constructor is hit the same way: on the document a b a, SHOULD(exp 1, exp 3) at pivot 4 scores 0.6666667 instead of 0.44444445. On a 4,000-document index with 100 colliding pairs, 218,304 of 221,120 matching-document scores differed from s1 + s2 for SHOULD(q1, q2), and the same count for MUST(q1, q2) (main ea57360912ed). Ranking changes once the query has another scoring clause: on the documents A = a b and B = a a a a a a a a a, SHOULD(q1, q2, an IntervalQuery on b) ranks B (1.8) above A (1.5) on stock main, and A (1.009901) above B (0.9825688) with the fix.
Exposure and likelihood262 words
- Silent wrong scores, which can change ranking. Matching documents are scored with the first clause's curve (with two different pivots, every matching document gets a wrong score; sigmoid curves can agree at some frequencies), the result depends on clause order, and ranking changes once another scoring clause is present. No exception, no warning. Which documents match,
count, MUST_NOT exclusions, deleted-document filtering and query-cache entries stay correct, because matching never reads the curve: the follow-up's probe ran 6,431,144 such checks with 0 failures on main, 10.5.2 and 9.12.3. - Default settings, any size. One document, the default
IndexWriterConfig, codec and similarity, a plainIndexSearcher. The test fails the same way with two seeds; the only randomized input, the class-level codec, does not affect interval scores. - Who is exposed. Applications that call the pivot or pivot/exp constructors themselves and put two such queries, on the same field and an equal source and differing only in pivot/exp, into one
BooleanQuery(SHOULD withminimumNumberShouldMatchat most 1 or equal to the SHOULD count, or MUST) or oneDisjunctionMaxQuery; for example a proximity boost tuned at two pivots. Lucene has no production caller of these constructors, the flexibleStandardQueryParserbuildsnew IntervalQuery(field, source)(IntervalQueryNode.java:44), and a read-only code read found that Elasticsearch, OpenSearch and Solr also use only the two-argument constructor. - Likelihood: rare. No public report of it was found in the searched sources since 8.0.0. The package "contains experimental classes" (
package-info.java:21). The open issue #16820 proposes interval queries as the replacement for span queries, so their use may grow.
One JUnit test in lucene/queries, public API only: one document with the word a, the default IndexWriterConfig, a plain IndexSearcher, two IntervalQuery objects with pivots 1 and 100, and one SHOULD BooleanQuery of both. Deterministic; it fails with assertions on and off.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queries.intervals;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.BooleanClause.Occur;
import org.apache.lucene.search.BooleanQuery;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestIntervalQueryDifferentPivotsDisjunction extends LuceneTestCase {

  public void testShouldClausesWithDifferentPivotsScoreAsSum() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new TextField("f", "a", Field.Store.NO));
      w.addDocument(doc);
      try (DirectoryReader reader = DirectoryReader.open(w)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query q1 = new IntervalQuery("f", Intervals.term("a"), 1f);
        Query q2 = new IntervalQuery("f", Intervals.term("a"), 100f);
        float s1 = searcher.search(q1, 1).scoreDocs[0].score;
        float s2 = searcher.search(q2, 1).scoreDocs[0].score;
        Query both = new BooleanQuery.Builder().add(q1, Occur.SHOULD).add(q2, Occur.SHOULD).build();
        float actual = searcher.search(both, 1).scoreDocs[0].score;
        // expected s1 + s2 (0.5 + 0.0099); actual 2 * s1 = 1.0, because q2 equals q1 and is merged
        assertEquals("score of SHOULD(pivot 1, pivot 100)", s1 + s2, actual, 1e-6f);
      }
    }
  }
}
cd $LUCENE   # an apache/lucene checkout at 645d4fe14a20 (or a later commit where IntervalQuery.java is unchanged)
cp $REPRO/TestIntervalQueryDifferentPivotsDisjunction.java lucene/queries/src/test/org/apache/lucene/queries/intervals/
./gradlew :lucene:queries:test --tests org.apache.lucene.queries.intervals.TestIntervalQueryDifferentPivotsDisjunction -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false
- Expected
- 0.509901, the sum of the two clause scores (0.5 + 0.0099).
- Observed
score of SHOULD(pivot 1, pivot 100) expected:<0.509901> but was:<1.0>on main, 10.6.0, 10.5.2, 9.12.3 and 9.1.0, with assertions on and off.
More files, environment, full output176 words
The test computes the two clause scores alone (0.5 and 0.0099) and asserts that the disjunction scores their sum. It uses ByteBuffersDirectory and new IndexWriterConfig(); Lucene's default similarity is a fixed BM25Similarity, and the test framework's class-level codec does not affect interval scores, so seeds DEADBEEF and 5EED1234 (5 iterations) fail the same way. The clause-order swap, MUST and DisjunctionMaxQuery shapes come from a separate probe and are not asserted, to keep one assertion.
The same file compiles and fails unchanged on the 9.1.0, 9.12.3, 10.5.2 and 10.6.0 jars; with only the LuceneTestCase import changed it fails the same way on 9.0.0 and 8.11.4, and with the package and import changed on 8.0.0; other 8.x releases were run only with the finder's test.
| lucene | main 645d4fe14a20: affected; also the 10.6.0, 10.5.2, 9.12.3 and 9.1.0 release jars with this test |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
TestIntervalQueryDifferentPivotsDisjunction > testShouldClausesWithDifferentPivotsScoreAsSum FAILED
    java.lang.AssertionError: score of SHOULD(pivot 1, pivot 100) expected:<0.509901> but was:<1.0>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:BC87C526B623306E]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
        at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:577)
at org.apache.lucene.queries.intervals.TestIntervalQueryDifferentPivotsDisjunction.testShouldClausesWithDifferentPivotsScoreAsSum(TestIntervalQueryDifferentPivotsDisjunction.java:50)- Pivot and exp are documented to change the score, and
BooleanQuerymerges equal clauses "into a single clause with a combined boost", which assumes equal queries score the same. - Clause order changes the score: 1.0 for (pivot 1, pivot 100), 0.0198 swapped.
- The curve's own value-based
equals(LUCENE-8633) is never called; core'sFeatureQuerycompares its scoring function.
The full argument250 words
- The curve is documented as changing the score. "The scores can be adjusted with two optional parameters", the pivot being "the sloppy frequency value at which the overall score of the document will equal 0.5" (
IntervalQuery.java:41-51; constructors:75-99). BooleanQuerytreats equal queries as score-interchangeable.deduplicateClausesmerges "repeated queries into a single clause with a combined boost" (BooleanQuery.java:706-713; LUCENE-7925, "Collapse duplicate SHOULD or MUST clauses by summing up their boosts").- Clause order changes the score of the same document: 1.0 vs 0.0198.
- History.
equals/hashCodewere written in LUCENE-8196 (2018), when field and source were the only state. LUCENE-8633 (#9679, 2019) addedscoreFunction, the pivot/exp constructors andIntervalScoreFunctionwith value-basedequals/hashCode, and did not touchIntervalQuery.equals. Its issue expects the scores to be "useful for things like proximity boosting on boolean queries"; equality was never discussed. Calling it an oversight is an inference; nobody said so. - Core precedent.
FeatureQuerycompares its function (FeatureQuery.java:63-71), andFeatureField'sSaturationFunctionandSigmoidFunction, whichIntervalScoreFunctionmirrors, compare pivot and exponent (FeatureField.java:417-431,:503-509); twoFeatureFieldsaturation queries with pivots 1 and 100 are unequal and their disjunction sums correctly (executed). LUCENE-7808 (PayloadScoreQuery, SpanPayloadCheckQuery), LUCENE-10026 (CombinedFieldQuery: "ensures query rewrites don't drop CombinedFieldQuery clauses") and GITHUB#12260 (SynonymQuery) fixed the same kind of omission as bugs. - Tests do not cover it.
TestIntervalQuery.testEqualityuses only the two-argument constructor (:475-493);testScoringuses the pivot constructors only in separate searches (:407-454).
The devil's-advocate check229 words
The strongest case for "intended": Query#equals "is required so that QueryCache works properly", and "Typically a query will be equal to another only if it's an instance of the same class and its document-filtering properties are identical" (Query.java:95-105). Queries that differ only in pivot filter the same documents, so the current equals meets the literal text, and the query cache stores match sets, which stay correct; that cache rationale is a real argument, if not a sufficient one. The package is experimental; IntervalQuery itself builds default-scored copies new IntervalQuery(field, source) in MatchesIterator#getQuery (MatchesIterator.java:94, overridden in an anonymous FilterMatchesIterator in IntervalWeight.matches, IntervalQuery.java:179-183) and in the sources' visit(); and the query shape is unusual.
Why it fails: that sentence is a necessary condition for caching, not permission for a scoring rewrite to change scores, and BooleanQuery, a core consumer of equals, reads equality as "scores the same". No wording makes a disjunction's score depend on clause order. "Experimental" disclaims API stability, not correctness (LUCENE-10026's class was in the sandbox and was still fixed). Nothing compares the default-scored copies with user queries. Verdict: not intended, a defect (the independent reproduction, the cross-model review and the intended-behaviour check returned real; the adjudication confirmed it with high confidence). The defect is wrong, order-dependent scores from duplicate-clause merging, not a breach of a documented equals contract.
Recommended A: include scoreFunction in equals/hashCode
Add scoreFunction to equals and hashCode (a 3-line change, +3/-2, in IntervalQuery.java); IntervalScoreFunction already compares pivot and exponent by value. The repro passes, and so does the whole lucene/queries suite (513 tests, 5 skipped, 0 failures) and the queryparser and highlighter suites that use IntervalQuery. Trade-off: default-scored copies from MatchesIterator#getQuery and visit() no longer equal a custom-pivot query.
  @Override
  public boolean equals(Object o) {
    if (this == o) return true;
    if (o == null || getClass() != o.getClass()) return false;
    IntervalQuery that = (IntervalQuery) o;
    return Objects.equals(field, that.field)
        && Objects.equals(intervalsSource, that.intervalsSource)
        && Objects.equals(scoreFunction, that.scoreFunction);
  }

  @Override
  public int hashCode() {
    return Objects.hash(field, intervalsSource, scoreFunction);
  }
All options and trade-offs3 options · 556 words
One fix was built and validated through gradle on 645d4fe14a20. It needs no API change, and equals/hashCode are identical in 10.6.0, so the same change applies to the 10.x line.
A 3-line change (+3/-2) in IntervalQuery.java. IntervalScoreFunction's SaturationFunction and SigmoidFunction already implement value-based equals/hashCode on pivot and exponent, so two queries built with the same pivot stay equal, and default queries (always saturationFunction(1)) stay equal to each other.
  @Override
  public boolean equals(Object o) {
    if (this == o) return true;
    if (o == null || getClass() != o.getClass()) return false;
    IntervalQuery that = (IntervalQuery) o;
    return Objects.equals(field, that.field)
        && Objects.equals(intervalsSource, that.intervalsSource)
        && Objects.equals(scoreFunction, that.scoreFunction);
  }

  @Override
  public int hashCode() {
    return Objects.hash(field, intervalsSource, scoreFunction);
  }
Trade-offs
- The default-scored copies that
IntervalQuerybuilds inMatchesIterator#getQuery(the anonymousFilterMatchesIteratorinIntervalWeight.matches,IntervalQuery.java:179-183) and in the sources'visit()(for exampleTermIntervalsSource.java:258) no longer equal a user query with a custom pivot. No in-tree code compares them; the highlighter suites pass. - Queries that differ only in pivot/exp get separate query-cache entries (memory, not correctness), and a disjunction of them runs two scorers instead of one.
saturationFunction(p)andsigmoidFunction(p, 1)give the same curve but are different classes whoseequalschecksgetClass()(IntervalScoreFunction.java:90-96,:149-155), so with the fix the two queries compare unequal: safe (they are just not merged), but it can split cache entries more than needed.toStringstill prints only field and source, so the two clauses look the same when printed (cosmetic; see the add-on).
What the checks validated
- Gradle, scratch worktree of
645d4fe14a20, seed DEADBEEF: the repro fails on stock and passes with the fix, assertions on and off. org.apache.lucene.queries.intervals.*(including the repro): 118 tests, 0 failures.- The whole
:lucene:queries:test: 513 tests, 5 skipped, 0 failures. - The other in-tree users of
IntervalQuery:TestStandardQPEnhancements(queryparser, 23 tests) andTestMatchRegionRetriever,TestMatchHighlighter,TestUnifiedHighlighterTermIntervals(highlighter, 144 tests): 0 failures. checkGoogleJavaFormat,ecjLintMain,ecjLintTest,forbiddenApisMainandforbiddenApisTestof:lucene:queriespass with the fix and the repro test.- Every probe shape gives the right value in both clause orders; earlier, the same change made the finder's tests, the independent reproduction's five tests, the intended-behaviour check's controls and 101 upstream intervals tests pass on main
ea57360912ed.
Print a non-default pivot/exp in IntervalQuery.toString (IntervalQuery.java:116-119), so merged or rewritten queries are debuggable.
Trade-offs
Cosmetic and not needed for the fix; it changes printed query strings that applications or tests may compare.
Say in the javadoc that equal IntervalQuery objects may score differently.
Trade-offs
It would document clause-order-dependent scores for BooleanQuery and DisjunctionMaxQuery. Until a fix ships, keep two IntervalQuery objects that differ only in pivot/exp out of one BooleanQuery or DisjunctionMaxQuery; in a BooleanQuery, wrapping one in a BoostQuery does not help: deduplicateClauses unwraps boosts before merging (BooleanQuery.java:720-726), and the surviving curve then follows the Multiset's hash-map order, not clause order (SHOULD(new BoostQuery(q1, 2), q2) scores 0.029702961, 3 x q2's score, instead of 1.009901). In a DisjunctionMaxQuery a boost other than 1 keeps the disjuncts apart but doubles that disjunct's score, so it is no workaround either.
Elasticsearch, OpenSearch and Solr build IntervalQuery with the default score function only, so their interval queries are not affected; only application code that constructs these queries with a pivot or exp (possibly taken from caller input) can hit it.
A bytecode scan of every concrete Query class listed fields that its weight or rewrite reads but equals does not, and flagged IntervalQuery.scoreFunction. An exhaustive equality check over small queries then found equal IntervalQuery pairs that score documents differently. An AI tool reduced it to a public-API JUnit; no model checker or solver was involved.
The method in full157 words
Method: semi-formal (a hunt unit, query object contracts).
- A bytecode scan of the stock main jars (JDK 25 ClassFile API) compared, for each of the 142 concrete
Queryclasses, the fields read bycreateWeight,rewriteand its nestedWeightclasses with the fields read byequals/hashCode. It reportedEQ-MISS IntervalQuery.scoreFunction, read byIntervalWeight.explainandscorerSupplierbut not byequals. - A bounded-exhaustive equality-congruence harness then compared every ordered pair within 28 small query families (249 queries, 3,510 pairs) on a fixed index, and witnessed equal
IntervalQuerypairs with different per-document scores: pivot 1 vs pivot 10 vs pivot 1 with exp 2 (for example 0.6666666 vs 0.16666669 on the same document). - The finder, an AI tool, wrote a 2-test public-API JUnit; the one-test repro was cut from it on 2026-10-29. The finder tagged the find "formal"; the registry records it as semi-formal because no model checker, solver or proof produced the signal.
No prior report: 83 recorded searches over GitHub, the mailing lists, JIRA, downstream repositories and the web, plus the files of all 412 open PRs (2026-10-26), rechecked on 2026-10-31. Closest: #13715, where identical regexp interval queries compare unequal (the opposite direction, a different cause).
Searches4 searches
Verdict new: 21 hits read, none the same bug. Related, not reports of this bug: #9679 / LUCENE-8633 (the introducing change; equality never discussed), #13715 (open; identical Intervals.regexp queries unequal), #7315 / LUCENE-6253 (the same bug class in SpanPositionCheckQuery), and the fixed precedents LUCENE-7808, LUCENE-10026 and #12260. The sibling LFV-295 (payload-filtered interval sources) is a separate finding. Gaps: keyword search only; PR review comments are not indexed; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits | 2026-10-26 | the scripted prior-report search (16 issue/PR, 3 commit and 2 downstream-repository queries) and manual searches over apache/lucene, Elasticsearch, OpenSearch and Solr: IntervalQuery equals/hashCode/pivot/exponent, IntervalScoreFunction, SaturationFunction pivot, interval query pivot equals, IntervalQuery toString pivot | only related items (#9679, #13715, #15961, #13691) |
| Open PRs | 2026-10-26 | the changed files of all 412 open apache/lucene PRs | only #16 touches IntervalQuery.java (adds a getter); none changes equals/hashCode or IntervalScoreFunction |
| Lists, JIRA, web | 2026-10-26 | dev@, java-user@, issues@, commits@ (20 queries and subject scans), JIRA (4 queries; full reads of LUCENE-8633, LUCENE-9073, LUCENE-8856, LUCENE-9204), 6 web queries | no report |
| Recheck (GitHub) | 2026-10-31 | IntervalQuery equals pivot; IntervalQuery hashCode; IntervalQuery score; IntervalScoreFunction; interval query pivot; open IntervalQuery items; items since 2026-10-20 mentioning intervals; the upstream file history | no report; IntervalQuery.java's last commit is still #13440 (2024) |
Introduced in 8.0.0 by LUCENE-8633 (2019), which added the pivot/exp curve but left equals/hashCode comparing only field and source. Executed from 7.7.1 (no such API) to 10.6.0 and main; not fixed upstream.
Versions tested5 rows
Introduced by LUCENE-8633 "Remove term weighting from IntervalQuery scores" (Alan Woodward, reviewed by jimczi on the JIRA patch; now #9679), 2019-01-16: master a8266492416d, branch_8x 18c3986cc4bd (the commit in the 8.0.0 tag). equals/hashCode date from LUCENE-8196 (00eab54f9d6, 2018), when field and source were the only state. The merge that exposes it, LUCENE-7925 (2017; master ab793e7ab56, branch_7x 325263a9398, released in 7.1.0), is older. #15818 (main only) changed how the merged boost is computed; the numbers are the same on 10.5.2 and main. Module: sandbox in 8.0-8.1, queries from 8.2.0. Upstream main 2f424fd428da (2026-10-30): the file's last commit is still #13440 (2024-06-06).
| Version or commit | Verdict | Result |
|---|---|---|
| 7.7.1, 7.7.3 | no such API | the pivot/exp constructors do not exist (the test does not compile); IntervalQuery has no scoring state |
| 8.0.0, 8.1.1, 8.2.0, 8.11.4, 9.0.0 | first affected: 8.0.0 | the finder's JUnit (package/import variants) fails 2 of 2: SHOULD scores 1.5 instead of 0.7791262; this doc's test with an import change (9.0.0, 8.11.4) or a package and import change (8.0.0) fails (1.0 instead of 0.509901) |
| 9.1.0, 9.12.3, 10.0.0, 10.5.2 | affected | the finder's JUnit fails 2 of 2; this doc's test fails on 9.1.0, 9.12.3 and 10.5.2 (1.0 instead of 0.509901) |
| 10.6.0 | affected | this doc's test fails with assertions on and off (1.0 instead of 0.509901) |
| main 645d4fe14a20 | affected | this doc's test fails through gradle and the standalone runner, assertions on and off; passes with fix A |
An independent reproducer, an intended-behaviour review by another model family (OpenAI GPT-5.6) and a devil's advocate all returned real, and an adjudication confirmed it with high confidence. The repro and the independent reproducer's test still fail on main 645d4fe14a20.
Checks and verdicts369 words
Before the finding was recorded, a reading-only refute review by OpenAI GPT-5.6 agreed on the root cause; its "not real" was procedural, because it could not run Java.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | Bytecode scan plus equality-congruence harness; the 2-test JUnit fails 2 of 2 on main (assertions on and off), 10.5.2 and 9.12.3; the fix passes 2 of 2 and 101 upstream intervals tests. |
| Refute review (OpenAI GPT-5.6, reading only) | not real (low, procedural) | Root cause agrees, inputs in contract, intended argument weak; a separate run re-ran the repro and it failed 2 of 2. |
| Independent reproducer | real | Own 5-test JUnit, written from the claim only, fails 4 of 5 on main (assertions on and off), 10.5.2, 9.12.3 and 8.11.4: clause order, MUST, exp and equality; its control passes; 5 of 5 pass with the fix. Re-run on 645d4fe14a20: same numbers. |
| Intended-behaviour review (OpenAI GPT-5.6) | real (medium) | Intended argument moderate (Query#equals wording, experimental package), rejected because BooleanQuery uses equality as score interchangeability; a separate re-run fails, the fix passes. |
| Devil's advocate | real (high) | Built the strongest intended case and rejected it; controls: FeatureField pivots compare unequal and sum correctly, MUST and DisjunctionMaxQuery (tie-breaker 1) are also wrong, swapped clauses differ. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit (5 run, 4 failed, assertions on and off; control passes) and with the fix (5 of 5 pass). |
| Repro minimization and this doc's runs | verified; still reproduces | The one-test repro fails on 645d4fe14a20 (seeds DEADBEEF and 5EED1234) and on 10.6.0, 10.5.2, 9.12.3 and 9.1.0, and passes with the fix through gradle. |
| Fact check of this doc | facts hold after corrections | Re-ran the repro on main (assertions on and off, and the gradle command) and on 10.6.0, 10.5.2, 9.12.3 and 9.1.0 with assertions off; the import/package variants on 9.0.0, 8.11.4 and 8.0.0; the fix shadowed in; and its own probes of every shape above, minimumNumberShouldMatch 2, a boosted duplicate and a ranking flip with a third clause. A second, reading-only fact check by OpenAI GPT-5.6 found no error that changes a conclusion. The wording errors both found are corrected here. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 473 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,502 words
- Registry title
- IntervalQuery equals/hashCode ignore the score function (pivot/exp), so BooleanQuery merges two differently scored IntervalQuery clauses into one and returns wrong, clause-order-dependent scores
- Area
- queries / intervals (IntervalQuery equality, consumed by BooleanQuery and DisjunctionMaxQuery duplicate-clause handling)
- Priority
- Low, rank 851: IntervalQuery equality ignores pivot and exp, so BooleanQuery merges differently scored clauses and scores silently change, but only for hand-built pairs that differ in pivot or exp and never for hit sets, so it follows LFV-295.
- Impact class
- silent wrong results
- Impact note
- Applications that build IntervalQuery objects with the public pivot or pivot/exp constructors and put two of them with the same field and an equal IntervalsSource but a different pivot/exp into one BooleanQuery (SHOULD with minimumNumberShouldMatch <= 1, or MUST) or one DisjunctionMaxQuery get wrong scores, and so a wrong ranking, for every matching document, with default writer, codec, similarity and searcher, under -ea and -da, in every release since 8.0.0; the hit set and counts do not change, and queries from Lucene's StandardQueryParser or from the Elasticsearch, OpenSearch and Solr intervals builders cannot trigger it, because they only use the default score function.
- Summary
- You build two IntervalQuery objects on the same field and term that differ only in their scoring pivot, new IntervalQuery("f", Intervals.term("a"), 1f) and the same with 100f, and combine them as SHOULD clauses of a BooleanQuery. You expect the document 'a b a c a' to score the sum of the two clause scores, 0.75 + 0.0291 = 0.7791, because the javadoc documents pivot and exp as parameters that change the score. Instead IntervalQuery.equals/hashCode compare only the field and the intervals source, so the two queries are equal, BooleanQuery.rewrite merges them into the single clause (f:a)^2.0 that keeps only the first clause's pivot, and the document scores 1.5; with the clauses swapped it scores 2 x 0.0291 = 0.0583, so the score also depends on clause order.
- Introduced
- a8266492416dbc2fcf665983d1cac141e50fa9eb on master and its branch_8x twin 18c3986cc4bdb38949fae14bd771621345d41776 (the commit in the 8.0.0 release tag), 'LUCENE-8633: Remove term weighting from IntervalQuery scores' (romseygeek; JIRA patch on LUCENE-8633, now apache/lucene#9679, reviewed by jimczi; no PR): it added the scoreFunction field, the public (field, source, pivot) and (field, source, pivot, exp) constructors and IntervalScoreFunction with its own value-based equals/hashCode, but left IntervalQuery.equals/hashCode as written in LUCENE-8196 (00eab54f9d6, 2018-04-03), when field and intervalsSource were the only state [read: git log -L and git blame on IntervalQuery.equals/hashCode in the history clone; blame on main shows only 00eab54f9d6 and the 8ef6a0da568 reformat (LUCENE-9570)]. The merge that exposes it, BooleanQuery's duplicate-clause collapse (LUCENE-7925, ab793e7ab56, 7.1.0), is older. (2019-01-16)
- First affected version
- 8.0.0 [exec] (lucene-sandbox, package org.apache.lucene.search.intervals); 7.7.1 and 7.7.3 are not affected [exec: the repro does not compile because the pivot/exp constructors do not exist], so 7.x (IntervalQuery since 7.4.0) has no scoring state for equals to miss
- Affected versions
- every release from 8.0.0 through 10.6.0 and main ea57360912ed. [exec] the one-test repro fails on the 10.6.0 jars with -ea and -da (2026-10-31); the follow-up history sweep ran the finder's JUnit (package/import-only variants for 8.0-8.1 and 8.2-9.0) on SHA-1-verified release jars: 8.0.0, 8.1.1, 8.2.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main all fail 2 of 2 with identical numbers (-ea; main also -da); the independent reproduction's JUnit fails 4 of 5 on main (-ea, -da), 10.5.2, 9.12.3 and 8.11.4; the intended-behaviour check re-ran 10.5.2; the security probe ran on 9.12.3, 10.5.2 and main. [read] no commit since LUCENE-8633 changed the compared fields; equals/hashCode on main and branch_10x (fetched 2026-10-26) still omit scoreFunction. Module: lucene-sandbox 8.0-8.1, lucene-queries (org.apache.lucene.queries.intervals) from 8.2.0 (LUCENE-8856). Intermediate releases not listed were not executed. Not fixed upstream. All runs on aarch64 with JDK 25.0.3.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new, read-only: 51 logged scripted prior-report search queries (16 GitHub issue/PR, 3 commit, 2 downstream-repository, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA-archive, 6 web), 32 manual searches (GitHub issue/PR and code search on apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr; the file lists of all 412 open apache/lucene PRs; lists.apache.org subject scans; LUCENE and SOLR JIRA text queries; full JIRA reads of LUCENE-8633, LUCENE-9073, LUCENE-8856 and LUCENE-9204; git log -L in the full history clone), plus the finder's and the intended-behaviour check's earlier searches; 21 hits read, none the same bug): nobody reports or discusses IntervalQuery equality ignoring the score function, or BooleanQuery merging differently scored IntervalQuery clauses. Not fixed: upstream main HEAD equals the tested ea57360912ed, the last commit touching IntervalQuery.java on main is from 2024-06 (#13440), and no open PR changes IntervalQuery equals/hashCode or touches IntervalScoreFunction.java (the only open PR touching IntervalQuery.java, #16, adds a getter). Related, not reports of this bug: #9679 (LUCENE-8633, the introducing change; its discussion never mentions equality, and the issue expects the scores to be 'useful for things like proximity boosting on boolean queries'), #13715 (open: identical Intervals.regexp IntervalQuery objects compare unequal, the opposite direction with a different root cause in CompiledAutomaton), #7315 (LUCENE-6253, SpanPositionCheckQuery equals misses a field: same bug class, other class), and the fixed precedents LUCENE-7808 (PayloadScoreQuery and SpanPayloadCheckQuery equals), LUCENE-10026 (CombinedFieldQuery equals) and #12260 (SynonymQuery equals). Gaps: GitHub search is lexical and does not index PR review comments, mailing-list search covered subjects and the first 400 characters of bodies, and private reports to security@lucene.apache.org are not visible
- Lucene commit tested
- main
645d4fe14a20(commit of 2026-10-28): this doc's one-method test through gradle with assertions on and off (seed DEADBEEF) and on the standalone runner, plus a clause-order probe and the independent reproducer's test; the same test on the 10.6.0, 10.5.2, 9.12.3 and 9.1.0 release jars with assertions on and off (fails), and with only an import change on 9.0.0 and 8.11.4 and a package and import change on 8.0.0 (fails). The hunt's tests ran on mainea57360912edand on 8.0.0, 8.1.1, 8.2.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2 (fail) and 7.7.1 and 7.7.3 (API absent); the classes involved are unchanged betweenea57360912edand645d4fe14a20. The fix was run through gradle in a scratch worktree of645d4fe14a20on 2026-10-31. Upstream main2f424fd428da(2026-10-30) still has the same code.
- Finding record
lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:41-57 (class javadoc: pivot/exp scoring), :61-63 (fields field, intervalsSource, scoreFunction), :71-109 (constructors: the 2-arg one uses saturationFunction(1); public (field, source, pivot) and (field, source, pivot, exp)), :134-146 (equals compares field and intervalsSource only; hashCode = Objects.hash(field, intervalsSource)), :158-168 (explain uses scoreFunction), :182 (Matches#getQuery builds new IntervalQuery(field, source)), :189-197 (scorerSupplier passes scoreFunction to the scorer)lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalScoreFunction.java:26-41 (pivot and exp must be finite and > 0), :46-51 (abstract equals/hashCode), :90-101 (SaturationFunction equals/hashCode on pivot), :149-160 (SigmoidFunction equals/hashCode on pivot and exponent)lucene/queries/src/java/org/apache/lucene/queries/intervals/package-info.java:21 (experimental classes)lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:438-455 (rewrite deduplicates SHOULD clauses when minimumNumberShouldMatch <= 1 and MUST clauses), :706-752 (deduplicateClauses: HashMap.merge on Query equality keeps the first equal key and gives it a combined boost)lucene/core/src/java/org/apache/lucene/search/DisjunctionMaxQuery.java:46 (disjuncts kept in a Multiset), :112-118 (one sub-weight per Multiset element), :273-279 (tieBreaker 1 rewrites to a SHOULD BooleanQuery)lucene/core/src/java/org/apache/lucene/search/Query.java:95-105 (equals 'is required so that QueryCache works properly'; 'Typically' equal 'only if' the 'document-filtering properties are identical')lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/nodes/IntervalQueryNode.java:44 (the parser builds new IntervalQuery(field, source), default score function only)
- The finding in 30 seconds
lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:61-63, (at 645d4fe14a20) :71-73, :83-85, :97-99, :116-119, :134-146, :158-168, :189-197lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalScoreFunction.java:26-41, (at 645d4fe14a20) :47-51, :72, :90-101, :149-160lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalScorer.java:36-42, (at 645d4fe14a20) :50-53lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:133-135, (at 645d4fe14a20) :442-455, :706-758 (:726, :743-749)lucene/core/src/java/org/apache/lucene/search/Multiset.java:33, (at 645d4fe14a20) :80-84lucene/core/src/java/org/apache/lucene/search/similarities/BM25Similarity.java:121-136 (at 645d4fe14a20) (k3 disabled by default: linear query-term weight)lucene/core/src/java/org/apache/lucene/search/DisjunctionMaxQuery.java:47, (at 645d4fe14a20) :115-117, :273-279
- Who is affected
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:123 (at 645d4fe14a20) (default similarity is BM25Similarity)lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/nodes/IntervalQueryNode.java:44 (at 645d4fe14a20)lucene/queries/src/java/org/apache/lucene/queries/intervals/package-info.java:21 (at 645d4fe14a20)gh api repos/apache/lucene/issues/16820 (read-only, 2026-10-31: open, romseygeek, span queries 'superseded by IntervalQueries')
- Minimal repro
lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:123 (at 645d4fe14a20)
- Why it looks unintended
lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:41-51, (at 645d4fe14a20) :75-99, :182lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:706-713; (at 645d4fe14a20) lucene/CHANGES.txt:7916-7917 (LUCENE-7925)lucene/core/src/java/org/apache/lucene/search/Query.java:95-105 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/document/FeatureQuery.java:63-71; (at 645d4fe14a20) FeatureField.java:417-431, :503-509lucene/CHANGES.txt:8266-8267 (at 645d4fe14a20) (LUCENE-7808), :5310-5311 (LUCENE-10026), :3670 (GITHUB#12260)lucene/queries/src/test/org/apache/lucene/queries/intervals/TestIntervalQuery.java:407-454, (at 645d4fe14a20) :475-493lucene/core/src/java/org/apache/lucene/search/MatchesIterator.java:94 (at 645d4fe14a20) (getQuery); lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:179-183
- Suggested fix
lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:116-119, (at 645d4fe14a20) :182; lucene/queries/src/java/org/apache/lucene/queries/intervals/TermIntervalsSource.java:258 (at 645d4fe14a20)lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalScoreFunction.java:90-101, (at 645d4fe14a20) :149-160lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:720-726 (at 645d4fe14a20)a Lucene clone releases/lucene/10.6.0 lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:134-146 (same equals/hashCode)
- History
a Lucene clone releases/lucene/10.6.0 lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:134-146gh api repos/apache/lucene/commits?path=lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java (read-only, 2026-10-31)
- Diagrams
lucene/queries/src/java/org/apache/lucene/queries/intervals/IntervalQuery.java:134-146; (at 645d4fe14a20) lucene/core/src/java/org/apache/lucene/search/BooleanQuery.java:442-455, (at 645d4fe14a20) :714-758
- TestIntervalQueryDifferentPivotsDisjunction.java (1 test):
repro/LFV-292/src/org/apache/lucene/queries/intervals/TestIntervalQueryDifferentPivotsDisjunction.java(54 lines)
A picture of the one-document repro and the equality check that lets BooleanQuery merge the two clauses, made in parallel with this doc from the code at 645d4fe14a20; the PNG is the summary still.
assets/LFV-292/bug.png(473 KB)