Intervals.before(source, reference) keeps the source intervals that end before some reference interval starts. It is built from a package-private helper that puts a one-position marker just before each reference interval, then stretches the marker back to position 0 and keeps the source intervals that fit inside.
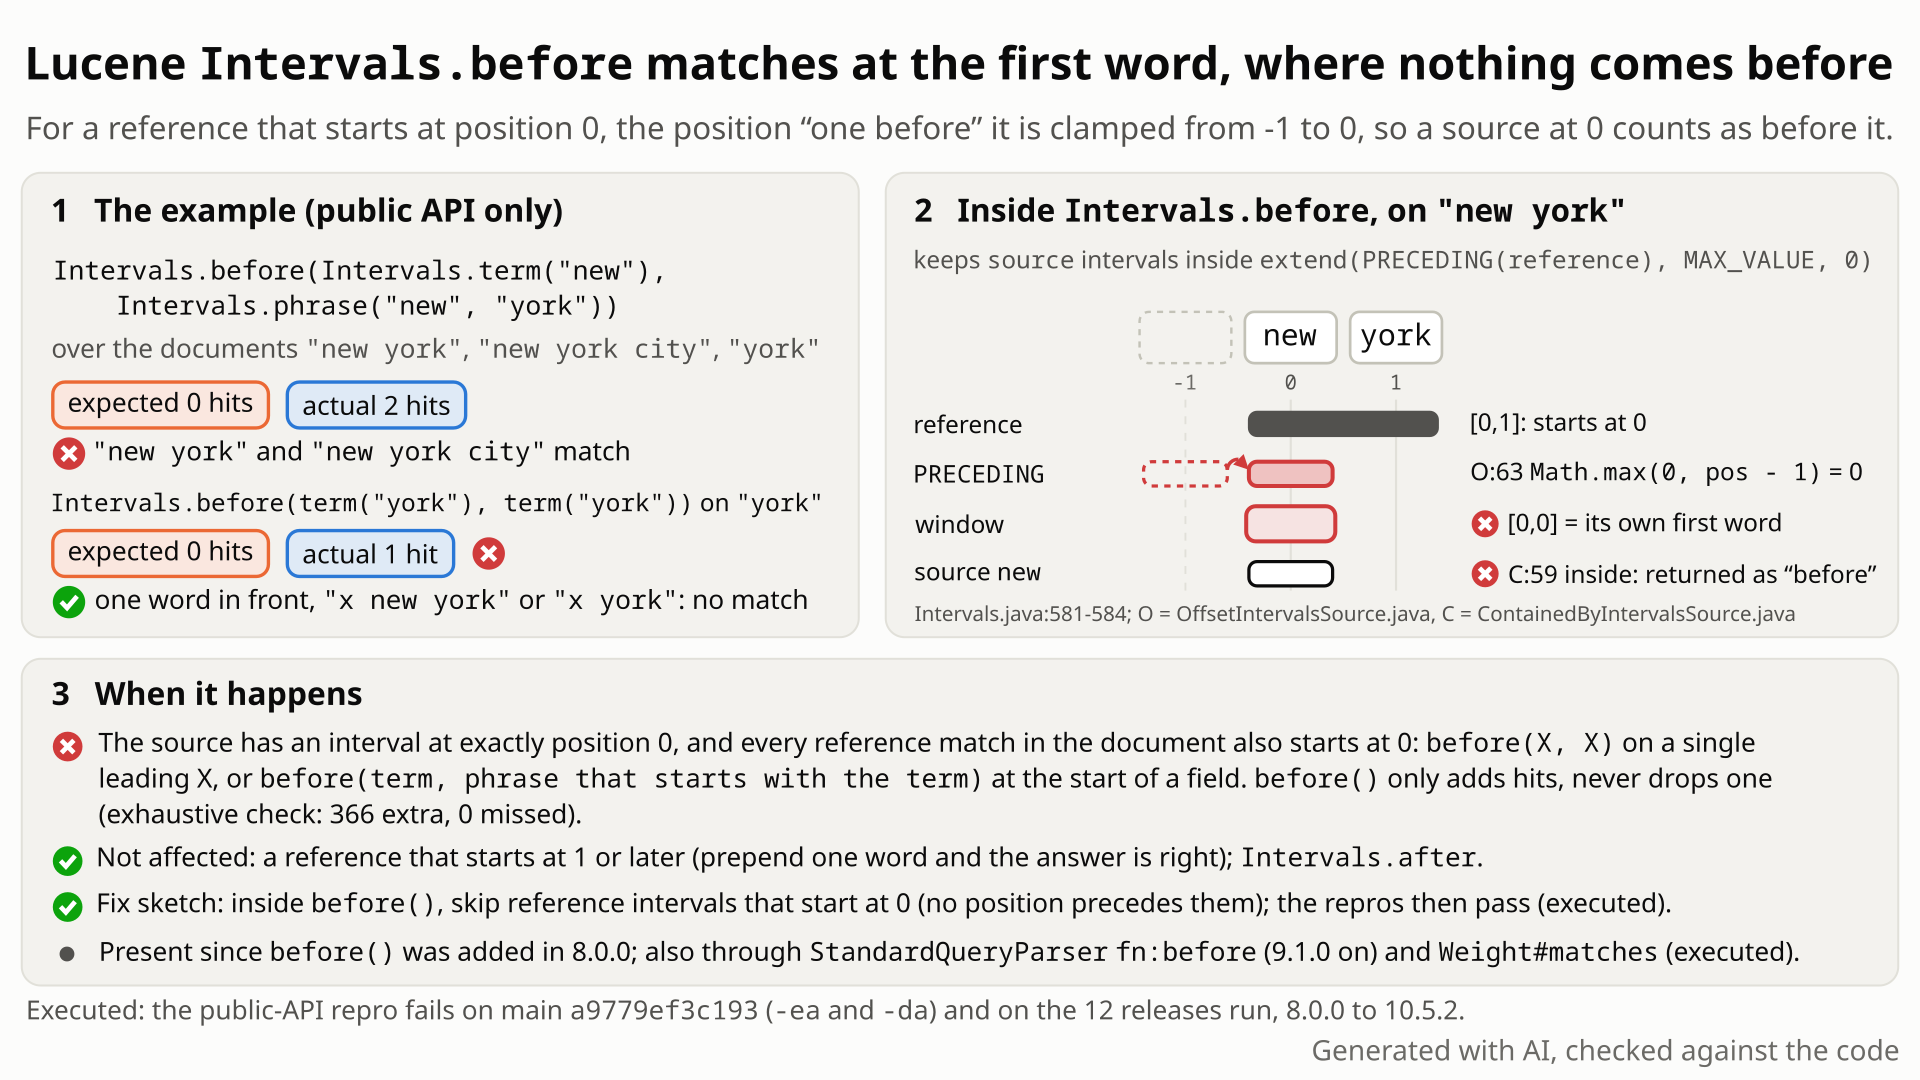
new york, the phrase new york starts at position 0; the position one before it is clamped from -1 to 0, so the "before" window is the phrase's own first word and the source new fits inside it. Select the still to open it at full size. Generated with AI, checked against the code.- Index three documents,
york,x yorkandyork york, with default settings, and search anIntervalQueryoverIntervals.before(term york, term york). - You expect 1 hit,
york york: before() "returns intervals from the source that appear before intervals from the reference", and only there does oneyorkcome before another. - Instead you get 2 hits: the lone
yorkmatches too.x york, the same text moved one position right, correctly does not match, andordered(york, york)andafter(york, york)give the expected 1 hit. - Why: before() keeps a source that fits in the window
[0, p-1]before each reference start p. For p = 0 no such position exists, but the code computesMath.max(0, p - 1)= 0, so the window is[0, 0]and a source on the first token fits. - The same with
before(new, phrase(new york)): 3 of 4 documents match instead of 1 (new yorkandnew york cityare extra).before()only adds hits, never drops one, from 8.0.0 to 10.5.2 and on main.
Users of Intervals.before or of fn:before in the flexible StandardQueryParser, with default settings, in every release since 8.0.0. Only documents where the source is at position 0 and every reference match starts there: before(X, X), or a reference phrase or synonym that begins with the source term. before() only adds hits; under a negation they hide documents instead.
Mechanism, terms and numbers871 words
Intervals.before(source, reference) "Returns intervals from the source that appear before intervals from the reference"; fn:before in the flexible StandardQueryParser calls it and is documented the same way. It is built as containedBy(source, extend(PRECEDING(reference), Integer.MAX_VALUE, 0)), where PRECEDING is a package-private helper that places a one-position pseudo-interval just before each reference interval, at Math.max(0, pos - 1). For a reference starting at p > 0 the window is [0, p-1], strictly before. For p = 0 there is no position before it, but the clamp gives the window [0, 0], so a source exactly on the first token counts as before a reference that starts on the same token. before(york, york) therefore matches the one-word document york, and before(new, phrase(new york)) matches new york and new york city; moved one position right (x york, x new york), the same texts correctly do not match, and ordered() and after() give the expected answers. before() itself only gains hits, never loses one (under a negating outer query, such as a MUST_NOT clause, the extra interval can hide a document instead); Weight#matches reports the extra [0, 0] interval too, which is what Matches-based highlighting reads. No special settings are needed (StandardAnalyzer or the test framework's whitespace analyzer, the default IndexWriterConfig, a plain or the test framework's randomized searcher; several random test codecs gave the same result). The code dates from LUCENE-8629, which added before(), so every release from 8.0.0 to 10.5.2 and main is affected (12 releases run). Skipping reference intervals that start at position 0 fixes it; two variants were validated with the repro and the whole lucene/queries module.
- Intervals:
org.apache.lucene.queries.intervalsmatches positions inside a field. An interval is a range of token positions[start, end]; the first token of a field is position 0.IntervalQuery(field, source)matches a document when the source has at least one interval in it. The package is marked "experimental classes" (package-info.java:21). - before():
Intervals.before(source, reference)"Returns intervals from the source that appear before intervals from the reference" (Intervals.java:580).fn:before(source reference)in the flexibleStandardQueryParser(since 9.1.0) calls it (intervalfn/Before.java:37) and says "Matches intervals from the source that appear before intervals from the reference" (intervalfn/package-info.java:425). - How it is built (
Intervals.java:581-584):containedBy(source, extend(PRECEDING(reference), Integer.MAX_VALUE, 0)).containedBy"Returns intervals from the small query that appear within intervals of the big query" (:554). PRECEDING is the package-privateOffsetIntervalsSourcewithbefore = true: "a pseudo-interval that appears ... one position before ... each interval from the reference" (OffsetIntervalsSource.java:28-31).
- The marker. For a reference interval starting at
pos, PRECEDING returnsstart()=end()=Math.max(0, pos - 1)(OffsetIntervalsSource.java:51-65, the clamp at:63;end()at:94-97). The Matches path (highlighting) wraps the same iterator (:143). - The window.
extend(marker, Integer.MAX_VALUE, 0)stretches it back to position 0 (ExtendedIntervalIterator.java:61):[0, pos-1]forpos > 0, which is exactly "strictly before". - The boundary. For
pos = 0,Math.max(0, -1)is 0, so the window is[0, 0]instead of absent.containedBykeeps a source intervalawhen a windowbhasb.start <= a.startandb.end >= a.end(ContainedByIntervalsSource.java:52-61), so a source at[0, 0]passes. - Why the clamp is there (presumably). A positioned iterator must not return -1 (it means "not positioned yet",
IntervalIterator.java:46-52); the history gives no reason. But an iterator may skip such a reference: "it is possible for a document to return NO_MORE_INTERVALS on the first call to nextInterval()" (IntervalIterator.java:35-36).
Both must hold: the source has a one-position interval exactly at [0, 0] (a wider source starting at 0, such as a phrase, does not fit in [0, 0]), and the reference has at least one interval in the document and every one of them starts at 0 (any later reference makes [0, 0] legitimately before it). Position 0 is absolute: normally the field's first token, but a first token behind a removed leading stopword sits at position 1 (FilteringTokenFilter.java:50-58), and a token in a later value of a multi-valued field normally sits after 0; neither triggers it. Typical shapes: before(X, X) with one leading X; before(term, phrase or disjunction that starts with that term) at the start of a field; synonyms stacked on the first token, also with two distinct terms (before(a, b) with a and b stacked at position 0 matches; the same stack one position later does not); and a reference that starts at 0 without sharing a token with the source, such as extend(b, 1, 0) on a b (seen in the finder's harness). An exhaustive check over all 363 documents of 1-5 tokens over {a, b, c} and 36 before() queries (13,068 checks) found 366 extra matches, every one with the source and the earliest reference at position 0, and 0 missed.
Intervals.after is not affected: for a positioned reference interval, FOLLOWING saturates only when end + 1 reaches Integer.MAX_VALUE (OffsetIntervalsSource.java:66-83), above the highest position IndexWriter accepts; its other branches only pass the "not positioned" and "exhausted" sentinels through.
Exposure and likelihood292 words
- Who is exposed. Users of
Intervals.before, directly or nested in other interval functions, throughIntervalQuery; and offn:beforein the flexibleStandardQueryParser(since 9.1.0). The API is public inlucene-queriessince 8.2.0 (lucene-sandbox in 8.0.0 and 8.1.x). Downstream engines expose it too: Elasticsearch's intervals query maps itsbeforefilter toIntervals.before(read in its source, not run). - When it shows. A query whose source can match position 0 (normally the field's first token), on a document whose reference matches all start there:
before(X, X);before(term, phrase that starts with it); synonyms stacked on the first token, also two distinct stacked terms (before(a, b)withaandbboth at position 0); a reference that starts at 0 for another reason, such asextend(b, 1, 0)ona b.before(a, b)with two distinct single terms, no stacked synonyms and no extension never triggers it. - Silent. No exception. Extra hits in
IntervalQuery, an extra[0, 0]interval from the iterator and fromWeight#matches(itsMatchesIteratorreports[0, 0], so a Matches-based highlighter would mark it; no highlighter was run), and an extra interval fed into any enclosing interval operator. Under a negating outer query (aMUST_NOTclause; by the same logic the negating interval operators) the extra interval removes a hit instead. - No special setup.
StandardAnalyzeror a whitespace analyzer, the defaultIndexWriterConfig, a plainIndexSearcheror the test framework's randomizednewSearcher; one document is enough; assertions on or off; several random test codecs gave the same result. - How likely. Rare: it needs source and reference to overlap at position 0. For such a query, the affected documents match every time. How often such queries meet such documents in real applications is unknown.
The test shows that Intervals.before(york, york) matches the one-word document "york", so a term at position 0 counts as before a reference that also starts at position 0.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queries.intervals;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestBeforeAtFirstPosition extends LuceneTestCase {

  public void testTermIsNotBeforeItself() throws Exception {
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new TextField("f", "york", Field.Store.NO));
        w.addDocument(doc);
      }
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IntervalsSource york = Intervals.term("york");
        IntervalQuery query = new IntervalQuery("f", Intervals.before(york, york));
        // expected: 0 hits, nothing comes before the only word "york"; actual: 1 hit
        assertEquals(0, new IndexSearcher(reader).count(query));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-293/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.queries.intervals.TestBeforeAtFirstPosition
- Expected vs actual
- Expected 0 hits (nothing comes before the only word); actual: 1 hit (
expected:<0> but was:<1>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<0> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.junit.Assert.assertEquals(Assert.java:633)
org.apache.lucene.queries.intervals.TestBeforeAtFirstPosition.testTermIsNotBeforeItself(TestBeforeAtFirstPosition.java:43)- before() "Returns intervals from the source that appear before intervals from the reference", as does
fn:before; nothing comes before the first token. - Shifting the text one position flips the answer (
yorkmatches,x yorkdoes not);ordered()andafter()follow the strict reading. - Only the package-private helper's clamp is tested; no test runs before() with a reference at position 0.
The full argument216 words
- The contract is strict. "Returns intervals from the source that appear before intervals from the reference" (
Intervals.java:580);fn:before: "Matches intervals from the source that appear before intervals from the reference" (intervalfn/package-info.java:425). No first-position exception, and at every other position the code is strict ([0, p-1]). - Not shift invariant.
yorkmatches andx yorkdoes not;new yorkmatches andx new yorkdoes not. No reading of "appear before" makesyorkprecede itself in one document and not in the other. - The design says "ordered". LUCENE-8629, which added
before(), describes it as "similar to an ordered near, but returning only intervals from 'a' rather than an interval spanning both a and b" (#9675).ordered()is strict (OrderedIntervalsSource.java:151) and gives the expected answer on the same texts. - Precedent. LUCENE-9099 (
7c1ba1aebee, 2020, "Correctly handle repeats in ORDERED and UNORDERED intervals") lists "UNORDERED(a, a)will match on documents that just containg a single a" as "somewhat confusing behaviour" and changes it: a source matching relative to itself. - No test covers it.
TestIntervals#testBefore(TestIntervals.java:909-913) usesbefore(cold, twelve), andtwelveis never at position 0 in its corpus; thefn:beforeexamples in the parser docs,TestStandardQPEnhancementsandTestMatchHighlighternever put a reference at position 0.
The devil's-advocate check212 words
The strongest case for "intended" (rated moderate by the intended-lens reviewer from another model family): the clamp is deliberate code, because -1 means "not positioned"; TestIntervals#testOffsetIntervals (TestIntervals.java:541-577), added in the same commit, asserts the helper's clamped [0, 0] output; extend() also clamps at 0 by a recorded decision (LUCENE-8612, #9658: a positional filter was removed because "it ends up breaking notWithin in certain circumstances"); and the package is experimental.
Why it fails: the helper test covers only the package-private helper, never before(). The helper's own javadoc promises a pseudo-interval "one position before" each reference, and none exists before position 0. Skipping such a reference is legal (IntervalIterator.java:35-36) and is what the fix does. The extend() clamp only drops positions below 0 and still contains the reference start; the PRECEDING clamp instead adds the reference's own first position to the "before" window. "Experimental" allows API changes, not wrong answers. LUCENE-8629's only review comment is "+1, the patch looks good"; position 0 was never discussed. Left for the reviewer to weigh: both fixes remove hits that every release since 8.0.0 has returned for the affected documents (a compatibility change of unknown practical reach), and they make an existing iterator-state quirk more frequent (see Fixes). Verdict: not intended, a defect.
Recommended A before()-only mode of the helper that skips references at position 0
Make the PRECEDING helper skip reference intervals that start at position 0, in a mode that Intervals.before turns on (+23/-3 in 2 files); the helper's own test is unchanged. The repro and the whole lucene/queries module pass with assertions on and off, and so do the fn:before suites in queryparser and highlighter.
   private final IntervalsSource in;
   private final boolean before;
+  // Set by Intervals.before: a reference interval that starts at position 0 has no position
+  // before it, so it produces no pseudo-interval instead of one clamped to position 0
+  private final boolean skipFirstPosition;
 ...
+        @Override
+        public int nextInterval() throws IOException {
+          int pos = in.nextInterval();
+          while (skipFirstPosition && pos == 0) {
+            pos = in.nextInterval();
+          }
+          return start();
+        }
All options and trade-offs3 options · 899 words
Both validated fixes stop PRECEDING from producing a pseudo-interval for a reference interval that starts at position 0, so a document whose every reference starts there has no "before" window. The first option adds a mode that only before() uses and leaves TestIntervals#testOffsetIntervals unchanged; the second changes the helper's PRECEDING mode for every caller (before() is its only production user; after() uses FOLLOWING, which neither fix touches) and updates three rows of that test. Both remove hits that every release since 8.0.0 has returned for the affected documents. Documenting the boundary instead is possible but leaves the shift variance. Until a fix ships, Intervals.ordered(source, reference) gives the expected documents for match/no-match filtering (it gave them in the repro's controls); its intervals span both sources, so highlighting and interval scores differ.
A before()-only mode of the helper that skips references at position 0 (validated by the checks) (recommended)
In OffsetIntervalsSource, add a skipFirstPosition flag (a 3-argument constructor; the 2-argument one passes false; the flag joins equals/hashCode), and in the PRECEDING iterator override nextInterval() to skip reference intervals that start at 0 when the flag is set. Intervals.before constructs the helper with the flag. The finder's sketch, with its comment reworded to fit 100 columns.
   private final IntervalsSource in;
   private final boolean before;
+  // Set by Intervals.before: a reference interval that starts at position 0 has no position
+  // before it, so it produces no pseudo-interval instead of one clamped to position 0
+  private final boolean skipFirstPosition;
 ...
+        @Override
+        public int nextInterval() throws IOException {
+          int pos = in.nextInterval();
+          while (skipFirstPosition && pos == 0) {
+            pos = in.nextInterval();
+          }
+          return start();
+        }
Trade-offs
- No existing test changes; the price is a flag that only matters in PRECEDING mode: the only PRECEDING construction with the flag off is
TestIntervals#testOffsetIntervals(after()also passesfalsethrough the 2-argument constructor, with no effect, though the flag now takes part inequals/hashCode).toString()staysPRECEDING(...). Cost: one comparison per reference interval. - Side effect: no wrong matches or interval contents were found, but iterator-state protocol violations become more frequent. In a document whose every reference starts at 0, the reference side now has no interval, so
FilteringIntervalIterator.start()/end()returnNO_MORE_INTERVALSinstead of -1 before the firstnextInterval()(FilteringIntervalIterator.java:36-50,reset()at:57-60). That pre-existing quirk is already reachable whenever a filter has no interval in a document; the fix makes it happen in more documents: in the finder's harness thebefore()protocol-check failures rise from 4,668 to 11,436 (documents of up to 4 positions) and from 11,973 to 35,568 (up to 3 positions with stacked synonyms). Worth stating in the PR. - Compatibility: the affected documents stop matching, a change of results every release since 8.0.0 has returned; how many applications see such documents is unknown.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: stock + the new test, 2 of 3 fail with assertions on and off; + the fix, assertions on::lucene:queries:check(ecjLint, forbiddenApis, checkGoogleJavaFormat and all 52 suites, 515 tests of the module, includingTestIntervals43 and the new test 3) plusTestStandardQPEnhancements(23) andTestMatchHighlighter(6), both of which usefn:before: 544 tests, 5 skipped, 0 failures; assertions off: the same tests, 6 skipped, 0 failures. - Standalone runner: 3 of 3 pass with assertions on and off.
- Earlier, on
ea57360912ed: the finder's, the independent reproducer's, the reviewer's and the devil's advocate's tests and the security probe pass with the finder's version; the exhaustive mismatches drop from 366 to 0; the finder's harness finds no extrabefore()interval in two before()-only re-runs (1,408,044 checks) and in a smaller re-run with all six of the unit's candidate fixes (287,753,697 checks).
Override nextInterval() in the PRECEDING iterator to skip reference intervals that start at 0 unconditionally, say so in the class javadoc, and drop the first 0, 0 pair from the three non-empty PRECEDING rows of TestIntervals#testOffsetIntervals (+11/-1, and +4/-3 in the test).
+        @Override
+        public int nextInterval() throws IOException {
+          int pos = in.nextInterval();
+          while (pos == 0) { // nothing precedes the first position
+            pos = in.nextInterval();
+          }
+          return start();
+        }
Trade-offs
Smaller (no flag, constructor or equals/hashCode change) and makes the helper match its javadoc. before() is the only production user of PRECEDING (Intervals.java:583), the only mode it changes; after() (:590) uses FOLLOWING. So results are identical to the first option. It changes an assertion a reviewer may read as deliberate; the same compatibility change and FilteringIntervalIterator side effect apply.
What the checks validated
Same worktree: assertions on, the whole module's tests and the two fn:before suites, 544 tests, 5 skipped, 0 failures (TestIntervals 43 of 43 with the updated rows), and :lucene:queries:check -x test passes; assertions off, the same 544 tests, 6 skipped, 0 failures. Standalone runner: 3 of 3 pass with assertions on and off.
State in the before() and fn:before javadoc that a source at position 0 counts as before a reference that starts at position 0.
Trade-offs
Changes no code, but keeps the shift variance and the disagreement with ordered(). Not built; not recommended.
Downstream rules built on before(), such as an intervals before filter used to allow or deny documents, let these documents through or hide them by the same mistake.
An AI finder compared Lucene's interval iterators with an independently written reference semantics on every small document and every 1- and 2-level interval expression, about 1.4 billion checks. Extra before() intervals showed up; none remained in smaller re-runs with references at position 0 skipped, and it reduced them to a two-test JUnit.
The method in full194 words
Method: bounded-exhaustive translation validation of the stock main jar against an independent reference semantics (the hunt's "semi-formal" tier).
- The hunt unit on spans and intervals wrote a reference semantics for the interval operators (
IvRef) and a harness (IvTV) that runs the real iterators on every document of up to 6 positions over {a, b, c} and up to 4 positions with stacked synonyms, for every 1- and 2-level expression over 24 interval operators: 1,401,702,324 checks. - The exact-interval check reported extra intervals for 206,037 of 7,200,414
before()checks (alone, underextend, with repeated sources, or both). With PRECEDING skipping reference intervals that start at position 0, none remain in two before()-only re-runs (1,408,044 checks, documents of up to 4 positions and up to 3 with stacked synonyms) and in a smaller re-run with all six of the unit's candidate fixes (287,753,697 checks; it did not cover the whole first run). - The finder reports that it first noticed the clamp while reading
OffsetIntervalsSourceto build the model; the harness then witnessed it, and it was reduced to a public-API JUnit. Independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found: 169 logged queries over GitHub, the JIRA archive, the mailing lists, downstream projects and the web (2026-10-26), a re-check on 2026-10-27, and the changed files of all 413 open PRs. The closest items are the issue that added before() and a fixed bug of the same kind in unordered().
Searches3 searches
No issue, PR, JIRA ticket, list thread or downstream report discusses before() matching a source at position 0 against a reference at position 0. On upstream main 20ced71c1e6e (2026-10-27) OffsetIntervalsSource.java was last changed in 2020 (a reformat) and Intervals.java by #16899, which is in the tested commit; no open PR touches either.
Closest, not this bug: #9675 (LUCENE-8629, added before(); position 0 never discussed); #9658 (LUCENE-8612) and lucene-solr PR #2127 (LUCENE-9633): extend() clamps at 0 by design, and a stale ExtendedIntervalIterator javadoc; #10141 (LUCENE-9099, UNORDERED(a, a) matching a single a, fixed); #11259 (LUCENE-10223, added fn:before).
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene), Elasticsearch, OpenSearch, Solr, dev@ / java-user@ / issues@ / commits@ lists, JIRA archive, web | 2026-10-26 | 169 logged queries: 128 from four runs of a scripted prior-report search and 41 manual GitHub, JIRA, list and web searches (8 web queries planned by the tool were not run); every issue or PR with "interval(s)" in the title and all 38 LUCENE JIRA issues with "interval(s)" in the summary scanned by title | only design context (#9675, #9658, lucene-solr #2127) and the LUCENE-9099 precedent |
| Open PRs | 2026-10-26 | the changed files of all 413 open apache/lucene PRs | 4 touch interval files; none touches OffsetIntervalsSource or before() |
| GitHub (apache/lucene), re-check | 2026-10-27 | 5 issue searches (OffsetIntervalsSource, fn:before, intervals position 0, before first position, Intervals.before), 3 open-PR searches, and the commit history of the three files on upstream main | 0 results; the code is unchanged upstream |
Introduced with before() itself by LUCENE-8629 (7d34bfdaad37, branch_8x 3593af2ac55f, 2019-01-07), first released in 8.0.0; not a regression. The same test fails on all 12 releases run from 8.0.0 to 10.5.2 and on main.
Versions tested7 rows
Introduced by LUCENE-8629 "New interval functions: before, after, within, overlapping" (@romseygeek; 7d34bfdaad37 on master and 3593af2ac55f on branch_8x, 2019-01-07; a JIRA patch, migrated to #9675, no GitHub PR). The one commit added before() as containedBy(source, extend(PRECEDING(reference), MAX, 0)), the Math.max(0, pos - 1) clamp, testOffsetIntervals and testBefore. Later commits (LUCENE-8633, LUCENE-3041, LUCENE-8477, LUCENE-8856, LUCENE-9050, LUCENE-9099, LUCENE-9570) did not change that logic. In lucene-sandbox for 8.0.0 and 8.1.x, in lucene-queries from 8.2.0, and reachable through fn:before from 9.1.0. Not fixed upstream.
Caveats: every run used JDK 25.0.3 on Linux aarch64; before 9.1.0 the test was ported only in its package line and test-framework imports. Tag containment: 3593af2ac55f is in every 8.x release tag of the local history clone (8.0.0 to 8.8.1) and 7d34bfdaad37 in every release tag from 9.0.0 to 10.5.2; the clone has no tags for 8.8.2 to 8.11.4. Of those, 8.9.0, 8.10.1, 8.11.3 and 8.11.4 were run and fail; 8.8.2, 8.10.0 and 8.11.0 to 8.11.2 were neither run nor covered by containment (they lie between failing releases).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this brief's test 2 of 3 fail (gradle and the standalone runner, assertions on and off); the finder's and the independent reproducer's tests fail as recorded |
| 10.5.2, 9.12.3 | affected | this brief's test 2 of 3 fail (assertions on and off); every earlier test fails too |
| 8.0.0, 8.1.1, 8.2.0, 8.11.4, 9.0.0, 9.1.0, 10.0.0 | affected | the finder's test 2 of 2 fail with the same numbers, assertions on and off |
| 8.9.0, 8.10.1, 8.11.3 | affected | the finder's test 2 of 2 fail, assertions on (run by the fact check) |
7d34bfdaad37, 3593af2ac55f (LUCENE-8629) | introducing | added before() and the clamp (read); 8.0.0 is the first release containing it |
| 7.6.0, 7.7.3 | no API | no Intervals.before: the port fails to compile only on that method |
| 8.0.0 + fix; main + fix | not affected | the repro passes; on main the whole lucene/queries module passes too |
An independent reproducer, a devil's advocate and reviews by another model family agree on the cause; the reproducer and the devil's advocate reproduced it with their own tests. An adjudication confirmed it (high), and re-runs on fresh seeds and on the current main reproduce it.
Checks and verdicts388 words
Every executed check ran its main repro with assertions on and off, except a separate re-run (-ea only). The cross-model reviews ran read-only on ea57360912ed; separate runs then ran the tests. No review executed code by itself.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | The exhaustive harness flagged extra before() intervals; the 2-test public-API JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3 and passes with the fix. |
| cross-model review, refute lens | procedural "not real" (low) | An independent reviewer from another model family (OpenAI GPT-5.6) could not run Java, so it voted not real on procedure only; it agreed with the root cause, found the inputs in contract and rated the intended case moderate. It recorded fix_fixes_it=false after seeing only the helper-level fix file, and proposed a before()-only variant, which is the first fix option. A separate run re-ran the finder's JUnit: 2 of 2 fail. |
| Independent reproducer | real | Own JUnit from the claim only, outside the intervals package: 4 of 4 fail on main (-ea, -da), 10.5.2 and 9.12.3; Weight#matches non-null; exhaustive 366 extra, 0 missed. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, read-only; separate controls: 3 of 4 fail on main (-ea, -da), including the raw iterator and fn:before; 4 of 4 pass with the fix. |
| Devil's advocate | real | Built the intended case and rejected it; own probe: before() not shift invariant and disagrees with ordered(), after() shift invariant in 24 of 24, on main, 10.5.2 and 9.12.3; passes with the fix. |
| adjudication | confirmed (high) | Re-ran the reproducer's JUnit (4 of 4 fail, -ea and -da) and the finder's (2 of 2), and the reproducer's with the fix (4 of 4 pass, mismatches 366 to 0); confirmed the root cause from source. |
| re-runs | still reproduces | Fresh seeds on ea57360912ed and a replay on a9779ef3c193: same failures; the fix passes. |
| fact checks | text corrected | An independent fact check re-ran the gradle command, the standalone runs (main, 10.5.2, 9.12.3, with assertions on and off), both fixes and TestIntervals, and added 8.9.0, 8.10.1, 8.11.3 and a stacked-synonym probe; a read-only review by another model family (OpenAI GPT-5.6) checked the text. Both found wording errors only. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 474 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,373 words
- Registry title
- Intervals.before(source, reference) treats a source interval at position 0 as before a reference interval that also starts at position 0, so for example before(york, york) matches the one-word document 'york'
- Area
- queries / intervals (Intervals.before, OffsetIntervalsSource PRECEDING)
- Priority
- Low, rank 346: Needs a before() query whose source and reference both match only at the first token of a field, a rare query shape.
- Impact class
- silent wrong results
- Impact note
- Anyone who uses Intervals.before, directly, through IntervalQuery or through StandardQueryParser fn:before (since 9.1.0), with default writer, codec, analyzer and searcher settings, at any index size and in every release since 8.0.0, gets an extra hit, and an extra interval from Weight#matches, on each document where the source matches exactly the first token and every reference match also starts at the first token (before(X, X) with a single leading X, before(term, phrase that starts with that term) at the start of a field, or synonyms stacked on the first token); matches are only ever added, never lost, Intervals.after is not affected, and nothing is written to the index.
- Summary
- You search with Intervals.before(source, reference), for example before(term new, phrase(new, york)) on the text 'new york', or before(term york, term york) on the one-word text 'york'. You expect no match, because the javadoc says before 'Returns intervals from the source that appear before intervals from the reference' and nothing comes before the first word. Instead both documents match: before() is built from a helper that places a pseudo-interval one position before each reference match, and for a reference at position 0 the helper clamps that position to 0 instead of producing nothing, so a source at position 0 counts as 'before' it; prepend one unrelated word and the same text correctly stops matching.
- Introduced
- 7d34bfdaad37a25bfda5df2bf2c2bd1a31540bc2 (master) and its branch_8x copy 3593af2ac55f12a2ce2cfa76fd58407aa3fafa67 (same day, same diff; the commit the 8.x releases contain), 'LUCENE-8629: New interval functions: before, after, within, overlapping' (romseygeek; a JIRA patch, migrated to apache/lucene#9675, no GitHub PR) [read: git show, git log --follow and git blame of OffsetIntervalsSource.java and git log -L of Intervals.before in the full-history clone]. The one commit created both halves: Intervals.before as containedBy(source, extend(PRECEDING(reference), MAX, 0)) and the PRECEDING start() = Math.max(0, pos - 1). Later commits that touched the class (LUCENE-8633, LUCENE-3041, LUCENE-8477, LUCENE-8856, LUCENE-9050, LUCENE-9099, LUCENE-9570) did not change that logic. Present since the API was created, not a regression (2019-01-07 (7d34bfdaad37 and 3593af2ac55f))
- First affected version
- 8.0.0 [exec] (release tag 2019-03-13; lucene-sandbox artifact, package org.apache.lucene.search.intervals; CHANGES 8.0.0 New Features 'LUCENE-8629: New interval functions: Intervals.before(), Intervals.after(), Intervals.within() and Intervals.overlapping()'); 7.6.0 and 7.7.3 have no Intervals.before [exec: a port of the repro fails to compile only on the missing before(IntervalsSource, IntervalsSource)]; the before()-only fix applied to the 8.0.0 sources makes the 8.0.0 port pass 2 of 2 [exec]
- Affected versions
- every release from 8.0.0 through 10.5.2 and main ea57360912ed. [exec] by the follow-up history sweep (the finder's 2-test JUnit, ported only in its package line and test-framework imports for releases before 9.1.0; its positive control passes everywhere): 8.0.0, 8.1.1, 8.2.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main all fail 2 of 2 with identical messages under -ea and -da; the independent reproduction (4 tests including a bounded-exhaustive oracle and the Matches API) and the intended-behaviour check (shift-invariance probe) also fail on 10.5.2 and 9.12.3. [read] 3593af2ac55f is in every 8.x tag of the history clone (8.0.0 to 8.8.1) and 7d34bfdaad37 in every 9.x and 10.x tag (9.0.0 to 10.5.2); 8.8.2 to 8.11.3 were not run individually. Exposure: lucene-sandbox 8.0.0 to 8.1.x, lucene-queries (org.apache.lucene.queries.intervals) from 8.2.0 (LUCENE-8856), query strings through StandardQueryParser fn:before from 9.1.0 (LUCENE-10223; executed on main by a separate check and on main, 10.5.2 and 9.12.3 by the security probe). Not affected: every release up to 7.7.3 (API absent) [exec]. Not fixed: upstream main HEAD was the tested commit at search time, OffsetIntervalsSource was last changed in 2020 (a reformat) on main and branch_10x, and no open PR touches OffsetIntervalsSource or before() [read]; 10.6.0 (released 2026-10-29) was not checked (it was not on Maven Central on 2026-10-26). All runs on aarch64 with JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (follow-up prior-report record verdict new, final pass 2026-10-26, read-only): 169 logged queries, from a scripted prior-report search in four runs (finder, the intended-behaviour check and two follow-up runs: GitHub issues and PRs on apache/lucene, commits, the downstream repositories Elasticsearch, OpenSearch and Solr, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web) plus manual GitHub, JIRA, list and web searches; every apache/lucene issue or PR with 'interval' or 'intervals' in the title and all 38 LUCENE JIRA issues with 'interval(s)' in the summary were scanned by title, the related ones read in full, and the changed files of all 413 open apache/lucene PRs were checked. Nearest items, none the same bug: LUCENE-8629 / #9675 (introduced before(); the only review comment is '+1, the patch looks good', position 0 never discussed); LUCENE-8612 / #9658 (Intervals.extend: the author tried, then removed, a positional filter, so extend() clamps at position 0 by design); lucene-solr PR #2127 / LUCENE-9633 (notes that the ExtendedIntervalIterator javadoc about positions below n is wrong because extend clamps to 0; still unchanged on main, a separate doc nit); LUCENE-9099 / #10141 (same defect class: UNORDERED(a, a) matching a single a was fixed as a bug); LUCENE-10223 / #11259 (added fn:before). Not fixed upstream: no open PR touches OffsetIntervalsSource or before(). Gaps: GitHub search reads only the first page per query; PR review comments only as far as GitHub's issue search indexes them; JIRA attachments were not read; two tool-planned web queries were not run (throttling)
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2 and 9.12.3 release jars (assertions on and off; 9.12.3 off was run by the fact check). The finder's 2-test JUnit ran earlier on 8.0.0, 8.1.1, 8.2.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3, 10.0.0, 10.5.2 and mainea57360912ed(assertions on and off), on 8.9.0, 8.10.1 and 8.11.3 (assertions on, fact check), and was re-run ona9779ef3c193. Two fixes were validated in the scratch worktree: the new test, the wholelucene/queriesmodule (515 tests, including ecjLint, forbiddenApis and checkGoogleJavaFormat),TestStandardQPEnhancementsandTestMatchHighlighter.
- Finding record
lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:578 (before javadoc 'Returns intervals from the source that appear before intervals from the reference'), :579-582 (before = ContainedByIntervalsSource.build(source, extend(new OffsetIntervalsSource(reference, true), Integer.MAX_VALUE, 0))), :584-589 (after)lucene/queries/src/java/org/apache/lucene/queries/intervals/OffsetIntervalsSource.java:28-31 (class javadoc: 'a pseudo-interval that appears either one position before or one position after each interval from the reference'), :51-65 (PRECEDING start(): -1 and NO_MORE_INTERVALS passed through, else Math.max(0, pos - 1) at :63), :66-82 (FOLLOWING start()), :94-108 (end() = start(); nextInterval advances the reference once)lucene/queries/src/java/org/apache/lucene/queries/intervals/package-info.java:21 ('experimental classes')lucene/queries/src/test/org/apache/lucene/queries/intervals/TestIntervals.java:541 (testOffsetIntervals asserts the helper's clamped [0,0] output), :909 (testBefore; reference 'twelve' never at position 0)lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/nodes/intervalfn/Before.java:37 (fn:before calls Intervals.before); intervalfn/package-info.java:423-425 (fn:before 'Matches intervals from the source that appear before intervals from the reference')
- The finding in 30 seconds
lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:554, (at a9779ef3c193) :580, :581-584lucene/queries/src/java/org/apache/lucene/queries/intervals/OffsetIntervalsSource.java:28-31, (at a9779ef3c193) :51-65 (:63), :66-83, :94-97, :104-108, :143lucene/queries/src/java/org/apache/lucene/queries/intervals/ExtendedIntervalIterator.java:61; (at a9779ef3c193) ContainedByIntervalsSource.java:52-61; IntervalIterator.java:35-36, :46-52; package-info.java:21; lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:50-58lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/nodes/intervalfn/Before.java:37; (at a9779ef3c193) package-info.java:423-425
- Why it looks unintended
lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:580; (at a9779ef3c193) OrderedIntervalsSource.java:151; IntervalIterator.java:35-36lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/nodes/intervalfn/package-info.java:423-425 (at a9779ef3c193)lucene/queries/src/test/org/apache/lucene/queries/intervals/TestIntervals.java:541-577 (at a9779ef3c193) (testOffsetIntervals), :909-913 (testBefore)
- Suggested fix
lucene/queries/src/java/org/apache/lucene/queries/intervals/FilteringIntervalIterator.java:36-50, (at a9779ef3c193) :57-60; IntervalIterator.java:31-33; OrderedIntervalsSource.java:151lucene/queries/src/test/org/apache/lucene/queries/intervals/TestIntervals.java:548, (at a9779ef3c193) :562 (the only other OffsetIntervalsSource constructions)lucene/queries/src/java/org/apache/lucene/queries/intervals/Intervals.java:583, (at a9779ef3c193) :590 (the two production OffsetIntervalsSource constructions)
- TestBeforeAtFirstPosition.java (JUnit test):
repro/LFV-293/src/org/apache/lucene/queries/intervals/TestBeforeAtFirstPosition.java(47 lines)
The PNG is the final summary card.
assets/LFV-293/bug.png(474 KB)