One vector field, four documents, one flush: with vectors on documents 0, 2 and 3, the flush-time ordToDoc answers 0, 1, 2 instead of 0, 2, 3.
- In a segment, the vectors of a field are numbered 0, 1, 2, ... in document order. Only documents that have a vector get a number, its ordinal: with vectors on documents 0, 2 and 3, the ordinals are 0, 1, 2.
KnnVectorValues.ordToDoc(ord)maps an ordinal back to its document.getAcceptOrds(acceptDocs)uses it to turn a set of accepted documents into a set of accepted ordinals.BufferingKnnVectorsWriteris a base class for vector codecs that keep a segment's vectors in memory: at flush it hands the subclass'swriteFieldone values object per field. SimpleText's writer is built on it.
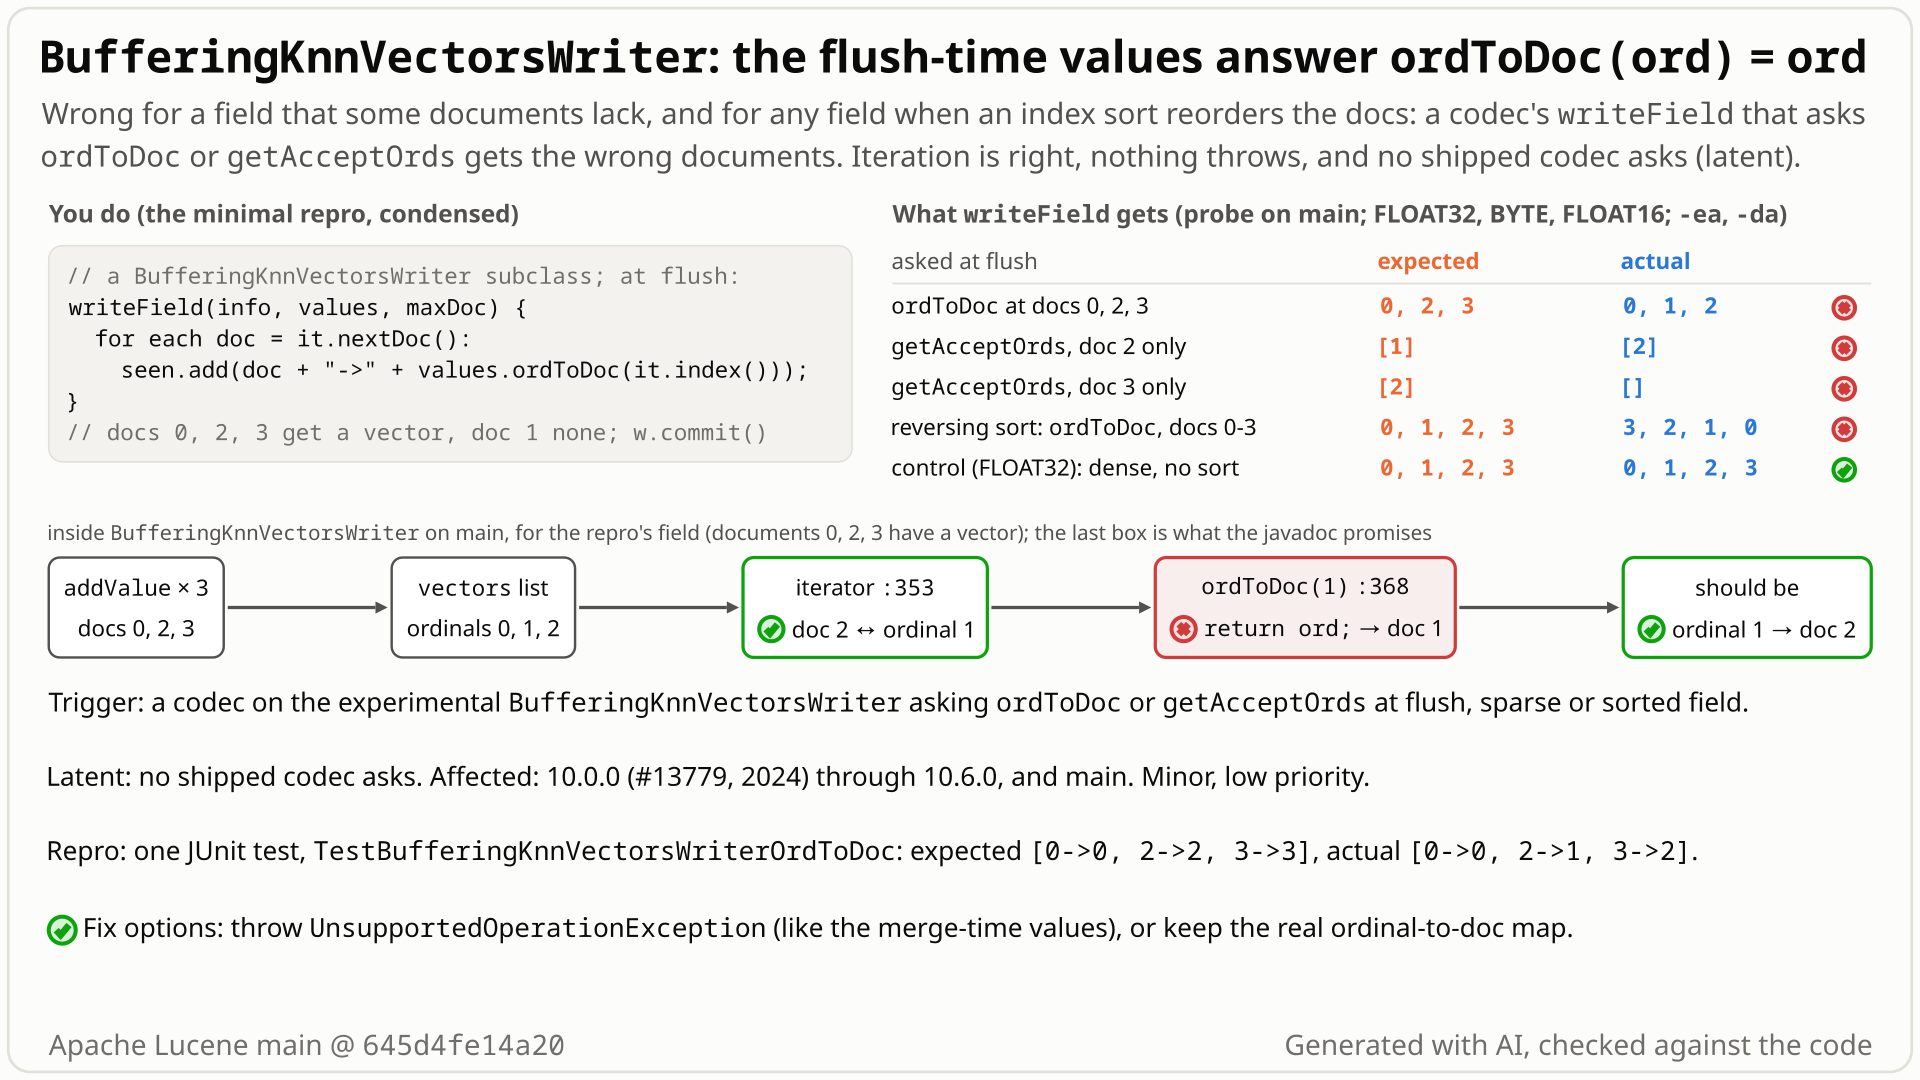
ordToDoc answers 0, 1, 2 instead of 0, 2, 3. Select the still to open it at full size. Generated with AI, checked against the code.- A custom vector codec's writer extends
BufferingKnnVectorsWriter. At flush, itswriteFieldgets the buffered vectors of fieldvand asksvalues.ordToDoc(ord)for each one: which document is this vector from? - Four documents are indexed and committed. Documents 0, 2 and 3 have a vector, document 1 has none, so the vector ordinals 0, 1, 2 belong to documents 0, 2, 3.
- You expect
ordToDocto answer 0, 2, 3: its javadoc says it returns "the docid of the document indexed with the given vector ordinal". - Instead it answers 0, 1, 2: it returns the ordinal itself. When an index sort reorders the documents, it does so even when every document has a vector (after a sort that reverses 4 documents, it answers 3, 2, 1, 0 for documents 0, 1, 2, 3), and
getAcceptOrds, built on it, keeps the wrong vectors. - Nothing throws, and iterating is right. Lucene's own writers only iterate, so stock indexes are correct; a custom codec that maps ordinals back to documents silently writes or filters vectors against the wrong documents.
Custom vector codecs only: a writer that extends the experimental BufferingKnnVectorsWriter and calls ordToDoc or getAcceptOrds in writeField at flush, on a field some documents lack, or when an index sort reorders the segment. Every Lucene writer only iterates and writes correct indexes, and no such custom codec is known. 10.0.0 to 10.6.0 and main.
Mechanism, terms and numbers528 words
At flush, BufferingKnnVectorsWriter hands its subclass's writeField a values object over the buffered vectors of each field. Its iterator visits only the documents that have a vector, so ordinal k is the k-th such document, but ordToDoc(ord) returns ord. For a field held by documents 0, 2 and 3 it answers 0, 1, 2 instead of 0, 2, 3; when an index sort reorders the segment, the sorting wrapper inherits the same identity, so even a dense field's ordinals map to themselves instead of to their sorted documents; and getAcceptOrds, built on ordToDoc, filters the wrong vectors. Nothing throws, iteration stays correct, and FLOAT32, BYTE and FLOAT16 behave the same with assertions on and off. It is latent: SimpleText's writer and the backward-codecs test writers only iterate, so stock indexes are correct, and only a custom codec on this experimental base class that maps ordinals back to documents is hit. It came with the random-access API in 10.0.0 (#13779) and is in every 10.x release and main; a lazily built ordinal-to-document table fixes it.
- Flush-time values.
flush(maxDoc, sortMap)wraps each field's buffered vectors and itsdocsWithFieldset inBufferedFloatVectorValues(BufferedByteVectorValues,BufferedFloat16VectorValues) and, when an index sort reorders the segment (sortMap != null), in a privateSorting*VectorValues, then calls the subclass'swriteField(BufferingKnnVectorsWriter.java:90-134at645d4fe14a20). - Contract.
KnnVectorValues#ordToDoc: "Return the docid of the document indexed with the given vector ordinal. This default implementation returns the argument and is appropriate for dense values implementations where every doc has a single value." (KnnVectorValues.java:43-50).
addValueappends a vector only for documents that have one (BufferingKnnVectorsWriter.java:310-322), so the list index, the ordinal, counts only those documents.- The values' iterator is
fromDISI(docsWithField.iterator())(:353):index()countsnextDoc()calls,docID()is the real document. That part is right. BufferedFloatVectorValues.ordToDoc(int ord) { return ord; }(:366-369), the same inBufferedFloat16VectorValues(:412-415);BufferedByteVectorValues(:433-472) inherits the identity default. For a sparse field, ordinal and document differ.- The sorting wrappers (
:137-250) override noordToDoc. Their iterator'sindex()is the delegate's ordinal for each sorted document (SortingCodecReader.java:244-266,:286-290), so the inherited identity maps it to itself, not to its sorted document, even for a dense field, whenever the sort reorders the segment (an already-sorted segment gets no sort map:IndexingChain.java:296). - The default
getAcceptOrdsreturnsacceptDocs.get(ordToDoc(index))(KnnVectorValues.java:110-127) and inherits the error. - For contrast, the merge-time values that
mergeOneFieldpasses to the samewriteField(:262-281) throwUnsupportedOperationExceptionfromordToDoc(KnnVectorsWriter.java:498-500,:596-597,:698-699).
| case | expected | got |
|---|---|---|
sparse (docs 0, 2, 3), ordToDoc(index()) | 0->0, 2->2, 3->3 | 0->0, 2->1, 3->2 |
sparse, getAcceptOrds accepting one doc | 0->{0}, 2->{1}, 3->{2} | 0->{0}, 2->{2}, 3->{} |
dense, 4 docs, reversing index sort, ordToDoc(index()) | 0->0, 1->1, 2->2, 3->3 | 0->3, 1->2, 2->1, 3->0 |
FLOAT32, BYTE and FLOAT16 give the same values. Answers stay inside [0, size): they are another vector's ordinal, never out of range. Only the first row is the minimal repro; the others come from the study's independent test, re-run for this doc.
Exposure and likelihood251 words
- Who is hit. Authors of a custom
KnnVectorsFormatwhose writer extends the public abstract,@lucene.experimentalBufferingKnnVectorsWriter(class javadoc: "Buffers up pending vector value(s) per doc, then flushes when segment flushes. Used for SimpleTextKnnVectorsWriter and for vectors writers before v 9.3 .") and whosewriteFieldcallsordToDocorgetAcceptOrdsat flush, for example to write an ordinal-to-document table or to keep only accepted documents' vectors. They silently get another vector's document for every field that some documents lack, and for every field when an index sort reorders the segment. - Not hit: Lucene's own writers. The only subclasses in the tree are
SimpleTextKnnVectorsWriterand the backward-codecs test writersLucene90/91/92HnswVectorsWriter; all take document ids from the iterator (the Lucene92 test writer builds its own ordinal-to-document table from the iterated documents). The production vector formats do not extend this class. None of them callsordToDocorgetAcceptOrdson these values (code read); consistent with that, withordToDocmade to throw, the SimpleText and the three backward-codecs HNSW format suites still pass. - Opt-in. It takes a third-party codec on an experimental base class; a read-only code search of Elasticsearch, OpenSearch, OpenSearch k-NN and Solr found no subclass (not exhaustive).
- Partly self-limiting. If such a writer's
writeFieldalso callsordToDocon the merge-time values, it hitsUnsupportedOperationExceptionat its first merge; avoiding that takes overridingmergeOneFieldor treating the merge-time values differently, which makes an undetected production user unlikely. - Scale. Any segment size; 4 documents are enough; deterministic; FLOAT32, BYTE and FLOAT16; assertions on and off.
One JUnit test, 4 documents, one flush. A write-only vector format whose writer extends BufferingKnnVectorsWriter records docID() and ordToDoc(index()) for each document the flush-time iterator visits; documents 0, 2 and 3 have a 1-dimensional vector.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.codecs;

import java.io.IOException;
import java.util.ArrayList;
import java.util.List;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.KnnFloatVectorField;
import org.apache.lucene.index.ByteVectorValues;
import org.apache.lucene.index.FieldInfo;
import org.apache.lucene.index.Float16VectorValues;
import org.apache.lucene.index.FloatVectorValues;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.KnnVectorValues;
import org.apache.lucene.index.SegmentReadState;
import org.apache.lucene.index.SegmentWriteState;
import org.apache.lucene.search.DocIdSetIterator;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;
import org.apache.lucene.tests.util.TestUtil;

public class TestBufferingKnnVectorsWriterOrdToDoc extends LuceneTestCase {

  public void testSparseFieldOrdToDoc() throws Exception {
    List<String> seen = new ArrayList<>();
    KnnVectorsFormat format =
        new KnnVectorsFormat("Probe") {
          @Override
          public KnnVectorsWriter fieldsWriter(SegmentWriteState state) {
            return new BufferingKnnVectorsWriter() {
              @Override
              protected void writeField(FieldInfo info, FloatVectorValues values, int maxDoc)
                  throws IOException {
                KnnVectorValues.DocIndexIterator it = values.iterator();
                for (int doc = it.nextDoc();
                    doc != DocIdSetIterator.NO_MORE_DOCS;
                    doc = it.nextDoc()) {
                  seen.add(doc + "->" + values.ordToDoc(it.index()));
                }
              }

              @Override
              protected void writeField(FieldInfo info, Float16VectorValues values, int maxDoc) {}

              @Override
              protected void writeField(FieldInfo info, ByteVectorValues values, int maxDoc) {}

              @Override
              public void finish() {}

              @Override
              public void close() {}
            };
          }

          @Override
          public KnnVectorsReader fieldsReader(SegmentReadState state) {
            throw new UnsupportedOperationException();
          }

          @Override
          public int getMaxDimensions(String fieldName) {
            return 1024;
          }
        };
    Codec base = TestUtil.getDefaultCodec();
    Codec codec =
        new FilterCodec(base.getName(), base) {
          @Override
          public KnnVectorsFormat knnVectorsFormat() {
            return format;
          }
        };
    try (Directory dir = new ByteBuffersDirectory();
        IndexWriter w = new IndexWriter(dir, new IndexWriterConfig().setCodec(codec))) {
      for (int d = 0; d < 4; d++) {
        Document doc = new Document();
        if (d != 1) {
          doc.add(new KnnFloatVectorField("v", new float[] {d}));
        }
        w.addDocument(doc);
      }
      w.commit();
    }
    // docID->ordToDoc(index()) at flush: expected each ordinal to map to its own doc, actual 2->1, 3->2
    assertEquals(List.of("0->0", "2->2", "3->3"), seen);
  }
}
cp $REPRO/TestBufferingKnnVectorsWriterOrdToDoc.java $LUCENE/lucene/core/src/test/org/apache/lucene/codecs/
cd $LUCENE && ./gradlew :lucene:core:test --tests org.apache.lucene.codecs.TestBufferingKnnVectorsWriterOrdToDoc -Ptests.seed=DEADBEEF -Ptests.asserts=true
# same failure with -Ptests.asserts=false
- Expected
[0->0, 2->2, 3->3]: each vector's ordinal maps back to the document it was indexed with.- Observed
[0->0, 2->1, 3->2]:ordToDocreturns the ordinal, so documents 2 and 3 are reported as 1 and 2.
More files, environment, full output328 words
Public and protected API only: an anonymous BufferingKnnVectorsWriter subclass (public abstract, @lucene.experimental; writeField is protected) inside an anonymous KnnVectorsFormat, plugged into a FilterCodec over TestUtil.getDefaultCodec(); IndexWriter, KnnFloatVectorField, ByteBuffersDirectory, LuceneTestCase. The format is write-only (its reader throws) and the index is never opened. The IndexWriterConfig and the codec are not randomized (the test framework still randomizes settings such as locale and time zone, which this path does not use); two seeds gave the same failure. The package org.apache.lucene.codecs is only a convention. It passes once each document maps to itself, which the recommended fix gives; it can serve as the regression test.
It covers the sparse FLOAT32 case only. The index-sort, getAcceptOrds, BYTE and FLOAT16 symptoms come from the same identity and were shown by the study's independent test; they are not part of the repro.
On a 10.x release, delete the Float16VectorValues import and the empty writeField(FieldInfo, Float16VectorValues, int) override (FLOAT16 came with #16383, which is on main and branch_11x but in no release); nothing else changes.
Lint: ecjLintTest and forbiddenApisTest pass with the test in lucene/core/src/test; checkGoogleJavaFormat flags its last comment line (104 columns).
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails with assertions on and off; 10.0.0 to 10.6.0: fails (10.x form); with the recommended fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 |
| os | Linux aarch64 |
# gradle, scratch worktree of main 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (the same with asserts=false)
TestBufferingKnnVectorsWriterOrdToDoc > testSparseFieldOrdToDoc FAILED
    java.lang.AssertionError: expected:<[0->0, 2->2, 3->3]> but was:<[0->0, 2->1, 3->2]>
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:E6A0A48A5C4E1EA8]:0)
        at org.junit.Assert.fail(Assert.java:89)
        at org.junit.Assert.failNotEquals(Assert.java:835)
        at org.junit.Assert.assertEquals(Assert.java:120)
        at org.junit.Assert.assertEquals(Assert.java:146)
        at org.apache.lucene.codecs.TestBufferingKnnVectorsWriterOrdToDoc.testSparseFieldOrdToDoc(TestBufferingKnnVectorsWriterOrdToDoc.java:103)

# standalone, same seed: the same message on main (-ea, -da) and on 10.0.0 to 10.6.0

# the study's independent test on main (not the repro): the other shapes, summarized from its JUnit failure messages
sparse getAcceptOrds(only doc):              [0->[0], 2->[2], 3->[]]          expected [0->[0], 2->[1], 3->[2]]
dense, reversing index sort, ordToDoc:       [0->3, 1->2, 2->1, 3->0]         expected [0->0, 1->1, 2->2, 3->3]
FLOAT32, BYTE and FLOAT16 give the same valuesordToDocis documented to "Return the docid of the document indexed with the given vector ordinal"; returning the argument is called appropriate "for dense values".- The introducing PR has partial implementations throw
UnsupportedOperationException; the merge-time values for the same hook do, these return a wrong document. - Precedent: #13842 fixed the same kind of identity
ordToDocin SimpleText's reader.
The full argument275 words
- The contract is unconditional.
KnnVectorValues.java:43-47: "Return the docid of the document indexed with the given vector ordinal. This default implementation returns the argument and is appropriate for dense values implementations where every doc has a single value." The buffered values iterate a sparsedocsWithField(BufferingKnnVectorsWriter.java:353) and still overrideordToDocwith the identity. - Nothing documents a restriction. The
writeFieldhooks say only "Write the provided float vector field" (:283-293). No javadoc, MIGRATE or CHANGES entry says flush-time values are forward-only; MIGRATE's 10.0 note is headed "Vector values APIs switched to primarily random-access" (lucene/MIGRATE.md:1725-1727). - The convention is to throw. #13779's description: "Some of the methods on
KnnVectorValueshave default impls that throwUnsupportedOperationExceptionenabling subclasses to provide partial implementations and relying on testing to catch missing required methods." The merge-time values follow it; the flush-time values answer with a plausible wrong document. - History. The identity override came in an intermediate #13779 commit (
2bbf8f1feda6, "adding some ordToDoc", 2024-09-02) while the baseordToDocstill threw; a later commit (dce766c9751d) made the base defaultreturn ord. No review comment discusses the overrides. #16383 copied the identity to FLOAT16 (on main andbranch_11x, in no release yet). - Precedent. #13842 ("Fix simple text byte vector iteration", @benwtrent, merged 2024-10-01, milestone 10.0.0; its first attempt, the closed PR #13839: "SimpleText format wasn't overriding the byte vector's ordToDoc, causing multiple tests to fail") added
ordToDoc(int ord) { return entry.ordToDoc[ord]; }toSimpleTextKnnVectorsReader. The writer was not touched. - No test covers it. No test asserts
ordToDocorgetAcceptOrdson writer-side values; with them made to throw, the related suites still pass.
The devil's-advocate check248 words
The strongest case (rated moderate by every reviewer): the values given to writeField are forward-only in practice. The merge-time values for the same hook throw from ordToDoc, copy and scorer and enforce forward iteration ("only supports forward iteration with a single iterator", KnnVectorsWriter.java:476-485); the merge-time class javadoc says "View over multiple vector values supporting iterator-style access via DocIdMerger" (KnnVectorsWriter.java:311); every in-tree subclass only iterates; the class is experimental and documented as for SimpleText and pre-9.3 writers; and #13779's description accepts partial implementations ("Some of these readers would only ever be used iteratively." and "Can we live with a little less API purity and gain some simplicity and less boilerplate?").
Why it fails: the same description says partial implementations should throw so that tests catch them; these values instead answer with another vector's ordinal. Nothing tells a codec author that the hook's values are forward-only, ordToDoc's contract is unconditional, and the identity default is documented as right only for dense values. During review of #13779 its author wrote (2024-09-19): "I also added a test-and-throw ensuring that the vectorValues impls that require forward-iteration enforce it"; these values enforce nothing. The maintainers fixed the same kind of defect, an inherited identity ordToDoc on sparse values, in a reader as a bug (#13842); it is analogous, not identical, since that one was visible to stock code and broke tests. What survives is the severity: latent, custom codecs only. Verdict: most likely not intended, a minor latent defect.
Recommended A. Correct mapping, built on first use
Make ordToDoc correct: each buffered and sorting values class looks the document up in an int[] built on its first call (one file, +75/-2). Validated: the repro, the SimpleText and three backward-codecs vector format suites and the study's wider test pass. Writers that never call it never build the table.
// Buffered{Float,Float16,Byte}VectorValues; the Sorting* wrappers use
// sortedDocIdsOf(iteratorSupplier.get(), size()) instead
private int[] docIds; // ord -> doc, built on first use

@Override
public int ordToDoc(int ord) {
  if (docIds == null) {
    docIds = docIdsOf(docsWithField, size()); // the documents of docsWithField, in order
  }
  return docIds[ord];
}
All options and trade-offs3 options · 564 words
Two fixes were built against 645d4fe14a20 and run with gradle.
Give Buffered{Float,Float16,Byte}VectorValues an ordToDoc that looks the document up in an int[] of the documents of docsWithField, in order, built on the first call; give the three Sorting*VectorValues the same, filled from the sorting iterator (docIds[it.index()] = doc). getAcceptOrds becomes correct with no change. One file, BufferingKnnVectorsWriter.java, +75/-2 lines.
// Buffered{Float,Float16,Byte}VectorValues; the Sorting* wrappers use
// sortedDocIdsOf(iteratorSupplier.get(), size()) instead
private int[] docIds; // ord -> doc, built on first use

@Override
public int ordToDoc(int ord) {
  if (docIds == null) {
    docIds = docIdsOf(docsWithField, size()); // the documents of docsWithField, in order
  }
  return docIds[ord];
}
Trade-offs
- No table and no extra pass for writers that never call
ordToDoc(SimpleText and every in-tree writer), only an unused field per values instance; a caller pays one O(size) pass and 4 bytes per vector, once per values instance. - Not thread-safe, like the rest of these values;
copy()starts without a table. - The helpers catch
IOExceptiononly becausenextDoc()declares it; neither iterator does I/O. - Flush and merge still differ (the merge-time values throw); a javadoc line on
writeFieldcan say so.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(--offline, seed DEADBEEF, JDK 25.0.3). Stock: the repro fails with assertions on and off. With the fix: it passes with assertions on and off. TestSimpleTextKnnVectorsFormat(57 tests, 4 skipped) andTestLucene90HnswVectorsFormat,TestLucene91HnswVectorsFormat,TestLucene92HnswVectorsFormat(174 tests, 9 skipped) pass, 0 failures.- Core lint:
ecjLintMain,ecjLintTest,forbiddenApisMain,forbiddenApisTestpass;checkGoogleJavaFormatfinds nothing in the fixed file (it flags only the test's long comment line); eclint is not configured here and was skipped. - With the fixed class compiled ahead of the stock main jars (shadowed, not a rebuilt Lucene): the study's independent test passes 6 of 6 (sparse, sparse
getAcceptOrds, reversing sort; FLOAT32, BYTE, FLOAT16;-eaand-da), and the hunt's 2 tests (sparse; sparse with an index sort) pass.
Make ordToDoc throw UnsupportedOperationException in the three Buffered* and three Sorting* classes, and document on the writeField hooks that the values support forward iteration only, at flush as at merge (one file, +43/-5).
Trade-offs
- Cheapest:
ordToDoc, and with it the defaultgetAcceptOrds, then fails at the first flush, as at merge, instead of writing wrong data. It does not make the buffered values forward-only in other respects: at flushvectorValue(ord)in any order andcopy()still work, while the merge-time values reject both. - Removes an answer that is correct today for dense, unsorted fields; a custom writer relying on it breaks (it would already break at merge if it calls
ordToDocon the merge-time values too). - The minimal test then fails with
UnsupportedOperationException, so as a regression test it would have to expect the exception.
What the checks validated
- Gradle: the repro fails with
UnsupportedOperationExceptionfromBufferedFloatVectorValues.ordToDoc;TestSimpleTextKnnVectorsFormatand the three backward-codecs HNSW suites pass (57 + 174 tests, 0 failures), so nothing in the tree needsordToDocon these values.
Say in the writeField javadoc that ordToDoc and getAcceptOrds of the values are valid only for dense, unsorted fields.
Trade-offs
Leaves the silent wrong answer in place. Not run.
Downstream engines would be hit only through their own vector codec built on BufferingKnnVectorsWriter; a read-only code search of Elasticsearch, OpenSearch, OpenSearch k-NN and Solr found no such subclass.
Bounded-exhaustive checking: a harness tried every call sequence of up to 4 calls on the values writeField receives, for every set of documents with a vector in segments of 1 to 8 documents, with and without an index sort, and checked ordToDoc(index()) == docID(). The smallest sparse case failed; a JUnit test through IndexWriter confirmed it.
The method in full172 words
Method: bounded-exhaustive translation validation (the hunt's "semi-formal" tier), hunt unit (vector document/ordinal mapping), 2026-10-26, main ea57360912ed.
- The harness ran on the real classes of the main jars and checked them against the javadoc. Write side: every set of documents with a vector in segments of 1 to 8 documents and every call sequence of length up to 4 over the values
BufferingKnnVectorsWriterhands towriteField, with and without an index sort (nextDoconly under the sort), for FLOAT32, BYTE and FLOAT16. - The first signal was its check
ordToDoc(index()) == docID()on the smallest sparse case: document set {1} after onenextDoc(),ordToDoc(0) = 0whiledocID() = 1. - The finder confirmed it with a hand-written JUnit through
IndexWriter(sparse; sparse with an index sort), and the hunt later minimized it to the one sparse test. The harness also showed that this fix removes only its own failures, and that with the fix forfromDISI.advance()(the root cause of another finding) as well, the write side is clean.
No prior report found (searched 2026-10-26 and again 2026-11-01: 212 and 132 logged searches and checks over GitHub, the mailing lists, the JIRA archive and downstream projects, plus the changed files of every open PR). Closest: #13842, which fixed the same identity ordToDoc in SimpleText's reader.
Searches4 searches
No issue, PR, review comment, commit, list thread, JIRA entry or downstream report describes the flush-time values of BufferingKnnVectorsWriter answering ordToDoc(ord) = ord. #13842 is read as precedent (a different class, fixed in that reader only), not as a report.
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues and PRs, downstream repositories, all of GitHub | 2026-10-26 and 2026-11-01 | 96 and 62 issue/PR queries (scripted, GraphQL and REST phrasings: the Buffered* and Sorting* class names, ordToDoc, getAcceptOrds, writeField, sparse, index sort); 45 items read in full in the first search | no report; closest #13842 / #13839, #13779, #16205, #15430, #16811, #16383 |
| Open PRs and code history | 2026-11-01 | changed files of all 409 open apache/lucene PRs; main, branch_11x, branch_10_6, branch_10_5 and the 10.6.0 tag | only #12636 (a rename) touches the file; not fixed anywhere |
| Mailing lists and JIRA archive | 2026-10-26 and 2026-11-01 | 80 and 41 queries over dev@, java-user@, issues@ and commits@; 17 and 4 JIRA-archive queries | no report |
| Downstream (Elasticsearch, OpenSearch k-NN) | 2026-10-26 and 2026-11-01 | code and PR search | Elasticsearch #137862 and OpenSearch k-NN #3196 fix the same pitfall in their own wrappers, not in Lucene's writer |
Introduced in 10.0.0 by #13779 (6053e1e3137, merged 2024-09-28), which created ordToDoc and gave the buffered values the identity answer; #16383 copied it to FLOAT16 on main. Fails on all 13 10.x releases and main; 9.x lacks the API.
Versions tested6 rows
Introduced by #13779 "First-class random access API for KnnVectorValues" (@msokolov, merged 2024-09-28 as 6053e1e3137, milestone 10.0.0). git log -S'return ord;' on the file returns only it and bfe5c847d3c (#16383, FLOAT16, 2026-07-27; on main and branch_11x, in no release); git blame gives the float return ord; line to it at 10.0.0, 10.5.2, 10.6.0 and 645d4fe14a20. Not a regression: before 10.0.0 these values had no ordinal-to-document method. Not fixed on upstream main f815e679bf6c (2026-11-01), branch_11x or branch_10_6 (read).
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails, assertions on and off (gradle and standalone) |
| 10.6.0 | affected | fails, assertions on and off (10.x form of the test) |
| 10.0.0 to 10.5.2 (12 releases) | affected | fails on each, the same [0->0, 2->1, 3->2] (10.0.0 also with assertions off) |
| 10.0.0 with only the identity line replaced | fix control | passes: the failure is that one line |
| 9.12.0, 9.12.3 | API absent | the test does not compile: KnnVectorValues does not exist |
| fix A (cached mapping) | not affected | the minimal test passes; related suites pass |
The finder, an independent reproducer, a devil's-advocate verifier, cross-model reviews (OpenAI GPT-5.6) and an adjudication agree on the root cause. The first refute review said not real only because it could not run Java; its executed re-run on 2026-11-01 said real (high).
Checks and verdicts267 words
Every executed check reproduced the identity mapping; the debate is only about whether the hook's values were meant to be forward-only.
| Check | Verdict | What it found |
|---|---|---|
| finder (bounded-exhaustive harness, then JUnit) | reproduced | 2 tests (sparse; sparse with an index sort) fail on main (-ea, -da), 10.0.0 and 10.5.2; pass with the fix sketch. |
| cross-model review, refute lens (OpenAI GPT-5.6, reading only) | not real (low), procedural | Agreed with the root cause and the trigger; voted not real on procedure only because it could not reproduce. |
| cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Intended-behaviour argument moderate; 8 of its 11 evidence items support real. |
| independent reproducer | real | Own test, 6 tests: sparse, sparse getAcceptOrds and dense under a reversing sort fail on main (FLOAT32, BYTE, FLOAT16), 10.5.2 and 10.0.0 (-ea, -da); the controls pass. |
| devil's-advocate verifier | real | Strongest works-as-designed case moderate, not a refutation; showed the merge-time values throw from copy() and ordToDoc(0); traced the override to #13779 commit 2bbf8f1fed. |
| adjudication | confirmed, high; minor | Re-ran the independent reproduction: 3 of 6 fail with -ea and -da. |
| registry re-runs and credibility audit | reproduces | Fresh seeds: the finder's and the independent reproduction's tests fail and pass with the fix sketch; audit re-run fails 2 of 2. |
| re-verification and refute review on 645d4fe14a20 (OpenAI GPT-5.6, executed) | real (high) | The minimal test fails on main, 10.5.2 and 10.6.0 (-ea, -da); the reviewer's own sparse and sorted tests reproduced it and its dense control passed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 420 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,417 words
- Registry title
- BufferingKnnVectorsWriter hands writeField vector values whose ordToDoc(ord) returns ord, which is wrong for sparse fields and, with an index sort, for every field (latent: no shipped writer calls it)
- Area
- codecs / BufferingKnnVectorsWriter flush-time vector values (KnnVectorValues.ordToDoc and getAcceptOrds)
- Priority
- Low, rank 1202: BufferingKnnVectorsWriter's ordToDoc is wrong for sparse or sorted fields, but no shipped or known writer calls it.
- Impact class
- minor
- Impact note
- Only third-party vector codecs that extend the public, @lucene.experimental BufferingKnnVectorsWriter and call ordToDoc or getAcceptOrds on the values their writeField receives at flush are hit, on 10.0.0 to 10.6.0 and main, with -ea and -da, at any index size: for a field that some documents lack, or for any field when the index has an index sort, they silently get a wrong document id (and getAcceptOrds filters the wrong vectors); no shipped Lucene codec is affected, because SimpleTextKnnVectorsWriter (the only shipped subclass) and the backward-codecs test writers only iterate, no such third-party writer is known, and the merge-time values passed to the same writeField throw UnsupportedOperationException from ordToDoc, so such a writer would also fail at its first merge unless it overrides mergeOneField.
- Summary
- You build a vector codec on BufferingKnnVectorsWriter and, in writeField, ask the flush-time vector values which document a vector ordinal belongs to (ordToDoc, or getAcceptOrds, which is built on it), expecting what the javadoc promises, 'the docid of the document indexed with the given vector ordinal'. Instead the buffered values answer ordToDoc(ord) = ord, which is right only when every document has a vector and there is no index sort: for a field that documents 0, 2 and 3 have, ordinals 1 and 2 map to documents 1 and 2 instead of 2 and 3, so a getAcceptOrds filter that accepts only document 2 accepts document 3's vector and one that accepts only document 3 accepts none; under a reversing index sort even a dense field's ordinals map to themselves instead of to their documents' sorted positions. Iteration (nextDoc, index, vectorValue) stays correct, nothing throws, and FLOAT32, BYTE and FLOAT16 behave the same.
- Introduced
- 6053e1e31378378f6d310a05ea6d7dcdfc45f48b (#13779 'First-class random access API for KnnVectorValues', author msokolov, merged into main 2024-09-28, milestone 10.0.0) [read: git log -S and git blame in the full-history clone, the float values' 'return ord;' line blames to it at 10.0.0, 10.5.2 and main, and git tag --contains lists exactly the 12 10.x release tags; exec: the API is absent on 9.12.3 and the repro fails on 10.0.0]. Inside the PR (commits read through the read-only GitHub API, not built): 2bbf8f1fed (2024-09-02, 'adding some ordToDoc') gave BufferedFloatVectorValues ordToDoc(ord) { return ord; } while the base ordToDoc still threw UnsupportedOperationException; dce766c975 (2024-09-05) made the base default return ord, documented as right for dense values; ff7a317a81 (2024-09-12, 'fix case where index is reordered') made the sorting views hand out ordinals in the delegate's ordinal space without an ordToDoc override. Later extension: bfe5c847d3c4 (#16383, fp16 vector encoding, 2026-07-27; on main and branch_11x, in no release) copied the identity override to BufferedFloat16VectorValues and added SortingFloat16VectorValues without one. The defect came with the API; it is not a regression, because before 10.0.0 these values had no ordinal-to-document method (2024-09-28 (merge of #13779; the identity override was written in its commit 2bbf8f1fed on 2024-09-02); FLOAT16 copy 2026-07-27 (#16383; on main and branch_11x, in no release))
- First affected version
- 10.0.0 [exec] (the first release with #13779); 9.x is not applicable: no KnnVectorValues class and no ordToDoc on these values [exec: on 9.12.3 the repro does not compile and an API-absence probe passes 2 of 2]
- Affected versions
- every 10.x release (10.0.0, 10.1.0, 10.2.0, 10.2.1, 10.2.2, 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2, 10.6.0) and main (ea57360912ed and 645d4fe14a20) [exec: the minimal test fails on all 13 10.x release jars and on main 645d4fe14a20 (-ea; also -da on 10.0.0, 10.6.0 and main); the finder repro fails 2 of 2 on each of the 12 releases before 10.6.0 and on main ea57360912ed, with -da as well on 10.0.0, 10.5.2 and main, and 2 of 2 on 10.6.0 and main 645d4fe14a20; the independent reproduction's own test fails 3 of 6 on main, 10.5.2 and 10.0.0 with -ea and -da]; the FLOAT16 classes exist on main and branch_11x only, in no release (#16383) [exec on main by the independent reproduction]; not affected: 9.x and earlier, where the API does not exist [exec 9.12.3]; not fixed: upstream main cb19aecba8f3 (2026-10-26) has not changed BufferingKnnVectorsWriter.java since #16383 [read]; unreleased maintenance branches not checked
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26: 212 logged queries, namely 96 GitHub issue and PR queries (a scripted prior-report search and GraphQL phrasings over apache/lucene, downstream repositories, all of GitHub), 7 commit queries, 2 downstream-repo queries, 80 mailing-list queries over dev@, java-user@, issues@ and commits@, 17 JIRA-archive queries and 10 web queries; 45 GitHub items read in full, the touched files of all 412 open apache/lucene PRs, the upstream commit history of the affected files, LUCENE-10592, LUCENE-9322 and LUCENE-9674; 26 hits judged, none the same bug; the independent reproduction and the intended-behaviour check found nothing either); not fixed upstream (upstream main cb19aecba8f3, 2026-10-26, has not changed BufferingKnnVectorsWriter.java since #16383; the only open PR that touches the file, #12636, is a 2023 rename that does not touch ordToDoc); closest items, not reports: #13842 / #13839 (merged 2024-10-01 for 10.0.0: a precedent of the same class of bug at a different site, SimpleTextKnnVectorsReader's sparse byte values inheriting the identity ordToDoc, fixed in that reader only), #13779 (the introducing PR; no review comment on these overrides), #16205 (closed unmerged, a reader-side getAcceptOrds default refactor), Elasticsearch #137862 and OpenSearch k-NN #3196 (the same pitfall in downstream wrappers, not in Lucene's writer)
- Lucene commit tested
- main
645d4fe14a20(2026-11-01): the minimal test fails through gradle in a scratch worktree with assertions on and off, and standalone on main (-ea,-da) and on all 13 10.x release jars, 10.0.0 to 10.6.0 (10.0.0 and 10.6.0 also-da); 9.12.0 and 9.12.3 lack the API. With the recommended fix it passes, together withTestSimpleTextKnnVectorsFormatand the three backward-codecs HNSW format suites (231 tests together, 13 of them skipped) and the core lint of the fixed file (eclint is not configured here and was skipped); the study's wider test (sparse,getAcceptOrds, reversing index sort, three encodings) passes with the fix too.BufferingKnnVectorsWriter.javais identical atea57360912ed, where the hunt ran; upstream mainf815e679bf6c(2026-11-01) still returns the ordinal (read).
- Finding record
lucene/core/src/java/org/apache/lucene/codecs/BufferingKnnVectorsWriter.java:36-43 (at ea57360912ed) (class javadoc 'Used for SimpleTextKnnVectorsWriter and for vectors writers before v 9.3', @lucene.experimental), :137-250 (private Sorting{Float,Float16,Byte}VectorValues, no ordToDoc override), :283-294 (protected abstract writeField hooks, javadoc 'Write the provided ... vector field', no forward-only restriction), :341-369 (BufferedFloatVectorValues: iterator = fromDISI(docsWithField.iterator()), ordToDoc returns ord at :366-369), :412-415 (BufferedFloat16VectorValues.ordToDoc returns ord), :433-472 (BufferedByteVectorValues, inherits the default)lucene/core/src/java/org/apache/lucene/index/KnnVectorValues.java:43-50 (at ea57360912ed) (ordToDoc javadoc 'Return the docid of the document indexed with the given vector ordinal. This default implementation returns the argument and is appropriate for dense values implementations where every doc has a single value.'), :109-127 (getAcceptOrds built on ordToDoc, FIXME 'provide this impl somewhere more specialized (in every non-dense impl)')lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:494-500 (at ea57360912ed) (merged values: ordToDoc throws UnsupportedOperationException; also :596 and :698 per the independent reproduction)
- The finding in 30 seconds
lucene/core/src/java/org/apache/lucene/codecs/BufferingKnnVectorsWriter.java:90-134, 137-250, 262-281, 310-322, 341-385 (iterator :353, ordToDoc :366-369), 387-431 (ordToDoc :412-415), 433-472 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/KnnVectorValues.java:43-50, 110-127, 187-213 (fromDISI) (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/index/SortingCodecReader.java:244-266 (iteratorSupplier), 268-308 (SortingValuesIterator, index() :286-290) (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:476-485, 497-510, 596-597, 698-699 (at 645d4fe14a20)
- Who is affected
lucene/core/src/java/org/apache/lucene/codecs/BufferingKnnVectorsWriter.java:38-44, 262-281 (at 645d4fe14a20); lucene/codecs/src/java/org/apache/lucene/codecs/simpletext/SimpleTextKnnVectorsWriter.java:75-130 (at 645d4fe14a20)lucene/backward-codecs/src/test/org/apache/lucene/backward_codecs/lucene92/Lucene92HnswVectorsWriter.java:194-208, 253-266 (at 645d4fe14a20); grep 'extends BufferingKnnVectorsWriter' over lucene/ (4 subclasses)
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/index/KnnVectorValues.java:43-50 (at 645d4fe14a20); lucene/core/src/java/org/apache/lucene/codecs/BufferingKnnVectorsWriter.java:283-293, 353, 366-369 (at 645d4fe14a20); lucene/MIGRATE.md:1725-1727 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/codecs/KnnVectorsWriter.java:311, 476-485, 497-510 (at 645d4fe14a20)
- TestBufferingKnnVectorsWriterOrdToDoc.java:
repro/LFV-298/src/org/apache/lucene/codecs/TestBufferingKnnVectorsWriterOrdToDoc.java(105 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output.
assets/LFV-298/bug.png(420 KB)