Inside a <!-- --> section of a script or style block the filter treats every quote as a string delimiter, and a string ends only at its matching quote. An apostrophe in a comment never gets one, so -->, the end tag and the text after them are consumed without output, and at the end of input the filter just stops.
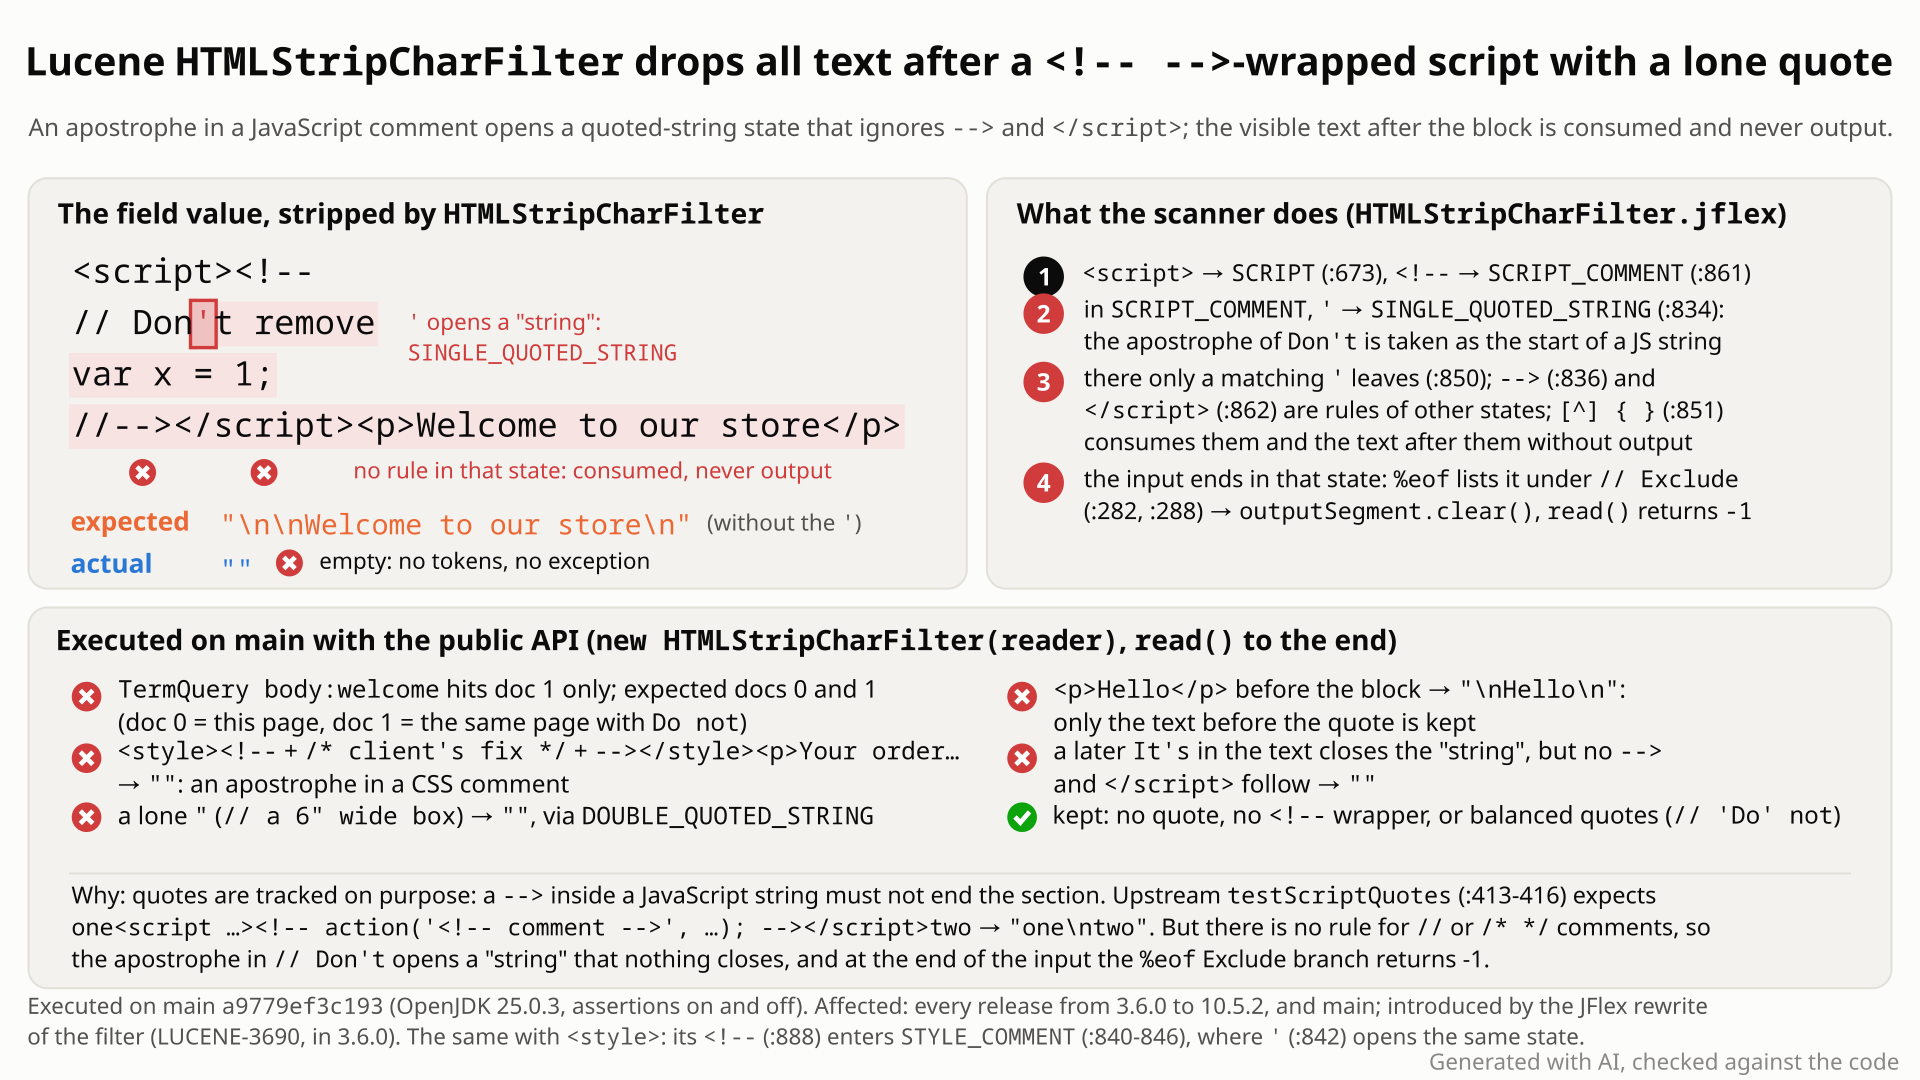
<!-- -->-wrapped script with // Don't remove, the lexical states the scanner passes through with the grammar lines involved, and the output with and without the apostrophe. Select the still to open it at full size. Generated with AI, checked against the code.- Strip a page whose script code is wrapped in the old
<!-- -->idiom, one line each:<script><!--,// Do not remove,var x = 1;,//--></script>,<p>Welcome to our store</p>.HTMLStripCharFilterreturns "Welcome to our store": the script is removed, the paragraph kept. - Change the JavaScript comment to
// Don't remove. The script is removed either way, so you expect the same "Welcome to our store". - You get an empty string. Inside a
<!-- -->-wrapped script the filter treats a quote as the start of a JavaScript string, and inside that "string" it ignores-->and</script>. - Everything after the apostrophe is read as part of that "string" and produces no output; the input ends still inside it, and at end of input the filter just ends the stream, with nothing that gives the text back. Through an analyzer the value gives 0 tokens instead of 4, so a search for "store" misses the document. No error.
- The same with an apostrophe in a CSS comment (
/* Outlook's spacing fix */) or a lone". One such line added to upstream's own test page cuts its text from 637 words to 15.
Anyone who strips HTML with HTMLStripCharFilter (directly, through the htmlStrip factory, or a downstream html_strip wrapper), at its default settings, on HTML that wraps script or style code in <!-- --> and has a lone quote there. Any index size; the loss runs to the end of that field value and nothing else is touched.
Mechanism, terms and numbers719 words
An old HTML idiom wraps the code of a <script> or <style> block in <!-- ... --> (upstream's own test fixture htmlStripReaderTest.html does). Inside such a section HTMLStripCharFilter tracks JavaScript/CSS string literals, so that a quoted --> or </script> cannot end the block, but it knows nothing about JavaScript or CSS comments or line ends. An apostrophe in // Don't remove or /* Outlook's spacing fix */, or a lone ", therefore opens a "string" that runs past the closing --> and the end tag. A string state consumes everything after the quote without output; if no matching quote follows, the input ends in that state and the %eof handler just ends the stream, so the visible text after the correctly closed block never reaches the tokenizer, the field is indexed without it, and nothing reports an error. In the executed controls, the same block without the quote, without the wrapper, or with balanced quotes keeps the text. The rules date from the JFlex rewrite of the filter (LUCENE-3690, 2012) and are unchanged; every release from 3.6.0 to 10.6.0 (10.6.0 by reading) and main is affected. The filter it replaced kept this text: it rolled back when it could not match a tag and its end tag.
HTMLStripCharFilter: aCharFilterin analysis-common that removes HTML markup before tokenization. It is generated by JFlex fromHTMLStripCharFilter.jflex; the scanner moves between named lexical states.- The
<!-- -->wrapper: an old idiom that hides script or style code from very old browsers:<script><!-- ... //--></script>,<style><!-- ... --></style>. It is valid HTML and browsers show the text after the block.
What happens to <script type="text/javascript"><!--\n// Don't remove\nvar x = 1;\n//--></script><p>Welcome to our store</p>
Line numbers are HTMLStripCharFilter.jflex at a9779ef3c193.
<script ...>entersSCRIPT. Script content is dropped and the end tag becomes one newline (SCRIPT_REPLACEMENT,:153; end-tag rule:862).<!--insideSCRIPTentersSCRIPT_COMMENT(:860-861; for style::887-888entersSTYLE_COMMENT).- In
SCRIPT_COMMENT(:832-838)'entersSINGLE_QUOTED_STRING(:834) and"entersDOUBLE_QUOTED_STRING(:835). The only direct route back toSCRIPTis an unquoted-->(:836;<!--#enters a server-side include,:833, that returns toSCRIPT_COMMENTat its own-->,:818); there is no rule for//or/* */comments and none for</script>.STYLE_COMMENTis the same (:840-846). SINGLE_QUOTED_STRING(:848-852) ends only at the next'(:850); a backslash escapes one character (:849) and every other character, including line breaks,-->,</script>,<p>and the text, is consumed by[^] { }(:851).DOUBLE_QUOTED_STRINGis the same for"(:854-858).- With no second apostrophe the input ends inside the string. Nothing after the apostrophe was output: the string state consumed it with
[^] { }.%eof(:275-296) listsSCRIPT_COMMENT,STYLE_COMMENT,SINGLE_QUOTED_STRINGandDOUBLE_QUOTED_STRING(:279-283) in the branch marked// Exclude(:288), which only corrects the offsets, clearsoutputSegment(:293) and ends the stream (:294). No fallback re-reads the consumed input as text, so everything from the apostrophe on is lost.
A later quote, such as Tom's in the body text, ends the "string" there, but the scanner then still needs an unquoted --> and an end tag, so the text after it is usually lost too: <script><!--\n// it's fine\n//--></script><p>Tom's book</p><p>after</p> strips to "".
- The same block keeps the text without the quote, without the
<!-- -->wrapper (outside a<!--sectionSCRIPTandSTYLEdo not track quotes), or with balanced quotes (var s = "Don't";). Text before the block survives (<p>before</p>stays). - Any literal
<!--in script or style text opens the quote-tracking section, wrapper or not: an unwrapped inline scriptvar author = 'Bob<!--';also drops the paragraph after it (the sub-trigger below). - A weaker sub-trigger, best presented as an open question: an unterminated
<!--inside a script,<p>before</p><script>a<!--</script><p>after</p>, strips to"\nbefore\n", becauseSCRIPT_COMMENThas no end-tag rule. The pre-3.6 filter skipped end tags inside script comments on purpose (its code comment cites<script><!-- </script> -->foo</script>), so a committer may call this one intended.
Exposure and likelihood255 words
- Entry points.
new HTMLStripCharFilter(reader)in an analyzer'sinitReader, thehtmlStripchar filter factory (HTMLStripCharFilterFactory.NAME, for example inCustomAnalyzer), and downstream wrappers of the filter (by code reading, nothing run: Solr'sHTMLStripCharFilterFactoryandHTMLStripFieldUpdateProcessorFactory, thehtml_stripchar filter and ingest processor of Elasticsearch and OpenSearch). - Default vs opt-in. No Lucene analyzer adds the filter, so using it is a choice; the bug then needs no non-default setting of the filter.
- Inputs. Legacy-style HTML: the
<!-- -->wrapper inside script or style blocks is an old idiom (upstream's own fixturehtmlStripReaderTest.htmlandtestStyleuse it; how common it is in current corpora was not surveyed), and the trigger is an ordinary apostrophe or inch sign in a comment. One inserted line// don't cache this valuein that fixture cuts the stripped output from 637 words (4,869 characters) to 15 (246 characters). - Scale and scope. Any index size; per field value. The loss runs from the quote to the end of the value, unless a later quote, an unquoted
-->and an end tag let the scanner resynchronise. Other values, fields and documents are unaffected,CheckIndexis clean, offsets stay valid, and if the application stores the original HTML, the stored value still shows text that search cannot find (one that stores the stripped value loses it there too). - Likelihood: rare. The combination is uncommon in current HTML and the prior-report searches found no report since 2012, but a silent loss like this can go unnoticed in large crawled or e-mail corpora.
The test shows that an apostrophe in a JavaScript comment inside a <!-- -->-wrapped <script> block makes HTMLStripCharFilter drop all text after the block.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.charfilter;

import java.io.Reader;
import java.io.StringReader;
import java.io.StringWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHTMLStripQuoteInScriptComment extends LuceneTestCase {

  public void testApostropheInWrappedScriptComment() throws Exception {
    String html = "<script><!--\n// Don't remove\n//--></script><p>Welcome to our store</p>";
    StringWriter out = new StringWriter();
    try (Reader r = new HTMLStripCharFilter(new StringReader(html))) {
      r.transferTo(out);
    }
    assertTrue(
        "expected the text after </script> to be kept, actual output: [" + out + "]",
        out.toString().contains("Welcome to our store"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-311/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.charfilter.TestHTMLStripQuoteInScriptComment
- Expected vs actual
- Expected the output of
<script><!--\n// Don't remove\n//--></script><p>Welcome to our store</p>to containWelcome to our store; actual output: the empty string, with-eaand-da.
More files, environment, full output40 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected the text after </script> to be kept, actual output: []
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.assertTrue(Assert.java:42)
org.apache.lucene.analysis.charfilter.TestHTMLStripQuoteInScriptComment.testApostropheInWrappedScriptComment(TestHTMLStripQuoteInScriptComment.java:32)- The class "attempts to strip out HTML constructs"; the text after a closed
</script>is not one. - Upstream tests expect the text after a
<!-- -->-wrapped block to survive; every quote test uses balanced quotes. - The filter it replaced in 3.6 kept this text, and #15754 fixed the same kind of loss elsewhere in the filter as a bug.
The full argument404 words
- Contract. Class javadoc (
HTMLStripCharFilter.jflex:31): "A CharFilter that wraps another Reader and attempts to strip out HTML constructs." Text after a correctly closed</script>or</style>is document text, not a construct. - Upstream tests.
TestHTMLStripCharFilter.testStyle(:431-440) stripsone<style type="text/css">\n<!--\n@import url('...');\n-->\n</style>twotoone\ntwo;testScriptQuotescase 1 (:414-417) strips a wrapped script with quoted<!-- comment -->and\"-->\"toone\ntwo. Every test of the quote tracking uses balanced quotes; we found no test, code comment, CHANGES or MIGRATE entry that accepts losing the rest of the document after a closed element. - Design intent. In LUCENE-3690 (GitHub #4764), which introduced the JFlex filter, its author (@sarowe) stated the goal "get as much content from as varied a range of sources as possible, and never ever allow the input to bork processing" and called its bad-HTML handling "a superset" of the old filter's. The Solr 3.6.0 CHANGES list of behaviour changes for it does not mention dropping text after a script or style block.
- The predecessor kept the text. The hand-written Solr filter it replaced (kept as
LegacyHTMLStripCharFilter) also tracked quotes in script comments, but its look-ahead was bounded, and when it could not match a tag and its end tag it rolled back and emitted the input as text (for an unterminated string in script code itsfindEndTagnotes "what to do about a non-match (non-terminated string?) play it safe and index the rest of the data I guess..."). Executed on the two finder inputs it keeps "Welcome to our store" and "Your order has shipped." (with a stray<), while 4.10.4 and main return"". - Precedent. GITHUB#15754 (10.5.0, "prevent tags from incorrectly consuming subsequent HTML when an attribute value ends with an equals sign") fixed the same symptom, a scanner state swallowing the text after it, as a bug. GITHUB#11556 (9.9.0) is not a second example: there
<or>in an attribute value stopped tag recognition and leaked markup into the output, and the text after the tag survived (executed on the 9.8.0 jars). The loss #15754 fixed first appeared in 9.9.0, with the #11556 fix (an input of that shape keeps its text on 9.8.0 and loses part of it on 9.9.0). - Separable. The recommended fix keeps both
testScriptQuotescases,testCommentand the rest of analysis-common passing (0 failures, 18 skipped), so the deliberate quote tracking and this loss can be told apart.
The devil's-advocate check171 words
The strongest case for "intended": the filter is best effort ("attempts to"); quote tracking inside script comments is deliberate and tested (testScriptQuotes case 2, :419-421, keeps a quoted </script> inside a script comment from ending the script, so upstream knowingly removes some text a browser would show); and dropping input at end of input in these states is explicit in %eof (its Exclude branch also covers SCRIPT, STYLE, COMMENT and the tag-tail states, :277-288, so this is a general policy), with testComment (:321-334) asserting that an unterminated <!-- strips to "".
Why it fails: best effort covers ambiguous or broken markup, while this input is valid HTML with every construct closed; the scanner just misreads where the comment ends. The quote tracking exists to keep a quoted --> or </script> from ending the block, and all its tests use balanced quotes. The end-of-input exclusion is right for genuinely unterminated constructs, which is all testComment asserts. The recommended fix shows the two are separable.
Recommended A. Make the script/style comment states aware of JavaScript and CSS comments and line ends
Teach the two comment states about JavaScript and CSS comments: // runs to the end of its line, /* */ to */ (or -->), and a string opened there ends at a line break. +41 grammar lines; the repro and the module checks pass, analysis-common has 0 failures (1,914 tests, 18 skipped), and the cost stays linear.
All options and trade-offs4 options · 1,136 words
Every option except C was applied to a scratch worktree at a9779ef3c193, the scanner regenerated with ./gradlew :lucene:analysis:common:regenerateHTMLStripCharFilter (which also updates src/generated/checksums/regenerateHTMLStripCharFilter.json), and run through gradle with -Ptests.asserts=true and =false; the regenerated scanners were also shadowed into the stock jars to run the hunt's repros and probes. C and D were run by the hunt at ea57360912ed, where the grammar is the same. Options A and B were re-run on 2026-10-27 after a backslash-CRLF rule was added to their string states (the first revision lacked it); the earlier revision is kept. Every command is in the fix folder's commands.txt.
A. Make the script/style comment states aware of JavaScript and CSS comments and line ends (validated by the checks) (recommended)
optionA-comment-states.diff: HTMLStripCharFilter.jflex +41 lines and one new TestHTMLStripCharFilter method. In SCRIPT_COMMENT, // enters a new SCRIPT_LINE_COMMENT state that ends at a line break (back to SCRIPT_COMMENT) or at --> (to SCRIPT, so the usual //--> still closes). In SCRIPT_COMMENT and STYLE_COMMENT, /* enters a new block-comment state that ends at */ or, as a safety net for an unterminated /*, at -->. In the two quoted-string states, a CR or LF ends a string that was opened from a script or style comment section: neither JavaScript nor CSS strings can contain an unescaped line break. A backslash before LF or CR is still consumed by the existing escape rule, and a new rule consumes a backslash before CRLF (without it the escape rule would take only the CR, and the LF would end the string early and expose a quoted --> or </script>); strings opened from server-side includes are unchanged. The three new states join the %eof Exclude list; like the existing states they use fixed-length rules (at most three characters) with a one-character fallback, so the scan stays linear.
<SCRIPT_COMMENT> {          // STYLE_COMMENT: the same without "//"
  ...                       // the existing quote and "-->" rules
  "//"    { yybegin(SCRIPT_LINE_COMMENT); }
  "/*"    { yybegin(SCRIPT_BLOCK_COMMENT); }
}
<SCRIPT_LINE_COMMENT>  { [\r\n] { yybegin(SCRIPT_COMMENT); }  "-->" { yybegin(SCRIPT); }  [^] { } }
<SCRIPT_BLOCK_COMMENT> { "*/"   { yybegin(SCRIPT_COMMENT); }  "-->" { yybegin(SCRIPT); }  [^] { } }
<SINGLE_QUOTED_STRING> {    // and DOUBLE_QUOTED_STRING
  "\\" [^] { }               // existing escape rule
  "\\" "\r\n" { }            // new: a backslash before CRLF continues the string
  ...
  [\r\n] { if (restoreState == SCRIPT_COMMENT || restoreState == STYLE_COMMENT) {
             yybegin(restoreState); restoreState = previousRestoreState; } }
  [^] { }
}
Trade-offs
It is still not a JavaScript lexer: a regex literal or a division followed by * can be read as a comment start (it then ends at */ or -->), and template literals (backticks) are not tracked. An unbalanced quote in code, not a comment, on the same line as --> and the end tag, in a value with no later line break, still loses the rest as today (<script><!-- var a = "6 wide; --></script><p>after</p> gives ""). Only CR and LF end a string; U+2028, U+2029 and the CSS form feed do not (not tested). It does not cover the unterminated-<!-- sub-trigger (option B).
What the checks validated
Gradle, assertions on and off: the repro 4 of 4; the charfilter package (TestHTMLStripCharFilter 37 with the new method and both testScriptQuotes cases, Factory 7, the mapping suites 20); all of :lucene:analysis:common:test (340 suites, 1,914 tests, 18 skipped, 0 failures); :lucene:analysis:common:check -x test (checksum checks, google-java-format, ecjLint, forbiddenApis). Shadowed into the stock jars: the finder's JUnit 4 of 4; the verifier's file 9 of 10 (only the unterminated-<!-- test fails); the hunt's 8-test reach probe 7 of 8, including its linear-time test on a 100M-character stream at -Xmx128m (the remaining failure is a one-line page with 'Bob<!--' in an unwrapped inline script string, the sub-trigger again); an unterminated /* repeated over 12.5k-100k characters takes 1.3-4.3 ms with no growth (stock 1.4-3.9 ms); the mutated upstream fixture strips to the same 637 words as the original; a backslash before LF or CRLF inside a string keeps a quoted --> and </script> protected, as on stock (CRLF probe; the first revision leaked ';\r\n--> there). All re-run on 2026-10-27 with the backslash-CRLF rule.
B. Add-on to A for the open question: an end tag outside a string closes the element (validated by the checks)
optionAB-comment-states-plus-end-tag.diff: A plus 10 grammar lines and one test method. In SCRIPT_COMMENT and the new script comment states, "</" \s* [sS][cC][rR][iI][pP][tT] \s* ">" { yypushback(yylength()); yybegin(SCRIPT); } (the same for style), so the existing SCRIPT/STYLE rule matches the end tag again. It fixes <script>a<!--</script><p>after</p>.
Trade-offs
It reverses the predecessor's deliberate rule that a </script> inside a script comment is not an end tag: <script><!-- </script> -->foo</script>bar gives "\nbar" today and "\n -->foo\nbar" with B (the first </script> then ends the element; no browser comparison was run). No upstream test pins that case, but a committer may prefer to keep it. B is not fully HTML5-style: a quoted </script> inside the comment section still does not end the element (only option C does that).
What the checks validated
Re-run with A's backslash-CRLF rule. Gradle, assertions on and off: all of analysis-common (1,915 tests, 18 skipped, 0 failures); check -x test passes. Shadowed: the verifier's file 10 of 10; the reach probe still 7 of 8 (in the one-line 'Bob<!--' page the template's closing quote opens a string before </script>); cost 1.4-4.4 ms, no growth.
C. HTML5-style: the first end tag always closes the script or style element (validated by the checks)
Delete the two "<!--" rules in SCRIPT and STYLE, so script and style content is never treated as a comment section.
Trade-offs
Fixes every trigger seen, but reverses a tested decision: testScriptQuotes case 2 (a quoted </script> inside a script comment) then outputs hello\n'); -->\n instead of hello\n. Worth proposing only if committers want HTML5 behaviour.
What the checks validated
By the hunt at ea57360912ed (same grammar), not re-run here: the verifier's file 10 of 10, the reach probe 8 of 8, linear on the probe's inputs; TestHTMLStripCharFilter 36 tests, 1 failure (testScriptQuotes).
The hunt's first sketch skipped /* ... */ with one look-ahead rule and ended strings at line breaks.
Trade-offs
Quadratic on an unterminated /*: 6.8 s at 100,031 characters against 0.8 ms on stock, and out of memory on a 100M-character stream at -Xmx128m. It also misses the one-line <script><!-- // don't --></script>. Option A replaces it with explicit states.
What the checks validated
By the hunt at ea57360912ed: the 43 TestHTMLStripCharFilter and Factory tests pass, the verifier's file 9 of 10; the cost probe shows the quadratic growth (ratio about 4 per doubling).
Downstream products that strip HTML with this filter (Solr's htmlStrip, the html_strip char filter of Elasticsearch and OpenSearch) inherit the loss, so a keyword rule that relies on a field not containing a word can miss the hidden text.
Code reading of the grammar's script and style states while building a fixed-seed, grammar-based fuzzer that generates well-formed HTML and checks that every plain-text word survives stripping. Script or style text with a quote or an open <!-- was the dominant loss class; a public-API JUnit then reproduced it on the stock jar.
The method in full167 words
Method: code reading during a fuzzing hunt (a hunt unit, analysis char filters, 2026-10-26, main ea57360912ed). No model checker, SMT solver or prover was involved.
- An AI tool (the finder) read the
SCRIPT,STYLEand comment states ofHTMLStripCharFilter.jflexwhile buildingHtmlLossFuzz, a fixed-seed fuzzer that generates random documents well formed under the HTML5 tokenizer rules, with script and style raw text over an alphabet of quotes,<!--,-->,//and/*. Its oracle: every plain-text word between constructs must appear in the output; each loss is minimised to one construct. - On the stock filter, raw text with a quote or an open
<!--was the dominant loss class (8,977 of 100,000 documents lost text across all loss classes, seed 1, including other HTMLStripCharFilter bugs). With quote-free, closed<!-- -->sections and the attribute triggers excluded, 1,000,000 documents lost nothing. - The finder then wrote the public-API JUnit, which fails 3 of 4 on the stock jar with
-eaand-da.
No prior report found (2026-10-26): 77 queries of a scripted prior-report search over GitHub, JIRA, the mailing lists and downstream projects, at least 60 direct GitHub searches, JIRA, web and Q&A searches, and the changed files of all 411 open PRs. Not fixed upstream (re-checked 2026-10-27); #15754 fixed the same kind of loss elsewhere in the filter.
Searches5 searches
None of the searched issues, PRs, commits, JIRA entries, list threads or downstream reports describes text lost after a <!-- -->-wrapped script or style block, or the comment states' quote tracking swallowing --> and the end tag. The nearest item, #15754, has the same symptom but another trigger and fix site (an attribute value) and is a precedent rather than a duplicate; #11556 (attribute values leaking markup) is a different symptom. Gaps: GitHub's search rate limit was reached, and lists.apache.org was the only list archive searched; word-based searches show what was found, not that no report exists anywhere.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | a scripted prior-report search (26 issue/PR, 3 commit and 2 downstream queries), at least 60 direct GitHub searches (60 recorded in the prior-report record) (class names, SCRIPT_COMMENT, script/style comment, apostrophe, quote, drops text), 4 gh CLI searches | no report; nearest #15754 / PR #15756 (an attribute value ending in = swallowing later HTML, fixed), #11556 / PR #11724 (< or > in attribute values leaking markup, fixed; a different symptom), #4764 / LUCENE-3690 (the introducing change), #6802 and #6825 (open feature requests), #14089 (offsets question) |
| Open PRs | 2026-10-26 | the changed files of all 411 open apache/lucene PRs (the three with more than 100 files through the REST file list) | none touches HTMLStripCharFilter.jflex or .java; #13157 (an attribute regression test) is the only one touching an HTMLStrip file |
| Upstream main and open PRs (re-check) | 2026-10-27 | gh api: the latest commits touching HTMLStripCharFilter.jflex and the head of main; gh search prs --state open HTMLStripCharFilter | main at a95c754ee003 (2026-10-26); the last .jflex commit is still 02014a6245d3 (#15756, 2026-03-03), older than a9779ef3c193; no open PR |
| JIRA archive and mailing lists | 2026-10-26 | the scripted prior-report search's 6 JIRA and 40 list queries over dev@, java-user@, issues@, commits@ and solr-user@, 5 direct JIRA queries and about 20 issue reads (LUCENE, SOLR) | no report; SOLR-2328 (won't fix, invalid HTML), SOLR-10337 (cannot reproduce, the opposite symptom), SOLR-5983 (unclosed CDATA, other states); solr-user threads about configuration and offsets |
| Downstream and web | 2026-10-26 | GitHub searches over Elasticsearch, OpenSearch, Solr and Lucene.NET; 16 web and 9 Q&A searches | no report; OpenSearch #20554 / #20575 (the #15754 attribute case downstream), Elasticsearch #15543 (escaped_tags docs) |
Present since the JFlex rewrite of the filter (LUCENE-3690, 2012), first released in 3.6.0; the rules never changed. Fails on all 15 releases run from 3.6.0 to 10.5.2 and on main. The hand-written filter it replaced kept the text. Not fixed upstream.
Versions tested8 rows
Introduced by LUCENE-3690 (GitHub #4764, "JFlex-based HTMLStripCharFilter replacement", @sarowe; a JIRA patch, no PR): trunk commit f3a363708ff (svn r1234452, 2012-01-22) and its branch_3x backport d387ae60fcf (svn r1235308, 2012-01-24). git blame -w -M -C -C and git log -L give f3a363708ff for every rule involved; the later commits on %eof (ada9780484e, comments; af831d28105, an (int) cast) did not change the excluded states. All 126 release tags that carry the .jflex have the trigger rules.
A regression against the predecessor, not within the JFlex scanner. Solr's hand-written filter (3.5.0 and earlier, kept as LegacyHTMLStripCharFilter) also tracked quotes in script comments but rolled back when it could not match a tag and its end tag, and kept the text; the Solr 3.6.0 CHANGES entry for the rewrite does not mention this change. On 2026-10-27 upstream main (a95c754ee003) still had the .jflex of a9779ef3c193 (last change 02014a6245d3, #15756), and no open PR mentions the filter.
| Version or commit | Verdict | Result |
|---|---|---|
| 3.5.0 | no class | no Lucene HTMLStripCharFilter (compile error); Solr's predecessor filter keeps the text in all 4 trigger cases (with a stray '<') |
| 3.6.0 | first affected | 4 of 4 trigger cases output nothing; 4 of 4 controls keep the text |
| 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0 | affected | the same |
| 9.8.0, 9.9.0, 9.10.0 | affected | only the finder's one-input version probe ran (the script-comment apostrophe): text lost |
| 9.12.3, 10.0.0, 10.5.2 | affected | the same; the finder's JUnit fails 3 of 4 |
| main ea57360912ed | affected | the finder's JUnit 3 of 4 and the verifier's 6 of 10 fail, -ea and -da |
| main a9779ef3c193 | affected | the doc's test fails 3 of 4 through gradle (assertions on and off) and the harness (-ea, -da) |
| main a9779ef3c193 with option A | fix | the doc's test 4 of 4; analysis-common 1,914 tests, 18 skipped, 0 failures |
An independent reproducer, a devil's advocate and an adjudication said real; an OpenAI GPT-5.6 reviewer (reading only) agreed on the root cause, said real in the intended-behaviour lens and "not real" in the refute lens only because it could not run code. This doc's test and two fixes were run through gradle.
Checks and verdicts443 words
All checks ran on main ea57360912ed unless noted; the GPT-5.6 reviews read code only. The hunt's runs used the harness with -ea and -da; this doc's gradle runs used an explicit -Ptests.asserts=true and =false.
| Check | Verdict | What it found |
|---|---|---|
| Finder (a hunt unit) | candidate | The 4-test JUnit fails 3 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; the control passes. |
| Cross-model review, intended lens (OpenAI GPT-5.6, reading only) | real (medium) | Rated the works-as-designed argument moderate and found the inputs within the contract; a separate run re-ran the repro: 3 of 4 fail. |
| Independent reproducer | real | Its own 10-test JUnit with 4 controls fails its 6 bug tests on main (-ea, -da), 10.5.2 and 9.12.3, including an indexed document a TermQuery misses. |
| The cross-model review, GPT-5.6 adversary (refute lens, reading only) | not real (low), procedural | Could not run anything and wrote that its verdict "is not a substantive demonstration that the behavior is absent"; agreed on the root cause. A separate re-run and a separate probe reproduce the loss with -ea and -da. |
| Devil's advocate | real (high; moderate for the sub-trigger) | Built the strongest intended readings and showed why each fails; the legacy filter keeps the text; one inserted line in upstream's fixture cuts 637 words to 15. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit (new seed, 6 of 10 fail) and the finder's (-da, 3 of 4); set the cross-model review aside as procedural. |
| Follow-up, registry re-runs and credibility audit | keep | History probes on 13 releases from 3.5.0 to 10.5.2 plus main, a security reach probe, re-runs with new seeds (3 of 4 and 6 of 10 fail, -ea and -da), and an audit re-run (3 of 4). |
| This doc's runs (2026-10-27, main a9779ef3c193) | reproduced; fix validated | The doc's test fails 3 of 4 through gradle (assertions on and off) and the harness (-ea, -da); with option A it passes, analysis-common runs 1,914 tests with 18 skipped and 0 failures, and the module checks pass. |
| Doc fact checks (2026-10-27): an independent re-run and an OpenAI GPT-5.6 reviewer (reading only) | corrections applied | The re-run reproduced the doc's test (3 of 4 fail, assertions on and off) and every stated output. The reviews found wording errors, now fixed: #11556 is not a same-symptom precedent, the test counts include 18 skipped tests, and the end-of-input mechanism was reworded. The GPT reviewer also found that the first revision of option A ended a string at the LF of a backslash-CRLF; a CRLF probe confirmed it, and options A and B now carry a backslash-CRLF rule and were re-validated. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 539 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,271 words
- Registry title
- HTMLStripCharFilter silently drops all text after a <!-- -->-wrapped <script> or <style> block whose content has an unbalanced quote (for example the apostrophe in a JS comment '// Don't remove' or a CSS comment '/* client's fix */'): the quote opens a quoted-string state that ignores '-->' and the end tag, and at end of input everything after the quote is removed, including the text after the closed </script> or </style>
- Area
- analysis / HTMLStripCharFilter (JFlex grammar: SCRIPT_COMMENT, STYLE_COMMENT, SINGLE_/DOUBLE_QUOTED_STRING and the %eof exclude list; also the 'htmlStrip' char filter SPI)
- Priority
- Medium, rank 127: Stock HTMLStripCharFilter silently drops all remaining text when a script or style block is wrapped in <!-- --> and contains an odd quote, so it heads the HTMLStripCharFilter text-loss group next to LFV-233.
- Impact class
- silent wrong results
- Impact note
- Applications that strip HTML with HTMLStripCharFilter (directly, through the 'htmlStrip' factory, or through a downstream html_strip char filter or strip-then-store processor; no Lucene analyzer adds it by default), at its default settings and at any index size, lose from the char-filter output, and so from the index, everything from an unbalanced quote inside a <!-- -->-wrapped script or style block to the end of the field value (unless a later matching quote and then an unquoted '-->' and end tag let the scanner resynchronise), including visible text after the correctly closed </script> or </style>; there is no exception, offsets stay valid and CheckIndex is clean, and other values, fields and documents are not affected.
- Summary
- You strip '<script><!--\n// Don't remove\nvar x = 1;\n//--></script><p>Welcome to our store</p>' with HTMLStripCharFilter and expect 'Welcome to our store', which is what you get without the apostrophe and what the filter's own tests expect after wrapped script and style blocks. Instead the output is empty: inside the <!-- --> section the apostrophe opens a quoted-string state that ignores '-->' and '</script>', and because the input ends in that state everything after the quote is dropped, so the text is never indexed and a TermQuery for a word after the block misses the document. The same happens with an apostrophe in a CSS comment of a wrapped <style> block or with a lone '"', with no error.
- Introduced
- f3a363708ff95f28b5f29fe2cc27c1cd9fd0fca9 (trunk, svn r1234452; LUCENE-3690 / GitHub #4764 'JFlex-based HTMLStripCharFilter replacement', by GitHub sarowe; SVN/JIRA era, no PR) and its branch_3x backport d387ae60fcf7ecb65596b756a0f8fc79923d0370 (svn r1235308), which shipped in 3.6.0 [read: git blame -w -M -C -C and git log -L on the '<!--' rules in SCRIPT/STYLE, the SCRIPT_COMMENT/STYLE_COMMENT quote rules, the quoted-string states and the %eof exclude list all give f3a363708ff; later commits on the %eof block (ada9780484e LUCENE-3913 comments, af831d28105 an int cast) did not change the excluded states; exec: 3.5.0 has no such Lucene class, 3.6.0 fails, and the Solr 3.5.0 predecessor filter keeps the text] (2012-01-22 (trunk, f3a363708ff); 2012-01-24 (branch_3x backport d387ae60fcf))
- First affected version
- 3.6.0 [exec] (through the branch_3x backport); on the 4.x line 4.0.0-alpha by code [read] and 4.0.0 GA [exec]
- Affected versions
- Every release from 3.6.0 to 10.6.0 (10.6.0 by reading) and main ea57360912ed. [exec] follow-up main() probe (4 trigger cases, 4 controls): 3.6.0, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) all lose the text, all controls pass; the finder's JUnit fails 3 of 4 on 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the independent reproduction's JUnit fails 6 of 10 on 9.12.3, 10.5.2 and main (-ea and -da); the intended-behaviour check's probe fails on 4.10.4; the finder's main() probe fails on 4.0.0, 6.6.6, 8.11.4, 9.0.0, 9.8.0, 9.9.0, 9.10.0, 9.12.3 and 10.0.0. [read] all 8 trigger rules are present at all 126 release tags that carry HTMLStripCharFilter.jflex. Not executed: 4.0.0-alpha and -beta (both tags carry the rules), 8.8.2-8.11.3 (not tagged in the history clone), x86 (pure scanner logic). Unaffected: Lucene 3.5.0 and earlier have no such class; Solr 3.5.0's hand-written predecessor filter keeps the text (with a stray '<') [exec]. Not fixed upstream: upstream main e1c4184cb983 (2026-10-26) has a byte-identical .jflex; branch_10x and branch_10_6 carry only the #15756 backport [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (searched 2026-10-26, read-only; the prior-report record): the scripted prior-report search (lists and JIRA run: 40 mailing-list queries over dev@, java-user@, issues@, commits@ and solr-user@, 6 JIRA queries; GitHub run: 26 apache/lucene issue/PR, 3 commit and 2 downstream queries), 60 direct GitHub searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, apache/lucenenet and all of GitHub, 4 gh CLI PR/issue searches and a changed-file scan of all 411 open apache/lucene PRs, 5 direct JIRA queries and about 20 issue reads over LUCENE and SOLR, the lists.apache.org archive, 16 web and 9 Stack Overflow queries, local git history and CHANGES.txt; the finder's, the independent reproduction's and the intended-behaviour check's own searches found nothing either. Not fixed upstream: upstream main e1c4184cb983 has a byte-identical .jflex, and no open PR touches HTMLStripCharFilter.jflex or .java (the only open PR touching an HTMLStrip file is #13157, an attribute test). Nearest items, none a report of this bug: #15754 / #15756 and #11556 / #11724 (attribute-value parsing that consumes later text: same symptom class, different trigger and fix site), OpenSearch#20554 / #20575 (the #15754 shape downstream), LUCENE-3690 / #4764 (the introducing change; design context only), SOLR-2328 (won't fix, invalid HTML), SOLR-10337 (cannot reproduce, the opposite symptom), LUCENE-5740 / #6802 and LUCENE-5763 / #6825 (open feature requests). Gaps: GitHub's search rate limit was reached (the tool's GitHub report was rebuilt offline from its cache), lists.apache.org is the only list archive searched, and 'not found' is the best available evidence, not proof.
- Lucene commit tested
- main
a9779ef3c193(2026-10-26; tested 2026-10-27;HTMLStripCharFilter.jflexand.javabyte-identical toea57360912ed): the doc's test through gradle with-Ptests.asserts=trueand=falseand through a standalone JUnit harness with-eaand-da; the fix options in a scratch worktree (regenerated scanner, the analysis-common suite with assertions on and off, the module checks; re-run after the backslash-CRLF rule was added to options A and B). Onea57360912ed(runs of 2026-10-26): the finder's and verifiers' JUnits with-eaand-da, and per-version probes on the release jars of 15 releases from 3.6.0 to 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex :30 (class javadoc 'attempts to strip out HTML constructs'), :275-296 (%eof, the '// Exclude' branch lists SCRIPT, SCRIPT_COMMENT, STYLE, STYLE_COMMENT, SINGLE_QUOTED_STRING, DOUBLE_QUOTED_STRING and clears outputSegment), :832-858 (SCRIPT_COMMENT, STYLE_COMMENT, SINGLE_/DOUBLE_QUOTED_STRING), :860-861 and :887-888 ('<!--' inside SCRIPT and STYLE)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:153, :275-296 (Exclude list :279-283, :288, :293-294), :832-858, :860-862, :887-889 (read at a9779ef3c193)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilterFactory.java:42 (NAME = "htmlStrip")lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:431-440 (testStyle uses a <!-- -->-wrapped style block)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:31 (class javadoc), :275-296 (%eof)lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:321-334 (testComment), :413-422 (testScriptQuotes), :431-440 (testStyle)lucene/CHANGES.txt:1160-1161 (GITHUB#15754, Lucene 10.5.0), :3278 (GITHUB#11556, Lucene 9.9.0)
- TestHTMLStripQuoteInScriptComment.java (JUnit test):
repro/LFV-311/src/org/apache/lucene/analysis/charfilter/TestHTMLStripQuoteInScriptComment.java(36 lines)
A picture of the scanner's path through the repro input, with every drawn value taken from the grammar at a9779ef3c193 or an executed probe run; made in parallel with this doc.
assets/LFV-311/bug.png(539 KB)