RescoreTopNQuery(query, source, n) re-scores every match of query with source and keeps the best n. A source may read each match's own score, but the query computes its inner matches in a mode that produces no scores.
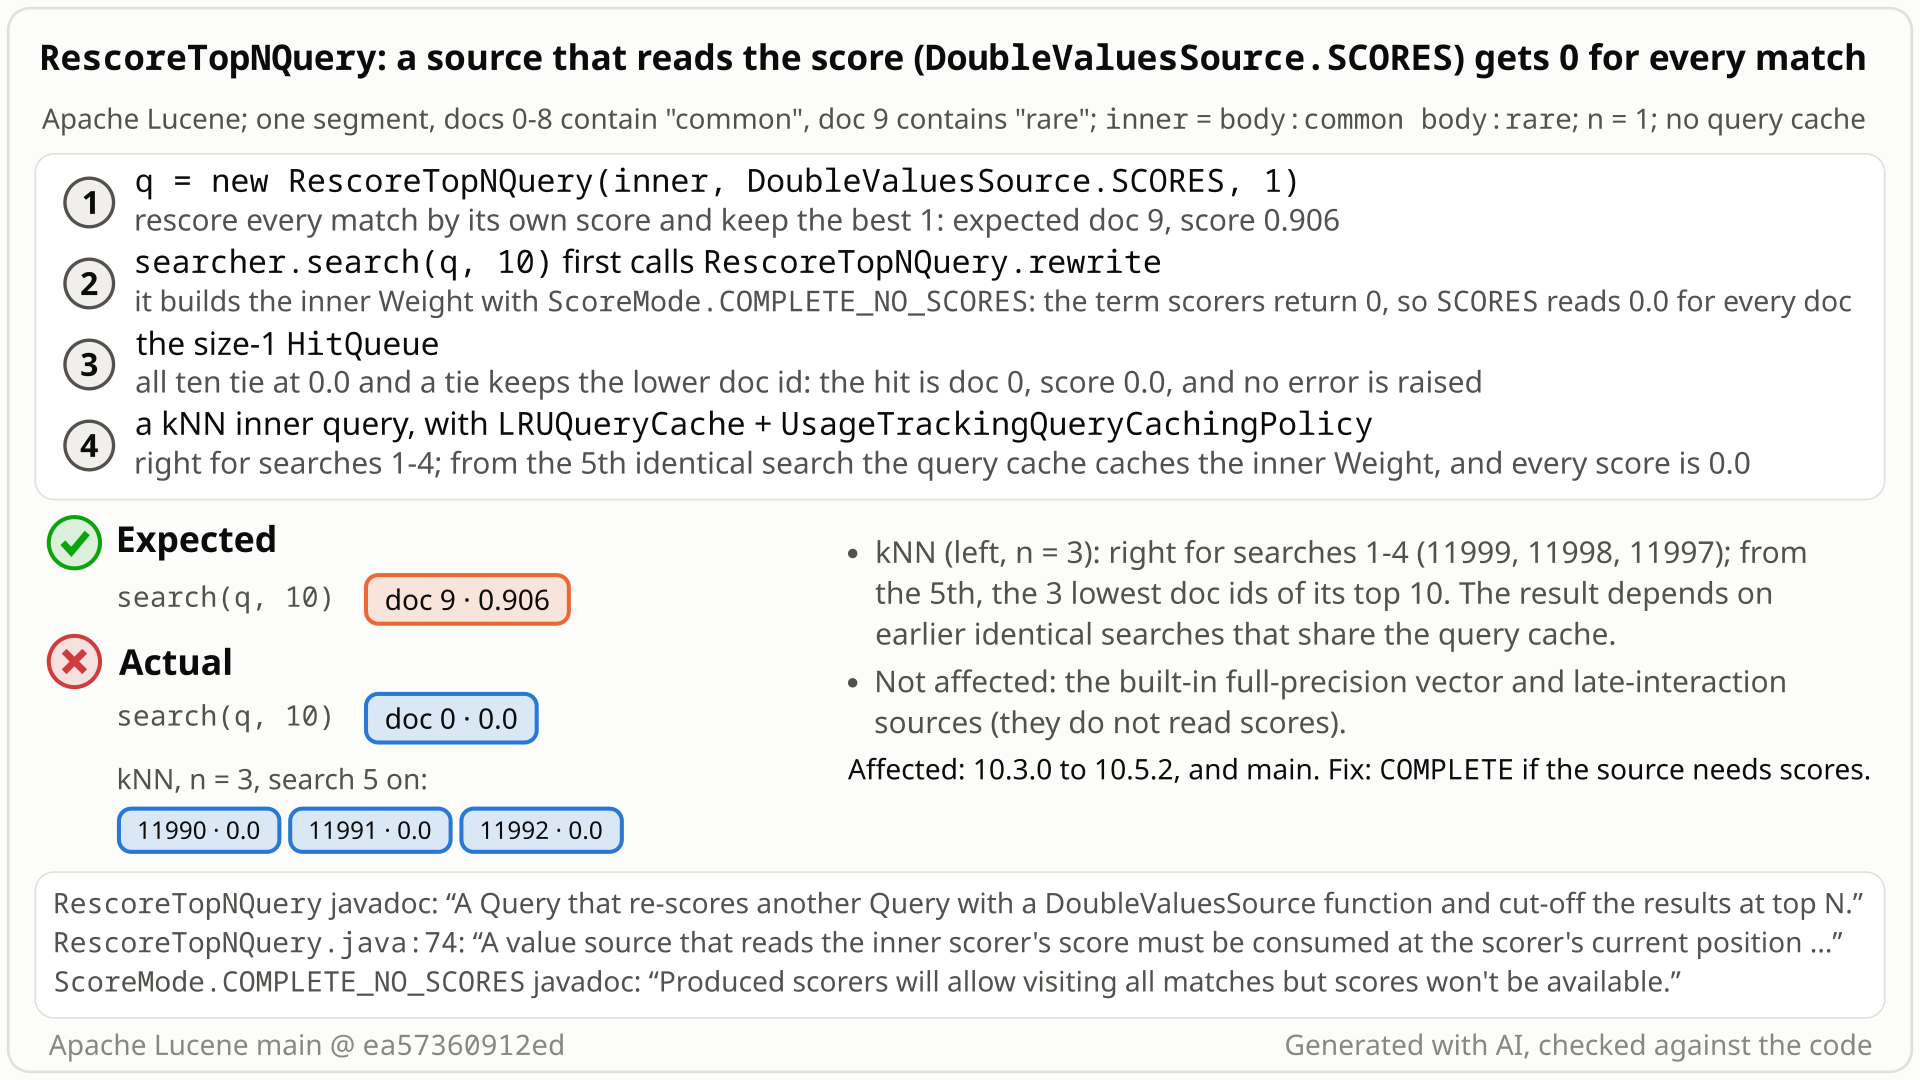
body:common OR body:rare by SCORES with n=1 should keep doc 9 (0.906), but every score reads 0.0 and doc 0 wins. Select the still to open it at full size. Generated with AI, checked against the code.- Index 10 docs: docs 0-8 contain "common", doc 9 contains "rare". A plain search for
body:common OR body:rareranks doc 9 first (score 0.906; docs 0-8 score 0.067). - Search
new RescoreTopNQuery(inner, DoubleValuesSource.SCORES, 1): re-score every match by its own score and keep the best one. You expect doc 9 at 0.906. - You get doc 0 at 0.0. The rewrite creates the inner Weight with
ScoreMode.COMPLETE_NO_SCORES, so the term scorers hand the source 0 for every match; all ten matches tie and the lowest doc id wins. - A kNN inner query keeps its scores until the query-caching policy decides to cache the inner query: with
UsageTrackingQueryCachingPolicy, searches 1-4 return 11999, 11998, 11997, and from the 5th on 11990, 11991, 11992, all at 0.0. - A normal
IndexSearcherraises no error (Lucene's asserting test searcher does). Other inner queries get other placeholders: a phrase query reads 1.0 for every match. The built-in vector and late-interaction rescoring sources do not read scores and are not affected.
Anyone who passes a score-reading source (DoubleValuesSource.SCORES, an expression with _score, or a custom source) to the experimental RescoreTopNQuery. Term inner queries and booleans of them are wrong on every search; kNN ones once a query cache caches them (default on 10.x for large segments). The built-in vector and late-interaction rescoring is not affected.
Mechanism, terms and numbers1,034 words
RescoreTopNQuery(query, valuesSource, n) re-scores every match of query with valuesSource at rewrite time and keeps the best n. For a source whose needsScores() is true (DoubleValuesSource.SCORES, an expression such as _score * popularity, or a custom source) the class deliberately feeds the inner scorer's score into the source, but it creates the inner Weight with ScoreMode.COMPLETE_NO_SCORES, a mode in which "scores won't be available". What the source then reads depends on the inner query. A term query, or a boolean of term queries, gives 0: every rescored value is computed from 0, all matches tie, and the top n are simply the first n matches by doc id, so body:common OR body:rare rescored by SCORES with n=1 gives doc 0 at 0.0 instead of doc 9 at 0.90565. A phrase query gives 1.0 for every match, in the same doc-id order. A kNN inner query keeps its scores until the query cache's policy decides to cache the non-scoring inner query; from then on (the 5th identical search with UsageTrackingQueryCachingPolicy) the caching wrapper returns a constant score of 0 and the top 3 of 10 neighbours become the 3 lowest doc ids. In a hybrid kNN OR term inner query the term part of the score is lost. A normal IndexSearcher raises no error. The built-in full-precision vector and late-interaction sources do not read scores and are not affected. Every executed release since the class was added (10.3.0 to 10.5.2) and main have it; the fix is one conditional statement.
RescoreTopNQuery(query, valuesSource, n)(@lucene.experimental, since 10.3.0): at rewrite time it runsquery, computesvaluesSourcefor every match, keeps the top n and rewrites itself into aDocAndScoreQueryholding those n documents and their new scores.- Score-reading source: a
DoubleValuesSourcewhoseneedsScores()is true, such asDoubleValuesSource.SCORES("exposes a document's score"), an expression that binds_score, or a custom source. It receives the current match's score throughDoubleValuesSource.fromScorer. - Score mode: what a
Weightmust produce.COMPLETEvisits every match with its score;COMPLETE_NO_SCORESvisits every match "but scores won't be available" (ScoreMode.java:25-26).
rewrite(RescoreTopNQuery.java:68-88) always creates the inner Weight withindexSearcher.createWeight(rewritten, ScoreMode.COMPLETE_NO_SCORES, 1.0f)(:72).- A source with
needsScores()true takesrescoreInline(:74-79; the comment says such a source "reads the inner scorer's score"), which hands itDoubleValuesSource.fromScorer(innerScorer)(:99,:230-236). - What
score()returns on a non-scoring Weight is up to the query;COMPLETE_NO_SCORESpromises no particular value. A non-scoringTermWeightuses a dummySimScorerthat returns0fand is "not expected to be called since scores are not needed" (TermQuery.java:77-92); a boolean of terms reads 0 as well. A non-scoringPhraseWeightuses one that returns 1 (PhraseWeight.java:46-51). A kNN query rewrites toDocAndScoreQuery, which returns its stored scores in any mode (DocAndScoreQuery.java:244-245). - Every value goes into a size-n
HitQueue(:221-228). When all values are equal (0 for term queries, 1.0 for a phrase query), the tie-break keeps the lower doc id (HitQueue.java:76-82): the top n are the first n matches in doc-id order. - kNN:
IndexSearcher.createWeightputs only non-scoring Weights in the query cache (IndexSearcher.java:979-981);DocAndScoreQueryis cacheable (DocAndScoreQuery.java:273-275) and equal across repeats of the same kNN query on the same reader (:294-307).UsageTrackingQueryCachingPolicycaches a query at its 5th use (UsageTrackingQueryCachingPolicy.java:122-137), and on that very callLRUQueryCachereturnsConstantScoreScorerSupplier(0f, ...)(LRUQueryCache.java:837-846). From the 5th search on every score is 0, while the entry stays in the cache for that reader (until eviction,clearQueryorclear, a new reader, or a replaced or disabled cache). Before the policy is asked, the cache also checks that the inner query is cacheable on the segment and that the index passes a worst-case size check (LRUQueryCache.java:792-807,:816); the lead-cost check at:850only decides whether the entry is filled, and the scorer returns 0 either way. - On main
IndexSearcherhas no default cache (#14187,IndexSearcher.java:82-84), so the kNN form needs a cache the application sets; on 10.x the defaultLRUQueryCachecaches segments of 10,000 or more documents (10.5.2IndexSearcher.java:95-100,LRUQueryCache.java:167-177). A fully default 10.5.2 searcher, with no cache or policy set, flips at the 5th search too (executed by the fact check); the repro sets an explicit cache with the same caps and policy.
Main ea57360912ed, one segment. Lexical: docs 0-8 body = "common", doc 9 body = "rare"; plain search: doc 9 at 0.90565, docs 0-8 at 0.06663794. kNN: 12,000 docs with vector [1, i] (EUCLIDEAN), the 10 nearest to [1, 11999].
| inner query | source, n | expected | got |
|---|---|---|---|
body:common OR body:rare, no cache | SCORES, 1 | doc 9 at 0.90565 | doc 0 at 0.0 |
| same | SCORES, 10 | doc 9, then docs 0-8 at 0.0666 | docs 0-9, all 0.0 |
same, popularity 2 on doc 3, else 1 | _score * popularity, 3 | docs 9, 3, 0 (0.906, 0.133, 0.067; computed from the plain scores) | docs 0, 1, 2, all 0.0 |
body:"x y" (phrase), no cache; docs 0-8 "x y z z z z", doc 9 "x y x y x y" | SCORES, 10 | doc 9 at 0.0665, then docs 0-8 at 0.0423 | docs 0-9, all 1.0 |
kNN, LRUQueryCache + UsageTrackingQueryCachingPolicy | SCORES, 3 | 11999, 11998, 11997 (1.0, 0.5, 0.2) every search | searches 1-4 right; 5 and 6: 11990, 11991, 11992, all 0.0 |
| kNN, a cache that accepts every segment + an always-cache policy (independent reproducer, 30 docs) | SCORES, 1 | the nearest doc | wrong on the 1st search (score 0.0) |
kNN OR body:rare, no cache | SCORES, 3 | doc 9 at 1.90565 | doc 9 at 1.0 (the term part reads 0) |
| kNN, fully default 10.5.2 searcher (no cache or policy set) | SCORES, 3 | 11999, 11998, 11997 every search | searches 1-4 right; 5 and 6: 11990, 11991, 11992, all 0.0 |
| kNN, no cache (control) | SCORES, 3 | 11999, 11998, 11997 | right, all six searches |
| control: a source that does not read scores | fromFloatField, 1 | the best field value | right |
With the fix every row gives the expected result.
Exposure and likelihood401 words
- Who is exposed. Callers of
RescoreTopNQuerywith a source whoseneedsScores()is true:DoubleValuesSource.SCORES, an expression that reads_score(for example "boost the text score by popularity and keep the top n for a later stage"), or a custom source. - Term inner queries and booleans of them: wrong on every search, with any configuration (the source reads 0). A phrase inner query reads 1.0 for every match; other query types get whatever their non-scoring scorer returns.
- kNN inner queries: wrong once the query cache's policy caches the inner query: the 5th identical search with
UsageTrackingQueryCachingPolicy; the 1st with an always-cache policy and a cache that accepts small segments. On 10.xIndexSearcher's default cache applies to segments of 10,000 or more documents (a fully default 10.5.2 searcher flips at the 5th search, executed); on main the cache is opt-in. - Hybrid (
kNN OR text): the text part of the score is lost on every search (run without a cache). - Not exposed. The built-in factories
createFullPrecisionRescorerQuery(float vectors, and on main also FLOAT16) andcreateLateInteractionQuery: their sources do not need scores. They are what the class was designed for and its only callers in Lucene's own code; how common each use is elsewhere is not known. - Default settings.
RescoreTopNQueryis opt-in and@lucene.experimental; nothing else needs a non-default setting: the lexical probe uses a defaultIndexWriterConfig(default codec, BM25) and a plainIndexSearcher, and a fully default 10.5.2 searcher shows the kNN form. No scale is needed for the lexical case (10 documents, n=1). - What you see. No error with a normal
IndexSearcher(the test framework's asserting searcher fails). Rescored scores of 0.0 (1.0 for a phrase inner query;0 + somethingfor a custom source: ascore + 1source returned 1.0) and, for a source that reads only the score, a top n that is the first n matches by doc id. The hits are always drawn from the inner query's matches. An application that applies a minimum score afterwards loses hits. For kNN, results depend on earlier identical searches that share the cache. - Downstream. Known code users (neo4j, nrtsearch, zuliasearch, luceneutil, a Go port, an open Solr PR) use sources that do not read scores; a code search found no
RescoreTopNQueryin the Elasticsearch, OpenSearch or Solr default branches. That fits the absence of reports, and says nothing about private code.
The test shows that RescoreTopNQuery with DoubleValuesSource.SCORES reads score 0 for every inner hit (inner Weight built with ScoreMode.COMPLETE_NO_SCORES).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.search;

import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.Term;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestRescoreTopNQueryScoresSource extends LuceneTestCase {

  public void testScoresSourceSeesInnerScore() throws Exception {
    try (Directory dir = newDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        for (String body : new String[] {"a b c d", "a"}) {
          Document doc = new Document();
          doc.add(new TextField("body", body, Field.Store.NO));
          w.addDocument(doc);
        }
      }
      try (IndexReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        Query inner = new TermQuery(new Term("body", "a"));
        ScoreDoc best = searcher.search(inner, 1).scoreDocs[0];
        ScoreDoc rescored =
            searcher.search(new RescoreTopNQuery(inner, DoubleValuesSource.SCORES, 1), 1)
                .scoreDocs[0];
        // expected: the inner query's best hit and score (doc 1, BM25 > 0); actual: doc 0, score 0
        assertEquals(best.doc + ":" + best.score, rescored.doc + ":" + rescored.score);
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-315/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.search.TestRescoreTopNQueryScoresSource
- Expected vs actual
- Expected: the TermQuery's own best hit and BM25 score (doc 1, 0.1098); actual on main 645d4fe: doc 0 with score 0.0 (with -ea and -da).
More files, environment, full output32 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[1:0.109832264]> but was:<[0:0.0]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.search.TestRescoreTopNQueryScoresSource.testScoresSourceSeesInnerScore(TestRescoreTopNQueryScoresSource.java:49)- The javadoc promises re-scoring "with a DoubleValuesSource function" for "any type of Query"; the class itself feeds the inner score to sources that need it.
COMPLETE_NO_SCORESmeans "scores won't be available";FunctionScoreQueryasks for scores when it uses a score-reading source;AssertingScorerfails here.- "Works even with the no-scoring ScoreMode" refers to the outer search, the author said in review.
The full argument305 words
- The contracts. Class javadoc (
RescoreTopNQuery.java:26-31): "A Query that re-scores another Query with a DoubleValuesSource function and cut-off the results at top N ... it can work with any type of Query"; the constructor takes a genericDoubleValuesSource(:58). 10.3.0 CHANGES (CHANGES.txt:1562-1563): "rescore other Query based on a generic DoubleValueSource".DoubleValuesSource(DoubleValuesSource.java:43-46): "Scores may be used as a source for value calculations by wrapping a Scorer using fromScorer ... accessed using the SCORES DoubleValuesSource".ScoreMode.COMPLETE_NO_SCORES(ScoreMode.java:25): "scores won't be available". - The class wires the score in on purpose.
getDoubleValuespassesfromScorer(innerScorer)exactly when the source needs scores (:230-236, since #14009), and #16705 added the inline path whose comment says such a source "reads the inner scorer's score" (:74-75). - The rest of Lucene asks for scores.
FunctionScoreQuery.createWeightusesCOMPLETEwhen the outer search scores and its source needs scores, and skips the source when the outer search does not score (FunctionScoreQuery.java:109-122), so whenever it computes a score-reading source its inner Weight scores;TestFunctionScoreQuery.testScoreModeassertsCOMPLETEforSCORESunder a scoring outer search (:318-322).TestDoubleValuesSourcepicksvs.needsScores() ? COMPLETE : COMPLETE_NO_SCORES(:310-312).RescoreTopNQueryalways computes its source, so the matching rule there isCOMPLETEwhenever the source needs scores. - The test framework enforces it.
AssertingWeightsetscanScore = scoreMode.needsScores()andAssertingScorer.score()asserts it (AssertingWeight.java:74,AssertingScorer.java:125-126, LUCENE-6526). The finder'sAssertingIndexSearcherprobe fails there, called fromRescoreTopNQuery.rescoreInline; the independent reproducer's own asserting probe fails the same way on main and passes with the fix. - Untested case. Every upstream
RescoreTopNQuerytest uses sources that do not need scores. No PR thread (#14009, #14729, #16628, #16656, #16705) discusses the inner score mode; #16705 and #16656 describe the inline path as needed becausefromScorerreads the scorer's current score.
The devil's-advocate check280 words
The strongest case for "intended" (built by a devil's-advocate verifier and by an OpenAI GPT-5.6 reviewer arguing "works as designed"): the javadoc says "Unlike or FunctionScoreQuery, this Query will work even with the no-scoring ScoreMode" (:31-32, sic); the class is @lucene.experimental and was built for kNN reranking, where DocAndScoreQuery returns real scores in any mode; a non-scoring inner Weight skips similarity work and can be cached, a real optimization; and since LUCENE-6329 calling score() without scores is safe, so 0 could be read as an unspecified placeholder.
Why it fails: in the #14009 review the author, dungba88, explained that sentence (2025-06-13): "it does not depend on the score mode (FunctionScoreQuery will be a no-op if needsScores = false) and it also trim down the results to N. ... The nuance is important in cases where we don't need the overall score (using ConstantScoreQuery) but still want to rescore and trim down results in some sub-Query (like KnnFloatVectorQuery). It's heavily influenced by KnnFloatVectorQuery but API-wise there would be no such limitation." So the sentence is about the outer search, and the class was meant for any inner query. The comment does not discuss sources that read scores; their support comes from the code and the DoubleValuesSource contract: two sets of authors routed the inner score into these sources. LUCENE-6329 made such calls safe, not meaningful, and LUCENE-6526 added assertions that they do not happen; @lucene.experimental marks an unstable API, not permission to return wrong results; the optimization survives the fix for sources that do not read scores; and no javadoc, CHANGES or MIGRATE text restricts the source. Every reviewer rated the intended argument weak. Verdict: a defect.
Recommended A: COMPLETE when the values source needs scores
Create the inner Weight with ScoreMode.COMPLETE when the source needs scores, and COMPLETE_NO_SCORES otherwise (one conditional statement, +4/-1 lines, one file). The built-in sources keep the fast, cacheable path. The test passes with assertions on, off and nightly; 33 tests in 9 nearby suites and the core static checks pass.
// A value source that reads the inner query's score needs a Weight that produces scores.
ScoreMode innerScoreMode =
    valuesSource.needsScores() ? ScoreMode.COMPLETE : ScoreMode.COMPLETE_NO_SCORES;
Weight weight = indexSearcher.createWeight(rewritten, innerScoreMode, 1.0f);
All options and trade-offs3 options · 609 words
The inner Weight must produce scores whenever the source reads them, whatever the outer search's score mode, because RescoreTopNQuery always computes the source at rewrite time. One option was built and validated in a scratch worktree at ea57360912ed (removed afterwards); the others are untested.
In rewrite, replace the fixed ScoreMode.COMPLETE_NO_SCORES at RescoreTopNQuery.java:72 by COMPLETE when valuesSource.needsScores(), whatever the outer search's score mode: unlike FunctionScoreQuery, which skips its source when the outer search does not score, RescoreTopNQuery always computes the source. COMPLETE, not TOP_SCORES, because the rewrite visits every match. +4/-1 lines, RescoreTopNQuery.java only.
// A value source that reads the inner query's score needs a Weight that produces scores.
ScoreMode innerScoreMode =
    valuesSource.needsScores() ? ScoreMode.COMPLETE : ScoreMode.COMPLETE_NO_SCORES;
Weight weight = indexSearcher.createWeight(rewritten, innerScoreMode, 1.0f);
Trade-offs
- The fast path stays. Sources that do not need scores (the built-in vector and late-interaction ones) keep
COMPLETE_NO_SCORES, the prefetch path and query caching. - Cost. Score-reading sources now pay for real scoring (for example BM25 per match), which is what they ask for. No benchmark was run.
- No caching for score-reading sources.
IndexSearchercaches only non-scoring Weights, so their inner Weight is no longer cached; with the fix the probe showed the cache was never consulted and every search was right. The cached path could only ever return 0 scores, so nothing correct is lost. - Nit (the adjudication's).
rewrittenValueSource.needsScores()would be slightly more precise thanvaluesSource.needsScores(); the existing branch andgetDoubleValuesusevaluesSource, so they differ only for a source whoserewritechangesneedsScores(). See option B. - Rebase. Open draft #16847 (long doc ids) edits this file but not this line.
What the checks validated
- Stock: the test fails 2 of 2 through gradle with assertions on, off and
-Ptests.nightly=true, and 10 of 10 over 5 iterations of a second seed. - Patched, assertions on and off:
TestRescoreTopN*(with the new test),TestFilterReadersForwardVectorPrefetch,*LateInteraction*andTestDoubleValuesSource: 9 classes, 33 tests, 0 failures, 2 skipped (@Nightly) each. - Patched,
-Ptests.nightly=true:TestRescoreTopNQuery(with its 2@Nightlytests) and the new test: 8 of 8. Patched,-Ptests.seed=5EED1234 -Ptests.iters=5: 10 of 10. - Formatting:
:lucene:core:tidyran and succeeded (its log does not show whether it edited anything);:lucene:core:check -x testpasses (google-java-format, ecjLint, forbiddenApis); google-java-format 1.37.0--dry-runreports no change for the patched file or the test. - Standalone harness with the patched class: 2 of 2 pass on main (assertions on and off); the same change on the 10.x file passes on 10.5.2 and 10.3.0. Earlier hunt runs of the same change: the independent reproducer's 7-test JUnit 7 of 7 (also on the adjudication's re-run with a new seed), its asserting-searcher probe, the security probe 4 of 4, and the finder's
TestRescoreTopNQuery+TestRescoreTopNQueryPrefetchrun 7 of 7. A phrase-query probe: with the fix the rescored phrase scores equal the plain ones.
Compute boolean needsScores = rewrittenValueSource.needsScores() once in rewrite and use it for the score mode, the inline/prefetch branch and getDoubleValues.
Trade-offs
Same behaviour for every in-tree source; more robust for a custom source whose rewrite changes needsScores(). A slightly larger diff (getDoubleValues reads the field valuesSource today).
Throw IllegalArgumentException in the constructor for a source whose needsScores() is true, or document that such sources are unsupported.
Trade-offs
Contradicts the generic DoubleValuesSource contract and the class's own inline path for these sources (#16705), and removes a natural use: combining the first-stage score with a field value, then keeping the top n.
With a shared cache: only non-scoring Weights enter it, the rewritten kNN query is identical for every user of a reader, and the cache's wrapper returns score 0 from the call that caches it, so anyone's earlier searches change the result. The hunt screen reads SECURITY.md as leaving user isolation to the application; no exploit or affected deployment is known.
Semi-formal. While writing a bounded translation-validation model of Lucene's rescoring code, an AI tool noticed that the score-reading path runs on a Weight without scores; the harness then found all 586 non-empty random trials (of 600) wrong on the stock jar. A follow-up probe found the kNN-with-cache form.
The method in full176 words
Method: semi-formal (bounded translation validation, then a public-API JUnit).
- A hunt unit (2026-10-26) checks that Lucene's rescoring paths (
RescoreTopNQuery,QueryRescorer,DoubleValuesSourceRescorer) compute what an independent reference computes, by bounded-exhaustive and random comparison on the stock jar. - While writing the model, the finder, an AI tool, noticed that
rewritesends score-reading sources down a path that reads the inner score, yet creates the inner Weight withCOMPLETE_NO_SCORES. - The harness's RTN-scores scope then compared
RescoreTopNQuerywith a reference built from the inner query'sCOMPLETE-mode scores: all 586 non-empty trials of 600 differ, for an array-backed score-reading source and forDoubleValuesSource.SCORES, with assertions on and off (example: expected[0:0.89166296], actual[0:0.0]). - A follow-up probe found the kNN form (right for 4 searches, then 0 once the query cache caches the inner Weight), and a public-API JUnit on the stock jars confirmed both.
- An independent reviewer from another model family (OpenAI GPT-5.6) then tried to refute it, verifiers and an adjudication confirmed it, and the history, prior-report and security checks followed.
No prior report found: 207 queries and reads on 2026-10-26 over GitHub issues, PRs and review comments, commits, open-PR file lists, downstream trackers, the mailing lists, JIRA and the web. Not fixed upstream; the closest items are the PRs that added the class and its inline path.
Searches6 searches
The searches found no upstream issue, PR, review comment, commit, mailing-list thread or JIRA entry that reports this bug, and no open PR that fixes it. GitHub search reads only the first page per query and GitHub's search rate limit cut some tool queries, so every RescoreTopNQuery and DocAndScoreQuery item was also enumerated by hand; "none found" is still not proof that none exists, and private reports to the security list are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene) | 2026-10-26 | every issue or PR mentioning RescoreTopNQuery (10) or DocAndScoreQuery (19), read with comments; scripted prior-report search runs over class, score-mode, kNN-cache and _score phrasings; 13 manual phrasing variants | no report; only the feature PRs #14009, #14860, #14729, #16628, #16705, #16656 and unrelated items |
| Review threads read in full | 2026-10-26 | inline review comments of #14009, #14729, #16628, #16656 and #16705 (issue search does not index them) | none discusses the inner score mode; #16705 and #16656 assume fromScorer reads a real score |
| Open PRs | 2026-10-26 | the file lists of all 411 open apache/lucene PRs | only draft #16847 (long doc ids) edits the file; it keeps the line |
| Commits and downstream | 2026-10-26 | upstream main and branch_10x history and contents; GitHub code search; Solr, Elasticsearch and OpenSearch trackers | not fixed; apache/solr#4919 reports a different RescoreTopNQuery defect (an empty inner result throws); code users wrap kNN queries with sources that do not read scores |
| Mailing lists and JIRA | 2026-10-26 | dev@, java-user@, issues@, commits@, builds@; the LUCENE and SOLR JIRA archives | no report; only background on calling score() without scores (LUCENE-6329, LUCENE-6526, LUCENE-7623) |
| Web | 2026-10-26 | 21 queries | nothing about this behaviour |
Introduced with the class by #14009 (merged 2025-06-28; backport #14860), so not a regression; first released in 10.3.0. All seven releases 10.3.0 to 10.5.2 and main fail; 10.2.2 and earlier have no such class. Not fixed upstream.
Versions tested8 rows
Introduced by #14009, "Add Query for reranking KnnFloatVectorQuery with full-precision vectors" (dungba88), merged 2025-06-28 as 3404496b3d77 on main and backported by #14860 as 4fcb6d6d50de (2025-06-29 UTC). Both defective lines, createWeight(rewritten, ScoreMode.COMPLETE_NO_SCORES, 1.0f) and DoubleValuesSource.fromScorer(innerScorer), are in that first version; git log -S on each returns only that commit, and the parents have no RescoreTopNQuery.java. Later changes kept the line: #14729 (late interaction), #16628 (fp16, main only) and #16705 (main only, split into inline and prefetch paths). On 10.x the line is RescoreTopNQuery.java:63. Branches read but not built: branch_10_6 (10.6.0, released 2026-10-29) and the unreleased branch_10x still have the line at :63; upstream main still has it at :72 (read, 2026-10-26).
| Version or commit | Verdict | Result |
|---|---|---|
| 9.12.3, 10.2.2 | class absent | the repro does not compile: RescoreTopNQuery does not exist |
| 10.3.0 | first affected | finder's test 2 of 2 fail (also with assertions off); this doc's test 2 of 2 fail (assertions on; off in the fact check's re-run) |
| 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1 | affected | finder's test 2 of 2 fail |
| 10.5.2 | affected | finder's test and this doc's test 2 of 2 fail, assertions on and off |
| branch_10_6 (10.6.0, released 2026-10-29), branch_10x (unreleased) | read, not built | the source still creates the inner Weight with COMPLETE_NO_SCORES (RescoreTopNQuery.java:63) |
main ea57360912ed | affected | this doc's test 2 of 2 fail through gradle (assertions on, off, nightly) and the harness |
| 10.3.0 and 10.5.2 + the fix | root-cause control | 2 of 2 pass (shadowed RescoreTopNQuery) |
| main + the fix | not affected | 2 of 2 pass; 33 tests in 9 nearby suites pass |
An independent reproducer, a "works as designed" reviewer from another model family (OpenAI GPT-5.6), a devil's advocate and an adjudication all say real. An earlier read-only GPT-5.6 refute review could not run Java and agreed on the root cause. This doc's test was re-run through gradle, on 10.5.2 and 10.3.0, and with the fix.
Checks and verdicts621 words
Every check ran on main ea57360912ed with assertions on and off unless noted. The GPT-5.6 reviews ran read-only (they could not execute Java); their execution evidence is a separate run's and the cross-model review's own re-runs of the finder's test.
| Check | Verdict | What it found |
|---|---|---|
| Refute review (OpenAI GPT-5.6) | not real, low (procedural) | It could not run Java and called its own verdict "procedural, not a substantive refutation". It agrees on the root cause, found the inputs in contract, rated the intended argument weak, and listed 7 evidence items for real (one new: TestDoubleValuesSource picks COMPLETE exactly when needsScores()). A separate re-run of the finder's test failed 2 of 2. |
| Independent reproducer | real | Own 7-test JUnit written from the claim only, every searcher with an explicit cache and policy: 5 of 7 fail on main, 10.5.2 and 10.3.0 (lexical SCORES: doc 0 at 0.0 instead of doc 17; all 30 of 30 hits 0.0; a score + 1 source returns 1.0; kNN with an always-cache policy wrong on the 1st search; with the usage policy from the 5th); both controls pass. Its own fix passes 7 of 7, and its AssertingIndexSearcher probe fails on main and passes with the fix. |
| "works as designed" reviewer (OpenAI GPT-5.6) | real, medium; intended argument weak | Read-only. It built the strongest intended case (experimental, kNN-oriented, a non-scoring Weight is a cacheable optimization) and rejected it: the generic constructor, the class's own score path, ScoreMode, the asserting framework and FunctionScoreQuery all point the other way. The cross-model review's re-runs of the finder's test fail on main (on and off), 10.5.2 and 10.3.0 and pass with the fix. |
| Devil's advocate | real, high | No intended, documentation, misuse or reachability argument survives; it read the #14009 and #16705 threads (the author's review reply ties the no-scoring sentence to the outer search). The finder's test fails on main with assertions on and off. |
| Adjudication | confirmed, high | Re-ran the independent reproduction's test with a fresh seed: 5 of 7 fail with assertions on and off, 0 of 7 with the independent reproduction's fix. |
| Security screen | out of scope of SECURITY.md | Its own probe: the cross-user cache test fails on main (on and off) and 10.5.2 and passes with the fix; 800 reach checks per target find no hit outside the inner query's live matches or an outer filter; one source call per match. |
| This doc's re-runs | reproduces; fix validated | The test (codec pinned for the kNN index) fails 2 of 2 through gradle (assertions on, off, nightly; 10 of 10 over 5 iterations of a second seed) and through the harness on main, 10.5.2 and 10.3.0, and passes with the fix; 33 tests in 9 nearby suites, the nightly tests and the core static checks pass. A hybrid probe showed the term part of the score lost without any cache. |
| Fact check of this doc (re-ran the test) | holds; citations and patch block fixed | Re-ran the test on main (assertions on and off, a second seed), 10.5.2, 10.3.0 with assertions off and with the fix, and ran a fully default 10.5.2 searcher, which flips at search 5. Found eight citations to probe logs that do not exist and a truncated patch block in the brief; both fixed. |
| Cross-model fact check (OpenAI GPT-5.6, reading only) | core bug real; 17 accuracy findings | Code path, numbers and history confirmed; 7 errors, 6 overclaims and 4 missing caveats, among them that only term queries read 0 (a phrase query reads 1.0, since executed). All handled: 15 fixed as suggested. |
| Diagram check | correct; no errors | Every value on screen re-run and matched; six optional polish items, not re-rendered. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 520 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,349 words
- Registry title
- RescoreTopNQuery builds its inner Weight with ScoreMode.COMPLETE_NO_SCORES, so a values source that needs scores (DoubleValuesSource.SCORES, an expression using _score) reads 0 instead of the inner query's score
- Area
- search / rescoring
- Priority
- Medium, rank 53: The experimental RescoreTopNQuery silently ranks wrongly with a score-reading values source, which is an unusual pairing.
- Impact class
- silent wrong results
- Impact note
- Applications that use the experimental RescoreTopNQuery with a values source whose needsScores() is true (DoubleValuesSource.SCORES, an expression reading _score, or a custom source): with a lexical or hybrid inner query every rescored value is computed from a score of 0 on every search, so the top n are just the first n matches in doc-id order, and with a kNN inner query the same happens once the query-caching policy caches the inner Weight (the 5th identical search with UsageTrackingQueryCachingPolicy, the 1st with an always-cache policy; IndexSearcher's default cache in 10.x for segments of 10000 or more docs, opt-in on main since #14187); default codec and IndexWriterConfig, ordinary scale, released 10.3.0-10.6.0 (10.6.0 by reading), no error; the built-in full-precision vector and late-interaction sources do not read scores and are not affected.
- Summary
- You wrap a query in RescoreTopNQuery and re-score its matches with a values source that uses the query's own score, for example DoubleValuesSource.SCORES or an expression such as _score * popularity, keeping the best n. You expect the source to see each match's real score, so rescoring body:common OR body:rare by SCORES with n=1 should return the rare-term document 9 with its normal score. Instead RescoreTopNQuery runs the inner query in a mode that produces no scores, so the source reads 0 for every match and the result is doc 0 with score 0.0 (the first match by doc id); for a kNN inner query the scores are right until the query cache caches the inner query, and from then on (the 5th identical search with the usage-tracking policy) they read 0 too.
- Introduced
- 3404496b3d77 (#14009 'Add Query for reranking KnnFloatVectorQuery with full-precision vectors', by GitHub dungba88, main), released through its branch_10x backport 4fcb6d6d50de (#14860 'Backport RescoreTopNQuery to 10.3') [read: git blame on main HEAD and git log -S on both defective lines (createWeight(rewritten, ScoreMode.COMPLETE_NO_SCORES, 1.0f) and DoubleValuesSource.fromScorer(innerScorer)) each return only 3404496b3d77; the parents of both commits have no RescoreTopNQuery.java; exec: fails on 10.3.0, the first release with the class]; not a regression: both lines are in the class's first version, and #16705 (main only) added the inline path for score-reading sources but kept COMPLETE_NO_SCORES (2025-06-28 (#14009 committed to main 2025-06-28T07:34Z; backport #14860 committed 2025-06-29T21:08Z))
- First affected version
- 10.3.0 [exec]
- Affected versions
- 10.3.0, 10.3.1, 10.3.2, 10.4.0, 10.5.0, 10.5.1, 10.5.2 and main ea57360912ed [exec: finder repro, seed DEADBEEF, 2 of 2 fail on each; 10.3.0, 10.5.2 and main also with -da; the independent reproduction's own test 5 of 7 fail on main, 10.5.2 and 10.3.0]; not applicable to 10.2.2, 9.12.3 and earlier (RescoreTopNQuery absent, the repro does not compile) [exec]; upstream main (re-checked 2026-10-26) and branch_10x still create the inner Weight with COMPLETE_NO_SCORES [read]; branch_10_6 4ae946e5a9b (10.6.0 RC1) and branch_10x 657014b3c57: RescoreTopNQuery.java byte-identical to 10.5.2 [read 2026-10-29]; main 645d4fe14a20 [exec 2026-10-29, -ea and -da]; branch_11x f85446cb1af [read: same blob as main]; not fixed anywhere
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, follow-up prior-report record verdict new, 207 logged queries and reads: scripted prior-report searches A (51 queries over GitHub, commits, downstream repos, four lists, JIRA and the web), B (kNN plus query-cache angle, 30 + 4 cached GitHub) and C (expressions and _score angle, 30 + 4 cached GitHub), the finder's 45-query run, 43 manual searches and reads; every apache/lucene issue or PR mentioning RescoreTopNQuery (10) or DocAndScoreQuery (19) read with its comments; the inline review comments of #14009, #14729, #16628, #16656 and #16705 read directly; the file lists of all 411 open PRs; dev@, java-user@, issues@, commits@ and builds@; the LUCENE and SOLR JIRA archives; 21 web queries; re-checked read-only while writing this row: upstream main RescoreTopNQuery.java:72 still uses COMPLETE_NO_SCORES, its last change is #16705 (2026-10-01), and no RescoreTopNQuery issue or PR is newer than #16902): not fixed upstream; related, not reports of this bug: #14009 (introduced it; in review the author tied 'will work even with the no-scoring ScoreMode' to the outer search), #14860 (backport to 10.3), #16705 and #16656 (their descriptions assume fromScorer reads a real score; #16705 kept COMPLETE_NO_SCORES), #13564 (design issue), open draft #16847 by jimczi (edits RescoreTopNQuery.java, keeps the line), LUCENE-6329 (#7390), LUCENE-6526 (#7584), LUCENE-7623 (#8674) and #12297/#12383 (background on calling score() without scores); apache/solr#4919 / SOLR-18424 report a different RescoreTopNQuery defect (empty inner result throws, the hunt's rescoretopn-no-candidates-throws); #16926 (merged 2026-10-28) changed rewrite() but keeps COMPLETE_NO_SCORES: not a fix
- Lucene commit tested
- main
ea57360912ed(2026-10-26) through gradle (assertions on, off,-Ptests.nightly=true, and 5 iterations of a second seed) and through a standalone JUnit harness (assertions on and off); this doc's test also on the Maven Central jars of 10.5.2 (assertions on and off) and 10.3.0; the finder's test on all seven releases 10.3.0-10.5.2 (10.3.0 and 10.5.2 also with assertions off); 10.2.2 and 9.12.3 do not have the class; the fix in a scratch worktree atea57360912ed(the test, 9 nearby suites with assertions on and off, the@Nightlytests,:lucene:core:check -x test), removed afterwards, and as a shadowed class over the main, 10.5.2 and 10.3.0 jars; an independent fact check re-ran this doc's test (main with assertions on and off, 10.5.2, 10.3.0 with assertions off, and with the fix) and a fully default 10.5.2 searcher; a phrase-query probe ran on main (assertions on and off, and with the fix).
- Finding record
lucene/core/src/java/org/apache/lucene/search/RescoreTopNQuery.java:26-33 (class javadoc: re-scores another Query with a DoubleValuesSource, 'it can work with any type of Query', 'will work even with the no-scoring ScoreMode', @lucene.experimental), :72 (createWeight(rewritten, ScoreMode.COMPLETE_NO_SCORES, 1.0f)), :74-79 (needsScores() sources take rescoreInline), :90-107 (rescoreInline passes getDoubleValues(innerScorer)), :230-236 (getDoubleValues returns DoubleValuesSource.fromScorer(innerScorer) when needsScores())lucene/core/src/java/org/apache/lucene/search/ScoreMode.java:25-26 (COMPLETE_NO_SCORES: 'scores won't be available')lucene/core/src/java/org/apache/lucene/search/TermQuery.java:77-92 (no-scores TermWeight uses a SimScorer returning 0f, 'not expected to be called'); LRUQueryCache.java:835-846 (a cached non-scoring Weight is served as ConstantScoreScorerSupplier(0f), also on the populating call)lucene/queries/src/java/org/apache/lucene/queries/function/FunctionScoreQuery.java:109-121 (asks for COMPLETE when the source needs scores); lucene/core/src/test/org/apache/lucene/search/TestDoubleValuesSource.java:311 (vs.needsScores() ? ScoreMode.COMPLETE : ScoreMode.COMPLETE_NO_SCORES)lucene/test-framework/src/java/org/apache/lucene/tests/search/AssertingWeight.java:74, AssertingScorer.java:125-127 (score() asserts canScore = scoreMode.needsScores(), LUCENE-6526)read-only GitHub checks while writing this row (2026-10-26): gh pr view 16847 (author jimczi, open draft); repos/apache/lucene/contents RescoreTopNQuery.java?ref=main (line 72 COMPLETE_NO_SCORES); repos/apache/lucene/commits?path=RescoreTopNQuery.java (latest 82d73908cb1, #16705, 2026-10-01); search/issues RescoreTopNQuery sorted by created (newest #16902, 2026-10-24)lucene/core/src/test/org/apache/lucene/search/TestRescoreTopNQuery.java:101 (testInnerQueryMatchesNothing, DoubleValuesSource.SCORES)
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/RescoreTopNQuery.java:26-34, 68-107, 221-236Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/ScoreMode.java:22-26; TermQuery.java:77-92; DocAndScoreQuery.java:244-245, 273-275, 294-307; HitQueue.java:76-82Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:82-84, 976-983; UsageTrackingQueryCachingPolicy.java:118-137; LRUQueryCache.java:811-814, 837-846a Lucene clone releases/lucene/10.5.2: lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:95-100, LRUQueryCache.java:167-177Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/PhraseWeight.java:46-51; PhraseScorer.java:84-95; PhraseQuery.java:476-488; LRUQueryCache.java:451, 458, 792-807, 816, 846-856; IndexSearcher.java:274
- Who is affected
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/RescoreTopNQuery.java:34, 272-331 (factories)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/AbstractFullPrecisionVectorSimilarityValuesSource.java:140-141; LateInteractionFloatValuesSource.java:106-107 (needsScores false)
- Why it looks unintended
Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/search/RescoreTopNQuery.java:26-34, 58, 74-79, 230-236; ScoreMode.java:25; DoubleValuesSource.java:43-46, 350Lucene main ea57360912ed: lucene/CHANGES.txt:1562-1563Lucene main ea57360912ed: lucene/queries/src/java/org/apache/lucene/queries/function/FunctionScoreQuery.java:109-122; lucene/queries/src/test/org/apache/lucene/queries/function/TestFunctionScoreQuery.java:303-323Lucene main ea57360912ed: lucene/core/src/test/org/apache/lucene/search/TestDoubleValuesSource.java:310-312Lucene main ea57360912ed: lucene/test-framework/src/java/org/apache/lucene/tests/search/AssertingWeight.java:74; AssertingScorer.java:125-126
- Suggested fix
Lucene main ea57360912ed: lucene/queries/src/java/org/apache/lucene/queries/function/FunctionScoreQuery.java:109-122; lucene/core/src/java/org/apache/lucene/search/IndexSearcher.java:979-981
- TestRescoreTopNQueryScoresSource.java (JUnit test):
repro/LFV-315/src/org/apache/lucene/search/TestRescoreTopNQueryScoresSource.java(53 lines)
The summary card (bug.png) shows the lexical case step by step, the kNN timeline, expected against actual, and the three contract sentences. Every value on screen comes from the printing probe run on ea57360912ed. The alt text follows the scene script's summary card as drafted when this doc was written.
assets/LFV-315/bug.png(520 KB)