HTMLStripCharFilter removes tags and keeps the text between them. Its grammar lets a backslash escape a quote inside a quoted attribute value, which HTML does not do. So a value that ends in a backslash can be read as still open, and the scanner keeps the longest reading.
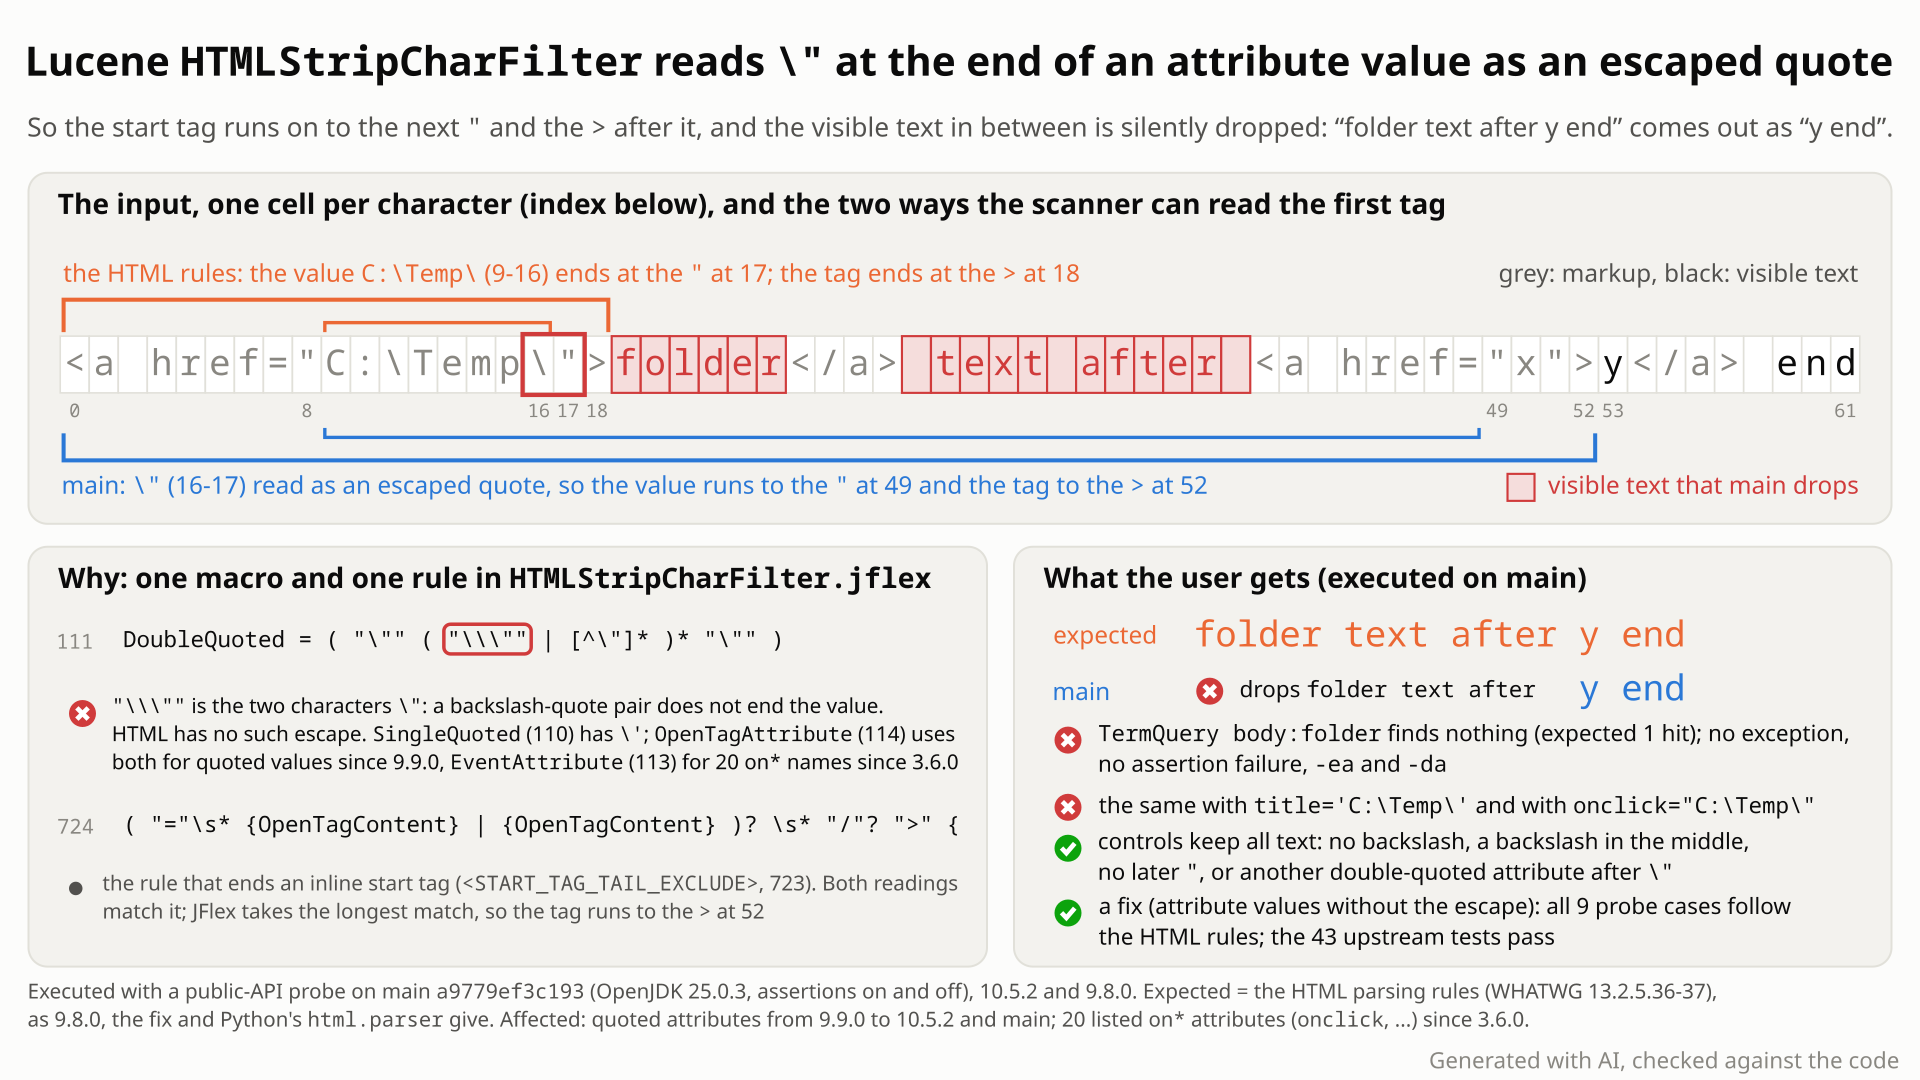
- Strip
<a href="C:\Temp\">folder</a> text after <a href="x">y</a> endwithHTMLStripCharFilter. The first link points to a Windows folder, so its quoted value ends in a backslash. - You expect
folder text after y end. In HTML a backslash means nothing inside an attribute value: the value ends at the next". Lucene 9.8.0, an independent HTML parser and the same input without the trailing backslash all give this. - You get
y end: 3 of the 5 words are gone, with no error. The scanner reads\"as an escaped quote, keeps the value open up to the next"(inhref="x") and removes everything up to the second tag's>as one tag. - Indexed, a
TermQueryfor a hidden word misses the document andCheckIndexis clean. Single quotes (title='C:\Temp\') andonclickvalues lose text the same way, and inside a<p>a whole paragraph can vanish.
Applications that strip HTML with HTMLStripCharFilter, its htmlStrip factory or a downstream html_strip char filter, on 9.9.0 or later. The trigger is legal but uncommon: a quoted value ending in a backslash, mostly Windows paths. The text up to the next quote of the same kind silently goes missing from the index.
Mechanism, terms and numbers969 words
HTMLStripCharFilter's quoted-value macros (HTMLStripCharFilter.jflex:110-111) accept a backslash followed by the quote character as part of the value, a rule from the 2012 JFlex rewrite that is also used for server-side-include strings. HTML has no such escape: a quoted value ends at the next matching quote. When a value ends in a backslash, as a Windows folder path does (href="C:\Temp\"), the scanner can read the backslash and the real closing quote as an escaped quote and keep the value open to the next quote of the same kind. The start-tag rule takes the longest match, so that reading wins: everything from the first tag to the end of the next tag that has such a quote is removed as one tag, and the visible text in between never reaches the index. <a href="C:\Temp\">folder</a> text after <a href="x">y</a> end strips to y end instead of folder text after y end; a TermQuery for a hidden word misses the document, CheckIndex is clean and no exception is raised. The 20 event attributes the grammar lists (onclick, onload, ...) have behaved this way since 3.6.0; #11724 (9.9.0) reused the macros for every quoted attribute whose name matches the grammar's Name macro, so href, title, alt, class, data-* and other on* values lose text since 9.9.0 (9.8.0 kept it). The run-on tag can also swallow a <script> start tag, and then script text is indexed. The fix gives attribute values their own macros without the escape; with it, :lucene:analysis:common:test passes (1,913 tests, 18 skipped, 0 failures).
HTMLStripCharFilter: aCharFilterinlucene/analysis/commonthat removes HTML markup and decodes character references before tokenization; it is used directly, through thehtmlStripfactory, or through downstreamhtml_stripchar filters. Its scanner is generated by JFlex fromHTMLStripCharFilter.jflex.- Quoted attribute value: the
"..."or'...'aftername=in a start tag. In HTML it ends at the next quote of the same kind; only&, NUL and end of input are special inside it (WHATWG 13.2.5.36-37). - Longest match: JFlex picks the rule and the reading that consume the most input. When the grammar allows two readings of a start tag, the longer one wins.
- The value macros accept an escaped quote (
HTMLStripCharFilter.jflex:110-111):
   SingleQuoted = ( "'" ( "\\'" | [^']* )* "'" )
   DoubleQuoted = ( "\"" ( "\\\"" | [^\"]* )* "\"" )
Inside the quotes: a backslash followed by the quote character, or any run of other characters, <, > and \ included. So "C:\Temp\" matches either as the value C:\Temp\ or with \" as an escaped quote and the value still open.
- Attribute rules use these macros:
EventAttribute(:113, since 3.6.0) for the 20 event attributes listed inEventAttributeSuffixes(:89-109:onclick,onload,onmouseover, ...) andOpenTagAttribute(:114, added by #11724 in 9.9.0) for everyname=attribute whose name matchesName(:69), both insideOpenTagContent(:115). - The start-tag tail
( "="\s* {OpenTagContent} | {OpenTagContent} )? \s* "/"? ">"(:714-745) takes the longest match. For<a href="C:\Temp\">folder</a> text after <a href="x">y</a> end:- reading 1 ends the value at the real quote and the tag at the next
>; - reading 2 takes
\"as escaped, runs through>folder</a> text after <a href=to the next", eatsx"as plain tag text and ends at the second tag's>. Reading 2 is longer and wins:<a href="C:\Temp\">folder</a> text after <a href="x">is one "tag", removed without replacement (an inline element) or replaced by a newline (a block element,:149).
- reading 1 ends the value at the real quote and the tag at the next
- Reading 2 needs a later quote of the same kind (
[^"]*skips single quotes) and then a>with no<in between. If a later attribute with the same quote kind follows in the same tag, both readings end at the same>and nothing is lost; a later attribute in the other quote kind does not help:<a href="C:\Temp\" class='c'>still givesy end. - Before #11724, ordinary attribute values (and
on*names outside the list) were consumed one character at a time by[^<>], so the first>ended the tag: 9.8.0 keeps the text. #11724 addedOpenTagAttributeso that<and>inside quoted values no longer end a tag, and reused the macros, escape included.
| input | expected | main |
|---|---|---|
<a href="C:\Temp\">folder</a> text after <a href="x">y</a> end | folder text after y end | y end |
<a title='C:\Temp\'>folder</a> text after <a title='x'>y</a> end | folder text after y end | y end |
<a onclick="C:\Temp\">folder</a> text after <a onclick="x">y</a> end | folder text after y end | y end (also on 3.6.0-9.8.0) |
<p data-path="C:\Temp\">para one</p><p class="x">para two</p> | para one and para two | para two only |
control: href="C:\Temp" (no trailing backslash) | folder text after y end | correct |
control: href="C:\Temp\" class="c" (a later double-quoted attribute in the same tag) | folder text after y end | correct |
href="C:\Temp\" class='c' (a later single-quoted attribute in the same tag) | folder text after y end | y end |
<a onpointerdown="C:\Temp\"> (an on* name outside the list) | folder text after y end | y end (9.8.0 keeps the text) |
<p>visible <a title="\">link</a></p><script>var t="x">scripttext</script> after | visible link after | visible scripttext after: link lost, script text output |
Also correct on main: a backslash in the middle of the value, no later quote of the same kind, only a later quote of the other kind outside the tag, a later same-kind quote followed by a < before any >, or an attribute name that Name rejects (@click). In a probe where 40 words without a double quote followed the trigger, all 40 were dropped. With escapedTags containing the tag, the run-on start tag is output verbatim instead, the swallowed text and markup included.
Exposure and likelihood309 words
- Who is exposed. Users of
HTMLStripCharFilterdirectly, through thehtmlStripSPI factory (HTMLStripCharFilterFactory.java:42), or through a downstreamhtml_stripchar filter built on it. No Lucene analyzer adds it by default: opt-in, but a stock component that needs no special setting. - What the damage looks like. Browser-visible text is missing from the char-filter output and so from the index: a term query for a hidden word misses the document and delete-by-term leaves it live, while text after the hidden span is indexed normally and
CheckIndexis clean. No exception, with assertions on or off. When the run-on tag swallows a<script>start tag, the script body is indexed instead: the same bug can add terms. - What it takes. A quoted attribute value whose last character is a backslash, no later quote of the same kind in the same tag, and a later quote of the same kind in the document followed by a
>with no<in between. Plausible sources: Windows paths (href="C:\Temp\", UNC\\server\share\),alt="\"for a backslash key, code or regex samples. HTML escaping leaves a backslash unchanged, so plain text that a site escapes into an attribute can trigger it too. How often this occurs in real pages was not measured. - How much is lost. Everything up to that later quote and the next
>: usually the text up to the next tag with a quoted attribute, a whole paragraph in the block case, 40 words in one probe. Deterministic in every run (inputs up to about 1,000,000 characters). - Versions. Quoted attributes whose names match
Name: 9.9.0 to 10.5.2 and main; the 20 listed event attributes (onclick, ...): from 3.6.0. - How likely. Rare: values ending in a backslash are uncommon in real pages, and no report was found since 9.9.0 (or 2012 for the listed event attributes).
The test shows that HTMLStripCharFilter drops visible text when a quoted attribute value ends in a backslash (href="C:\Temp\"): the backslash is read as escaping the closing quote, so the tag runs on to the next double quote.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.charfilter;

import java.io.Reader;
import java.io.StringReader;
import java.io.StringWriter;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestHTMLStripAttributeBackslash extends LuceneTestCase {

  public void testAttributeValueEndingInBackslash() throws Exception {
    String html = "<a href=\"C:\\Temp\\\">folder</a> text <a href=\"x\">y</a>";
    StringWriter out = new StringWriter();
    try (Reader r = new HTMLStripCharFilter(new StringReader(html))) {
      r.transferTo(out);
    }
    // expected "folder text y"; actual "y": the backslash is read as escaping the closing quote
    assertEquals("folder text y", out.toString());
  }
}
# in a copy of this finding's repro folder (repro/LFV-317/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.charfilter.TestHTMLStripAttributeBackslash
- Expected vs actual
- Expected
folder text y(what 9.8.0 and the fixed grammar give); actualy(expected:<[folder text ]y> but was:<[]y>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: expected:<[folder text ]y> but was:<[]y>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.analysis.charfilter.TestHTMLStripAttributeBackslash.testAttributeValueEndingInBackslash(TestHTMLStripAttributeBackslash.java:33)- In HTML a quoted attribute value ends at its matching quote; a backslash means nothing there. Lucene 9.8.0 and Python's
html.parserkeep the text. - #11724 (9.9.0) aimed at HTML5 attribute rules and reused the escaping macros; its review saw "no logical changes".
- Upstream fixed the same symptom as a bug in #15754: "prevent tags from incorrectly consuming subsequent HTML".
The full argument335 words
- HTML rules. The WHATWG tokenizer's attribute value (double-quoted) and (single-quoted) states end the value at the matching quote; only
&, NUL and end of input are special. Python'shtml.parser, run as an independent reference, readshrefasC:\Temp\and keepsfolder text after y end, also fortitle,onclickand the paragraph case. - Earlier behaviour. 9.8.0, 8.11.4, 4.0.0 and 3.6.0 keep the text for ordinary attributes (executed); the releases in between have the same
OpenTagContentline, withoutOpenTagAttribute. - #11724's goal. Its PR body: "'<' and '>' characters are acceptable in attribute values per the HTML5 spec". A reviewer (rmuir) looked at the generated code: "I only see smaller DFAs, not any 'logical changes'". Neither the PR nor #11556 mentions backslashes. CHANGES lists it under 9.9.0 Bug Fixes (
CHANGES.txt:3278). - Precedent. "GITHUB#15754: Fix HTMLStripCharFilter to prevent tags from incorrectly consuming subsequent HTML when an attribute value ends with an equals sign." (
CHANGES.txt:1160-1161, 10.5.0 Bug Fixes). Its four tests (TestHTMLStripCharFilter.java:652-713) expect only the tags to be removed. - Where the escape came from. The 2012 grammar introduced the escape-aware macros for server-side-include strings and the listed event attributes at the same time; nothing records them as meant for ordinary attribute values. The upstream tests that use
\'or\"do so inside a server-side-include string (testServerSideIncludes,:400-411) and inside a<!-- -->comment in a script (testScriptQuotes,:413-422). Quoted strings in such comments, and in server-side includes nested in comments, have their own states with an escape rule (HTMLStripCharFilter.jflex:848-858). No upstream test has an attribute value ending in a backslash; the onetestMalformedHTMLinput with\"in an attribute (:168) strips the same either way, and every:lucene:analysis:commontest passes with the fix. - No contract for the escape. The class javadoc only says it "attempts to strip out HTML constructs" (
HTMLStripCharFilter.jflex:31); nothing documents backslash escapes in attribute values. The contract is behavioural, not a javadoc promise.
The devil's-advocate check224 words
The strongest case for "intended": (a) the escape is deliberate grammar, written in the 2012 rewrite and applied to the listed event attributes from the start, so 9.9.0 could be read as a deliberate extension; (b) the filter is best effort ("attempts to strip"), and committers have said that "right" is not well defined for broken HTML; (c) the escape helps some malformed input: for <a title="5 \" > 3">x</a> after, main gives x after, closer to what the author meant, while 9.8.0, the fix and html.parser give 3">x after; (d) the event-attribute half has stood for nearly 15 years (since January 2012) without a report found, and changing it alters indexed output for existing users.
Why it fails: the trigger is valid HTML that 9.8.0 handled correctly, and the best-effort caveat covers malformed input; #11724 aimed at HTML5 attribute semantics, and no recorded discussion in it addresses backslashes; the case (c) benefit is narrow, while the cost falls on valid documents, up to whole paragraphs; for event attributes the HTML tokenizer also ends the attribute at the quote, whatever JavaScript does inside; and a long silence is not a decision: no issue, test or discussion accepts it. The case for "intended" is moderate for the event-attribute half: a committer may prefer to keep it, and fix option B does that.
Recommended A. Escape-free value macros for attribute values
Give EventAttribute and OpenTagAttribute their own quoted-value macros without the backslash escape, keep the escape for server-side-include strings, and regenerate the scanner. Validated: the new tests pass, :lucene:analysis:common:test passes (1,913 tests, 18 skipped, 0 failures), check passes, and the generated scanner gets smaller.
 SingleQuoted = ( "'" ( "\\'" | [^']* )* "'" )
 DoubleQuoted = ( "\"" ( "\\\"" | [^\"]* )* "\"" )
 ServerSideInclude = ( "<!--#" ( [^'\"] | {SingleQuoted} | {DoubleQuoted} )* "-->" )
-EventAttribute = \s+ [oO][nN] {EventAttributeSuffixes} \s* "=" \s* ( {SingleQuoted} | {DoubleQuoted} )
-OpenTagAttribute = \s+ {Name} \s* "=" \s* ( {SingleQuoted} | {DoubleQuoted} )
+// HTML attribute values have no backslash escapes (unlike the server-side-include strings above)
+AttributeSingleQuoted = ( "'" [^']* "'" )
+AttributeDoubleQuoted = ( "\"" [^\"]* "\"" )
+EventAttribute = \s+ [oO][nN] {EventAttributeSuffixes} \s* "=" \s* ( {AttributeSingleQuoted} | {AttributeDoubleQuoted} )
+OpenTagAttribute = \s+ {Name} \s* "=" \s* ( {AttributeSingleQuoted} | {AttributeDoubleQuoted} )
 OpenTagContent = ( {EventAttribute} | [^<>] | {ServerSideInclude} | {OpenTagAttribute} )*
All options and trade-offs3 options · 611 words
Three grammar options were applied in a scratch worktree of a9779ef3c193, each with the scanner regenerated by ./gradlew :lucene:analysis:common:regenerateHTMLStripCharFilter (JFlex 1.9.1; it also updates the checksum file), and run against TestHTMLStripCharFilter with the four new tests, assertions on and off.
Add AttributeSingleQuoted / AttributeDoubleQuoted without the \' / \" alternative, use them in EventAttribute and OpenTagAttribute, leave SingleQuoted / DoubleQuoted for server-side-include strings, then regenerate HTMLStripCharFilter.java.
 SingleQuoted = ( "'" ( "\\'" | [^']* )* "'" )
 DoubleQuoted = ( "\"" ( "\\\"" | [^\"]* )* "\"" )
 ServerSideInclude = ( "<!--#" ( [^'\"] | {SingleQuoted} | {DoubleQuoted} )* "-->" )
-EventAttribute = \s+ [oO][nN] {EventAttributeSuffixes} \s* "=" \s* ( {SingleQuoted} | {DoubleQuoted} )
-OpenTagAttribute = \s+ {Name} \s* "=" \s* ( {SingleQuoted} | {DoubleQuoted} )
+// HTML attribute values have no backslash escapes (unlike the server-side-include strings above)
+AttributeSingleQuoted = ( "'" [^']* "'" )
+AttributeDoubleQuoted = ( "\"" [^\"]* "\"" )
+EventAttribute = \s+ [oO][nN] {EventAttributeSuffixes} \s* "=" \s* ( {AttributeSingleQuoted} | {AttributeDoubleQuoted} )
+OpenTagAttribute = \s+ {Name} \s* "=" \s* ( {AttributeSingleQuoted} | {AttributeDoubleQuoted} )
 OpenTagContent = ( {EventAttribute} | [^<>] | {ServerSideInclude} | {OpenTagAttribute} )*
Trade-offs
- Also changes the listed event attributes (
onclick, ...), which have read\"as an escape since 2012 (the HTML rule applies to them too). - A malformed value naively escaped with a backslash and containing
>after the escape now strips like 9.8.0 and HTML parsers do, not like main. - Server-side includes keep the escape, also inside a tag (
{ServerSideInclude}inOpenTagContentstill uses the escape-aware macros). - The new tests check the stripped text only, not offsets; the existing offset tests pass.
What the checks validated
- The four new tests pass;
TestHTMLStripCharFilter40 of 40 with assertions on and off. - All of
:lucene:analysis:common:test(assertions on): 339 classes, 1,913 tests, 18 skipped, 0 failures. :lucene:analysis:common:check -x testpasses (generated-source checksums, google-java-format, ecjLint, forbiddenApis).- The generated scanner shrinks from 428,378 to 391,691 bytes.
- Earlier, with the hunt's own regeneration: the independent checkers' tests and probes keep the text, and
TestHTMLStripCharFilterplusTestHTMLStripCharFilterFactorypass (43 tests). - With the fix's scanner shadowed, the other-quote-kind cases,
onpointerdownand the<script>case keep their text (resolution probe).
Use the escape-free macros only in OpenTagAttribute; keep EventAttribute as it is.
Trade-offs
Keeps the listed event attributes' behaviour of nearly 15 years, bug included: for onclick both rules match and the longer escape reading still wins. The generated scanner grows from 428,378 to 7,164,352 bytes.
What the checks validated
The double- and single-quoted tests and the control pass; testBackslashAtEndOfEventAttributeValue still fails (40 tests, 1 failed, assertions on and off).
Change SingleQuoted / DoubleQuoted themselves to ( "'" [^']* "'" ) / ( "\"" [^\"]* "\"" ): a 2-line diff.
Trade-offs
Smallest diff, but it also removes the escape from server-side-include strings inside a tag, one of the two places the 2012 grammar used it. The one upstream test with escaped quotes in an in-tag server-side-include string (testServerSideIncludes, TestHTMLStripCharFilter.java:403) has balanced escaped quotes and strips the whole tag either way, so it passes; no upstream test depends on the escape there, and the effect on input that does is unverified. A changes less for the same benefit.
What the checks validated
The four new tests and all 40 TestHTMLStripCharFilter tests pass with assertions on and off, testServerSideIncludes included; all of :lucene:analysis:common:test passes (1,913 tests, 18 skipped, 0 failures); scanner 364,122 bytes. check was not run for this option.
Downstream html_strip char filters wrap this class (an OpenSearch html_strip report led to #15754, the same symptom with another trigger), so their indexes would lose the same text (inferred; not run on a downstream product).
A grammar-based fuzzer generated random HTML-like documents and checked that every plain-text word survives stripping. Excluding the classes it found one by one isolated this one: with backslashes, script and style content and one sibling shape excluded, 1,000,000 documents lost nothing.
The method in full136 words
Method: random grammar-based fuzzing (registry tier non-formal), a hunt unit.
- The fuzzer builds random HTML-like documents from constructs the HTML5 tokenizer defines (not checked by a conformance validator) and checks the oracle "every plain-text word between constructs appears in the output", then minimises each violation to a shape.
- Stock run (seed 1, 100,000 documents): 8,977 documents lost text, 8,472 distinct minimal shapes; most were script/style cases (the sibling LFV-311), and some had a backslash before a value's closing quote.
- With script/style content and backslashes excluded (seed 2, 300,000 documents), only 12 shapes remained, all with
name=inside a value (the sibling LFV-290). Excluding those too (seed 3), 1,000,000 documents lost nothing, which isolated this class. - The finder then wrote the public-API JUnit, bisected with release jars and a commit-level scanner swap, and wrote the grammar fix.
No prior report found (searched 2026-10-26, re-checked 2026-10-27): GitHub issues and PRs, commits, four mailing lists, JIRA, downstream projects and the web. The closest, #15754 (fixed in 10.5.0), has the same symptom with a different trigger, rule and fix.
Searches6 searches
No report was found of the backslash trigger or the escape in the attribute-value macros, in Lucene or downstream.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search | 2026-10-26 | 57 queries: 16 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list (dev@, java-user@, issues@, commits@), 4 JIRA, 12 web; 193 hits, titles reviewed, medium hits read in full | no report |
| GitHub (manual) | 2026-10-26 | 15 searches over apache/lucene, all of GitHub, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, apache/lucenenet | no report |
| JIRA and list archives | 2026-10-26 | 6 JQL queries over LUCENE and SOLR; the full HTMLStripCharFilter result sets of the archives (341 mails) grepped for backslash and escape | no report; SOLR-2328 (Won't Fix) is a different defect on the pre-JFlex filter |
| Open apache/lucene PRs | 2026-10-26 | changed files of every PR with a module:analysis label (15) or no module label (153) | none touches the grammar or the generated scanner |
| Related items (read in full) | 2026-10-26 | #15754, #15756, #11724 and its review, #11556, #13157, #4764 (LUCENE-3690), OpenSearch #20554 and #20575 | same symptom family only: #15754's trigger is a value ending in '=', fixed by requiring whitespace before attribute names |
| GitHub re-check | 2026-10-27 | read-only gh search, 2026-10-27: newest apache/lucene issues and PRs naming HTMLStripCharFilter; 'html strip backslash', 'HTMLStrip attribute backslash', 'HTMLStripCharFilter backslash' | nothing newer than #15754 / #15756; no hits |
Ordinary quoted attributes since 9.9.0, introduced by #11724 (merged 2023-10-02), which reused the escaping macros for every attribute value; the 20 listed event attributes (onclick, ...) since 3.6.0 (LUCENE-3690, 2012). Affects 10.5.2, 9.12.3 and main; not fixed upstream.
Versions tested6 rows
Introduced by #11724 "LUCENE-10520 / #11556 HTMLStripCharFilter bugfix" (by elliotzlin, merged by dweiss on 2023-10-02; main 4cff584a489, branch_9x fc174052719) for ordinary attributes, and by LUCENE-3690, the JFlex rewrite (f3a363708ff, 2012-01-22; branch_3x d387ae60fcf), for the 20 event attributes the grammar lists. #15756 (10.5.0) did not touch the macros. Upstream main a95c754ee003 (fetched 2026-10-26) has the same grammar as a9779ef3c193; branch_10x and branch_10_6 have no grammar commit after #15756; no open PR changes the grammar.
Not executed one by one: 9.9.1-9.12.2, 10.1.0-10.3.2 and 10.5.1 (tag containment and an identical scanner source); x86 (pure scanner logic).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193, ea57360912ed | affected | the four new tests: 3 fail through gradle (assertions on and off); the standalone JUnit 2 of 3 fail |
| 10.5.2, 10.5.0, 10.4.0, 10.0.0, 9.12.3, 9.9.0 | affected | standalone JUnit 2 of 3 fail (assertions on): y end instead of folder text after y end |
| 9.8.0 | listed on* only | ordinary attributes keep the text (3 of 3 pass); onclick loses it (main() probe); onpointerdown, not in the list, keeps it (resolution probe) |
| 8.11.4, 4.0.0, 3.6.0 | listed on* only | ordinary attributes keep the text; onclick loses it (main() probes) |
9.9.0 jars with the scanner of fc174052719's parent | bisect | pass 3 of 3 |
9.8.0 jars with the scanner of fc174052719 (#11724) | bisect | fail 2 of 3 |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication and a credibility audit each re-ran it on main and confirmed it. A reviewer from another model family, reading only, judged it real in one review and "not real" in another; that verdict came from its need for an executed repro of its own, which it could not run.
Checks and verdicts362 words
Each check ran or re-ran a public-API test on the stock main jars; the run records are in the sources.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only; it had no executed repro of its own. Most of its points support real; two support "not real": existing tests with backslash-escaped quotes and the class's "attempts to strip" wording (both answered in "Why it is a bug"). A separate run re-ran the repro: fails 2 of 3. |
| Independent reproducer | real | Own 6-test JUnit (3 controls pass, 3 defect tests fail) on main with assertions on and off, 10.5.2, 9.12.3 and 9.9.0; 9.8.0 passes; found the onclick loss on 9.8.0 and 8.11.4; passes 6 of 6 with the fix. |
| Works-as-designed review | real (medium) | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens, reading only: the javadoc's "attempts" does not outweigh the HTML rules, 9.8.0 and #15754. |
| Intended-behaviour devil's advocate | real (high; moderate for the event attributes) | Built the strongest "intended" case and rejected it; WHATWG and Python's html.parser agree with 9.8.0 and the fix; probes on main, 9.9.0, 9.8.0, 4.0.0 and the fix. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's test (3 of 6 fail, assertions on and off) and the finder's (2 of 3), the independent reproduction's on 9.8.0 (pass) and 9.9.0 (fail); corrected the version scope. |
| Credibility audit | keep | New seed and new inputs (UNC path, single-quoted alt, data-path) at read-buffer sizes 1, 3 and 4096: every defect shape loses text on main and 10.5.2, none on 9.8.0 or with the fix. |
| This doc's validation | reproduces; fix A validated | Gradle on a9779ef3c193: the new tests fail on stock and pass with fix A; fix A passes the module's tests (1,913, 18 skipped, 0 failures) and check. |
| Fact checks of this doc | corrections applied | A fact check, a cross-model fact check (OpenAI GPT-5.6) and a diagram check re-ran the repro and probes; their corrections (event-attribute scope, the same-quote-kind bound, the script case, wording) are applied and re-run where new claims needed it. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 459 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,449 words
- Registry title
- HTMLStripCharFilter reads a backslash right before a quoted attribute value's closing quote as an escaped quote, so the tag runs on to the next quote of the same kind and the visible text in between is dropped (every quoted attribute since 9.9.0 / GITHUB#11724; on* event attributes since the 2012 JFlex rewrite)
- Area
- analysis / HTMLStripCharFilter (JFlex grammar: SingleQuoted, DoubleQuoted, OpenTagAttribute, EventAttribute)
- Priority
- Low, rank 303: The char filter is widely used, but only a quoted attribute value that ends in a backslash, a legal but uncommon input unreported since 9.9.0, triggers the text loss.
- Impact class
- silent wrong results
- Impact note
- Applications that strip HTML with HTMLStripCharFilter (directly, through the 'htmlStrip' factory, or through a downstream html_strip char filter; no Lucene analyzer adds it by default) lose, from the char-filter output and so from the index, the visible text after any tag in which a quoted attribute value ends in a backslash (for example a Windows directory path, href="C:\Temp\" or title="dir\") and that backslash-quote is the tag's last quote, up to the next quote of the same kind in the document and the next '>' after it (in ordinary HTML usually the next tag's quoted attribute); the loss is deterministic at any scale, with -ea and -da, with no exception and a clean CheckIndex, for every quoted attribute since 9.9.0 and for on* attributes since 3.6.0.
- Summary
- You strip '<a href="C:\Temp\">folder</a> text after <a href="x">y</a> end' with HTMLStripCharFilter and expect 'folder text after y end', which is what 9.8.0, the HTML parsing rules (Python's html.parser as an independent check) and the same document without the trailing backslash give. Instead main returns 'y end': the scanner reads the backslash and the closing quote as an escaped quote, so the attribute value runs on to the next double quote (the one in href="x"), everything from the first tag to the end of the second tag is treated as one tag, and 'folder text after' is never indexed. No error is raised, and a single-quoted value ending in a backslash loses text the same way.
- Introduced
- Layered, one root cause. Ordinary quoted attributes: 4cff584a48941c5c00bbcfaedf799b629dcc7806 (PR #11724, GITHUB#11556 / LUCENE-10520, by GitHub elliotzlin, merged by dweiss; branch_9x backport fc17405271983e27770993d277f144f1f5cc8f94), which added OpenTagAttribute = {Name} \s* "=" \s* ( {SingleQuoted} | {DoubleQuoted} ) to OpenTagContent and so applied the existing backslash-escape macros to every attribute value [exec: commit-level scanner swap, 9.9.0 jars with the fc174052719^ scanner pass the finder's JUnit 3 of 3 and 9.8.0 jars with the fc174052719 scanner fail 2 of 3]. On* event attributes: f3a363708ff95f28b5f29fe2cc27c1cd9fd0fca9 (LUCENE-3690 / GitHub #4764, the JFlex rewrite, svn era, no PR; branch_3x d387ae60fcf7ecb65596b756a0f8fc79923d0370), which wrote SingleQuoted / DoubleQuoted with the \' / \" escape alternative and used them for EventAttribute and server-side-include strings [read: git blame of HTMLStripCharFilter.jflex:110-112; exec: 3.6.0 loses text for onclick="...\"]. PR #15756 (GITHUB#15754, 10.5.0) did not touch these macros [read; exec: the finder's JUnit fails 2 of 3 on 10.4.0 and on 10.5.0] (2023-10-02 (PR #11724 merged; ordinary quoted attributes); 2012-01-22 (LUCENE-3690 on trunk, branch_3x 2012-01-24; on* event attributes))
- First affected version
- 9.9.0 [exec] for ordinary quoted attributes (9.8.0 passes the finder's JUnit 3 of 3 and the independent reproduction's 6 of 6); 3.6.0 [exec] for on* event attributes (the class first shipped in Lucene in 3.6.0)
- Affected versions
- Ordinary quoted attributes (href, title, alt, class, data-, ...): 9.9.0 to 9.12.3, 10.0.0 to 10.6.0 (10.6.0 by reading) and main ea57360912ed [exec: 9.9.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0, 10.5.2 and main -ea and -da; the releases in between by tag containment of 4cff584a489 / fc174052719 and a byte-identical generated scanner from 9.9.0 to 10.4.0, read]. On event attributes (onclick, ...): every release from 3.6.0 to 10.6.0 (10.6.0 by reading) and main [exec: 3.6.0, 4.0.0, 8.11.2, 8.11.4, 9.8.0, 9.9.0, main; the macro and EventAttribute lines are unchanged in between, read]. 10.6.0 (by reading), 10.5.2 and 9.12.3 (the latest 9.x release) are affected. Not fixed upstream: upstream main e1c4184cb983 (2026-10-26), branch_10x and branch_10_6 have the same macros, and no open PR touches the grammar [read]. Not run: 10.5.1 (same scanner source as 10.5.0 and 10.5.2), x86 (pure scanner logic)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (searched 2026-10-26, read-only; the prior-report record: the scripted prior-report search with 57 queries (16 GitHub issue/PR, 3 commit, 2 downstream-repo, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA, 12 web; 193 hits, all titles reviewed, every medium hit read in full), 15 manual GitHub searches over apache/lucene, all of GitHub, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr and apache/lucenenet, 6 JQL queries over LUCENE and SOLR, list-archive searches including the full HTMLStripCharFilter result sets (341 mails) grepped for backslash and escape, and a changed-file scan of the open apache/lucene PRs with a module:analysis label (15) or no module label (153); the finder's and the intended-behaviour check's earlier searches found nothing either). Not fixed upstream: upstream main e1c4184cb983 (2026-10-26), branch_10x and branch_10_6 have no commit to HTMLStripCharFilter.jflex after #15756, and no open PR touches the grammar. Nearest items, none a report of this bug: apache/lucene#15754 (closed; fixed by #15756 in 10.5.0) and its precursors (a comment by GitHub mjustice3 on #11724, the open test-only PR #13157, opensearch-project/OpenSearch#20554 and #20575) share the symptom (a tag swallows later text up to the next same-kind quote) but have a different trigger (a value ending in '='), defective rule and fix; #11724 (the 9.9.0 origin for ordinary attributes; its review never mentions backslashes); LUCENE-3690 / #4764 (introduced the escaping macros; its comments do not discuss backslashes in attribute values); SOLR-2328 (Won't Fix; backslash-escaped quotes in its input, but a different defect on the pre-JFlex filter). Gaps: GitHub search was rate-limited at times (every limited query was retried); closed unmerged PRs that do not name the class are not findable by search; list bodies are matched only through the archive's own full-text index
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: four newTestHTMLStripCharFiltermethods with assertions on and off (stock: 3 of 4 fail; fix A: all pass), fix A with all of:lucene:analysis:common:testand:lucene:analysis:common:check -x test, fix C with all of:lucene:analysis:common:test, fix B with the suite, each scanner regenerated by the build's own task; the worktree was removed afterwards. Mainea57360912edand the Maven Central jars 9.8.0, 9.9.0, 9.12.3, 10.0.0, 10.4.0, 10.5.0 and 10.5.2 with the hunt's standalone JUnit;main()probes on 3.6.0, 4.0.0, 8.11.4, 9.8.0, 9.9.0 and main; a commit-level scanner swap atfc174052719; the independent checkers' tests and probes on main, 10.5.2, 9.12.3, 9.9.0, 9.8.0, 8.11.4, 8.11.2 and 4.0.0; a re-run ona9779ef3c193(still reproduces); a resolution probe for the fact checks (quote kinds inside the tag, anon*name outside the list, a nameNamerejects, the<script>case) on main with assertions on and off, main with fix A, 9.8.0 and 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex :31 (class javadoc 'attempts to strip out HTML constructs'), :110-115 (SingleQuoted, DoubleQuoted, ServerSideInclude, EventAttribute, OpenTagAttribute, OpenTagContent), :714-745 (START_TAG_TAIL_INCLUDE, _EXCLUDE, _SUBSTITUTE rules)lucene/CHANGES.txt :1144-1145 (10.5.0 Bug Fixes, GITHUB#15754) and :3262 (9.9.0, GITHUB#11556)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:110-115 (macros and attribute rules), :693-712 (tag-name dispatch), :714-745 (START_TAG_TAIL_* rules), :149 (block replacement)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:69 (Name), :89-109 (EventAttributeSuffixes, 20 names)
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilterFactory.java:42 (SPI name htmlStrip)
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/CHANGES.txt:1158-1161 (10.5.0 Bug Fixes, GITHUB#15754), :3269-3278 (9.9.0 Bug Fixes, GITHUB#11556)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:168, :400-411, :413-422, :652-713a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:31 (class javadoc), :848-858 (script/style string escapes)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/HTMLStripCharFilter.jflex:805, :819-828, :833-835, :841-843 (entry into the quoted-string states)
- Suggested fix
a Lucene main checkout (a9779ef3c193) lucene/core/build.gradle:260-273 (regenerateHTMLStripCharFilter task)a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestHTMLStripCharFilter.java:400-411 (testServerSideIncludes, line 403), :336-375 (offset tests)
- History
a Lucene clone release tags (releases/lucene/9.8.0 lacks fc174052719, 9.9.0 contains it)
- TestHTMLStripAttributeBackslash.java (JUnit test):
repro/LFV-317/src/org/apache/lucene/analysis/charfilter/TestHTMLStripAttributeBackslash.java(35 lines)
Summary card (bug.png), made in parallel with this doc from the grammar at a9779ef3c193 and executed probe runs; see the diagram notes.
assets/LFV-317/bug.png(459 KB)