A merged view puts the inputs end to end; document N belongs to the last input that starts at or before N. An empty input starts where the next one starts, and the lookup can stop on the empty one.
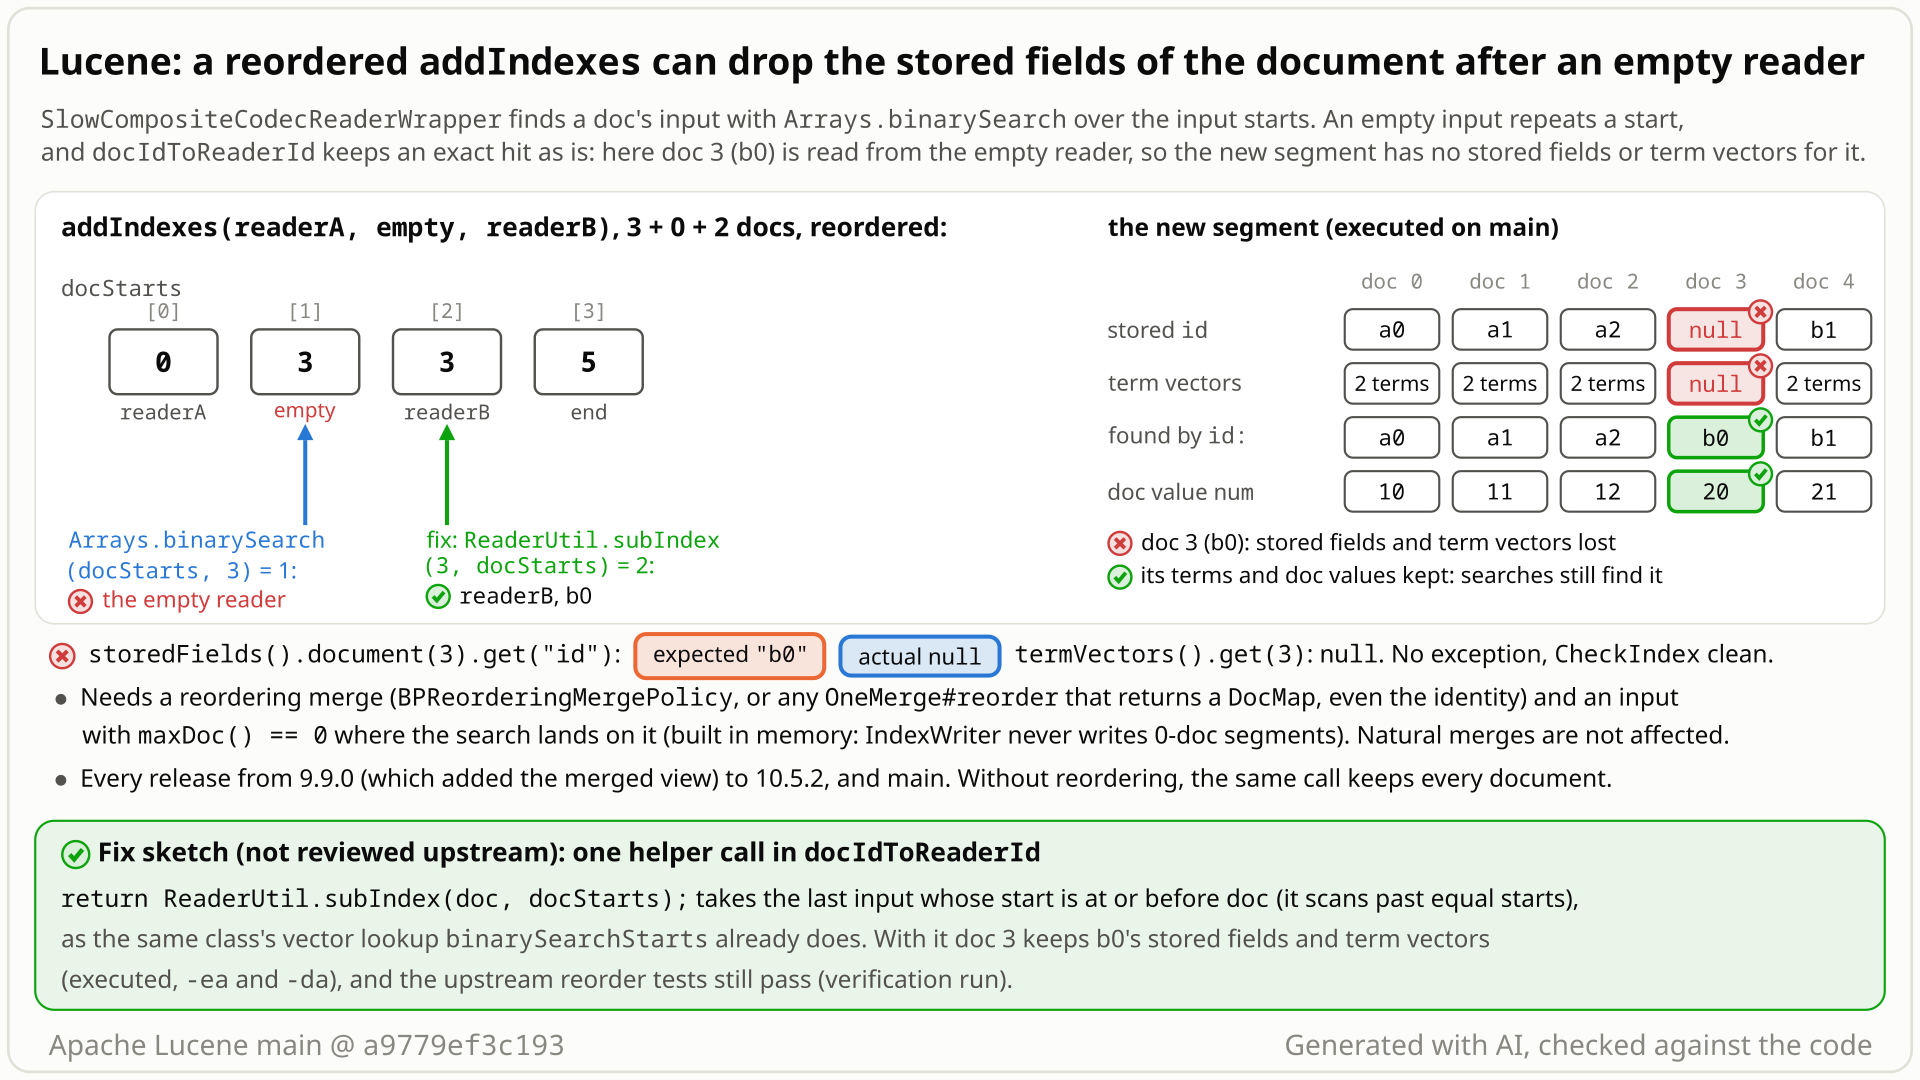
[0, 3, 3, 5], and where the binary search for doc 3 stops: on the empty input instead of the one that holds b0. Select the still to open it at full size. Generated with AI, checked against the code.- You have index A with 3 documents (
a0-a2), index B with 2 (b0,b1), and an emptyCodecReaderwithmaxDoc() == 0, such asSlowCodecReaderWrapper.wrap(new ParallelLeafReader()). Each document has a storedidand a storedbodywith term vectors. - You call
addIndexes(A, empty, B)on a writer that usesBPReorderingMergePolicywith its defaults. A customOneMerge#reorderthat returns aDocMaptriggers it too; the identity is enough. - You expect 5 documents, each with its stored fields and term vectors. Without reordering, the same call gives exactly that.
- Instead doc 3 (
b0) has no stored fields and no term vectors. To find the input that owns doc 3, Lucene binary-searches the input start offsets[0, 3, 3, 5]. The empty input and B both start at 3, the search stops on the empty input, and nothing is copied. - Nothing reports an error, with assertions on or off, and CheckIndex finds nothing.
b0still matches itsidterm and keeps its doc values, and the committed new segment keeps the loss.
Applications on 9.9.0 through 10.5.2 or main that call addIndexes(CodecReader...) through a reordering merge (opt-in: BPReorderingMergePolicy or a custom OneMerge#reorder) with a maxDoc() == 0 input before a non-empty one. Such inputs are built in memory: IndexWriter never writes empty segments, so segment merges (natural and forceMerge) cannot hit it.
Mechanism, terms and numbers656 words
When a merge reorders documents, IndexWriter.addIndexes(CodecReader...) first glues its inputs end to end into one merged view and copies every document through it. To find which input owns document N, the view binary-searches the inputs' start offsets. An input with maxDoc() == 0 starts where the next input starts, and the search can stop on the empty input. The first document of the next input is then read from the empty one: in the new index it has no stored fields and no term vectors, while its terms and doc values are intact, so searches still find it but it comes back empty. No error, CheckIndex is clean, and every release from 9.9.0 to 10.6.0 (10.6.0 by reading) and main is affected. The trigger is narrow: a reordering merge (opt-in) plus an empty input reader built in memory, which no real index produces.
addIndexes(CodecReader...)copies documents from caller-supplied readers into a new segment of the target index.- Reordering merge: a merge whose
OneMerge#reorderreturns aSorter.DocMapthat renumbers the documents, for exampleBPReorderingMergePolicy(misc module), which treatsaddIndexesas a forced merge ("addIndexes is considered a forced merge") and so reorders it whenever the merged view has a live document and the reorderer has enough memory. - Merged view (
SlowCompositeCodecReaderWrapper): for a reordering merge, IndexWriter glues the inputs into oneCodecReaderand copies every document through it (IndexWriter.java:3560-3565). It records where each input starts,docStarts, the running sum ofmaxDoc().
- Inputs of 3, 0 and 2 documents give
docStarts = [0, 3, 3, 5](SlowCompositeCodecReaderWrapper.java:70-75): the empty input repeats the start 3. docIdToReaderId(:100-107) callsArrays.binarySearch(docStarts, doc)and corrects the result only on a miss (-2 - pos). For doc 3 the search probes index 1 first, finds 3, and returns 1, the empty input. The owner is input 2.- Only the view's stored-fields reader (
prefetch,document,:156-165) and term-vectors reader (prefetch,get,:247-263) use this lookup. They ask the empty input for its local doc 0, which yields nothing for an emptyParallelLeafReader, so doc 3 is written with no stored fields and no term vectors. - Postings, doc values, norms and points are merged per input, live docs use
ReaderUtil.subIndex(viaMultiBits,:97), and vectors usebinarySearchStarts(:1093-1106), which already scans to the last equal start. Sob0keeps its terms and doc values and is still found by itsid.
Only a document whose id equals a repeated start can be misrouted, and only when the binary search's probes land on the empty input. Executed: [3, empty, 2] and [2, empty, empty, 2] lose b0; [2, empty, 2, empty, empty, 2] loses b0 and c0; the randomized differential lost doc 0 for [empty, 6, 4, 3]. A plain replay of the Java lookup shows [empty, 3, 2], [3, 2, empty] and [2, empty, 2, empty, 2] are not hit. A trailing empty input and an all-deleted input (numDocs 0, maxDoc 1) are not hit (executed). At most one document per run of repeated starts can be lost: only the document whose id equals that start is looked up there (by reading the lookup; an executed probe with two such runs lost exactly b0 and c0). The merge must also really be reordered: IndexWriter calls reorder only without an index sort (and, with blocks, only when a parent field is set), and BP reorders only when the view has a live document and enough memory.
addIndexes([a0, a1, a2], empty, [b0, b1]) with BPReorderingMergePolicy or an identity reorder: 5 documents whose stored ids, in document order, are a0, a1, a2, null, b1 (doc 3 lost); the repro fails with AssertionError: doc 3 lost its stored fields. The same call without reordering keeps all 5.
Exposure and likelihood334 words
- Who is exposed. Applications that reorder
addIndexes(CodecReader...)merges (BPReorderingMergePolicyfrom the misc module, or a custom@lucene.experimentalOneMerge#reorder) and pass an input reader withmaxDoc() == 0at a position the binary search lands on. The merge must really be reordered (no index sort; for BP a live document in the view and enough memory). Default merge policies do not reorder. - How such an input arises. It must be built in memory: IndexWriter never writes a 0-document segment (
SegmentMerger.java:101-103,PendingDeletes.java:88), so readers opened on real indexes cannot provide one. Examples: an emptyParallelLeafReader(upstreamTestParallelReaderEmptyIndexpasses exactly this toaddIndexes), or a customCodecReaderthat reports no documents. Segment merges cannot produce such an input unless a customOneMerge#wrapForMergereturns a 0-document reader (not tested). No downstream caller of this shape was found in limited code searches (not exhaustive). Likelihood: rare. - Silent and lasting. No exception with assertions on or off, and CheckIndex reports nothing (the test framework runs it on close; the diagram probe runs it explicitly). The committed target keeps the empty document, and by reasoning later merges copy it as it is. The document is still found by queries and keeps its doc values, but fetching, highlighting or re-indexing from stored fields gets nothing for it.
- Bounded. At most one document per run of repeated starts (by reading the lookup). In the executed probe no other document's data is substituted, deleted documents stay deleted, and the tested term queries and ACL filter return the same hits as without reordering. By reasoning:
addIndexesonly reads its inputs, so a fresh target can be rebuilt from them while they exist (with the fix, or without the empty input); repairing an existing target means replacing the affected documents, since a secondaddIndexesinto it adds another copy. - Caveat. The silent form was shown with an empty
ParallelLeafReader. Another empty reader whose stored-fields or term-vectors reader rejects local doc 0 could make the merge throw instead (not tested).
The test shows that addIndexes(1 doc, empty CodecReader, 1 doc) through BPReorderingMergePolicy reads the document after the empty reader from the empty reader (SlowCompositeCodecReaderWrapper.docIdToReaderId), so it is written without stored fields.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.misc.index;

import java.io.IOException;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.StoredField;
import org.apache.lucene.index.CodecReader;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.index.LogDocMergePolicy;
import org.apache.lucene.index.ParallelLeafReader;
import org.apache.lucene.index.SlowCodecReaderWrapper;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestReorderedAddIndexesEmptyReader extends LuceneTestCase {

  public void testDocAfterEmptyReaderKeepsStoredFields() throws IOException {
    try (Directory a = oneDocIndex("a");
        Directory b = oneDocIndex("b");
        Directory target = new ByteBuffersDirectory();
        DirectoryReader ra = DirectoryReader.open(a);
        DirectoryReader rb = DirectoryReader.open(b)) {
      IndexWriterConfig iwc =
          new IndexWriterConfig()
              .setMergePolicy(
                  new BPReorderingMergePolicy(new LogDocMergePolicy(), new BPIndexReorderer()));
      try (IndexWriter w = new IndexWriter(target, iwc)) {
        w.addIndexes(
            (CodecReader) ra.leaves().get(0).reader(),
            SlowCodecReaderWrapper.wrap(new ParallelLeafReader()),
            (CodecReader) rb.leaves().get(0).reader());
      }
      try (DirectoryReader r = DirectoryReader.open(target)) {
        int withStoredId = 0;
        for (int doc = 0; doc < r.maxDoc(); doc++) {
          if (r.storedFields().document(doc).get("id") != null) {
            withStoredId++;
          }
        }
        // expected: both keep their stored id; actual: the doc after the empty reader has none
        assertEquals("documents with a stored id, of maxDoc " + r.maxDoc(), 2, withStoredId);
      }
    }
  }

  private static Directory oneDocIndex(String id) throws IOException {
    Directory dir = new ByteBuffersDirectory();
    try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
      Document doc = new Document();
      doc.add(new StoredField("id", id));
      w.addDocument(doc);
    }
    return dir;
  }
}
# in a copy of this finding's repro folder (repro/LFV-318/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/misc/build/libs/lucene-misc-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.misc.index.TestReorderedAddIndexesEmptyReader
- Expected vs actual
- Expected: both documents of the new segment keep their stored id (2 of 2). Actual (-ea and -da): 1 of 2.
More files, environment, full output41 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: documents with a stored id, of maxDoc 2 expected:<2> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.misc.index.TestReorderedAddIndexesEmptyReader.testDocAfterEmptyReaderKeepsStoredFields(TestReorderedAddIndexesEmptyReader.java:59)- The class is documented as "A merged CodecReader view of multiple CodecReader"; the same
addIndexescall without reordering keeps all 5 documents. - Empty inputs are accepted: nothing rejects a
maxDoc() == 0reader, and upstreamTestParallelReaderEmptyIndexpasses this exact reader toaddIndexes. - The class's vector lookup already got this fix (
f21ec8414c1, 2024); the stored-fields lookup did not.
The full argument312 words
- Class javadoc: "A merged
CodecReaderview of multipleCodecReader" (SlowCompositeCodecReaderWrapper.java:44-45). A view whose document 3 is not input 3's first document is not a merged view of the inputs. OneMerge#reorder: "Extend this method if you wish to renumber doc IDs. This method will be called when index sorting is disabled on a merged view of theOneMerge" (MergePolicy.java:312-314). Renumbering must not lose content.addIndexes(CodecReader...): "NOTE: empty segments are dropped by this method and not added to this index" (IndexWriter.java:3262). No code rejects amaxDoc() == 0input (validateMergeReaderchecks versions and the index sort only,:3228-3252), andTestParallelReaderEmptyIndexaddsSlowCodecReaderWrapper.wrap(new ParallelLeafReader())(:50). LUCENE-1918 (2009) already fixed exceptions when an emptyParallelReaderwas passed toaddIndexes.- Consistency. The vector lookup in the same class scans to the last repeated start: "Arrays.binarySearch can return any of a sequence of repeated value but we always want the last one" (
:1099-1103, added byf21ec8414c1).ReaderUtil.subIndex, used for the same job byMultiBits, scans to the last match too. It was added in 2009 (7fff5a7ea7c, LUCENE-1771) with the loop that933bac2435e(2002, "Patched to fix a bug when empty indexes or segments exist") had added to the multi-reader lookups it descends from. - History. The introducing PR #12622 never discusses empty readers. No javadoc, test, CHANGES or MIGRATE entry restricts reordered inputs to
maxDoc() >= 1. - Why tests missed it.
TestParallelReaderEmptyIndexpasses the empty reader alone, so no view is built (SlowCompositeCodecReaderWrapper.wrapreturns a single reader as is,SlowCompositeCodecReaderWrapper.java:49-57);TestAddIndexes.testAddEmptypasses no readers;testFakeAllDeletedusesmaxDoc1;MockRandomMergePolicyoverridesreorderbut notfindMerges(CodecReader...), so the randomized coverage that relies on it never reorders anaddIndexesmerge. The dedicated nightly testTestBPReorderingMergePolicy.testReorderOnAddIndexesdoes reorder one, but has nomaxDoc() == 0input.
The devil's-advocate check147 words
The strongest case for "works as designed" (made by an intended-behaviour checker, and separately by a reviewer from another model family, who rated it weak): the view is package-private merge infrastructure ("primarily targeted at merging, not searching"), OneMerge#reorder is @lucene.experimental, and IndexWriter never writes 0-document segments (LUCENE-5173), so only synthetic empty inputs reach the lookup; on real inputs the starts are strictly increasing and the plain binary search is correct.
Why it fails: that limits how often it happens, not whether it is wrong. The loss happens during the merge, the view's own purpose, and experimental marks API instability, not permission to drop data. Empty inputs are accepted and tested upstream, the class's other doc-to-input lookups (live docs through ReaderUtil.subIndex, vectors through binarySearchStarts) already take the last equal start, and the fix is the one the vector path received. Verdict: not intended, a defect.
Recommended Use ReaderUtil.subIndex in docIdToReaderId (validated)
Make docIdToReaderId return ReaderUtil.subIndex(doc, docStarts), which picks the last input that starts at or before the document, as MultiBits and the vector path already do (+3/-5 lines). With it all 14 repro tests pass, and 11 neighbouring upstream suites stay green with assertions on and off.
   private int docIdToReaderId(int doc) {
     Objects.checkIndex(doc, docStarts[docStarts.length - 1]);
-    int readerId = Arrays.binarySearch(docStarts, doc);
-    if (readerId < 0) {
-      readerId = -2 - readerId;
-    }
-    return readerId;
+    // docStarts has repeated values when a reader is empty: pick the last reader that starts at or
+    // before doc, which is the only one that can contain it
+    return ReaderUtil.subIndex(doc, docStarts);
   }
All options and trade-offs5 options · 486 words
One fix was validated in a scratch worktree at a9779ef3c193; the alternatives are by reasoning.
Replace the raw Arrays.binarySearch hit with the existing helper that scans to the last equal start. ReaderUtil.subIndex exists back to 9.9.0, so the patch backports unchanged.
   private int docIdToReaderId(int doc) {
     Objects.checkIndex(doc, docStarts[docStarts.length - 1]);
-    int readerId = Arrays.binarySearch(docStarts, doc);
-    if (readerId < 0) {
-      readerId = -2 - readerId;
-    }
-    return readerId;
+    // docStarts has repeated values when a reader is empty: pick the last reader that starts at or
+    // before doc, which is the only one that can contain it
+    return ReaderUtil.subIndex(doc, docStarts);
   }
Trade-offs
- Same O(log n) search, plus a forward scan over runs of equal starts, which only exist when inputs are empty. No benchmark was run.
- A Z3 model of the lookup shows the scan-to-last rule correct for 2 to 6 inputs (query Q3 unsat).
What the checks validated
- Gradle, seed DEADBEEF,
-eaand-da: 15 classes, 106 tests, 0 failures (3 skipped, as on stock): the 14 repro tests (the finder's, an independent reproducer's core and misc tests, the scope test) and the upstream suites miscTestBPReorderingMergePolicy,TestBPIndexReorderer,TestBpVectorReordererand coreTestGetVectorCountCodecWrappers,TestAddIndexes,TestParallelReaderEmptyIndex,TestSortingCodecReader,TestIndexWriterMerging,TestIndexWriterForceMerge,TestMultiDocValues,TestStressIndexing2. On stock main the same set, run with assertions on, has 8 failures, all in repro classes. - A separate nightly-enabled run: the repro and the three BP suites, 22 tests including the
@NightlytestReorderOnAddIndexes, 0 failures, 0 skipped (the log lists the tests, not the command line). :lucene:core:check :lucene:misc:check -x testwith the fix and the repro test: build successful.- On the 9.9.0 and 10.5.2 release jars, the release's own class with only this method changed passes the repro; recompiled unchanged it still fails.
Keep Arrays.binarySearch and, on an exact hit, advance while the next start equals doc, as binarySearchStarts does.
Trade-offs
Same behaviour as the recommended fix with a few more lines, duplicating a helper that already exists. Not run separately.
Build docStarts and the per-input arrays only from inputs with maxDoc() > 0, keeping all inputs for the merged FieldInfos.
Trade-offs
Removes repeated starts at the source, for this lookup and any later one, but touches the constructor and every per-input array. A design choice for the maintainers; the recommended fix is the smallest change for this bug. Not run.
Throw for an empty input reader.
Trade-offs
Changes accepted behaviour that upstream TestParallelReaderEmptyIndex relies on. Not run.
Drop inputs with maxDoc() == 0 before calling addIndexes.
Trade-offs
By reasoning, not executed. They contribute no documents, though a custom empty reader could carry field definitions.
Apache Solr ships an opt-in BPReorderingMergePolicyFactory, but its index-merge path passes real segments (maxDoc() >= 1), so no downstream caller that reaches this was found (limited code reading, not exhaustive).
An SMT model (Z3) of the merged view's document-to-reader lookup, with exact Java int and Arrays.binarySearch semantics, showed the lookup correct when every input has documents and produced a counterexample (inputs [a, 0, b], document a) once empty inputs were allowed. A randomized differential test and a public-API JUnit test then reproduced it end to end.
The method in full220 words
Method: SMT solving (Z3, bit-vector logic) of one correctness obligation (the study's "formal" tier). The hunt unit on CodecReader wrappers modelled docIdToReaderId with exact Java int arithmetic and the JDK's Arrays.binarySearch loop, and asked for 2 to 6 inputs: can the returned input fail to contain the document?
- Q1, every input has
maxDoc >= 1: unsat for n = 2 to 6 (the lookup is correct). - Q2, inputs may be empty: sat from n = 3; in every witness the document sits at a start shared by an empty input and the next input, and the chosen input has
maxDoc0 (for n = 3: inputs[a, 0, b], documenta). An exhaustive plain replay overmaxDoc <= 4, n <= 5 found 1,320 of 37,100 lookups wrong, every one on an empty input. - Q3, the scan-to-last fix: unsat (the fix is complete for the modelled sizes).
The obligation was posed separately with and without empty inputs, so empty inputs were in the modeller's mind; the failing document and placement came from the solver. By file times the solver log predates the unit's randomized differential harness, which then flagged the same stored-field mismatches independently (through the view and through addIndexes with an identity reorder, only with empty inputs), and the public-API JUnit test.
No prior report found (searched 2026-10-26: GitHub issues, PRs and commits, the JIRA archive, the dev@, java-user@, issues@ and commits@ lists, downstream repositories and the web; 27 items read). Closest: f21ec8414c1, which fixed the same pattern only in the vector lookup.
Searches4 searches
No issue, PR, commit, JIRA ticket or list thread reports this bug. The closest items are precedents or context, not reports.
| Where | When | How | Found |
|---|---|---|---|
| Automated multi-source search (three runs) | 2026-10-26 | the finder's run: GitHub issues, PRs and commits of apache/lucene, the dev@, java-user@, issues@ and commits@ lists and the JIRA archive, with no downstream or web queries; two follow-up runs: the same plus 2 downstream-repository and 6 web queries each; class-, method-, symptom- and mechanism-oriented queries | 1163 (finder), 75 and 1486 hits, none high; every medium hit checked: none is this bug |
| GitHub issues and PRs (apache/lucene) | 2026-10-26 | 21 phrasings, e.g. SlowCompositeCodecReaderWrapper, docIdToReaderId, BPReorderingMergePolicy, addIndexes empty reader, addIndexes stored fields missing, empty CodecReader, binary search repeated values; the file lists of all open PRs | no report; docIdToReaderId returns nothing. Open PRs #16879, #16847, #13342 touch the file but not the lookup |
| Downstream repositories, ASF JIRA, lists.apache.org, web | 2026-10-26 | the class and policy names and symptom phrasings in Elasticsearch, Solr and other downstream repositories; JIRA text search; dev@, java-user@, issues@, builds@, commits@; 18 web queries | no report; downstream items only show the merge policy is exposed (a Solr factory) |
| git history | 2026-10-26 | pickaxe for docIdToReaderId and 'scan to last match'; commit messages since 2023-10 about empty readers or repeated values | f21ec8414c1 (2024, the same fix in the vector lookup only) and 933bac2435e (2002, the same defect class in the old multi-reader lookup): precedents |
Introduced in 9.9.0 by #12622 (f7cab164501, merged 2023-11-23), which created the merged view and its lookup. All 22 releases from 9.9.0 to 10.5.2 and main fail the repro; 9.8.0 and older have no merged view.
Versions tested6 rows
Introduced by #12622 "Add a merge policy wrapper that performs recursive graph bisection on merge." (@jpountz, approved by @s1monw, merged 2023-11-23): f7cab164501 on main and the identical backport 6b1538b3313 on branch_9x. It created SlowCompositeCodecReaderWrapper with docStarts and docIdToReaderId, OneMerge#reorder, the merged-view calls in IndexWriter, and BPReorderingMergePolicy; git blame on main still assigns the lookup to it. On 9.9.0 and 10.5.2, the release's own class recompiled unchanged still fails and with only the lookup fixed passes.
Later changes that did not move the onset: #13128 (block guard), #13289 (Executor parameter of reorder), #13424 and #13758 (prefetch callers of the same lookup), and f21ec8414c1 (2024, vector path only). Not fixed on main, branch_10x or branch_10_6 as of 2026-10-26.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 and ea57360912ed | affected | 2 of 3 fail ("doc 3 lost its stored fields"), assertions on and off; the control passes |
| 10.0.0-10.5.2 (12 releases) | affected | 2 of 3 fail on the release jars; also with assertions off on 10.5.2 |
| 9.9.0-9.12.3 (10 releases) | affected | 2 of 3 fail (9.9.0-9.11.1 with the 2-argument reorder); 9.9.0 is the first affected release |
| 9.8.0, 9.7.0 | not affected | no merged view, no OneMerge#reorder; a no-reorder probe with the same inputs passes |
| 9.9.0 and 10.5.2, release class recompiled | pinning | unchanged: fails; only docIdToReaderId fixed: passes |
fix on main a9779ef3c193 | not affected | 14 repro tests and 11 upstream suites pass, assertions on and off |
An independent reproducer wrote its own tests (5 of 8 fail, its 3 controls pass), a reviewer from another model family (OpenAI GPT-5.6, reading only) agreed on the root cause, an intended-behaviour devil's advocate found no documented restriction, and an adjudication re-ran everything: confirmed, high confidence.
Checks and verdicts355 words
Each check ran separately from the finder. The cross-model reviews read the code only (they could not run Java); every other check executed the tests.
| Check | Verdict | What it found |
|---|---|---|
| Independent reproducer | real | Own tests from the claim only (core and misc): 5 of 8 fail on main (assertions on and off), 10.5.2 and 9.12.3: identity and reverse reorder, two empties, BPReorderingMergePolicy, and the merged view read directly; its 3 controls pass; its own fix passes 8 of 8; CheckIndex on close silent. |
| Cross-model review, refute lens | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only. It voted not real on procedure only because it could not run code; its substantive fields agree: root cause agreed, inputs in contract, intended-behaviour argument weak. |
| Cross-model review, intended lens | real (medium) | The same reviewer: the works-as-designed argument is weak. |
| Cross-model adversary, root-cause lens | real (medium) | The first wrong state is the exact-hit branch of docIdToReaderId; the repeated starts are valid. Not a duplicate. Separate re-runs fail on main and 10.5.2 and pass with the fix. |
| Intended-behaviour devil's advocate | real (high that it is not intended) | Re-ran the repro (assertions on and off: fails). Scope test: an all-deleted middle input and a trailing empty input pass, an empty middle input fails (sorted ids [a0, a1, a2, b1, null]: b0 missing). |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's tests (5 of 8 fail, assertions on and off), the finder's test and the fix check (passes). Data corruption, not security-sensitive, not a duplicate. |
| Security probe | not security-sensitive | Each probe first asserts that the bug fired. Then: deleted documents stay deleted and no data is substituted; the tested term queries and ACL filter return the same hits as without reordering; a shape with two runs of repeated starts loses exactly one document per run (b0, c0). |
| Refresh on a9779ef3c193 and this doc's fix validation | still reproduces; fix validated | Same failures on a9779ef3c193; the fix passes all repro tests and the neighbouring upstream suites (Suggested fix). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 457 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,448 words
- Registry title
- A reordered addIndexes(CodecReader...) silently drops the stored fields and term vectors of the first document after an empty (maxDoc 0) input reader: SlowCompositeCodecReaderWrapper.docIdToReaderId keeps an Arrays.binarySearch hit on a repeated doc start and reads that document from the empty reader
- Area
- index / addIndexes reorder path: SlowCompositeCodecReaderWrapper doc-ID-to-reader lookup (stored fields, term vectors), reached through misc BPReorderingMergePolicy or any OneMerge#reorder
- Priority
- Low, rank 470: A reordered addIndexes permanently drops stored fields after an empty CodecReader, which is durable damage, but like LFV-202 it needs an application-built maxDoc-0 input, so it leads the hand-built-input rows.
- Impact class
- data corruption
- Impact note
- Applications on 9.9.0 through 10.6.0 (10.6.0 by reading) or main that call IndexWriter.addIndexes(CodecReader...) through a merge that reorders documents (misc BPReorderingMergePolicy, which reorders every addIndexes merge, or any custom OneMerge#reorder that returns a DocMap, even the identity) and pass an input CodecReader with maxDoc() == 0 before a non-empty input, at a placement where the binary search lands on the empty input (for example [3 docs, empty, 2 docs]), silently get a new segment in which the first document of that non-empty input has no stored fields and no term vectors while its postings and doc values are intact, so searches still find it but it comes back as an empty document; nothing throws with -ea or -da, CheckIndex reports nothing, the loss is permanent in the target (the inputs are untouched), and no scale is needed, but IndexWriter never writes 0-document segments, so natural merges, forceMerge and readers opened on real indexes cannot trigger it and the empty input must be built in memory (for example SlowCodecReaderWrapper.wrap(new ParallelLeafReader()), as upstream TestParallelReaderEmptyIndex does).
- Summary
- You call IndexWriter.addIndexes(CodecReader...) with a 3-document reader, an empty reader (maxDoc() == 0) and a 2-document reader on a writer whose merge policy reorders the merge, such as BPReorderingMergePolicy or any OneMerge#reorder that returns a DocMap (the identity is enough), and you expect all 5 documents to keep their stored fields and term vectors, as they do with the same call without reordering. Instead the merged view that IndexWriter builds for the reorder (SlowCompositeCodecReaderWrapper) has doc starts [0, 3, 3, 5], Arrays.binarySearch finds start 3 at the empty reader's index, and docIdToReaderId keeps that exact hit, so merged doc 3 (the first document of the third reader) is read as doc 0 of the empty reader. The new segment is written without any error under -ea and -da: that document is still found by its id term and keeps its doc values, but its stored fields and term vectors are gone.
- Introduced
- f7cab1645017d863331b42900581b67d3591e2da on main and its branch_9x backport 6b1538b33136a4737ad0d22b3633e62f3d7f362b (identical patch), PR #12622 'Add a merge policy wrapper that performs recursive graph bisection on merge.' (jpountz): it created SlowCompositeCodecReaderWrapper with docStarts (prefix sums of maxDoc) and docIdToReaderId (Arrays.binarySearch, correction only on a miss), OneMerge#reorder and the merged-view call in IndexWriter.addIndexesReaderMerge [read: git blame on main still assigns docIdToReaderId, the docStarts loop and the stored-fields and term-vectors callers to f7cab164501; #12622's review led to the shared docIdToReaderId helper and never mentions empty readers. exec: 9.8.0 has no merged view (the reordered repro does not compile, the no-reorder probe passes), 9.9.0 fails, and on 9.9.0 and 10.5.2 recompiling the release's own SlowCompositeCodecReaderWrapper unchanged keeps the failures while changing only docIdToReaderId to ReaderUtil.subIndex makes them pass]. Commit-level builds of f7cab164501 and its parent were not run (the parent has no reorder hook to express the repro) (2023-11-23 (f7cab164501 on main and the branch_9x backport 6b1538b3313))
- First affected version
- 9.9.0 [exec] (tagged 2023-12-04, through the branch_9x backport 6b1538b3313; fails with -ea and -da); on the 10.x line 10.0.0 [exec]; 9.8.0 is the last unaffected release (no merged view, no OneMerge#reorder, no BPReorderingMergePolicy) [exec]
- Affected versions
- Every release from 9.9.0 through 10.6.0 (10.6.0 by reading; the 22 releases through 10.5.2: 9.9.0-9.9.2, 9.10.0, 9.11.0, 9.11.1, 9.12.0-9.12.3, 10.0.0, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0, 10.5.0-10.5.2) and main ea57360912ed [exec: the BPReorderingMergePolicy and identity-reorder tests fail with 'doc 3 lost its stored fields' at every one and the no-reorder control passes; -da also on 9.9.0, 9.12.3, 10.5.2 and main; 9.9.0-9.11.1 use the 2-argument OneMerge#reorder variant of the same test; the independent reproduction's tests fail on main, 10.5.2 and 9.12.3]. Not affected: 9.7.0 and 9.8.0 [exec: the reordered test does not compile, the no-reorder probe with the same input shapes passes]. Not fixed: docIdToReaderId is textually identical at all 22 tags and on main [read], and unchanged on main, branch_10x and branch_10_6 on 2026-10-26 [read, GitHub contents API]; the 10.6 line (10.6.0, released 2026-10-29) was not executed. All runs on aarch64 Linux, JDK 25 (plain Java logic, no vector code).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- formal: Z3; also reached by fuzzing/PBT
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new): three scripted prior-report searches over apache/lucene issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and the web (the finder's run 1163 hits, run A 75, run BCD 1486; none high), 21 GitHub issue and PR list searches on apache/lucene, searches in elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr, ASF JIRA REST, lists.apache.org (dev@, java-user@, issues@, builds@, commits@), manual web searches, git pickaxe and log grep over the full history, the open-PR file lists; 27 items read, none the same bug. Related, not reports: commit f21ec8414c1 (2024-09-28, with #13779, no issue or PR of its own) fixed the same Arrays.binarySearch-over-repeated-starts pattern only in this class's vector-ordinal lookup (binarySearchStarts) and left docIdToReaderId unchanged; 933bac2435e (2002) fixed the same defect class in the old multi-reader lookup that became ReaderUtil.subIndex; #12622 (the introducing PR; its review never discusses empty readers); the open PRs #16879, #16847 and #13342 touch the file but not the lookup. Not fixed on main, branch_10x or branch_10_6 (2026-10-26).
- Lucene commit tested
- main
a9779ef3c193(the repro runner, assertions on and off, with and without the fix; gradle in a scratch worktree: the fix over the 14 repro tests and 11 neighbouring upstream suites with assertions on and off, stock main over the same set with assertions on and the finder's test with assertions off, the misc BP suites with nightly tests, and the core and misc static checks); mainea57360912ed(the hunt and its independent checks); the release jars 9.7.0, 9.8.0 and all 22 releases from 9.9.0 to 10.5.2; the 9.9.0 and 10.5.2 wrapper class recompiled unchanged and with only the lookup fixed. JDK 25.0.3, Linux aarch64.
- Finding record
lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:44-46 (at ea57360912ed) (class javadoc 'A merged CodecReader view of multiple CodecReader ... primarily targeted at merging'), :49-57 (wrap returns a single reader as is), :66-75 (docStarts += reader.maxDoc()), :97 (live docs via MultiBits), :100-107 (docIdToReaderId: Arrays.binarySearch, -2-pos only on a miss), :156-165 (stored fields prefetch/document), :247-263 (term vectors prefetch/get), :1093-1106 (vector binarySearchStarts scans to the last repeated start)lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3262 (at ea57360912ed) ('NOTE: empty segments are dropped by this method'), :3560-3565 (addIndexesReaderMerge: merged view, merge.reorder, SortingCodecReader.wrap(mergedReader, docMap, null)), :5557-5558 (the same view on the regular merge path)lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:311-327 (at ea57360912ed) (OneMerge#reorder javadoc: renumber doc IDs on 'a merged view of the OneMerge'; @lucene.experimental; default returns null)lucene/core/src/java/org/apache/lucene/index/ReaderUtil.java:48-68 (at ea57360912ed) (subIndex scans to the last equal start; the fix reuses it)lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:200-201 (at ea57360912ed) (findMerges(CodecReader...): 'addIndexes is considered a forced merge', so every addIndexes merge is reordered)lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:50 (at ea57360912ed) (upstream adds SlowCodecReaderWrapper.wrap(new ParallelLeafReader()) to addIndexes, alone)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:66-75, 97, 100-107, 156-165, 247-263, 1093-1106a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3560-3565a Lucene main checkout (a9779ef3c193) lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:200-202a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/IndexWriter.java:3548-3560; lucene/misc/src/java/org/apache/lucene/misc/index/BPReorderingMergePolicy.java:102-105, 133-144 (when a reorder happens)
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SegmentMerger.java:101-103; PendingDeletes.java:88a Lucene main checkout (a9779ef3c193) lucene/core/src/test/org/apache/lucene/index/TestParallelReaderEmptyIndex.java:50
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:44-45, 49-57, 1093-1106 (loop :1099-1103)a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/MergePolicy.java:312-327; IndexWriter.java:3228-3252, 3262, 3275-3296; ReaderUtil.java:48-68; MultiBits.java:91a Lucene main checkout (a9779ef3c193) lucene/test-framework/src/java/org/apache/lucene/tests/index/MockRandomMergePolicy.java:240; lucene/misc/src/test/org/apache/lucene/misc/index/TestBPReorderingMergePolicy.java:146-195 (@Nightly testReorderOnAddIndexes)
- Suggested fix
a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/index/SlowCompositeCodecReaderWrapper.java:100-107, 1093-1106; ReaderUtil.java:48-68
- TestReorderedAddIndexesEmptyReader.java (JUnit test):
repro/LFV-318/src/org/apache/lucene/misc/index/TestReorderedAddIndexesEmptyReader.java(73 lines)
A step-by-step picture of the repro's example (inputs of 3, 0 and 2 documents), made in parallel with this doc.
assets/LFV-318/bug.png(457 KB)