The parser analyzes your text once per field, then ORs clause 0 of every field, clause 1 of every field, and so on, and under AND requires each group. That only works when clause i is the same word in every field.
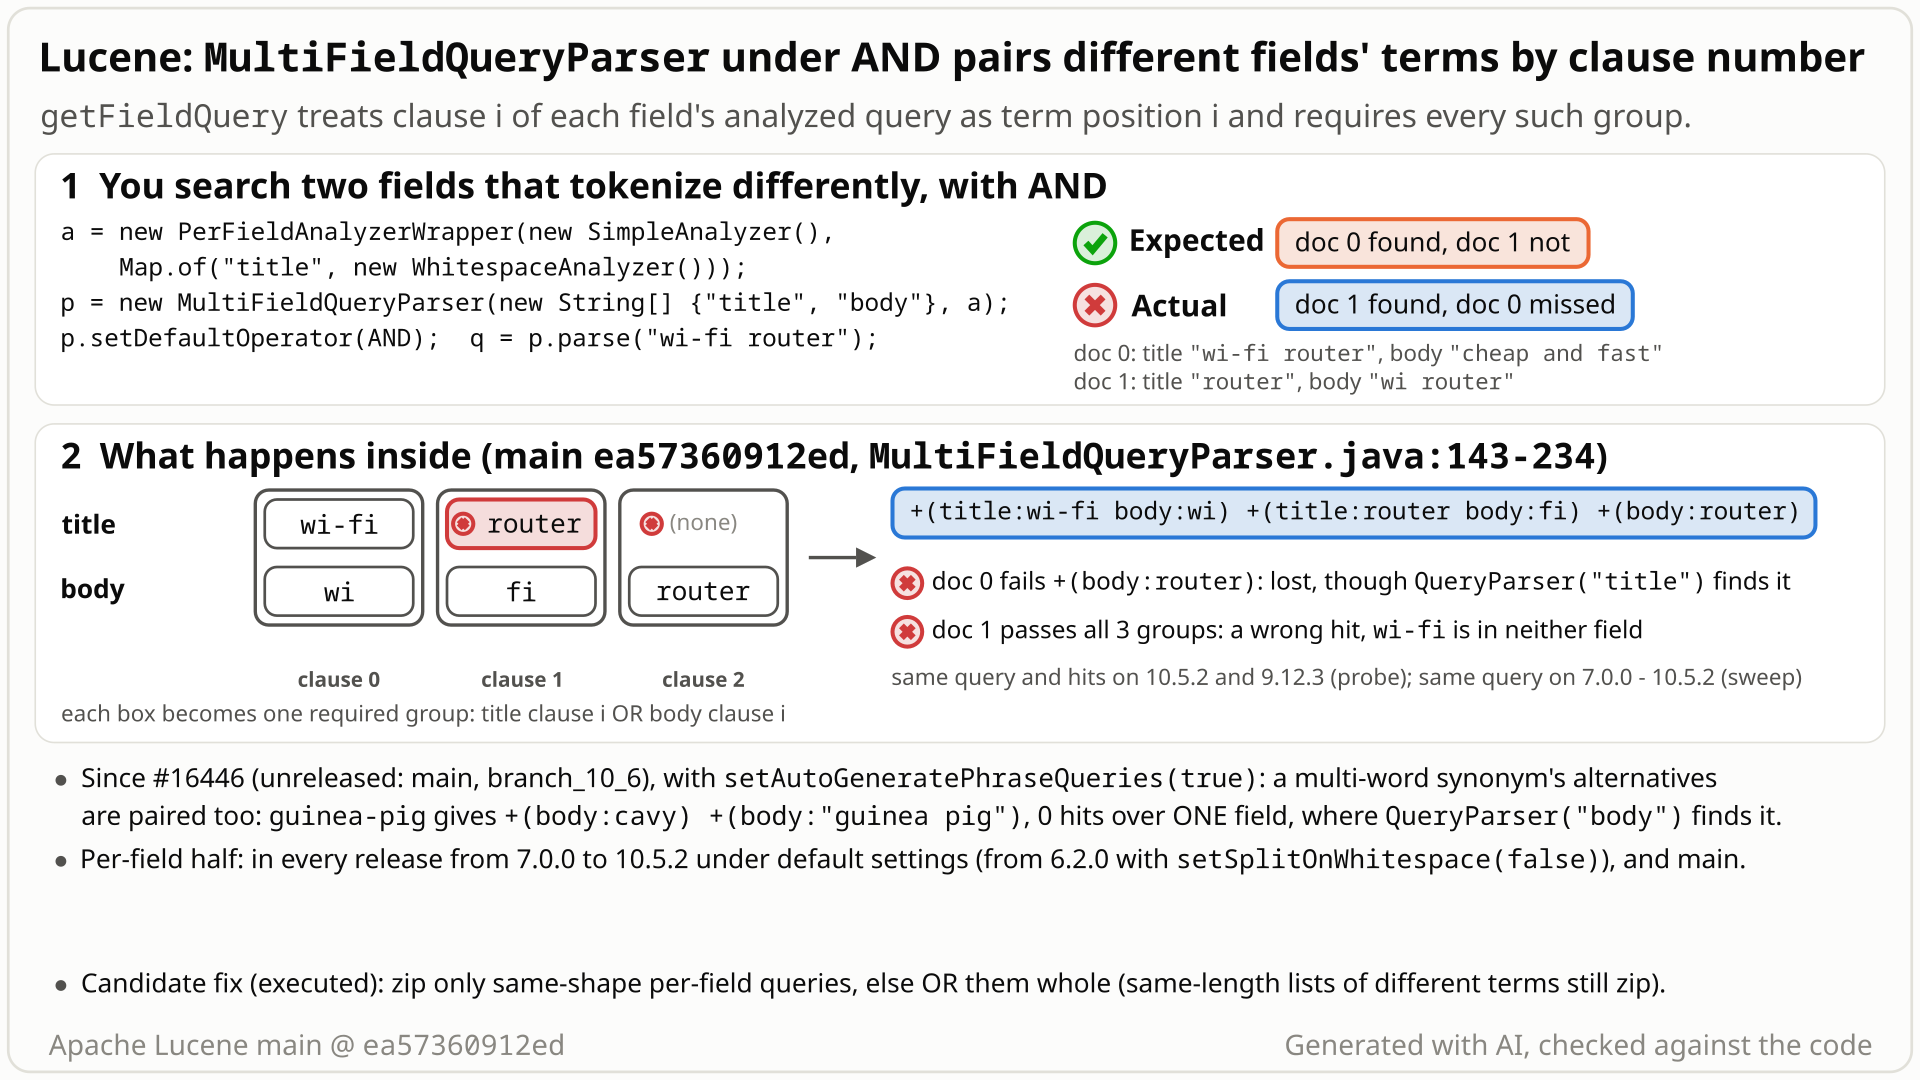
- Search
title(split on whitespace) andbody(split on every non-letter) withMultiFieldQueryParserand AND. Doc 0: title "wi-fi router", body "cheap and fast". Doc 1: title "router", body "wi router". - You expect doc 0 for
wi-fi router:QueryParserontitlefinds it, and the javadoc says each word may appear in any field. Doc 1 has no "fi" in any field, so it should not match. - Instead the parser lines up the fields' words by number: title [wi-fi, router] and body [wi, fi, router] give
+(title:wi-fi body:wi) +(title:router body:fi) +(body:router). Doc 0 fails the third group, doc 1 passes all three: hits [1] instead of [0]. - Since #16446 (10.6.0, main and
branch_10_6) the same pairing breaks even one field: withautoGeneratePhraseQueriesand the synonym "guinea pig" = cavy,guinea-pigbecomes+(body:"guinea pig") +(body:cavy): 0 hits whereQueryParserfinds 1. - No error. The two-word case is in every release from 7.0.0 to 10.5.2 under default settings; the one-word
wi-fiand synonym cases are new in 10.6.0 (main andbranch_10_6).
Applications that search several fields with the classic MultiFieldQueryParser and AND, when the fields split words differently (a whitespace title or tag field next to a standard body, different stop words): default settings since 7.0.0. The synonym case needs autoGeneratePhraseQueries and a graph analyzer and is new in 10.6.0. One document is enough; no error.
Mechanism, terms and numbers518 words
MultiFieldQueryParser analyzes the query text once per field, takes clause i of each field's analyzed BooleanQuery, ORs those across the fields into group i, and under AND_OPERATOR requires every group. That is only right when clause i covers the same query word in every field. With fields that split text differently (title on whitespace, body on non-letters), wi-fi router parses to +(title:wi-fi body:wi) +(title:router body:fi) +(body:router): it misses the document titled "wi-fi router", which QueryParser("title") finds, and matches a document with title "router" and body "wi router". That is in every release from 7.0.0 under default settings (6.2.0 with setSplitOnWhitespace(false)). Since #16446 (10.6.0, main and branch_10_6) the alternatives of a token graph are paired the same way, so with autoGeneratePhraseQueries a multi-word synonym's alternatives are all required and even a single field disagrees with QueryParser; #16446 also widened the per-field case to single words. No error is raised.
- Per-field analysis: an analyzer that treats fields differently, e.g.
PerFieldAnalyzerWrapperor anyDelegatingAnalyzerWrapper. Heretitlesplits on whitespace (wi-fistays one token) andbodysplits on every non-letter (wi,fi). - Token graph: analysis that offers alternatives for the same words, e.g. a multi-word synonym ("guinea pig" = cavy) or
WordDelimiterGraphFilterwith catenation ("wi fi" or wifi). WithautoGeneratePhraseQueries,QueryBuilder.analyzeGraphPhraseturns it into one phrase per path, ORed.
- With the default
splitOnWhitespace=false, the grammar joinswi-fi routerinto onegetFieldQuery(null, "wi-fi router", false)call (QueryParser.jj:376-409). MultiFieldQueryParser.getFieldQuery(String,String,boolean)(MultiFieldQueryParser.java:142-209) builds each field's query: title+title:wi-fi +title:router(2 clauses), body+body:wi +body:fi +body:router(3 clauses).- It takes clause
termNumof each field's query, dropping its occur (:160-172), and ORs them into one group per number (:185-192): (title:wi-fi body:wi), (title:router body:fi), (body:router). getMultiTermPositionQuery(:220-234, added by #16446) adds every group with MUST under AND (:227-228). The code comment calls the groups "one group per analyzed TERM POSITION" (:199-204).- For a token graph the clauses are alternatives, not positions:
analyzeGraphPhraseadds one SHOULD phrase per path (QueryBuilder.java:565-583), so("guinea pig" OR cavy)becomes+(body:"guinea pig") +(body:cavy).
Before #16446 the groups of a one-word call were combined with SHOULD: correct for graphs, an over-match for per-field wi-fi (the known #16443). Multi-word per-field text was already required group by group since LUCENE-2605 (2016).
| query, parser | parsed query | hits (expected) |
|---|---|---|
wi-fi router, MultiFieldQueryParser{title, body}, main and 10.5.2 | +(title:wi-fi body:wi) +(title:router body:fi) +(body:router) | [1] ([0]) |
wi-fi router, flexible StandardQueryParser, same fields | +(title:wi-fi (+body:wi +body:fi)) +(title:router body:router) | [0] |
wi-fi, MultiFieldQueryParser, main | +(title:wi-fi body:wi) +(body:fi) | [] ([0]) |
wi-fi, MultiFieldQueryParser, 10.5.2 | (title:wi-fi body:wi) (body:fi) | [0, 1]: the #16443 over-match |
guinea-pig, MultiFieldQueryParser{body}, main | +(body:"guinea pig") +(body:cavy) | [] ([0], as QueryParser("body"): body:"guinea pig" body:cavy) |
wi-fi with WordDelimiterGraphFilter, MultiFieldQueryParser{body}, main | +(body:wifi) +(body:"wi fi") | [] (2 docs) |
For these inputs the flexible parser builds the by-word expansion that the classic javadoc's example suggests: each query word ORed over the fields, whatever each field's analysis makes of it.
Exposure and likelihood228 words
- Who is hit. Callers of the classic
MultiFieldQueryParserwithAND_OPERATOR. Per-field half: the searched fields use analyzers that split the same text differently; the typical trigger is a word one field keeps whole and another splits, such aswi-fi. Graph half:autoGeneratePhraseQueries=true(withsplitOnWhitespace=true) and a multi-word synonym orWordDelimiterGraphFilterwith catenation; it hits even one field with one analyzer. - Default vs opt-in. AND and per-field analysis are application choices; given those, the two-word case needs no other setting, because
splitOnWhitespace=falseis the default since 7.0.0. The graph half needs the opt-inautoGeneratePhraseQueries. - Both directions. The per-field half loses matches and can add wrong ones (doc 1). The graph half only loses matches: requiring every alternative can never match more than one of them.
- Scale. None: one or two documents and a one- or two-word query. Silent: fewer or different hits.
- Reach. Solr, Elasticsearch and OpenSearch do not reference the class (code search of their default branches, not exhaustive); applications that embed Lucene directly can. The recorded search found no user report in the roughly nine years since the default changed (7.0.0, 2017); it was not exhaustive. The likelihood is rated plausible.
- Release timing. The graph half and single-word per-field input first shipped in 10.6.0 (released 2026-10-29) and are on main and
branch_10_6. Thebranch_10_6backport of #16446 adds no CHANGES entry there.
The test shows that under AND with autoGeneratePhraseQueries, MultiFieldQueryParser over the single field body turns the synonym alternatives of guinea-pig ("guinea pig" OR cavy) into two required clauses.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.classic;

import org.apache.lucene.analysis.Analyzer;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.search.IndexSearcher;
import org.apache.lucene.search.Query;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.analysis.MockSynonymFilter;
import org.apache.lucene.tests.analysis.MockTokenizer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMultiFieldQueryParserSynonymGraph extends LuceneTestCase {

  public void testMultiWordSynonymUnderAnd() throws Exception {
    Analyzer analyzer =
        new Analyzer() {
          @Override
          protected TokenStreamComponents createComponents(String fieldName) {
            Tokenizer tokenizer = new MockTokenizer(MockTokenizer.SIMPLE, true);
            return new TokenStreamComponents(tokenizer, new MockSynonymFilter(tokenizer));
          }
        };
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document doc = new Document();
        doc.add(new TextField("body", "guinea pig", Field.Store.NO));
        w.addDocument(doc);
      }
      QueryParser single = new QueryParser("body", analyzer);
      single.setDefaultOperator(QueryParser.Operator.AND);
      single.setSplitOnWhitespace(true);
      single.setAutoGeneratePhraseQueries(true);
      MultiFieldQueryParser multi = new MultiFieldQueryParser(new String[] {"body"}, analyzer);
      multi.setDefaultOperator(QueryParser.Operator.AND);
      multi.setSplitOnWhitespace(true);
      multi.setAutoGeneratePhraseQueries(true);
      Query expected = single.parse("guinea-pig");
      Query actual = multi.parse("guinea-pig");
      try (DirectoryReader reader = DirectoryReader.open(dir)) {
        IndexSearcher searcher = new IndexSearcher(reader);
        // expected: MultiFieldQueryParser{body} finds the 1 doc QueryParser(body) finds; actual: 0
        assertEquals(
            expected + " vs " + actual, searcher.count(expected), searcher.count(actual));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-319/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:$LUCENE/lucene/queryparser/build/libs/lucene-queryparser-$V.jar
CP=$CP:$LUCENE/lucene/sandbox/build/libs/lucene-sandbox-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.queryparser.classic.TestMultiFieldQueryParserSynonymGraph
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected: 1 hit, the same as
QueryParser("body")(body:"guinea pig" body:cavy). Actual:+(body:"guinea pig") +(body:cavy)finds 0 hits.
More files, environment, full output40 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: body:"guinea pig" body:cavy vs +(body:"guinea pig") +(body:cavy) expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.queryparser.classic.TestMultiFieldQueryParserSynonymGraph.testMultiWordSynonymUnderAnd(TestMultiFieldQueryParserSynonymGraph.java:65)- Javadoc: under AND "all the query's terms must appear, but it doesn't matter in what fields they appear"; adding
bodymust not lose doc 0. - Graph-phrase clauses are OR'ed alternatives; requiring both contradicts
QueryParseron the same field. - #16446's tests cover one shared analyzer only; Solr has guarded the same pairing since 2017 (SOLR-9185).
The full argument280 words
- The contract (javadoc of both constructors,
MultiFieldQueryParser.java:35-55,61-76): the query becomes(title:term1 body:term1) (title:term2 body:term2), under AND+(title:term1 body:term1) +(title:term2 body:term2), "In other words, all the query's terms must appear, but it doesn't matter in what fields they appear." The example uses the same terms in both fields and does not say what a term is when the fields' analyzers differ. Natural consistency properties suggested by it, not explicit API guarantees: with one field the class matches whatQueryParseron that field matches; when every field keeps every query word, adding a field does not lose a match; and a document that lacks a query word in every field does not match. - Per-field analysis is supported for query parsing.
PerFieldAnalyzerWrapper"can be used like any other analyzer, for both indexing and query parsing" (PerFieldAnalyzerWrapper.java:42-43). No javadoc, CHANGES, MIGRATE or package text restricts the class to one analysis for all fields. - Graph clauses are alternatives.
analyzeGraphPhrasebuilds "phrase queries" from "all the finite strings from the graph" and adds each as SHOULD (QueryBuilder.java:571-579). - The class disagrees with itself. A quoted
"wi-fi"takesgetFieldQuery(String,String,int)(MultiFieldQueryParser.java:82-108), which ORs each field's whole query and keeps the alternatives as SHOULD; the flexibleStandardQueryParserbuilds+(title:wi-fi (+body:wi +body:fi)) +(title:router body:router)and finds doc 0. - Tests and history. #16446's tests (
TestMultiFieldQueryParser.java:403-457,TestMultiFieldQueryParserBoostAndOperator) use one shared analyzer with aligned positions; none usesautoGeneratePhraseQueriesor fields that split text differently. The #16446 discussion (25 comments, 10 reviews) never considers either. The pairing came with LUCENE-2605 (2016); in 2017 the same author guarded the same pairing in Solr's edismax withallSameQueryStructure(SOLR-9185), which Lucene's parser never got.
The devil's-advocate check211 words
The strongest case for "intended" (the devil's-advocate verifier, the adjudication and reviews by OpenAI GPT-5.6): #16446 deliberately requires every analyzed position under AND, and its new javadoc names "synonym expansion" among the causes (MultiFieldQueryParser.java:211-219); an upstream test pins required groups; a 2009 java-user mail by uschindler said one "can use MultiFieldQueryParser, but not if the analyzer for both fields is different", because the different analyzers "will produce different tokens"; and the per-field half is nine years old, so it could be called a known limitation.
Why it fails: graph clauses are alternatives, not positions, and requiring a word and its synonym together contradicts QueryParser on the same field; #16443/#16446 and their tests cover aligned positions from one shared analyzer only; nothing in the docs restricts the class to uniform analysis, and the 2009 remark, though on point, is a list answer, not documentation, and predates the 2016 code that zips by clause index; a group like (title:router body:fi) has no meaning under any reading of the contract; and Solr guarded the same hazard. Verdict: a defect, clearly for the graph half new in 10.6.0; for the per-field half, which has shipped since 2016, whether to change it or keep it as a limitation is the maintainers' compatibility decision.
Recommended B (prototype): pair only aligned per-field queries (structure and text offsets), else OR whole per-field queries
A prototype: pair the fields' clauses only when they line up (same clause count and occurs, and each position covers the same span of the query text), else OR each field's whole query (+96 lines, one file). All bug tests and the module's 533 other tests pass. Limits: misaligned fields match only within one field; it trusts analyzer offsets.
if (maxTerms > 1
    && (termPositionsAligned(fieldQueries) == false   // same size, all clauses MUST under AND
        || sameTermSpans(fieldQueries, queryText) == false)) { // same text span per position
  for (int i = 0; i < fields.length; i++) {
    if (fieldQueries[i] != null) {
      clauses.add(applyBoost(fieldQueries[i], fields[i])); // keep each field's query whole
    }
  }
  return getMultiFieldQuery(clauses);
}
// ... the existing loop that pairs clause i of every field, unchanged
All options and trade-offs5 options · 869 words
The root cause is one method: pairing is only valid when clause i of every field's query covers the same words. Two options were built and run in a scratch worktree at ea57360912ed (removed afterwards); the others are untested.
B (prototype): pair only aligned per-field queries (structure and text offsets), else OR whole per-field queries (validated by the checks) (recommended)
Builds on the finder's structure check (option A) and adds sameTermSpans: it re-analyzes the text for each field with getAnalyzer().tokenStream(field, text) and compares the (start offset, end offset) of every position; stacked tokens widen the previous span. If either check fails, the method ORs each field's whole query. Results: wi-fi router gives (+title:wi-fi +title:router) (+body:wi +body:fi +body:router), hits [0]; wi-fi gives title:wi-fi (+body:wi +body:fi), [0].
if (maxTerms > 1
    && (termPositionsAligned(fieldQueries) == false   // same size, all clauses MUST under AND
        || sameTermSpans(fieldQueries, queryText) == false)) { // same text span per position
  for (int i = 0; i < fields.length; i++) {
    if (fieldQueries[i] != null) {
      clauses.add(applyBoost(fieldQueries[i], fields[i])); // keep each field's query whole
    }
  }
  return getMultiFieldQuery(clauses);
}
// ... the existing loop that pairs clause i of every field, unchanged
Trade-offs
- Fallback = the union of the per-field queries. When analyses differ, a document matches only if one field alone holds all the words. A document with title
wi-fiand bodyrouteris not found forwi-fi router, though the javadoc's expansion would find it (stock main does not find it either). - Stop-word behaviour changes. If
titlekeeps "the" andbodydrops it,the matrixnow matches a body-only "the matrix" document, asQueryParser("body")does; the literal expansion+title:the +(title:matrix body:matrix)requirestitle:the, and stock main gives+(title:the body:matrix) +(title:matrix), which requirestitle:matrix; both miss that document. Worth a CHANGES line. - Normalisation-only differences keep the pairing. Lowercased vs case-sensitive fields with the same token boundaries still give
+(title:router body:Router) +(title:cheap body:Cheap). - Cost. One extra analysis per field, only for multi-position text whose structure already lines up.
- It trusts the offsets (read, not run).
termSpansgets theOffsetAttributewithaddAttribute, which creates it when the chain has none (AttributeSource.java:209-220), andOffsetAttributeImplstarts and clears at (0, 0) (:27-28,:63-67). So fields whose chains set no offsets give equal (0, 0) spans, and equal-length but misaligned queries are still zipped, as on stock main.WordDelimiterGraphFilter's 3-argument constructor turnsadjustInternalOffsetsoff (WordDelimiterGraphFilter.java:249-250), so its parts keep the incoming token's offsets (:263,:401-403). - It assumes repeatable analysis and flattens graphs (read, not run). It analyzes the text a second time, so a stateful or nondeterministic analyzer could give a different stream from the one that built the query; it merges tokens with position increment 0 into one span and ignores larger increments and
PositionLengthAttribute. More design work is needed before proposing it upstream.
What the checks validated
- Gradle,
:lucene:queryparser:testwith this doc's test and five evidence tests from the hunt (the finder's, verifiers', two security probes): 548 tests, 0 failures, 1 skipped. Stock: 548 tests, 15 failures, exactly the 15 bug tests. With only this doc's test: 536 tests, 0 failures. - The classic package with
-Ptests.asserts=false -Ptests.seed=1234ABCD: 112 tests, 0 failures (with this doc's test and the 12 evidence tests from the hunt; 100 tests, 0 failures with only this doc's test, the fact check's run). checkGoogleJavaFormat,forbiddenApisMainandforbiddenApisTestfor the module pass.- Standalone runner with the fix: this doc's test 3 of 3 (assertions on and off), and every verifier's and security probe's test, including the
WordDelimiterGraphFilterand equal-length over-match tests, pass.
Pair only if every per-field query is a BooleanQuery of the same size whose clauses all carry the default-operator occur; else OR the whole per-field queries (+39 lines). Solr's allSameQueryStructure is the same kind of check.
Trade-offs
Equal-length lists with different words are still paired: the wi-fi with title [the, wi-fi] and a stop-word body [wi, fi] gives +(title:the body:wi) +(title:wi-fi body:fi), which admits a document with no "the" and no "fi". SOLR-16594 discusses the same weakness of structure-only checks. Otherwise as B.
What the checks validated
Gradle, same worktree: 548 tests, 1 failure, the equal-length over-match test. This doc's test passes 3 of 3.
Analyze each field with offsets and put every field's clauses for the same words into one group: +(title:wi-fi (+body:wi +body:fi)) +(title:router body:router). That is what the flexible StandardQueryParser already builds for this input.
Trade-offs
Keeps cross-field matches and follows the javadoc exactly, but needs more code, and token graphs and stacked tokens need care.
Fall back to whole per-field queries when a field's BooleanQuery has SHOULD clauses under AND (the occur part of A).
Trade-offs
Removes the #16446 regression only; the per-field half stays as in the releases.
Drop the pairing entirely.
Trade-offs
Breaks #16446's test, which asserts +(field1:foo field2:foo) +(field1:bar field2:bar) for a shared analyzer (read, not run), and drops cross-field matching everywhere.
Downstream: one field's word can stand in for another query word (the group (title:router body:fi)). A parsed allow rule can admit a document lacking a rule word in every field; a parsed deny rule can leave visible a document holding all its words, which a document author who knows the rule can arrange. Authorization is the application's job (SECURITY.md).
Semi-formal. While writing a Z3 model of the field grouping and reading #16446, an AI tool spotted the case; the model's bounded enumeration found the disagreeing shapes, and an exhaustive check of every query of up to 4 symbols on the stock jar found 22,670 failures, all in these two families. A JUnit test confirmed both.
The method in full224 words
Method: semi-formal (a hypothesis formed while modelling, then witnessed by a tool).
- A hunt unit (the classic query parser, 2026-10-26). The finder, an AI tool, wrote a Z3 model of
getFieldQuery's per-field grouping: 1 to 3 fields, per-field query shapes none, one term, k positions or k alternatives (k = 2..3), both operators, shared and per-field analyzers. The lead came from reading #16446 while writing the model. - The model enumerated the (shape, operator) classes where the code disagrees with its reading of the documented per-term expansion: with one shared analyzer only graph alternatives under AND; with per-field analyzers also misaligned shapes under AND. The enumeration ran to exhaustion for up to 2 fields and for 3 fields with a shared analyzer; for 3 fields with per-field analyzers it stopped at its cap of 50 classes.
- A bounded-exhaustive harness on the stock jar (every query of at most 4 symbols, 6 analyzer families, 24 parser configurations) found the oracle "one field equals
QueryParser" failing 10,640 times, all multi-word synonyms with AND andautoGeneratePhraseQueries, and "adding a field never loses a match" failing 12,030 times, all per-field analyzers with AND. A public-API JUnit test then confirmed both. - An independent reviewer from another model family (OpenAI GPT-5.6) reviewed it, verifiers and an adjudication confirmed it, and the history, prior-report and security checks followed.
No prior report found (2026-10-26): 110 logged searches over GitHub issues and PRs, commits, mailing lists, the JIRA archive, Stack Overflow and the web, #16446's full discussion, and all 413 open PRs (408 at a later re-check). Closest: #16443, the opposite symptom that #16446 fixed, and Solr's 2017 guard against the same pairing (SOLR-9185).
Searches4 searches
Verdict new for both halves (110 logged searches: 89 by a scripted prior-report search, 21 manual): high confidence for the graph half (merged four days before the search), medium-high for the per-field half (reachable since 2016, and the same hazard is guarded in Solr's own parser). Keyword search can miss differently worded reports, and private security reports cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues and PRs (apache/lucene and downstream) | 2026-10-26 | scripted prior-report search runs for each half (class and method names such as getMultiTermPositionQuery, PerFieldAnalyzerWrapper, autoGeneratePhraseQueries, synonym + AND), plus manual read-only searches; the per-field run had only 5 GitHub queries (GitHub's search rate limit) | no report; related: #16443, #16446, #16441/#16442, #8648 (LUCENE-7597), #8524 (LUCENE-7472), #3679 (LUCENE-2605), #14262 |
| Threads read in full | 2026-10-26 | #16446 (body, 25 comments, 8 inline comments, 10 reviews); LUCENE-2605, LUCENE-7472, LUCENE-7533; SOLR-9185, SOLR-12779, SOLR-15407, SOLR-15449, SOLR-16594, SOLR-3589 | #16446 covers one shared analyzer with aligned positions; SOLR-9185 added allSameQueryStructure to edismax (a precedent, not a report) |
| Open PRs and commits | 2026-10-26 | the file lists of all 413 open apache/lucene PRs (the fact check's re-scan later that day: 408, none touching the file); commits on the file on main and branch_10_6 | no fix; the newest commits on the file are #16446 |
| Mailing lists, JIRA archive, Stack Overflow, web | 2026-10-26 | dev@, java-user@, issues@, commits@ and solr-user@; JQL over LUCENE and SOLR; 63 Stack Overflow questions since 2016-07 (13 read); general web search | adjacent java-user threads from 2008, 2009 and 2011 (a stop word required under AND; an informal remark that the class does not suit differing analyzers); no report |
Two starts. The pairing came with LUCENE-2605 (2016): the per-field two-word case is in 6.2.0 with an option and in every release from 7.0.0 to 10.5.2 by default. #16446 (merged 2026-10-22, backported to branch_10_6, released in 10.6.0) added the synonym and one-word cases; 10.5.2 is correct there. Not fixed upstream.
Versions tested8 rows
Per-field half introduced by LUCENE-2605 (#3679, commits 17d113dac1e on master and 7d092fac4ea on branch_6x, 2016-07-05), which added the clause-number loop; first released in 6.2.0 behind setSplitOnWhitespace(false), default from 7.0.0 (24e5c1c2058). Graph half and one-word input introduced by #16446 (c71ef11c549, merged 2026-10-22, fixes #16443; backport 88c0bd4c346 on branch_10_6), which added getMultiTermPositionQuery and removed addMultiTermClauses. It first shipped in 10.6.0 (released 2026-10-29). A portable probe ran 92 releases x 4 cases; branch_10_6 was run by shadowing its parser sources over the 10.5.2 jars, not built, and there was no build exactly at c71ef11c549.
| Version or commit | Verdict | Result |
|---|---|---|
| 6.0.0 - 6.1.0 | before LUCENE-2605 | whole per-field queries ORed: every case finds the document |
| 6.2.0 - 6.6.6 | opt-in | two words with setSplitOnWhitespace(false) miss the document; default settings find it but also match doc 1; one word over-matches (#16443) |
| 7.0.0 - 10.5.2 | default settings | wi-fi router gives +(title:wi-fi body:wi) +(title:router body:fi) +(body:router); this doc's test 1 of 3 fails on 9.12.3 and 10.5.2; the synonym case is correct |
7cecf795236 (parent of #16446) | commit level | synonym and one-word cases pass; two-word case fails |
b83101cdd2c (#16446 plus 3 unrelated commits) | commit level | all four cases fail |
branch_10_6 aac3c7ae947 / 2763db11b0a | shadowed | before the backport like 10.5.2; at the head all four cases fail |
main ea57360912ed | affected | this doc's test 3 of 3 fail, assertions on and off, gradle and runner |
| main + fix B | not affected | 3 of 3 pass; queryparser module 536 tests, 0 failures |
A reviewer from another model family (OpenAI GPT-5.6), AI verifiers and an adjudication: all say real except one procedural "not real" from a review that could not run code; the adjudication confirmed it with high confidence after re-running the tests. This doc's test was re-run on main, 10.5.2, 9.12.3 and with both fixes.
Checks and verdicts456 words
Every check ran on main ea57360912ed unless noted.
| Check | Verdict | What it found |
|---|---|---|
| Refute review (OpenAI GPT-5.6, read-only) | not real, low confidence, procedural | It could not run Java, and it needs an executed test of its own to vote real; its notes say "Static inspection strongly supports a genuine defect". A separate run re-ran the repro: 2 of 2 fail. |
| Independent reproducer | real | Own test: 4 of 4 fail on main (assertions on and off), 1 of 4 on 10.5.2 and 9.12.3 (the two-word case); a WordDelimiterGraphFilter variant fails on main only; controls pass; all pass with the fix. |
| "works as designed" review (OpenAI GPT-5.6) | real, medium; intended argument moderate | Its verifier ran a per-field test: 3 of 3 fail on main, 1 of 3 on 10.5.2, 3 of 3 pass with the fix; the flexible StandardQueryParser finds the match. |
| Devil's advocate | real | Graph half: a clean #16446 regression; per-field half: real but older. Probes: a stock WordDelimiterGraphFilter trigger, and the quoted path keeps the alternatives. |
| Adjudication | confirmed, high | Re-ran the finder's and the independent reproduction's tests; required the scope correction that only the graph half and one-word input are a #16446 regression. |
| Follow-up | new; not security-sensitive (strict re-evaluation) | History sweep of 92 releases, prior-art search, and the security probe that found the over-match direction. |
| This doc | reproduced; fix B validated | A compact 3-test repro on main, 10.5.2 and 9.12.3; fix B and fix A run with the full queryparser suite in a scratch worktree. |
| Independent fact check (2026-10-26) | real; 2 wording errors and 14 minor items, applied | A separate AI tool re-ran the gradle command on a clean copy of ea57360912ed (3 of 3 fail), the runner on main, 10.5.2 and 9.12.3 with assertions on and off and three root seeds, its own probe of every parsed query and hit list, and fix B with the module suite (536 tests, 0 failures). Errors: the document author's role in deny rules, and over-match described as "no field's own query matches". |
| Cross-model fact check (OpenAI GPT-5.6, read-only) | diagnosis sound; 2 errors, 5 overclaims, 5 missing caveats, applied | An independent reviewer from another model family checked the brief against the code and the recorded runs. Errors: fix B's claimed safety with broken offsets (removed; its offset limits are now stated) and the Z3 model's coverage. Intended-behaviour case: moderate for both halves. |
| Diagram check | one card error, fixed and re-rendered | Every query string, hit set, API name and line number in the PNG matched the code and the re-run probe. The summary card's synonym bullet left out setAutoGeneratePhraseQueries(true); the card now names it, and its security bullet covers allow and deny rules. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 449 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,663 words
- Registry title
- MultiFieldQueryParser under AND treats clause i of every field's analyzed BooleanQuery as term position i and requires each group, so fields whose analyzers tokenize the same text differently lose (and sometimes gain wrong) matches (released since 6.2.0, default settings since 7.0.0), and since #16446 (10.6.0) graph-phrase alternatives such as a multi-word synonym are required together
- Area
- queryparser / classic MultiFieldQueryParser (getFieldQuery(String,String,boolean) per-field clause grouping and getMultiTermPositionQuery; core util/QueryBuilder graph phrases)
- Priority
- Medium, rank 28: In the default classic MultiFieldQueryParser, ordinary AND queries over fields with different analyzers have silently lost matches since 7.0.0 and 10.6.0 made it worse, a wide-reach core query-construction bug.
- Impact class
- silent wrong results
- Impact note
- Applications that parse query text with MultiFieldQueryParser under AND_OPERATOR get fewer hits with no error, and in the per-field case sometimes wrong extra hits, when the searched fields use analyzers that tokenize the same text differently (for example whitespace versus letter tokenization of 'wi-fi router', or different stop sets): for multi-word input under the default splitOnWhitespace=false this is in every release from 7.0.0 (6.2.0 with the option set) through 10.6.0 and main; since #16446 (main and branch_10_6, released in 10.6.0 on 2026-10-29) single-token input such as 'wi-fi' is affected too, and with autoGeneratePhraseQueries=true and splitOnWhitespace=true any query word that analysis turns into a token graph (multi-word synonyms, WordDelimiterGraphFilter catenation) has all its alternatives required, so even a single field disagrees with QueryParser; AND and per-field analysis are application choices, and no scale is needed.
- Summary
- You search the fields title and body with MultiFieldQueryParser under AND_OPERATOR and expect what its class javadoc promises: every query term must appear, in any field, so adding a field never loses a document that QueryParser on one of those fields finds. Instead getFieldQuery takes clause i of each field's analyzed BooleanQuery as 'term position i' and requires every such group: with title tokenized on whitespace and body on letters, 'wi-fi router' becomes +(title:wi-fi body:wi) +(title:router body:fi) +(body:router), which misses a document titled 'wi-fi router' and matches one with title 'router' and body 'wi router' (released since 6.2.0, default settings since 7.0.0; since #16446 the single word 'wi-fi' loses the match too). Since #16446 (in 10.6.0), with autoGeneratePhraseQueries and the multi-word synonym 'guinea pig' -> 'cavy', 'guinea-pig' becomes +(body:"guinea pig") +(body:cavy), so even MultiFieldQueryParser over body alone finds nothing where QueryParser(body) finds the document.
- Introduced
- Two starts, one root cause (follow-up). (1) The grouping: 17d113dac1e6 (master) / 7d092fac4ea (branch_6x), LUCENE-2605 'queryparser parses on whitespace' (apache/lucene#3679, 2016-07-05) added the termNum loop in MultiFieldQueryParser.getFieldQuery that ORs clause termNum of every per-field BooleanQuery across fields; for multi-word input with splitOnWhitespace=false, QueryParser's MultiTerm rule and addMultiTermClauses then made each group required under AND (opt-in in 6.2.0; default from 7.0.0, when 24e5c1c2058 made splitOnWhitespace=false the default). (2) c71ef11c549d (apache/lucene#16446, fixes #16443, merged 2026-10-22; backported to branch_10_6 as 88c0bd4c346) added getMultiTermPositionQuery, which combines the groups of one getFieldQuery call with the default operator (MUST under AND) and removed addMultiTermClauses: QueryBuilder.analyzeGraphPhrase's SHOULD alternatives and unaligned single-token per-field lists became required groups. [exec: a portable main() probe passes the graph case and the single-token per-field case at 7cecf795236 (parent of c71ef11c549) and fails them at b83101cdd2c (c71ef11c549 plus 2 commits that do not touch the query parser, QueryBuilder or memory) and on main; branch_10_6's classic-parser sources shadowed over the 10.5.2 jars pass at aac3c7ae947 (pre-backport) and fail at 2763db11b0a; the multi-word per-field case fails on every release from 6.2.0 with the option and from 7.0.0 under defaults, and 6.0.0 to 6.1.0 pass. read: git blame -w, git log -S and git tag --contains in the full-history clone; no build exactly at c71ef11c549] (2016-07-05 (LUCENE-2605, 17d113dac1e) for the per-field grouping with multi-word input (released in 6.2.0, default settings from 7.0.0); 2026-10-22 (#16446, c71ef11c549 and the branch_10_6 backport 88c0bd4c346) for graph alternatives and single-token per-field input)
- First affected version
- 6.2.0 [exec] for per-field analyzers with multi-word input and setSplitOnWhitespace(false); 7.0.0 [exec] under default parser settings (splitOnWhitespace=false became the default). Graph alternatives and single-token per-field input: 10.6.0 (released 2026-10-29; main and branch_10_6 since #16446; 10.5.2 and 9.12.3 pass [exec])
- Affected versions
- Per-field analyzers, multi-word input: every executed release from 6.2.0 to 6.6.6 with setSplitOnWhitespace(false) and from 7.0.0 to 10.5.2 under default settings, and main [exec: 92-release sweep of a portable main() probe; the independent reproduction's JUnit fails 1 of 4 on 10.5.2 and 9.12.3, exactly this case; a separate test, 1 of 3 on 10.5.2]; 6.0.0 to 6.1.0 not affected (no splitOnWhitespace option, whole per-field queries ORed) [exec]. Graph alternatives and single-token per-field input: main ea57360912ed [exec, -ea and -da] and branch_10_6 head 2763db11b0a [exec as a shadow of its classic-parser sources over the 10.5.2 jars, not a build]; no release before 10.6.0 [exec: pass on every release in the sweep, except 6.2.0 and 6.2.1, where the graph case fails for a different, since-fixed reason, LUCENE-7472]. On releases up to 10.5.2 the single-token per-field input over-matches instead (the #16443 symptom that #16446 fixed; not counted here). The over-match of the per-field half reproduces on main (-ea and -da), 10.5.2 and 9.12.3 [exec, security probe]. Not fixed upstream: the newest commits on MultiFieldQueryParser.java are #16446 on main (c71ef11c549) and branch_10_6 (88c0bd4c346), and no open PR touches the file (413 open PRs scanned, 2026-10-26) [read]. All runs on JDK 25, aarch64 Linux, not each release's own JDK.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: Z3, code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, verdict new for both halves; read-only: scripted prior-report searches for the graph half and the per-field half, about 90 queries over apache/lucene issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, LUCENE JIRA and the web; the body, 25 comments, 8 inline comments and 10 reviews of #16446; full reads of LUCENE-2605, LUCENE-7472, LUCENE-7533, SOLR-9185, SOLR-12779, SOLR-15407, SOLR-15449, SOLR-16594 and SOLR-3589; JQL over LUCENE and SOLR; list statistics and thread reads; 63 Stack Overflow questions since 2016-07 screened, 13 read; the file lists of all 413 open apache/lucene PRs). Related, not reports of this bug: #16443 (the opposite symptom, closed by #16446) and #16446 itself (the cause of the graph half; its discussion covers aligned positions from one shared analyzer only, and its new javadoc names 'synonym expansion' among the cases where all positions must be required), #16441 (per-field boosts under AND; closed as completed 2026-10-26 by javanna, 'Fixed by #16446'; #16446 merged 2026-10-22 as c71ef11c549), #16442 (unmerged alternative fix for #16441), #8648 / LUCENE-7597 (the #16443 symptom), #8524 / LUCENE-7472 (same loop, dropped MultiPhraseQuery, fixed 2016), #3679 / LUCENE-2605 (origin of the grouping), #8584 / LUCENE-7533, #14262 (open, multi-field QueryBuilder), SOLR-9185 (2017: Solr's edismax checks allSameQueryStructure before zipping per-field queries by clause position, a guard Lucene's MultiFieldQueryParser never got), SOLR-16594, SOLR-12779, SOLR-15449, SOLR-15407 and SOLR-3589 (edismax), and java-user threads of 2008, 2009 and 2011 (a stopword dropped by one field's analyzer becomes required under AND; an informal remark that MultiFieldQueryParser does not suit differing analyzers; different mechanism). Not fixed upstream (no later commit on MultiFieldQueryParser.java on main or branch_10_6, no open PR touches it). Gaps: GitHub's search rate limit was reached, so the per-field run used 5 GitHub queries (earlier runs cover the class-name, title and PerFieldAnalyzerWrapper queries); downstream projects were checked through issue and PR text only; keyword search can miss differently worded reports; private security reports cannot be searched.
- Lucene commit tested
- main
ea57360912ed(commit of 2026-10-24, tested 2026-10-26), assertions on and off, seed DEADBEEF, through gradle in a scratch worktree (removed afterwards) and through a standalone JUnit runner; the Maven Central jars of 10.5.2 (assertions on and off) and 9.12.3; fix A and fix B, each with the full queryparser test suite; the follow-up's portable probe on 92 releases from 6.0.0 and on commits around #16446.
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/MultiFieldQueryParser.java:35-55 (at ea57360912ed) (class javadoc: '(title:term1 body:term1) (title:term2 body:term2)', under AND '+(title:term1 body:term1) +(title:term2 body:term2)', 'all the query's terms must appear, but it doesn't matter in what fields they appear'), :143-209 (getFieldQuery(String,String,boolean): clause termNum of every per-field BooleanQuery, occurs dropped, ORed across fields; comment 'one group per analyzed TERM POSITION'), :211-234 (getMultiTermPositionQuery: MUST per group under AND; javadoc names 'synonym expansion')lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:565-583 (at ea57360912ed) (analyzeGraphPhrase: one SHOULD clause per finite string of the token graph)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/PerFieldAnalyzerWrapper.java:24-43 (at ea57360912ed) (different analysis per field; 'can be used like any other analyzer, for both indexing and query parsing')
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/MultiFieldQueryParser.java:142-234 (per-field analysis, the clause loop, the comment, getMultiTermPositionQuery)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:565-583 (analyzeGraphPhrase: one SHOULD clause per finite string)Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:376-409 (MultiTerm: one getFieldQuery call for the joined text when splitOnWhitespace=false)
- Who is affected
a Lucene clone: git show 88c0bd4c346 --stat and origin/branch_10_6 (2763db11b0a) lucene/CHANGES.txt (no #16443/#16441 entry)Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/QueryParser.jj:123-166 (autoGeneratePhraseQueries and splitOnWhitespace, LUCENE-7533)
- Why it looks unintended
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/classic/MultiFieldQueryParser.java:35-55, 61-76 (constructor javadoc), 82-108 (quoted path), 199-204, 211-219Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:565-583Lucene main ea57360912ed: lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/PerFieldAnalyzerWrapper.java:42-43Lucene main ea57360912ed: lucene/queryparser/src/test/org/apache/lucene/queryparser/classic/TestMultiFieldQueryParser.java:304 (testAnalyzerReturningNull), 403-457 (#16446 tests)
- Suggested fix
Lucene main ea57360912ed: lucene/queryparser/src/test/org/apache/lucene/queryparser/classic/TestMultiFieldQueryParser.java:403-420 (shared-analyzer test that option 'always-whole' would break)Lucene main ea57360912ed: lucene/core/src/java/org/apache/lucene/util/AttributeSource.java:209-220, lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/OffsetAttributeImpl.java:27-28, 63-67, lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:249-250, 263, 401-403 (fix B's offset assumption)
- History
a Lucene clone: git log c71ef11c549..b83101cdd2c (3 commits)
- TestMultiFieldQueryParserSynonymGraph.java (JUnit test):
repro/LFV-319/src/org/apache/lucene/queryparser/classic/TestMultiFieldQueryParserSynonymGraph.java(70 lines)
Made in parallel with this doc from its own executed probe on main, 10.5.2 and 9.12.3; the alt text follows the summary card's plan.
assets/LFV-319/bug.png(449 KB)