SortedSetDocValues faceting stores every facet path as one term, with U+001F between the parts, and indexes every ancestor of a hierarchical path. When the reader state is created for a reader, it walks the terms in sorted order and builds the tree from neighbours: a next term with more components (labels) is taken as the first child, one with as many as the next sibling.
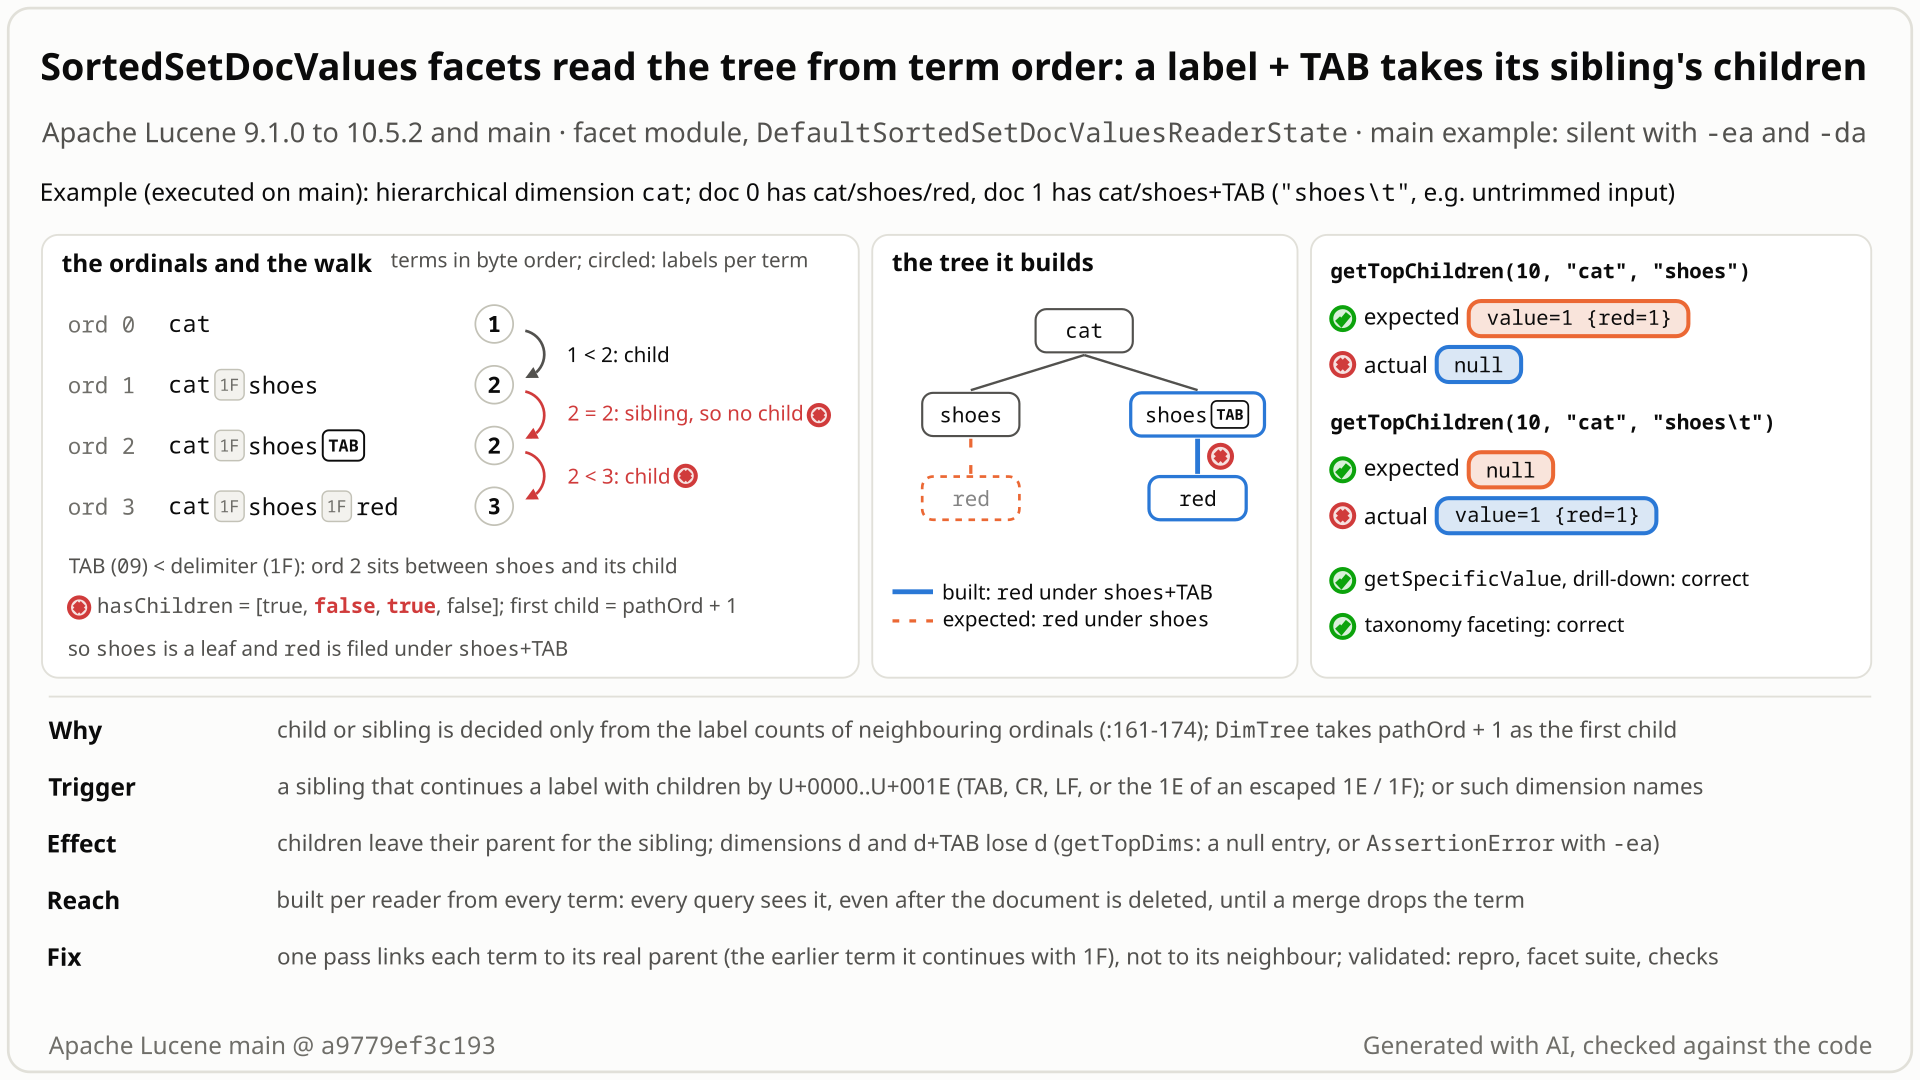
cat, cat/shoes, cat/shoes<TAB>, cat/shoes/red. Read by neighbours, red hangs under shoes<TAB> and shoes has no children; the real tree has red under shoes. Select the still to open it at full size. Generated with AI, checked against the code.- Configure
setHierarchical("cat", true)and index two documents withSortedSetDocValuesFacetField: one labeledcat/shoes/red, one labeledcat/"shoes<TAB>"(an untrimmed label). The API accepts both. - You expect
getTopChildren(10, "cat", "shoes")to returnred (1), as taxonomy faceting does for the same labels, and"shoes<TAB>"to have no children. - You get null for
shoes, andgetTopChildren(10, "cat", "shoes<TAB>")returnsred (1).getSpecificValue("cat", "shoes", "red")is still 1 and a drill-down still finds the document. - Why: paths are stored as one term each, with U+001F between the parts (shown as /), sorted by byte. TAB (0x09) sorts before U+001F (0x1F), so the order is
cat,cat/shoes,cat/shoes<TAB>,cat/shoes/red, and Lucene decides parent and child only from neighbouring terms:redlands undershoes<TAB>. - The same order trick on dimension names (
colornext tocolor<TAB>) makes a dimension vanish fromgetTopChildrenandgetAllDims, or drops one label of a flat multi-valuedrequireDimCountdimension. No error in any case.
Applications using SortedSetDocValues facets with a hierarchical dimension, or a flat multi-valued requireDimCount dimension, whose labels can carry a stray TAB, CR or LF (imported or user-typed paths) or contain U+001E/U+001F. Two documents are enough. The wrong tree applies to every request that walks the affected paths on that reader, and the indexed data stays correct.
Mechanism, terms and numbers763 words
SortedSetDocValues (SSDV) faceting stores each facet path as one term, dim U+001F label U+001F ..., and for a hierarchical dimension it also indexes every ancestor path. When the application creates a DefaultSortedSetDocValuesReaderState for a reader, it walks the terms in sorted order and builds the facet tree from neighbours only: a next term with more components is taken as the first child, one with as many components as the next sibling. That is right only if the separator sorts first after a label, but TAB, CR, LF and every other character from U+0000 to U+001E sort before U+001F, and FacetsConfig itself writes U+001E when it escapes a label that contains U+001F or U+001E. So with documents cat/shoes/red and cat/"shoes<TAB>" the terms sort cat, cat/shoes, cat/shoes<TAB>, cat/shoes/red: getTopChildren(10, "cat", "shoes") returns null and the leaf "shoes<TAB>" reports red (1). Dimension names built the same way (color next to color<TAB>) make a dimension disappear from getTopChildren and getAllDims, give getTopDims a null entry, or make a flat multi-valued requireDimCount dimension lose a label. There is no exception; taxonomy faceting, getSpecificValue and drill-down stay right. Every release from 9.1.0 (2022) to 10.5.2 and main is affected. A fix that finds each term's real parent with a stack of byte prefixes passes the repro, the whole facet test suite and an exhaustive and a randomized differential check.
- SSDV faceting:
SortedSetDocValuesFacetFieldlabels, counted bySortedSetDocValuesFacetCountsorConcurrentSortedSetDocValuesFacetCountsover aDefaultSortedSetDocValuesReaderStatebuilt once per reader. No taxonomy index. - Encoded path:
FacetsConfig.pathToStringjoins the dimension and labels withDELIM_CHARU+001F and puts the escape character U+001E in front of any U+001F or U+001E inside a part (FacetsConfig.java:550-553,:569-593). Terms sort by unsigned byte, and each term's position is its ord. - Hierarchical dimension:
FacetsConfig.setHierarchical(dim, true). Every prefix of a path is indexed, the bare dimension included (FacetsConfig.java:474-481). A flat multi-valued +requireDimCountdimension indexes its bare dimension term plusdim/label(:491-497).
- The constructor walks the ords from 0 and handles one run of terms with the same dimension at a time (
DefaultSortedSetDocValuesReaderState.java:101-111); a run ends when the next term's dimension differs (:154-159). - Inside a run it decides structure from the next term only: more components means "next ord must be a direct child of current ord, this is because we are indexing all ancestral paths" (
:161-168); as many means "next ord must be a sibling" (:169-174).DimTreethen takes the first child of a path to be the next ord (SortedSetDocValuesReaderState.java:122-124). - A sibling that continues a label with a byte below 0x1F sorts between the label and its children:
cat/shoes<cat/shoes<TAB><cat/shoes/red. Soshoesis recorded as childless andredbecomes the first child ofshoes<TAB>. - Dimension names: the terms of
color<TAB>sort betweencolorandcolor/red, so the run ofcolorends after its bare term and a later run ofcoloroverwrites its state (prefixToDimTree.put,:185; flatprefixToOrdRange.put,:234). The new state starts atcolor/red, which has no children. For a flat multi-valuedrequireDimCountdimension the surviving range starts at a label, which the counting code skips as if it were the dimension term (AbstractSortedSetDocValueFacetCounts.java:274-281).
Documents cat/shoes/red and cat/"shoes<TAB>", setHierarchical("cat", true), MatchAllDocsQuery (U+001F shown as /):
| ord | term | read as | really |
|---|---|---|---|
| 0 | cat | dimension, first child ord 1 | dimension |
| 1 | cat/shoes | child of cat, no children, sibling ord 2 | child of cat, child red |
| 2 | cat/shoes<TAB> | child of cat, first child ord 3 | child of cat, no children |
| 3 | cat/shoes/red | child of shoes<TAB> | child of shoes |
| call | expected | SSDV faceting |
|---|---|---|
getTopChildren(10, "cat", "shoes") | red (1) | null |
getTopChildren(10, "cat", "shoes<TAB>") | null | red (1) |
getTopChildren(10, "cat") | shoes (1), shoes<TAB> (1) | the same |
getSpecificValue("cat", "shoes", "red") | 1 | 1 |
label "shoes\u001F" (escaped) instead of "shoes\t" | red (1) under shoes | null; the sibling reports red (1) |
dims color (doc color/red) and color<TAB> (doc color<TAB>/x): getTopChildren(10, "color") | red (1) | null; getAllDims lists only color<TAB>; getTopDims returns [null, color<TAB>] (AssertionError with assertions on) |
flat tag, multi-valued + requireDimCount, docs {a, b}, {b} and tag<TAB>/c: getTopChildren(10, "tag") | value=2, b=2, a=1 | value=1, b=2 |
Over three segments with US/New York/Manhattan, US/New York/Brooklyn and US/"New York<CR>", the leaf New York<CR> is returned as a parent with value=1 and the children it was wrongly given, Brooklyn=1, Manhattan=1: a value smaller than the sum of its children.
Exposure and likelihood305 words
- Who is exposed. Users of
DefaultSortedSetDocValuesReaderStatewithSortedSetDocValuesFacetCountsorConcurrentSortedSetDocValuesFacetCounts(both fail alike) on a dimension configuredsetHierarchical(dim, true), or flat withsetMultiValued+setRequireDimCount, where a sibling label continues a label with a character from U+0000 to U+001F, at the end (shoes<TAB>) or followed by more text (shoes<TAB>clearance, executed), and the shorter label has children: untrimmed CRLF or TAB artefacts in imported category paths, or labels that contain U+001E or U+001F. Trimming only the ends of labels does not rule it out. The dimension-name variants need names likecolorandcolor<TAB>. - Default vs opt-in. Default codec,
IndexWriterConfigand searcher; the hierarchical (or multi-valued +requireDimCount) setting is opt-in, and hierarchical SSDV facets exist since 9.1.0. - Scale. Two documents; single- and multi-segment indexes fail alike.
- Index-wide. The tree is built from every term of the field, so a document outside the query, or deleted but not yet merged away, also triggers it; a merge that drops the document restores the tree.
- Silent. No exception, except an AssertionError from
getTopDimsin the dimension-name variant when assertions are on (a null list entry when they are off). A result can contradict itself: a leaf returned as a parent whose value is smaller than the sum of the children it was wrongly given. - Not affected. Taxonomy faceting,
getSpecificValue, drill-down and hits, flat dimensions withoutrequireDimCount(single- or multi-valued; they index no bare dimension term, executed), and siblings that continue with a character at or above U+0020 (shoes sale). The indexed terms are correct, so a fix needs no reindex. - How likely. Rare: it needs a label and a sibling label that continues it with a control character, and the shorter label must have children. The searches listed under prior reports found no public report since 9.1.0 (2022).
The test shows that SortedSetDocValues hierarchical faceting moves the children of a label to a sibling label that is the same text plus a TAB (cat/shoes/red next to cat/"shoes\t").
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.facet.sortedset;

import org.apache.lucene.document.Document;
import org.apache.lucene.facet.FacetResult;
import org.apache.lucene.facet.FacetsConfig;
import org.apache.lucene.facet.LabelAndValue;
import org.apache.lucene.index.DirectoryReader;
import org.apache.lucene.index.IndexWriter;
import org.apache.lucene.index.IndexWriterConfig;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSsdvFacetChildrenMovedToTabSibling extends LuceneTestCase {

  public void testChildStaysUnderItsLabel() throws Exception {
    FacetsConfig config = new FacetsConfig();
    config.setHierarchical("cat", true);
    try (Directory dir = new ByteBuffersDirectory()) {
      try (IndexWriter w = new IndexWriter(dir, new IndexWriterConfig())) {
        Document d1 = new Document();
        d1.add(new SortedSetDocValuesFacetField("cat", "shoes", "red"));
        w.addDocument(config.build(d1));
        Document d2 = new Document();
        d2.add(new SortedSetDocValuesFacetField("cat", "shoes\t"));
        w.addDocument(config.build(d2));
      }
      try (DirectoryReader r = DirectoryReader.open(dir)) {
        SortedSetDocValuesFacetCounts facets =
            new SortedSetDocValuesFacetCounts(new DefaultSortedSetDocValuesReaderState(r, config));
        LabelAndValue[] red = {new LabelAndValue("red", 1)};
        FacetResult expected = new FacetResult("cat", new String[] {"shoes"}, 1, red, 1);
        // expected: cat/shoes has the child red=1; actual: null (red moved to sibling "shoes\t")
        assertEquals(expected, facets.getTopChildren(10, "cat", "shoes"));
      }
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-324/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.facet.sortedset.TestSsdvFacetChildrenMovedToTabSibling
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected
getTopChildren(10, "cat", "shoes")to return value=1 with child red (1); actual:null(red is reported under "shoes\t"), with-eaand-da.
More files, environment, full output40 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<dim=cat path=[shoes] value=1 childCount=1
  red (1)
> but was:<null>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.facet.sortedset.TestSsdvFacetChildrenMovedToTabSibling.testChildStaysUnderItsLabel(TestSsdvFacetChildrenMovedToTabSibling.java:50)getTopChildrenreturns "the topN child labels under the specified path"; here the path exists and has a child, yet it returns null.FacetsConfigescapes U+001F and U+001E inside labels on purpose, and the escape character itself triggers the bug; taxonomy facets get it right.- Labels are checked only for null or empty.
The full argument286 words
- Contract.
Facets.java:39-44:getTopChildren"Returns the topN child labels under the specified path. Returns null if the specified path doesn't exist or if this dimension was never seen."getAllChildren(:32-37): "all child labels with non-zero counts under the specified path". For a path without childrengetTopChildrenreturns null in SSDV and taxonomy faceting alike (AbstractSortedSetDocValueFacetCounts.java:364-371), so the null is not the defect by itself; the defect is thatshoeshas a child.getTopDims(:59-69): "Results should be the same as calling getAllDims", which drops null results (AbstractSortedSetDocValueFacetCounts.java:122-125). - Accepted input.
FacetField.verifyLabel(FacetField.java:64-73), called for every label and dimension of aSortedSetDocValuesFacetField, rejects only null or empty strings.FacetsConfig"Escapes any occurrence of the path component inside the label" (FacetsConfig.java:552,:582-583). No javadoc, CHANGES or MIGRATE entry limits SSDV label characters. - Tests.
TestTaxonomyFacetCounts#testLabelWithDelimiter(:422) asserts that labels containing U+001F and U+001E work for taxonomy facets. The randomized SSDV tests draw labels fromTestUtil.randomRealisticUnicodeString, whose first block starts at U+0000, so they do generate control characters, but almost never the needed pair of sibling labels. - History. In LUCENE-4795 (2013) mikemccand wanted labels to be allowed to use the delimiter; LUCENE-5339 (4.7.0) replaced the restriction with escaping and rewrote
testLabelWithDelimiter, which had expected such a label to be rejected, to assert that labels containing U+001F and U+001E are counted. LUCENE-10250 (#509, 9.1.0) built the tree from adjacency; its review praised "the first child will always have to be one value greater than the parent ordinal" as a memory saving and never discussed characters below the delimiter. - Consistency. Taxonomy faceting with the same labels and config returns
red (1)undershoes(executed control).
The devil's-advocate check227 words
The strongest "intended" case: building the tree from sorted order is a deliberate, reviewed memory optimisation (rmuir in #11286: "due to the sorted order, we really do effectively have a tree already"); in 2013 a committer argued that U+001F is "really not expected to be part of a category string" and that applications should keep it out; control characters in labels are unclean data; the facet API is @lucene.experimental; and the dimension-name variants are contrived.
Why it fails: the premise holds only if the separator is the smallest byte that can follow a label, which the encoding does not guarantee, and FacetsConfig itself writes U+001E, which sorts lower. The 2013 stance was replaced by deliberate escaping in LUCENE-5339, backed by an upstream test, and taxonomy faceting handles the same labels. The API accepts these labels and nothing documents a restriction; silently moved children are not a reasonable reading of "unclean data", and @lucene.experimental is about API stability, not wrong counts. The case is weakest for labels containing U+001F/U+001E (escaped on purpose); for raw TAB/CR/LF a committer could reasonably prefer to reject raw control characters in SSDV labels from now on, and the dimension-name variants are contrived. Verdict: a defect (adjudication: confirmed, high), of low likelihood; every check called it real except the refute-lens review, whose "not real" (low) was procedural because it could not run anything.
Recommended Build the tree from real parent links, and keep a dimension's state when other terms interleave
Find each term's real parent instead of trusting neighbours: one pass keeps a stack of earlier terms that are byte prefixes of the current one; the parent is the entry the term continues with U+001F. First children are stored only when needed. The repro, all 312 facet tests and the nightly SSDV tests pass.
// DefaultSortedSetDocValuesReaderState, single pass over ords (condensed)
int common = commonPrefixLength(previous.get(), term);
while (openPaths.isEmpty() == false && openPaths.peek().length > common) {
  openPaths.pop();
}
if (components.length > 1) { // link to the entry it continues with U+001F
  OpenPath parent = findParent(openPaths, term, components.length - 1);
  if (parent != null) {
    if (parent.lastChild == INVALID_ORDINAL) firstChild[parent.ord] = ord;
    else siblings[parent.lastChild] = ord;
    parent.lastChild = ord;
  }
}
openPaths.push(new OpenPath(ord, term.length, components.length));
All options and trade-offs5 options · 944 words
For clean data (each dimension's terms contiguous, every first child right after its parent) the kept state has the same size as today (a bit set and a sibling array); a dimension split by another one's terms keeps arrays over its whole first-to-last ord range, and the new first-child array appears only for a dimension that needs it. Nothing in the index changes, so no reindex is needed. Nothing was benchmarked. The patch touches the same counting code as two other SSDV facet bugs (a never-seen hierarchical dimension throwing, and the unescaped bare dimension term of flat requireDimCount dimensions), so if they are fixed together one patch needs a rebase.
Build the tree from real parent links, and keep a dimension's state when other terms interleave (validated by the checks) (recommended)
Three files in lucene/facet/src/java/org/apache/lucene/facet/sortedset/, +175/-127. DefaultSortedSetDocValuesReaderState: one pass over all ords replaces the run-by-run loop. A stack holds the earlier terms that are byte prefixes of the current term (pop while an entry is longer than the common prefix with the previous term). A term's parent is the topmost entry with one component less that the term continues with the delimiter byte; it is always on the stack, because the parent sorts first and every term in between starts with its bytes. Links go into two transient int[] of the field's value count. Each hierarchical dimension keeps its first and last ord (terms of color<TAB> inside the range of color are never linked from it); each flat dimension records its bare dimension ord and its label range separately. DimTree gets a package-private constructor with an optional int[] firstChild, used by iterator(pathOrd) when present. AbstractSortedSetDocValueFacetCounts looks up the bare dimension term of a flat multi-valued requireDimCount dimension and skips ordRange.start() only when it is that term.
// DefaultSortedSetDocValuesReaderState, single pass over ords (condensed)
int common = commonPrefixLength(previous.get(), term);
while (openPaths.isEmpty() == false && openPaths.peek().length > common) {
  openPaths.pop();
}
if (components.length > 1) { // link to the entry it continues with U+001F
  OpenPath parent = findParent(openPaths, term, components.length - 1);
  if (parent != null) {
    if (parent.lastChild == INVALID_ORDINAL) firstChild[parent.ord] = ord;
    else siblings[parent.lastChild] = ord;
    parent.lastChild = ord;
  }
}
openPaths.push(new OpenPath(ord, term.length, components.length));
Trade-offs
- Kept state: for clean data the same size as today. A dimension whose terms are interleaved with another dimension's (the split case) keeps its arrays over its whole first-to-last ord range, the interleaved ords included (today only the last, overwritten run is kept); a dimension that needs first-child links also keeps an
int[] firstChildover that range (+4 bytes per ord of the range). - Construction: two transient
int[valueCount]instead of today's per-dimension boxedArrayList<Integer>andArrayList<Boolean>; per ord oneArrays.mismatchagainst the previous term, and per hierarchical term a walk down the stack of open prefix paths, whose length grows with the depth of the hierarchy. Not benchmarked. - Queries: one
lookupTermeach time the children of a flat multi-valuedrequireDimCountdimension are iterated (getTopChildren,getAllChildren,getAllDims), and ingetTopDimsone more per such dimension to rank it. - Compatibility (argued, not tested): a split flat
requireDimCountdimension's publicOrdRangein the default state now holds only its labels, which direct callers ofgetOrdRangemay notice; custom states that keep today's layout should still work, because the dimension term is then found atordRange.start(). No test covers a custom state. - If the unescaped bare dimension term (a separate bug) is fixed by escaping it, the new lookup must use the escaped form.
What the checks validated
- Scratch worktree of
a9779ef3c193, gradle, JDK 25: the new test fails 4 of 6 on stock (assertions on and off) and passes 6 of 6 with the fix; the whole:lucene:facet:test, 40 suites and 312 tests, 0 failures, with assertions on and off;TestSortedSetDocValuesFacetswith-Ptests.nightly=true -Ptests.iters=5, 95 tests, 0 failures;:lucene:demo:test, 23 tests, 0 failures;:lucene:facet:check -x test(google-java-format, ecj lint, forbidden APIs) passes. - Standalone runner with the fix shadowed: the finder's and the other checkers' tests 24 of 24, assertions on and off (18 fail on stock, assertions on); the finder's exhaustive check drops from 1,290 to 0 mismatches over 4,525 indexes; the randomized differential check passes 20 of 20 runs (at least 300 random indexes each) with assertions on and off; on stock all 20 runs fail, each at its first or second index.
As suggested in #11286, the prefix path U+001F marks a path's children: DimTree.iterator(pathOrd) could find the first child with one lookupTerm instead of assuming the next ord.
Trade-offs
No extra memory, but term lookups per call; the dimension-split handling of the first option is still needed. Not run.
Like the first option, but DimTree always keeps int[] firstChild.
Trade-offs
Simpler; +4 bytes per ord of every hierarchical dimension, the memory the #509 review chose to save. Not run.
Throw for U+0000-U+001F and change the escape scheme so no escaped byte sorts below the delimiter.
Trade-offs
Not recommended: rejects inputs accepted today and supported by taxonomy facets, changes the term encoding while existing indexes stay wrong, and undoes the escaping of LUCENE-5339. A narrower variant, rejecting only raw C0 controls (not the escaped U+001E/U+001F) from now on, is a defensible compatibility choice for raw TAB/CR/LF, but leaves labels containing U+001E/U+001F and existing indexes wrong.
Say that SSDV labels must not continue a sibling label with a character below U+001F.
Trade-offs
Not recommended: leaves silent wrong results for inputs the API accepts and that FacetsConfig itself produces when escaping.
Products that index user-supplied or imported category paths into hierarchical SortedSetDocValues facets can lose a category's sub-categories through one stray label; rejecting or replacing control characters anywhere in labels (trimming only the ends is not enough), or using taxonomy facets, avoids it until a fix ships.
An AI finder reading code that consumes global ordinals noticed the comment "next ord must be a direct child of current ord" and confirmed the hypothesis on the stock jar. Over 4,525 small indexes, an exhaustive check then found it wrong exactly when a sibling's encoded label continues a label with children by a byte below 0x1F.
The method in full208 words
Method: code reading, then bounded-exhaustive checking (the hunt's "non-formal" tier), a hunt unit (OrdinalMap and its global-ordinal consumers), 2026-10-26.
- While reading the consumers of
OrdinalMap's global ords, the finder read "next ord must be a direct child of current ord, this is because we are indexing all ancestral paths" (DefaultSortedSetDocValuesReaderState.java:162-163) and asked what sorts between a path and its children. A probe on the stock jar confirmed it. - A bounded-exhaustive check of the real jar against brute force (one hierarchical dimension, labels
a,a<TAB>,a U+001F,a b,b; every set of 1-3 distinct paths of depth 1-2; 4,525 indexes; every indexed path and the root checked withgetAllChildren) found 1,290 mismatching sets: within that universe exactly those with sibling componentspandqwhose encoded forms continue each other with a byte below 0x1F (a TAB, or the U+001E thatFacetsConfigwrites in front of a U+001F) wherephas a child, and no others, with assertions on and off. It is an exhaustive check of that small universe, not a proof for every label or depth. - The finder reduced it to a 6-test public-API JUnit; then independent AI tools reproduced, reviewed and judged it (see the checks).
No prior report found (best-effort search, 2026-10-26, re-checked 2026-10-27): GitHub issues, PRs and commits, all 411 open PRs, four mailing lists, JIRA, downstream projects and the web. Nearest: LUCENE-10250 and LUCENE-9952, the features that introduced the code.
Searches4 searches
None of the issues, PRs, review comments, JIRA tickets, list threads, downstream issues or web pages these searches found describes SSDV faceting misplacing children or dropping dimensions when a label or dimension name continues with a character below U+001F. No upstream commit has touched lucene/facet/.../sortedset/ since May 2026, and no open PR changes the state construction.
Nearest items, none of them this bug: LUCENE-10250 (#11286, PR #509), the introducing work, whose discussion states the sorted-order premise without the caveat; LUCENE-9952 (#10991, PRs #611 and #621), the bare dimension term the flat variant needs; LUCENE-4795 (#5860) and LUCENE-5339 (#6403), which show labels are meant to be able to contain the delimiter; open draft PR #16847 (long global doc ids), which changes DefaultSortedSetDocValuesReaderState only in getDocValues() (Math.toIntExact casts); open PR #12862 (Facets#getBulkSpecificValues, touches AbstractSortedSetDocValueFacetCounts) and draft #11780 (reader states after refresh) touch nearby facet files but not the state construction. Gaps: GitHub's search rate limit was reached (GraphQL searches covered the skipped queries), PR review comments may not be search-indexed (the #509 and #611 threads were read in full), and private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene and all of GitHub) | 2026-10-26; re-checked 2026-10-27 | a scripted prior-report search (20 issue and PR queries, 3 commit queries), 72 GraphQL searches on apache/lucene (class names, symptoms, trigger characters, JIRA keys), upstream commits by path; 2026-10-27: 4 issue searches, an open-PR search and the commit list of the sortedset package | no report; the introducing work and related items listed above |
| Open PRs | 2026-10-26 | the changed files of all 411 open apache/lucene PRs | 17 touch lucene/facet; only draft #16847 touches the state class, in getDocValues() only; #12862 touches AbstractSortedSetDocValueFacetCounts (status re-read 2026-10-27) |
| Mailing lists and JIRA | 2026-10-26 | 76 tool queries over dev@, java-user@, issues@ and commits@; 10 JIRA-archive queries | design threads only; no report |
| Downstream repositories and web | 2026-10-26 | 2 downstream tool queries and 15 GraphQL searches (Elasticsearch, OpenSearch, Solr, nrtsearch, Jackrabbit Oak, global); 7 web queries | no report |
Introduced in 9.1.0 by LUCENE-10250 (#509, hierarchical SSDV facets, 2022); the flat-dimension variant also needs LUCENE-9952 (#611). Executed: all 32 releases from 9.1.0 to 10.5.2 and main are wrong; 9.0.0 and 8.11.4 are correct. Not fixed upstream.
Versions tested5 rows
Introduced by LUCENE-10250 "Add support for arbitrary length hierarchical SSDV facets" (PR #509, by @mdmarshmallow, merged by @gsmiller): b4e27f2c638d on main and the branch_9x backport c7650cdec2cb, both 2022-01-10. It indexed every ancestor path and derived the tree from adjacent ords; the review endorsed the first-child = next-ord rule as a memory saving. The flat multi-valued + requireDimCount variant also needs LUCENE-9952 (PR #611, 9e560c1af19e; branch_9x #621, 225fd1527c8f; 2022-01-24), which indexes the bare dimension term and treats ordRange.start() as that term. Before 9.1.0 every SSDV term was dim/label and each dimension's terms were contiguous, so the order assumption (from LUCENE-4795, 2013) held. Commit-level attribution comes from git blame, the diffs and the review; execution is at release granularity.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test: 4 of 6 fail (gradle and the standalone runner, assertions on and off); probe: shoes null, shoes<TAB> reports red (1) |
| 10.5.2, 9.12.3, 9.3.0 | affected | this doc's test: 4 of 6 fail with the same messages (assertions on); probe on 10.5.2 (assertions on): the same output |
| 9.1.0 ... 10.5.2 (32 releases) | affected | history sweep: the finder's test fails 4 of 6 from 9.3.0, its legacy variant 4 of 4 on 9.1.0 and 9.2.0; the version-portable flat probe is wrong on every release; assertions off also on 9.1.0, 9.12.3, 10.0.0 and 10.5.2 |
| 9.0.0, 8.11.4 | not affected | the version-portable flat probe is correct; hierarchical SSDV facets do not exist before 9.1.0 |
| main + the fix | not affected | the test passes 6 of 6; the whole facet suite, the nightly SSDV tests, the exhaustive check (0 of 4,525) and the differential check pass |
An independent reproducer, a root-cause review by another model family, a devil's advocate and an adjudication found it real (adjudication: confirmed, high); the repro was re-run after every review. Registry re-runs and this doc's gradle runs reproduced it on main a9779ef3c193 and validated the fix.
Checks and verdicts495 words
A separate run re-ran the repro for each review. The reproducer, the devil's advocate, the adjudication and this doc's validation wrote or ran their own tests on the stock jars with assertions on and off.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive check: 1,290 of 4,525 sets wrong, exactly the predicted ones; the 6-test JUnit fails 4 of 6 on main (-ea, -da), 10.5.2 and 9.12.3. |
| cross-model review, refute lens | not real (low, procedural) | OpenAI GPT-5.6, read-only: "not real" only because it could not create or run a test; it agreed with the root cause, found the inputs within the contract and the intended argument weak. A separate run re-ran the repro: 4 of 6 fail. |
| cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, read-only: the intended-behaviour argument is weak; root cause agreed. |
| Independent reproducer | real | Own 8-test class from the claim only, with LF, CR, TAB and U+001E and both count classes: 6 of 8 fail on main (-ea, -da), 10.5.2, 9.12.3 and 9.1.0 (on 9.1.0 one of the 6 is an API limit of that release, not this bug); controls with ! pass. |
| Cross-model review, root-cause lens | real (medium) | OpenAI GPT-5.6, read-only: the first wrong step is the equal-depth adjacency decision; the dimension split is a second mechanism from the same premise. A separate getTopDims probe shows the null entry (-da) and the AssertionError (-ea). |
| Devil's advocate | real (high) | Rejected the sorted-order design premise, the 2013 delimiter stance, the unclean-data and experimental-API arguments; its 3-segment probe with New York<CR> and <LF> fails on main and 10.5.2. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test (6 of 8 fail) and the finder's (4 of 6) with a new seed; set the procedural "not real" aside. |
| security assessment | none (strict rule) | The strict security re-evaluation of 2026-10-27 found it out of scope of SECURITY.md: wrong facet structure only, no documented untrusted-input guarantee for labels; file publicly. Its cross-document probe: documents outside the query or deleted but unmerged also trigger it. |
| registry re-runs and audit | still reproduces | On main a9779ef3c193: the finder's test 4 of 6 and the independent reproduction's 6 of 8 fail, same messages; a credibility audit kept the bug with its own two-segment LF probe. |
| this doc's validation | reproduced, fix validated | Gradle in a scratch worktree: 4 of 6 fail on stock, -ea and -da; with the fix the test, the whole facet suite, the nightly SSDV tests, lucene/demo and the static checks of check -x test pass, and the exhaustive and differential checks find no mismatch. |
| fact checks of this doc | corrections applied | An independent fact check (re-ran the test, the fix, the exhaustive and differential checks) and a cross-model fact check (OpenAI GPT-5.6, read-only) found no error in the bug or the fix; their wording, count and caveat corrections are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 418 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,439 words
- Registry title
- SortedSetDocValues faceting builds its facet tree from the byte order of the encoded paths, so a label or dimension name that equals a sibling's name followed by a character below U+001F (TAB, CR, LF, or the U+001E that FacetsConfig writes when it escapes U+001E/U+001F) moves a label's children under that sibling, or drops a whole dimension or one of its labels
- Area
- facet / SortedSetDocValues faceting (DefaultSortedSetDocValuesReaderState: the per-dimension DimTree and OrdRange built from the field's ordinals in term order, shared by SortedSetDocValuesFacetCounts and ConcurrentSortedSetDocValuesFacetCounts)
- Priority
- Low, rank 330: Needs a label that equals a sibling label plus a C0 control character in a hierarchical SortedSetDocValues facet field, uncommon dirty data.
- Impact class
- silent wrong results
- Impact note
- Applications that use SortedSetDocValues faceting with a hierarchical dimension (FacetsConfig.setHierarchical), or with a flat dimension that is multiValued and requireDimCount, get wrong facet navigation with no exception once the field holds a label that equals a sibling label followed by a character U+0000..U+001E while the shorter label has children (or a dimension name built the same way): getTopChildren/getAllChildren of the real parent return null or no children while the sibling reports the subtree (so a parent count can be smaller than the sum of its children), a whole dimension can vanish from getTopChildren and getAllDims (getTopDims then returns a null entry with -da, or throws AssertionError with -ea), and a flat requireDimCount dimension loses one label and reports that label's count as the dimension count; default codec, IndexWriterConfig and searcher, any scale (2-3 documents), and the damage is index-wide because the tree is built from every term in the reader, including documents outside the query and deleted documents until a merge drops them; getSpecificValue, drill-down queries, search hits and taxonomy faceting stay correct.
- Summary
- You index hierarchical SortedSetDocValues facets, for example cat/shoes/red in one document and cat/'shoes<TAB>' (an untrimmed input) in another, and expect getTopChildren(10, 'cat', 'shoes') to return red=1, as taxonomy faceting does for the same labels. Instead it returns null and the leaf 'shoes<TAB>' reports red=1: the encoded paths sort by byte, a character below the path delimiter U+001F places 'shoes<TAB>' between 'shoes' and 'shoes U+001F red', and the reader state infers parent, child and sibling links only from the order of consecutive ordinals. The same happens for a label that contains U+001F or U+001E (FacetsConfig escapes both with U+001E), and dimension names such as 'd' next to 'd<TAB>' make dimension d disappear or, for a flat multiValued + requireDimCount dimension, lose one label, all with no error.
- Introduced
- b4e27f2c638d31473c48503d0def2259b5d5a408 (main, 2022-01-10; LUCENE-10250 / PR #509 'Add support for arbitrary length hierarchical SSDV facets', by GitHub mdmarshmallow, merged by gsmiller), shipped through the branch_9x backport c7650cdec2cb4ed6b31c536a8eb2818c868dc42b; the flat multiValued + requireDimCount variant also needs 9e560c1af19e3d785af52ebb6bdc12b8c75ed125 (LUCENE-9952 / PR #611; branch_9x backport 225fd1527c8f78a1837538ea0dcbe3644166ef13, PR #621), which indexes the bare dimension term and treats ordRange.start() as the dimension ordinal [read: git blame of DefaultSortedSetDocValuesReaderState.java 101-188 and SortedSetDocValuesReaderState.java 105-131, the diffs and the PR #509 review; exec only at release granularity: the same probe is correct on 9.0.0 and wrong on 9.1.0, and the 2022 snapshots between them were not built, so execution cannot separate the two changes] (2022-01-10 (b4e27f2c638 on main and the branch_9x backport c7650cdec2c, same day); flat variant 2022-01-24 (9e560c1af19 / 225fd1527c8))
- First affected version
- 9.1.0 [exec] (tagged 2022-03-16; both changes are in its CHANGES.txt); last unaffected 9.0.0 [exec: the version-portable flat probe is correct there, and the hierarchical SSDV API does not exist yet]
- Affected versions
- All 32 releases from 9.1.0 to 10.5.2 (the last release before 10.6.0) and main ea57360912ed. [exec] the finder's JUnit (repro/src) fails 4 of 6 on every release from 9.3.0 to 10.5.2 and on main; its legacy variant (repro/src-legacy, no getAllChildren) fails 4 of 4 on 9.1.0 and 9.2.0; the version-portable flat probe is wrong on every release from 9.1.0 on and correct on 8.11.4 and 9.0.0; -da gives the same results on 9.1.0, 9.12.3, 10.0.0, 10.5.2 and main (82 history runs). The independent reproduction's JUnit fails 6 of 8 on main (-ea and -da), 10.5.2, 9.12.3 and 9.1.0 (on 9.1.0 one of the 6 is an API limit of that release, not this bug); the intended-behaviour check's probe fails on main and 10.5.2; the security probe fails 5 of 7 as expected on main and 10.5.2. Unaffected: 9.0.0 and earlier, where every SSDV term was dim/label and each dimension's terms were contiguous (executed on 8.11.4 and 9.0.0; older releases [read]). Not fixed upstream: upstream main e1c4184cb983 (2026-10-26) keeps the adjacency logic (last change to DefaultSortedSetDocValuesReaderState.java is the cosmetic #15842) and branch_10x last changed the file in #12454 [read]. Not executed: x86 (pure Java logic), releases before 8.11.4.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (searched 2026-10-26 by the finder, and by the follow-up step, read-only; the prior-report record): the scripted prior-report search (GitHub run: 20 generated apache/lucene issue/PR queries, 3 commit and 2 downstream queries; lists and JIRA runs: 76 mailing-list queries over dev@, java-user@, issues@ and commits@ and 10 JIRA-archive queries), 87 GitHub GraphQL searches over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, Yelp/nrtsearch, apache/jackrabbit-oak and all of GitHub, a changed-file scan of all 411 open apache/lucene PRs, upstream commits by path on main and branch_10x, 7 web queries and the full local git history; the finder's, the independent reproduction's and the intended-behaviour check's own searches found nothing either. Not fixed upstream: upstream main e1c4184cb983 keeps the adjacency logic, and the only open PR that touches DefaultSortedSetDocValuesReaderState.java, #16847, adds Math.toIntExact casts in getDocValues(). Nearest items, none a report of this bug: LUCENE-10250 (#11286 / PR #509) and LUCENE-9952 (#10991 / PR #611, #621), the introducing work, whose discussions state the sorted-order premise without the caveat; LUCENE-4795 (#5860) and LUCENE-5339 (#6403), context showing that labels may contain the delimiter. Gaps: GitHub's search rate limit was reached (the tool ran 20 of its 40 generated issue queries; the skipped generic ones largely overlap the GraphQL searches), PR review comments may not be search-indexed (the #509 and #611 review threads were read in full through the API), and 'not found' is a search result, not proof.
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26; tested 2026-10-27) through gradle in a scratch worktree and through the standalone JUnit runner, with assertions on and off; the 10.5.2, 9.12.3 and 9.3.0 release jars with assertions on (this doc's test). The hunt's history sweep ran a version-portable probe on all 32 releases from 9.1.0 to 10.5.2 and on 9.0.0 and 8.11.4. The hunt, the reviews and the adjudication ran on mainea57360912ed, whose facet module is identical. The fix was validated in the scratch worktree: the new test, the wholelucene/facetsuite (40 suites, 312 tests) with assertions on and off, the nightlyTestSortedSetDocValuesFacets,lucene/demo,:lucene:facet:check -x test, and with the standalone runner the other checkers' tests, the finder's exhaustive check and a randomized differential check.
- Finding record
lucene/facet/src/java/org/apache/lucene/facet/sortedset/DefaultSortedSetDocValuesReaderState.java :101-111 (constructor loop: a new dimension state whenever components[0] changes), :115-188 (createOneHierarchicalFacetDimState; 'next ord must be a direct child' :162-163, 'must be a sibling' :170-171, dimension run ends :154, prefixToDimTree.put :185), :191-237 (createOneFlatFacetDimState; run ends :219, prefixToOrdRange.put :234)lucene/facet/src/java/org/apache/lucene/facet/sortedset/SortedSetDocValuesReaderState.java :109-131 (DimTree.iterator: the first child of pathOrd is pathOrd + 1, :122-124); AbstractSortedSetDocValueFacetCounts.java :274-281 (requireDimCount: ordRange.start() skipped as the dimension ordinal, :280), :230 (assert facetResult != null in getTopDims)lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java :550 (DELIM_CHAR U+001F), :553 (ESCAPE_CHAR U+001E), :569-593 (pathToString escapes U+001E/U+001F with U+001E, :582-584); FacetField.java :69-72 (verifyLabel rejects only null or empty); Facets.java :33-43 (children under the specified path)
- The finding in 30 seconds
lucene/facet/src/java/org/apache/lucene/facet/sortedset/DefaultSortedSetDocValuesReaderState.java:101-111, :115-188 (:154-159 run end, :161-168 child, :169-174 sibling, :185 put), :234lucene/facet/src/java/org/apache/lucene/facet/sortedset/SortedSetDocValuesReaderState.java:109-131 (:122-124 first child = next ord)lucene/facet/src/java/org/apache/lucene/facet/sortedset/AbstractSortedSetDocValueFacetCounts.java:169-170, :228-232, :274-281lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:474-481, :491-497, :550-553, :569-593
- Why it looks unintended
lucene/facet/src/java/org/apache/lucene/facet/Facets.java:25, :32-44, :59-69lucene/facet/src/java/org/apache/lucene/facet/sortedset/AbstractSortedSetDocValueFacetCounts.java:122-125lucene/facet/src/java/org/apache/lucene/facet/FacetField.java:64-73; lucene/facet/src/java/org/apache/lucene/facet/sortedset/SortedSetDocValuesFacetField.java:48-59lucene/facet/src/java/org/apache/lucene/facet/FacetsConfig.java:552, :582-583lucene/facet/src/test/org/apache/lucene/facet/taxonomy/TestTaxonomyFacetCounts.java:422 (testLabelWithDelimiter)lucene/facet/src/test/org/apache/lucene/facet/FacetTestCase.java:110-117; lucene/test-framework/src/java/org/apache/lucene/tests/util/TestUtil.java:1146, :1206-1212
- TestSsdvFacetChildrenMovedToTabSibling.java (JUnit test):
repro/LFV-324/src/org/apache/lucene/facet/sortedset/TestSsdvFacetChildrenMovedToTabSibling.java(54 lines)
A light diagram of the repro, made in parallel with this doc from the executed probe output and the code.
assets/LFV-324/bug.png(418 KB)