FeatureField and any TokenStream that sets TermFrequencyAttribute tell Lucene how often a term occurs instead of repeating it. IndexWriter keeps that number. MemoryIndex, the one-document in-memory index, ignores it and counts each token once.
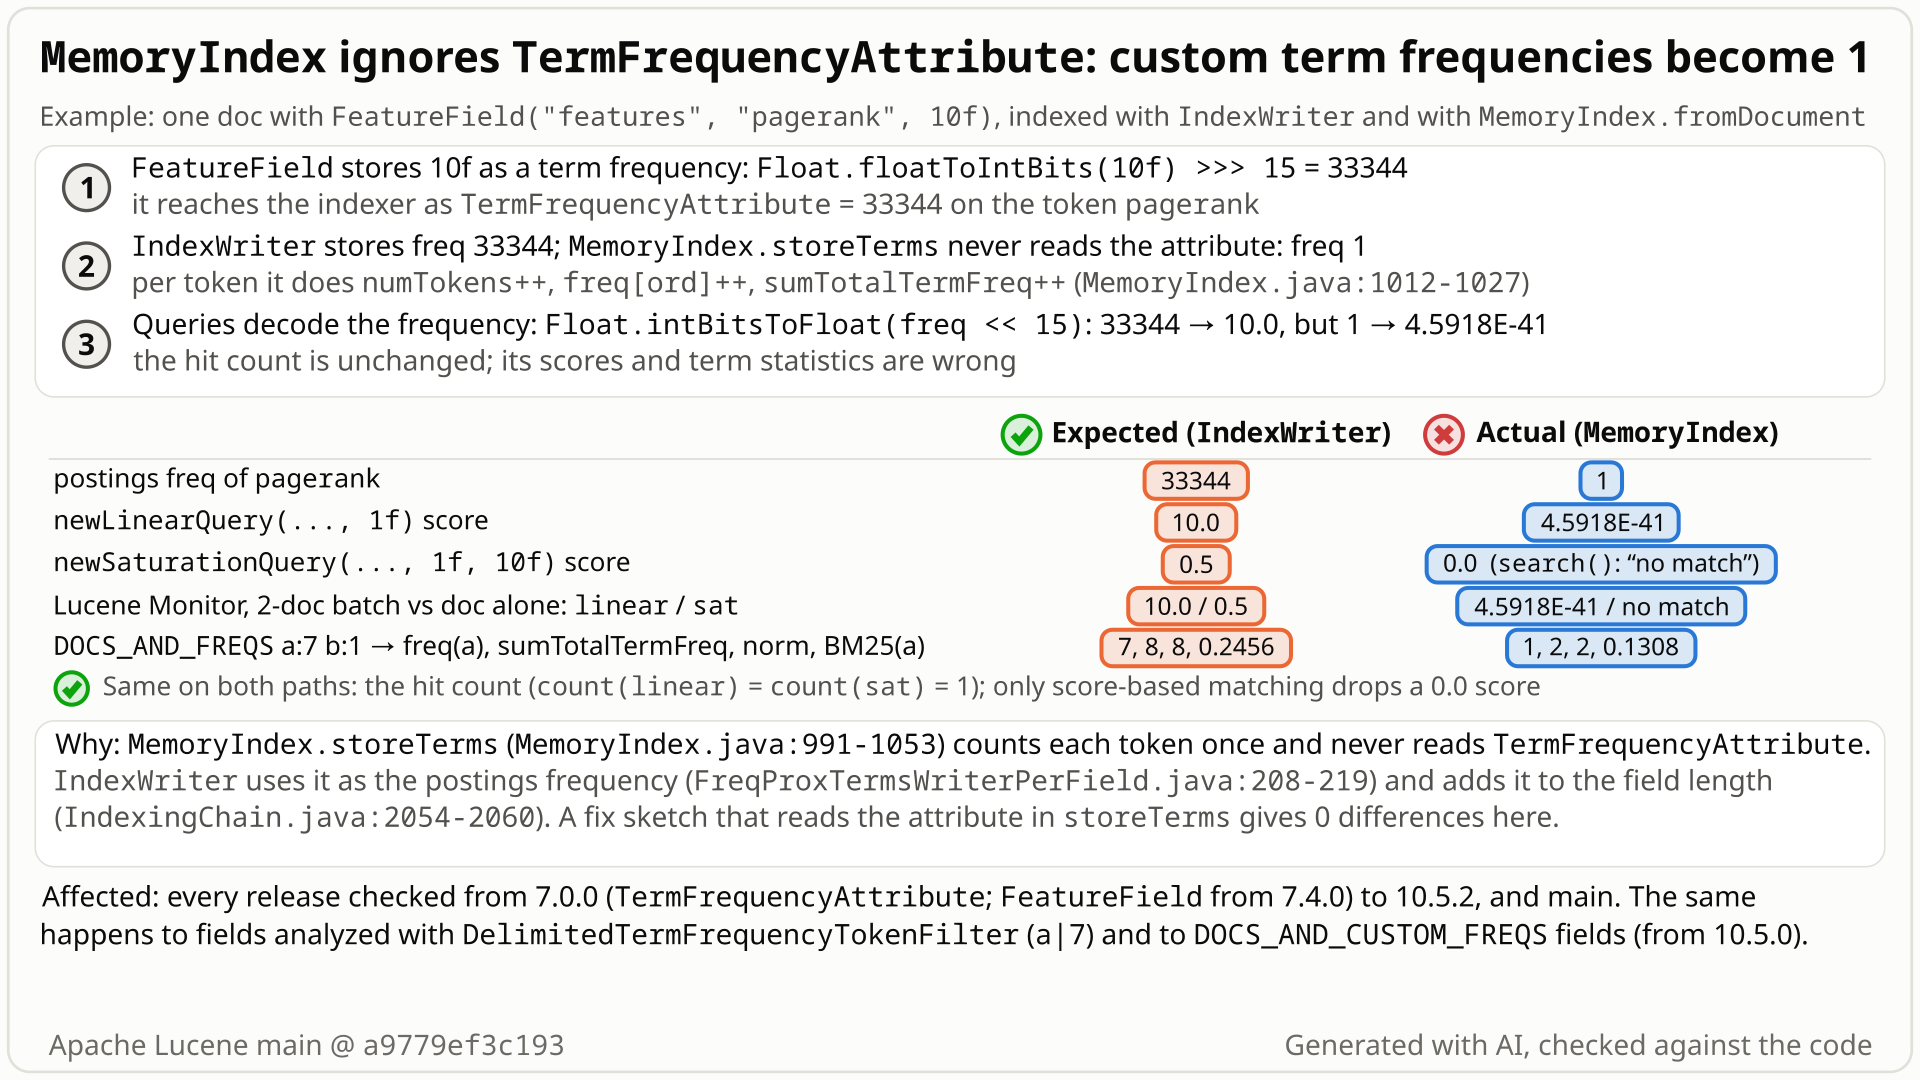
FeatureField value, 10f, stored as the frequency 33344: IndexWriter keeps it and scores 10.0 and 0.5, MemoryIndex counts the token once, so the frequency 1 decodes to 4.5918E-41 and the saturation score is 0.0, and Monitor scores the document differently alone than in a batch. Select the still to open it at full size. Generated with AI, checked against the code.- You put one document with
FeatureField("features", "pagerank", 10f)into a one-documentIndexWriterindex and intoMemoryIndex.fromDocument.FeatureFieldstores the value as a term frequency: 10f becomes 33344. - You search
FeatureField.newLinearQuery("features", "pagerank", 1f)and expect the score 10.0 from both, as for ordinary fields.IndexWritergives 10.0. MemoryIndexnever reads the frequency attribute and counts the token once. Frequency 1 decodes to 4.5918E-41, so the score is 4.5918E-41. WithnewSaturationQuery(pivot 10) it is exactly 0.0 instead of 0.5, whichMemoryIndex.searchdocuments as "no match", whilecount()says the document matches.- Custom frequencies on text fields shrink the same way: a
DOCS_AND_FREQStermawith frequency 7 gets freq 1,sumTotalTermFreq2 instead of 8, norm 2 instead of 8, and BM25 0.1308 instead of 0.2456. - Lucene Monitor (since 8.6.0) matches one document on a
MemoryIndexand two or more on anIndexWriterreader: the same document scores 10.0 in a batch of two and 4.5918E-41 alone, and a saturation query with the pivot 10 is not reported for it at all.
Code that scores FeatureField queries or reads term statistics of custom-frequency fields on a MemoryIndex: Lucene Monitor with ScoringMatch matching single documents (since 8.6.0), callers of MemoryIndex.search (whose documented match test is score > 0), and DelimitedTermFrequencyTokenFilter or DOCS_AND_CUSTOM_FREQS fields. Default settings, opt-in custom frequencies, every time; for the tested queries the matching documents stay the same.
Mechanism, terms and numbers759 words
FeatureField stores its value as a term frequency, and any TokenStream can set a custom frequency through TermFrequencyAttribute (for example DelimitedTermFrequencyTokenFilter on a|7, or a DOCS_AND_CUSTOM_FREQS field since 10.5.0). For DOCS_AND_FREQS and DOCS_AND_CUSTOM_FREQS fields IndexWriter indexes that frequency; MemoryIndex.storeTerms never reads the attribute and adds 1 per token to the postings frequency, sumTotalTermFreq and the field length. A document put into a MemoryIndex (fromDocument, addField(IndexableField, Analyzer), or Lucene Monitor matching one document) therefore counts each such token as frequency 1: FeatureField("features", "pagerank", 10f) is frequency 33344 in an IndexWriter index and 1 in a MemoryIndex, which decodes to 4.5918E-41. FeatureField.newLinearQuery scores 4.5918E-41 instead of 10.0, and newSaturationQuery with the pivot 10 scores exactly 0.0 instead of 0.5 although the document matches; 0.0 is what MemoryIndex.search documents as "no match". Since 8.6.0, Monitor scores the same document 10.0 in a two-document batch and 4.5918E-41 alone, and drops a stored saturation query with the pivot 10 for the single document. For the tested queries the set of matching documents (IndexSearcher.count) is unchanged; only score-based match tests lose the match. Every release checked from 7.0.0 to 10.6.0 (10.6.0 by reading) is affected; the validated fix reads the attribute where IndexWriter honours it and rejects overflow as IndexWriter does.
TermFrequencyAttribute: a token attribute that "Sets the custom term frequency of a term within one document"; the field must be indexed withDOCS_AND_FREQS(TermFrequencyAttribute.java:24-26on maina9779ef3c193).DelimitedTermFrequencyTokenFiltersets it from text likea|7; since 10.5.0 aDOCS_AND_CUSTOM_FREQSfield treats it as a per-term score, adding 1 per term to the field length.FeatureField: a rank-feature field (pagerank, learned-sparse term weights). "Feature values are internally encoded as term frequencies" (FeatureField.java:47): the value becomesFloat.floatToIntBits(value) >>> 15(:185-186; 10f gives 33344), set through the attribute (:222) on aDOCS_AND_FREQSfield (:114). Its queries decode the frequency back withFloat.intBitsToFloat(freq << 15)(:240-249).MemoryIndex: a single-document index held in memory, "a replacement/substitute for RAM-resident Directory implementations" (MemoryIndex.java:106). Lucene Monitor uses one for a one-document batch and anIndexWriter-built reader for larger batches (DocumentBatch.java:44-62, 105-113).
IndexWriteruses the attribute, forDOCS_AND_FREQSandDOCS_AND_CUSTOM_FREQSfields.FreqProxTermsWriterPerField.getTermFreq(FreqProxTermsWriterPerField.java:208-219) takes it as the postings frequency, andIndexingChainadds it to the field length (1 per term forDOCS_AND_CUSTOM_FREQS) withMath.addExact(IndexingChain.java:2053-2064). ADOCSfield keeps no frequencies (distinct terms read as 1 on both paths), and a positional field throws "cannot index positions while using custom TermFrequencyAttribute" (:210-216).MemoryIndexdoes not.storeTerms(MemoryIndex.java:991-1053) asks the stream only for the term, position-increment, offset and payload attributes (:1002-1007) and per token doesinfo.numTokens++(:1012),info.sliceArray.freq[ord]++(:1025) andinfo.sumTotalTermFreq++(:1027). The norm is computed fromnumTokens(:1380-1393).TermFrequencyAttributeappears nowhere in the file.- Frequency 1 decodes to almost nothing.
Float.intBitsToFloat(1 << 15)is 4.5918E-41, a subnormal float below the smallest valueFeatureFieldaccepts (Float.MIN_NORMAL,FeatureField.java:162-171). The linear function returns it. The other functions depend on their parameters (executed): saturationweight * (1 - pivot / (f + pivot))(:450) with the pivot 10 rounds10f / (10f + 4.5918E-41f)to 1.0 and returns exactly 0.0, and so does sigmoid with the pivot 10 (:531); log withscalingFactor1 (:356) is always 0.0, because1f + 4.5918E-41fis1f. Saturation without a pivot takes the pivot from the index statistics (:408-415,:725-738), which on a one-documentMemoryIndexdecode to the same 4.5918E-41, so it scores 0.5 as onIndexWriter; tiny explicit pivots give positive but wrong scores. - 0.0 is "no match".
MemoryIndex.searchreturns "0.0 indicating no match" (MemoryIndex.java:1105-1106; the class example testsscore > 0.0f,:153-157), and Monitor'sScoringMatchreports a match only whenscore > 0(ScoringMatch.java:37). That convention was already imperfect: a FILTER-only query and a boost-0 query match but score 0.0 on both paths (executed); this bug adds matching documents that score 0.0 only because their frequency was dropped. - The hit set is unchanged for the tested queries. Every term is still indexed for the document. The follow-up's probe ran 12 query shapes (five
FeatureFieldfunction settings, two term queries, FILTER and two MUST_NOT combinations, two zero-score controls):IndexSearcher.countwas the same on both paths for all 12 (executed). A query that itself depends on frequencies could still differ; none was tested.
Exposure and likelihood232 words
- Monitor. With
ScoringMatchandFeatureFieldqueries, a single document scores differently from the same document in a batch (10.0 vs 4.5918E-41), and a stored query whose only scoring parts round to 0.0 (saturation or sigmoid with an explicit pivot such as 10, log withscalingFactor1) is not reported at all for a single document (executed: saturation on main and 10.5.2; sigmoid and log in the fact checks' Monitor runs on main). The no-pivot saturation query keeps its match (0.5 on both paths). Monitor matches a single document onMemoryIndexonly since 8.6.0 (LUCENE-9314): in 8.2.0 to 8.5.2match(Document)went through theIndexWriter-based batch (read). - Direct
MemoryIndex.search. Its javadoc makesscore > 0.0fthe match test; the same query shapes report "no match" for a matching document (executed). - Custom-frequency text fields. Postings frequency,
totalTermFreq,sumTotalTermFreq, the norm and BM25 scores are wrong forDOCS_AND_FREQSfields fed byDelimitedTermFrequencyTokenFilteror a custom stream, and forDOCS_AND_CUSTOM_FREQSfields (10.5.0+) (executed). - Default vs opt-in. Default
MemoryIndex, Monitor and similarity settings; the trigger is the opt-in custom-frequency feature. - Scale. Any document, deterministic, every time.
- Silent. No exception, and for the tested queries no change in which documents match, so only code that reads frequencies, term statistics, norms or scores notices (including score-based match tests); no report was found in the nine years since 7.0.0, so the registry rates the likelihood "rare".
The test shows that MemoryIndex ignores TermFrequencyAttribute, so a FeatureField("f", "pr", 10f) is indexed with frequency 1 and FeatureField.newLinearQuery("f", "pr", 1f) scores it wrongly.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.index.memory;

import org.apache.lucene.document.FeatureField;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMemoryIndexFeatureField extends LuceneTestCase {

  public void testLinearQueryScoresFeatureValue() {
    MemoryIndex mi = new MemoryIndex();
    mi.addField(new FeatureField("f", "pr", 10f), null);
    // expected: the feature value 10.0 (as with IndexWriter); actual: 4.5918E-41 (frequency 1)
    assertEquals(10f, mi.search(FeatureField.newLinearQuery("f", "pr", 1f)), 0f);
  }
}
# in a copy of this finding's repro folder (repro/LFV-333/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.index.memory.TestMemoryIndexFeatureField
- Expected vs actual
- Expected:
mi.search(...)returns the feature value10.0(as a one-document IndexWriter index does). Actual:4.5918E-41.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<10.0> but was:<4.5918E-41>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:577)
       org.junit.Assert.assertEquals(Assert.java:701)
org.apache.lucene.index.memory.TestMemoryIndexFeatureField.testLinearQueryScoresFeatureValue(TestMemoryIndexFeatureField.java:28)TermFrequencyAttributesets "the custom term frequency of a term within one document";FeatureFieldvalues "are internally encoded as term frequencies".MemoryIndexaccepts both and drops the number.MemoryIndexis a documented "substitute" for an index; its duel test checks norms, hit counts and term-vector frequencies againstIndexWriter.- No limitation is documented; ignoring
omitNormswas fixed as a bug (LUCENE-7679).
The full argument361 words
- The attribute's contract.
TermFrequencyAttribute.java:24-26: "Sets the custom term frequency of a term within one document. If this attribute is present in your analysis chain for a given field, that field must be indexed with IndexOptions#DOCS_AND_FREQS."FeatureFieldand theDOCS_AND_FREQSrepro field meet that precondition word for word.DOCS_AND_CUSTOM_FREQS(10.5.0) is newer than that sentence and not named in it;IndexOptions.java:53-54calls it "Like DOCS_AND_FREQS except the "custom freqs" are treated as scores", andIndexWriterhonours the attribute for it, so it is a parity case.DelimitedTermFrequencyTokenFilterstates the same precondition: "DOCS_AND_FREQS but no positions or offsets" (DelimitedTermFrequencyTokenFilter.java:31-32). FeatureField's contract.FeatureField.java:47: "Feature values are internally encoded as term frequencies." Its query functions read the value back from the frequency.MemoryIndex's role.MemoryIndex.java:106: "a replacement/substitute for RAM-resident Directory implementations";:129: "Arbitrary Lucene queries can be run against this class". Monitor swaps it in for a one-documentIndexWriterindex only for speed (DocumentBatch.java:101-102: "MemoryIndex benchmarks as better performing than RAMDirectory for this case"), since 8.6.0, when LUCENE-9314 fixed "Single-document monitor runs were using the less efficient MultiDocumentBatch implementation" (CHANGES.txt:5804-5805).- Tests.
TestMemoryIndexAgainstDirectoryduelsMemoryIndexagainst anIndexWriterindex: equal norms (:200-207), equal hit counts (:259-268), and intestDuelMemoryIndexCoreDirectoryWithArrayFieldequal term-vector frequencies, positions and offsets (:714-800). Its postings andsumTotalTermFreqchecks (:210-250) compare theMemoryIndexreader with its own term vectors, not withIndexWriter(:193-196). Its analyzers never set the attribute. No test inlucene/memoryorlucene/monitorusesTermFrequencyAttributeorFeatureField, and none asserts frequency 1. - History. LUCENE-7854 (
d276acfbbcb8, 2017) added the attribute in 14 files, none inlucene/memory; #15584 (DOCS_AND_CUSTOM_FREQS, 10.5.0) changed oneMemoryIndexline without adding support. Neither discussion mentionsMemoryIndexor Monitor. - Precedents. LUCENE-7679 / #8730 (
type:bug, Bug Fixes in 6.5.0,CHANGES.txt:8442-8443): "MemoryIndex was ignoring omitNorms settings on passed-in IndexableFields", which also made its scores differ fromIndexWriter's. LUCENE-8756 / #9801 (type:bug): "MLT queries ignore custom term frequencies", the same omission in MoreLikeThis; 8.1.0's CHANGES lists the fix under "Changes in Runtime Behavior" (CHANGES.txt:6564, entry:6578-6579).
The devil's-advocate check200 words
The strongest works-as-designed case, built by the verifiers and a reading-only review by a model from another family (rated "moderate"): MemoryIndex does not mirror index options. createFieldInfo always declares DOCS_AND_FREQS_AND_POSITIONS[_AND_OFFSETS] (MemoryIndex.java:759-763), TestMemoryIndex.testKeywordWithoutTokenStream (:1093) accepts occurrence counts with positions for DOCS-only keyword fields, and IndexWriter rejects custom frequencies together with positions ("cannot index positions while using custom TermFrequencyAttribute", FreqProxTermsWriterPerField.java:208-219). The attribute's javadoc names only DOCS_AND_FREQS, and Monitor's use of MemoryIndex is a speed optimization, not a stated promise of full equivalence. So custom frequencies may never have been part of MemoryIndex's model.
Why it fails: MemoryIndex accepts these stock fields without complaint and then returns wrong scores, including a documented "no match" for a matching document. The caller met the attribute's precondition; it is MemoryIndex that overrides the index options. Nothing in javadoc, CHANGES, MIGRATE or tests documents a limitation (compare GITHUB#15334, whose CHANGES entry says "MemoryIndex does not support nearest neighbor search"). Honouring the frequency or rejecting the field would both remove the silent wrong score. The argument does hold for addField(String, TokenStream), which always indexes positions (it uses defaultFieldType, MemoryIndex.java:476-479, :728; its javadoc does not say so).
Recommended Honour the frequency where IndexWriter does, reject overflow as IndexWriter does
In MemoryIndex.storeTerms, read TermFrequencyAttribute on DOCS_AND_FREQS and DOCS_AND_CUSTOM_FREQS fields (where IndexWriter honours it), add it to the frequency, sumTotalTermFreq and field length, and reject int overflow with IndexWriter's "too many tokens for field" (+40/-8, one file). The repro passes with assertions on and off, and the whole memory, monitor and highlighter test suites pass (73 classes, 991 tests).
final boolean customFreqs =
    indexOptions == IndexOptions.DOCS_AND_FREQS || indexOptions == IndexOptions.DOCS_AND_CUSTOM_FREQS;
final boolean termDoc = indexOptions == IndexOptions.DOCS_AND_CUSTOM_FREQS;
TermFrequencyAttribute termFreqAtt =
    customFreqs ? stream.addAttribute(TermFrequencyAttribute.class) : null;
// per token:
final int termFreq = termFreqAtt == null ? 1 : termFreqAtt.getTermFrequency();
info.numTokens = addTokens(info, info.numTokens, termDoc ? 1 : termFreq); // was ++
info.sliceArray.freq[ord] = addTokens(info, info.sliceArray.freq[ord], termFreq); // was ++
info.sumTotalTermFreq += termFreq; // was ++
All options and trade-offs4 options · 906 words
One fix was applied in a scratch worktree at a9779ef3c193 and run through gradle (seed DEADBEEF); the other options were not run. The hunt's first sketch (no overflow check) is listed last because it must not be used as is.
Honour the frequency where IndexWriter does, reject overflow as IndexWriter does (validated by the checks) (recommended)
storeTerms gets the field type's IndexOptions. For DOCS_AND_FREQS and DOCS_AND_CUSTOM_FREQS it reads TermFrequencyAttribute and adds the frequency to the postings frequency, maxTermFrequency, sumTotalTermFreq and the field length (1 per term for DOCS_AND_CUSTOM_FREQS, as IndexingChain does). Positional field types, including every addField(String, ...) path and the highlighters' re-analysis, keep today's one-per-token counting. Int sums go through Math.addExact and throw IllegalArgumentException("too many tokens for field ...") like IndexingChain. MemoryPostingsEnum.nextPosition returns -1 once the stored positions run out (a frequency of 33344 has one stored position), which is what PostingsEnum returns when positions are not indexed. A second diff adds the repro tests plus testCustomFrequencyOverflowIsRejected.
final boolean customFreqs =
    indexOptions == IndexOptions.DOCS_AND_FREQS || indexOptions == IndexOptions.DOCS_AND_CUSTOM_FREQS;
final boolean termDoc = indexOptions == IndexOptions.DOCS_AND_CUSTOM_FREQS;
TermFrequencyAttribute termFreqAtt =
    customFreqs ? stream.addAttribute(TermFrequencyAttribute.class) : null;
// per token:
final int termFreq = termFreqAtt == null ? 1 : termFreqAtt.getTermFrequency();
info.numTokens = addTokens(info, info.numTokens, termDoc ? 1 : termFreq); // was ++
info.sliceArray.freq[ord] = addTokens(info, info.sliceArray.freq[ord], termFreq); // was ++
info.sumTotalTermFreq += termFreq; // was ++
Trade-offs
- The positional view stays inconsistent.
MemoryIndexstill declares positions (hasPositionstrue) while aFeatureFieldposting now has frequency 33344 and one stored position: later positions read as -1, term vectors report frequency 33344, andtoStringDebugprints "positions=33344" next to one real position (executed). -1 is whatPostingsEnumreturns when positions are not indexed, but this reader says they are, so a positional query on aFeatureFieldruns instead of throwing as on anIndexWriterindex. MakingcreateFieldInfofollow the field type would fix it, but changes whattestKeywordWithoutTokenStreamasserts. - Not validated for position consumers. No test runs a phrase, span or other positional query, or
CheckIndex, against a fixed custom-frequency field; apart from this doc's own tests the upstream memory and monitor suites have noFeatureFieldorTermFrequencyAttributecase. A PR should add such tests, or stop advertising positions for these fields. - Positional fields stay lenient. A
TextFieldanalysed withDelimitedTermFrequencyTokenFiltermakesIndexWriterthrow "cannot index positions while using custom TermFrequencyAttribute";MemoryIndexkeeps counting 1. Throwing there too could break highlighting of such fields, which re-analyses text into aMemoryIndexthroughaddField(String, TokenStream)(MemoryIndexOffsetStrategy.java:112,WeightedSpanTermExtractor.java:411-413). DOCSfields stay lenient. For a repeated term with a frequency other than 1,IndexWriterthrows "must index term freq while using custom TermFrequencyAttribute" (FreqProxTermsWriterPerField.java:147-152); the fix does not read the attribute forDOCS, soMemoryIndexaccepts it.- No duplicate-term check for
DOCS_AND_CUSTOM_FREQS.IndexWriterrejects the document with "Document update skipped due to duplicate termdoc term" (IndexingChain.java:2095-2097, caused by "has duplicate term" atFreqProxTermsWriterPerField.java:193-194);MemoryIndexadds the two frequencies (executed). The hunt's harness counted 432 such cases; a separate parity gap that can go in the same PR. - The overflow exception leaves the
MemoryIndexpartly updated, like any exception in the middle of aTokenStream(IndexWritermarks the document deleted). Not benchmarked: per token one attribute read and two checked additions.
What the checks validated
- Stock main
a9779ef3c193: the memory repro fails 4 of 5 and the Monitor test 2 of 2, with assertions on and off; the control passes. - With the fix: the 5 memory tests plus
testCustomFrequencyOverflowIsRejectedand the 2 Monitor tests pass, with assertions on and with assertions off. - With the fix, all of
lucene/memory,lucene/monitorandlucene/highlighterand core'sTestFeatureFieldandTestCustomTermFreqpass: 73 classes, 991 tests, 1 skipped, 0 failures. ecjLintandcheckGoogleJavaFormatpass for memory and monitor, andforbiddenApisfor memory, with the tests in place.- Through the classpath runner with the fixed
MemoryIndex.javashadowed, the finder's repro (3 of 3) and the independent reproducer's (7 of 7) pass; the follow-up's input of 50,000 tokens with frequencyInteger.MAX_VALUE, which made the field vanish under the hunt's first sketch, now throws "too many tokens for field".
Throw IllegalArgumentException when a token's frequency is not 1 ("MemoryIndex does not support custom term frequencies"). Not run.
Trade-offs
Small and removes the silent wrong score, but every document with a FeatureField that goes through a MemoryIndex (a single-document Monitor match, the percolator path) would start failing, even when no query reads the field; Monitor batches of two or more use IndexWriter and are not affected. Given MemoryIndex's always-positional design, maintainers may well prefer this option.
Say in the MemoryIndex class javadoc that custom term frequencies are counted as 1. (GITHUB#15334 stated its kNN limitation only in its CHANGES entry, CHANGES.txt:1476-1477; MemoryIndex.java has no such javadoc.) Not run.
Trade-offs
Makes the behaviour a documented limitation, but leaves the wrong scores and the "no match" for matching documents in place.
Reads the attribute for every field type and adds it with plain +=. It passes the repros and the 51 upstream memory tests.
Trade-offs
With 50,000 tokens of frequency Integer.MAX_VALUE the field length wraps and the field vanishes from the reader (MemoryIndex hides fields with numTokens <= 0, MemoryIndex.java:1834, 1842), executed; with the recommended fix the same input throws "too many tokens for field".
Downstream percolators that build a MemoryIndex from the document, such as Elasticsearch's and OpenSearch's with rank_feature (a FeatureField), score such queries wrong (by code reading); they decide matches by hit existence, so the matched queries do not change.
Bounded-exhaustive translation validation on the real jar: the same tiny document (every stream of up to two tokens with custom frequencies 1, 2 and 7, plus FeatureField with four values and four query functions, 1,836 cases) built once with IndexWriter and once with MemoryIndex, then compared through the public API. Every case with a frequency other than 1 differed.
The method in full162 words
Method: bounded-exhaustive translation validation on the stock jar (semi-formal tier), in a hunt unit on MemoryIndex equivalence.
- The harness builds each case twice, with a one-document
IndexWriterindex and withMemoryIndex, and compares the postings frequency,totalTermFreq,sumTotalTermFreq, the norm and query scores throughLeafReaderand the query API. Scope CF: one field,DOCS_AND_FREQSandDOCS_AND_CUSTOM_FREQS,omitNormson and off, every stream of at most two tokens over {a, b} with custom frequencies {1, 2, 7}, plusFeatureFieldwith 4 values and 4 query functions: 1,836 cases, 4,220 comparisons. - Mismatches in every class (for example 1,120
DOCS_AND_FREQSand 800DOCS_AND_CUSTOM_FREQSscore mismatches, and all 16FeatureFieldquery scores); 0 mismatches with the fix sketch shadowed. - Found 2026-10-26 on main
ea57360912ed; then turned into public-API JUnits and checked by an independent reproducer, an intended-behaviour devil's advocate, reading-only reviews by an independent reviewer from another model family (OpenAI GPT-5.6), an adjudication and a follow-up with history and prior-report searches.
No prior report found (2026-10-26) in 152 recorded queries over GitHub, the mailing lists, JIRA, Elasticsearch, OpenSearch, Solr and the web, plus the changed files of all 411 open PRs. Closest: LUCENE-8756 (MoreLikeThis ignored custom frequencies) and LUCENE-7679 (MemoryIndex ignored omitNorms).
Searches4 searches
Verdict new: no hit is a report of this bug by anyone. Keyword search cannot prove absence: a report that never names MemoryIndex (for example odd rank_feature scores in a percolator) could be missed, though the downstream percolator searches were aimed at that case.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs (GitHub search, migrated JIRA included); Elasticsearch, OpenSearch, Solr | 2026-10-26 | 34 issue/PR searches (7 also over downstream repositories) plus 2 further downstream queries: MemoryIndex with term frequency, TermFrequencyAttribute, FeatureField, custom term, rank feature, DelimitedTermFrequencyTokenFilter, DOCS_AND_CUSTOM_FREQS; storeTerms; percolator rank_feature | no report; related only: LUCENE-8756 / #9801, LUCENE-7679 / #8730, #15584, #11799 |
| apache/lucene commits and git history of lucene/memory and lucene/monitor | 2026-10-26 | 3 commit searches; git log -S TermFrequencyAttribute / getTermFrequency; all 40 MemoryIndex commits; CHANGES.txt | MemoryIndex has never read the attribute; no fix |
| dev@, java-user@, issues@, commits@ (full archive); JIRA archive (LUCENE, SOLR) | 2026-10-26 | 60 list queries; 19 JIRA queries, 13 issues read in full (as listed in the prior-report record) | no report; SOLR-10828 (Solr PreAnalyzedField lacks TermFrequencyAttribute support, open) is the same class elsewhere |
| open apache/lucene PRs; luwak issues; the web | 2026-10-26 | changed files of all 411 open PRs; all 191 luwak issue titles; 25 web queries | 7 open PRs touch MemoryIndex.java (#486, #13342, #13525, #13948, #14475, #14716, #16847), none changes storeTerms; luwak #135 is the omitNorms report behind LUCENE-7679 |
An omission since custom frequencies exist: LUCENE-7854 (d276acfbbcb8, 2017-06-06; first release 7.0.0) taught IndexWriter the attribute but not MemoryIndex. FeatureField (7.4.0) and DOCS_AND_CUSTOM_FREQS (10.5.0) widened the reach. Ten releases from 7.0.0 to 10.5.2 and main were run: all fail; not fixed upstream.
Versions tested10 rows
Introduced by d276acfbbcb8 (2017-06-06), "LUCENE-7854: enable indexing custom term frequencies" (@mikemccand; GitHub issue #8905; committed from a JIRA patch). It added TermFrequencyAttribute and made DefaultIndexingChain, FreqProxTermsWriterPerField and TermVectorsConsumerPerField honour it, in 14 files, none in lucene/memory. The one-per-token counting in storeTerms is older (current lines from LUCENE-7091, cf3eea264066, 2016), so this is an omission, not a regression.
Later commits widened the reach without touching it: 5844ed4ac953 (DelimitedTermFrequencyTokenFilter, 7.0.0), LUCENE-8197 (FeatureField, 7.4.0; main commit 710993435f36, backport 70cc7b68783), LUCENE-8031 (29e5b8abcee8, edited storeTerms, 8.0.0) and #15584 (DOCS_AND_CUSTOM_FREQS, 10.5.0; main commit 5158a52a082b, backport 3a55cc9ac5e; one MemoryIndex line changed). Lucene Monitor arrived in 8.2.0, but its single-document match uses MemoryIndex only since 8.6.0 (LUCENE-9314, 633ae90d7d9): in 8.2.0 to 8.5.2 match(Document) went through match(new Document[] {doc}) and the IndexWriter-based MultiDocumentBatch (read). 10.6.0 was released on 2026-10-29; on branch_10_6 (2763db11b0a, 2026-10-24) storeTerms still counts one per token (source only, not run). MemoryIndex.java never mentions the attribute at any of the 65 local release tags 7.0.0 to 10.5.2; the local clone has no tags for 8.8.2 to 8.11.3, which were neither read nor run (8.8.1 and 8.11.4 on either side are affected).
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's JUnits: 6 of 7 fail through gradle, assertions on and off; the control passes |
main ea57360912ed | affected | the finder's test 3 of 3, the independent test 6 of 7; -ea and -da |
| 10.5.2 | affected | this doc's JUnits 6 of 7 fail (control passes); the finder's, the independent and the Monitor tests and the history probes fail |
| 10.5.0 | DOCS_AND_CUSTOM_FREQS arrives | the DOCS_AND_CUSTOM_FREQS JUnit fails (sumTotalTermFreq 7 vs 1); 10.4.0 has no such option |
| 9.0.0, 9.12.3, 10.0.0 | affected | history probes fail (custom stream, FeatureField saturation and log); on 9.12.3 the finder's JUnit 2 of 2 and the independent one 4 of 5 |
| 8.0.0, 8.11.4 | affected | history probes fail; BM25 0.24558227 vs 0.13076457 from 8.0.0 |
| 7.4.0, 7.7.3 | FeatureField arrives | FeatureField freq 33344 vs 1, saturation 0.5 vs 0.0, log 2.3978953 vs 0.0 |
| 7.0.0 | first release | custom stream freq 7 vs 1, sumTotalTermFreq 8 vs 2, norm 8 vs 2; DelimitedTermFrequencyTokenFilter fails |
| 6.6.6 | no API | compile error: no TermFrequencyAttribute |
fix (scratch worktree at a9779ef3c193) | not affected | this doc's JUnits pass with assertions on and off; memory, monitor and highlighter suites pass (73 classes, 991 tests) |
An independent reproducer and an intended-behaviour devil's advocate reproduced it with their own tests, controls passing. Reading-only reviews by a model from another family (OpenAI GPT-5.6) agreed on the root cause; an adjudication confirmed it, and this doc's gradle runs reproduce it on a9779ef3c193 and validate the fix.
Checks and verdicts394 words
Every executing check wrote or re-ran its own JUnit on stock main; every control passed.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Translation-validation harness plus public-API JUnits: 3 of 3 fail on main (-ea, -da), 2 of 2 on 10.5.2 and 9.12.3; with the first fix sketch they pass and 51 upstream memory tests pass. |
| independent reproducer | real | Own JUnits written from the claim: 6 of 7 fail on main (control passes), 5 of 6 on 10.5.2, 4 of 5 on 9.12.3, a main() variant on 8.11.4; found the saturation 0.0 and the Monitor batch-size symptom. |
| cross-model reviews (refute, intended) | not real (low, procedural); real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6) could only read code. The refute lens agreed on the root cause and that the inputs are legal; its "not real" was procedural. The intended lens rated the always-positional argument moderate and rejected it. A separate run re-ran the repro: 3 of 3 fail. |
| intended-behaviour devil's advocate | real | Built the strongest intended reading and showed why it fails; its own Monitor batch-size test fails on main (-ea, -da) and 10.5.2. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test (6 of 7, -ea and -da); corrected the DOCS_AND_CUSTOM_FREQS sub-case to released since 10.5.0. |
| Follow-up and main refresh | reproduces; keep | History probes on 14 targets from 6.6.6 to main, the security probe, 152 prior-report queries, re-runs; the refresh to a9779ef3c193 gives identical failures. |
| this doc's gradle runs | reproduces; fix validated | Stock a9779ef3c193: 6 of 7 fail through gradle, assertions on and off, control passing; with the fix 8 of 8 pass (with the overflow test) and 73 nearby classes (991 tests) pass; lint and format pass. |
| fact checks of this doc (two, 2026-10-27) | bug, mechanism and fix hold; text corrected | An independent fact check re-ran the gradle repro (4 of 5 and 2 of 2 fail, assertions on and off) and the fix (8 of 8; 73 classes pass), and found two citation errors. A second check by an independent reviewer from another model family (OpenAI GPT-5.6, reading only, on reference outputs and a probe made for it) found that Monitor's single-document path dates from 8.6.0, not 8.2.0, that the zero scores depend on the function parameters, and several overclaims. All were corrected in this doc. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 508 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,424 words
- Registry title
- MemoryIndex ignores TermFrequencyAttribute, so FeatureField values and custom term frequencies are indexed as frequency 1 and their postings frequencies, term statistics, norms and scores differ from IndexWriter's (Lucene Monitor's single-document matching included)
- Area
- memory / MemoryIndex term inversion (custom term frequencies: FeatureField, TermFrequencyAttribute streams, DOCS_AND_CUSTOM_FREQS); reached in-tree through monitor single-document batches
- Priority
- Medium, rank 239: Since 7.0, MemoryIndex ignores custom term frequencies, so FeatureField scores collapse while matching is unchanged for the tested queries, a silent scoring error like the norms row LFV-105, which it follows.
- Impact class
- silent wrong results
- Impact note
- Anyone who puts a FeatureField (rank feature) or another field whose TokenStream sets TermFrequencyAttribute (a DOCS_AND_FREQS custom-frequency stream, DelimitedTermFrequencyTokenFilter input, or since 10.5.0 a DOCS_AND_CUSTOM_FREQS field) into a MemoryIndex, directly, through fromDocument/addField(IndexableField, Analyzer) or through Lucene Monitor's one-document batches (since 8.6.0), counts each such token as frequency 1, so FeatureField query scores collapse (linear 10.0 becomes 4.5918E-41; saturation or sigmoid with an explicit pivot such as 10, and log with scalingFactor 1, become exactly 0.0, which MemoryIndex.search documents as 'no match' and which makes Monitor's ScoringMatch drop the match) and term statistics, norms and BM25 scores of custom-frequency fields are wrong; for the tested queries, which documents match is unchanged; default settings otherwise, opt-in custom-frequency feature, any scale, every release checked since 7.0.0.
- Summary
- You add a document with FeatureField("features", "pagerank", 10f), or a tokenized DOCS_AND_FREQS field whose TokenStream sets TermFrequencyAttribute (for example DelimitedTermFrequencyTokenFilter on 'a|7'), to a MemoryIndex and expect its postings, statistics and scores to equal those of the same document in a one-document IndexWriter index, as they do for ordinary fields. Instead MemoryIndex.storeTerms never reads the attribute and counts every token as frequency 1: FeatureField.newLinearQuery scores 4.5918E-41 instead of 10.0, newSaturationQuery with the pivot 10 scores exactly 0.0 (MemoryIndex.search's 'no match' value) for a document that matches, and a term with custom frequency 7 reports freq 1, sumTotalTermFreq 1 and a lower BM25 score. Lucene Monitor inherits it (since 8.6.0): the same FeatureField document scores 10.0 in a two-document batch (IndexWriter path) and 4.5918E-41 when matched alone (MemoryIndex path).
- Introduced
- d276acfbbcb8ea6124fe486e35cea9eb928e4702 (LUCENE-7854 'enable indexing custom term frequencies', by GitHub mikemccand; a JIRA patch with no GitHub PR, migrated as apache/lucene#8905) [read: it added TermFrequencyAttribute and made the IndexWriter chain (DefaultIndexingChain, FreqProxTermsWriterPerField, TermVectorsConsumerPerField) honour it, in 14 files, none in lucene/memory; exec: the history probe does not compile on 6.6.6 (no TermFrequencyAttribute) and fails on 7.0.0]. An omission since the feature was introduced, not a regression: MemoryIndex's one-per-token counting is older (current lines from LUCENE-7091 cf3eea264066, 2016-03-09; a per-token loop since 2005). Later commits widened the reach without touching it: 5844ed4ac953 (LUCENE-7854 follow-up, DelimitedTermFrequencyTokenFilter, 7.0.0), 70cc7b68783b / 710993435f36 (LUCENE-8197, FeatureField, 7.4.0), 29e5b8abcee8 (LUCENE-8031, edited storeTerms and the norm, still not reading the attribute, 8.0.0) and 3a55cc9ac5e9 / 5158a52a082b (#15584, DOCS_AND_CUSTOM_FREQS, one MemoryIndex line changed, 10.5.0) (2017-06-06 (d276acfbbcb8); reach widened 2017-06-09 (DelimitedTermFrequencyTokenFilter), 2018-03-20 (FeatureField) and 2026-04-24 (#15584 merged, DOCS_AND_CUSTOM_FREQS))
- First affected version
- 7.0.0 [exec] (first release with TermFrequencyAttribute; 6.6.6 has no such API and the probe does not compile); the FeatureField path from 7.4.0 [exec; 7.3.1 has no FeatureField]; the DOCS_AND_CUSTOM_FREQS sub-case from 10.5.0 [exec; the option is absent in 10.4.0]
- Affected versions
- Every release checked from 7.0.0 to 10.6.0 (10.6.0 by reading), and main (ea57360912ed and a9779ef3c193). [exec] plain main() history probes (a DOCS_AND_FREQS custom-frequency stream; FeatureField with saturation and log queries; DelimitedTermFrequencyTokenFilter) fail on 7.0.0, 7.4.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main, each with a passing frequency-1 control, and pass on main with the fix sketch shadowed; the finder's JUnit fails on main (3 of 3, -ea and -da), 10.5.2 and 9.12.3 (2 of 2) and a main() variant on 8.11.4; the DOCS_AND_CUSTOM_FREQS JUnit fails on 10.5.0, 10.5.2 and main; the independent reproduction's JUnit fails on main (6 of 7, -ea and -da), 10.5.2 (5 of 6) and 9.12.3 (4 of 5) and its main() variant on 8.11.4; the Monitor batch-size test fails on main (-ea and -da) and 10.5.2. [exec] on main a9779ef3c193 the bug doc's JUnits fail 6 of 7 through gradle, assertions on and off. [read] the releases not executed (7.1-7.3, 8.1-8.8.1, 9.1-9.11, 10.1-10.4): MemoryIndex.java never mentions the attribute at any of the 65 local release tags 7.0.0 to 10.5.2; the local history clone has no tags for 8.8.2 to 8.11.3, which were neither read nor run; Lucene Monitor (from 8.2.0) matches a single document on MemoryIndex only since 8.6.0 (LUCENE-9314): in 8.2.0 to 8.5.2 Monitor.match(Document) called match(new Document[] {doc}) and DocumentBatch.of(Analyzer, Document...) always built the IndexWriter-based MultiDocumentBatch. branch_10_6 (2763db11b0a, 2026-10-24, before the 10.6.0 release of 2026-10-29): storeTerms unchanged, read only. Not checked: x86. Unfixed: no commit in lucene/memory or lucene/monitor adds custom-frequency support, and no open PR changes storeTerms
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, verdict new: 152 read-only queries: 34 GitHub issue/PR searches (7 also over Elasticsearch, OpenSearch and Solr repositories) plus 2 further downstream-repository queries, 3 commit searches, 60 mailing-list queries over dev@, java-user@, issues@ and commits@, 19 JIRA-archive queries over LUCENE and SOLR (13 issues read in full, as listed in the prior-report record), 25 web queries, GitHub thread reads, the changed-file lists of all 411 open apache/lucene PRs, git history of lucene/memory and lucene/monitor, CHANGES.txt and the luwak issue titles); not fixed upstream: no commit in lucene/memory or lucene/monitor adds custom-frequency support, and the 7 open PRs that touch MemoryIndex.java (#486, #13342, #13525, #13948, #14475, #14716, #16847) do not change storeTerms or frequencies. Related items, not reports of this bug: LUCENE-8756 / #9801 (MoreLikeThis ignored custom term frequencies; same bug class, other component, fixed in 8.1.0), LUCENE-7679 / #8730 and luwak #135 (MemoryIndex ignored omitNorms and gave wrong scores; fixed in 6.5.0), SOLR-10828 (Solr PreAnalyzedField lacks TermFrequencyAttribute support, open), LUCENE-7854 / #8905 (introduced the attribute), LUCENE-8197 / #9244 (FeatureField), LUCENE-7866, #15584, #11086, #9547, #9990, #11799, LUCENE-9314, LUCENE-4880 / #5945, elastic/elasticsearch #28803
- Lucene commit tested
- main
a9779ef3c193(commit of 2026-10-26): the two JUnits through gradle in a clean worktree, stock and with the fix, assertions on and off, plus the whole memory, monitor and highlighter test suites with the fix (2026-10-27); the same JUnits through the hunt's classpath runner on main and the 10.5.2 release jars. Hunt runs on mainea57360912edand on releases from 7.0.0 to 10.5.2; the main refresh toa9779ef3c193reproduces with identical messages.
- Finding record
a Lucene main checkout lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:991-1050 (storeTerms: numTokens++, freq[ord]++, sumTotalTermFreq++ per token; no TermFrequencyAttribute anywhere in the file), :1100-1108 (search javadoc: 0.0 indicating no match)a Lucene main checkout lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:208-218 (getTermFreq) and lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:1997-2008 (field length adds getTermFrequency(), or 1 for term-doc fields, with Math.addExact)a Lucene main checkout lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:23-35 (contract) and lucene/core/src/java/org/apache/lucene/document/FeatureField.java (values encoded as term frequencies)a Lucene main checkout lucene/monitor/src/java/org/apache/lucene/monitor/DocumentBatch.java:44-62 (one document -> SingletonDocumentBatch on MemoryIndex, more -> IndexWriter) and ScoringMatch.java:34-39 (a match needs score > 0)
- The finding in 30 seconds
lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:106, 153-157, 991-1053 (1002-1007, 1012, 1025, 1027), 1105-1106, 1380-1393lucene/core/src/java/org/apache/lucene/document/FeatureField.java:47, 114, 162-171, 185-186, 222, 240-249, 356, 408-415, 450, 531, 725-738lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:24-26lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:208-219 (210-216: positions); lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2053-2064lucene/monitor/src/java/org/apache/lucene/monitor/DocumentBatch.java:44-62, 105-113; ScoringMatch.java:37
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/TermFrequencyAttribute.java:24-26; lucene/core/src/java/org/apache/lucene/document/FeatureField.java:47; lucene/core/src/java/org/apache/lucene/index/IndexOptions.java:53-56; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/DelimitedTermFrequencyTokenFilter.java:29-32lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java:106, 129, 476-479, 692-730 (728), 759-763; lucene/monitor/src/java/org/apache/lucene/monitor/DocumentBatch.java:101-102lucene/memory/src/test/org/apache/lucene/index/memory/TestMemoryIndexAgainstDirectory.java:193-196, 200-207, 210-250, 259-268, 714-800; TestMemoryIndex.java:1093lucene/CHANGES.txt:1476-1477 (GITHUB#15334), 5804-5805 (LUCENE-9314)gh issue view 9801 / 8730 --repo apache/lucene (labels type:bug; read-only, 2026-10-27)
- Suggested fix
lucene/core/src/java/org/apache/lucene/index/FreqProxTermsWriterPerField.java:147-152, 193-194, 208-219; lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2095-2097; lucene/highlighter/src/java/org/apache/lucene/search/uhighlight/MemoryIndexOffsetStrategy.java:112; lucene/highlighter/src/java/org/apache/lucene/search/highlight/WeightedSpanTermExtractor.java:411-413; lucene/CHANGES.txt:1476-1477 (GITHUB#15334)
- History
a Lucene clone origin/branch_10_6 2763db11b0a lucene/memory/src/java/org/apache/lucene/index/memory/MemoryIndex.java (storeTerms)
- TestMemoryIndexFeatureField.java (JUnit test):
repro/LFV-333/src/org/apache/lucene/index/memory/TestMemoryIndexFeatureField.java(30 lines)
Made in parallel with this doc from a probe run on main a9779ef3c193 (assertions on and off, 10.5.2, and with the fix shadowed); the values on screen come from the probe. The probe adds a DOCS_AND_FREQS field with frequencies a=7, b=1, the same case as the repro. Revised on 2026-10-27 after the diagram check: the code panel now declares Document doc (the panel's lines were compiled and run on main, same values), and some labels were reworded; no value changed.
assets/LFV-333/bug.png(508 KB)