One parenthesis is in the wrong place: the factory upper-cases its own default instead of the value you configured.
JapaneseCompletionFilter(kuromoji module) adds romanized forms of Japanese tokens for auto-complete. It has two modes:INDEX(simple romanization, used when indexing; the default) andQUERY(Input-Method-aware romanization, used on what the user is typing).- Analysis factories build components from string settings.
JapaneseCompletionFilterFactory, SPI namejapaneseCompletion, reads the settingmodefrom its argument map;CustomAnalyzerand analyzer definitions loaded by SPI name pass it that way. - Its neighbour
JapaneseTokenizerFactoryreads its ownmodesetting the same way and upper-cases it, somode="search"andmode="normal"work there.
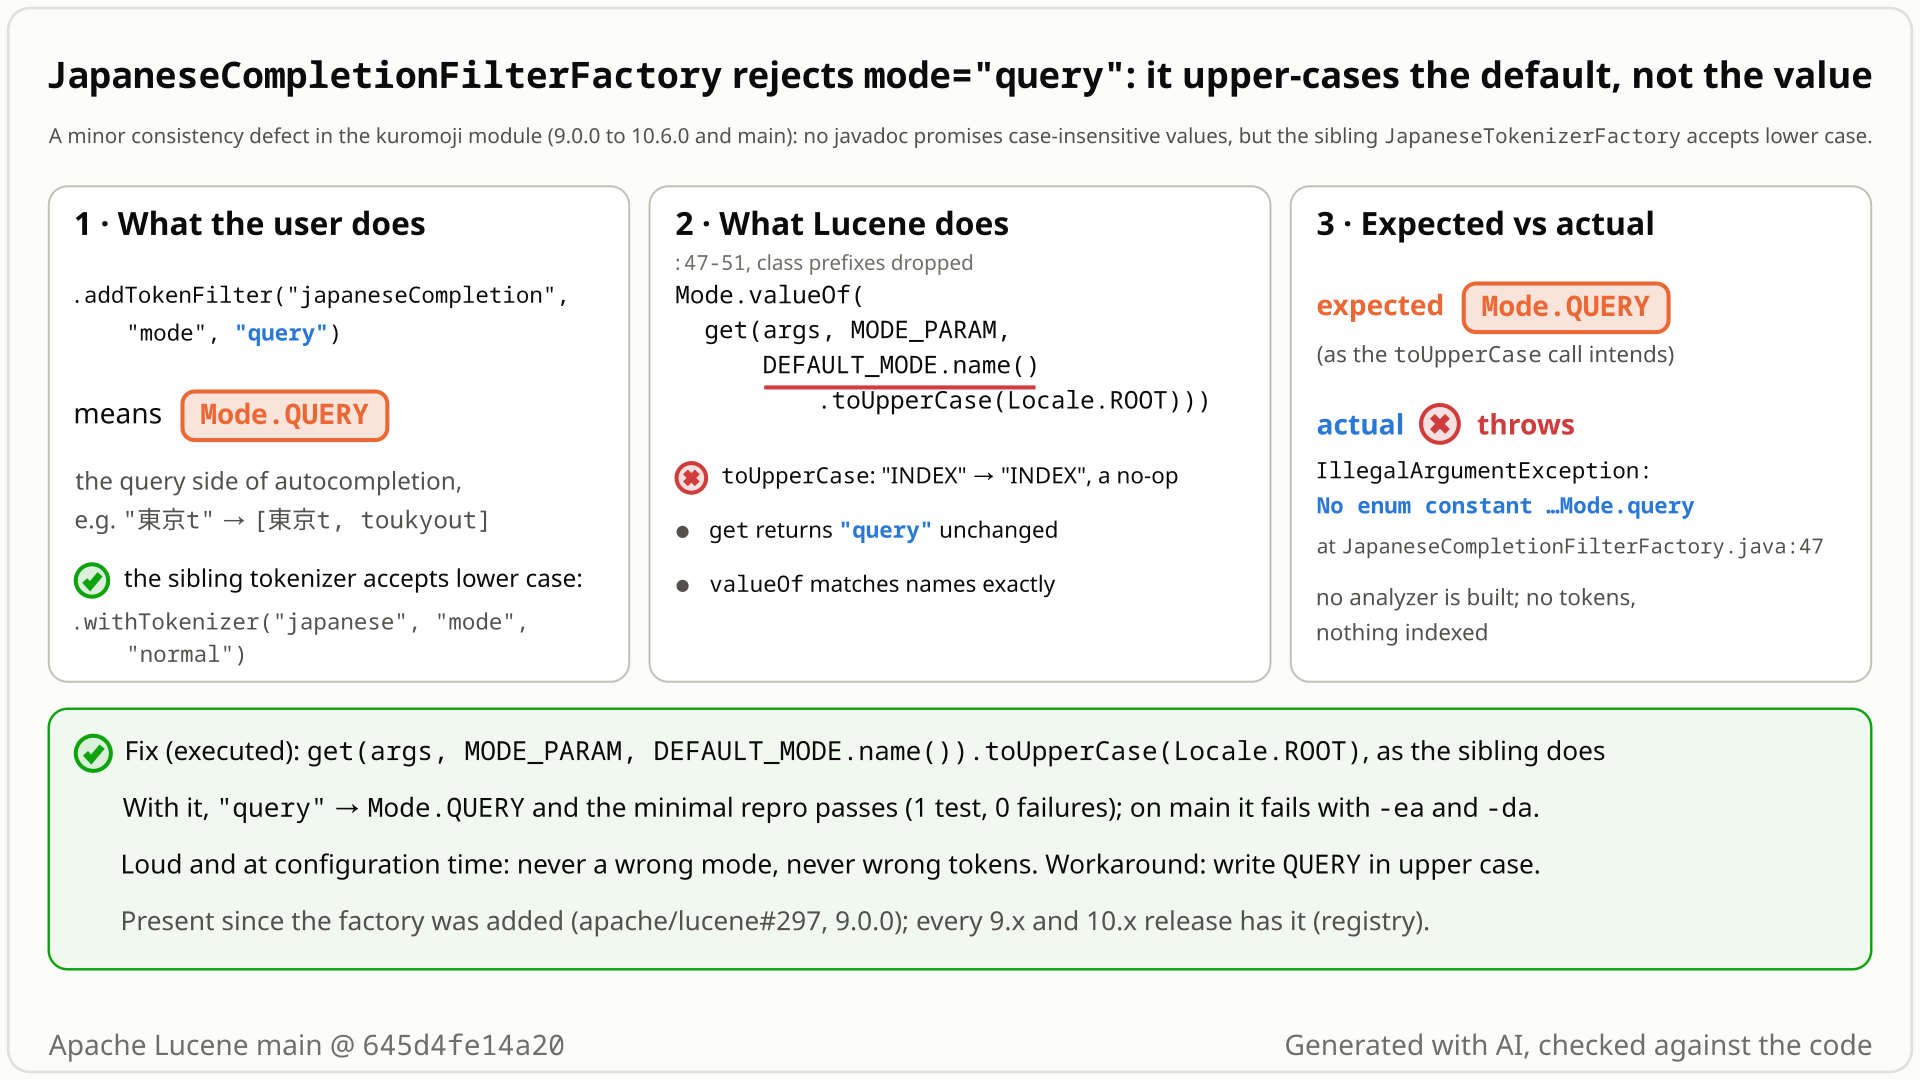
"INDEX", so "query" reaches Mode.valueOf unchanged and is rejected. Select the still to open it at full size. Generated with AI, checked against the code.- Build the
japaneseCompletionfilter through its factory withmode="query", for exampleCustomAnalyzer.builder().withTokenizer("japanese", "mode", "normal").addTokenFilter("japaneseCompletion", "mode", "query"): lower case, as the Japanese tokenizer factory accepts in the same call. - You expect a
QUERY-mode filter: the factory's mode expression contains atoUpperCase(Locale.ROOT)call, and withQUERYthe filter turns the input東京t, after width normalization (CJKWidthFilter), into the 2 tokens東京tandtoukyout. - Instead the constructor throws
IllegalArgumentException: No enum constant ...JapaneseCompletionFilter.Mode.query. ThetoUpperCaseruns on the default,DEFAULT_MODE.name(), which is already"INDEX", so your"query"reaches the case-sensitiveMode.valueOfunchanged. - Only the exact names
INDEXandQUERYwork. The error is immediate and never selects the wrong mode, and every release from 9.0.0 to 10.6.0 has it.
Applications that build the opt-in japaneseCompletion filter through its factory (the Map constructor, TokenFilterFactory.forName, CustomAnalyzer or an analyzer definition loaded by SPI name) and write the mode as query or Query. The analyzer cannot be built; writing QUERY works. Nothing at index or search time is affected.
Mechanism, terms and numbers395 words
JapaneseCompletionFilterFactory (SPI name japaneseCompletion) reads its mode argument with Mode.valueOf(get(args, MODE_PARAM, DEFAULT_MODE.name().toUpperCase(Locale.ROOT))). The toUpperCase is applied to the default, the constant name "INDEX", so it does nothing, and the configured value reaches the case-sensitive Enum.valueOf unchanged: mode="query" throws IllegalArgumentException: No enum constant org.apache.lucene.analysis.ja.JapaneseCompletionFilter.Mode.query from the constructor and through CustomAnalyzer, and only INDEX and QUERY work. The sibling JapaneseTokenizerFactory in the same module uses the same idiom with the parenthesis after get(...) and accepts lower-case modes. The expression has been there since the factory was added (LUCENE-10102, #297, 2021) and is in every release from 9.0.0 to 10.6.0 and on main. No javadoc promises case-insensitive values, so this is a minor consistency defect, not a broken contract: it fails loudly when the analyzer is built, never picks the wrong mode and never affects tokens or an index. Moving .toUpperCase(Locale.ROOT) onto the result of get(...) fixes it.
JapaneseCompletionFilter.Mode: an enum with the constantsINDEXandQUERY(JapaneseCompletionFilter.java:74-79at645d4fe14a20);DEFAULT_MODE = Mode.INDEX(:61).AbstractAnalysisFactory.get(args, name, defaultVal): removes the argument from the map and returns it as given, or the default when it is absent (AbstractAnalysisFactory.java:160-163).Enum.valueOf: case-sensitive; any string that is not exactly a constant name throwsIllegalArgumentException: No enum constant ....
- The constructor parses the mode (
JapaneseCompletionFilterFactory.java:46-51):
mode =
    JapaneseCompletionFilter.Mode.valueOf(
        get(
            args,
            MODE_PARAM,
JapaneseCompletionFilter.DEFAULT_MODE.name().toUpperCase(Locale.ROOT)));- The closing parenthesis of
get(...)comes after thetoUpperCase, so the call belongs to the third argument, the default.DEFAULT_MODE.name()is already"INDEX"; upper-casing it can never change anything. - The configured value, for example
"query", is returned unchanged andMode.valueOf("query")throws. - The sibling
JapaneseTokenizerFactoryputs the call on the configured value:Mode.valueOf(get(args, MODE, JapaneseTokenizer.DEFAULT_MODE.toString()).toUpperCase(Locale.ROOT))(JapaneseTokenizerFactory.java:122-124);KoreanTokenizerFactorydoes the same (KoreanTokenizerFactory.java:92-95).
- A probe of 19 mode values, each through the constructor and through
CustomAnalyzer: only exactlyINDEXandQUERYwere accepted, each giving its own mode;query,Query,index,' QUERY'and the others were rejected. On the input東京t,INDEXgives[東京, toukyou, t, thiー, texiー]andQUERYgives[東京t, toukyout]. - With the fix the lower- and mixed-case spellings probed (7 ASCII variants such as
query,Query,qUERYandiNDEX, plusındex) give the mode they name, and the other values are still rejected.
Exposure and likelihood135 words
- Who is hit. Only users of the factory.
JapaneseCompletionAnalyzerbuilds the filter directly, not through the factory, so it is not affected; neither is code that constructsJapaneseCompletionFilterorJapaneseCompletionAnalyzerdirectly, since their constructors take theModeenum or pickINDEXwhen none is given, and never parse a string. - What it takes. Writing the query-side mode in lower or mixed case. That is the natural spelling next to the sibling tokenizer: its factory accepts lower case, its upstream test passes
"normal", and the Solr reference guide documents lower-case modes for it. - What happens. A deterministic
IllegalArgumentExceptionwhen the factory is constructed, naming the enum. It never selects the other mode, never yields wrong tokens and never reaches an index. - Scale. Minor: a loud configuration-time nit with a one-word workaround, unreported since 9.0.0 (2021).
One JUnit test on the public API: it builds the factory with mode=query through its Map constructor and fails if that throws. Deterministic, single thread, no randomness; the test method takes about 20 ms.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.ja;

import java.util.HashMap;
import java.util.Map;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestJapaneseCompletionFilterFactoryLowerCaseMode extends LuceneTestCase {

  public void testLowerCaseMode() {
    try {
      new JapaneseCompletionFilterFactory(new HashMap<>(Map.of("mode", "query")));
    } catch (IllegalArgumentException e) {
      fail("expected mode=query to be upper-cased to QUERY, but the factory threw: " + e);
    }
  }
}
cp TestJapaneseCompletionFilterFactoryLowerCaseMode.java $LUCENE/lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/
cd $LUCENE && ./gradlew :lucene:analysis:kuromoji:test --tests org.apache.lucene.analysis.ja.TestJapaneseCompletionFilterFactoryLowerCaseMode -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
- Expected
mode=queryis upper-cased toQUERYand the factory builds aQUERY-mode filter.- Observed
IllegalArgumentException: No enum constant org.apache.lucene.analysis.ja.JapaneseCompletionFilter.Mode.queryfrom the factory constructor (JapaneseCompletionFilterFactory.java:47).
More files, environment, full output199 words
The map is a mutable HashMap because the factory removes the arguments it consumes. The same exception comes out of CustomAnalyzer.builder().withTokenizer("japanese", "mode", "normal").addTokenFilter("japaneseCompletion", "mode", "query").build(), which calls the same constructor through AnalysisSPILoader.newFactoryClassInstance. The test compiles on 9.1.0 and later (where LuceneTestCase lives in org.apache.lucene.tests.util); 9.0.0 was checked with a main() form making the same calls.
As the regression test: the same test, for example as a new method in TestJapaneseCompletionFilterFactory.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the test also fails on 10.6.0 and 9.1.0; every release from 9.0.0 has the same factory code |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestJapaneseCompletionFilterFactoryLowerCaseMode.java $LUCENE/lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/
cd $LUCENE && ./gradlew :lucene:analysis:kuromoji:test --tests org.apache.lucene.analysis.ja.TestJapaneseCompletionFilterFactoryLowerCaseMode -Ptests.seed=DEADBEEF
# assertions off: add -Ptests.asserts=false (same result)
# gradle, main 645d4fe14a20, seed DEADBEEF (the same with -Ptests.asserts=false)
TestJapaneseCompletionFilterFactoryLowerCaseMode > testLowerCaseMode FAILED
    java.lang.AssertionError: expected mode=query to be upper-cased to QUERY, but the factory threw: java.lang.IllegalArgumentException: No enum constant org.apache.lucene.analysis.ja.JapaneseCompletionFilter.Mode.query
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:8EC20BA6F19FBC63]:0)
        at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
        at org.apache.lucene.analysis.ja.TestJapaneseCompletionFilterFactoryLowerCaseMode.testLowerCaseMode(TestJapaneseCompletionFilterFactoryLowerCaseMode.java:29)

# where it is thrown (the hunt's earlier tests, which let the exception escape; same lines at 645d4fe14a20)
java.lang.IllegalArgumentException: No enum constant org.apache.lucene.analysis.ja.JapaneseCompletionFilter.Mode.query
  at org.apache.lucene.analysis.ja.JapaneseCompletionFilterFactory.<init>(JapaneseCompletionFilterFactory.java:47)
(through CustomAnalyzer the same exception, with AnalysisSPILoader.newFactoryClassInstance(AnalysisSPILoader.java:195) in its stack)- The factory's mode expression does call
toUpperCase(Locale.ROOT), but on the default'sname(), the already upper-case"INDEX", where it can never change anything. - The sibling
JapaneseTokenizerFactoryputs the same call afterget(...), and its upstream test passes lower-case"normal". - No javadoc, test, PR review or issue comment makes the case sensitivity deliberate; none promises case-insensitivity either, hence a minor defect.
The full argument156 words
- The dead call.
DEFAULT_MODE.name().toUpperCase(Locale.ROOT)is always"INDEX"(JapaneseCompletionFilterFactory.java:51,JapaneseCompletionFilter.java:61). - Sibling convention, same module.
JapaneseTokenizerFactoryhas upper-cased the configured value since at least 2013 (LUCENE-4877,6de43dea0af, which introduced theget(...).toUpperCase(Locale.ROOT)form);KoreanTokenizerFactory(:92-95) andWord2VecSynonymFilterFactory(:58) do the same. - Tests.
TestJapaneseTokenizerFactory.testModepasses"normal"; the completion factory's only mode test passes"QUERY"(TestJapaneseCompletionFilterFactory.java:36), and no test asserts that lower case is rejected. - History. The factory came in one commit,
4e86df96c03(LUCENE-10102, #297, by Tomoko Uchida, co-authored by Robert Muir, 2021-09-17), with this exact expression, and the file has never been edited since. None of the PR's review comments or the issue's comments is about themodeargument or its case. - Project convention. In LUCENE-4877 (#5942, 2013) Steven Rowe proposed a
getEnum(...)helper for factory arguments, "probably case insensitivity could be assumed?", and Robert Muir replied "+1 to all of this". Context only, eight years before this factory.
The devil's-advocate check186 words
The strongest case for "intended" (an intended-behaviour checker, and a read-only reviewer from another model family, OpenAI GPT-5.6, which leaned "not real"): the only documentation is "mode: Completion mode. see JapaneseCompletionFilter.Mode" (JapaneseCompletionFilterFactory.java:30), whose constants are INDEX and QUERY; the upstream test uses QUERY; even JapaneseTokenizerFactory's javadoc example writes mode="NORMAL" (:43); BeiderMorseFilterFactory is case-sensitive (a plain valueOf at :58-59, and its javadoc example uses upper-case values); and the failure is loud, immediate and has a one-word workaround.
Why it fails: it shows there is no broken contract, which is why this is classed as a minor consistency defect, but not that case sensitivity was chosen. BeiderMorseFilterFactory has no toUpperCase call at all, so it is no precedent for a misplaced one; this factory's mode expression does call toUpperCase(Locale.ROOT), and only the call's placement (on the default instead of the configured value) makes it useless. No javadoc, test, CHANGES.txt, MIGRATE.md, review or issue comment says the case sensitivity is deliberate. This is still an inference about intent: a maintainer could reasonably prefer option B or decline.
Recommended A. Upper-case the configured value, not the default (mirrors JapaneseTokenizerFactory)
Move .toUpperCase(Locale.ROOT) from the default onto the result of get(...), exactly as JapaneseTokenizerFactory does. Lower- and mixed-case spellings of INDEX and QUERY then give the mode they name, and other values are still rejected. With it the repro passes with assertions on and off, and the kuromoji module's 196 tests (0 failures) and its check pass.
     mode =
         JapaneseCompletionFilter.Mode.valueOf(
-            get(
-                args,
-                MODE_PARAM,
-                JapaneseCompletionFilter.DEFAULT_MODE.name().toUpperCase(Locale.ROOT)));
+            get(args, MODE_PARAM, JapaneseCompletionFilter.DEFAULT_MODE.name())
+                .toUpperCase(Locale.ROOT));
All options and trade-offs3 options · 366 words
One option was run through gradle in a scratch worktree of 645d4fe14a20 and is recommended; the alternatives were not run.
A. Upper-case the configured value, not the default (mirrors JapaneseTokenizerFactory) (validated by the checks) (recommended)
In the constructor (JapaneseCompletionFilterFactory.java:46-51), move .toUpperCase(Locale.ROOT) onto the result of get(...).
     mode =
         JapaneseCompletionFilter.Mode.valueOf(
-            get(
-                args,
-                MODE_PARAM,
-                JapaneseCompletionFilter.DEFAULT_MODE.name().toUpperCase(Locale.ROOT)));
+            get(args, MODE_PARAM, JapaneseCompletionFilter.DEFAULT_MODE.name())
+                .toUpperCase(Locale.ROOT));
Trade-offs
- Lower- and mixed-case spellings of
INDEXandQUERYare accepted and give the mode they name (7 ASCII variants probed, such asquery,Query,qUERY,iNDEX); any other value is still rejected with the same exception type (its message then shows the upper-cased value). Upper-case configurations behave as before; no signature or index-format change, but construction-time parsing becomes more permissive (values rejected today are accepted). - As in
JapaneseTokenizerFactory,Locale.ROOTupper-casing maps U+0131 (dotless i) toI, soındexis accepted asINDEX; harmless for a trusted configuration value and independent of the JVM default locale.
What the checks validated
- Gradle in a scratch worktree of
645d4fe14a20(2026-11-01): stock, the minimal test fails with assertions on and off; with the fix it passes both ways. - With the fix:
TestJapaneseCompletion*(analyzer, filter, factory and the repro) 4 classes, 12 tests, 0 failures; the whole kuromoji module 31 classes, 196 tests, 0 failures (7 skipped by the test framework);:lucene:analysis:kuromoji:check -x testpasses (formatting, ecjLint, forbiddenApis). - Earlier: the same change shadowed into the stock jars passes the hunt's 3-test and 4-test JUnits (which also check the
QUERY-mode tokens) and themain()form on 9.0.0.
For example "mode: INDEX (default) or QUERY, case-insensitive" next to the existing "see JapaneseCompletionFilter.Mode" line.
Trade-offs
Documentation only; makes the accepted spellings explicit. Not run.
Replace the default with JapaneseCompletionFilter.DEFAULT_MODE.name() and state in the javadoc that only INDEX and QUERY are accepted.
Trade-offs
No behaviour change, so no configuration changes meaning; but the completion filter factory stays deliberately stricter than the tokenizer factory it is configured next to, and the lower-case spelling stays a trap. Not run.
Elasticsearch and OpenSearch parse the kuromoji_completion mode case-insensitively in their own code and never call this factory, so they are unaffected; products that build analyzers by the SPI name japaneseCompletion are affected.
Non-formal: while checking a rewrite of the Japanese completion filter's output buffering (#16416), a finder read the factory that builds the filter and noticed toUpperCase applied to the default DEFAULT_MODE.name(), the already upper-case "INDEX", where it can never change anything. A public-API JUnit test with a sibling-factory control then reproduced it.
The method in full91 words
Method: non-formal (code reading, then executed tests). The hunt unit was checking that the #16416 rewrite of JapaneseCompletionFilter's output buffering keeps its behaviour. Reading the factory that constructs the filter under test, the finder saw DEFAULT_MODE.name().toUpperCase(Locale.ROOT), a call that cannot change the already upper-case constant name "INDEX". A 3-test public-API JUnit (control: JapaneseTokenizerFactory with mode=search; claims: the factory and CustomAnalyzer with mode=query) reproduced it on main, 10.5.2 and 9.1.0. Independent checkers then reproduced it with their own tests, and it was cut to the one-test repro.
No prior report found in GitHub issues, PRs and commits (incl. the JIRA archive), all 411 open PRs, the Lucene and Solr mailing lists, downstream trackers or the web (2026-10-26; re-checked 2026-11-01). Not fixed upstream as of 2026-10-30.
Searches4 searches
Closest items, none a report of this bug: #297 / #11140 (introduced the factory; nobody discussed mode case); #11399 / LUCENE-10363 (open; the filter's offsets, a different defect); #16416 (changes only the filter); #5942 / LUCENE-4877 (2013, the case-insensitive enum-argument discussion); elastic/elasticsearch#81858 and opensearch-project/OpenSearch#12287 (their own case-insensitive parsers, never calling the Lucene factory); an outside Kotlin port that silently upper-cases the configured value, with no comment or report. Limits: GitHub search does not index diffs; 4 of the 6 planned web queries were not run (6 manual ones overlap them); private discussions are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs (incl. the migrated JIRA issues) and commits | 2026-10-26 | three scripted prior-report searches (51 + 24 + 24 queries) and about 50 manual GitHub queries: the class and SPI names, mode=query, case sensitivity, valueOf/toUpperCase, the error text | no report |
| Open PRs and the factory's history | 2026-10-26 | changed files of all 411 open apache/lucene PRs; the factory's commits on main, branch_10x and branch_10_5 | no open PR touches the factory; its only commit is 4e86df96c038 |
| Mailing lists, JIRA, downstream, web | 2026-10-26 | dev@, java-user@, issues@ and commits@; the Lucene and Solr lists; LUCENE and SOLR JIRA; Elasticsearch, OpenSearch and Solr; GitHub code search; 6 web queries | context only (downstream integrations with their own parsers) |
| Upstream main and issues | 2026-11-01 | the factory's file blob and commit list at 2f424fd428da (2026-10-30); issue and PR searches for JapaneseCompletionFilterFactory, japaneseCompletion mode, JapaneseCompletionFilter mode case | same blob 608bc5a1be39, unchanged; 0, 0 and #16416 only |
Present since the factory was added by LUCENE-10102 (4e86df96c03, #297, 2021-09-17), so in every release from 9.0.0 to 10.6.0 and on main; 8.x does not have the class.
Versions tested6 rows
Introduced by 4e86df96c03 "LUCENE-10102: Add JapaneseCompletionFilter for Input Method-aware auto-completion (#297)" (Tomoko Uchida, co-authored by Robert Muir, merged 2021-09-17), which added the factory as a new file with this expression. git blame, git log without --follow and git log -S 'DEFAULT_MODE.name().toUpperCase(Locale.ROOT)' return only this commit. The factory file is byte-identical (blob 608bc5a1be39) in every 9.x and 10.x release tag, including 10.6.0, on main 645d4fe14a20 and on upstream main 2f424fd428da. CHANGES.txt lists LUCENE-10102 under 9.0.0 New Features. Not a regression.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal test fails with assertions on and off (through Gradle and standalone); passes with fix A |
| 10.6.0 | affected | minimal test fails with assertions on and off (release jars) |
| 9.1.0 | affected | minimal test fails (assertions off); the finder's JUnit fails 2 of 3 |
| 9.0.0, 9.12.3, 10.0.0, 10.5.2 | affected | the hunt's main() form or JUnit fails with No enum constant ...Mode.query; 9.0.0 passes with the fix |
| other 9.x and 10.x releases | read | factory file byte-identical (blob 608bc5a1be39) |
| 8.9.0, 8.10.1, 8.11.4 | no factory | the class does not exist (API probe on the release jars) |
Confirmed with high confidence that the defect exists, impact minor: the finder, an independent reproducer, an intended-behaviour devil's advocate and an adjudication all reproduced it. A reviewer from another model family, unable to run code, leaned "not real" on the contract but agreed with the root cause.
Checks and verdicts244 words
Everyone agrees on the root cause and that no javadoc promises case-insensitive values, so it is classed as a minor consistency defect.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate (doc, minor) | 3-test JUnit fails 2 of 3 on main with assertions on and off, on 10.5.2 and on 9.1.0; the sibling-factory control passes; the fix sketch passes 5/5 with the upstream factory test. |
| cross-model review, refute lens (OpenAI GPT-5.6, read-only) | not real, medium | Could not run code; argued that no javadoc promises case-insensitivity. Agreed on the root cause ("a minor normalization typo"). A separate re-run: 2 of 3 fail. |
| independent reproducer | real | Its own 4-test JUnit, which also checks the QUERY-mode tokens, fails 2 of 4 on main (assertions on and off), 10.5.2 and 9.12.3; controls pass; 4/4 with the fix. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6, read-only) | real, medium | The intended argument is moderate but does not hold; root cause agrees. |
| intended-behaviour devil's advocate | real, lowest severity | Built the strongest intended case and rejected it; main and 10.5.2 fail 2 of 3. |
| adjudication | confirmed, high | Re-ran the reproducer's JUnit with assertions on and off (2 of 4 fail each) and its fix check (4/4). It classed it as a misplaced no-op normalization with a one-line fix. |
| Follow-up and credibility audit | confirmed | Re-runs on main ea57360912ed and a9779ef3c193 reproduce; the one-test repro fails on 645d4fe14a20 and passes with the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 378 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,251 words
- Registry title
- JapaneseCompletionFilterFactory upper-cases the default mode name instead of the configured value, so mode="query" is rejected with IllegalArgumentException while the sibling JapaneseTokenizerFactory accepts lower-case modes (minor consistency defect; no javadoc promises case-insensitive values)
- Area
- analysis / kuromoji (JapaneseCompletionFilterFactory 'mode' argument parsing, SPI name japaneseCompletion)
- Priority
- Low, rank 1065: JapaneseCompletionFilterFactory rejects lower-case mode values with an immediate, clear error and has an upper-case workaround: a loud configuration nit.
- Impact class
- minor
- Impact note
- Only applications that build the kuromoji japaneseCompletion filter through its factory (the Map constructor, TokenFilterFactory.forName, CustomAnalyzer, or an analyzer definition that uses the SPI factory) and write the mode in lower or mixed case, for example mode="query", are affected: the factory constructor throws IllegalArgumentException 'No enum constant org.apache.lucene.analysis.ja.JapaneseCompletionFilter.Mode.query' when the analyzer is built, with -ea and -da, in every release from 9.0.0 to 10.6.0 and on main; it never selects the wrong mode, never yields wrong tokens and never reaches an index, writing INDEX or QUERY in upper case avoids it, and Elasticsearch and OpenSearch parse the mode themselves and are unaffected.
- Summary
- You configure the Japanese completion filter through its factory with mode="query", for example CustomAnalyzer.builder().withTokenizer("japanese", "mode", "normal").addTokenFilter("japaneseCompletion", "mode", "query"), the same way the sibling Japanese tokenizer factory accepts mode="search". You expect a QUERY-mode filter, because the factory's own parsing code calls toUpperCase(Locale.ROOT) on the mode. Instead the constructor throws IllegalArgumentException 'No enum constant ...JapaneseCompletionFilter.Mode.query': the toUpperCase is applied to the default name "INDEX", which is already upper case, so the configured value reaches the case-sensitive Enum.valueOf unchanged and only the exact names INDEX and QUERY work.
- Introduced
- 4e86df96c0385a7b552434d7e2a9bee69f18bd77 (apache/lucene#297, LUCENE-10102 / GitHub issue #11140 'Add JapaneseCompletionFilter for Input Method-aware auto-completion', by GitHub mocobeta, co-authored by rmuir) [read: the commit added JapaneseCompletionFilterFactory.java as a new file with lines 46-51 in their current form; git blame, git log without --follow and git log -S 'DEFAULT_MODE.name().toUpperCase(Locale.ROOT)' in the full-history clone all return only this commit; inside the PR, branch commit 18ec9a861b ('add test cases; fix bugs.') already had the expression; the factory blob 608bc5a1be39 is unchanged in every 9.x and 10.x release tag and in main ea57360912ed]. Present since the factory was written, so not a regression; the other LUCENE-10102 commits (5dfbef313cf, 6c1e5920d84) touch only JapaneseCompletionFilter.java (2021-09-17 (authored 22:37 +0900; merged 2021-09-17T13:37:13Z))
- First affected version
- 9.0.0 [exec] (the first release with JapaneseCompletionFilterFactory, tagged 2021-12-06; CHANGES.txt lists LUCENE-10102 only under 9.0.0 New Features; 8.9.0, 8.10.1 and 8.11.4 do not have the class [exec: API probe on the published jars])
- Affected versions
- every release that has the factory: 9.0.0, 9.1.0, 9.2.0, 9.3.0, 9.4.0-9.4.2, 9.5.0, 9.6.0, 9.7.0, 9.8.0, 9.9.0-9.9.2, 9.10.0, 9.11.0, 9.11.1, 9.12.0-9.12.3, 10.0.0, 10.1.0, 10.2.0-10.2.2, 10.3.0-10.3.2, 10.4.0, 10.5.0-10.5.2, 10.6.0 and main ea57360912ed [exec: 9.0.0 (-ea and -da, a main() form of the repro, because the JUnit form needs the test-framework package of 9.1.0), 9.1.0 (-da), 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da), each rejecting mode=query through the constructor and through CustomAnalyzer while the controls pass; fix checks pass on 9.0.0 and main; the one-test minimal repro fails on the 10.6.0 release jars (SHA-1 checked against Maven Central) with -ea and -da and on main 645d4fe14a20 (2026-11-01); read: the factory blob 608bc5a1be39 is byte-identical in every other 9.x and 10.x tag]; not applicable to 8.x and older, where the class does not exist [exec: probe on 8.9.0, 8.10.1 and 8.11.4; never backported to branch_8x]; upstream main still has the expression (read 2026-10-26, head e1c4184cb983); not fixed anywhere. All runs used JDK 25 on Linux aarch64, which does not matter for this string parsing
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code and voted “not real” while agreeing with the root cause (the adjudication ruled it real), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal: code reading
- Upstream and prior reports
- none found (2026-10-26: three scripted prior-report searches (the first over all sources: 51 queries, of them 16 GitHub, 3 commit, 2 downstream, 20 list (dev@, java-user@, issues@, commits@) and 4 JIRA, 551 distinct hits, 0 high and 16 medium, all triaged; the second and third over lists and JIRA: 24 queries each); 27 manual GitHub GraphQL phrasings over apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch and GitHub-wide; the changed-file lists of all 411 open apache/lucene PRs, none of which touches the factory; the factory's commit history on main, branch_10x and branch_10_5 (only 4e86df96c038); manual queries on the Lucene and Solr mailing lists; LUCENE and SOLR JIRA queries; GitHub code search (apache/solr has no use of the factory); 6 web queries; the intended-behaviour check's and the finder's earlier GitHub, list and JIRA searches found nothing either). Context, not reports: #297 and #11140 (introduced the factory; no review comment on mode case), #11399 / LUCENE-10363 (a different defect: filter offsets), #16416 (changes only the filter), #5942 / LUCENE-4877 (a 2013 discussion of case-insensitive enum factory arguments as a convention, 8 years before the factory), elastic/elasticsearch#81858 and opensearch-project/OpenSearch#12287 (kuromoji_completion integrations that parse index/query case-insensitively themselves and never call the Lucene factory), and the lucene-kmp Kotlin port, which silently upper-cases the configured value with no comment or report. Upstream main still has the expression (read 2026-10-26, head e1c4184cb983). Gaps: GitHub search does not index diffs, so a closed unmerged PR that silently changed the file would be missed; 4 of the 6 planned web queries were not run (6 manual web queries overlap them); private discussions are not visible, and searches cannot prove absence
- Lucene commit tested
- main
645d4fe14a20(the minimal test through gradle in a scratch worktree, assertions on and off, stock and with the fix, plus the kuromoji module's tests with the fix; also standalone); release jars 10.6.0 (assertions on and off) and 9.1.0 (assertions off) with the minimal test; earlier the hunt's tests on mainea57360912edanda9779ef3c193, 9.0.0, 9.1.0, 9.12.3, 10.0.0 and 10.5.2. Upstream main2f424fd428da(2026-10-30) has the same factory file (read).
- Finding record
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilterFactory.java:24-34 (javadoc 'mode: Completion mode. see JapaneseCompletionFilter.Mode'), :44-55 (constructor; Mode.valueOf(get(args, MODE_PARAM, DEFAULT_MODE.name().toUpperCase(Locale.ROOT))) at :46-51), :62-65 (create passes the parsed mode)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:61 (DEFAULT_MODE = Mode.INDEX), :74-79 (enum Mode { INDEX, QUERY })lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:122-124 (sibling upper-cases the configured value) and :35-43 (its javadoc example writes mode="NORMAL"); lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizerFactory.java:92-95; lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/BeiderMorseFilterFactory.java:58-59 (case-sensitive, no toUpperCase)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilterFactory.java:36 (passes only "QUERY") and TestJapaneseTokenizerFactory.java:54 (testMode passes lower-case "normal")
- The finding in 30 seconds
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilterFactory.java:24-34, :44-55, :62-65 (at 645d4fe14a20)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilter.java:61, :73-79 (at 645d4fe14a20)lucene/core/src/java/org/apache/lucene/analysis/AbstractAnalysisFactory.java:160-163 (at 645d4fe14a20)lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseTokenizerFactory.java:122-124; lucene/analysis/nori/src/java/org/apache/lucene/analysis/ko/KoreanTokenizerFactory.java:92-95 (at 645d4fe14a20)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilterFactory.java:29-39 (QUERY on 東京t gives 東京t, toukyout)
- Who is affected
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionAnalyzer.java:42; JapaneseCompletionFilter.java:87 (constructors take the enum; at 645d4fe14a20)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseTokenizerFactory.java:52-60 (testMode passes "normal")
- Why it looks unintended
lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilterFactory.java:30, :46-51; JapaneseTokenizerFactory.java:43, :122-124 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/synonym/word2vec/Word2VecSynonymFilterFactory.java:58; lucene/analysis/phonetic/src/java/org/apache/lucene/analysis/phonetic/BeiderMorseFilterFactory.java:58-59 (at 645d4fe14a20)lucene/analysis/kuromoji/src/test/org/apache/lucene/analysis/ja/TestJapaneseTokenizerFactory.java:52-60; TestJapaneseCompletionFilterFactory.java:36 (at 645d4fe14a20)GitHub API, apache/lucene issue #5942 comments of 2013-04-01 (Steven Rowe; Robert Muir), read 2026-11-01
- Prior reports
GitHub API (read-only), 2026-11-01: commits?path=...JapaneseCompletionFilterFactory.java, contents?ref=main, search/issues
- History
a Lucene clone: git rev-parse releases/lucene/10.6.0:lucene/analysis/kuromoji/src/java/org/apache/lucene/analysis/ja/JapaneseCompletionFilterFactory.java (608bc5a1be39)GitHub API (read-only), 2026-11-01: contents of the factory at upstream main (blob 608bc5a1be39), commit list (only 4e86df96c038)
- TestJapaneseCompletionFilterFactoryLowerCaseMode.java (JUnit, one test):
repro/LFV-335/src/org/apache/lucene/analysis/ja/TestJapaneseCompletionFilterFactoryLowerCaseMode.java(32 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output.
assets/LFV-335/bug.png(378 KB)