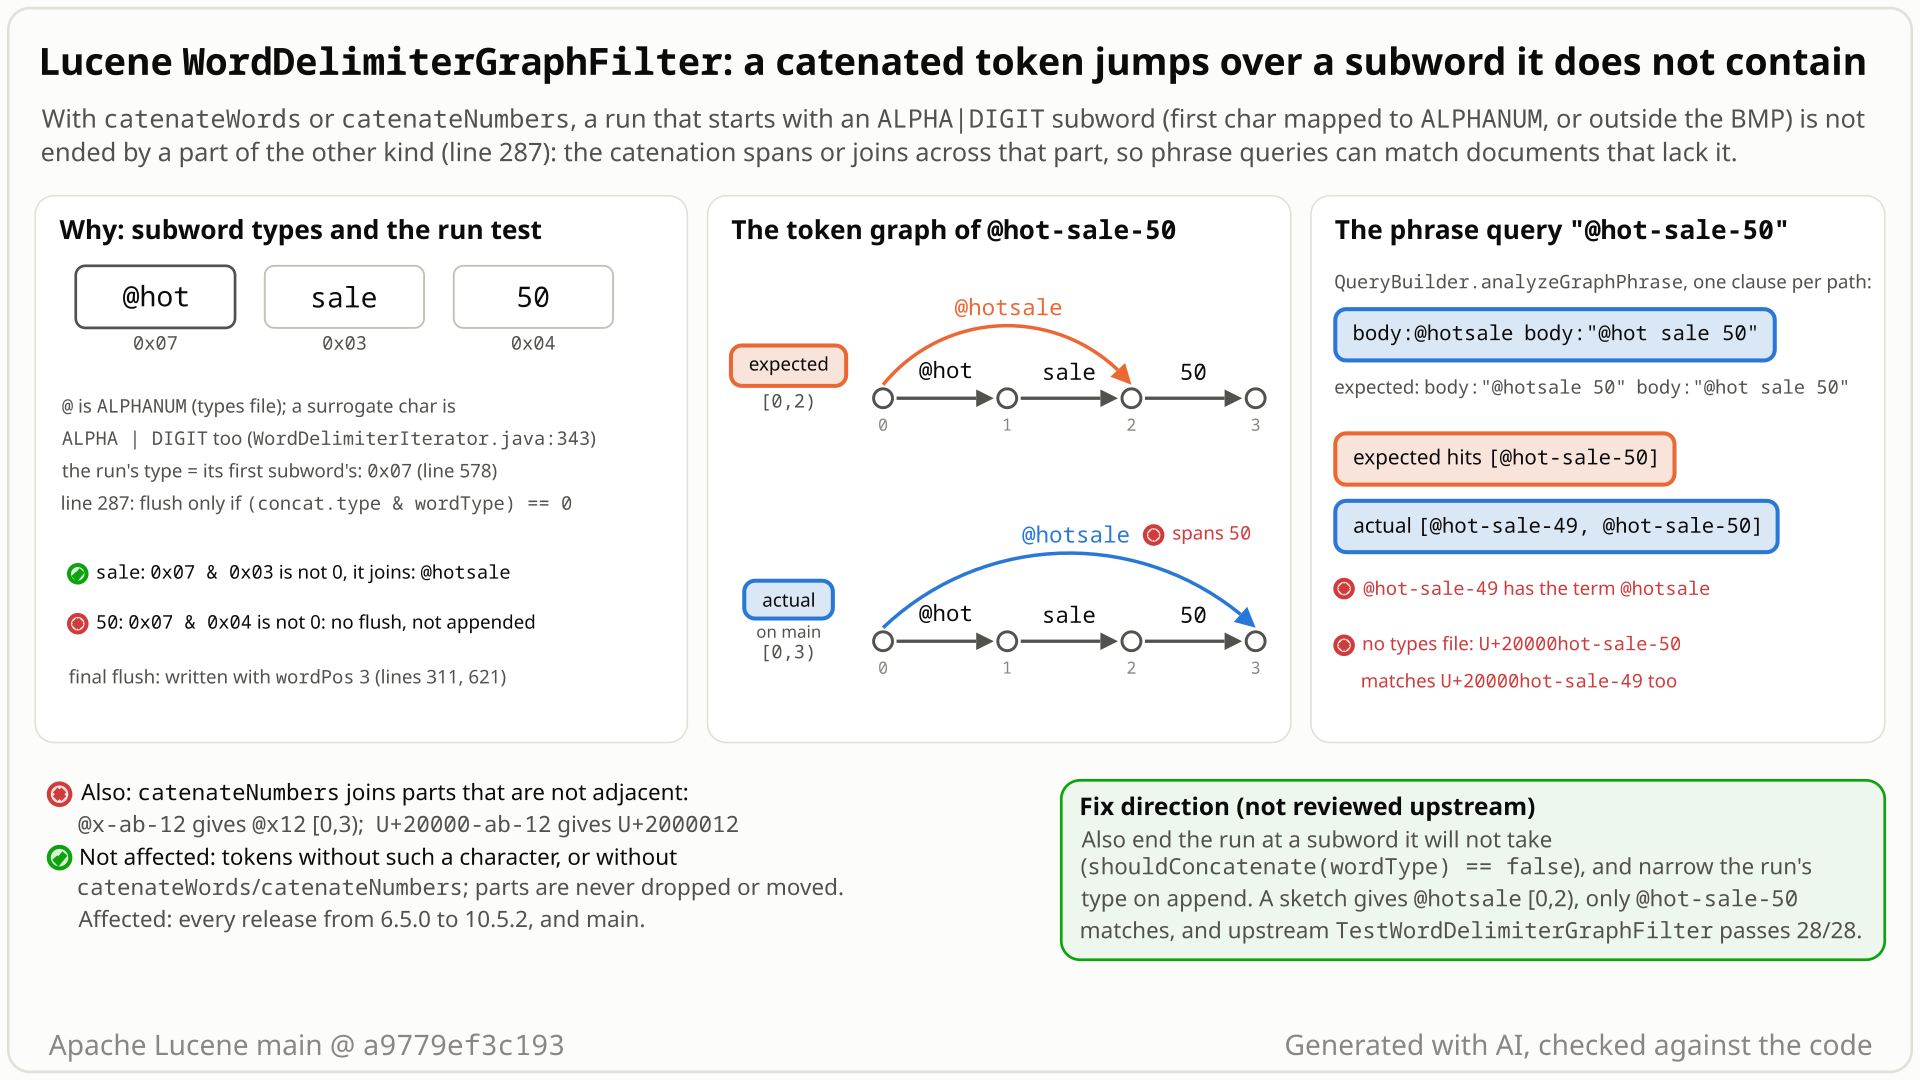
With CATENATE_WORDS or CATENATE_NUMBERS, the filter adds one glued token per run of neighbouring parts of one kind (words or numbers), placed over exactly the parts it contains. A first part typed ALPHA|DIGIT breaks that.
- You split hashtags with
WordDelimiterGraphFilter(GENERATE_WORD_PARTS | GENERATE_NUMBER_PARTS | CATENATE_WORDS) and map#toALPHANUMin the type table, so#stays on its word:#hot-sale-50gives the parts#hot,sale,50at positions 0, 1, 2. - You expect the glued token
#hotsaleto cover positions 0-1 only, asxhot-sale-50givesxhotsaleover 2 positions. Over the five documents#hot-sale-50,#hot-sale-49,#hot-sale,xhot-sale-50,xhot-sale-49, a phrase search for#hot-sale-50should need50and find only the first. - You get
#hotsalewith position length 3: it also covers50. The query becomesbody:#hotsale body:"#hot sale 50"; its first alternative is a single term, so#hot-sale-49and#hot-salematch too: 3 of 5. - Why: here
#, like every emoji or other character outside the BMP, is typed letter and digit at once (ALPHA|DIGIT). A run that starts with such a part ends only at a part sharing no type bit with it, which never happens:50is not added, but the run stays open past it. - Other shapes, same cause:
🔥hot-sale-50needs no type table (3 of 5 hits again), and withCATENATE_NUMBERS,#x-ab-12indexes the extra term#x12, gluing two parts that are not adjacent.
Users of WordDelimiterGraphFilter or its wordDelimiterGraph factory with CATENATE_WORDS or CATENATE_NUMBERS (both off by default), on whole tokens such as hashtags or product codes that start with an emoji, a CJK Extension B letter or an ALPHANUM-mapped character and then mix word and number parts. Wrong extra terms are indexed and phrase queries over-match; deterministic, any index size.
Mechanism, terms and numbers700 words
With CATENATE_WORDS or CATENATE_NUMBERS, WordDelimiterGraphFilter adds a token that glues neighbouring parts of one kind together and places it over exactly those parts. When a catenation run starts with a part whose first character is typed ALPHA|DIGIT, that breaks. Every supplementary character (an emoji, a CJK Extension B letter) gets that type, and so does any character mapped to ALPHANUM in the type table, such as # to keep hashtags whole. Such a run never ends at a part of the other kind: the part is neither added nor allowed to close the run. So #hot-sale-50 gives #hotsale with position length 3, covering 50, which it does not contain, while xhot-sale-50 gives xhotsale over 2 positions. QueryBuilder turns that path into a single-term alternative, so the phrase #hot-sale-50 also matches #hot-sale-49 and #hot-sale: 3 of 5 test documents instead of 1. With CATENATE_NUMBERS, #x-ab-12 indexes the extra term #x12. It has been there since the filter was added in 6.5.0 (LUCENE-7619, 2017); the run logic comes from the 2010 WordDelimiterFilter rewrite, and the deprecated filter emits the same wrong catenations (#x12, and #hotsale from #hot-12-sale). Ending a run at a part it will not absorb (one condition, in both filters) fixes it; the whole analysis module passes with that change.
- Parts: the filter splits
#hot-sale-50into the word parts#hot,saleand the number part50, at positions 0, 1, 2 (withGENERATE_WORD_PARTS | GENERATE_NUMBER_PARTS). - Run and catenation: with
CATENATE_WORDS, a run of neighbouring word parts is glued into one extra token (#hotsale) whose position length should cover exactly those parts;CATENATE_NUMBERSdoes the same for number parts. - Type: each part is typed by its first character (
WordDelimiterIterator.java:190-204): ALPHA (letters), DIGIT, or both. Characters below the type table's length come from the table (256 entries by default; a factory-built table can be longer);getTypetypes the others, and it types every UTF-16 surrogate, so every supplementary character, ALPHA|DIGIT (:302-307,:342-343, "prevent splitting").ALPHANUM(:36) is the same value, and the factory'stypesoption accepts it (WordDelimiterGraphFilterFactory.java:195). A table passed to the constructor may hold any byte, so any entry with an alpha bit and the digit bit acts the same.
concatenate()sets a run's type from its first part only (WordDelimiterGraphFilter.java:576-584).- The run is flushed only when
(concat.type & wordType) == 0(:286-289); a part joins only ifshouldConcatenate(wordType):CATENATE_WORDSand an alpha bit, orCATENATE_NUMBERSand the digit bit (:292-294,:555-558). - A run typed ALPHA|DIGIT overlaps every part, so it is never flushed. With one CATENATE flag, a part of the other kind (
50) is not added, yet the run stays open; the part is still emitted and advances the position (:302-305). - At the next or the final flush (
:309-312),write()places the run from its start to the current position (:618-621), so it also covers the skipped part. Later parts of the run's kind are appended across the gap (#hot-12-salegives#hotsale). QueryBuilder.analyzeGraphPhrasemakes every graph path a SHOULD clause (QueryBuilder.java:566-583); the path through#hotsale[0,3)is one term, so the phrase gets an alternative that does not require50.
| input | flags | output | the same shape with x |
|---|---|---|---|
#hot-sale-50 (# = ALPHANUM) | words | #hotsale[0,3) + parts | xhotsale[0,2) |
🔥hot-sale-50 (U+1F525) | words | 🔥hotsale[0,3) + parts | xhotsale[0,2) |
𠀀hot-sale-50 (U+20000) | words | 𠀀hotsale[0,3) + parts | xhotsale[0,2) |
#hot-12-sale | words | #hotsale[0,3), across 12 | no catenation |
#x-ab-12 | numbers | extra #x12[0,3) | no catenation |
🔥-ab-12 | numbers | extra 🔥12[0,3) | no catenation |
#x-ab-12 | words + numbers | #xab12[0,3) (self-consistent) | xab[0,2) |
"words" is GENERATE_WORD_PARTS | GENERATE_NUMBER_PARTS | CATENATE_WORDS, "numbers" the same with CATENATE_NUMBERS. With both CATENATE flags the glued token contains every part it covers, so that combination is not claimed as a graph error. The deprecated WordDelimiterFilter has the same flush line (WordDelimiterFilter.java:336-337) and emits #x12, the emoji-plus-12 term and, with CATENATE_WORDS, #hotsale from #hot-12-sale as well (it sets no position lengths).
Exposure and likelihood388 words
- Who is exposed. Applications that run
WordDelimiterGraphFilterwithCATENATE_WORDSorCATENATE_NUMBERS: directly, through thewordDelimiterGraphSPI factory, or through a search server's word-delimiter-graph filter built on it. Both flags are off by default, so it is opt-in. - What it takes. A token kept whole by the tokenizer (the javadoc recommends
WhitespaceTokenizer) in which a catenation run starts with a part that begins with a supplementary character (emoji, CJK Extension B, mathematical alphanumerics) or with a character mapped toALPHANUM(a hashtag#or a mention@kept on its word), followed by a part of the other kind:#hot-sale-50,🔥-ab-12,#hot-12-sale. At least two parts must join the run in total, before or after the skipped part (#hot-12-sale:#hotbefore12,saleafter it); a one-part run writes no catenation when parts are generated. - Index time. Wrong extra terms:
#x12from#x-ab-12(CATENATE_NUMBERS),#hotsalefrom#hot-12-sale(CATENATE_WORDS). Word and number parts themselves are not dropped: none in 1,499,520 exhaustive checks over every flag set with a CATENATE flag; where both GENERATE flags were set, the checks also compared their positions, and none moved. - Query time, with catenation in the query analyzer: phrase queries gain an alternative that drops a part and over-match (3 of 5 documents instead of 1). Position length is not indexed, so the position-length-only case changes no indexed term.
FlattenGraphFilterconsumes it: on these examples it keeps every position, but it can change the glued token's end offset (next item). - Offsets. With
adjustInternalOffsets, the filter ends the glued token's offsets at the last part it appended, so they cover a skipped part only when a later part is appended across it:#hot-12-salegives#hotsaleoffsets 0-12, over12, while#hot-sale-50gives 0-9. AfterFlattenGraphFilterat index time,#hot-sale-50also gives 0-12, over50. With fix A: 0-9 after flattening, and no#hotsalefor#hot-12-sale. - Scale and versions. Deterministic and independent of index size; no error. Every release from 6.5.0 to 10.5.2 and main: the root-cause lines are in all 74 tagged releases, and the probe fails on 19 releases, among them the 9 untagged ones from 8.8.2 to 8.11.4.
- How likely. Rare: it needs the opt-in flags and that token shape, and nobody has reported it since 2017.
The test shows that WordDelimiterGraphFilter with CATENATE_NUMBERS catenates non-adjacent parts when a run starts with a subword typed ALPHA|DIGIT: #x-ab-12 with # typed ALPHANUM (public constructor type table) emits #x12 across the word part ab.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import static org.apache.lucene.analysis.miscellaneous.WordDelimiterGraphFilter.CATENATE_NUMBERS;
import static org.apache.lucene.analysis.miscellaneous.WordDelimiterGraphFilter.GENERATE_NUMBER_PARTS;
import static org.apache.lucene.analysis.miscellaneous.WordDelimiterGraphFilter.GENERATE_WORD_PARTS;

import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestWordDelimiterGraphFilterAlphanumCatenation extends BaseTokenStreamTestCase {

  public void testCatenateNumbersJoinsOnlyAdjacentParts() throws Exception {
    byte[] types = WordDelimiterIterator.DEFAULT_WORD_DELIM_TABLE.clone();
    types['#'] = WordDelimiterIterator.ALPHANUM;
    int flags = GENERATE_WORD_PARTS | GENERATE_NUMBER_PARTS | CATENATE_NUMBERS;
    // expected [#x, ab, 12]; actual adds "#x12", catenating "#x" and "12" across "ab"
    assertTokenStreamContents(
        new WordDelimiterGraphFilter(whitespaceMockTokenizer("#x-ab-12"), false, types, flags, null),
        new String[] {"#x", "ab", "12"});
  }
}
# in a copy of this finding's repro folder (repro/LFV-337/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestWordDelimiterGraphFilterAlphanumCatenation
- Expected vs actual
- Expected tokens
[#x, ab, 12]; actual has an extra first token#x12(term 0 expected:<#x[]> but was:<#x[12]>), with-eaand-da; passes with the doc's option A fix.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => org.junit.ComparisonFailure: term 0 expected:<#x[]> but was:<#x[12]>
       org.junit.Assert.assertEquals(Assert.java:117)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:262)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:689)
org.apache.lucene.analysis.miscellaneous.TestWordDelimiterGraphFilterAlphanumCatenation.testCatenateNumbersJoinsOnlyAdjacentParts(TestWordDelimiterGraphFilterAlphanumCatenation.java:32)- The javadoc places a word catenation "at the same position of the last subword in the run", limits number catenation to "adjacent digit sequences" and promises a graph "so that e.g. PhraseQuery can work correctly".
- A plain first letter (
xhot-sale-50) gives the right output. - No test pins this output; with the fix all 1,913 module tests pass.
The full argument324 words
- The javadoc.
CATENATE_WORDS: "maximum runs of non-numeric subwords are catenated and produced at the same position of the last subword in the run".CATENATE_NUMBERS"works like CATENATE_WORDS, but for adjacent digit sequences". The class produces "a correct token graph so that e.g. PhraseQuery can work correctly when this filter is used in the search-time analyzer" (WordDelimiterGraphFilter.java:38-40,:67-76).#hotsale[0,3)ends at50, not at the last part of its run;#x12glues parts that are not adjacent; the phrase over-matches. Under any reading of ALPHA|DIGIT (word, number or both), a glued token must not cover a part it does not contain. - The type is legitimate input. The surrogate typing exists to keep a surrogate pair from being split ("prevent splitting", SOLR-1078, 2009, whose tests set no CATENATE flag). Upstream
testSplitscovers supplementary input ("don't split supplementaries into unpaired surrogates",TestWordDelimiterGraphFilter.java:218-219). The factory documents thetypesoption and parsesALPHANUM; SOLR-2059, which added the option in 2010, mapped\u200D => ALPHANUMin its test types file. - Position length is what this filter is for. LUCENE-7619 added it "just like WordDelimiterFilter except it produces correct token graphs so that proximity queries at search time will produce correct results" (
lucene/CHANGES.txt:8407-8410). Upstream fixed another graph defect of the filter as a bug (LUCENE-8395, a spurious hole withPRESERVE_ORIGINAL, listed under Bug Fixes in 7.5.0) and changed its token order twice as improvements (LUCENE-9006 and LUCENE-9458). - Nothing pins the current output. No upstream test checks the output for such input.
testRandomStringsandtestRandomHugeStringsdo feed random text, supplementary characters included, through random flags, but only check token-stream consistency and skip position length ("TODO: properly support positionLengthAttribute",TestWordDelimiterGraphFilter.java:703-756); theslowWDFreference oftestRandomPathstypes surrogates as delimiters, and its random text is ASCII only (:826-837,:1105-1139); no test of the module maps a character toALPHANUM. With the fix, all 1,913 tests of the module pass.
The devil's-advocate check267 words
The checkers built the strongest case for "intended": (a) the flush test is bitwise on purpose, an ALPHA|DIGIT part is meant to be compatible with both run kinds, and with both CATENATE flags the output is self-consistent (#xab12[0,3)); (b) the logic is inherited unchanged from WordDelimiterFilter (2010), and LUCENE-8730 made the two filters' output identical except for position length; (c) the ALPHANUM constant is commented "combinations: for testing, not for setting bits"; (d) a committer wrote in 2018 that the filter "is really only suitable for categorizing characters in the BMP, it just doesn't split surrogates"; (e) the javadoc suggests CATENATE options in the index analyzer, not the query analyzer.
Why it fails: (a) explains why such a part may join either kind of run, not why a run may skip a part and still cover it; nothing in the code, comments, tests or history covers that case, and the recommended fix leaves the both-flags output exactly as it is. (b) Parity explains the identical #x12 in the deprecated filter, but position length is precisely the attribute that is wrong; the fix changes both filters, so parity stays. (c) The class itself returns ALPHA|DIGIT for every surrogate, and the factory's public parser accepts ALPHANUM. (d) The type-table trigger is plain ASCII, and the 2018 thread was about BMP symbols deleted as delimiters, not catenation. (e) The javadoc calls index-only catenation "One way", promises a correct graph in the search-time analyzer, and the wrong extra terms are an index-time effect anyway. Every checker rejected the case; the cross-model reviews and the adjudication rated it moderate.
Recommended A. End the run at a part it will not absorb (WordDelimiterGraphFilter and WordDelimiterFilter)
End a run at a part it will not absorb: add || shouldConcatenate(wordType) == false to the run-flush test of WordDelimiterGraphFilter, and the same in the deprecated WordDelimiterFilter. Output changes only when one CATENATE flag is set and the run starts with an ALPHA|DIGIT part. Validated: the new tests pass, as do all 1,913 module tests and check.
-        // do we already have queued up incompatible concatenations?
-        if (concat.isNotEmpty() && (concat.type & wordType) == 0) {
+        // do we already have queued up incompatible concatenations? A run also ends at a subword it
+        // will not absorb: a run that starts with an ALPHA|DIGIT subword overlaps both kinds
+        if (concat.isNotEmpty()
+            && ((concat.type & wordType) == 0 || shouldConcatenate(wordType) == false)) {
           flushConcatenation(concat);
         }
All options and trade-offs3 options · 893 words
Option A was applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off; option B is the finder's sketch, run through the repro harness only; option C was not run.
A. End the run at a part it will not absorb (WordDelimiterGraphFilter and WordDelimiterFilter) (validated by the checks) (recommended)
In WordDelimiterGraphFilter.bufferWordParts (WordDelimiterGraphFilter.java:287) and in WordDelimiterFilter.incrementToken (WordDelimiterFilter.java:337), also flush the pending run when shouldConcatenate(wordType) is false. The WDGF hunk is the one-line root-cause change the independent reproducer ran.
What it changes, by code. With only CATENATE_WORDS, a run starts only with a part that has an alpha bit; if its type is exactly ALPHA, "overlaps the run" and "will be absorbed" are the same test, so nothing changes; likewise for CATENATE_NUMBERS and DIGIT. With both flags, shouldConcatenate is true for every part, so the new clause never fires. Output therefore changes only when one CATENATE flag is set and the run's first part is typed ALPHA|DIGIT; the both-flags output (#xab12[0,3)) stays.
New output. #hot-sale-50 and 🔥hot-sale-50 give the glued token over 2 positions; #hot-12-sale gives no catenation (as xhot-12-sale); #x-ab-12 and 🔥-ab-12 with CATENATE_NUMBERS give none, in both filters; the phrase #hot-sale-50 builds body:"#hotsale 50" body:"#hot sale 50" and finds 1 of 5.
-        // do we already have queued up incompatible concatenations?
-        if (concat.isNotEmpty() && (concat.type & wordType) == 0) {
+        // do we already have queued up incompatible concatenations? A run also ends at a subword it
+        // will not absorb: a run that starts with an ALPHA|DIGIT subword overlaps both kinds
+        if (concat.isNotEmpty()
+            && ((concat.type & wordType) == 0 || shouldConcatenate(wordType) == false)) {
           flushConcatenation(concat);
         }
Trade-offs
- Indexed terms change only for the affected token shapes; an index built before the fix keeps the old terms until reindexed.
- The wrong
CATENATE_NUMBERSterms disappear from the deprecated filter too, which keeps the LUCENE-8730 output parity; fixing onlyWordDelimiterGraphFilterwould break it. - Without both GENERATE flags, fix A also changes positions in some outputs, and with
PRESERVE_ORIGINALthe original's position length: in 240 outputs with one GENERATE flag a later part moves one position, because fix A writes a part the stock run had absorbed as its own one-part catenation (U+1F600a1a1withGENERATE_NUMBER_PARTS | CATENATE_WORDS | SPLIT_ON_NUMERICS); withCATENATE_WORDS | PRESERVE_ORIGINAL,U+1F600-1-agets an original of position length 2 instead of 1, asa-1-ahas. No oracle judges these configurations. - The new test pins fix A's output; the part that holds under any reading is only that no catenation covers a part it does not contain or joins parts that are not adjacent. With option B or C its expected tokens change.
What the checks validated
- The 4 new tests pass; upstream
TestWordDelimiterGraphFilter(28) andTestWordDelimiterFilter(16) pass; assertions on and off (stock: the 4 new tests fail). - All of
:lucene:analysis:common:testwith assertions on: 340 classes, 1,913 tests, 18 skipped, 0 failures. :lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis, licenses).- Through the repro harness: the finder's repro passes 5 of 5 and the independent reproducer's suite 10 of 10.
- The hunt's exhaustive check (every string up to length 6 over
a,A,1,-, U+1F600, every value of the 9 flags belowIGNORE_KEYWORDS(0 to 511), 9,999,360 checks; the span oracle judges configurations with both GENERATE flags): stock 40,128 offset and 44,968 span violations, fix A none. Overa,A,1,-,',s(28,664,832 checks, also compared with upstream'sslowWDFreference): no mismatch on stock or with fix A, so ASCII behaviour does not change. - Everything it changes (after the fact checks): the full output of every string up to length 5 over
a,A,1,-, U+1F600 for every flag value from 0 to 511, stock against fix A: 15,024 of 1,999,360 outputs change, all with the emoji and none with both CATENATE flags; no output loses a part. Where the emoji stands alone between hyphens, fix A's output equals the stock output of the ASCII analog (emoji replaced byaunderCATENATE_WORDS, by1underCATENATE_NUMBERS) in all 47,616 comparable cases (stock: 4,512 differ).
B. Option A plus narrowing the run's type when a part joins (the finder's sketch, WordDelimiterGraphFilter only)
In concatenate(), also concatenation.type &= iterator.type() (except for the catenate-all run), so a run started by an ALPHA|DIGIT part becomes a word run or a number run once a second part joins. Run through the repro harness: the finder's repro 5 of 5, upstream TestWordDelimiterGraphFilter 28 of 28, the exhaustive check with no mismatch, and the new test 4 of 4.
Trade-offs
Also changes the both-flags output, #x-ab-12 to #xab[0,2) instead of #xab12[0,3), a change of indexed terms for a configuration whose output is self-consistent today (a semantic choice for upstream); and the sketch leaves the deprecated filter emitting #x12.
Type a surrogate pair by Character.getType(codePoint) instead of ALPHA|DIGIT.
Trade-offs
Fixes only the supplementary trigger, not the ALPHANUM type-table trigger; changes splitting for every supplementary character (an emoji is OTHER_SYMBOL, which getType types as a delimiter in its default branch, so emoji would be dropped); and the iterator works on UTF-16 chars, so it is a larger change.
Products built on this filter inherit the over-matching phrases; where an application uses such a phrase as an allow filter, it also admits the extra documents (executed through Lucene's QueryBuilder and classic QueryParser; not run on a downstream product).
A bounded-exhaustive check of the real filter: every string up to length 6 over a, A, 1, - and an emoji, times every value of the 9 flags below IGNORE_KEYWORDS (9,999,360 runs), compared with the javadoc's catenation rule. All 44,968 rule violations had a supplementary character; reading the run-flush code then gave the cause and the ALPHANUM trigger.
The method in full175 words
- Method (semi-formal): bounded-exhaustive translation validation of the stock main jar, in the hunt's unit on analysis graph filters. Every string up to length 6 over
a,A,1,-and U+1F600, as one token, with every combination of the 9 flags belowIGNORE_KEYWORDS(flag values 0 to 511): 9,999,360 checks. - Oracle, taken from the class javadoc and independent of the code: when both GENERATE flags are set, a token spanning positions
[p, p+len), other than the preserved original, must equal the parts at those positions glued together. Further checks covered graph invariants, offsets withadjustInternalOffsets, and agreement with upstream'sslowWDFreference. - Signal. 44,968 span violations and 40,128 offset violations, all on texts with a supplementary character; the 28.7 million checks without one found none and matched the reference exactly.
- Root cause by reading the run-flush test and
WordDelimiterIterator.getType, which also showed that a character mapped toALPHANUMgives the same type. The finder then wrote the public-API JUnit and the fix sketch; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-26, 254 queries over GitHub issues and PRs, JIRA, the Lucene and Solr lists, downstream trackers, the web and all 411 open PRs). Closest: a 2018 java-user thread about BMP emoji being deleted as delimiters, a different code path.
Searches6 searches
40 plausible hits were read; none describes this bug. Keyword search only: GitHub search does not index PR review comments, GitHub's search rate limit was saturated (covered by GraphQL searches), and private lists cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search (four runs) | 2026-10-26 | lists, JIRA, GitHub issues, PRs and commits, downstream trackers | no report |
| GitHub (GraphQL) | 2026-10-26 | 80 issue and PR searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch and all of GitHub, including title lists of every WordDelimiter* issue; the changed-file lists of all 411 open apache/lucene PRs | no report; open PR #202 (removes WordDelimiterFilter) changes one javadoc sentence (two lines) of the graph filter |
| Mailing lists | 2026-10-26 | 78 searches: dev@, java-user@, issues@lucene; solr-user@; users@ and dev@solr | no report; the closest is the 2018 java-user thread "WordDelimiterGraphFilter swallows emojis" (BMP emoji typed as delimiters and deleted; no catenation or position length) |
| JIRA (LUCENE, SOLR) | 2026-10-26 | 11 REST searches; all 23 WordDelimiter* bug tickets reviewed | no report; SOLR-1078, SOLR-2059 and SOLR-3102 introduced or documented the types involved; SOLR-1706 was an ASCII off-by-one fixed in 2010 |
| Web | 2026-10-26 | 6 searches | no relevant hit |
| Closest items (read) | 2026-10-26 | full threads | OpenSearch#6867 (a downstream type_table entry # => ALPHANUM for hashtags, parsed as a comment), #8048 / LUCENE-6991, #9741 / LUCENE-8695 (position length is not indexed), #9776 / LUCENE-8730, #10049 / LUCENE-9006, #10498 / LUCENE-9458 |
Introduced with the filter itself, LUCENE-7619 (637915b890d9, 2017-01-17), first released in 6.5.0; it copied the run logic of the 2010 WordDelimiterFilter rewrite. Fails on every tested release from 6.5.0 to 10.5.2 and on main; the deprecated filter's wrong number catenations go back to 4.0.0. Not fixed upstream.
Versions tested7 rows
Introduced by LUCENE-7619 (now #8670), "add WordDelimiterGraphFilter (replacing WordDelimiterFilter)": master 637915b890d9 and branch_6x 4e4ec082caa7, both 2017-01-17, committed from JIRA patches (no PR). It kept the run logic of WordDelimiterFilter and added position lengths, which is where the run's late end shows.
Older roots. The WordDelimiterFilter rewrite 65a21459a258 (svn r922957, 2010-03-14, credited to SOLR-1657 and SOLR-1706) made a run's type its first part's type and ended a run only on zero overlap. The surrogate typing came from SOLR-1078 (79414d2b7263, 2009, "prevent splitting"), harmless under the earlier run algorithm (code reading); the types option with ALPHANUM from SOLR-2059 (2010).
Not fixed upstream. At a9779ef3c193 (main, 2026-10-26), the last commits to WordDelimiterGraphFilter and WordDelimiterFilter are from 2023-11-14 (stray semicolons) and to WordDelimiterIterator from 2024-08-16 (formatting); the factory's later commits rename a static field, expand wildcard imports and change a javadoc tag. The three root-cause lines are unchanged in all 74 tagged releases from 6.5.0 to 10.5.2; the 9 releases from 8.8.2 to 8.11.4 have no tag in the history clone and were run instead. The search-time over-match was executed on 9.12.3, 10.0.0, 10.5.2 and main only; on older releases the token graph is the same and the search effect is inferred.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 4 of 4 fail through gradle (assertions on and off); probe: #hotsale[0,3), phrase 3 of 5 |
| 10.5.2, 9.12.3 | affected | new test 4 of 4 fail; the finder's and the reproducer's JUnit fail |
| 10.0.0 | affected | version-independent probe 4 of 4 violations; the reproducer's JUnit fails 7 of 10, including the phrase false positive |
| 6.5.0, 6.5.1, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0, 8.11.1, 8.11.2, 8.11.3, 8.11.4, 9.0.0 | affected | version-independent probe: 4 of 4 trigger cases violate the span rule, 3 ASCII controls pass (assertions on; 6.5.0 also off; 8.8.2 to 8.11.3 run after the fact checks) |
| 6.4.2 | no such class | WordDelimiterGraphFilter does not exist yet |
| WordDelimiterFilter 4.0.0, 4.10.4, 5.5.5, 6.4.2, 6.5.0, 7.7.3, 8.8.2-8.11.4 (9 releases), 9.12.3, 10.5.2, main | terms only | the deprecated filter emits the same non-adjacent catenations (#x12; #hotsale from #hot-12-sale); it sets no position lengths; its flush line is in every tag from 4.0.0-alpha |
fix A on main a9779ef3c193 | not affected | 48 of 48 WordDelimiter tests and 1,913 module tests pass; exhaustive check: no violation |
An independent reproducer (own 10-case suite), a works-as-designed review by a reviewer from another model family, an intended-behaviour devil's advocate, an adjudication and a credibility audit all judged it real; the reproducer, the devil's advocate, the adjudication and the audit re-ran it on main. A read-only refute review said "not real" only because it could not run code.
Checks and verdicts476 words
Every verdict below that re-ran a repro did so on main ea57360912ed, whose analysis module is identical to a9779ef3c193; the reading-only cross-model reviews were followed by a separate re-run of the repro (fails). This doc's own fix validation ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (medium), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it could run no command, so it could not vote real. It agreed with the root cause, found the inputs within the contract and rated the intended-behaviour case moderate. A separate run re-ran the repro: fails. |
| Independent reproducer | real | Own public-API suite outside the filter's package (7 defect cases, 3 ASCII controls): 7 of 10 fail on main with assertions on and off, on 10.5.2 and on 9.12.3. Used the CJK letter U+20000 to avoid the "is an emoji a word" question, executed the phrase false positive, and found the one-line root-cause change (10 of 10 pass with it). |
| Works-as-designed review | real (medium) | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens, reading only: the "ALPHA|DIGIT joins both kinds / output parity" case is moderate and does not hold. Separate re-runs fail with assertions on and off. |
| Intended-behaviour devil's advocate | real (high) | High that the wrong position length and the non-adjacent catenations are not intended, moderate on the exact output upstream will want. Own probe: #hot-sale-50 with # typed ALPHANUM through the factory gives #hotsale[0,3). |
| Adjudication | confirmed (high) | Re-ran the reproducer's suite on main with assertions on and off: 10 run, 7 failed each, controls pass. |
| Credibility audit | keep | Re-ran both suites on main: the reproducer's with assertions on and seed DEADBEEF (10 run, 7 failed), the finder's with assertions off and a new seed, 1234ABCD (5 run, 4 failed); code trace confirms the run-flush root cause; score kept. |
| Fix validation (this doc) | fix A passes | Gradle in a scratch worktree of a9779ef3c193: stock 4 of 48 WordDelimiter tests fail; fix A 0 of 48, the whole module 0 of 1,913, check -x test passes; the exhaustive check finds no violation with fix A. |
| Fact checks of this doc | reproduced; corrections applied | An independent fact check re-ran the doc's gradle command in its own scratch worktree (4 of 4 fail, assertions on and off), fix A with the WordDelimiter suites (48 of 48 pass) and the whole module (1,913 tests, 0 failures), and its own probe of every table row and phrase result. A second one, by another model family (OpenAI GPT-5.6, read-only), re-read the sources and logs. A diagram check compared the diagram with the code and the runs. All found the bug as described; their corrections are applied, and the missing 8.x releases and fix A's full effect were run afterwards. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 454 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,360 words
- Registry title
- WordDelimiterGraphFilter catenates non-adjacent subwords and gives catenations a too-long position length when a catenation run starts with a subword typed ALPHA|DIGIT (any supplementary character such as an emoji, or a character mapped to ALPHANUM in a types table), so graph phrase queries can match documents that lack a subword (released since 6.5.0)
- Area
- analysis / WordDelimiterGraphFilter catenation runs (CATENATE_WORDS, CATENATE_NUMBERS; WordDelimiterIterator character types; factory 'types' option; term-level half shared with the deprecated WordDelimiterFilter)
- Priority
- Low, rank 480: WordDelimiterGraphFilter with opt-in catenation emits non-adjacent catenations only for a specific supplementary or ALPHANUM-mapped token shape, which is silent but rare, so it sits with the rare-input rows.
- Impact class
- silent wrong results
- Impact note
- Applications that run WordDelimiterGraphFilter with CATENATE_WORDS or CATENATE_NUMBERS (both off by default) on a delimited token whose catenation run starts with a supplementary character (emoji, CJK Extension B, mathematical alphanumerics) or with a character mapped to ALPHANUM in a types table, and then switches between word and number parts (e.g. U+1F600hot-sale-50, @x-ab-12), silently index wrong extra catenated terms (CATENATE_NUMBERS; the deprecated WordDelimiterFilter does the same) and, with catenation in the query analyzer, get graph phrase queries with an alternative that drops a subword and so return false-positive hits; deterministic, ordinary scale, every release from 6.5.0 through 10.5.2 and main.
- Summary
- You run WordDelimiterGraphFilter with CATENATE_WORDS or CATENATE_NUMBERS on a token such as 'U+20000-ab-12' (a supplementary character at the start) or '@x-ab-12' with '@' mapped to ALPHANUM, and expect catenations only of adjacent subwords of one kind, each placed over exactly the parts it contains, as the ASCII control 'x-ab-12' gets (xab at [0,2), no number catenation). Instead, because such a subword is typed ALPHA|DIGIT and a run started by it is never ended by a subword it does not absorb, the filter emits catenations of non-adjacent parts ('U+20000 12', '@x12', 'U+20000abcd' across '12') and catenations whose position length also covers the skipped part ('U+20000ab' at [0,3), over '12'). At search time QueryBuilder turns that graph into a phrase query with a bare-term alternative, so the phrase 'U+20000hot-sale-50' also matches a document 'U+20000hot-sale-49' (executed).
- Introduced
- 637915b890d9 (LUCENE-7619, 'add WordDelimiterGraphFilter (replacing WordDelimiterFilter)', master; branch_6x backport 4e4ec082caa7 the same day; committed from JIRA patches, no GitHub PR; the issue is now #8670) [read: git log -L and copy-aware blame; exec: 6.4.2 has no WDGF, 6.5.0 fails]. The run logic it copied is older: the WordDelimiterFilter rewrite 65a21459a258 (svn r922957, 2010-03-14, credited to SOLR-1657 and SOLR-1706) made a run's type the type of its first subword and ended a run only when (concat.type & wordType) == 0; the SURROGATE -> ALPHA|DIGIT typing came from 79414d2b7263 (SOLR-1078, 2009-05-08, 'prevent splitting'), harmless under the pre-2010 run algorithm [read]; the factory 'types' option accepting ALPHANUM from SOLR-2059 (33cc5a041e8 / 878a697766c, 2010-08-28) (2017-01-17 (LUCENE-7619, the WDGF graph/position-length half); 2010-03-14 (r922957, the shared run logic and the term-level half); 2009-05-08 (SOLR-1078, surrogate typing); 2010-08-28 (SOLR-2059, ALPHANUM types option))
- First affected version
- 6.5.0 [exec] (first release with WordDelimiterGraphFilter; 6.4.2 does not have the class); the term-level half (non-adjacent CATENATE_NUMBERS output) in the deprecated WordDelimiterFilter since 4.0.0 [exec], the first Lucene release with WDF (Solr 3.1-3.6 by code reading only)
- Affected versions
- every WordDelimiterGraphFilter release, 6.5.0 through 10.5.2, and main ea57360912ed (not fixed). Executed with a version-independent WDGF probe (4 of 4 trigger cases violate the catenation-span oracle, 3 of 3 ASCII controls pass) on 6.5.0 (also --da), 6.5.1, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and --da) [exec]; finder JUnit fails on main (-ea, --da, 5 run / 4 failed), 10.5.2 (5/4) and 9.12.3 (9.x variant, 4/3); the independent reproduction JUnit fails 10 run / 7 failed on main (-ea, --da), 10.5.2, 9.12.3 and 10.0.0 [exec]; the three root-cause lines are present in all 74 tagged releases from 6.5.0 to 10.5.2 [read]. Deprecated WordDelimiterFilter (term-level half only, it has no position lengths): fails on 4.0.0, 4.10.4, 5.5.5, 6.4.2, 6.5.0, 7.7.3, 8.11.4, 9.12.3, 10.5.2 and main [exec]; flush line in all 123 tagged releases from 4.0.0-ALPHA [read]. The search-time false positive was executed on 9.12.3, 10.0.0, 10.5.2 and main only (inferred for 6.5-9.x). Upstream main e1c4184cb98 (2026-10-26) has no change to the three files since 2024-08-16 (formatting only) [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record, 254 read-only queries: a scripted prior-report search in four runs (lists, JIRA, GitHub issues/PRs/commits, downstream), 80 GitHub GraphQL issue/PR searches over apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch and all of GitHub (including in:title lists of every WordDelimiter* issue), 78 Pony Mail searches (dev@, java-user@, issues@, solr-user@, users@ and dev@solr), 11 JIRA REST searches (all 23 LUCENE/SOLR WordDelimiter* bug tickets reviewed), 6 web searches, the changed-file lists of all 411 open apache/lucene PRs; 40 plausible hits read, all same_bug false). Closest items, none this bug: java-user@ thread 'WordDelimiterGraphFilter swallows emojis' (2018-07-03; BMP symbols typed as delimiters and deleted; a committer replied that the filter 'is really only suitable for categorizing characters in the BMP, it just doesn't split surrogates'; no catenation, position length or ALPHANUM); SOLR-1078 (added the surrogate typing), SOLR-1706 (ASCII wrong-token off-by-one fixed in 2010), SOLR-2059 and SOLR-3102 (types file with ALPHANUM), OpenSearch#6867 (a downstream factory parses '# => ALPHANUM' as a comment), #8048/LUCENE-6991, #9741/LUCENE-8695, #9776/LUCENE-8730, #10049/LUCENE-9006, #10498/LUCENE-9458; the only open PR touching these files, #202 (removes WordDelimiterFilter), changes one javadoc line of WordDelimiterGraphFilter.java; upstream main e1c4184cb98 still has the same code
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: a new 4-test class with the upstreamTestWordDelimiterGraphFilterandTestWordDelimiterFilter, assertions on and off (stock: 4 of 48 fail; fix A: 0), fix A with all of:lucene:analysis:common:test(1,913 tests, 0 failures) andcheck -x test; the worktree was removed afterwards. The new test through the repro harness on 9.12.3, 10.5.2 and main (-ea,-da); the hunt's exhaustive harness on main, stock and with fix A (38,664,192 checks each); the hunt's version-independent probe on 19 releases from 6.5.0 to 10.5.2, among them all 9 releases from 8.8.2 to 8.11.4 that have no tag in the history clone, and main (hunt commitea57360912ed, whose analysis module is identical); after the fact checks, a stock-versus-fix-A comparison of the full output on 1,999,360 inputs and aFlattenGraphFilterprobe; OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:38-42 (class javadoc: correct token graph so PhraseQuery works at search time), :67-77 (CATENATE_WORDS 'maximum runs of non-numeric subwords ... produced at the same position of the last subword in the run'; CATENATE_NUMBERS 'for adjacent digit sequences'), :283-294 (flush test '(concat.type & wordType) == 0' at :287, shouldConcatenate gate), :555 (shouldConcatenate), :576-584 (concatenate(): run type set from the first subword only)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterIterator.java:190-204 (type() uses the first char's type), :342-343 ('case Character.SURROGATE: // prevent splitting' returns ALPHA | DIGIT), :34-36 (ALPHANUM constant)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:195 (parseType accepts 'ALPHANUM')lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:337 (the same flush test in the deprecated filter)lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:566-583 (analyzeGraphPhrase: each graph path becomes a SHOULD alternative)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:38-40, :67-77, :283-312, :555-558, :576-584, :618-621 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterIterator.java:34-36, :190-204, :302-307, :342-343 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:190-198 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:336-337 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:566-583 @ a9779ef3c193
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:73 (NAME), :96-101 (catenate defaults 0) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:83-85 (WhitespaceTokenizer recommendation) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:543, :582-583, :621 @ a9779ef3c193
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:38-40, :67-77, :82-83 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterIterator.java:34-36, :342-343 @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilter.java:188-220, :826-837, :1105-1139, :1149 @ a9779ef3c193lucene/CHANGES.txt:6569-6572 (LUCENE-8730), :8407-8410 (LUCENE-7619) @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilter.java:703-756 (random tests, TODO at :724, :752) @ a9779ef3c193
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:286-294, :555-558, :576-584 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:336-352 @ a9779ef3c193
- TestWordDelimiterGraphFilterAlphanumCatenation.java (JUnit test):
repro/LFV-337/src/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilterAlphanumCatenation.java(36 lines)
assets/LFV-337/bug.png(454 KB)