- A char filter rewrites text before the tokenizer.
MappingCharFilterwith the mapa->xyturnsa bintoxy b. - Tokens need positions in the original text, for example for highlighting. So the filter records correction points while it reads, and
correctOffset(n)maps an output offset back: offset 2 (the end ofxy) becomes 1 (the end ofa). - Each correction point is computed from the one before it: a running total of how far output and input have drifted apart. The first read starts that total at 0.
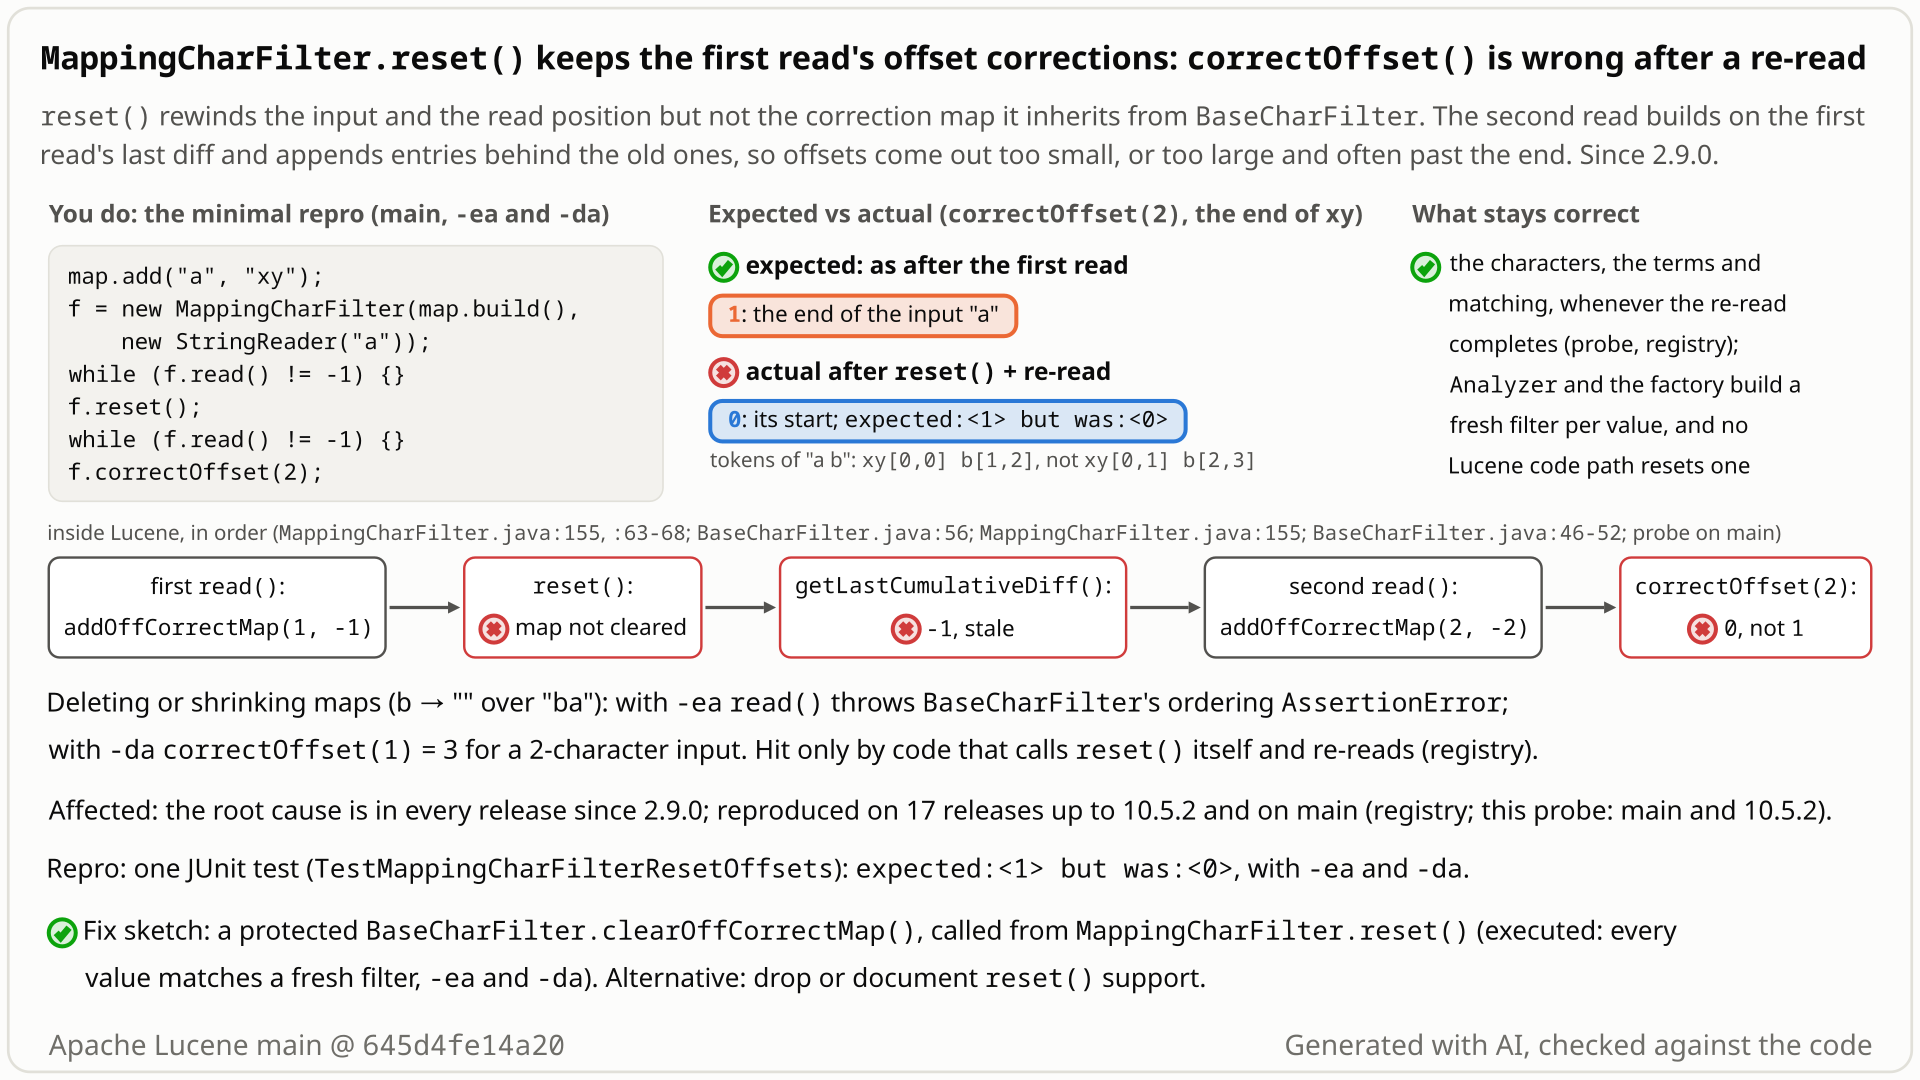
MappingCharFilter with a->xy over "a": the first read records the correction (1, -1); reset() keeps it; the second read starts from -1 and appends (2, -2), so correctOffset(2) gives 0 instead of 1. Select the still to open it at full size. Generated with AI, checked against the code.- Map
atoxyand read aMappingCharFilterover"a"to the end. The output isxy, andcorrectOffset(2)is 1: the end ofxymaps back to the end ofa. - Call
reset()and read again.MappingCharFilteroverridesreset()so it can be re-read, and Lucene's own test does this. The output isxyagain, so you expectcorrectOffset(2)= 1 again. - Instead you get 0. Through a
WhitespaceTokenizerover"a b", the re-read gives the tokensxy[0,0] b[1,2]instead ofxy[0,1] b[2,3]. - Why:
reset()rewinds the reader but keeps the list of corrections. The second read starts from the first read's running total (-1, not 0), so it appends the entry (2, -2) after (1, -1), and offset 2 now maps to 0. - Deleting maps are worse:
b->""over"ba"givescorrectOffset(1)= 3 for a 2-character input with assertions off, and anAssertionErrorinsideread()with them on. When the re-read completes, the characters and terms are right; only the offsets are wrong.
Only application code that calls reset() on a MappingCharFilter itself and reads it again. With assertions off, the offsets it then uses (correctOffset(), token offsets for highlighting) are wrong; with assertions on, the second read() can throw. No Lucene path resets a char filter. A one-character input is enough; terms and matching stay right when the re-read completes. Rare.
Mechanism, terms and numbers530 words
MappingCharFilter overrides Reader.reset() so that it can be rewound and read again. reset() rewinds the input and the read position, but not the list of offset corrections the filter inherits from BaseCharFilter. On the second read every length-changing match computes its correction from the first read's last running total and appends it to the old list.
So after reset() and a re-read, correctOffset() is wrong: for a->xy over "a" it maps the end of the output to 0 instead of 1, and a tokenizer over "a b" gives xy[0,0] b[1,2] instead of xy[0,1] b[2,3]. For deleting or shrinking maps, offsets come out too large, often past the end of the input (assertions off); with assertions on, BaseCharFilter's ordering assertion can fire inside read() and the second read never finishes. When the re-read completes, characters, terms and matching are right. No Lucene code path resets a char filter, so only application code that calls reset() itself and reads again is hit. The fix is to clear the list in reset() (8 added lines), or to drop reset() support.
BaseCharFilter.java:31-33: the correction list isprivate int[] offsets; private int[] diffs; private int size. It is private, andBaseCharFilterhas no method that clears it.BaseCharFilter.java:55-57:getLastCumulativeDiff()returnsdiffs[size - 1], the running total of the last entry.MappingCharFilter.java:142-157: for a match whose replacement has a different length,prevCumulativeDiff = getLastCumulativeDiff()(:145), and the new entries are placed and valued relative to it (:148for a shorter replacement,:153-156for a longer one).MappingCharFilter.java:62-68:reset()isinput.reset(); buffer.reset(input); replacement = null; inputOff = 0;. The list is kept.BaseCharFilter.java:59-67:addOffCorrectMapdocuments that each offset "will not be smaller than the offset given at the previous invocation";:77-87asserts it.correct()binary-searches the list (:46), which needs it sorted.
pass 1   running total  0   adds (off 1, diff -1)    list [(1,-1)]          correctOffset(2) = 2-1 = 1
reset()  input rewound, inputOff = 0                 list [(1,-1)]   kept
pass 2   running total -1   adds (off 2, diff -2)    list [(1,-1),(2,-2)]   correctOffset(2) = 2-2 = 0
For b->"" over "ba": pass 1 adds (0, +1), so correctOffset(0..1) = [1,2]. Pass 2 starts from +1 and computes (-1, +2), an offset that goes backwards. With assertions on, addOffCorrectMap throws AssertionError: Offset #1(-1) is less than the last recorded offset 0 from inside read(); with them off the list [0,-1] is unsorted, the binary search for 1 lands on the entry (-1, +2), and correctOffset(1) = 1 + 2 = 3, past the end of the 2-character input.
The characters stay right whenever the re-read completes: the characters read() returns depend only on state that reset() rewinds (input, buffer, replacement, inputOff) and on the immutable map. The stale list is read by correct() and, inside read(), by getLastCumulativeDiff(), whose value only goes into new corrections; those go through addOffCorrectMap, so with assertions on its ordering assertion can throw from inside read() (the b->"" case) before the second read finishes.
Exposure and likelihood339 words
- Trigger. An explicit
reset()on aMappingCharFilterover a reader that can rewind (such asStringReader), a second read (with assertions on, that read can already throw), and then offsets. The usereset()support was added for in 2009 was exactly this: show the normalized text, rewind, tokenize the same reader. - Not on any Lucene path.
AnalyzercallsinitReaderfor every value (Analyzer.java:155,:191),MappingCharFilterFactory.createbuilds a new filter each time (MappingCharFilterFactory.java:91), andTokenizernever rewinds its reader.MappingCharFilteris the onlyCharFilterin the source tree that overridesreset(); the others inheritjava.io.Reader.reset(), which throws. - Scale. No special setting; a one-character input is enough. Only inputs on which a length-changing mapping fires are affected (an empty input, or one the map never matches, is not), and whether a wrong value shows depends on the input, the read style, the assertion mode and the offset asked for. Over all 1,092 strings of length 1 to 6 on
{a, b, ' '}, the re-read gave wrong offsets for 966 (a->xy), 602 (b->"") and 363 (ab->x) of them with assertions off. - Effect. With assertions off, offsets too small for a longer replacement (
a->xy) and too large for deleting or shrinking maps, often past the end of the input: over the same 1,092 strings,b->""gives 516 too-large values inside the input and 774 past the end,ab->x429 and 371,a->xyonly too-small values (for exampleb->""over"baa":correctOffset(1)= 3 instead of 2). With assertions on, the secondread()instead throwsBaseCharFilter's orderingAssertionErroron 966 (b->""), 484 (ab->x) and 516 (a->xy) of those inputs. When the re-read completes, terms and matching are right. - Likelihood. Rare: nothing in Lucene resets a char filter, and the recorded searches found no report since 2009.
One JUnit class, one test method, a 1-character input, public API only, analysis-common only. It reads the filter to the end, calls reset(), reads it again and checks correctOffset(2).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.charfilter;

import java.io.StringReader;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestMappingCharFilterResetOffsets extends LuceneTestCase {

  public void testCorrectOffsetAfterReset() throws Exception {
    NormalizeCharMap.Builder map = new NormalizeCharMap.Builder();
    map.add("a", "xy");
    MappingCharFilter f = new MappingCharFilter(map.build(), new StringReader("a"));
    while (f.read() != -1) {}
    f.reset();
    while (f.read() != -1) {}
    // expected: the end of the re-read output "xy" maps to the end of the input "a" (1); actual: 0
    assertEquals("correctOffset(2) after reset()", 1, f.correctOffset(2));
  }
}
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests TestMappingCharFilterResetOffsets -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
correctOffset(2)= 1 afterreset()and a second read, as after the first read.- Observed
correctOffset(2) after reset() expected:<1> but was:<0>, with assertions on and off.
More files, environment, full output252 words
new MappingCharFilter(map, new StringReader("a")) with the map a->xy is read to the end, rewound with reset(), read to the end again, and correctOffset(2) is compared with 1, the value a fresh filter gives. Deterministic, single thread; LuceneTestCase is only the base class. This input fails the same way with assertions on and off and does not hit the ordering assertion, so the failure is the wrong value itself.
Regression test (for the recommended fix): this same class (or its one method added to TestMappingCharFilter, next to testReaderReset); it passes with the recommended fix. Dropping reset() support needs a different test (expectThrows(IOException.class, f::reset)) and testReaderReset removed or rewritten; with the documentation-only option no offset-correctness test can pass.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; release 10.6.0: fails; 9.12.3, 10.0.0, 10.5.2: the finder's longer version of this test fails; 2.9.0 to 9.0.0: a version-portable probe fails; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux aarch64 (the only platform run; plain Java, no native code) |
cp $REPRO/TestMappingCharFilterResetOffsets.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests TestMappingCharFilterResetOffsets -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
   >     java.lang.AssertionError: correctOffset(2) after reset() expected:<1> but was:<0>
   >         at __randomizedtesting.SeedInfo.seed([DEADBEEF:6D266AAE1879C9E0]:0)
   >         at junit@4.13.2/org.junit.Assert.fail(Assert.java:89)
   >         at junit@4.13.2/org.junit.Assert.failNotEquals(Assert.java:835)
   >         at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:647)
   >         at org.apache.lucene.analysis.charfilter.TestMappingCharFilterResetOffsets.testCorrectOffsetAfterReset(TestMappingCharFilterResetOffsets.java:32)

:lucene:analysis:common:test (FAILURE): 1 test, 1  failure

# standalone runner, seed DEADBEEF: main 645d4fe14a20 and 10.6.0, -ea and -da, fail with the same messageMappingCharFilteroverridesreset()on purpose, Lucene's owntestReaderResetre-reads after it, andjava.io.Readerallowsreset()withoutmark().- A
CharFilteris a Reader "with additional offset correction", yet afterreset()offsets even land past the end of the input. - In LUCENE-4321 a committer called this tested
reset()support fine;BaseCharFilter's own assertion fires insideread()after it.
The full argument239 words
- Deliberate support.
MappingCharFilter.reset()(MappingCharFilter.java:62-68) was added by LUCENE-3830 (2012) to rewind the buffer,replacementandinputOff. LUCENE-1734 (2009) first madereset()work, because its reporter wanted "to call reset() to rewind reader in SOLR-1256", and addedTestMappingCharFilter.testReaderReset(TestMappingCharFilter.java:65-79), which re-reads afterreset()and checks characters only. Its input"x"matches none of the mappings insetUp()(TestMappingCharFilter.java:41-63), so it records no corrections and could not catch this bug even if it checked offsets. - Legal Reader use. The
java.io.Reader.reset()javadoc: "If the stream has not been marked, then attempt to reset it in some way appropriate to the particular stream, for example by repositioning it to its starting point. ... some support reset() without supporting mark()". - Offsets are the point.
CharFilter.java:22-25: "They can be used as java.io.Reader with additional offset correction";MappingCharFilter.java:29-33: "correcting the resulting changes to the offsets". - Lucene's own precondition breaks.
BaseCharFilter.addOffCorrectMapdocuments and asserts non-decreasing offsets (BaseCharFilter.java:59-67,:77-87);MappingCharFilterviolates it from a plainread()afterreset(). - A committer called it supported. LUCENE-4321 (#5388, 2012), Robert Muir: "If someone (like MappingCharFilter) wants to support reset() and has tests for it (like MappingCharFilter), then thats fine" and "it supports reset() but not mark(), (only if also its input supports reset()) which is allowed". The outcome kept
MappingCharFilter.reset(). - Nothing says otherwise. No javadoc, test, CHANGES or MIGRATE entry says offsets are invalid after
reset().
The devil's-advocate check210 words
The strongest case for "intended": CharFilter does not document reset(), markSupported() is false (inherited from Reader), and java.io.Reader.reset() says nothing about a subclass's offset metadata, so a maintainer can call the second-pass offset semantics underspecified. In the same LUCENE-4321 thread Uwe Schindler wrote that Lucene does not use those methods at all and that implementing them correctly with offsets is too heavy. The only test checks characters, on an input that no mapping matches.
Why it fails: the Reader contract only shows that calling reset() is legal, not what the offsets must be; the stronger evidence is the class's purpose (offset correction), its override that rewinds every other read coordinate, and its own tripped ordering assertion. The remark argues for not supporting reset() unless it is done right, not for supporting it with wrong offsets, and the thread then kept MappingCharFilter's reset() as supported (Robert Muir, above). Offsets past the input length and a tripped internal assertion are not a defensible behaviour. Upstream may fairly prefer to drop reset() support instead of fixing it; that is a choice of fix, not evidence that the behaviour is intended. The intended-behaviour devil's advocate and the adjudication rejected the argument, and the cross-model reviewers rated their own intended-behaviour argument weak.
Recommended Clear the correction list on reset() (validated)
Clear the correction list in reset(): add a protected BaseCharFilter.clearOffCorrectMap() (sets offsets and diffs to null and size to 0) and call it from MappingCharFilter.reset(), 8 added lines. Validated on main: the repro passes with assertions on and off, as do the 64 charfilter tests (two seeds) and the whole analysis-common module.
   // BaseCharFilter
+  /** Removes all recorded offset corrections, e.g. when a subclass rewinds its input in reset(). */
+  protected void clearOffCorrectMap() {
+    offsets = null;
+    diffs = null;
+    size = 0;
+  }

   // MappingCharFilter.reset()
     inputOff = 0;
+    clearOffCorrectMap();
   }
All options and trade-offs3 options · 555 words
One fix was validated in a scratch worktree of 645d4fe14a20; the alternatives are described but not run.
A protected clearOffCorrectMap() in BaseCharFilter, called at the end of MappingCharFilter.reset(). 2 files, +8 lines.
   // BaseCharFilter
+  /** Removes all recorded offset corrections, e.g. when a subclass rewinds its input in reset(). */
+  protected void clearOffCorrectMap() {
+    offsets = null;
+    diffs = null;
+    size = 0;
+  }

   // MappingCharFilter.reset()
     inputOff = 0;
+    clearOffCorrectMap();
   }
Trade-offs
- Adds a protected method to the public abstract
BaseCharFilter; the name and shape are upstream's call. A package-private method would also work (both classes are in the same package), but subclasses in other modules could not use it. A downstream subclass may already declare aclearOffCorrectMap(): the call fromreset()is virtual and would dispatch to it (or the subclass stops compiling if the signatures clash).final, a package-private method or another name avoids that;@lucene.internalonly documents intent. - A first read is unchanged; only code that calls
reset()sees different offsets, now the same as a fresh filter's. - A bare
size = 0(the approach of the unmerged 2010 LUCENE-2788 patch) is not enough on main:offsetsstays non-null, sogetLastCumulativeDiff()would readdiffs[-1](BaseCharFilter.java:55-57). - Out of scope: if the underlying reader was
mark()ed mid-stream before it was wrapped,input.reset()returns to the mark whileinputOffrestarts at 0. - Not run: a
MappingCharFilterover anotherMappingCharFilter. By reading the source, the fix handles it (the outerinput.reset()resets the inner filter, which clears its own list, andCharFilter.correctOffsetchains the two,CharFilter.java:71-77), and no other state stays stale (replacementPointeris unused oncereplacementis null; the buffer, the FST reader andscratchArcare reset or overwritten), but no executed test checks it.
What the checks validated
Gradle --no-daemon in a scratch worktree of 645d4fe14a20, OpenJDK 25.0.3 (2026-11-01). Stock: the repro fails with assertions on and off. With the fix:
- the repro passes with assertions on and off;
org.apache.lucene.analysis.charfilter.*: 64 tests (TestHTMLStripCharFilter 36, TestHTMLStripCharFilterFactory 7, TestMappingCharFilter 18, TestMappingCharFilterFactory 2, the repro 1), 0 failures, seeds DEADBEEF and CAFEBABE;- the whole
:lucene:analysis:common:test, seed DEADBEEF: 340 test classes, 1,910 tests, 18 skipped, 0 failures (counted from the test-result XML); - the other modules with
BaseCharFiltersubclasses compile (:lucene:analysis:nori,:lucene:analysis:icu); - a probe with the fix gives the fresh filter's values after
reset()for all three cases on this page ([0,0,1];[1,2]forb->""over"ba";xy[0,1] b[2,3]), with assertions on and off; - earlier, on main
ea57360912ed: an independent 6-test JUnit (deleting and shrinking maps included) and the devil's advocate's 3-test tokenizer probe pass with the fix shadowed.
Remove the override, so reset() throws IOException("reset() not supported") from java.io.Reader, like every other CharFilter. Precedent: LUCENE-4072 (#5144), where reset() support was removed from ICUNormalizer2CharFilter before it was committed.
Trade-offs
Smallest change, but it removes behaviour that has worked for characters since 2009 and deletes testReaderReset; a breaking change, so main (11.0) with a MIGRATE note.
State that offsets are not valid after reset().
Trade-offs
Leaves the wrong offsets and the AssertionError inside read() in place.
The Lucene.NET port's MappingCharFilter.Reset() has the same structure and does not clear the correction list either (read, not run).
A bounded-exhaustive check compared MappingCharFilter's output and offsets with a reference model for every small map and input. Its reset obligation (read, reset(), read again: same output and offsets) failed 248 of its 640 reset checks (in 960 runs) at the smallest scope, while the single-pass checks held on 81 million runs. A public-API test then confirmed it.
The method in full240 words
Method: semi-formal (bounded-exhaustive translation validation, then an executed test).
- Finder. The hunt unit for analysis char filters, stemmers and tokenizers wrote a reference model of
MappingCharFilterand checked the real filter against it for every map of 1 to 3 keys (keys of up to 3 characters over{a, b}, values"",x,xy,xyz) and every input of length up to 6 over{a, b, c}: output characters,correctOffset()at every position, two chunkings of the underlying reader and two read styles. The single-pass obligations held on 81,345,432 runs. - Reset obligation. Read to the end,
reset(), read again: same output and same offsets. At the smallest scope (one 1-character key, inputs over{a, b, c}of length at most 3) it failed 248 of the 640 reset checks with assertions off and 300 of 640 with them on (the orderingAssertionError); the scope has 960 runs, and the reset is checked on 2 of each input's 3 read styles. Every violation it printed was an offset mismatch, never an output mismatch. - Confirmation. A public-API JUnit (
a->xyover"a") failed on main with assertions on and off and on 9.12.3; amain()probe failed on releases back to 4.0.0. - Hunt. Independent reproduction, cross-model reviews, an adjudication, the version-history runs, a prior-art search, a security screen, a credibility audit and a one-test minimal repro followed (see the checks below).
No prior report: 85 logged queries and reads on 2026-10-26 over GitHub (Lucene and downstream), the mailing lists, JIRA and the web, and a re-check on 2026-11-01. Upstream main still has the code, and no open PR changes either file.
Searches3 searches
Verdict new: in the recorded searches, no issue, PR, JIRA entry, list thread, commit or downstream report says that MappingCharFilter.reset() keeps BaseCharFilter's offset corrections. Closest, none of them this bug: LUCENE-4321 / #5388 (2012, the CharFilter mark/reset design discussion quoted above), LUCENE-2788 / #3862 (open since 2010, "Make CharFilter reusable"; its unmerged patch cleared the list in a reset(Reader) for reuse with a new reader), LUCENE-4072 / #5144 (reset() support dropped from ICUNormalizer2CharFilter), LUCENE-6595 / #7653 (open, single-pass end offsets at deletions), LUCENE-3971 / #5044 (a fixed single-pass final-offset bug), LUCENE-3990 / #5063 (Reader-method delegation). The Lucene.NET port has the same structure, unreported.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene; Elasticsearch, OpenSearch, Solr, Lucene.NET) | 2026-10-26 | a scripted prior-report search (18 issue/PR, 6 commit, 5 downstream queries), every apache/lucene issue and PR mentioning MappingCharFilter (23 issues) or BaseCharFilter (8 issues), the changed files of all 411 open apache/lucene PRs | background only: #5388, #3862, #5144, #7653, #5044, #5063, #2808, #4903, #16823 |
| Mailing lists, JIRA and the web | 2026-10-26 | 24 list queries (dev@, java-user@, issues@, commits@), 8 JIRA-archive queries (including the assertion text "less than the last recorded offset"), JIRA reads of 17 LUCENE issues and SOLR-1256, 8 web queries | unrelated threads; LUCENE-1734 and LUCENE-3830 are the history |
| Upstream source and open PRs | 2026-11-01 | last commits to MappingCharFilter.java and BaseCharFilter.java on upstream main (2f424fd428da); gh search issues "MappingCharFilter reset", "correctOffset reset"; gh search prs --state open MappingCharFilter, BaseCharFilter | files unchanged since 2024-05-27 (#13422) and 2021-08-25 (LUCENE-10003); no issue; open PRs #15 (ICUTransformCharFilter) and #16949 (javadoc names in charfilter/package-info.java) do not touch either file |
The root cause dates from LUCENE-1734 (6a3752feb8f, 2009), first released in 2.9.0, which made reset() rewind the input without clearing the list. LUCENE-3830 (4.0.0) added the current override; from then on the simple repro fails. All 18 releases run, from 2.9.0 to 10.6.0, fail; releases in between were not run.
Versions tested7 rows
Root cause introduced by 6a3752feb8f "LUCENE-1734: CharReader should delegate reset/mark/markSupported" (Uwe Schindler, 2009-07-06, svn era, a JIRA patch; the issue is now #2808). Before it, MappingCharFilter.reset() threw "mark/reset not supported"; after it, reset() rewound the input and kept the correction list. Nothing has cleared that list since.
Current code: LUCENE-3830 (3e9b5a9893c, Michael McCandless, 2012-05-06, #4903, first release 4.0.0) added the reset() override that rewinds the read state but not the list; LUCENE-4321 (568156b710a) changed super.reset() to input.reset() without changing behaviour (git blame of MappingCharFilter.java:62-67; the closing brace at :68 blames to 675597141b7f, an unrelated 2010 repository move, LUCENE-2326).
Before 4.0 a second stale counter mostly hid the bug on a plain read to the end (0 to 9 of 960 probe cases fail in 2.9.0 to 3.6.0; 134 to 135 of 960 for reads that stop before the end); 3.6.1 and 3.6.2 fail 133 of 960; from 4.0.0 on 569 of 960 fail with assertions on. On 2.9.0 sources, also clearing the list on reset gives 0 of 2,880 failures.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0 | affected | minimal repro fails with assertions on and off |
| 10.5.2, 10.0.0, 9.12.3 | affected | the finder's longer version of the JUnit fails (-ea and -da); probe fails |
| 9.0.0, 8.11.4, 7.7.3, 6.6.6, 5.5.5, 4.10.4, 4.0.0 | affected | cross-version probe fails: 569 of 960 read-to-end cases with -ea (396 to 538 with -da) |
| 3.6.1, 3.6.2 | affected | 133 of 960 read-to-end cases fail |
| 2.9.0, 2.9.4, 3.0.3, 3.5.0, 3.6.0 | mostly hidden | 0 to 9 of 960 read-to-end cases fail; 134 to 135 of 960 reads that stop before the end |
parent 7acabfe of the introducing commit (six classes from it shadowed onto the 2.9.0 jar, not a build); 2.4.1 | no bug | reset() refused with an IOException (2,880 of 2,880); 2.4.1 has no MappingCharFilter |
main 645d4fe14a20 with the fix | not affected | repro passes; charfilter tests and the analysis-common module pass |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication and a credibility audit each re-ran it and confirmed it; a cross-model intended-lens review judged it real. The one dissent, a read-only refute review, said "not real" only because it could not run code, and agreed on the root cause. This doc's gradle runs validated the fix.
Checks and verdicts319 words
Every verdict below re-ran a repro on stock main jars or release jars, except the reading-only cross-model reviews, for which separate runs re-ran the repro (fails).
| Check | Verdict | What it found |
|---|---|---|
| Finder | candidate | Bounded-exhaustive check: reset obligation fails 248 of 640 reset checks in 960 runs (-da), 300 of 640 (-ea), single-pass obligations hold on 81,345,432 runs; public-API JUnit fails on main (-ea, -da) and 9.12.3; the fix passes 20 upstream tests. |
| Cross-model intended-lens review | real (medium) | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: root cause agrees, inputs in contract, intended argument weak. |
| Independent reproducer | real | Own 6-test JUnit written from the claim: 4 fail, 2 controls pass, on main (-ea, -da), 10.5.2 and 9.12.3; main() probe fails on 8.11.4; exhaustive sweep of 1,092 strings; all 6 pass with the fix. |
| Cross-model refute review | not real (low), procedural | OpenAI GPT-5.6, reading only; it could execute nothing, agreed on the root cause and legal inputs and rated its intended argument weak. Every re-run of the repro fails. |
| Intended-behaviour devil's advocate | real, minor | Tokenizer probe xy[0,0] b[1,2] vs xy[0,1] b[2,3] on main and 10.5.2; argument for "intended" rejected with LUCENE-4321; 3 of 3 pass with the fix. |
| Adjudication | confirmed (high), minor | Re-ran the independent reproduction's JUnit on main with -ea and -da: 4 of 6 fail with the same messages. |
| Credibility audit, minimal repro and main refresh | confirmed; verified | The audit re-ran the finder's and the independent reproduction's JUnits (fail); the one-test class fails on 645d4fe14a20 with -ea and -da and passes with the fix; on main a9779ef3c193 the recorded replay failed as before. |
| This doc | real; fix validated | Gradle in a scratch worktree: stock fails with assertions on and off; the fix passes the repro, the charfilter tests and the analysis-common module; 10.6.0 fails; a probe re-measured every number on this page. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 486 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,591 words
- Registry title
- MappingCharFilter.reset() rewinds the input but keeps the offset corrections recorded on the first pass, so after a reset and re-read correctOffset() (and the token offsets a Tokenizer derives from it) are wrong, or BaseCharFilter's ordering assertion fires
- Area
- analysis / char filters (MappingCharFilter, BaseCharFilter offset correction)
- Priority
- Low, rank 1047: MappingCharFilter.reset() keeps stale offset corrections, which affects only direct reset-and-reread callers and only offsets.
- Impact class
- minor
- Impact note
- Only application code that calls Reader.reset() directly on a MappingCharFilter (over a resettable reader such as StringReader), reads it again and then uses offsets (correctOffset(), or token offsets from a Tokenizer over the re-read filter) is hit, at any input size and with no setting needed, on every release from 2.9.0 to 10.6.0 and on main: offsets come out too small or, with -da, past the end of the input, and with -ea BaseCharFilter's ordering assertion fires inside read(); the characters produced, the terms and matching are unaffected, and no Lucene code path (Analyzer, MappingCharFilterFactory, Tokenizer) ever resets a char filter.
- Summary
- You read a MappingCharFilter to the end, call reset() to rewind it (MappingCharFilter overrides reset() for this, and upstream TestMappingCharFilter.testReaderReset re-reads after it), read it again and expect correctOffset() to map the second pass's output back to the input exactly as on the first pass. Instead reset() rewinds the input and the filter's read state but not the offset-correction map it inherits from BaseCharFilter, so the second pass appends new corrections computed from the first pass's last cumulative diff: for the map a->xy over "a", correctOffset(2) returns 0 instead of 1, and a WhitespaceTokenizer over the re-read filter for "a b" gives xy[0,0] b[1,2] instead of xy[0,1] b[2,3]. For deleting or shrinking maps, with -ea the second read() trips BaseCharFilter's 'Offset ... is less than the last recorded offset' assertion, and with -da it returns offsets past the end of the input (b->'' over "ba": correctOffset(1) = 3 for a 2-character input).
- Introduced
- 6a3752feb8f13541603e85326db997147047b2a6 (svn r791415), LUCENE-1734 'CharReader should delegate reset/mark/markSupported' (apache/lucene#2808; a JIRA patch from the svn era, no GitHub PR), committed by uschindler for an issue reported by kojisekig: it removed MappingCharFilter's reset() that threw 'mark/reset not supported' and made reset() delegate to the input, and no commit since has cleared BaseCharFilter's correction list [exec: the parent 7acabfecf02's analysis classes shadowed on the 2.9.0 jar refuse reset() in 2880 of 2880 probe runs (no bug); the commit's classes fail 134 of 960 exact-length reads, the same as stock 2.9.0; read: git tag --contains, git log -G 'void reset\(\)' over every historical path of the file]. The current reset() override (rewinds input, buffer, replacement and inputOff, not the map) comes from LUCENE-3830 (3e9b5a9893c, apache/lucene#4903, 2012-05-06, first release 4.0.0), which made the defect visible on a plain read to EOF for most inputs [read: git blame of main MappingCharFilter.java:63-68; exec: root-cause check on 2.9.0 sources] (2009-07-06 (6a3752feb8f, commit date); the current reset() override dates from 2012-05-06 (3e9b5a9893c, LUCENE-3830))
- First affected version
- 2.9.0 [exec] (the first release with MappingCharFilter, and it already has the delegating reset(); there the bug shows only for reads that stop before EOF); the canonical read-to-EOF repro (a->xy over "a") fails from 4.0.0 on [exec]
- Affected versions
- Every release from 2.9.0 to 10.6.0, and main ea57360912ed; 10.6.0 [exec 2026-11-01]: the minimal test fails on the 10.6.0 release jars (SHA-1 checked against Maven Central) with -ea and -da. [exec] the follow-up's version-portable main() probe (8 maps x 120 inputs x 3 read styles, comparing every correctOffset(i) after reset() with the first pass) fails with -ea and -da on 2.9.0, 2.9.4, 3.0.3, 3.5.0, 3.6.0, 3.6.1, 3.6.2, 4.0.0, 4.10.4, 5.5.5, 6.6.6, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; in 2.9.0 to 3.6.0 a plain read to EOF was mostly right by luck (0 to 9 of 960 cases fail, because a second stale counter pushed the new corrections past the output end) and only exact-length reads that never see EOF showed it (134 to 135 of 960); 3.6.1 and 3.6.2 fail 133 of 960 on read to EOF; from 4.0.0 on, read to EOF fails broadly (569 of 960 with -ea; 538 with -da up to 5.5.5 and 396 from 6.6.6 on). The finder's JUnit fails on 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da) and does not compile on 9.0.0 (test-framework package missing; the probe covers it); the independent reproduction's JUnit fails 4 of 6 on main, 10.5.2 and 9.12.3 (-ea and -da); the independent reproduction's main() probe fails on 8.11.4 (-da). Not applicable: 2.4.1 and older (no MappingCharFilter: compile error) [exec]. Not fixed on upstream main (e1c4184cb983, 2026-10-26), and no open PR touches MappingCharFilter.java or BaseCharFilter.java [read].
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (verdict new, confidence high, searched 2026-10-26, read-only; upstream main checked at e1c4184cb983, 2026-10-26): 85 logged queries and reads, namely a scripted prior-report search with 18 GitHub issue/PR queries on apache/lucene, 6 commit queries, 5 downstream-repository queries (Elasticsearch, OpenSearch, Solr), 24 mailing-list queries over dev@, java-user@, issues@ and commits@lucene.apache.org, 8 JIRA-archive queries (including the assertion text 'less than the last recorded offset') and 8 web queries, plus manual GitHub searches (every apache/lucene issue mentioning MappingCharFilter (23) or BaseCharFilter (8), every PR mentioning them, the same terms on Elasticsearch, OpenSearch, Solr and Lucene.NET), the changed files of all 411 open apache/lucene PRs, JIRA REST reads of 17 LUCENE issues and SOLR-1256, and the full git history of both files; no issue, PR, commit, JIRA ticket, list thread or downstream report describes this defect, and it is not fixed upstream (last changes to MappingCharFilter.java 2024-05-27 #13422 and BaseCharFilter.java 2021-08-25 LUCENE-10003, neither touches reset() or the map). Closest context, not a report: LUCENE-4321 / apache/lucene#5388 (2012, closed), a design discussion of CharFilter mark/reset in which uschindler said implementing it correctly with offsets is hard and rmuir said MappingCharFilter's tested reset() support is fine; related, not the same: LUCENE-2788 / #3862 (open since 2010, unmerged patch that cleared the map in a reset(Reader) for reuse with a new reader), LUCENE-1734 / #2808 and LUCENE-3830 / #4903 (history), LUCENE-4072 / #5144 (reset() support dropped from ICUNormalizer2CharFilter before commit), LUCENE-6595 / #7653 (open, single-pass end offsets at deletions, no reset), LUCENE-3971 / #5044 (fixed single-pass final-offset bug), LUCENE-3990 / #5063 (Reader-method delegation), #16823 (package-doc typo)
- Lucene commit tested
- main
645d4fe14a20(2026-10-28): the minimal test fails with assertions on and off, through gradle in a scratch worktree and through a standalone runner; with the fix it passes, as do the charfilter tests (two seeds) and the analysis-common test module. Release 10.6.0 fails the same way; the follow-up's cross-version probe fails on 17 releases from 2.9.0 to 10.5.2.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/MappingCharFilter.java:29-33 (class javadoc: 'correcting the resulting changes to the offsets'), :62-68 (reset(): input.reset(), buffer.reset(input), replacement = null, inputOff = 0; the inherited correction map is not cleared), :138-158 (each length-changing match computes its correction from getLastCumulativeDiff() and calls addOffCorrectMap at :148 and :155)lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:31-33 (private offsets, diffs, size; no method clears them), :39-53 (correct(): binary search over the map), :55-57 (getLastCumulativeDiff), :59-95 (addOffCorrectMap: documented non-decreasing assumption at :62-63, assertion at :77-87)lucene/core/src/java/org/apache/lucene/analysis/CharFilter.java:22-25 (a CharFilter is a java.io.Reader 'with additional offset correction')lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestMappingCharFilter.java:65-79 (testReaderReset: reads 'x', reset(), reads 'x' again; characters only)lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:155 and :191 (initReader for every value) and lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/MappingCharFilterFactory.java:88-92 (create(): a new MappingCharFilter per reader); grep 2026-10-26: MappingCharFilter is the only CharFilter subclass under lucene/*/src/java that overrides reset()
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/MappingCharFilter.java:29-33, :62-68, :142-157a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:31-33, :41-57, :59-87
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:155, :191 (initReader per value)a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/MappingCharFilterFactory.java:91 (new MappingCharFilter per create)a Lucene main checkout (645d4fe14a20) grep of every CharFilter subclass under src/java: only MappingCharFilter overrides reset() (2026-11-01)
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/MappingCharFilter.java:29-33, :62-68a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:59-67, :77-87a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/CharFilter.java:22-25a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestMappingCharFilter.java:65-79 (testReaderReset: characters only)a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/test/org/apache/lucene/analysis/charfilter/TestMappingCharFilter.java:41-63 (setUp mappings: none matches "x")OpenJDK 25.0.3 src.zip java.base/java/io/Reader.java:583-598 (reset() javadoc; default throws IOException("reset() not supported"))GitHub (read-only, 2026-11-01): gh issue view 5388 --comments (LUCENE-4321: Uwe Schindler's and Robert Muir's quoted comments)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/analysis/common/src/java/org/apache/lucene/analysis/charfilter/BaseCharFilter.java:55-57, :70-71 (getLastCumulativeDiff reads diffs[size - 1] when offsets != null; arrays of 64)a Lucene main checkout (645d4fe14a20) lucene/core/src/java/org/apache/lucene/analysis/CharFilter.java:71-77 (correctOffset chains through input CharFilters); MappingCharFilter.java:40-44, :62-68, :76-79 (other read state)OpenJDK 25.0.3 src.zip java.base/java/io/Reader.java:596-598 (default reset() throws)
- Prior reports
GitHub (read-only, 2026-11-01): commits?path= for MappingCharFilter.java (f394c9418e1e, #13422) and BaseCharFilter.java (8ac26737913d, LUCENE-10003); main at 2f424fd428da; gh search issues/prs as listed; gh pr view 16949 (files: no MappingCharFilter.java or BaseCharFilter.java)
- TestMappingCharFilterResetOffsets.java (one test class):
repro/LFV-338/src/org/apache/lucene/analysis/charfilter/TestMappingCharFilterResetOffsets.java(34 lines)
Made in parallel with this doc, from the code at 645d4fe14a20 and an instrumented trace run on main (the addOffCorrectMap calls and the list after each read, with assertions on and off and with the fix).
assets/LFV-338/bug.png(486 KB)