- A hunspell dictionary is two files: the
.dicword list and the.afffile with rules. Lucene'sDictionaryreads both, for stemming (HunspellStemFilter) and spell checking. - Many
.affrules come as counted tables: a header line says how many entry lines follow.REP 2announces two replacement entries such asREP a bandREP c d. PFX/SFX (prefix and suffix rules), MAP, ICONV/OCONV, COMPOUNDRULE, BREAK and CHECKCOMPOUNDPATTERN work the same way. - The parser reads exactly the announced number of lines after the header. If the file ends sooner, there is no next line: Java's
readLine()returnsnull.
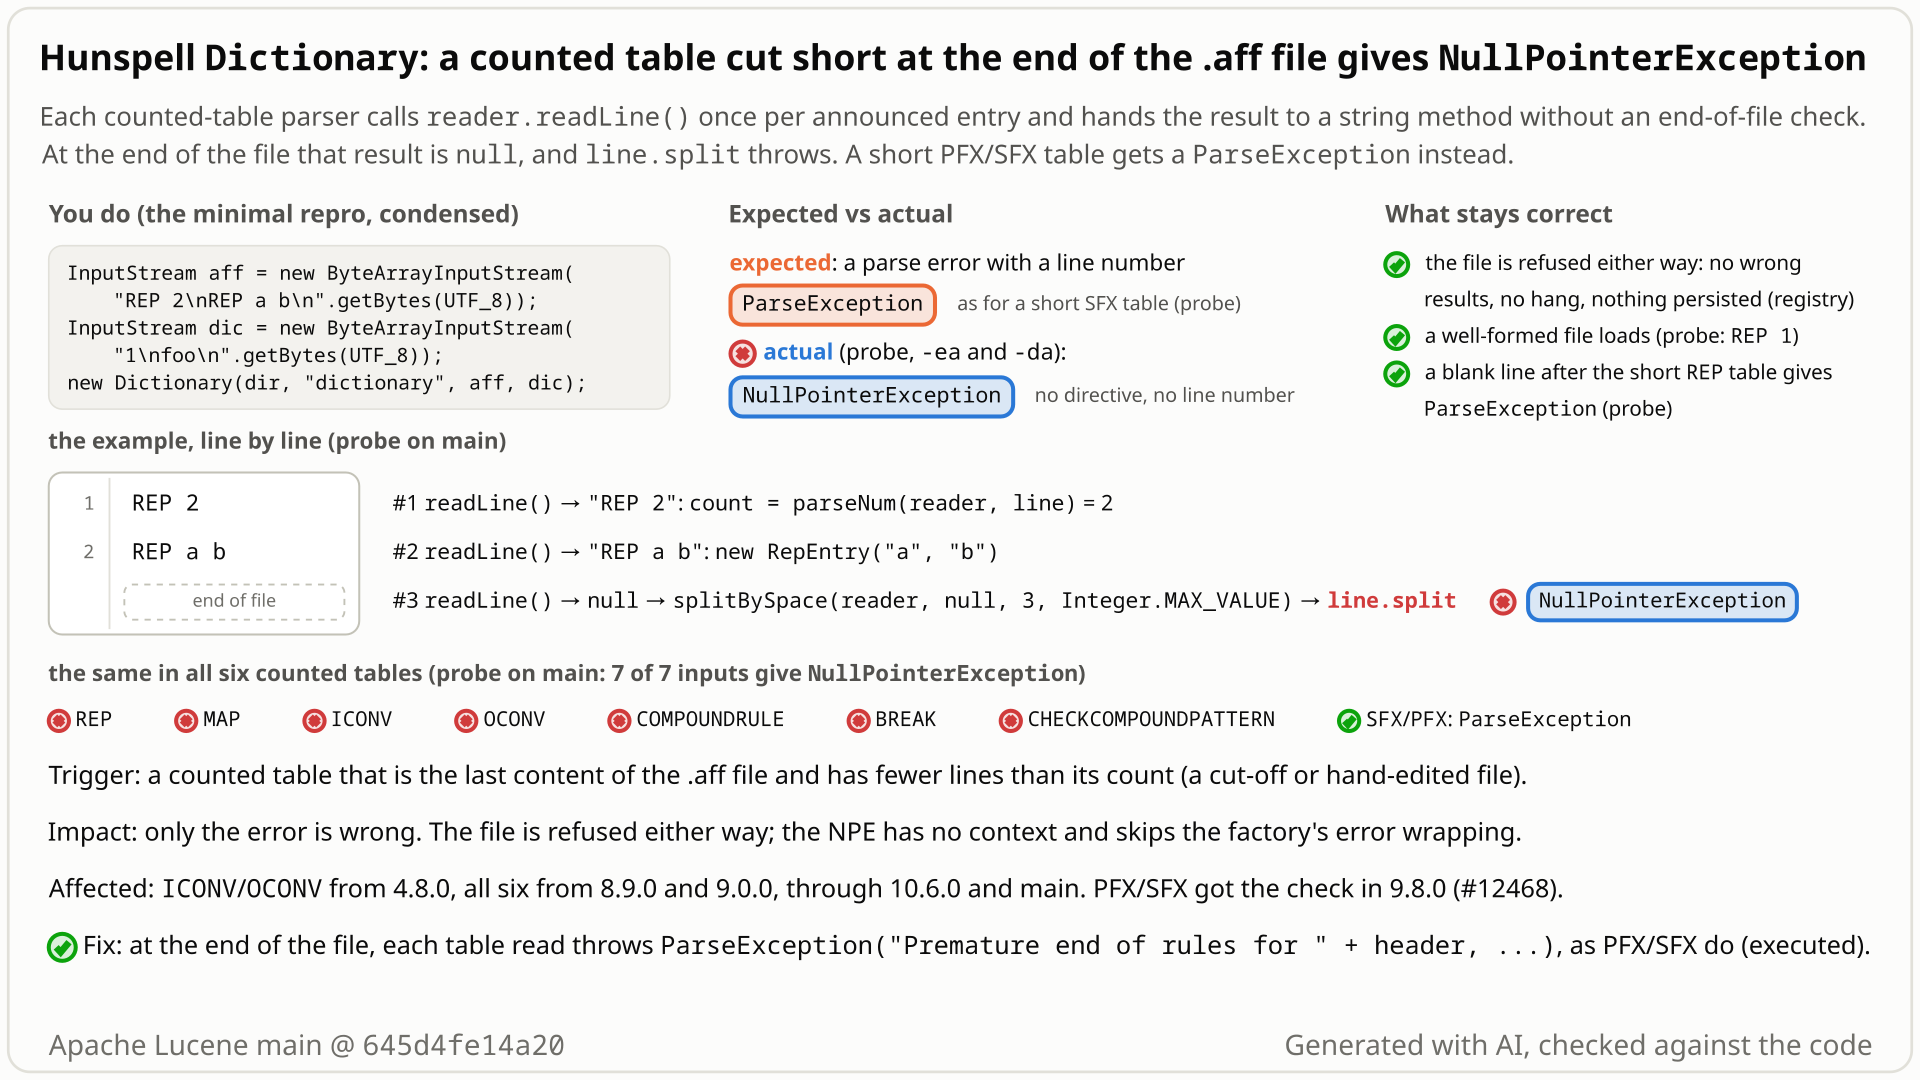
- Load a hunspell dictionary whose
.afffile is two lines,REP 2thenREP a b: a replacement table that announces 2 entries, holds 1, and the file ends there (a cut-off download, or an entry deleted without fixing the count). - You expect a parse error. Lucene documents that a wrong REP count gives a
ParseExceptionby default, and the same mistake in a suffix table (SFX A Y 2, then one rule) givesParseException: Premature end of rules for SFX A Y 2. - Instead the parser asks for the second entry, gets
nullbecause the file has ended, and splits it:NullPointerException: Cannot invoke "String.split(String)" because "line" is null. No table name, no line number, andHunspellStemFilterFactory's "Unable to load hunspell data!" wrapper is skipped. - MAP, ICONV, OCONV, COMPOUNDRULE, BREAK and CHECKCOMPOUNDPATTERN fail the same way. Add one blank line after
REP a band the same mistake givesParseException: Invalid syntax. Every release since 4.8.0 (ICONV/OCONV) or 8.9.0 (the other five) has it, up to 10.6.0 and main.
Users of the opt-in hunspell component, through any Dictionary constructor or HunspellStemFilterFactory, whose .aff file ends inside one of these six tables with fewer lines than announced: a cut-off download or a hand edit. Rare: a well-formed file never triggers it, and the damaged file is refused either way; only the error is wrong.
Mechanism, terms and numbers617 words
Several hunspell .aff directives are counted tables: a header such as REP 2 announces how many entry lines follow. Dictionary.readAffixFile reads those lines with reader.readLine() and passes the result straight to a string method, with no end-of-file check, for REP, MAP, CHECKCOMPOUNDPATTERN, COMPOUNDRULE, BREAK and ICONV/OCONV. When the file ends before the announced lines are all there, readLine() returns null and splitBySpace (or the CheckCompoundPattern constructor) throws NullPointerException: Cannot invoke "String.split(String)" because "line" is null. So the two-line affix file REP 2 / REP a b makes every Dictionary constructor throw an NPE that names no table and no line, and HunspellStemFilterFactory lets it escape unwrapped. The PFX/SFX parser has had the check since #12468 (9.8.0) and throws ParseException: Premature end of rules for ..., and since #14079 (10.2.0) the tolerateRepRuleCountMismatches() javadoc says a wrong REP count gives a ParseException by default. The unchecked reads date from each parser's first commit (ICONV/OCONV in 4.8.0, the other five in 8.9.0 and 9.0.0), and every release since, including 10.6.0, and main are affected. The file is refused either way; only the error is wrong. The same null check that PFX/SFX have, at the six table reads, fixes it.
- Counted table: a header
<DIRECTIVE> <count>followed by<count>entry lines, for exampleREP 2/REP a b/REP c d(replacement suggestions),MAP(groups of similar characters),ICONV/OCONV(input and output conversions),COMPOUNDRULE,BREAK(word-break characters),CHECKCOMPOUNDPATTERN, and the prefix/suffix tablesPFX/SFX. - Strict mode: the default.
tolerateRepRuleCountMismatches()andtolerateAffixRuleCountMismatches()returnfalseunless a subclass overrides them; the other five tables have no tolerant mode.
readAffixFilereads the file line by line (Dictionary.java:350at645d4fe14a20), trims each line, skips blank ones (:355-356) and dispatches on the first word.- Each counted-table branch parses the count and then reads that many lines itself, passing
reader.readLine()straight on: REPsplitBySpace(reader, reader.readLine(), 3, Integer.MAX_VALUE)(:411), MAPparseMapEntry(reader, reader.readLine())(:419), CHECKCOMPOUNDPATTERNnew CheckCompoundPattern(reader.readLine(), ...)(:462), COMPOUNDRULE and BREAKsingleArgument(reader, reader.readLine())(:621,:633), ICONV/OCONVsplitBySpace(reader, reader.readLine(), 3)(:825). - At end of file
readLine()returnsnull.splitBySpacestarts withline.split("\\s+")(:610) andCheckCompoundPattern's constructor withunparsed.split("\\s+")(CheckCompoundPattern.java:32); neither checks fornull, so both throwNullPointerException. - If any line follows the short table, even a blank one, the loop takes it as the missing entry (the blank-line skip of step 1 does not apply inside a table) and
splitBySpacethrowsParseException("Invalid syntax: ..."), orCheckCompoundPatternthrowsIllegalArgumentException("Invalid pattern: ..."). A following line that happens to fit the entry syntax is silently taken as an entry (read, not executed); that older leniency is not part of this bug. - The PFX/SFX parser
parseAffixalready checks:if (line == null) { ... throw new ParseException("Premature end of rules for " + header, reader.getLineNumber()); }(:703-709, added by #12468).
Gradle on 645d4fe14a20; each .aff announces 2 entries, holds 1 and ends; .dic is 1 / foo:
.aff | result |
|---|---|
REP 2 / REP a b | NullPointerException: Cannot invoke "String.split(String)" because "line" is null |
MAP 2 / MAP ab, ICONV 2 / ICONV a b, OCONV 2 / OCONV a b, COMPOUNDRULE 2 / COMPOUNDRULE AB, BREAK 2 / BREAK - | the same NPE |
CHECKCOMPOUNDPATTERN 2 / CHECKCOMPOUNDPATTERN a b | NullPointerException: ... because "unparsed" is null |
control: SFX A Y 2 / SFX A 0 s . | ParseException: Premature end of rules for SFX A Y 2 (offset 2) |
REP 2 / REP a b / one blank line | ParseException: Invalid syntax: (offset 3) |
Exposure and likelihood294 words
- Who is hit. Users of the opt-in hunspell analysis component that load an
.afffile through anyDictionaryconstructor (both sorting strategies) orHunspellStemFilterFactory(SPI namehunspellStem, for example inCustomAnalyzer). The failing strict mode is the default. - What it takes. One of the six tables must be the very last content of the file, with a count higher than the lines present: a download or copy cut off inside the table, or an entry deleted without lowering the count. The layout itself is ordinary: 17 of the 97
.afffiles in Lucene's own hunspell test package end with one of these tables. A well-formed file never triggers it, so it is rated rare. - What happens. The load fails with an exception that does not say what is wrong or where:
"line" is nullmeans "your REP table announces more lines than the file has".HunspellStemFilterFactory.informwraps onlyParseExceptioninto itsUnable to load hunspell data! [dictionary=...,affix=...]IOException(HunspellStemFilterFactory.java:115-118), so factory users do not get the affix file name either. - What does not happen. No wrong stems, no silent acceptance, no hang, nothing written: the load fails at once even when a table announces 2,000,000,000 lines, and writes no temp files;
HunspellStemFilterFactorycloses the streams it opened and removes its temp directory (a directDictionarycaller closes its own streams, as the constructor javadoc asks). Well-formed files are not affected; REP's opt-in tolerant mode loads the truncated REP file, as documented. - Related, separate fix sites (not part of this bug). In default mode a REP count that is too low gives
NumberFormatExceptionfromparseNum, which also contradicts the REP javadoc; and the COMPOUNDRULE count sizes an array up front (Dictionary.java:619), so an absurd count givesOutOfMemoryError.
One JUnit test on the public constructor: a two-line .aff (REP 2, REP a b) and a one-word .dic, expecting ParseException. Deterministic, single thread, no randomized components; it fails the same way with assertions on and off (gradle and standalone).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.io.InputStream;
import java.nio.charset.StandardCharsets;
import java.text.ParseException;
import org.apache.lucene.store.ByteBuffersDirectory;
import org.apache.lucene.store.Directory;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestTruncatedRepTable extends LuceneTestCase {

  public void testRepCountHigherThanLinesAtEndOfFile() throws Exception {
    try (Directory dir = new ByteBuffersDirectory();
        InputStream aff = new ByteArrayInputStream("REP 2\nREP a b\n".getBytes(StandardCharsets.UTF_8));
        InputStream dic = new ByteArrayInputStream("1\nfoo\n".getBytes(StandardCharsets.UTF_8))) {
      // expected ParseException (tolerateRepRuleCountMismatches() is false by default); actual NullPointerException
      expectThrows(ParseException.class, () -> new Dictionary(dir, "dictionary", aff, dic));
    }
  }
}
cp TestTruncatedRepTable.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.hunspell.TestTruncatedRepTable -Ptests.seed=DEADBEEF
# the seed picks the assertion setting (off for DEADBEEF); add -Ptests.asserts=true to force them on: same result
- Expected
ParseException, as the REP javadoc says and as a PFX/SFX table cut short gives (Premature end of rules for SFX A Y 2).- Observed
NullPointerException: Cannot invoke "String.split(String)" because "line" is nullfromDictionary.splitBySpace; the same with assertions on and off.
More files, environment, full output251 words
REP is the table with the explicit javadoc contract; the other five tables share the root cause and the fix and were executed with a separate probe (see "The finding in 30 seconds"). The test imports org.apache.lucene.tests.util.LuceneTestCase, a package that exists from 9.1.0 on (9.0.0 still has org.apache.lucene.util.LuceneTestCase), so as written it compiles on 9.1.0 and later; older releases were checked with a release-agnostic main() probe.
As the regression test: the same test, for example as a new method in TestDictionary, after ./gradlew tidy (google-java-format wraps two over-long lines; nothing else changes). Checked with gradle: the formatted test fails on stock, passes with fix B, and :lucene:analysis:common:check -x test is clean with it.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT); the test also fails on 10.6.0, 10.5.2 and 9.1.0; the bug is in every release from 4.8.0 (ICONV/OCONV) and 8.9.0 (all six tables) |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 |
cp TestTruncatedRepTable.java $LUCENE/lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/
cd $LUCENE && ./gradlew :lucene:analysis:common:test --tests org.apache.lucene.analysis.hunspell.TestTruncatedRepTable -Ptests.seed=DEADBEEF
# the seed picks the assertion setting (off for DEADBEEF); add -Ptests.asserts=true to force them on: same result
# gradle, main 645d4fe14a20, seed DEADBEEF, assertions off (the seed's default); the same with -Ptests.asserts=true; verbatim excerpt
TestTruncatedRepTable > testRepCountHigherThanLinesAtEndOfFile FAILED
    junit.framework.AssertionFailedError: Unexpected exception type, expected ParseException but got java.lang.NullPointerException: Cannot invoke "String.split(String)" because "line" is null
        at __randomizedtesting.SeedInfo.seed([DEADBEEF:667F3789FE972978]:0)
        at app/org.apache.lucene.test_framework@11.0.0-SNAPSHOT/org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1437)
        at app/org.apache.lucene.test_framework@11.0.0-SNAPSHOT/org.apache.lucene.tests.util.LuceneTestCaseParent.expectThrows(LuceneTestCaseParent.java:1418)
        at app//org.apache.lucene.analysis.hunspell.TestTruncatedRepTable.testRepCountHigherThanLinesAtEndOfFile(TestTruncatedRepTable.java:34)

        Caused by:
        java.lang.NullPointerException: Cannot invoke "String.split(String)" because "line" is null
            at org.apache.lucene.analysis.hunspell.Dictionary.splitBySpace(Dictionary.java:610)
            at org.apache.lucene.analysis.hunspell.Dictionary.readAffixFile(Dictionary.java:411)
            at org.apache.lucene.analysis.hunspell.Dictionary.<init>(Dictionary.java:264)
            at org.apache.lucene.analysis.hunspell.Dictionary.<init>(Dictionary.java:213)
at org.apache.lucene.analysis.hunspell.Dictionary.<init>(Dictionary.java:192)- The javadoc of the REP count option: "False by default: a ParseException will happen."
- PFX/SFX tables got exactly this check in #12468 (9.8.0), with an upstream test case that cuts an SFX table short at the end of the file.
- One blank line after the short table already gives
ParseException; the exception type should not depend on a trailing newline.
The full argument224 words
- REP contract (10.2.0 and later).
tolerateRepRuleCountMismatches(): "Whether incorrect REP rule counts will be silently ignored. False by default: a {@link ParseException} will happen." (Dictionary.java:1178-1184). #14079 (Robert Muir, 2024-12-18) added it "Similar to support for tolerating PFX/SFX count mismatches", with the PFX/SFX wording (:1170-1176). - PFX/SFX precedent. #12468 (Peter Gromov, 2023-07-29, "hunspell: check for aff file wellformedness more strictly", 9.8.0) added the
readLine() == nullcheck toparseAffixonly (:703-709) and extended the existingTestDictionary.testInvalidData(:145-164) with five broken.afffiles, each expected to giveParseException; one of them,broken_extraAffRule_last.aff, is an SFX table that announces 4 rules and holds 3 at the end of the file. Up to 9.7.0 that SFX case was an NPE too. - Constructors.
@throws ParseException Can be thrown if the content of the files does not meet expected formats(:187,:204,:224). Nothing documents an NPE for a malformed file. - Position dependence. The same short table followed by a blank line gives
ParseException: Invalid syntax:(executed). - Maintainer intent. LUCENE-3976 (#5049, 2012) was closed with the preference to find the exceptions malformed affix files cause and "fix them at their source", "on a per-error basis"; #12468 and #16919 (2026-10-28: in
AffixConditionan internalAssertionErrorbecame anIllegalStateException, andThrowableis no longer caught) continue that work.
The devil's-advocate check172 words
The strongest case for "intended" (the study's intended-behaviour checkers, the tie-break and the refute-lens reviewer): the parser was never hardened and ParseException was never exhaustive. Other malformed content already escapes as NumberFormatException (non-numeric count), IllegalArgumentException (bad CHECKCOMPOUNDPATTERN, COMPOUNDRULE or FLAG line), ArrayIndexOutOfBoundsException (short PFX header) or IllegalStateException (duplicate ICONV mapping, documented at :1186-1192); "can be thrown" is permissive; the .aff file is trusted configuration and is refused either way.
Why it fails: it limits how strongly one may say "must be ParseException", not whether this is a defect. Nothing makes an NPE from dereferencing readLine()'s null intended: the REP javadoc names ParseException for this very mistake, the same class already handles the identical case for PFX/SFX, and a blank line after the table already gives ParseException. The REP javadoc is itself loose for a REP count that is too low (NumberFormatException), so it shows the intent, not a complete list of exceptions. Hence "wrong error" at low priority: the case is for a descriptive parse error.
Recommended B. Check each table read for end of file and throw "Premature end of rules for <header>" (as PFX/SFX do)
Check each table read for end of file and throw ParseException("Premature end of rules for " + header, line), as PFX/SFX do: REP 2 / REP a b then gives Premature end of rules for REP 2, and likewise for the other five tables. With it the repro passes with assertions on and off; the hunspell package has 0 failures.
+  private static String readTableLine(LineNumberReader reader, String header)
+      throws IOException, ParseException {
+    String line = reader.readLine();
+    if (line == null) {
+      throw new ParseException("Premature end of rules for " + header, reader.getLineNumber());
+    }
+    return line;
+  }

   // REP, and the same at MAP, CHECKCOMPOUNDPATTERN, COMPOUNDRULE, BREAK, ICONV/OCONV:
-  String[] parts = splitBySpace(reader, reader.readLine(), 3, Integer.MAX_VALUE);
+  String[] parts =
+      splitBySpace(reader, readTableLine(reader, line), 3, Integer.MAX_VALUE);
All options and trade-offs2 options · 780 words
Two options were run through gradle in a scratch worktree of 645d4fe14a20; both cover the same six reads and change nothing else. B gives the better message.
B. Check each table read for end of file and throw "Premature end of rules for <header>" (as PFX/SFX do) (validated by the checks) (recommended)
A small helper readTableLine(reader, header) replaces the six reader.readLine() arguments (REP, MAP, CHECKCOMPOUNDPATTERN, COMPOUNDRULE, BREAK, ICONV/OCONV); parseCompoundRules and parseConversions get the header line as a new parameter. 26 lines added, 10 removed, all in Dictionary.java.
+  private static String readTableLine(LineNumberReader reader, String header)
+      throws IOException, ParseException {
+    String line = reader.readLine();
+    if (line == null) {
+      throw new ParseException("Premature end of rules for " + header, reader.getLineNumber());
+    }
+    return line;
+  }

   // REP, and the same at MAP, CHECKCOMPOUNDPATTERN, COMPOUNDRULE, BREAK, ICONV/OCONV:
-  String[] parts = splitBySpace(reader, reader.readLine(), 3, Integer.MAX_VALUE);
+  String[] parts =
+      splitBySpace(reader, readTableLine(reader, line), 3, Integer.MAX_VALUE);
Trade-offs
- The load still fails, now with the same exception and wording as PFX/SFX:
ParseException: Premature end of rules for REP 2(and... for MAP 2,... for ICONV 2, ...), which names the table and carries a line number.HunspellStemFilterFactorythen wraps it in itsIOException("Unable to load hunspell data! [dictionary=...,affix=...]"), which names the affix file (thedictionary=part prints the stream objects, not file names). - It touches six call sites and two private signatures, so it conflicts textually with the open refactor PR #16422.
- The reported offset is the reader's line number at end of file: 2 for
REP 2/REP a bwith and without a final newline on JDK 25. #10121 (LUCENE-9079, 2019) records that an early-access JDK of the time numbered an unterminated last line differently, so do not assert an exact offset. - No API or format change; the only added work is one null check per table line while the file loads (not measured).
What the checks validated
- Gradle on
645d4fe14a20(assertions off, the seed's default, and with-Ptests.asserts=true) and standalone (-eaand-da): without a fix the repro fails and the finder's 7-test class fails 6 of 7; with fix B the repro passes and the 7-test class passes 7/7. - A probe of all seven directives gives
ParseException: Premature end of rules for <header>(offset 2) for REP, MAP, ICONV, OCONV, COMPOUNDRULE, BREAK and CHECKCOMPOUNDPATTERN; the SFX control and the blank-line case are unchanged (gradle, and standalone with-eaand-da). - Closest suites: every test class of the hunspell package (
TestDictionarywithtestInvalidData,TestHunspellStemFilterFactory,TestSpellChecking,TestStemmer, ...): 49 classes including the repro, the probe and the 7-test class, 167 tests, 0 failures, 13 skipped (three classes that need external dictionaries or corpora). ./gradlew :lucene:analysis:common:check -x testpasses with fix B and the repro in place (google-java-format, ecj lint, forbidden APIs, license and checksum checks) once the repro is reformatted by./gradlew tidy(two lines wrapped); unformatted, onlycheckGoogleJavaFormatobjects. The full Lucene test suite was not run.
The study's original fix: splitBySpace throws ParseException("Premature end of the affix file", line) for a null line, which covers REP, MAP, COMPOUNDRULE, BREAK and ICONV/OCONV (they all reach it), and the CHECKCOMPOUNDPATTERN loop checks readLine() itself. 9 lines added, 1 removed.
   private String[] splitBySpace(LineNumberReader reader, String line, int minParts, int maxParts)
       throws ParseException {
+    if (line == null) {
+      throw new ParseException("Premature end of the affix file", reader.getLineNumber());
+    }
     String[] parts = line.split("\\s+");

   // CHECKCOMPOUNDPATTERN does not go through splitBySpace:
+  String patternLine = reader.readLine();
+  if (patternLine == null) {
+    throw new ParseException("Premature end of the affix file", reader.getLineNumber());
+  }
-  new CheckCompoundPattern(reader.readLine(), flagParsingStrategy, this)
+  new CheckCompoundPattern(patternLine, flagParsingStrategy, this)
Trade-offs
- Smallest change, and it also guards any future caller of
splitBySpace. - The message does not name the table (
Premature end of the affix file, with a line number), unlike PFX/SFX; the six tables give the same message.
What the checks validated
- Gradle, same worktree (assertions off): the repro passes, as it did earlier standalone with
-eaand-da; the 7-test class passes 7/7; the probe givesPremature end of the affix file(offset 2) for all seven directives; the hunspell package runs 49 classes, 167 tests, 0 failures, 13 skipped. check -x testwith the study's diff fails only incheckGoogleJavaFormat(its CHECKCOMPOUNDPATTERNthrowfits on one line); the snippet above is the tidied form.- Earlier, shadowed into the stock jars: 74 upstream hunspell tests at the study's commit and 145 at
645d4fe14a20, 0 failures.
Products that load user-supplied hunspell dictionaries and catch only ParseException around the load, as HunspellStemFilterFactory does, see this NullPointerException escape instead.
Non-formal: a static-analysis sweep (SpotBugs) flagged readLine() results that Dictionary uses without a null check; a search for the same pattern added the other tables, and a public-API JUnit test reproduced all six.
The method in full98 words
Method: non-formal (static analysis, then executed tests). On 2026-10-26 a hunt unit ran SpotBugs 4.10.5 (-effort:max -low) over the non-sandbox module jars. Its NP_DEREFERENCE_OF_READLINE_VALUE check flagged Dictionary.parseConversions and two reads in readAffixFile (REP and CHECKCOMPOUNDPATTERN). A grep for readLine() passed straight as a call argument, over all non-sandbox modules, added the COMPOUNDRULE, BREAK and MAP reads in the same file. A 7-test JUnit through the public constructor (six truncated tables plus a truncated-SFX control) failed 6 of 7; independent checkers then reproduced it with their own tests, and it was cut to the one-test REP repro.
No prior report found in GitHub issues, PRs and commits (incl. the JIRA archive), all open PRs, the mailing lists, downstream trackers or the web (2026-10-26, refreshed 2026-11-01). #12468 is the PFX/SFX precedent. Not fixed upstream.
Searches4 searches
Closest items, none a report of this bug: #12468 (9.8.0, the same end-of-file check for PFX/SFX only, with the broken_extraAffRule_last.aff test; no linked issue, the other tables not discussed): the precedent; #5049 (LUCENE-3976, Won't Fix 2012: a generic request for better errors on malformed affix files, closed before any of the six parsers existed): context; #14079 (10.2.0, the REP javadoc; its test models a REP count that is too low); #14239 (merged 2025-02-15, PFX/SFX end of file in the opt-in tolerant mode); open PR #16422 / issue #16421 (a switch refactor of readAffixFile that keeps the unchecked reads); #10121 (LUCENE-9079, LineNumberReader line numbers at end of file, relevant to a fix); #16919 (AffixCondition only). Related finding: LFV-1012 (undefined AM alias gives ArrayIndexOutOfBoundsException), same class, different fix site. Limits: list search is fuzzy, and private channels are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs (incl. the migrated JIRA issues) and commits | 2026-10-26, refreshed 2026-11-01 | scripted prior-report searches (two runs per round: hunspell plus NullPointerException, NPE, ParseException, "Premature end", truncated, readLine, "end of file", EOF, "rule count", each directive name, the NPE message, splitBySpace, parseConversions) and manual queries | no report; #12468, #14079, #14239 related; splitBySpace 0 hits |
| Open PRs | 2026-11-01 | changed files of all 410 open apache/lucene PRs | only #16422 touches the hunspell package; it keeps the unchecked reads |
| JIRA archive, mailing lists, downstream trackers, web | 2026-10-26, refreshed 2026-11-01 | manual LUCENE and SOLR JIRA queries; dev@, java-user@, issues@ and commits@; Elasticsearch, OpenSearch, Solr and all of GitHub; web queries including the exact NPE message | context only (LUCENE-3976) |
| Upstream main | 2026-11-01 | Dictionary.java blob at 2f424fd428da (2026-10-30) and its commit list | byte-identical to 645d4fe14a20; newest change #16313 (2026-07-21) |
ICONV/OCONV since 4.8.0 (LUCENE-5224, 2014); BREAK, COMPOUNDRULE, REP, CHECKCOMPOUNDPATTERN and MAP since 8.9.0 and 9.0.0 (2021). Each parser lacked the check from its first commit, so it is not a regression; 10.6.0 and main still have it.
Versions tested8 rows
Introduced (one root cause, two introduction points): ICONV/OCONV by 3064419624f (LUCENE-5224, Robert Muir, 2014-03-04, svn era; branch_4x 66368a9f904); BREAK 939699f5509 (LUCENE-9667, lucene-solr#2207), COMPOUNDRULE d7968130c3f (LUCENE-9684, #2228), REP 8a34cc7afd3 (LUCENE-9701, #2251), CHECKCOMPOUNDPATTERN d0ae2bd2b9c (LUCENE-9717, #2280) and MAP 653626399f1 (LUCENE-9736, #2314), all by Peter Gromov, 2021-01-20 to 2021-02-08, backported to 8.x in the squashed c6b964a1157 (lucene-solr#2499, 8.9.0). Later refactors (f64e7cbbda1 added splitBySpace) moved the reads without a check.
PFX/SFX gave the same NPE up to 9.7.0; #12468 fixed them in 9.8.0, so the two kinds of table disagree since 9.8.0, and the REP javadoc is contradicted since 10.2.0.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20 | affected | minimal repro fails with assertions on and off (gradle and standalone); all six tables NPE; passes with fix A or B |
| 10.6.0 | affected | minimal repro fails with assertions on and off; probe: all six tables NPE (release jars) |
| 10.5.2 | affected | minimal repro fails with assertions on and off; the study's 7- and 11-test JUnits fail |
| 9.8.0, 9.12.3, 10.0.0, 10.1.0, 10.2.0 | PFX/SFX fixed in 9.8.0 | the study's 7-test JUnit fails 6 of 7: all six tables NPE while the short SFX control gives ParseException |
| 9.7.0, 9.1.0 | affected | all six tables NPE, and the short SFX table too (7 of 7 fail) |
| 8.9.0, 9.0.0 | first with all six | probe: all six tables NPE (SFX also NPE) |
| 4.8.0 to 8.8.2 | ICONV/OCONV only | probe: ICONV/OCONV NPE; the other five tables are not parsed and the file loads |
| 4.7.2 | no parsers yet | probe: none of the six tables is parsed; the files load |
Confirmed, high confidence: the finder, an independent reproducer, an intended-behaviour devil's advocate, an adjudication and a tie-break all reproduced it. A reviewer from another model family, run twice and unable to run code either time, returned a procedural "not real" both times while agreeing on the root cause.
Checks and verdicts318 words
Everyone agrees on the root cause and that it is a wrong error only: the file is refused either way.
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | SpotBugs flagged the reads; its 7-test JUnit fails 6 of 7 on main (assertions on and off), 10.5.2 and 9.12.3, the SFX control passing; fix A passes 7/7 and 74 upstream hunspell tests. |
| cross-model review, refute lens (OpenAI GPT-5.6, read-only), run twice | not real, low (procedural), both runs | Could not run code either time, so its verdict is procedural. Its notes: "It should not be treated as a substantive refutation: static evidence strongly favors a genuine wrong-exception bug" (2026-10-26, on the study's 7-test candidate) and "It is not a substantive refutation: static evidence strongly favors a small wrong-exception defect" (2026-11-01, on the minimal repro). It agreed on the root cause and found the REP javadoc and the factory path. Separate re-runs: 6 of 7 fail; the minimal test fails on 10.5.2. |
| independent reproducer | real | Its own JUnit from a package outside hunspell fails 8 of 11 on main (assertions on and off), 10.5.2 and 9.12.3: all seven directives and the factory path; 3 controls pass. |
| cross-model review, works-as-designed lens (OpenAI GPT-5.6, read-only) | real, medium | The intended argument is weak: "can be thrown" is permissive, but nothing makes the NPE intended. |
| intended-behaviour devil's advocate | real | Built the strongest intended case (other malformed content escapes as other unchecked exceptions) and rejected it; reproduced all six tables on main and 10.5.2. |
| adjudication | confirmed, high | Re-ran the reproducer's JUnit with assertions on and off: 8 of 11 fail, 3 controls pass. |
| re-verification and tie-break on 645d4fe14a20 | real, high | The minimal test fails on main and 10.5.2 under fresh seeds; controls pass; the in-memory constructor and the factory fail the same way; with fix A shadowed in, 145 upstream hunspell tests stay green. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 456 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,321 words
- Registry title
- Hunspell Dictionary throws NullPointerException instead of a parse error when a REP, MAP, ICONV/OCONV, COMPOUNDRULE, BREAK or CHECKCOMPOUNDPATTERN table at the end of the .aff file has fewer lines than its count
- Area
- analysis / hunspell (Dictionary affix-file parsing)
- Priority
- Low, rank 1061: Hunspell throws NullPointerException instead of a parse error only for a truncated or hand-damaged .aff file whose last table is short, a loud wrong-error case in config parsing.
- Impact class
- wrong error
- Impact note
- Only applications that build a hunspell Dictionary (directly or through HunspellStemFilterFactory) from a malformed .aff file whose last content is a counted table with too few lines are hit, and they get a bare NullPointerException with no directive name or line number instead of the ParseException that the same mistake gives in a PFX/SFX table; the dictionary is refused either way, so there are no wrong results, no hang and nothing persisted, and a well-formed file never triggers it.
- Summary
- You load a hunspell dictionary whose .aff file ends with a REP, MAP, ICONV/OCONV, COMPOUNDRULE, BREAK or CHECKCOMPOUNDPATTERN table that announces more lines than it holds (for example 'REP 2' followed by a single REP line, as a cut-off download or a careless hand edit leaves it), and expect the parse error that the Dictionary constructors document (ParseException), which is what Lucene already throws for a PFX/SFX table cut short ('Premature end of rules') and, since 10.2.0, what the tolerateRepRuleCountMismatches() javadoc promises for a wrong REP count by default. Instead the parser passes the null that readLine() returns at end of file straight into a string method and throws NullPointerException ('Cannot invoke "String.split(String)" because "line" is null'), with no directive or line number, which also bypasses HunspellStemFilterFactory's 'Unable to load hunspell data!' wrapping of ParseException. The file is refused either way; only the error is wrong.
- Introduced
- Two introduction points, one root cause: each counted-table parser passed reader.readLine() to a string method without an end-of-file check from its first commit. ICONV/OCONV: 3064419624fd10622da2844399d4009fc2e62e00 (LUCENE-5224, by rmuir, svn r1574135, no GitHub PR; branch_4x backport 66368a9f904c). The other five on main in 2021, each in its own commit by donnerpeter: BREAK 939699f5509 (lucene-solr#2207, LUCENE-9667), COMPOUNDRULE d7968130c3f (lucene-solr#2228, LUCENE-9684), REP 8a34cc7afd3 (lucene-solr#2251, LUCENE-9701), CHECKCOMPOUNDPATTERN d0ae2bd2b9c (lucene-solr#2280, LUCENE-9717), MAP 653626399f1 (lucene-solr#2314, LUCENE-9736); they reached 8.x through the squashed branch_8x backport c6b964a1157 (lucene-solr#2499, LUCENE-9687). [read: code at each introducing commit and git history; bracketed by execution: 4.7.2 loads / 4.8.0 NPE for ICONV/OCONV, 8.8.2 loads / 8.9.0 NPE for the other five; backport ancestry checked with read-only GitHub compare GETs]. f64e7cbbda1 (LUCENE-9691) later moved the split into splitBySpace (refactor, not the origin). Not a regression: no release ever gave a ParseException for these tables (2014-03-04 (ICONV/OCONV, LUCENE-5224); 2021-01-20 to 2021-02-08 (BREAK, COMPOUNDRULE, REP, CHECKCOMPOUNDPATTERN, MAP on main); 2021-05-28 (branch_8x backport))
- First affected version
- 4.8.0 for ICONV/OCONV [exec: 4.7.2 ignores these directives and loads, 4.8.0 throws NPE]; all six tables from 8.9.0 (branch_8x backport) and 9.0.0 [exec: 8.8.2 loads the other five silently, 8.9.0 throws NPE for all of them]
- Affected versions
- 4.8.0 - 8.8.2: ICONV and OCONV only [exec 4.8.0, 5.5.5, 7.7.3, 8.8.2]; 8.9.0 - 8.11.4, 9.0.0 - 9.12.3, 10.0.0 - 10.6.0 and main ea57360912ed: all six tables [exec 8.9.0, 8.11.4, 9.0.0, 9.1.0, 9.7.0, 9.8.0, 9.12.3, 10.0.0, 10.1.0, 10.2.0, 10.5.2, main with -ea and -da; the 10.6.0 release jars, SHA-1 checked against Maven Central, 2026-11-01: the minimal repro with -ea and -da and the probe with -ea]; [read] the same unguarded readLine() arguments and the null-unchecked splitBySpace are present at every 9.x and 10.x tag, and parseConversions has the unchecked read at every tag from 4.8.0 on. Up to 9.7.0 a short PFX/SFX table also threw NPE; #12468 fixed that in 9.8.0, so the PFX/SFX-vs-other-tables inconsistency exists since 9.8.0 and the REP javadoc contract since 10.2.0. Not fixed upstream: Dictionary.java on upstream main e1c4184cb983 (2026-10-26) is byte-identical to the snapshot. Not affected: 4.7.2 and older (none of the six tables parsed). All runs on aarch64 with JDK 25.0.3
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an adjudication that ruled it real, an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- non-formal
- Upstream and prior reports
- none found (2026-10-26, read-only: a scripted prior-report search in three runs plus the finder's and the intended-behaviour check's runs (GitHub issue/PR, commit, downstream-repo, mailing-list over dev@, java-user@, issues@ and commits@, JIRA-archive and web queries; 403, 380 and 43 distinct hits in the follow-up runs, none high); manual GitHub searches over apache/lucene, Elasticsearch, OpenSearch, Solr and all of GitHub; the changed files of all 411 open apache/lucene PRs; manual JIRA (LUCENE, SOLR) and mailing-list searches; git history and CHANGES.txt; none the same bug). Closest items: #12468 (9.8.0, fixed the same readLine()==null pattern for PFX/SFX only), #5049 (LUCENE-3976, Won't Fix 2012, a general request for better hunspell error messages), #14079 (10.2.0, added the REP javadoc 'False by default: a ParseException will happen'), #14239 (PFX/SFX end of file in the opt-in tolerant mode), #10121 (LUCENE-9079, LineNumberReader line numbers at end of file, relevant to a fix), #16422 (the only open PR touching the hunspell package, a switch refactor that keeps the bug). Not fixed upstream (Dictionary.java byte-identical on upstream main e1c4184cb983).
- Lucene commit tested
- main
645d4fe14a20(the minimal repro through gradle with assertions off and with-Ptests.asserts=true, and standalone with-eaand-da; a probe of all seven table directives and the finder's 7-test class through gradle; both fix options in a scratch worktree, with the whole hunspell test package and the static checks; fix B also standalone with-eaand-da); SHA-1-checked release jars: the minimal repro on 9.1.0, 10.5.2 and 10.6.0 (assertions on and off on the last two), a release probe on 4.7.2, 4.8.0, 8.8.2, 8.9.0, 9.0.0 and 10.6.0, and the study's runs on 16 releases from 4.7.2 to 10.5.2. Upstream main2f424fd428da(2026-10-30) has a byte-identicalDictionary.java(read).
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java at ea57360912ed: :187, :204, :224 (constructor javadoc '@throws ParseException Can be thrown if the content of the files does not meet expected formats'), :401-414 REP (:411), :416-421 MAP (:419), :458-464 CHECKCOMPOUNDPATTERN (:462), :608-615 splitBySpace (:610 line.split, no null check), :617-624 parseCompoundRules (:621), :626-640 parseBreaks (:633), :703-709 parseAffix ('Premature end of rules'), :820-830 parseConversions (:825), :1170-1192 tolerate*CountMismatches() javadoclucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/CheckCompoundPattern.java:29-35 (constructor calls unparsed.split at :32; IllegalArgumentException 'Invalid pattern' for fewer than 3 parts); lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/HunspellStemFilterFactory.java:96-123 (inform catches only ParseException and wraps it in IOException 'Unable to load hunspell data!')lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/*.aff (16 of the 97 test fixtures have REP, MAP, ICONV, OCONV, COMPOUNDRULE, BREAK or CHECKCOMPOUNDPATTERN as their last non-blank, non-comment directive; counted with grep/awk on 2026-10-26)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:350-359, :408-421, :458-464, :595-615, :617-643, :703-709, :820-832 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/CheckCompoundPattern.java:29-35 (at 645d4fe14a20)
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:186-231 (constructors), :1170-1192 (tolerate* hooks), :619 (at 645d4fe14a20)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/HunspellStemFilterFactory.java:58, :96-123 (inform; catch ParseException only at :115-118) (at 645d4fe14a20)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/*.aff (17 of 97 end with one of the six tables; recount of the last non-blank, non-comment directive at 645d4fe14a20, the study counted 16)
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:187, :204, :224, :703-709, :1170-1192 (at 645d4fe14a20)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestDictionary.java:145-164 and lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/broken_extraAffRule_last.aff (at 645d4fe14a20)
- History
a Lucene clone: git show releases/lucene/10.6.0:lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java (six unchecked reads at :417, :424, :478, :631, :643, :837)
- TestTruncatedRepTable.java (JUnit, one test):
repro/LFV-345/src/org/apache/lucene/analysis/hunspell/TestTruncatedRepTable.java(37 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and the repro's input and output; the fix step shows fix B, run with the probe (assertions on and off).
assets/LFV-345/bug.png(456 KB)