RegexpQueryHandler lets the Monitor pre-select regexp queries: it indexes each query under its longest literal plus XX, and its SuffixingNGramTokenFilter turns each short document word into all of its substrings plus XX. The filter measures substrings in code points but starts their size from the UTF-16 length, so a word with a surrogate pair gets none.
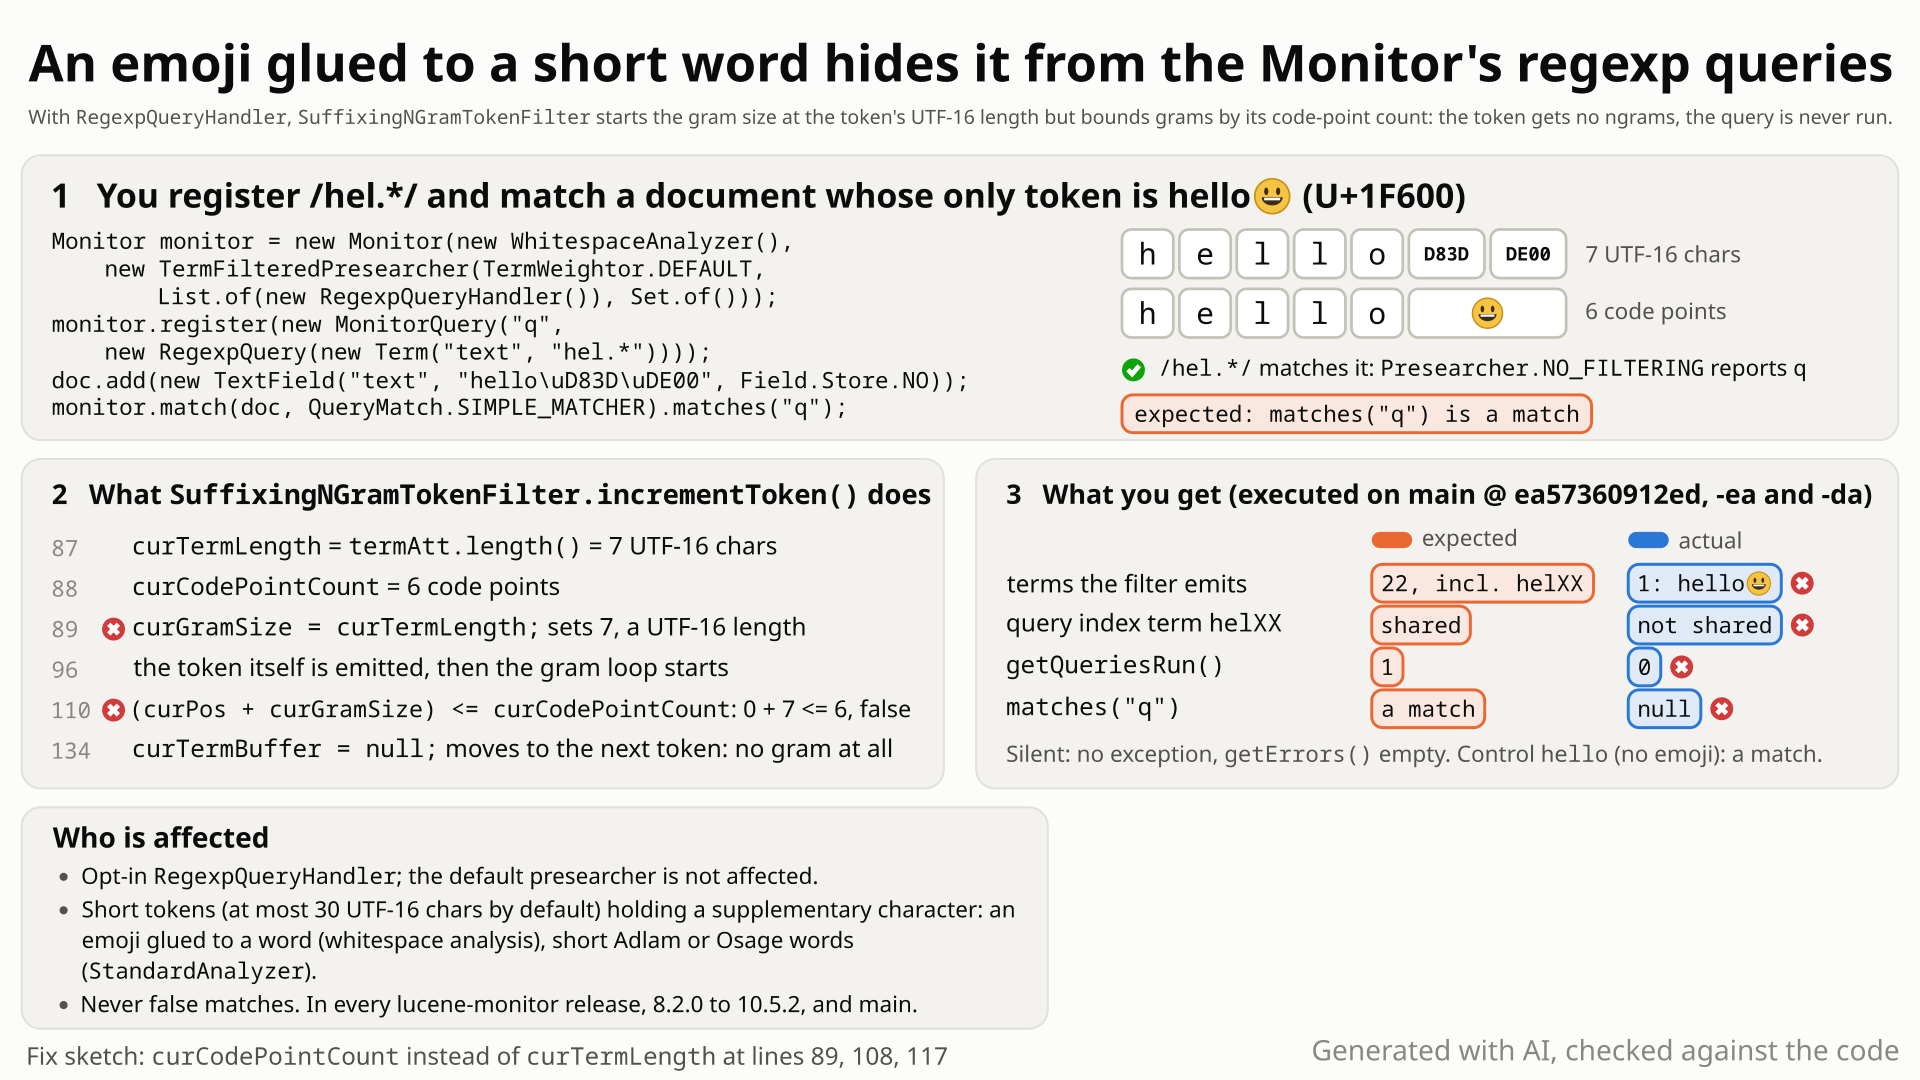
hello😀 through the presearcher: hello yields 16 terms including helXX and /hel.*/ runs; hello😀 (7 UTF-16 chars, 6 code points) yields only itself, so the query is skipped; with the fix it yields 22 terms. Select the still to open it at full size. Generated with AI, checked against the code.- You give a Monitor's
TermFilteredPresearchertheRegexpQueryHandler, register/hel.*/and match the one-word documenthello😀(WhitespaceAnalyzer). The handler indexes the query under its literal plus a suffix,helXX, and turns each document word into all of its substrings plusXX. - You expect a match: the regexp matches the word, and a Monitor without filtering reports it. For
hellothe handler emits 16 terms, among themhelXX, so the query is selected and runs. - Instead
hello😀gives 1 term, the word itself. The emoji is 2 UTF-16 chars but 1 code point, so the word is 7 chars but 6 code points: the filter starts its substring size at 7, checks it against 6, and gives up on the word. Monitor.matchruns 0 queries and reports no match and no error, with assertions on or off. With the 3-line fix the word gives 22 terms, includinghelXX, and the query matches.- It hits any word of up to 30 UTF-16 chars with an emoji, a CJK Extension B ideograph or a letter of a script such as Adlam, also under
StandardAnalyzerfor such scripts. Another word of the field that supplies the literal, a word over 30 chars in the field, or such a word in another document of the same match batch hides the miss. Term queries and the default presearcher are not affected.
Applications that give TermFilteredPresearcher the opt-in RegexpQueryHandler and register regexp queries. A token of up to 30 UTF-16 chars with an emoji, a CJK Extension B ideograph or an Adlam or Osage letter silently loses the regexp queries only its substrings could select; another token of the field or document of the batch can hide the miss. No false matches.
Mechanism, terms and numbers702 words
RegexpQueryHandler is the optional handler that lets a Monitor's TermFilteredPresearcher pre-select RegexpQuerys: it indexes each regexp under its longest literal plus XX and runs each document field that is not in its excludedFields through SuffixingNGramTokenFilter, which emits each short token and its substrings plus XX (skipping substrings already emitted in the same field). The filter measures substrings in code points but starts and resets their size from the token's UTF-16 length, so for any token that contains a supplementary character (an emoji, a CJK Extension B ideograph, a letter of Adlam, Osage or Gothic) the first bound check fails and the token gets no substrings at all. A regexp query that only one of them could select is not selected: /hel.*/ is not reported for hello😀, with 0 queries run and no error, while a Monitor without filtering reports it. It affects tokens of at most 30 UTF-16 chars (the default maxTokenSize) unless another token of the field supplies the substring, a token of the field is longer than 30 chars (it emits the wildcard token), or another document of the same match batch does either; also under StandardAnalyzer for words in supplementary-plane scripts; it never causes false matches and leaves term queries and the default presearcher alone. It is in every lucene-monitor release, 8.2.0 to 10.6.0 (10.6.0 by reading), and on main; the fix is three lines.
- Monitor (
lucene/monitor): stores queries and reports which of them a document matches. Its presearcher turns the document's terms into a query over the stored queries, so that only queries that can match are run (package-info.java:55-63). RegexpQueryHandler: an optionalCustomQueryHandlerforTermFilteredPresearcher. It indexes/hel.*/under its longest literal plus the suffix,helXX, and under the wildcard token__WILDCARD__(RegexpQueryHandler.java:96-114), and wraps each document field not in itsexcludedFieldsinSuffixingNGramTokenFilter(:90-93; defaultsXX, 30,__WILDCARD__at:41-47). The query is selected if the document yieldshelXXor__WILDCARD__.- Supplementary character: a code point above U+FFFF (an emoji, a CJK Extension B ideograph, Adlam, Osage, Gothic letters). Java stores it as two
chars, a surrogate pair, so such a word has more UTF-16 chars than code points.
TermFilteredPresearcher.buildQuery(TermFilteredPresearcher.java:100-113,final) reads each field's distinct terms as aTermsEnumTokenStream(:110) and wraps it with every handler (:112). That stream carries only aCharTermAttribute(TermsEnumTokenStream.java:27-30), so the filter's keyword pass-through (:84) never fires in the Monitor.SuffixingNGramTokenFilter.incrementToken(SuffixingNGramTokenFilter.java:76-136) first returns the token itself (:96), after settingcurTermLength= UTF-16 length (:87),curCodePointCount(:88) andcurGramSize = curTermLength(:89).- Each substring must pass
(curPos + curGramSize) <= curCodePointCount(:110) and is sliced withCharacter.offsetByCodePoints(:112-114), both in code points; the size is reset tocurTermLength - curPos(:108) and the suffix check usescurTermLength - curPos(:117), in UTF-16 chars. - For
hello😀: 7 chars, 6 code points, so the first check is0 + 7 <= 6, false. The filter drops to:134and takes the next token, having emitted onlyhello😀. One surrogate pair anywhere in a token is enough; not evenXXis emitted. - The document yields neither
helXXnor__WILDCARD__, so/hel.*/is not selected andMonitor.matchnever runs it (Monitor.java:224,:294-299). - Tokens longer than 30 chars take the wildcard path (
:99-104), which every regexp query collects (RegexpQueryHandler.java:113), so they are safe (executed: 30 chars missed, 31 reported), and any such token in the same field hides the miss. The presearcher query is built once permatch(Document[])batch (Monitor.java:218-225), so a token of another document in the batch can also select the query (executed).
Executed on main (-ea and -da), one token per document: hello gives 16 terms including helXX and the query runs; hello😀 gives 1 term and 0 queries run; with the fix hello😀 gives 22 terms and the query matches; a😀 gives [a😀] instead of {a😀, a😀XX, aXX, 😀XX, XX}.
Exposure and likelihood333 words
- Who is exposed. Monitors built with
TermFilteredPresearcherorMultipassTermFilteredPresearcher(which inherits thefinalbuildQuery; executed with the same misses) plusRegexpQueryHandler, that registerRegexpQuerys on fields not in itsexcludedFields. Code search found no public user outside copies of Lucene's own source; Solr's open Monitor integration PR passes no custom handlers. - Default vs opt-in. The handler is opt-in; the default presearcher does not use this filter and reported every probe document. Inside the opt-in configuration nothing special is needed:
new RegexpQueryHandler(), stock analyzers, assertions on or off. - Which text. Executed:
WhitespaceAnalyzerwithhello😀,say hello𠀀 now(U+20000),x😀hello(/.*hello/) or the Gothic word𐌰𐌱;KeywordAnalyzerwithgreat product 😀;StandardAnalyzerwith short Adlam or Osage words,hello𝐀(U+1D400) orhelloplus a variation selector (U+E0100) or tag character (U+E0041), default-ignorable code points that are normally not rendered.StandardAnalyzersplits an emoji or a CJK ideograph off a Latin word, sohello😀is found there. - Bounds. Only tokens of at most
maxTokenSizeUTF-16 chars (default 30); another token of the same field that yields the needed substring hides the miss, and so does any token of the field longer than 30 chars (it emits__WILDCARD__) or such a token in another document of the samematch(Document[])batch (executed; a token in another field does not help); term queries are unaffected because the token itself is always emitted. - Scale. None: one token of two code points is enough. Exhaustive check of the stock jar over all 1,560 inputs of 1-2 tokens of 1-3 code points over {a, b, U+1F600}: 1,350 miss required substrings (each input on its own), exactly those with U+1F600; 0 of the 210 BMP-only inputs; 0 with the fix.
- Damage. Silent false negatives for regexp queries only: no error, 0 queries run. Never false matches (0 in an exhaustive probe of 1,764 documents x 10 queries, where 2,478 of 4,520 true pairs were missed), no hang, less work rather than more.
The test shows that a Monitor with RegexpQueryHandler never runs a regexp query against a token that contains a supplementary character, because SuffixingNGramTokenFilter emits no ngrams for that token.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.monitor;

import java.util.List;
import java.util.Set;
import org.apache.lucene.analysis.core.WhitespaceAnalyzer;
import org.apache.lucene.document.Document;
import org.apache.lucene.document.Field;
import org.apache.lucene.document.TextField;
import org.apache.lucene.index.Term;
import org.apache.lucene.search.RegexpQuery;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestRegexpQueryHandlerSupplementaryChar extends LuceneTestCase {

  public void testRegexpMatchesTokenWithEmoji() throws Exception {
    Presearcher presearcher = new TermFilteredPresearcher(TermWeightor.DEFAULT, List.of(new RegexpQueryHandler()), Set.of());
    try (Monitor monitor = new Monitor(new WhitespaceAnalyzer(), presearcher)) {
      monitor.register(new MonitorQuery("q", new RegexpQuery(new Term("f", "hel.*"))));
      Document doc = new Document();
      doc.add(new TextField("f", "hello\uD83D\uDE00", Field.Store.NO));
      MatchingQueries<QueryMatch> matches = monitor.match(doc, QueryMatch.SIMPLE_MATCHER);
      // expected: /hel.*/ matches the one token "hello" + U+1F600; actual: the presearcher never runs the query, 0 matches
      assertEquals("queries run: " + matches.getQueriesRun(), 1, matches.getMatchCount());
    }
  }
}
# in a copy of this finding's repro folder (repro/LFV-347/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:$LUCENE/lucene/memory/build/libs/lucene-memory-$V.jar
CP=$CP:$LUCENE/lucene/monitor/build/libs/lucene-monitor-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.monitor.TestRegexpQueryHandlerSupplementaryChar
- Expected vs actual
- Expected: /hel.*/ matches the document whose only token is "hello" + U+1F600 (1 match). Actual (-ea and -da): 0 matches, and 0 queries are run by the presearcher.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: queries run: 0 expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
org.apache.lucene.monitor.TestRegexpQueryHandlerSupplementaryChar.testRegexpMatchesTokenWithEmoji(TestRegexpQueryHandlerSupplementaryChar.java:39)- The handler "generates ngrams from Document tokens to match them"; the filter documents one exclusion: tokens longer than
maxTokenLength. - The filter bounds and slices substrings in code points but sizes them in UTF-16 chars: a token with a surrogate pair gets nothing.
- Lucene fixed this mix-up in its n-gram filters (LUCENE-5042) and
TruncateTokenFilter(#15899), and missed Monitor matches (#14886).
The full argument355 words
- Contracts.
RegexpQueryHandlerclass javadoc: "A query handler implementation that matches Regexp queries by indexing regex terms by their longest static substring, and generates ngrams from Document tokens to match them" (RegexpQueryHandler.java:29-31).SuffixingNGramTokenFilterconstructor: "@param maxTokenLength tokens longer than this will not be ngrammed" (SuffixingNGramTokenFilter.java:60), the filter's only documented exclusion; the handler also documentsexcludedFields, "a Set of fields to ignore when generating ngrams" (RegexpQueryHandler.java:64, applied at:91), and the filter passes keyword-marked tokens through (:84, undocumented; never the case in the Monitor path). None covers short tokens with supplementary characters. Package doc: queries that match the document disjunction "are then run against the document. In this way, the Monitor can avoid running queries that have no chance of matching" (package-info.java:60-61). - The code's own unit.
:88computescurCodePointCount,:110bounds substrings by it and:112-114slice withCharacter.offsetByCodePoints(whosecurTermLengthargument is the char-array bound, correctly in chars); of the gram arithmetic, only:89,:108and:117use the UTF-16 length.:99also compares the UTF-16 length withmaxTokenLength, which only over-selects and is a separate question (option "maxlength-codepoints"). The mix is not an alternative design: it makes the first check fail for every token with a surrogate pair. - Tests.
TestSuffixingNGramTokenizerandTestRegexpQueryHandleruse ASCII only; no upstream test covers non-BMP text.TestWildcardTermPresearcherrunsRegexpQueryHandlerthrough the sharedPresearcherTestBasesuite (TestWildcardTermPresearcher.java:25,:93), so it is a supported configuration. - History. The lines came with the module (LUCENE-8766,
251dbe7cea8, 2019), from the donated Luwak code, whose master still has them; neither LUCENE-8766's 28 comments nor its import PR discusses Unicode. - Precedent. LUCENE-5042: "The n-gram and edge n-gram tokenizers and filters now correctly handle supplementary characters" (
lucene/CHANGES.txt:13522-13524); LUCENE-5269: "Fix bug in NGramTokenFilter where it would sometimes count unicode characters incorrectly" (:13215-13216); #15899/#15900,TruncateTokenFilter(10.5.0,:1182-1184), where a maintainer wrote: "We modified all other similar filters in the past (like ngrams), they all work correctly." Missed Monitor matches fixed as bugs: LUCENE-9791 (:5370-5372), GITHUB#14886 (:1743-1746). The UTF-16-versus-code-point pattern itself is not new.
The devil's-advocate check187 words
The strongest case for "intended or best effort" (built by the devil's-advocate verifier; rated weak by it, the independent reproducer, the GPT-5.6 "works as designed" reviewer and the adjudication): the package doc says RegexpQueryHandler "gives an example of a different method of indexing automaton-based queries" (package-info.java:93-95); it is opt-in; the filter is package-private; the tests are ASCII-only and nothing promises Unicode support; and RegexpQuery itself is tagged @lucene.experimental (RegexpQuery.java:40).
Why it fails: these limit reach, not intent. The handler is public API with public defaults and constructors, has no @lucene.experimental tag and runs in the upstream presearcher test suite; the experimental tag on RegexpQuery marks an API that may change, not licence for the presearcher to drop a query the document matches (under Presearcher.NO_FILTERING the same query matches); the regexps in the repro (a literal prefix plus .*) are the shape the handler's own tests cover; every short token with a surrogate pair gets no substrings at all, which is not an edge of regexp syntax; and the filter's own code counts code points, as the project expects of n-gram filters (#15899).
Recommended Count the substring size in code points (3 lines)
Use the code-point count in the three places the filter uses the UTF-16 length (SuffixingNGramTokenFilter.java:89, :108, :117; 3 lines). This doc's test and a new TestSuffixingNGramTokenizer case pass, the whole monitor module (185 tests) passes with assertions on and off, and the format and lint checks pass.
@@ -86,7 +86,7 @@ final class SuffixingNGramTokenFilter extends TokenFilter {
         curCodePointCount = Character.codePointCount(termAtt, 0, termAtt.length());
-        curGramSize = curTermLength;
+        curGramSize = curCodePointCount;
@@ -105,7 +105,7 @@ final class SuffixingNGramTokenFilter extends TokenFilter {
         ++curPos;
-        curGramSize = curTermLength - curPos;
+        curGramSize = curCodePointCount - curPos;
@@ -114,7 +114,7 @@ final class SuffixingNGramTokenFilter extends TokenFilter {
-        if ((curGramSize == curTermLength - curPos)
+        if ((curGramSize == curCodePointCount - curPos)
             && !seenSuffixes.add(termAtt.subSequence(0, termAtt.length()))) {
All options and trade-offs4 options · 587 words
One fix was built and validated in a scratch worktree at ea57360912ed (gradle, JDK 25; removed afterwards); an alternative was run against this doc's test. Workaround in every affected release: do not use RegexpQueryHandler (the default presearcher selects every regexp query), or use a copy of the handler with the fix.
Replace curTermLength by curCodePointCount at :89, :108 and :117, so the size uses the unit the bound check (:110) and the slicing (:112-114) already use. BMP tokens are unchanged, since both units agree. Diffs: codepoint-fix.diff (code only) and fix-with-test.diff (with both tests; applies cleanly at ea57360912ed).
@@ -86,7 +86,7 @@ final class SuffixingNGramTokenFilter extends TokenFilter {
         curCodePointCount = Character.codePointCount(termAtt, 0, termAtt.length());
-        curGramSize = curTermLength;
+        curGramSize = curCodePointCount;
@@ -105,7 +105,7 @@ final class SuffixingNGramTokenFilter extends TokenFilter {
         ++curPos;
-        curGramSize = curTermLength - curPos;
+        curGramSize = curCodePointCount - curPos;
@@ -114,7 +114,7 @@ final class SuffixingNGramTokenFilter extends TokenFilter {
-        if ((curGramSize == curTermLength - curPos)
+        if ((curGramSize == curCodePointCount - curPos)
             && !seenSuffixes.add(termAtt.subSequence(0, termAtt.length()))) {
Trade-offs
- Tokens with supplementary characters now get their substrings, so the presearcher query grows for them; the per-token count stays within the bound BMP tokens already reach (1 + c(c+1)/2 + 1 for c code points): a 30-char token of 15 different emoji gives 122 terms, a 30-char BMP token already 457.
- No performance benchmark was run (only tokens with surrogate pairs change); not reviewed by a committer.
What the checks validated
- Stock: the doc's 3 tests and the new tokenizer case fail (4 of the 8 tests in the two classes), assertions on and off; with the fix all 8 pass, assertions on and off (gradle).
- The whole monitor module with the fix: 33 classes, 185 tests (181 upstream + 4 new), 0 failures, 1 skipped, assertions on and off.
:lucene:monitor:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- The harness with the fixed class shadowed: the doc's test 3 run, 0 failed,
-eaand-da. The class is byte-identical to the hunt's, with which the finder's, the independent reproducer's, the GPT-5.6 reviewer's and the devil's advocate's tests pass, the exhaustive check finds 0 missing substrings, and 8.2.0 passes.
:99 compares the UTF-16 length with maxTokenLength, so a token of 16 emoji (32 chars) takes the wildcard path. That only over-selects (the query runs and is checked), so it is safe; the javadoc ("the maximum length of an input token") names no unit.
Trade-offs
Not needed for correctness; the tokens of 31-60 UTF-16 chars that have at most 30 code points would be ngrammed instead of wildcarded (more terms, fewer queries run); a 32-char token with one surrogate pair has 31 code points and would still be wildcarded. Not validated.
if (curTermLength > maxTokenLength || curTermLength != curCodePointCount) at :99 (option-wildcard.diff).
Trade-offs
Every regexp query on that field then runs for every document batch with such a token, which defeats the handler's filtering for emoji-rich text; the recommended fix is as small and keeps the filtering.
What the checks validated
Both Monitor tests of this doc pass; testShortTokenIsNgrammed fails by design (it asserts the substrings; got [a😀, __WILDCARD__]).
Not recommended.
Trade-offs
Leaves silent misses for ordinary text in the opt-in configuration.
The document author controls the trigger: one supplementary character attached to a short word hides it from the regexp rules whose literal only that word supplies; under StandardAnalyzer a default-ignorable variation selector (U+E0100), normally not rendered, works. Only regexp rules fail open: no false matches, hang or data exposure. Out of scope under SECURITY.md; no exploit or affected deployment known.
Semi-formal. An AI tool modelling the Monitor's presearcher noticed by code reading that the filter mixes UTF-16 length and code-point count. A bounded-exhaustive check of the stock jar (all 1,560 inputs of 1-2 words of 1-3 code points over a, b and 😀) found missing substrings in exactly the 1,350 inputs with the emoji. A public-API JUnit confirmed it.
The method in full176 words
Method: semi-formal (a code-reading hypothesis witnessed by bounded-exhaustive translation validation), a hunt unit (monitor and presearcher, 2026-10-26).
- While modelling the document side of the presearcher, the finder (an AI tool) read
SuffixingNGramTokenFilterand saw the UTF-16 length and the code-point count mixed in one loop. No formal tool produced the first signal. - It then ran every input of 1-2 tokens of 1-3 code points over {a, b, U+1F600} (1,560 inputs) through
RegexpQueryHandler.wrapTermStreamon the stock jar against an exact reference (every code-point substring plusXX): 1,350 inputs miss required substrings, exactly those that contain U+1F600, and 0 of the 210 BMP-only inputs; with the fix, 0. - It minimised this into a public-API JUnit on the stock jars. Then: a refute review by an independent reviewer from another model family (OpenAI GPT-5.6, reading only), an independent reproducer, a GPT-5.6 "works as designed" review whose test design was executed, a devil's advocate with stock analyzers, an adjudication, a release sweep, a prior-report search, a security screen, a credibility audit, and this doc's own test and fix validation.
No prior report found (2026-10-26, 213 recorded queries and reads): GitHub issues and PRs, every open PR's files, commits, the dev@, java-user@, issues@ and commits@ lists, JIRA, the original Luwak project and downstream projects. Precedents for the same kind of fix: LUCENE-5042, LUCENE-5269, #15899.
Searches5 searches
Verdict new. No issue, PR, commit, list thread, JIRA entry, Luwak issue or downstream report describes SuffixingNGramTokenFilter emitting no ngrams for tokens with supplementary characters or the resulting RegexpQueryHandler misses; no issue or PR anywhere on GitHub names either class. Precedents, not reports: LUCENE-5042 (#6106) and LUCENE-5269 (#6333), 2013, the same mix-up fixed in analysis-common's n-gram filters; #15899/#15900 (2026), TruncateTokenFilter. Luwak PR #149 (2017) reports presearcher false negatives with a query-side cause; it belongs to the sibling LFV-322. Limits: private security reports are not searchable; GitHub search does not index code or review comments (the relevant threads were read directly); searches cannot prove absence.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs, commits, downstream repositories, mailing lists, JIRA, web | 2026-10-26 | a scripted prior-report search in 4 runs, 127 queries (class and field names, supplementary character, surrogate, code point, emoji, ngram, presearcher, luwak, false negative) | 0 high hits; medium hits are analysis-common n-gram and Unicode work (LUCENE-5042, -5269 and others) and monitor feature requests |
| GitHub search (apache/lucene, Elasticsearch, OpenSearch, Solr, Luwak, all of GitHub) | 2026-10-26 | 66 GraphQL queries (GitHub's search rate limit was saturated) | no issue or PR names either class; #10988 (a flaky test of another monitor class) only |
| Open PRs and branch history | 2026-10-26 | the changed files of all 411 open apache/lucene PRs; commits by path on main, branch_10x, branch_10_6, branch_9x | 9 open PRs touch lucene/monitor, none either file; only the import and cosmetic commits |
| Introducing change and predecessor | 2026-10-26 | LUCENE-8766 (28 comments) and its import PR; the 191 Luwak issues and PRs of the follow-up's list (Luwak has 192; the one not listed, PR #188, is a dependency bump) and Luwak's file history | no mention of Unicode or surrogates; Luwak master has the same lines; Luwak #149 is query-side |
| Downstream and web | 2026-10-26 | apache/solr#2382 read; a Monitor-based grep tool's 216 issues and PRs; 11 web and 3 Stack Exchange searches | nothing about this bug |
In the filter since the monitor module was added (LUCENE-8766, 2019; first released in 8.2.0), from the donated Luwak code, and never changed in behaviour. Executed on 14 releases from 8.2.0 to 10.5.2 and on main: all affected. Not a regression; not fixed upstream.
Versions tested6 rows
Introduced by LUCENE-8766 "Add monitor subproject" (by @romseygeek, 2019-06-13): 251dbe7cea8 on the main line and b8773d13ad8 on branch_8x the same day, with an identical file; GitHub does not record the import PR apache/lucene-solr#648 as merged, but its one comment says "This has been merged."; the code landed through these commits. git blame puts :89, :108 and :110 on 251dbe7cea8 and :117 on the LUCENE-9570 reformat, which only rewrapped it (251dbe7cea8 already has the same three UTF-16 uses). The later commits (LUCENE-9570, #13413, #16063) change no behaviour. The code is older than Lucene: Luwak's master has the same lines (file last changed 2016). The 48 release tags of the history clone that have the file (8.2.0-8.8.1, 9.0.0-10.5.2) all contain the four lines; the others were executed. Upstream main, branch_10x and branch_10_6 have no behaviour change to either file (read, not built).
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | this doc's test 3/3 fail (gradle and harness, -ea and -da); finder 2/2, the independent reproduction 2 of 3, the cross-model review 2/2, the intended-behaviour check 2/2 |
| 10.0.0-10.5.2 | affected | 10.0.0 and 10.5.2 executed (main() repro); this doc's test 3/3 fail on 10.5.2 |
| 9.0.0-9.12.3 | affected | 9.0.0 and 9.12.3 executed; this doc's test 3/3 fail on 9.12.3 |
| 8.2.0-8.11.4 | affected | 8.2.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0-8.11.4 executed (main() repro) |
| 8.1.1 and older | no module | no lucene-monitor artifact |
| fix (code-point gram size) on main and 8.2.0 | not affected | this doc's test, the new tokenizer case and 185 monitor-module tests pass on main, -ea and -da; the main() repro passes on 8.2.0 |
An independent reproducer, a devil's advocate and an adjudication, each running tests on main, said real, as did a "works as designed" review from another model family (OpenAI GPT-5.6, reading only); an earlier GPT-5.6 review said "not real" only because it could not run code. An audit and this doc re-ran it on releases and with the fix.
Checks and verdicts385 words
Every check ran on main ea57360912ed; the GPT-5.6 reviews could read code but not run it, and a separate run re-ran the finder's repro (it failed both times).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Exhaustive tier: 1,350 of 1,560 inputs miss substrings, exactly those with U+1F600; JUnit 2/2 fail on main (-ea, -da), 10.5.2 and 9.12.3; passes with the fix. |
| refute review (GPT-5.6, reading only) | not real, low (procedural) | Could not run any command, so it voted not real on procedure only; it agreed with the root cause and the inputs and rated the intended argument weak. A separate run re-ran the repro: it failed. |
| Independent reproducer | real | Own JUnit in another package from the claim alone, ground truth Presearcher.NO_FILTERING: 2 of 3 fail on main (-ea, -da), 10.5.2 and 9.12.3 (the BMP control passes); its main() fails on 8.2.0 and 8.11.4; passes with the fix. |
| "works as designed" review (GPT-5.6, reading only) | real, high | Intended argument weak. The reviewer's test design (Q🚀Z, control QAZ) was executed: 2/2 fail on main, 10.5.2 and 9.12.3; passes with the fix. |
| Devil's advocate | real | Built the strongest intended case ("an example", opt-in, ASCII-only tests) and rejected it; stock-analyzer test (StandardAnalyzer on Adlam and Osage, KeywordAnalyzer with an emoji) 2/2 fail, passes with the fix; showed StandardAnalyzer splits an emoji off a Latin word but not U+1D400. |
| adjudication | confirmed, high | Re-ran the independent reproduction's test on main -ea and -da (3 run, 2 failed) and with the fix (0 failed). |
| security screen | out of scope of SECURITY.md | Exhaustive probe: 0 false matches, 2,478 of 4,520 true pairs missed, all regexp; corrected the earlier note that the trick fails under StandardAnalyzer (the default-ignorable U+E0100 and U+E0041 and the letter U+1D400 still hide a word). |
| credibility audit | keep | 4th independent re-run: finder JUnit 2/2 on main -ea, -da and 10.5.2 -da; the intended-behaviour check's test 2/2 on main -da and 0 with the fix; distinct from LFV-322. |
| this doc | fails on stock, passes with the fix | Own 3-test JUnit: 3/3 fail on main (gradle and harness, -ea and -da), 10.5.2 and 9.12.3; with the fix it, a new tokenizer case and the whole monitor module (185 tests) pass, -ea and -da. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 471 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,218 words
- Registry title
- Monitor with RegexpQueryHandler silently misses regexp matches on any short token that contains a supplementary character (an emoji, a CJK Extension B ideograph, a Gothic or Adlam letter), because SuffixingNGramTokenFilter emits no ngrams for that token
- Area
- monitor / presearcher (RegexpQueryHandler document-side ngram filter SuffixingNGramTokenFilter)
- Priority
- Medium, rank 68: This is a second deterministic silent miss in the opt-in Monitor RegexpQueryHandler, triggered by ordinary text such as an emoji glued to a short word, but it hits fewer inputs than LFV-322.
- Impact class
- silent wrong results
- Impact note
- Applications whose Monitor uses TermFilteredPresearcher (or, by code reading, MultipassTermFilteredPresearcher) with the opt-in RegexpQueryHandler: any document token of at most maxTokenSize UTF-16 units (default 30) that contains a supplementary character gets no ngrams, so Monitor.match silently skips every RegexpQuery that needs a substring of that token (0 queries run, no error) unless another term of the same field supplies the gram; ordinary text triggers it (an emoji glued to a word under whitespace or keyword tokenization; a word in a supplementary-plane script such as Adlam or Osage, a mathematical letter or a supplementary variation selector even under StandardAnalyzer, which does split an emoji off a Latin word), at tiny inputs, with -ea and -da, in every lucene-monitor release from 8.2.0 to 10.6.0 (10.6.0 by reading) and main; it never causes false matches, term queries and BMP-only tokens are unaffected, and the default presearcher without the handler is not affected.
- Summary
- You build a Monitor whose presearcher uses RegexpQueryHandler, register the query /hel.*/ and match a document whose text is 'hello😀' (WhitespaceAnalyzer, one token). You expect a match, because the regexp matches that token and the presearcher may only skip queries that cannot match. Instead SuffixingNGramTokenFilter, which should emit every substring of the token with the suffix 'XX' so that the query's index term 'helXX' is found, starts its gram size at the token's UTF-16 length (7) but checks it against the token's code-point count (6), gives up on the token without emitting a single ngram, and the query is silently never run.
- Introduced
- 251dbe7cea81 (LUCENE-8766 'Add monitor subproject', by GitHub romseygeek, main) and its branch_8x twin b8773d13ad8e (same date; SuffixingNGramTokenFilter.java and RegexpQueryHandler.java byte-identical), released in 8.2.0 [read: git blame of SuffixingNGramTokenFilter.java:89, :108, :110 and :117 on main gives 251dbe7cea81, and git log -S 'curGramSize = curTermLength' finds only the import; exec: fails on 8.2.0, the first lucene-monitor release]; not a regression: the defect is in the file's first Lucene version, and the later commits 2cbf261032dc (LUCENE-9570 reformat), 40f674c5d3d3 (#13413 imports) and c2825cfc4b2a (#16063 final modifiers) are behaviour-neutral; the same lines are in the donated Luwak class (flaxsearch/luwak master, file last changed 2016-11-28) [read] (2019-06-13 (251dbe7cea81 on main and b8773d13ad8e on branch_8x the same day; first released in 8.2.0))
- First affected version
- 8.2.0 [exec] (the first lucene-monitor release; 8.1.1 has no monitor module: the lucene-monitor 8.1.1 artifact does not exist on Maven Central, setup error [exec]); 9.0.0 [exec] on the main line
- Affected versions
- every lucene-monitor release, 8.2.0 to 10.6.0 (57 versions to 10.5.2; 10.6.0 by reading), and main ea57360912ed; no fixed release. [exec, follow-up version-portable main() repro, -ea] 8.2.0, 8.8.2, 8.9.0, 8.10.0, 8.10.1, 8.11.0, 8.11.1, 8.11.2, 8.11.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main; the finder's JUnit fails 2 of 2 on main (-ea, -da), 10.5.2 and 9.12.3; the independent reproduction's own JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3 and its main() variant on 8.2.0 and 8.11.4; a separate JUnit fails on main, 10.5.2 and 9.12.3; the security probe gives identical results on main (-ea, -da), 10.5.2 (-da) and 9.12.3 (-da); [read] all four defect lines are present at each of the 48 release tags 8.2.0-8.8.1 and 9.0.0-10.5.2 in the history clone; the fix sketch makes 8.2.0 and main pass [exec]; upstream main, branch_10x and branch_10_6 have no behaviour change to either file (commits by path, read 2026-10-26), but those branches were not built
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check, code reading
- Upstream and prior reports
- none found (2026-10-26, the prior-report record verdict new, 213 recorded queries and reads: a scripted prior-report search in 4 runs, 127 queries over GitHub issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the JIRA archive and 6 web queries, 0 high hits; 66 GitHub GraphQL searches of apache/lucene, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, flaxsearch/luwak and all of GitHub (GitHub's search rate limit was saturated); the changed files of all 411 open apache/lucene PRs (9 touch lucene/monitor, none touches SuffixingNGramTokenFilter.java or RegexpQueryHandler.java); commits by path on upstream main, branch_10x, branch_10_6 and branch_9x (only the import and cosmetic commits); LUCENE-8766's 28 JIRA comments and its import PR apache/lucene-solr#648; all 191 flaxsearch/luwak issues and PRs (Luwak master still has the defect); apache/solr#2382 and the 216 issues and PRs of a Monitor-based grep tool; 5 more web and 3 Stack Exchange searches). Not fixed upstream. Gaps: private reports to security@lucene.apache.org cannot be searched; GitHub search does not index code or review comments (the relevant threads were read directly); searches cannot prove absence
- Lucene commit tested
- main
ea57360912ed(2026-10-26): this doc's test through gradle with assertions on and off and through the repro harness, also on the 10.5.2 and 9.12.3 release jars; a version-portablemain()on 14 releases from 8.2.0 to 10.5.2 and on main; the recommended fix in a scratch worktree atea57360912ed(removed afterwards): this doc's test, a newTestSuffixingNGramTokenizercase and the whole monitor module (185 tests) with assertions on and off, and the module's static checks; an alternative fix against this doc's test.
- Finding record
lucene/monitor/src/java/org/apache/lucene/monitor/SuffixingNGramTokenFilter.java:60, :84-96, :99-104, :106-134 (read at ea57360912ed)lucene/monitor/src/java/org/apache/lucene/monitor/RegexpQueryHandler.java:29-31 (class javadoc), :43-47 (defaults), :90-93 (wrapTermStream), :96-114 (handleQuery)lucene/monitor/src/java/org/apache/lucene/monitor/TermFilteredPresearcher.java:100-113 (buildQuery wraps each field's document terms with every handler)lucene/monitor/src/java/org/apache/lucene/monitor/package-info.java:60-61 ('avoid running queries that have no chance of matching'), :91-95 (RegexpQueryHandler 'gives an example')
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/SuffixingNGramTokenFilter.java:60, :76-136 (read)Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/RegexpQueryHandler.java:29-31, :41-47, :90-93, :96-114 (read)Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/TermFilteredPresearcher.java:100-113; Monitor.java:224, :294-299; package-info.java:55-63 (read)Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/TermsEnumTokenStream.java:27-30; RegexpQueryHandler.java:91, :113; Monitor.java:218-225 (read)
- Who is affected
Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/TermFilteredPresearcher.java:100 (final buildQuery); MultipassTermFilteredPresearcher.java:55, :75
- Why it looks unintended
Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/RegexpQueryHandler.java:29-31; SuffixingNGramTokenFilter.java:60, :88-89, :108-117; package-info.java:60-61, :93-95 (read)Lucene main ea57360912ed: lucene/monitor/src/test/org/apache/lucene/monitor/TestSuffixingNGramTokenizer.java, TestRegexpQueryHandler.java, TestWildcardTermPresearcher.java:25, :93 (read)Lucene main ea57360912ed: lucene/CHANGES.txt:1182-1184, :1743-1746, :5370-5372, :13215-13216, :13522-13524 (read)Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/RegexpQueryHandler.java:64, :91; SuffixingNGramTokenFilter.java:84, :99; lucene/core/src/java/org/apache/lucene/search/RegexpQuery.java:40 (read)
- Suggested fix
Lucene main ea57360912ed: lucene/monitor/src/java/org/apache/lucene/monitor/SuffixingNGramTokenFilter.java:99-104; RegexpQueryHandler.java:62-63, :83
- TestRegexpQueryHandlerSupplementaryChar.java (JUnit test):
repro/LFV-347/src/org/apache/lucene/monitor/TestRegexpQueryHandlerSupplementaryChar.java(42 lines)
Made in parallel with this doc from an executed probe on main ea57360912ed (-ea, -da, and with the fix): the emitted terms of hello, hello😀 and a😀, the query's index terms and the match results. The PNG is the final summary card.
assets/LFV-347/bug.png(471 KB)