WordDelimiterGraphFilter drops a token made only of delimiters and leaves a hole in its place. With IGNORE_KEYWORDS, a keyword right after that token should keep the hole in front of it.
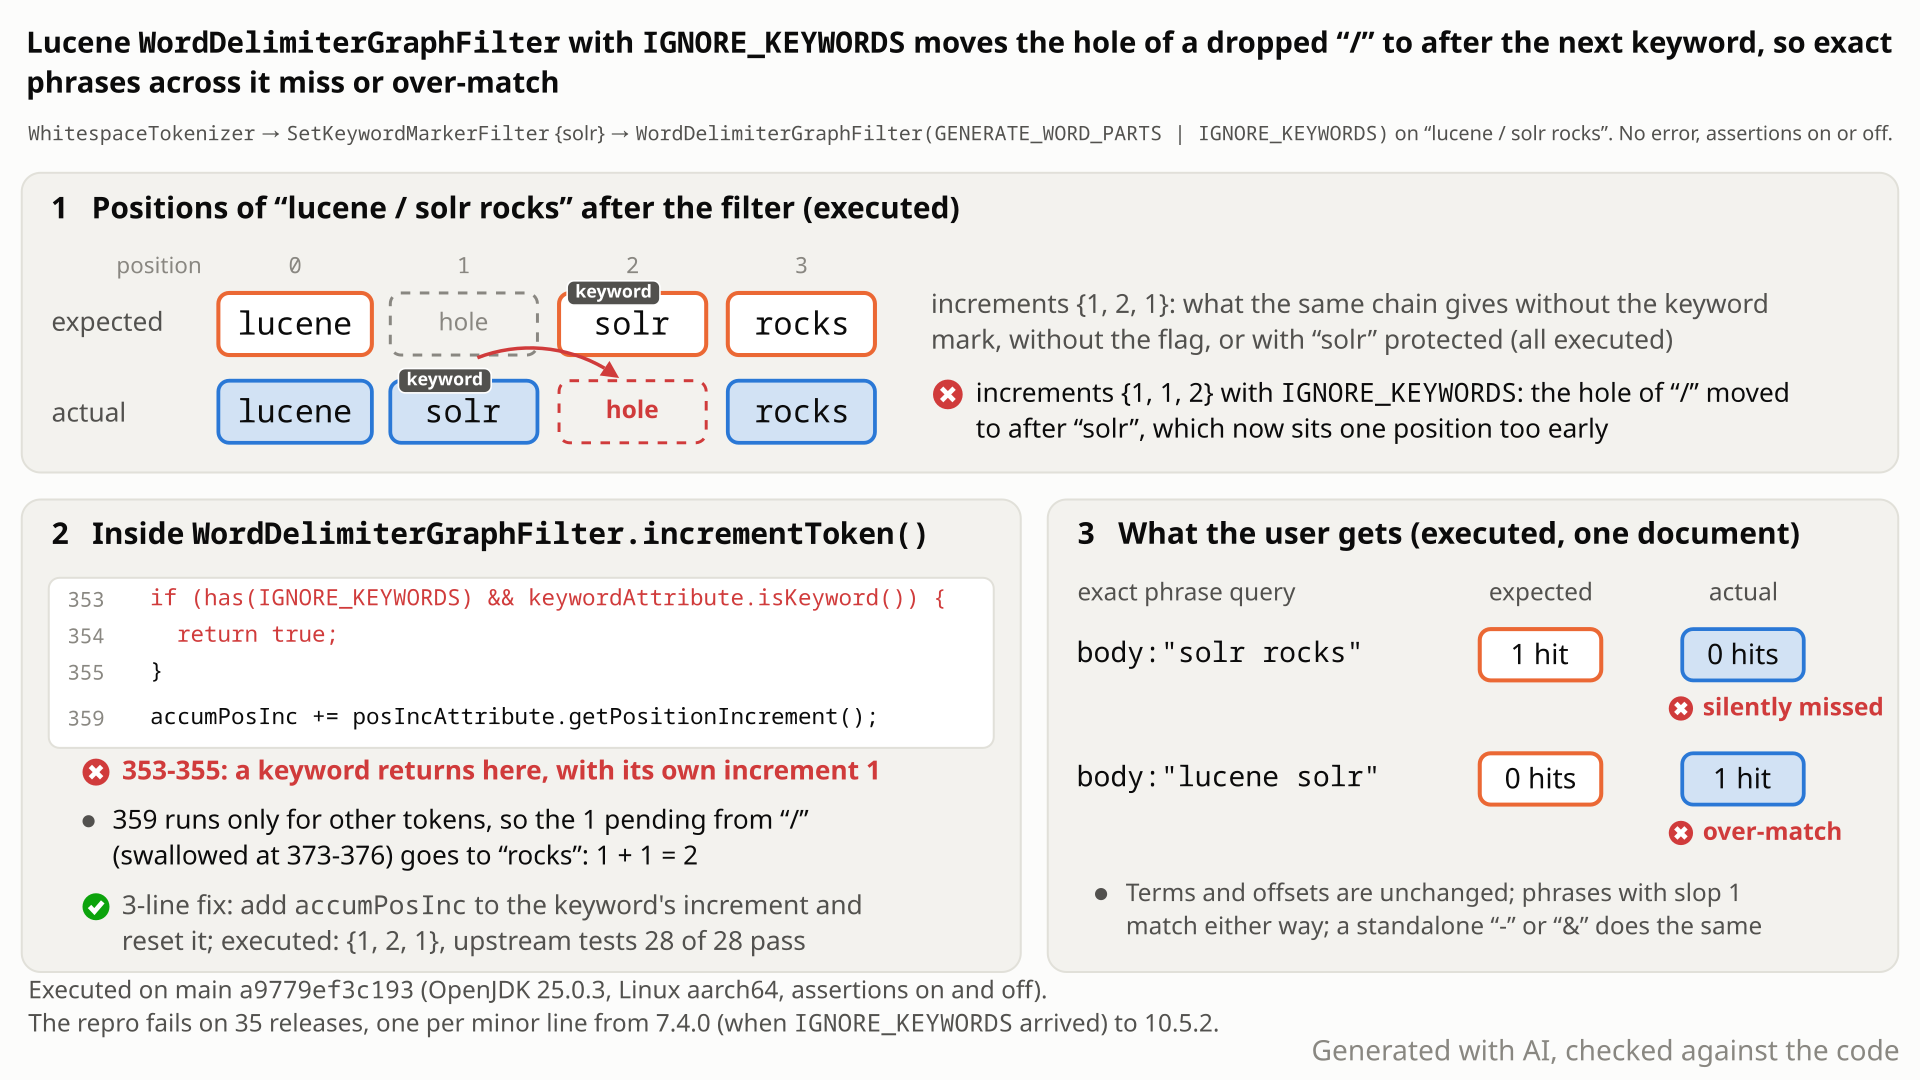
lucene / solr rocks: with IGNORE_KEYWORDS the keyword returns before the hole of the dropped / is applied, so the hole moves behind solr, "solr rocks" misses and "lucene solr" matches. Select the still to open it at full size. Generated with AI, checked against the code.- Analyze
lucene / solr rockswith a whitespace tokenizer, a keyword marker forsolr, andWordDelimiterGraphFilter(GENERATE_WORD_PARTS | IGNORE_KEYWORDS). The/is only a delimiter, so the filter drops it and leaves a one-position hole. - You expect the hole to stay where the
/was:luceneat 0,solrat 2,rocksat 3 (increments{1, 2, 1}). That is what you get whensolris a plain word, a protected word, or marked without the flag. - You get
{1, 1, 2}:solrsits at 1, right afterlucene, and the hole opens betweensolrandrocks. The keyword is returned before the line that applies pending holes, so the hole lands on the next non-keyword token. - With the same analyzer at index and query time, on that one document the exact phrase "solr rocks" gets 0 hits instead of 1, and "lucene solr" gets 1 hit instead of 0. Span and interval phrases miss too. Terms, offsets and term queries are unaffected, and a phrase slop of 1 hides this one-position shift (not a larger one).
- The fraction example from LUCENE-8265's description breaks the same way: with fractions marked as keywords,
1/2 - 3/4 inchloses the phrase "3/4 inch" (0 hits) and gains "1/2 3/4" (1 hit). No error is raised.
Applications that turn on the opt-in IGNORE_KEYWORDS flag (factory ignoreKeywords since 9.9.0) behind a keyword marker, with whitespace-style tokenization. Ordinary text triggers it: a spaced /, - or & before a marked word. Exact phrase, span and interval queries across that spot silently miss or over-match.
Mechanism, terms and numbers602 words
WordDelimiterGraphFilter drops a token made only of delimiters, such as the / in lucene / solr rocks under the whitespace tokenization its javadoc recommends, and leaves a hole, so solr gets position increment 2 (WordDelimiterGraphFilter.java:373-376; asserted upstream for LUCENE / SOLR). With the opt-in IGNORE_KEYWORDS flag and solr marked as a keyword, the increments become {1, 1, 2}: the keyword slides back into the hole and the gap reappears between solr and rocks, two words that are adjacent in the text. The keyword early return (:353-355) runs before the line that collects pending holes (:359), so the hole skips the keyword and lands on the next non-keyword token. The protected-word bypass in the same method keeps the hole, and so does the keyword mark without the flag. With the same analyzer at index and query time, exact phrase, span and interval queries across the keyword miss ("solr rocks": 0 of 1) or match across the dropped token ("lucene solr": 2 instead of 0). It arrived with the flag in 7.4.0 (LUCENE-8265) and fails on every release run from 7.4.0 to 10.5.2 and on main. A 3-line fix (4 after formatting) applies the pending hole to the keyword.
- Position increment: how many positions a token moves forward from the previous one. 1 means adjacent; 2 means one position is empty, a hole. Exact phrase queries need adjacent positions.
- Dropped (swallowed) token:
WordDelimiterGraphFilteremits nothing for a token made only of delimiters, such as a standalone/,-or&under a whitespace tokenizer, or for a token whose parts the flags do not generate. It leaves a hole instead ("swallow this token, creating a hole",:373). - Keyword: a token whose
KeywordAttributeis set by a marker such asSetKeywordMarkerFilter. WithIGNORE_KEYWORDSthe filter passes it through without splitting it (:148).
accumPosInc(:187-188, "so that we preserve incoming holes") collects the increment of every non-keyword input token (:359). Plain and protected words (:368-369) and word parts (:422-423) take the whole amount and reset it.- A dropped token leaves its increment pending: a delimiter-only token
continues at:376, and a delimited token with no parts under the flags falls through at:430. That pending amount is the hole. - The keyword return at
:353-355comes before:359. The keyword leaves with its own increment (1), and the pending amount goes to the next non-keyword token on top of its own. lucene / solr rocks:lucene+1 (position 0),/dropped (pending 1),solr+1 (position 1, should be 2),rocks1 + 1 = +2 (position 3). Only the keyword moves, back into the hole.
Same shift for - and &, for a token with no parts under the flags (1-2 a-b solr rocks with number parts only), for two keywords in a row ({1, 1, 1, 2} instead of {1, 2, 1, 1}), for a larger incoming hole (solr +1 and rocks +11 instead of +11 and +1), and for two dropped tokens in a row (lucene / - solr rocks: solr at 1 instead of 3). A trailing keyword (lucene / solr) ends one position earlier than without the mark. Not affected: PRESERVE_ORIGINAL (the / is kept, no hole), a hole from a StopFilter right before the keyword, a keyword before the /, and the deprecated WordDelimiterFilter (it leaves no hole for /).
Exposure and likelihood345 words
- Who is exposed. Users of
WordDelimiterGraphFilterwithIGNORE_KEYWORDS(the Java flag since 7.4.0; the factory parameterignoreKeywordssince 9.9.0, default 0), a keyword-marking filter in front (KeywordMarkerFilter,SetKeywordMarkerFilter,PatternKeywordMarkerFilter, or anything that setsKeywordAttribute), andPRESERVE_ORIGINALoff (the default). - What it takes. A marked token directly after a token the filter drops. Under the whitespace tokenization the class javadoc recommends, a spaced
/,-or&is such a token. The fraction example in LUCENE-8265's description hits it: it wanted fractions marked as keywords "so that 1/2 does not become 12", and1/2 - 3/4 inchthen loses the phrase "3/4 inch". - What the damage looks like. In the ordinary linear chain, wrong positions in the index and no error. Exact phrase,
PhraseQuery, span and interval queries across the spot miss ("solr rocks": 0 of 1) or match across the dropped token ("lucene solr": 2 instead of 0). A phrase that quotes the whole text,/included, still matches, because query analysis shifts the same way. Terms, offsets, and term and boolean queries are unaffected. A phrase slop of 1 hides a one-position shift but not a larger one: with two dropped tokens (lucene / - solr rocks), "solr rocks"~1 still misses and "lucene solr"~1 still matches. In a multi-valued field the pending hole does not carry into the next value, but a phrase across the value boundary sees the shifted positions of the value before it (valueslucene / solrandrocks: "lucene solr rocks" matches). - Scale. Deterministic, per occurrence, any index size, assertions on or off. Each keyword after a dropped token moves back by that token's increment (1, or more if a hole came with it or several tokens were dropped).
- How likely. Plausible rather than common: opt-in, the keyword must directly follow such a token, only exact positional queries across that spot change, and no report was found.
- After a fix. Positions are written at index time, so documents indexed before the fix keep the shifted positions until they are reindexed.
The test shows that with IGNORE_KEYWORDS, WordDelimiterGraphFilter returns a keyword token before applying the hole left by a swallowed delimiter-only token, so the hole moves to after the keyword.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import static org.apache.lucene.analysis.miscellaneous.WordDelimiterGraphFilter.GENERATE_WORD_PARTS;
import static org.apache.lucene.analysis.miscellaneous.WordDelimiterGraphFilter.IGNORE_KEYWORDS;

import java.io.StringReader;
import java.util.List;
import org.apache.lucene.analysis.CharArraySet;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestWdgfIgnoreKeywordsHole extends BaseTokenStreamTestCase {

  public void testHoleStaysBeforeKeyword() throws Exception {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("lucene / solr rocks"));
    TokenStream ts =
        new WordDelimiterGraphFilter(
            new SetKeywordMarkerFilter(tokenizer, new CharArraySet(List.of("solr"), false)),
            GENERATE_WORD_PARTS | IGNORE_KEYWORDS,
            null);
    // the hole of the swallowed "/" must stay before keyword "solr": expected {1,2,1}, actual {1,1,2}
    assertTokenStreamContents(ts, new String[] {"lucene", "solr", "rocks"}, new int[] {1, 2, 1});
  }
}
# in a copy of this finding's repro folder (repro/LFV-353/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestWdgfIgnoreKeywordsHole
- Expected vs actual
- Expected position increments for
lucene / solr rockswithsolrmarked as a keyword:{1, 2, 1}. Actual:{1, 1, 2}(posIncrement 1 term=solr expected:<2> but was:<1>, with-eaand-da).
More files, environment, full output41 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: posIncrement 1 term=solr expected:<2> but was:<1>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:274)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:513)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:598)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:622)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:699)
org.apache.lucene.analysis.miscellaneous.TestWdgfIgnoreKeywordsHole.testHoleStaysBeforeKeyword(TestWdgfIgnoreKeywordsHole.java:41)- The class promises a correct token graph "so that e.g. PhraseQuery can work correctly", and
accumPosIncexists "so that we preserve incoming holes". - Protected words take the pending hole (
:366-370): a protectedwi-fiafter a dropped/keeps it, a keyword-markedwi-filoses it. - LUCENE-8265, which added the flag, never discussed positions; its only test has no dropped token.
The full argument302 words
- The contract. Class javadoc
WordDelimiterGraphFilter.java:38-40: "producing a correct token graph so that e.g. PhraseQuery can work correctly when this filter is used in the search-time analyzer".:187:accumPosIncis "used for accumulating position increment gaps so that we preserve incoming holes".:373: "word of simply delimiters: swallow this token, creating a hole".:148: the flag "Suppresses processing terms with KeywordAttribute#isKeyword()=true", which speaks of the keyword term, not of a hole that belongs to an earlier token. - The analysis package rule.
package-info.java:303-305: "a filter that filters out tokens must increment the position increment in order not to generate corrupt tokenstream graphs"; itsStopFilterexample (:307-326) adds the accumulated increment to the next returned token, whatever it is. - Upstream tests.
TestWordDelimiterGraphFilter.java:328-338("in this case, works as expected."):LUCENE / SOLR->{1, 2};:352-361:LUCENE / NUTCH SOLR->{1, 2, 1}, a word after the dropped/keeps the hole. (NUTCHis protected but has no delimiter, so it takes the plain-word half of:366and the protected set is never consulted; a protected word with a delimiter keeps the hole too:lucene / wi-fi rockswithwi-fiprotected gives{1, 2, 1}, executed.)testKeywordFilter(:466-481), the only test added with the flag, has no dropped token, so nothing pins the current behaviour. - History. LUCENE-7619 added the filter to "produce holes properly" (2017). LUCENE-8265 (2018) added the flag; its discussion is about overloading
KeywordAttribute, never positions. LUCENE-8395 (#9442, fixed in 7.5.0) fixed a misplaced hole in the same bookkeeping on thePRESERVE_ORIGINALbranch, so a wrongly placed hole in this filter has been treated as a bug before. None of the javadoc, tests, CHANGES entries and recorded discussions that were reviewed says the shifted increments are by design.
The devil's-advocate check262 words
The strongest case for "intended" (the cross-model reviews rated it moderate, the devil's-advocate verifier weak): IGNORE_KEYWORDS is a literal pass-through. The javadoc says processing is suppressed, CHANGES says the option lets the filter "skip tokens marked with KeywordAttribute", the deprecated WordDelimiterFilter has the same early return, and returning the keyword with its own increment of 1 is exactly "untouched".
Why it fails: the pending increment belongs to an earlier token that the filter itself removed, and the package rule puts it on the next returned token, here the keyword. The current code does not leave positions alone either: the keyword moves from 2 to 1 and a gap opens between two adjacent words. The protected-word bypass, the static sibling the keyword option was requested as an alternative to (LUCENE-7342), keeps the hole, and so does the same keyword with the flag off. The deprecated WordDelimiterFilter (used instead of this filter) and ProtectedTermFilter around this filter give {1, 1, 1}: they drop the hole consistently and move no gap, so they are no precedent for {1, 1, 2}.
How strong the case is depends on the sub-case: weak for a keyword followed by another token (the main claim); moderate for a trailing keyword, because the filter reports no hole at the end of the stream in any configuration (the separate bug LFV-354), so the claim there is only the lost +1; strong for a stacked synonym in front of the filter, which feeds it a token graph it says it cannot consume, so that chain is left out of the claim.
Recommended Apply the pending hole in the keyword branch (validated)
In the keyword branch, add the pending accumPosInc to the keyword's own increment and reset it (3 lines, 4 after formatting). Nothing changes when no hole is pending. With it, the new tests and the whole analysis-common module (1,913 tests) pass with assertions on and off. Documents indexed before the fix keep the shifted positions until reindexed.
if (has(IGNORE_KEYWORDS) && keywordAttribute.isKeyword()) {
  // apply any hole left by previously swallowed tokens to this keyword token
  posIncAttribute.setPositionIncrement(
      accumPosInc + posIncAttribute.getPositionIncrement());
  accumPosInc = 0;
  return true;
}
All options and trade-offs3 options · 516 words
Two equivalent shapes were built in a scratch worktree of main a9779ef3c193; A is the smallest and was run against the whole module. Workarounds for affected releases follow.
The keyword is still returned without splitting or catenation; it only takes the increment that the filter owes for tokens it dropped just before it, as plain and protected words already do (:368-369).
if (has(IGNORE_KEYWORDS) && keywordAttribute.isKeyword()) {
  // apply any hole left by previously swallowed tokens to this keyword token
  posIncAttribute.setPositionIncrement(
      accumPosInc + posIncAttribute.getPositionIncrement());
  accumPosInc = 0;
  return true;
}
Trade-offs
- No change when no hole is pending: the keyword keeps its own increment.
- With the fix, two dropped tokens in a row and a two-valued field also give the positions of the chain without the mark (executed).
- Behaviour change only for the affected inputs: positions become those of the chain without the mark, so phrases that matched across the dropped token ("lucene solr") stop matching, which is the intent.
- Existing indexes keep the old positions until reindexed; query-side analysis changes at once.
- A stacked keyword (incoming increment 0) right after a dropped token now takes the hole too.
- The same lines exist on every maintained branch, so the patch should apply as is; only main was built.
What the checks validated
- Stock: 32 tests, 4 failed (this doc's 3 and the upstream-suite method), assertions on and off.
- Fix: the same 32 tests pass, assertions on and off; the whole analysis-common module, 340 classes, 1,913 tests, 0 failures, 18 skipped, assertions on and off;
check -x test(formatting, lint, forbidden APIs) passes. - Earlier, with the finder's equivalent fix: the finder's test 3 of 3, the independent reproducer's 7 of 7 and the security probe's 6 of 6 pass.
Move accumPosInc += posIncAttribute.getPositionIncrement(); above the keyword test and, in the keyword branch, set the increment to accumPosInc and reset it, exactly like the protected-word branch.
Trade-offs
Same behaviour as the recommended option; reads as one rule (every returned token takes the pending increment) at the cost of a slightly larger diff. Only the 32 targeted tests were run (assertions on), not the whole module.
List the words as protected words (protWords, factory protected=) instead of keyword-marking them: that path keeps the hole (executed: lucene / wi-fi rocks with wi-fi protected gives {1, 2, 1}). It does not help in addition to the mark: the keyword return comes first, and a word that is both keyword-marked and protected still gives {1, 1, 2} (executed). For a word without a delimiter, simply do not keyword-mark it.
Trade-offs
Only for a fixed word list, not for pattern-based marks such as fractions. Alternatives: PRESERVE_ORIGINAL keeps the delimiter token, so no hole is pending, but it indexes punctuation tokens and changes the output for every split word; a phrase slop of 1 hides a one-position shift (not a larger one) but loses exactness everywhere.
Elasticsearch and OpenSearch expose this flag as ignore_keywords on word_delimiter_graph (default off), so their users who enable it behind a keyword marker get the same shifted phrases (read in their sources, not run there).
A bounded-exhaustive check compared the filter's output for multi-token texts with its per-token outputs joined, holes included: 157 million checks over small alphabets and all 1,024 flag combinations. Every one of the 119,632 mid-stream position mismatches involved IGNORE_KEYWORDS and a keyword (the trailing-hole mismatches are the separate LFV-354); code reading found the cause.
The method in full198 words
Method: bounded-exhaustive translation validation on the stock main jar (the hunt's "semi-formal" tier). A hunt unit, analysis graph filters, 2026-10-26.
- Oracle: the output for a whitespace-separated text equals the outputs of its tokens analysed one by one, concatenated, with a hole for every token the filter drops.
- Inputs: every text over {a, A, 1, -, space} up to length 7 (99,998,720 checks) and over {a, 1, -, ', s, space} up to length 6 (57,329,664 checks), each with all 1,024 flag combinations and with keyword and protected-word sets.
- Result: 47,044 and 72,588 mid-stream position mismatches (category M1), every one with
IGNORE_KEYWORDSand a keyword token. The split-category rerun printed no line for the same mismatch without a keyword, and the harness prints only categories it has counted, so that count was 0. The same runs reported 1,764,524 and 3,247,808 trailing-hole mismatches (category M3), many without a keyword: that is the separate bug LFV-354. Offsets were consistent. - An AI finder then read
incrementTokenfor the root cause and minimised the signal by hand into a public-API JUnit; independent AI tools reproduced and judged it (see the checks). No model checker, SMT solver or prover found or verified this bug.
No prior report: 221 queries over GitHub issues, PRs and commits, the mailing lists, JIRA, downstream repositories, forums and the web (2026-10-26); 20 hits read, none this bug. Closest: LUCENE-8395 (#9442), the same hole bookkeeping fixed on the PRESERVE_ORIGINAL branch in 7.5.0.
Searches7 searches
No issue, PR, review, JIRA entry, mailing-list thread, forum post, downstream issue or web page says that IGNORE_KEYWORDS moves or drops the hole of a dropped token. None of the 411 open PRs touches the keyword branch (the only one that touches the file, #202, changes class javadoc only). Upstream main e1c4184cb98 (2026-10-26) last changed the file on 2023-11-14 (#12805, formatting). Private reports to the security list cannot be searched, and GitHub search does not index code or review comments.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene) | 2026-10-26 | five runs of a scripted prior-report search plus 74 GraphQL searches: class, flag and field names, accumPosInc, symptoms, code-comment phrases, LUCENE-8265 and LUCENE-8395 | no report; LUCENE-8395 (#9442) is the closest, a different branch |
| Downstream repositories | 2026-10-26 | 19 GraphQL searches over Elasticsearch, OpenSearch and Solr; 8 items read in full | no report; the downstream ignore_keywords option and unrelated word_delimiter_graph phrase issues |
| JIRA (LUCENE, SOLR) | 2026-10-26 | 8 JQL searches plus the tool's JIRA queries | no report |
| Mailing lists (dev@, java-user@, issues@, commits@) | 2026-10-26 | the tool's list queries | no report |
| Forums and the web | 2026-10-26 | web searches, a forum search and 5 Stack Overflow questions | no report |
| Open PRs | 2026-10-26 | the changed files of all 411 open apache/lucene PRs | only #202 touches the file (class javadoc) |
| Related items (read) | 2026-10-26 | 29 apache/lucene items and lucene-solr PR #359 read in full | LUCENE-8265 (#9312, origin), #12522 / #12525 (factory flag), LUCENE-7619 (#8670, hole design), LUCENE-7842 (#8893, withdrawn question), LUCENE-7342 (#8396, the request behind the flag) |
Introduced together with the flag by LUCENE-8265 (fc0878cc2f9, committed 2018-04-28), first released in 7.4.0; through the factory from 9.9.0. Fails on all 35 releases run from 7.4.0 to 10.5.2 and on main; the keyword branch is unchanged upstream since 2018.
Versions tested8 rows
Introduced by LUCENE-8265 "WordDelimiterFilter should pass through terms marked as keywords" (#9312): fc0878cc2f9 on master and backport d1bf6ad79a8 on branch_7x, authored 2018-04-22 by msokolov and committed 2018-04-28 by mikemccand (proposed as lucene-solr PR #359, committed directly). The commit put the early return in front of the hole accumulator that LUCENE-7619 (637915b890d, 2017) had added. Not a regression: the bug arrived with the flag.
Factory. ignoreKeywords (#12525) is listed under 9.8.0 in CHANGES, but the 9.8.0 release rejects it (Unknown parameters: {ignoreKeywords=1}); it first shipped in 9.9.0.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | this doc's test 3 of 3 fail (gradle with assertions on and off; standalone -ea and -da); the finder's test fails with byte-identical messages (registry refresh) |
main ea57360912ed | affected | the finder's test 2 of 3 (-ea and -da, control passes); the independent 7-test JUnit 3 of 7 (4 controls pass); the factory probe fails |
| 10.5.2, 9.12.3 | affected | this doc's test 3 of 3; the finder's test 2 of 3 (-ea and -da) |
| 7.4.0 to 10.4.0 (33 releases, one per minor line) | affected | the finder's test 2 of 3 each (a two-import variant before 9.1.0); 7.4.0 also with -da |
| 9.9.0, 10.5.2, main (factory) | affected | CustomAnalyzer keywordMarker + wordDelimiterGraph ignoreKeywords=1: posIncrement 1 term=solr expected:<2> but was:<1> |
| 9.8.0 (factory) | Java API only | the factory rejects ignoreKeywords (Unknown parameters); the Java flag fails like every release |
| 7.3.1 | not affected | no IGNORE_KEYWORDS (compile error); the keyword-marked control keeps the hole |
| main + fix | not affected | the new tests pass; the analysis-common module, 1,913 tests, passes with assertions on and off |
An independent reproducer, a devil's advocate and an adjudication said real and re-ran it with assertions on and off. Reviews by another model family (reading only) agreed on the root cause; one said "not real" only because it could not run code. A later audit kept it.
Checks and verdicts336 words
Every verifier wrote or ran its own test on the stock jars; the cross-model reviews could only read code, and a separate run re-ran the finder's test for each (3 run, 2 failed).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | Public-API JUnit fails 2 of 3 on main (-ea and -da), 10.5.2 and 9.12.3, control passes; the fix sketch passes 3 of 3 and upstream TestWordDelimiterGraphFilter 28 of 28. |
| cross-model review, refute lens | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6, reading only) could not run code, so it voted not real on procedure only; it agreed with the root cause and judged the inputs in contract. |
| Independent reproducer | real | Own 7-test JUnit, written from the claim only: the 3 claim tests fail on main (-ea, -da), 10.5.2 and 9.12.3; the 4 controls pass; 7 of 7 with the fix. Diagnostics: two keywords, a larger incoming hole. |
| Cross-model review, intended lens | real (medium) | OpenAI GPT-5.6, reading only: the literal pass-through case is moderate and defeated; separate runs with another seed fail on main, 10.5.2 and 9.12.3 and pass with the fix. |
| Devil's advocate | real (high) | Intended argument weak; reproduces on main, 10.5.2 and 9.12.3; probes show a no-parts token triggers it, a StopFilter hole before a keyword is kept, and ProtectedTermFilter gives a separate behaviour. |
| adjudication | confirmed (high) | Re-ran the independent reproduction's test with a new seed (7 run, 3 failed with -ea and -da; 0 failed with the fix) and the finder's test. |
| security screen | none | Out of scope of SECURITY.md; executed the over-match direction and a stacked-keyword chain. |
| audit | keep | Fourth independent check: the finder's test fails with a new seed, -ea and -da; own probe confirms the controls and that the over-match occurs only with the keyword. |
| this doc's runs | reproduced on a9779ef3c193 | New 3-test JUnit fails 3 of 3 through gradle and the standalone runner; the fix passes the whole analysis-common module. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 440 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,362 words
- Registry title
- WordDelimiterGraphFilter with IGNORE_KEYWORDS moves the position hole of a swallowed delimiter-only token (a standalone '/', '-' or '&') to after the next keyword token, so exact phrases across the keyword miss or over-match (released since 7.4.0)
- Area
- analysis / WordDelimiterGraphFilter position increments (IGNORE_KEYWORDS keyword bypass; factory ignoreKeywords option)
- Priority
- Medium, rank 132: WordDelimiterGraphFilter with the opt-in IGNORE_KEYWORDS flag silently shifts a hole on ordinary input (a spaced '/', '-' or '&' before a keyword), and that widely used filter puts it first of the two new rows that close the analysis text-loss group.
- Impact class
- silent wrong results
- Impact note
- Applications that run WordDelimiterGraphFilter with the opt-in IGNORE_KEYWORDS flag (factory parameter ignoreKeywords since 9.9.0; Elasticsearch and OpenSearch expose it as ignore_keywords) behind a keyword-marking filter, with PRESERVE_ORIGINAL off (the default), get silently wrong positions whenever a keyword token directly follows a token the filter drops entirely (a standalone '/', '-' or '&' under the recommended whitespace tokenization, or a delimited token with no parts under the flags): the keyword sits one position too early and the gap moves to after it, so exact phrase, span and interval queries across that spot miss ('solr rocks' in 'lucene / solr rocks') or match where the same chain without the keyword mark does not ('lucene solr' in 'lucene / solr'); terms, offsets, non-positional queries and phrases with slop >= 1 are unaffected; tiny inputs, -ea and -da, every release from 7.4.0 to 10.5.2 and main.
- Summary
- You analyze 'lucene / solr rocks' with a whitespace tokenizer, a keyword marker that marks 'solr', and WordDelimiterGraphFilter(GENERATE_WORD_PARTS | IGNORE_KEYWORDS), and expect the hole left by the swallowed '/' to stay in front of 'solr' (position increments {1, 2, 1}), exactly as when 'solr' is not a keyword, is marked without IGNORE_KEYWORDS, or is a protected word. Instead the keyword branch returns 'solr' before the pending increment is applied, so 'solr' gets 1 and 'rocks' gets 2 ({1, 1, 2}); with the same analyzer at index and query time the exact phrase "solr rocks" finds 0 of the 1 matching documents, and the phrase "lucene solr" matches the document 'lucene / solr', which the chain without the keyword mark does not.
- Introduced
- fc0878cc2f97 (LUCENE-8265 'WordDelimiterFilter should pass through terms marked as keywords', now apache/lucene#9312; master) and its branch_7x backport d1bf6ad79a86, which shipped in 7.4.0; proposed as apache/lucene-solr#359 by GitHub msokolov, closed without a GitHub merge and committed directly by GitHub mikemccand [read: git blame of WordDelimiterGraphFilter.java:353 and :355 on main gives fc0878cc2f9, :354 is the LUCENE-9570 reformat 8ef6a0da568, and git merge-base / tag --contains place the backport in 7.4.0 and not in 7.3.1; exec: 7.3.1 has no IGNORE_KEYWORDS (compile error) and 7.4.0 fails]. Not a regression: the defect arrived with the flag, whose early return was placed before the hole accumulator 'accumPosInc += posIncAttribute.getPositionIncrement()' that LUCENE-7619 (637915b890d9, 2017-01-17) had added; no later commit changed that order (2018-04-28 (fc0878cc2f9 on master and d1bf6ad79a8 on branch_7x, both committed that day; authored 2018-04-22); first released in 7.4.0 (tagged 2018-06-18))
- First affected version
- 7.4.0 [exec] (the first release with IGNORE_KEYWORDS: 7.3.1 has no such flag, compile error [exec], and its keyword-marked control without the flag keeps the hole [exec]); through WordDelimiterGraphFilterFactory (ignoreKeywords, #12525) only from 9.9.0 [exec]: the 9.8.0 factory rejects the parameter ('Unknown parameters'), although CHANGES.txt lists #12525 under 9.8.0
- Affected versions
- every release from 7.4.0 to 10.5.2, and main ea57360912ed; no fixed release (upstream main e1c4184cb98 checked 2026-10-26: the file last changed 2023-11-14, #12805, formatting). [exec, follow-up history sweep, 47 runs, seed DEADBEEF] the finder's JUnit (its pre-9.1-import variant on 7.4.0-9.0.0) fails 3 run / 2 failed on 7.4.0 (-ea and -da), 7.5.0, 7.6.0, 7.7.3, 8.0.0, 8.1.1, 8.2.0, 8.3.1, 8.4.1, 8.5.2, 8.6.3, 8.7.0, 8.8.2, 8.9.0, 8.10.1, 8.11.4, 9.0.0, 9.1.0, 9.2.0, 9.3.0, 9.4.2, 9.5.0, 9.6.0, 9.7.0, 9.8.0, 9.9.2, 9.10.0, 9.11.1, 9.12.3 (-ea and -da), 10.0.0, 10.1.0, 10.2.2, 10.3.2, 10.4.0, 10.5.2 (-ea and -da) and main (-ea and -da); the factory probe (CustomAnalyzer keywordMarker + wordDelimiterGraph ignoreKeywords=1) fails on 9.9.0, 10.5.2 and main; the independent reproduction's own JUnit and the intended-behaviour check's runs fail on main (-ea, -da), 10.5.2 and 9.12.3; [read] the keyword return precedes 'accumPosInc +=' in the tagged sources of 7.4.0, 8.0.0, 9.0.0, 9.12.3 and 10.5.2; untested patch releases inside the range are inferred affected (the latest patch of every minor line fails and the lines did not change)
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26 plus the finder's and the intended-behaviour check's runs, the prior-report record verdict new, 221 recorded queries: 111 scripted prior-report search queries in five runs over GitHub issues, PRs and commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; 93 GitHub GraphQL searches, 74 over apache/lucene and 19 over elastic/elasticsearch, opensearch-project/OpenSearch and apache/solr; 8 JIRA REST searches over LUCENE and SOLR; 9 git and API reads; 29 apache/lucene items, lucene-solr PR #359 and 8 downstream items read in full; a forum search and 5 Stack Overflow questions; the changed files of all 411 open apache/lucene PRs (only #202 touches WordDelimiterGraphFilter.java, class javadoc only); commits by path on upstream main (the keyword branch is unchanged since 2018); 20 hits analysed, all same_bug false). Not fixed upstream. Closest item: LUCENE-8395 (#9442, fixed in 7.5.0), a different defect in the same accumPosInc bookkeeping on the PRESERVE_ORIGINAL branch (precedent, not a report of this bug). Gaps: private reports to security@lucene.apache.org cannot be searched; GitHub search tokenises identifiers and does not index code or review comments; searches cannot prove absence
- Lucene commit tested
- main
a9779ef3c193(2026-10-27): this doc's test through gradle in a scratch worktree with assertions on and off, and through the standalone JUnit runner with-eaand-da; the 10.5.2 and 9.12.3 release jars. Earlier pipeline runs (2026-10-26): mainea57360912edand 35 releases from 7.4.0 to 10.5.2 (the finder's test), 7.3.1 (no such flag), and the factory path on 9.8.0, 9.9.0, 10.5.2 and main. The recommended fix was validated with the whole analysis-common test module.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:38-42 (class javadoc: correct token graph so that PhraseQuery works; processing suppressed by isKeyword), :80-85 (WhitespaceTokenizer recommended), :148 (IGNORE_KEYWORDS), :187-188 (accumPosInc 'so that we preserve incoming holes'), :345-382 (incrementToken: keyword return :353-355, accumulation :359, protected-word return :364-370, swallow :373-375) (read at ea57360912ed)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:62 (javadoc example with WhitespaceTokenizerFactory and ignoreKeywords), :117-118 (ignoreKeywords, default 0)lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilter.java:283-359 testPositionIncrements ('in this case, works as expected': 'LUCENE / SOLR' -> {1, 2}; 'LUCENE / NUTCH SOLR' with NUTCH protected -> {1, 2, 1}) and testKeywordFilter (no swallowed token)lucene/core/src/java/org/apache/lucene/analysis/package-info.java:303-326 (a filter that filters out tokens must increment the position increment; the StopFilter example adds the accumulated increment to the next returned token)
- The finding in 30 seconds
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:148-149, 187-188, 345-381, 422-423, 435-437
- Who is affected
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:62, 117-118a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:80-85 (WhitespaceTokenizer recommended)
- Why it looks unintended
a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:38-42, 148, 187, 373a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/package-info.java:303-326a Lucene main checkout (a9779ef3c193) lucene/core/src/java/org/apache/lucene/analysis/tokenattributes/PositionIncrementAttribute.java:35-39a Lucene main checkout (a9779ef3c193) lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilter.java:328-338, 352-361, 466-481a Lucene main checkout (a9779ef3c193) lucene/CHANGES.txt:7202-7204 (LUCENE-8395), 7397-7398 (LUCENE-8265)
- History
a Lucene main checkout (a9779ef3c193) lucene/CHANGES.txt:3358 (GITHUB#12525 under 9.8.0), 7397-7398 (LUCENE-8265 under 7.4.0)
- TestWdgfIgnoreKeywordsHole.java (JUnit test):
repro/LFV-353/src/org/apache/lucene/analysis/miscellaneous/TestWdgfIgnoreKeywordsHole.java(43 lines)
A light, three-panel picture of the repro (positions, the code path, the query results on one document), made in parallel with this doc from the executed runs on main a9779ef3c193 and the code. Its "3-line fix" is the same change as the recommended option, which formatting reflows to 4 lines.
assets/LFV-353/bug.png(440 KB)