WordDelimiterGraphFilter drops a token that has nothing to emit (only punctuation, or parts the flags switch off) and leaves a hole, like StopFilter. A hole after the last token must be reported by end() as the final position increment; this filter forgets it.
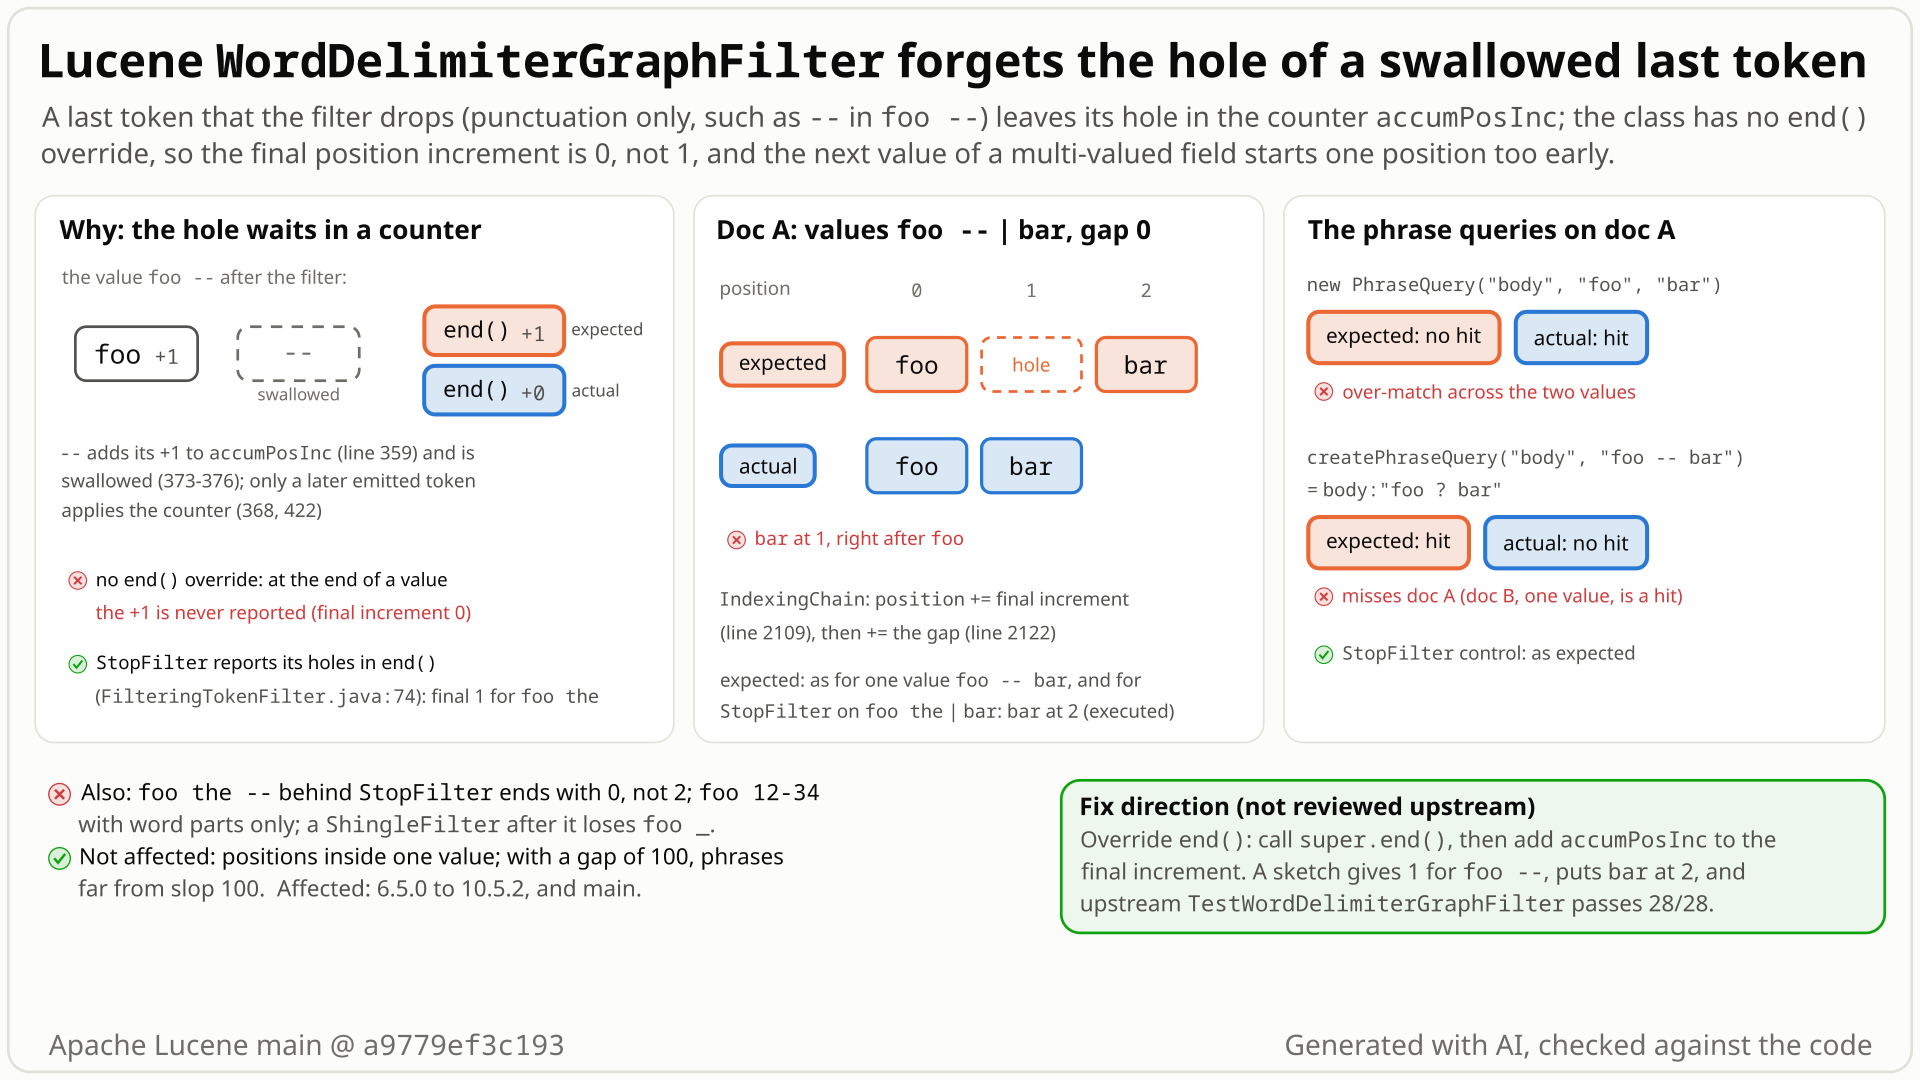
-- waits in a counter, where bar lands in the two-valued document foo -- | bar, and what the two phrase queries return. Select the still to open it at full size. Generated with AI, checked against the code.- You index a multi-valued text field with a whitespace tokenizer and
WordDelimiterGraphFilterat its default flags, and Lucene's default gap of 0 between values. Infoo -- barthe filter drops--and leaves a hole:fooat position 0,barat 2. - You add one document with the two values
foo --andbar. You expect the same hole afterfoo, sobarat position 2, as a StopFilter gives for the valuesfoo the|bar. - You get
barat position 1. The filter keeps the dropped token's position step in a counter that only a later token uses, and it does not overrideend(), so when nothing follows the step is lost: the final position increment is 0, not 1. - So the phrase query for
foo -- bar(body:"foo ? bar") finds 0 documents instead of 1, and"foo bar"finds 1 instead of 0. Behind a StopFilter,foo the --loses both steps: final increment 0 instead of 2. - The same happens to a last token whose parts the flags switch off (
foo 12-34with word parts only) and to several dropped tokens in a row (foo -- --ends with 0, not 2). Positions inside one value do not change; a single value differs only for a later consumer of the final increment, such as a ShingleFilter after the filter, which loses its trailingfoo _shingle.
Applications that index multi-valued text fields through WordDelimiterGraphFilter with a small gap between values (Lucene's default is 0) and run phrase, span or interval queries that can cross a value boundary; or that put a ShingleFilter after it. Ordinary text triggers it; with a gap of 100 only phrases whose slop is close to 100 see it.
Mechanism, terms and numbers788 words
WordDelimiterGraphFilter drops a token made only of delimiters, such as --, and leaves a hole for it, like a stop word removed by StopFilter: foo -- bar gives bar a position increment of 2, which upstream's tests assert for LUCENE / SOLR. It keeps the dropped token's increment in a counter, accumPosInc, that only the next emitted token applies, and it has no end() override. So when the dropped token is the last one, the hole is lost: foo -- ends with a final position increment of 0 instead of 1. The same happens to a stop-word hole such a token carries (foo the -- behind a StopFilter: 0 instead of 2) and to a last token whose parts the flags all switch off (foo 12-34 with GENERATE_WORD_PARTS only).
It shows wherever the final increment is used. In a multi-valued field with Lucene's default position increment gap of 0, the next value starts one position early: PhraseQuery(foo, bar) matches the values foo -- | bar while the StopFilter values foo the | bar do not, and the phrase QueryBuilder builds for foo -- bar matches the single value foo -- bar but not the two values. A ShingleFilter after the filter loses its trailing filler shingle. It has been there since the filter was added in 6.5.0 (LUCENE-7619, 2017). A small end() override, the same shape as FilteringTokenFilter.end(), fixes it; with it, the new tests and all 1,914 tests of the analysis module pass.
- Position increment: how many positions a token moves forward from the previous one; 1 for the next word, 2 when one word between them was removed (a hole).
- Final position increment: the increment a token stream reports in
end(), after its last token. It carries holes left at the end of a value. The indexer adds it to the field's position before the next value of the same field. - Swallowed token: an input token for which
WordDelimiterGraphFilteremits nothing: a token made only of delimiters (--,/,&) with PRESERVE_ORIGINAL off, the default, or a token whose parts the flags all switch off (12-34with only GENERATE_WORD_PARTS).
incrementToken()adds every input token's increment toaccumPosInc(WordDelimiterGraphFilter.java:359), "so that we preserve incoming holes" (:187-188); only an IGNORE_KEYWORDS keyword returns before that line, unchanged (:353-355, the sibling bug).- A token made only of delimiters is dropped with
continue(:373-380, "swallow this token, creating a hole"); a token whose parts are all switched off buffers nothing (:384,:387) and is dropped the same way. - Only a later emitted token applies
accumPosInc(:368-369,:422-423);reset()clears it (:434-442). - The class has no
end()override. The inheritedTokenFilter.end()only callsinput.end(), so the final increment is the input's and the pendingaccumPosIncis never reported. IndexingChainadds the final increment to the field position afterend()(IndexingChain.java:2105-2109) and then the analyzer's gap before the next value (:2121-2123;Analyzer.getPositionIncrementGapreturns 0 by default). So the next value starts one position early per lost hole: one per trailing dropped token, plus each stop-word hole they carry.
| input | chain | stock | expected (and with the fix) |
|---|---|---|---|
foo -- bar | WDGF | foo +1, bar +2, final 0 | the same (control) |
-- foo | WDGF | foo +2, final 0 | the same (control: a leading hole is kept) |
foo --, foo /, foo & | WDGF | foo +1, final 0 | final 1 |
foo -- -- | WDGF | foo +1, final 0 | final 2 (foo -- -- bar gives bar +3) |
foo 12-34 | WDGF, word parts only | foo +1, final 0 | final 1 |
foo the | StopFilter + WDGF | foo +1, final 1 | the same (control) |
foo the -- | StopFilter + WDGF | foo +1, final 0 | final 2 (foo the -- bar gives bar +3) |
values foo -- | bar | WDGF, gap 0 | bar at position 1 | position 2, as foo -- bar and foo the | bar |
WDGF is WordDelimiterGraphFilter with the factory's default flags. The filter's own terms, offsets, token counts and positions inside a value do not change; only the final increment does. When the filter is last in the query analyzer, queries do not change either: QueryBuilder reads only per-token increments. A later filter that reads the final increment, such as ShingleFilter (ShingleFilter.java:379-382), turns it into tokens, so there the terms differ too (foo _), at index and at query time. A value that ends in a stop word alone keeps its hole, because the inherited end() passes the StopFilter's value through.
Exposure and likelihood386 words
- Who is exposed. Applications that index a multi-valued text field through
WordDelimiterGraphFilter(directly, through thewordDelimiterGraphfactory, or through a search server's word-delimiter-graph filter built on it) with a small position increment gap, and run phrase, span or interval queries that can span two values. Also chains with a ShingleFilter after the filter (the trailing filler shingle is lost). Suggesters that keep trailing holes see a different final increment too (by reading; not executed). - Default vs opt-in. The filter is an optional analysis-common filter; once added, its default flags trigger the bug. With PRESERVE_ORIGINAL on, a punctuation-only token is kept, not dropped.
- What it takes. A value whose last token the filter drops: a spaced punctuation-only token (
--,/,&) or a token whose parts the flags all switch off, optionally after removed stop words; and a following value of the same field, or a later consumer of the final increment. - What happens. The next value starts one position early per lost hole (one per trailing dropped token, plus carried stop-word holes; no cap). Phrase and proximity queries across the boundary match where the StopFilter chain does not (
"foo bar"onfoo --|bar) or miss where the same text in one value matches ("foo ? bar"). Positions inside one value do not change; in a single-valued field only a later consumer of the final increment sees a difference: a ShingleFilter losesfoo _, andTokenStreamToAutomatonturns a positive final increment into a trailing hole (TokenStreamToAutomaton.java:214-232, by reading). - Large gaps hide it. Common search servers default text fields to a gap of 100; then only phrases whose slop is close to the gap see it. Over slops 0 to 250, on the values
foo --|baragainst the StopFilter chain,PhraseQuery(foo, bar)differs only at slop 100 (100-101 with two lost holes), and the phraseQueryBuilderbuilds forfoo -- bar(body:"foo ? bar") only at slop 99. - Scale and versions. Deterministic and independent of index size; no error,
CheckIndexclean. Every release from 6.5.0 to 10.6.0 (10.6.0 by reading) and main. - How likely. Rare: the wrong final increment is common, but users see it only across value boundaries with a small gap, and no report was found in the recorded searches.
The test shows that WordDelimiterGraphFilter (factory default flags, after a WhitespaceTokenizer) drops the hole of a swallowed trailing punctuation-only token: for foo -- its end() reports no final position increment, although the same token leaves a hole mid-stream.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.miscellaneous;

import java.io.StringReader;
import java.util.HashMap;
import org.apache.lucene.analysis.TokenStream;
import org.apache.lucene.analysis.Tokenizer;
import org.apache.lucene.analysis.core.WhitespaceTokenizer;
import org.apache.lucene.tests.analysis.BaseTokenStreamTestCase;

public class TestWordDelimiterGraphFilterTrailingHole extends BaseTokenStreamTestCase {

  public void testTrailingPunctuationOnlyTokenLeavesHole() throws Exception {
    Tokenizer tokenizer = new WhitespaceTokenizer();
    tokenizer.setReader(new StringReader("foo --"));
    TokenStream ts = new WordDelimiterGraphFilterFactory(new HashMap<>()).create(tokenizer);
    // "--" is swallowed and leaves a hole, as it does mid-stream: expected finalPosInc 1, actual 0
    String[] terms = {"foo"};
    assertTokenStreamContents(
        ts, terms, null, null, null, new int[] {1}, null, null, 1, null, false, null);
  }
}
# in a copy of this finding's repro folder (repro/LFV-354/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.miscellaneous.TestWordDelimiterGraphFilterTrailingHole
- Expected vs actual
- Expected
finalPosInc1; actual 0 (finalPosInc expected:<1> but was:<0>), with-eaand-da.
More files, environment, full output36 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: finalPosInc expected:<1> but was:<0>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:647)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:436)
       org.apache.lucene.tests.analysis.BaseTokenStreamTestCase.assertTokenStreamContents(BaseTokenStreamTestCase.java:544)
org.apache.lucene.analysis.miscellaneous.TestWordDelimiterGraphFilterTrailingHole.testTrailingPunctuationOnlyTokenLeavesHole(TestWordDelimiterGraphFilterTrailingHole.java:34)- The analysis docs say filters "must put accurate values" into the attributes at a field's end; LUCENE-3849 and four later bug fixes added such
end()handling. - The filter makes this hole mid-stream and at the start on purpose (
LUCENE / SOLR: +1, +2); only the end loses it. - No test pins it; the fixed filter passes all module tests.
The full argument434 words
- The package docs say "must". "End of Input Cleanup": "The components of the token stream (the tokenizer and the token filters) must put accurate values into the token attributes to reflect the situation at the end of the field" (
package-info.java:274-284).TokenStream#end: "any skipped positions (such as those removed by a stopfilter) can be applied to the position increment" (TokenStream.java:152-154). - LUCENE-3849 fixed exactly this symptom as a bug (4.5.0, Bug Fixes: "TokenStreams now set the position increment in end(), so we can handle trailing holes"). Its report was a phrase across the values of a multi-valued field with gap 0, after a value ending in removed stop words.
- The same omission was fixed as a bug in four later changes: LUCENE-8360 (NGram filters, 7.4.0), LUCENE-8376/8371 (ConditionalTokenFilter, FixedShingleFilter, 7.5.0), LUCENE-8650 (ConcatenatingTokenStream, 7.7.0) and #16577 (FixedShingleFilter, 10.5.2; reported for a wrong mid-stream increment), whose fix also adds an
end()of the same shape: a pending counter added to the final increment. - The filter makes this hole on purpose everywhere else. Upstream asserts
LUCENE / SOLR-> +1, +2 (TestWordDelimiterGraphFilter.java:328-338, with other flags; the drop does not depend on them), that an incoming increment of 10 on a dropped/"is carried over" (:392-414), and that a stop word before a split word "should add a gap here" (:451-461). A leading-- foogivesfoo+2. The code says "preserve incoming holes" (WordDelimiterGraphFilter.java:187) and "swallow this token, creating a hole" (:373). - The history says holes were the point. LUCENE-7619, which added the filter: "I'm also trying to produce holes properly (removes logic from the current WDF that swallows a hole when whole token is just delimiters)". The deprecated filter's code asks for "proper hole adjustment (FilteringTokenFilter-like)" (
WordDelimiterFilter.java:264-265). - Nothing pins the current output. No upstream test asserts the filter's final increment, and it is excluded from the random-chain tests (
@IgnoreRandomChains,WordDelimiterGraphFilter.java:87). With the fix, the 28 upstream tests of the filter and the 16 of the deprecated one pass, and all 1,914 tests of the analysis module pass. - The weakest of the three triggers is a token whose parts the flags all switch off: no upstream comment or test says it must leave a hole. The support is the filter's own behaviour: in the middle,
foo 12-34 bar(word parts only) givesbar+2, so the filter already treats it as a hole and drops it only at the end. The cross-model fact check rated the intended case moderate for this trigger and weak for the other two.
The devil's-advocate check270 words
The checkers built the strongest case for "intended": (a) TokenStream#end says skipped positions "can be applied", which reads as optional; (b) no upstream test checks the filter's final increment; (c) the deprecated WordDelimiterFilter cancels the increment of a plain punctuation-only token, so "no hole" is the older behaviour; (d) the class javadoc says the filter "cannot consume an input token graph correctly", so a StopFilter in front could be called unsupported; (e) at gap 0 Lucene already lets a phrase run across values (foo | bar matches "foo bar"), so one position more or less is cosmetic.
Why it fails: (a) the package docs say "must", and the project fixed missing final increments as bugs in LUCENE-3849 and four later changes (the last, #16577, added the same kind of end() while fixing a mid-stream increment). (b) Untested is not specified; nothing asserts a final 0. (c) This filter was written to replace exactly that logic (LUCENE-7619), and it makes the hole in the middle and at the start, so dropping it only at the end is inconsistent with the class itself. (d) A hole is not a graph (position length stays 1), and upstream's own test puts a StopFilter in front of the filter and asserts the stop word's gap. (e) The issue is not that values touch, but that the same text gets different positions depending on where a value ends: the phrase foo -- bar matches it as one value and misses it as two, while StopFilter is consistent. Every checker rejected the case; the cross-model reviewer rated it weak, the independent reproducer weak to moderate.
Recommended A. Report the pending hole in end()
Add a small end() override that reports the pending hole: super.end(), then add accumPosInc to the final position increment, as FilteringTokenFilter.end() does. Output changes only for values that end in dropped tokens, and in the IGNORE_KEYWORDS sibling case. Validated: the new tests, all 1,914 analysis-module tests and check pass. It composes with the sibling fix.
  @Override
  public void end() throws IOException {
    super.end();
    // report the holes of swallowed trailing tokens (and the incoming holes they carried)
    posIncAttribute.setPositionIncrement(posIncAttribute.getPositionIncrement() + accumPosInc);
  }
All options and trade-offs3 options · 872 words
Option A was applied in a scratch worktree of main a9779ef3c193 and run through gradle with assertions on and off. Option B (with the IGNORE_KEYWORDS sibling fix) was run through the repro harness with shadowed classes; option C was not run.
Add end() to WordDelimiterGraphFilter, next to reset() (WordDelimiterGraphFilter.java:434): call super.end(), then add accumPosInc to the position increment. The finder's and the reproducer's fix sketches are the same method.
What it changes, by code. accumPosInc is non-zero at end() when the last input tokens emitted nothing, and in one more case: a dropped token followed only by IGNORE_KEYWORDS keywords, which are emitted without touching the counter (:353-355, the sibling bug). Every other emitted token resets it to 0 (:369, :378, :423). So output changes for values that end in dropped tokens, and in that keyword case: with solr a keyword, lucene / solr ends with 1 instead of 0 under this fix alone (executed by the fact check); option B fixes it.
New output. foo -- and foo 12-34 (word parts only) end with 1, foo the -- with 2; the values foo -- | bar put bar at position 2, so the phrase foo -- bar finds the document and "foo bar" does not; a ShingleFilter after the filter emits foo _ for foo --, as for foo the behind a StopFilter.
End-composition controls (a print-only probe, not in the 5-test class; stock and with the fix shadowed): no double count. foo -- the behind a StopFilter ends with 2 (stock 1); foo -- -- and -- -- with 2 (stock 0); a value of only -- with 1 (stock 0), like StopFilter's 1 for the; a -- whose incoming increment is 0 adds nothing (final 0 with and without the fix).
  @Override
  public void end() throws IOException {
    super.end();
    // report the holes of swallowed trailing tokens (and the incoming holes they carried)
    posIncAttribute.setPositionIncrement(posIncAttribute.getPositionIncrement() + accumPosInc);
  }
Trade-offs
- The next value's positions move by the lost holes, so documents indexed before the fix keep the old positions until reindexed; query parsing does not change when the filter is last in the query analyzer (with a ShingleFilter after it, query-side filler shingles change the same way as index-side ones, by reading).
- On its own it leaves the IGNORE_KEYWORDS sibling bug: a hole pending in front of a last keyword token is reported at the end instead of being lost (executed by the fact check); option B puts it on the keyword.
What the checks validated
- The 5 new tests pass; upstream
TestWordDelimiterGraphFilter(28) andTestWordDelimiterFilter(16) pass; assertions on and off (stock: the 4 defect tests fail). - All of
:lucene:analysis:common:testwith assertions on: 340 classes, 1,914 tests, 18 skipped, 0 failures. :lucene:analysis:common:check -x testpasses (google-java-format, ecjLint, forbiddenApis, licenses).- Through the repro harness with the class shadowed: the new test 5 of 5 (assertions on and off), the finder's repro 4 of 4, the independent reproducer's suite 9 of 9, the devil's advocate's phrase test 3 of 3; earlier runs: upstream 28 of 28, the security probe 8 of 8, and the same override on 6.5.0 and 10.5.2 4 of 4.
The sibling bug's recommended fix applies the pending accumPosInc to an IGNORE_KEYWORDS keyword before its early return (WordDelimiterGraphFilter.java:353-355). Both patches apply cleanly together. A composition probe (lucene / solr with solr a keyword must give solr +2 and a final 0; lucene solr / a final 1; lucene / solr / both) fails 3 of 3 on stock, 2 of 3 with either fix alone, and passes 3 of 3 with both; with both, the new test (5/5), the sibling's test (3/3), upstream TestWordDelimiterGraphFilter (28/28) and the three older repros pass.
Trade-offs
None beyond the two fixes' own; it is the only option that puts every dropped token's hole where StopFilter would put it. One issue with two fixes, or two cross-referenced issues.
What the checks validated
Through the repro harness with both fixes shadowed, assertions on; not run through gradle or the whole module together.
The deprecated filter also keeps an accumPosInc (WordDelimiterFilter.java:183, :247) and has no end(). A verifier observed that it drops a stop-word hole carried by a last dropped token (foo the -- final 0, while foo the -- bar gives bar +3), and a probe shows it also drops the hole of a last token whose parts the flags all switch off (foo 12-34 with word parts only: final 0, while foo 12-34 bar gives bar +2). The same override would report 2 and 1 there and leave a plain trailing -- at 0, matching that filter's own behaviour in the middle (by reading). It needs its own validation: the deprecated filter has the same IGNORE_KEYWORDS early return before the accumulation (WordDelimiterFilter.java:241-243), so an end()-only patch can move a pending hole there too.
Trade-offs
The filter is deprecated, and open PR #202 proposes removing it; not run.
Products built on this filter inherit the shifted positions; those that keep a gap of 100 between values see it only in phrases whose slop is close to 100.
A bounded-exhaustive check of the real filter: every short whitespace-separated text over a few letters, digits, - and ', times all 1,024 flag combinations (about 157 million runs), checked against a hand-written rule: the final position increment equals the steps of the trailing tokens that emitted nothing. It found about 5 million violations; reading the class gave the cause.
The method in full157 words
- Method (semi-formal): bounded-exhaustive translation validation of the stock main jar, in the hunt's unit on analysis graph filters. Every whitespace-separated text up to length 7 over
a,A,1,-and space, and up to length 6 overa,1,-,',sand space, with keyword-marker and protected-word variants, times all 1,024 flag combinations: 99,998,720 and 57,329,664 checks. - Oracle, a hand-written rule that encodes the intended trailing-hole invariant (not a formal specification), independent of the code: the final position increment must equal the sum of the increments of the trailing input tokens that produced no output.
- Signal. 1,764,524 and 3,247,808 violations of that rule; the only other category in those runs was the IGNORE_KEYWORDS sibling bug.
- Root cause by reading the class: no
end()override, so the pendingaccumPosIncis dropped. The finder then wrote the public-API JUnit and the fix sketch; independent checkers followed (see "Independent checks").
No prior report found (searched 2026-10-26, 220 queries over GitHub issues and PRs, JIRA, the Lucene and Solr lists, downstream trackers, the web and all 411 open PRs). Closest: LUCENE-3849, the same symptom for StopFilter, fixed in 4.5.0 before this filter existed.
Searches6 searches
21 hits were recorded and 51 issues and PRs read in full; none describes this bug. Keyword search only: a report that describes only the symptom (a phrase matching across values after trailing punctuation) cannot be ruled out; GitHub search does not index PR review comments, GitHub's search rate limit was saturated (covered by GraphQL searches), and private lists cannot be searched.
| Where | When | How | Found |
|---|---|---|---|
| scripted prior-report search | 2026-10-26 | lists and JIRA in full; all 38 apache/lucene GitHub issue and PR queries (commit and downstream queries stopped on GitHub's search rate limit) | no report |
| GitHub (GraphQL) | 2026-10-26 | 104 searches over apache/lucene, apache/lucene-solr, apache/solr, Elasticsearch, OpenSearch, Lucene.NET and all of GitHub, covering the stopped queries and 62 more phrasings (class names, hole, trailing, punctuation, StopFilter, multivalued, phrase, finalPosInc, accumPosInc) | no report |
| JIRA (LUCENE, SOLR) and mailing lists | 2026-10-26 | 10 JIRA REST searches; 9 list searches over java-user@, dev@, issues@, solr-user@ and users@solr (7 mails from 4 threads read in full) | no report; the 2018 solr-user@ thread on WordDelimiterGraphFilter behaviour is the LUCENE-8395 shape |
| Open PRs and history | 2026-10-26 | the changed-file lists of all 411 open apache/lucene PRs; the full local git history of the file | only #202 touches the file (removes the deprecated filter, edits one javadoc sentence) |
| Web | 2026-10-26 | 6 searches; 2 Stack Overflow questions read | no relevant hit |
| Closest items (read) | 2026-10-26 | full threads | LUCENE-3849 / #4922 (the StopFilter precedent); LUCENE-8360 / #9407, LUCENE-8371 / #9418, LUCENE-8376 / #9423, LUCENE-8650 / #9696, #16577 (the same omission in other filters); LUCENE-8395 / #9442 (same branch, a mid-stream extra hole); LUCENE-7842 / #8893 (questioned the mid-stream hole; withdrawn by its reporter, resolved Invalid, no maintainer ruling); LUCENE-8361 / #9408 (generic random-chain check, never names the filter); LUCENE-7619 / #8670 (introducing issue) |
Introduced with the filter itself, LUCENE-7619 (637915b890d9, 2017-01-17), first released in 6.5.0; the class never had an end(). Fails identically on every tested release from 6.5.0 to 10.5.2 and on main. Not fixed upstream.
Versions tested6 rows
Introduced by LUCENE-7619 (now #8670, "Add WordDelimiterGraphFilter"; commit subject "add WordDelimiterGraphFilter (replacing WordDelimiterFilter) to produce a correct token stream graph when splitting words"): master 637915b890d9 and branch_6x 4e4ec082caa7, both 2017-01-17, the same file, committed from JIRA patches (no PR). It replaced the old filter's "no hole" logic for punctuation-only tokens with the counter, which delivers the hole only if another token follows, and added no end(). The accumulation line itself came over from WordDelimiterFilter.
Not fixed upstream. The file is byte-identical on main a9779ef3c193 and upstream main c5ab3e57b9b (2026-10-28), and was identical on branch_10x and branch_10_6 (2026-10-24). All 74 release tags from 6.5.0 to 10.5.2 in the full history clone have the swallow branch and the accumulation and no end() in the class; 8.8.2 and 8.9.0 to 8.11.3 (released from the separate lucene-solr repository, not in the clone) are inferred, and 8.11.4 was executed. Old releases ran on JDK 25, not the JDKs of their time.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 | affected | new test 4 of 5 fail through gradle and the repro harness, assertions on and off |
| 10.5.2, 9.12.3 | affected | new test 4 of 5 fail (10.5.2 also with assertions off); the finder's and the reproducer's JUnit fail |
| 6.5.0, 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.1.0, 10.0.0 | affected | the finder's test (an import port for older releases) fails the same 3 of 4; 6.5.0 also with assertions off |
| 6.4.2 | no such class | WordDelimiterGraphFilter does not exist yet (the repro does not compile) |
| deprecated WordDelimiterFilter, main | two trailing cases | drops a stop-word hole carried by a last dropped token (foo the -- final 0) and the hole of a last token whose parts the flags all switch off (foo 12-34, word parts only: final 0); its legacy logic cancels the increment of a plain punctuation-only token, so a trailing -- makes no hole there |
fix A on main a9779ef3c193; the same override on 6.5.0 and 10.5.2 | not affected | the new test, the finder's, the reproducer's and the devil's advocate's repros pass; 1,914 module tests pass; 6.5.0 and 10.5.2 pass the finder's test 4 of 4 |
An independent reproducer (own 9-test suite), a works-as-designed review by a reviewer from another model family, an intended-behaviour devil's advocate, an adjudication and a credibility audit all judged it real; each of them except the review re-ran it. A read-only refute review said "not real" only because it could not run code.
Checks and verdicts404 words
Every verdict below that re-ran a repro did so on main ea57360912ed, whose analysis module is identical to a9779ef3c193; the reading-only cross-model reviews were followed by a separate re-run of the repro (fails). This doc's own fix validation ran on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| Cross-model refute review | not real (low), procedural | An independent reviewer from another model family (OpenAI GPT-5.6), reading only: it could run no command, so it could not vote real. It agreed with the root cause, found the inputs within the contract and rated the intended-behaviour case weak. A separate run re-ran the repro: fails 4/3. |
| Independent reproducer | real | Own public-API suite in another package (4 defect cases, 5 controls): 4 of 9 fail on main with assertions on and off, on 10.5.2 (on and off) and on 9.12.3. Found the second trigger (all parts switched off), the lost trailing shingle and the deprecated filter's carried-hole case; its minimal end() fix passes 9 of 9 and upstream 28 of 28. |
| Works-as-designed review | real (medium) | The same OpenAI GPT-5.6 reviewer with an intended-behaviour lens, reading only: the "can be applied" / no-test / old-filter case is weak. Separate re-runs fail with assertions on and off. |
| Intended-behaviour devil's advocate | real | Executed the LUCENE-3849 scenario with a QueryBuilder phrase: 2 of 3 fail on main (on and off) and 10.5.2, 3 of 3 pass with the fix. No test, comment or CHANGES entry says the trailing hole should be dropped. |
| Adjudication | confirmed (high) | Re-ran the reproducer's suite on main with assertions on and off (9 run, 4 failed each) and the finder's (4/3). Low severity, narrow reach, comparable to LUCENE-8360/8371/8376; file with the IGNORE_KEYWORDS sibling. |
| Credibility audit | keep | Re-ran the finder's repro with assertions on and off (4/3) and with the fix (4/0); its own probe with the real WhitespaceTokenizer and factory defaults shows the leading/trailing asymmetry (-- foo keeps the hole, foo -- loses it). |
| Fix validation (this doc) | fix A passes | Gradle in a scratch worktree of a9779ef3c193: stock 4 of 49 WordDelimiter tests fail (assertions on and off), and the exact single-class command 4 of 5; fix A 0 of 49, the whole module 0 of 1,914, check -x test passes. With the IGNORE_KEYWORDS sibling fix also shadowed, a composition probe passes 3 of 3 (either fix alone 1 of 3). |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 414 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,487 words
- Registry title
- WordDelimiterGraphFilter drops the hole of a swallowed last token (a punctuation-only token such as the '--' in 'foo --', or a token whose parts the flags all switch off) and any stop-word hole that token carries, because it has no end() override, so the final position increment is 0 and the next value of a multi-valued field starts too early (released since 6.5.0)
- Area
- analysis / WordDelimiterGraphFilter final position increment (end of stream, accumPosInc)
- Priority
- Low, rank 485: WordDelimiterGraphFilter's missing end() override drops a trailing hole, which shows only across value boundaries of a multi-valued field with a small gap and a cross-boundary phrase, so it is a rare silent analysis row that follows its sibling LFV-337.
- Impact class
- silent wrong results
- Impact note
- Applications that index a multi-valued text field through WordDelimiterGraphFilter at its default flags (PRESERVE_ORIGINAL off) with a small position increment gap (Lucene's Analyzer default is 0): when a value ends in a token the filter swallows (a punctuation-only token such as '--', '/' or '&', or a token whose parts the flags all switch off), optionally after removed stop words, end() reports 0 instead of the hole, so the next value starts 1 position (plus 1 per carried stop-word hole) too early and phrase, span and interval queries across the two values match or miss differently from the same text in one value or from the equivalent StopFilter chain, and a downstream ShingleFilter loses its trailing filler shingle; matching inside one value is unchanged; deterministic, ordinary scale, every release from 6.5.0 to 10.6.0 (10.6.0 by reading) and main; with the gap of 100 that common search servers use, only slop of 100 or more is affected.
- Summary
- You analyse 'foo --' (or 'foo the --' behind a StopFilter) with a whitespace tokenizer and WordDelimiterGraphFilter at its default flags, and expect the swallowed punctuation-only token to leave a hole that end() reports as a final position increment of 1 (2 with the stop word), as the filter does mid-stream ('foo -- bar' puts bar at +2, which upstream tests assert) and as StopFilter does for 'foo the'. Instead the filter keeps that hole in an internal accumulator that only a later emitted token applies and has no end() override, so the final increment is 0. In a multi-valued field with the default gap 0 the next value 'bar' then lands at position 1 instead of 2: PhraseQuery(foo, bar) matches the values 'foo --' | 'bar' while the StopFilter control 'foo the' | 'bar' does not, and the phrase QueryBuilder builds for 'foo -- bar' matches the single value 'foo -- bar' but not the two values (both executed).
- Introduced
- 637915b890d9 (LUCENE-7619 'Add WordDelimiterGraphFilter', by GitHub mikemccand, master; identical branch_6x backport 4e4ec082caa7 the same day; committed from JIRA patches, no GitHub PR; the issue is now #8670): the class never had an end() override [read: git blame attributes the hole bookkeeping lines 187, 373-377, 422-423 and 437-442 to it; no commit on the file adds end(); exec: 6.4.2 has no WordDelimiterGraphFilter (compile error), 6.5.0 fails]; the accumulation line (main :359) was carried over from WordDelimiterFilter [read] (2017-01-17)
- First affected version
- 6.5.0 [exec] (first release with WordDelimiterGraphFilter; 6.4.2 does not have the class, executed compile_error)
- Affected versions
- every WordDelimiterGraphFilter release, 6.5.0 through 10.6.0 (10.6.0 by reading), plus branch_10_6, branch_10x and main ea57360912ed (not fixed). Executed with the finder repro or its version ports (3 of 4 fail identically, control passes): 6.5.0 (-ea and -da), 6.6.6, 7.0.0, 7.7.3, 8.0.0, 8.11.4, 9.0.0, 9.1.0, 9.12.3 (-ea and -da), 10.0.0, 10.5.2 (-ea and -da) and main (-ea and -da) [exec]; the independent reproduction's suite fails on main (-ea, -da), 10.5.2 (-ea, -da) and 9.12.3, the intended-behaviour check's cross-value phrase test on main (-ea, -da) and 10.5.2 [exec]; the swallow branch and accumulation without an end() are in all 66 release tags 6.5.0 to 10.5.2 of the history clone [read]; 8.9.0 to 8.11.3 (released from the separate lucene-solr repository) inferred. The file blob is identical in 9.12.3, 10.5.2, main and upstream main, branch_10x and branch_10_6 (fetched 2026-10-24) [read]
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, the prior-report record verdict new, 220 recorded queries: a scripted prior-report search (89: lists and JIRA in full; its GitHub pass finished all 38 apache/lucene issue/PR queries but, with GitHub's search rate limit saturated, not 4 of its 5 commit queries or its 4 downstream queries), 104 read-only GitHub GraphQL searches (those phrasings plus 62 more, over apache/lucene, apache/lucene-solr, apache/solr, elastic/elasticsearch, opensearch-project/OpenSearch, apache/lucenenet and all of GitHub), 10 JIRA REST searches (LUCENE and SOLR), 9 more list searches (adding solr-user@ and users@solr), 6 web searches, the changed-file lists of all 411 open apache/lucene PRs, and the local full history; 21 hits read, all same_bug false). Closest items, none this bug: LUCENE-3849 (#4922, fixed 4.5.0) reported the same symptom for StopFilter and set the end() contract, before WordDelimiterGraphFilter existed; the same omission was fixed as a bug in other filters by LUCENE-8360 (#9407, NGram filters, 7.4.0), LUCENE-8371/8376 (#9418/#9423, ConditionalTokenFilter and FixedShingleFilter, 7.5.0), LUCENE-8650 (#9696, ConcatenatingTokenStream, 7.7.0) and #16577 (FixedShingleFilter, merged 2026-08-31, 10.5.2); LUCENE-8395 (#9442, fixed 7.5.0) is the same WDGF branch but a different defect (an extra mid-stream hole with PRESERVE_ORIGINAL); LUCENE-8361 (#9408, open) proposes a generic TestRandomChains position check and never names WDGF (WDGF is @IgnoreRandomChains); the only open PR touching WordDelimiterGraphFilter.java, #202, changes one javadoc sentence; the last commit on the file is #12805 (2023-11-14, syntax clean-up)
- Lucene commit tested
- main
a9779ef3c193(2026-10-26) through gradle in a scratch worktree: the new 5-test class with the upstreamTestWordDelimiterGraphFilterandTestWordDelimiterFilter, assertions on and off (stock: 4 of 49 fail; fix A: 0), fix A with all of:lucene:analysis:common:test(1,914 tests, 0 failures) andcheck -x test, and the exact single-class command on stock (5 run, 4 failed); the worktree was removed afterwards. The new test through the repro harness on maina9779ef3c193(-ea,-da), 10.5.2 (-ea,-da) and 9.12.3, and with the fix shadowed; a composition probe with the IGNORE_KEYWORDS sibling fix; a print-only probe of end-composition controls and of the deprecated filter, stock and with fix A shadowed. The hunt's repro on 6.5.0 through 10.5.2 and on mainea57360912ed, whose analysis module is identical. OpenJDK 25.0.3, Linux aarch64.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:84-85 (class javadoc recommends WhitespaceTokenizer), :87 (@IgnoreRandomChains), :187-188 (accumPosInc 'so that we preserve incoming holes'), :359 (accumulation), :368-369 and :422-423 (applied only to a later emitted token), :373-380 ('swallow this token, creating a hole'), :384 (bufferWordParts), :434-442 (reset(); no end() override in the class)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:90-119 (default flags; preserveOriginal default 0 at :111)lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:261-269 (deprecated filter: 'TODO: proper hole adjustment (FilteringTokenFilter-like)')lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154 (skipped positions 'can be applied to the position increment'); lucene/core/src/java/org/apache/lucene/analysis/package-info.java:274-284 ('End of Input Cleanup': components 'must put accurate values into the token attributes to reflect the situation at the end of the field'); lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:71-75 (end() adds skippedPositions)lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2050-2054 (final increment added to the field position after end()), :2066-2068 (position increment gap added before the next value); lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:309-311 (default gap 0)lucene/CHANGES.txt:835 (GITHUB#16577), 6912 (LUCENE-8650), 7182 (LUCENE-8376/8371), 7482 (LUCENE-8360), 13321 (LUCENE-3849)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:187-188, :345-432 (accumulation :359, applied :368-369 and :422-423, swallow :373-380, bufferWordParts :384, :387, :430), :434-442 (reset; no end() in the class) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/TokenFilter.java:45-48 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/index/IndexingChain.java:2105, :2109, :2121-2123 @ a9779ef3c193; lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:300-311 @ a9779ef3c193lucene/core/src/java/org/apache/lucene/util/QueryBuilder.java:316-330 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/shingle/ShingleFilter.java:379-382 (input.end() at exhaustion, filler tokens from the final increment) @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:353-355 (IGNORE_KEYWORDS early return) @ a9779ef3c193
- Who is affected
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilterFactory.java:90-119 (default flags; preserveOriginal default 0 at :111) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/Analyzer.java:300-311 (default gap 0) @ a9779ef3c193lucene/core/src/java/org/apache/lucene/analysis/TokenStreamToAutomaton.java:214-232 (positive final increment becomes trailing holes) @ a9779ef3c193
- Why it looks unintended
lucene/core/src/java/org/apache/lucene/analysis/package-info.java:274-284 @ a9779ef3c193; lucene/core/src/java/org/apache/lucene/analysis/TokenStream.java:152-154 @ a9779ef3c193; lucene/core/src/java/org/apache/lucene/analysis/FilteringTokenFilter.java:71-75 @ a9779ef3c193lucene/CHANGES.txt:851 (GITHUB#16577, 10.5.2 Bug Fixes), :6928-6930 (LUCENE-8650, 7.7.0 Bug fixes), :7198-7200 (LUCENE-8376/8371, 7.5.0 Bug Fixes), :7498-7499 (LUCENE-8360, 7.4.0 Bug Fixes), :8407-8410 (LUCENE-7619), :13337-13340 (LUCENE-3849, 4.5.0 Bug Fixes) @ a9779ef3c193lucene/analysis/common/src/test/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilter.java:263-281 (LargePosIncTokenFilter), :328-338, :392-414, :427-461 @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:37-42 (class javadoc), :87 (@IgnoreRandomChains), :187, :373 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:261-269 @ a9779ef3c193
- Suggested fix
lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:353-355, :369, :423, :434 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:183, :247 (no end()) @ a9779ef3c193lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterGraphFilter.java:378 @ a9779ef3c193; lucene/analysis/common/src/java/org/apache/lucene/analysis/miscellaneous/WordDelimiterFilter.java:241-243, :320-323, :360-363, :482-485 @ a9779ef3c193
- History
a Lucene clone: git rev-parse origin/main:<WordDelimiterGraphFilter.java> = a9779ef3c193:<same> = e9a563fecf14 (origin/main c5ab3e57b9b, 2026-10-28)
- TestWordDelimiterGraphFilterTrailingHole.java (JUnit test):
repro/LFV-354/src/org/apache/lucene/analysis/miscellaneous/TestWordDelimiterGraphFilterTrailingHole.java(37 lines)
assets/LFV-354/bug.png(414 KB)