- In the standard syntax,
field:textsearches one field. A backslash escapes a special character, also in a field name:my\ field:xsearches the fieldmy field,a\:b:xthe fielda:b. - The flexible parser first builds a tree of query nodes (
getSyntaxParser().parse), then aQuery. A node can also print itself back as query text withtoQueryString, documented as a string "understood by the query parser". - When it prints, a node passes its term text through an
EscapeQuerySyntax, which puts the backslashes back.
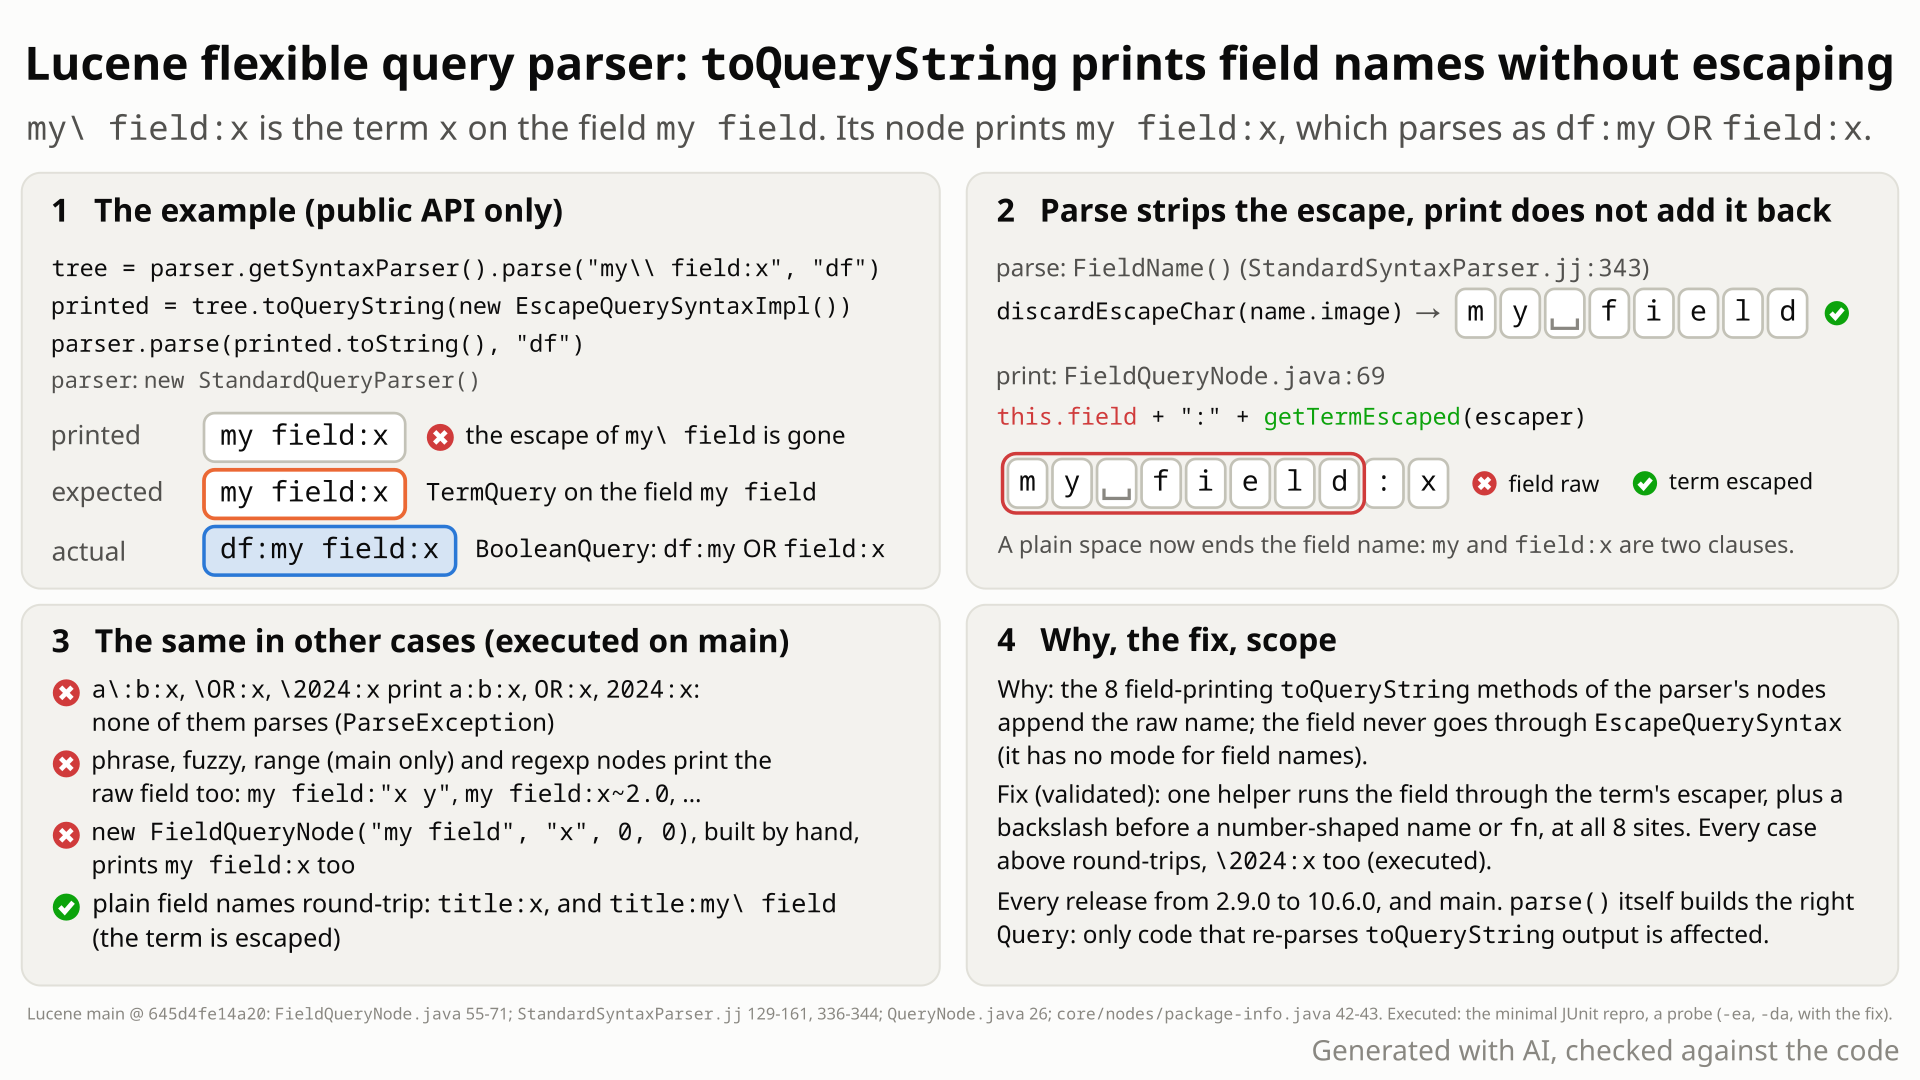
my\ field:x is on the field my field, but toQueryString prints my field:x, which parses as df:my OR field:x. Select the still to open it at full size. Generated with AI, checked against the code.- Parse
my\ field:xwithnew StandardQueryParser().getSyntaxParser(). The escaped space is allowed on purpose: you get a node on the fieldmy fieldwith the textx. - Print it with
toQueryString(new EscapeQuerySyntaxImpl())and parse the text again. You expectmy\ field:x, which gives back the same query, as the javadoc promises. - Instead it prints
my field:x, which parses as two clauses,df:myORfield:x, with no error. On an index with the documents {my field: x} and {field: x}, the original finds the first, the printed text the second. - Why: every
toQueryStringthat prints a field (term, phrase, fuzzy, range, point, wildcard, regexp, interval, and two nodes no parser builds) appends the name raw; the field never goes through the escaper. - Scale: of 9,119 one- and two-character printable-ASCII field names (all but
*), put in hand-built term nodes, 3,384 fail the round trip;a\:b:xprintsa:b:x, a syntax error.
Applications that print flexible-parser node trees back to text with toQueryString and parse, store or forward that text, for fields whose names contain a query-syntax character (space, colon, quote, bracket) or are a token by themselves (2024, OR, fn). Default settings; no index is needed to show it. StandardQueryParser.parse is unaffected, and no Lucene code re-parses the output.
Mechanism, terms and numbers649 words
The standard flexible query parser accepts escaped field names on purpose: my\ field:x is a term query on the field my field and a\:b:x one on a:b. QueryNode#toQueryString is documented to return "a query string understood by the query parser", and the node package says a tree "can also generate a query string that can be parsed back by the original text parser". But every toQueryString that prints a field appends the name raw; the field never goes through the EscapeQuerySyntax. So the node of my\ field:x prints my field:x, which parses as df:my OR field:x, and the node of a\:b:x prints a:b:x, a syntax error; phrase, fuzzy, hand-built nodes and, on main, range nodes do the same. Of 9,119 printable-ASCII field names of length 1 or 2 (all but *), 3,384 fail. It has been there since the flexible parser's first release, 2.9.0; StandardQueryParser.parse builds the right Query, and only code that prints node trees back to text is affected. A validated fix escapes the field through one helper at the eight field-printing sites of the nodes the standard parser builds; two more raw prints, in nodes no parser builds and whose output does not parse back anyway, are left as they are.
FieldQueryNode.toQueryString (FieldQueryNode.java:65-71) returns this.field + ":" + getTermEscaped(escaper) (:69); getTermEscaped (:56-58) runs only the text through escaper.escape(text, Locale.getDefault(), Type.NORMAL). The same raw field print is at the seven other sites of the nodes the standard parser builds: QuotedFieldQueryNode.java:39, FuzzyQueryNode.java:55, AbstractRangeQueryNode.java:166 (sb.append(getField()).append(":")), PointQueryNode.java:89, WildcardQueryNode.java:47, RegexpQueryNode.java:93 and IntervalQueryNode.java:49. Where a node escapes its text at all, only the term text meets the escaper: WildcardQueryNode, RegexpQueryNode and IntervalQueryNode print their text raw. Two more nodes print the field raw, AnyQueryNode.java:121 and ProximityQueryNode.java:186, but no parser code builds them, and their ANY / WITHIN output does not parse back even for a plain field (f:(( a b ) WITHIN 3) parses to (f:a f:b) f:WITHIN f:3, executed).
The parser keeps the escapes: FieldName() "strips escape characters from field names" (StandardSyntaxParser.jj:336-344) and returns an UnescapedCharSequence that records which characters were escaped. They are lost only when printing. EscapeQuerySyntax.Type has only STRING and NORMAL, no field mode.
A field name must lex as one TERM token (StandardSyntaxParser.jj:328). A character outside _TERM_START_CHAR (:131-133) cannot start it, and a space, :, ", (, [, @ and the others also outside _TERM_CHAR (:134) end it (+ and - break a name only in first position), and a whole name that is a number (NUMBER, :160), the interval prefix fn: (:147) or AND/OR/NOT (:144-146) lexes as something else.
input to the syntax parser                 toQueryString prints   parsing the printed text gives
f:x (control)                              f:x                    f:x (same)
my\ field:x                                my field:x             df:my OR field:x
a\:b:x                                     a:b:x                  syntax error
my\ field:"p q"                            my field:"p q"         df:my OR the quoted query on field
my\ field:xyz~1                            my field:xyz~1.0       df:my OR field:xyz~1
my\ field:[a TO b]  (main only)            my field:[a TO b]      df:my OR a range on field
my\ field:/x/                              my field:/x/           df:my OR a regexp on field
a\\b:c (the field a\b)                     a\b:c                  ab:c (the field ab)
new FieldQueryNode("dc:title","hugo",0,0)  dc:title:hugo          syntax error
\2024:x, \fn:x, \OR:x                      2024:x, fn:x, OR:x     errors
Exhaustive check on the stock jar: of 9,119 printable-ASCII field names of length 1 or 2 (all but *; each in a hand-built FieldQueryNode(name, "x"), printed and parsed again), 3,384 fail (479 parse to a different query, 2,905 do not parse; the finder's 3,388 include 4 point-field artifacts of the harness). Over every query string of length <= 5 from a 20-symbol alphabet (163,434 parsed), 3,832 of the 6,168 round-trip failures are this bug alone.
Exposure and likelihood143 words
- Who. Trees from the public
getSyntaxParser()(QueryParserHelper.java:172), processed trees (which can also hold post-analysis nodes such asTokenizedPhraseQueryNode, marked not re-parseable), or hand-built nodes; the node package says the nodes "are designed to be used by UI or other text parsers" (core/nodes/package-info.java:28). - Trigger. A field name with a syntax character, or one that is a token by itself. Namespaced names like
dc:titleoccur in practice (#1349 / LUCENE-271 reported one in 2004, for the classic API). - Effect. The printed text fails to parse or, silently, queries other fields. No index damage; the
Queryfromparseis right. - In-tree. The output only feeds exception messages (
QueryTreeBuilder.java:161,BooleanQueryNodeBuilder.java:72,MatchAllDocsQueryNodeBuilder.java:42,MatchNoDocsQueryNodeBuilder.java:42,AllowLeadingWildcardProcessor.java:74) andIntervalQueryNode.toString; nothing in Lucene parses it again. - Likelihood. Rare: the documented searches found no report in the 17 years since 2.9.0.
One JUnit class, one test method, public API only (StandardQueryParser, getSyntaxParser(), toQueryString, EscapeQuerySyntaxImpl), no analyzer, nothing randomized. It parses my\ field:x, prints the tree and asserts the printed text parses to the same query.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.flexible.standard;

import org.apache.lucene.queryparser.flexible.core.nodes.QueryNode;
import org.apache.lucene.queryparser.flexible.standard.parser.EscapeQuerySyntaxImpl;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestToQueryStringFieldNames extends LuceneTestCase {

  public void testFieldNameWithSpace() throws Exception {
    StandardQueryParser parser = new StandardQueryParser();
    QueryNode node = parser.getSyntaxParser().parse("my\\ field:x", "df");
    String printed = node.toQueryString(new EscapeQuerySyntaxImpl()).toString();
    // expected the printed string to parse back to my field:x; actual "my field:x" is df:my field:x
    assertEquals(
        "printed: " + printed, parser.parse("my\\ field:x", "df"), parser.parse(printed, "df"));
  }
}
cd $LUCENE && ./gradlew :lucene:queryparser:test --tests TestToQueryStringFieldNames -Ptests.seed=DEADBEEF -Ptests.asserts=true
- Expected
- The printed text parses back to the term query
my field:x. - Observed
expected:<my field:x> but was:<df:my field:x>: the node printsmy field:x; assertions on and off.
More files, environment, full output159 words
Oracle: parse(q) must equal parse(toQueryString(syntax tree of q)), which is what the javadoc promises. LuceneTestCase is only the base class; single thread, deterministic (same result with seeds DEADBEEF and 5EED1234).
Regression test: this same class (or its one method added to TestQPHelper); it passes with the recommended fix.
| lucene | main 645d4fe14a20 (11.0.0-SNAPSHOT): fails; 10.6.0 and every release back to 2.9.0: fail; with the fix: passes |
|---|---|
| jdk | OpenJDK 25.0.3 (build 25.0.3+9-LTS) |
| os | Linux, aarch64 (the only platform run; plain string handling) |
cp $REPRO/TestToQueryStringFieldNames.java $LUCENE/lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/
cd $LUCENE && ./gradlew :lucene:queryparser:test --tests TestToQueryStringFieldNames -Ptests.seed=DEADBEEF -Ptests.asserts=true
# assertions off fails the same way: -Ptests.asserts=false
# gradle, stock 645d4fe14a20, -Ptests.seed=DEADBEEF -Ptests.asserts=true (stack trimmed; -Ptests.asserts=false identical)
   >     java.lang.AssertionError: printed: my field:x expected:<my field:x> but was:<df:my field:x>
   >         at __randomizedtesting.SeedInfo.seed([DEADBEEF:2DCFAF3042D63897]:0)
   >         at junit@4.13.2/org.junit.Assert.assertEquals(Assert.java:120)
   >         at org.apache.lucene.queryparser.flexible.standard.TestToQueryStringFieldNames.testFieldNameWithSpace(TestToQueryStringFieldNames.java:30)

:lucene:queryparser:test (FAILURE): 1 test, 1  failure

# standalone runner, seed DEADBEEF: main 645d4fe14a20 and 10.6.0 fail with -ea and -da, same message- The javadoc promises "a query string understood by the query parser", one that "can be parsed back by the original text parser".
- Escaped field names are deliberate, tested syntax:
TestQPHelperassertsa\:b:cis a query on the fielda:b. - Lucene fixed the same round trip for range nodes as a bug in 11.0.0 (#7865, PR #14697).
The full argument193 words
- Contract.
QueryNode.java:26: "convert to a query string understood by the query parser".core/nodes/package-info.java:42-43: "A query node tree can also generate a query string that can be parsed back by the original text parser, at this point only the standard lucene syntax is supported."EscapeQuerySyntax.java:22-23: the escaper exists "to allow the QueryNode to escape the queries, when the toQueryString method is called". The colon case does not even parse. - Deliberate input.
StandardSyntaxParser.jj:337;TestQPHelper.java:817-820assertsa\-b:c,a\+b:c,a\:b:canda\\b:cgive the fieldsa-b,a+b,a:banda\b; LUCENE-161 (#1239) added escaped field names in 2004. - Precedent.
CHANGES.txt:296-298(11.0.0 Bug Fixes): "GITHUB#7865 AbstractRangeQueryNode#toQueryString(EscapeQuerySyntax) now returns a string which can be parsed back into the original node." Field escaping never came up in #14697 (its tests use an ordinary field name). - No intent found. In the material reviewed (the flexible parser's source, tests and javadoc, CHANGES and MIGRATE, the six commits that added the eight sites, the review threads in the follow-up) nothing says fields are printed raw on purpose. The three core lines are unchanged since 2009; the later sites (2010-2025) copied the pattern without comment.
The devil's-advocate check279 words
The strongest case for "intended": a 2017 java-user reply on range round trips said "There has never been a guarantee that going back and forth between a parsed query and its string representation is idempotent"; open #8667 calls toQueryString a design error; #1349 / LUCENE-271, the same symptom for the classic Query.toString(field) (dc\:title:hugo printed as dc:title:hugo), was closed "Not A Problem" in 2011; inside Lucene the output feeds only error messages and one toString; some nodes say their output is not re-parseable (TokenizedPhraseQueryNode.java:47; MultiPhraseQueryNode prints [MTP[...]]); and the escaper never had a field mode.
Why it fails: Query.toString is documented as user-readable, while QueryNode#toQueryString and its package promise text the parser understands and can parse back. In the same 2017 thread Michael McCandless answered "Why don't we fix this in Lucene?", and #14697 then fixed the range round trip as a bug, its approver noting "we're changing behaviour that is public and has been around a long time, but it's also a bug fix". #8667 is about non-standard syntaxes; this fails with the standard one. The not-re-parseable nodes are post-analysis nodes and are marked as such; the syntax parser's field nodes carry no such mark. Being used only in messages limits impact, not intent. For hand-built nodes the promise can hold only for names the standard syntax can write at all (an empty name cannot be written); the claim is about names it can write, as the parser's own escaped-field tests show. A read-only cross-model refute review returned only a procedural "not real" (it could not run Java), agreed on the root cause and rated this argument weak; the intended-lens review said real.
Recommended Escape the field through one helper at the eight standard-parser sites (validated)
A helper in QueryNodeImpl runs the field through the term's escaper (plus a backslash for names that lex as a number or fn:); the eight field-printing sites of the nodes the parser builds call it (+43/-8 in 9 files). The repro and the queryparser module pass; exhaustive field-name mismatches drop from 3,388 to 101 (a sibling escaper gap, harness artifacts).
protected CharSequence getFieldEscaped(CharSequence fld, EscapeQuerySyntax escaper) {
  CharSequence escaped = escaper.escape(fld, Locale.ROOT, EscapeQuerySyntax.Type.NORMAL);
  // a field name must lex as a term; a bare number or "fn" would lex as a number or as the
  // interval function prefix "fn:", so escape its first character
  if (escaped != null
      && ("fn".contentEquals(escaped) || NUMBER_FIELD.matcher(escaped).matches())) {
    return "\\" + escaped;
  }
  return escaped;
}
All options and trade-offs4 options · 779 words
One fix was written and validated in a scratch worktree of 645d4fe14a20; the alternatives are described, and one partial variant was run by a verifier. The output of toQueryString changes for such names, so maintainers may want it in 11.0 only, as for #14697.
+43/-8 in 9 files (tidy-formatted). QueryNodeImpl gets protected getFieldEscaped(CharSequence, EscapeQuerySyntax); FieldQueryNode, QuotedFieldQueryNode, FuzzyQueryNode, AbstractRangeQueryNode, PointQueryNode, WildcardQueryNode, RegexpQueryNode and IntervalQueryNode call it instead of printing the raw field. AnyQueryNode.java:121 and ProximityQueryNode.java:186 stay as they are: no parser builds those nodes, and their ANY / WITHIN text does not parse back even for a plain field, so escaping their field alone would not make them round-trip (with the fix their output is unchanged, executed); a maintainer may still want them to call the helper for consistency. NUMBER_FIELD is Pattern.compile("[0-9]+(\\.[0-9]+)?"), the grammar's NUMBER token.
protected CharSequence getFieldEscaped(CharSequence fld, EscapeQuerySyntax escaper) {
  CharSequence escaped = escaper.escape(fld, Locale.ROOT, EscapeQuerySyntax.Type.NORMAL);
  // a field name must lex as a term; a bare number or "fn" would lex as a number or as the
  // interval function prefix "fn:", so escape its first character
  if (escaped != null
      && ("fn".contentEquals(escaped) || NUMBER_FIELD.matcher(escaped).matches())) {
    return "\\" + escaped;
  }
  return escaped;
}
Trade-offs
- Output change: names with syntax characters print with backslashes (
my\ field:x); names equal (ignoring case) to AND, OR, NOT, TO, WITHIN, SENTENCE, PARAGRAPH or INORDER, number-shaped names (2024,1.5) andfnget a leading one (\to:x,\2024:x); plain names print as before. Worth a CHANGES entry. - Inherits the escaper's own gaps. Sibling LFV-398:
@after the first character and the names&&/||still fail untilEscapeQuerySyntaxImplis fixed; in the exhaustive printable-ASCII check those are the only real field-name failures left. Beyond ASCII,escapeIgnoringCasematches on a lower-cased copy and inserts the backslashes at its indexes, so a character whose lower case is longer shifts them: with the fix the fieldİ:a(U+0130) printsİ:\a:x, which does not parse, andİ aprintsİ \a:x, which parses todf:İ a:x(executed; stock fails too). Open outside PR #16853 fixes that escaper bug. - Reusing the term escaper is safe for fields:
\toparses back to the fieldto, and*/?are escaped only when they were escaped in the input. - Puts two standard-syntax rules (number,
fn:) in the core node base class, which already prints standard syntax (:,~,[ TO ]).
What the checks validated
Gradle --no-daemon in a scratch worktree of 645d4fe14a20, OpenJDK 25.0.3 (2026-10-31). Stock: the repro fails with assertions on and off. With the fix:
- the repro passes with assertions on and off;
- the whole
:lucene:queryparser:testpasses: 534 tests (533 plus the repro), 0 failures, 1 skipped, seeds DEADBEEF and CAFEBABE;checkGoogleJavaFormat,forbiddenApisMainandecjLintMainpass; - the finder's 4-test class, the independent reproduction's 11-test class and the intended-behaviour check's 9-test class pass on the fixed sources;
- the exhaustive harness on the fixed sources: field mode 3,388 -> 101 of 9,119 (4 point-field artifacts of the harness; 95 names with
@after the first character,&&and||, all LFV-398); syntax mode 6,168 -> 2,144 of 163,434, all LFV-398 classes. Without the number/fnrule 212 remain (110 all-digit names andfnmore). The field mode buildsFieldQueryNode(name, "x")directly, so it covers that node; the other sites were run by the probes and the verifiers' tests.
An independent fact check re-ran all of this (gradle stock and fixed, -ea/-da, the module, lint, the harness) with the same results.
Add EscapeQuerySyntax.Type.FIELD and let EscapeQuerySyntaxImpl own the field rules (the term rules plus number, fn, inner @, &&, ||); the nodes call escape(field, locale, Type.FIELD).
Trade-offs
Keeps the syntax rules in the syntax's escaper, but adds a constant to a public enum that custom EscapeQuerySyntax implementations must handle.
When the field is an UnescapedCharSequence (as FieldName() returns), print toStringEscaped().
Trade-offs
Reproduces what the user typed, but does nothing for hand-built nodes or String field names (new FieldQueryNode("my field", ...)), nor for parsed interval queries, whose node gets field.toString() and loses the escape flags (StandardSyntaxParser.jj:379); it is incomplete on its own.
Change only FieldQueryNode.toQueryString.
Trade-offs
Fixes the term, colon and hand-built-node cases; phrase, fuzzy and range still fail (3 of 11 tests), because each node prints the field itself.
An application that checks or rewrites a node tree and then re-parses or forwards the printed text runs a query on other fields than the tree it checked; an allowlist of field names catches it.
A bounded-exhaustive round-trip check on the stock jar built a term node for every printable-ASCII field name of length 1 or 2 (9,119, all but *), printed it with toQueryString and parsed the text again; about 3,400 names failed. A public-API JUnit then reproduced it from parsed input, and independent verifiers confirmed it with their own tests.
The method in full129 words
Method: semi-formal (bounded-exhaustive translation validation on the real jar).
- Finder. Hunt unit on the flexible, simple and XML query parsers (2026-10-26, main
ea57360912ed).FlexRoundTripmodefield: hand-builtFieldQueryNode(name, "x")for 9,119 names, printed and parsed again, 3,388 mismatches (3,384 genuine, 4 point-field artifacts of the harness); modesyntax: every string of length <= 5 over a 20-symbol alphabet, 163,434 parsed, 6,168 failures, 3,832 of them this class alone and 264 more combined with@. Then a 4-test JUnit on the stock jars (3 of 4 fail on main with-eaand-da, and on 10.5.2). - Verification. Read-only cross-model reviews (OpenAI GPT-5.6), an independent reproducer, an intended-behaviour devil's advocate, an adjudication, the version-history runs, an audit and a one-test minimal repro (see the checks below).
No prior report: 54 tool queries plus direct searches over GitHub (Lucene and downstream), the mailing lists, JIRA and the web on 2026-10-26, re-checked on 2026-10-31. Closest: #1349 / LUCENE-271, the same symptom in the classic Query.toString, closed "Not A Problem" because that API is not meant to be parseable.
Searches3 searches
Verdict new: no issue, PR, commit, JIRA ticket or list thread reports that the flexible toQueryString prints field names unescaped. Not fixed upstream: main 2f424fd428da (2026-10-30) still prints the raw field, and no open PR touches a field-printing node. The closest item, #1349 / LUCENE-271, concerns the classic Query.toString, a different API that is not meant to parse back.
| Where | When | How | Found |
|---|---|---|---|
| GitHub issues, PRs and commits (apache/lucene; Lucene.NET, Elasticsearch, OpenSearch, Solr) | 2026-10-26 | a scripted prior-report search (16 issue/PR, 3 commit, 2 downstream queries) plus direct searches (toQueryString with field/escape, "escaped field", the node class names); the changed-file lists of all 410 open PRs; git log --grep=toQueryString over the full history | context only: #1349 / LUCENE-271, #5738 / LUCENE-4673, #8667 / LUCENE-7616, #7865 / PR #14697, open PRs #16853 and #16892 (term escaping), #1239 / LUCENE-161 |
| Mailing lists, JIRA and the web | 2026-10-26 | 20 list queries (dev@, java-user@, issues@, commits@), 4 JIRA archive queries and JIRA REST, 9 web queries | a 2017 java-user thread on range round trips; nothing about field names |
| GitHub re-check | 2026-10-31 | issue and PR searches for toQueryString, FieldQueryNode and escape field name; upstream main's FieldQueryNode | nothing new; upstream main unchanged |
Introduced with the flexible parser itself (343992fcbb4b, LUCENE-1567, 2009-08-03), so every release from 2.9.0 to 10.6.0 and main is affected. The range variant shows only on main, since #14697 fixed the older range-printing bug that hid it.
Versions tested6 rows
Introduced by 343992fcbb4b "LUCENE-1567: New flexible QueryParser framework." (svn r800191, 2009-08-03; migrated issue #2641; no PR in the svn era). git blame attributes the field-printing lines of FieldQueryNode, QuotedFieldQueryNode and FuzzyQueryNode to it; its grammar already stripped escapes from field names. LUCENE-9528 (3a92e1b93eb, 9.0.0) moved that into FieldName() unchanged. The later sites copied the pattern: WildcardQueryNode and RegexpQueryNode (2010), PointQueryNode (2011), IntervalQueryNode (f725b27e12a, LUCENE-10223, 2021). #14697 (17ca89d52fa, merged 2025-05-29, unreleased 11.0.0) fixed GITHUB#7865 and added the raw getField() print to the range node; before it, range output failed for every field. The raw print and the escape-stripping grammar are in all 134 release tags 2.9.0 to 10.5.2 of the history clone.
| Version or commit | Verdict | Result |
|---|---|---|
main 645d4fe14a20; 10.6.0 | affected | minimal repro fails, assertions on and off |
| 2.9.0, 3.6.2, 4.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 | affected | version-portable probe: all 5 field-name cases fail, 3 controls pass (SHA-1-checked jars) |
| 2.4.1 and earlier | not affected | no flexible query parser (the probe does not compile) |
| range on an escaped field | main only | releases fail for every field (GITHUB#7865): 4.0.0 to 10.5.2 print [my field:a my field:b], 2.9.0 and 3.6.2 my field>="a" AND my field<="b"; main after #14697 prints the raw field |
main with AbstractRangeQueryNode at 17ca89d52fa^ | bisect | the plain-field range control fails again, which ties the range change to #14697 |
main 645d4fe14a20 with the fix | not affected | repro passes; the queryparser module passes |
An independent reproducer, an intended-behaviour devil's advocate, an adjudication, the version-history runs and an audit all found it real; the only dissent was a procedural "not real" from a read-only OpenAI GPT-5.6 review that could not run Java and agreed on the root cause. This doc's gradle run reproduced it and validated the fix.
Checks and verdicts374 words
Every executed check ran on stock builds or SHA-1-checked release jars; the cross-model reviewers could only read code, and separate runs re-ran the repro.
| Check | Verdict | What it found |
|---|---|---|
| Finder (bounded-exhaustive round trip) | candidate | Field mode 3,388 of 9,119 names fail (3,384 genuine); a 4-test JUnit fails 3 of 4 on main -ea/-da and 10.5.2. |
| Refute lens (OpenAI GPT-5.6, read-only) | not real (procedural, low) | Could not run Java; agreed on the root cause and that the inputs are legal; rated the intended argument weak. |
| Independent reproducer | real | Own 11-test JUnit fails 6 of 11 on main -ea/-da (5 controls pass), 7 of 11 on 10.5.2 and 9.12.3; a FieldQueryNode-only fix leaves 3 failing. |
| Intended lens (OpenAI GPT-5.6, read-only) | real (medium) | Intended argument moderate; root cause agrees; a separate run re-ran the repro on main and 10.5.2. |
| Devil's advocate | real | Own 9-test JUnit fails 5 of 9 on main -ea/-da and 10.5.2 (4 legality probes pass); found no intent for raw printing; corrected the count to 3,384. |
| Adjudication | confirmed (high) | Re-ran the independent reproduction's JUnit on main -ea/-da: 6 of 11 fail, controls pass. |
| History follow-up | 2.9.0, 343992fcbb4b | Probe on 2.9.0 to main; 134-tag sweep; commit-level shadow for the range variant. |
| Audit | keep | Finder repro on main -da fails 3 of 4; own probe fails 3 of 5, both controls pass. |
| Minimal repro and this doc | real; fix validated | The one-test class fails on 645d4fe14a20 and 10.6.0 with -ea and -da; gradle in a scratch worktree validated the fix. |
| Fact check (independent, executed) | correct in substance; three text fixes, applied | Re-ran the doc's gradle command stock and fixed (-ea/-da), the runner on main and 10.6.0, the module with the fix, every table row, the harness and the 4.0.0 history probe. Found the two extra raw prints, an unscoped fix claim and the how-found wording; all fixed. |
| Cross-model fact check (OpenAI GPT-5.6, read-only) | sound with corrections, applied | Checked the claims against the code and the saved logs; agreed the bug is real and minor. Its corrections (site count, node-by-node mechanism, run names, scoping) are applied. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 528 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,594 words
- Registry title
- Flexible query parser: QueryNode#toQueryString prints field names without escaping, so nodes for escaped field names such as 'my field' or 'a:b' print strings that parse to a different query or do not parse
- Area
- queryparser / flexible parser node serialization (QueryNode#toQueryString of FieldQueryNode, QuotedFieldQueryNode, FuzzyQueryNode, AbstractRangeQueryNode and the other field-printing nodes)
- Priority
- Low, rank 771: The flexible parser's toQueryString round trip breaks only for escaped field names and only in applications that re-parse node text, which no in-tree caller does, so it joins the niche flexible-parser rows.
- Impact class
- minor
- Impact note
- A round-trip (contract) defect in a utility method, with no effect on the Query that StandardQueryParser.parse builds: applications that turn flexible-parser node trees back into text with toQueryString (trees from StandardQueryParser.getSyntaxParser(), processed trees, or hand-built nodes) and parse or forward that text get a string that does not parse, or that silently queries other fields, whenever a field name contains a query-syntax character (space, colon, quote, bracket, ...) or is a token by itself ('2024', 'OR', 'fn'); inside Lucene the output only feeds exception messages; default parser configuration, any scale, every release since 2.9.0 (the range variant on unreleased main only).
- Summary
- The standard flexible-parser grammar accepts escaped field names on purpose ('my\ field:x' is a query on the field 'my field', 'a\:b:x' on 'a:b'), and QueryNode#toQueryString is documented to return 'a query string understood by the query parser' that 'can be parsed back by the original text parser'. Every toQueryString that prints a field appends the name raw (only the term goes through the escaper), so the node of 'my\ field:x' prints 'my field:x', which parses as df:my OR field:x, and the node of 'a\:b:x' prints 'a:b:x', which is a syntax error. The same happens for phrase and fuzzy nodes, for range nodes on main (after the #7865 range fix), and for hand-built nodes such as new FieldQueryNode("my field", "x", 0, 0).
- Introduced
- 343992fcbb4b31249f07354014723f18d0508d8a (LUCENE-1567 'New flexible QueryParser framework', SVN r800191; SVN era, no GitHub PR; issue migrated as apache/lucene#2641). The raw field printing in FieldQueryNode, QuotedFieldQueryNode and FuzzyQueryNode is unchanged since that commit, and its grammar already stripped escapes from field names (discardEscapeChar(fieldToken.image); LUCENE-9528 / 3a92e1b93eb moved this into FieldName() for 9.0 without changing it). [read: git blame on main and git log --follow -G'field \+ ":"' on each file return only 343992fcbb4b; exec: 2.4.1 has no flexible parser, 2.9.0 fails]. The range variant was un-masked, not introduced, by 17ca89d52fa (PR #14697, fixes GITHUB#7865 / LUCENE-6807, merged 2025-05-29, unreleased 11.0.0): before it the range printer's output did not parse for any field, and it added sb.append(getField()).append(":") with the raw field. Other field-printing sites (read only): WildcardQueryNode (LUCENE-588, a25dc8b9d5c, 2010), RegexpQueryNode (LUCENE-2604, 838e19beae1, 2010), PointQueryNode (LUCENE-1768, c178c8eb1a8, 2011). (2009-08-03 (343992fcbb4b); range variant visible from 2025-05-29 (17ca89d52fa, main only))
- First affected version
- 2.9.0 [exec] (the first release with the flexible query parser; 2.4.1 has no such API [exec: compile error, and no queryparser artifact on the central repository]); range-on-escaped-field variant: unreleased (main only, after #14697, slated for 11.0.0)
- Affected versions
- every release from 2.9.0 to 10.5.2 (the last before 10.6.0) and main ea57360912ed for term, phrase, fuzzy, colon and hand-built nodes; no fixed release. [exec] a version-portable main() probe fails 5 of 5 field-name cases with 3 of 3 controls passing on 2.9.0, 3.6.2, 4.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (-ea and -da); the finder's JUnit fails 3 of 4 on main (-ea and -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 6 of 11 on main (-ea and -da) and 7 of 11 on 10.5.2 and 9.12.3; the intended-behaviour check's fails 5 of 9 on main (-ea and -da) and 10.5.2. Range variant: on 9.12.3, 10.5.2 and older the range printer still has the pre-#14697 bracket bug ('[my field:a my field:b]', and the plain-field range control fails too, which is the independent reproduction's 7th failure), so the range-on-escaped-field failure is a clean, separate demonstration only on main; a commit-level check (AbstractRangeQueryNode at 17ca89d52fa^ shadowed onto main) makes the plain range control fail again. [read] source-checked in all 134 release tags 2.9.0..10.5.2 of the history clone; untagged releases (2.9.3, 2.9.4, 3.0.2, 3.0.3, 8.8.2, 8.9.0, 8.10.x, 8.11.0-8.11.3) inferred from identical neighbours. Upstream main still prints this.field raw (GitHub REST, 2026-10-26). Not executed: x86, the JDK of each release's era (all runs JDK 25.0.3 aarch64; the code path is pure string handling).
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only; the prior-report record, verdict new): no issue, PR, commit, JIRA ticket or mailing-list thread reports that the flexible QueryNode#toQueryString prints field names unescaped; upstream main still has FieldQueryNode.toQueryString return this.field + ":" + getTermEscaped(escaper), and none of the 410 open apache/lucene PRs touches a field-printing node. Related, not this bug: #1349 / LUCENE-271 (the classic core Query.toString(field) prints escaped field names raw; closed Not A Problem in 2011 because Query.toString is not meant to be parseable; it predates the flexible parser and is a different API, contract and fix site; maintainers may cite it as precedent), #5738 / LUCENE-4673 (open; TermQuery.toString is user-readable, not re-parsable), #8667 / LUCENE-7616 (open; toQueryString always emits standard syntax), #7865 / LUCENE-6807 and PR #14697 (the range round trip, fixed as a bug for 11.0.0; #14697 added the raw getField() print of the range variant, and field escaping never came up in the issue or the review), open outside PRs #16853 and #16892 (term text escaping only), #1239 / LUCENE-161 (escaped field names on the parse side, fixed 2004) and a 2017 java-user thread on range round trips (a reply quoted there says round trips were never guaranteed; a committer answered 'Why don't we fix this in Lucene?'). Searched: a scripted prior-report search with 54 queries (16 GitHub issue/PR, 3 commit, 2 downstream, 20 mailing-list over dev@, java-user@, issues@ and commits@, 4 JIRA, 9 web; 440 distinct hits, every high/medium hit read), direct GitHub searches over apache/lucene, apache/lucenenet, elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr, a downstream flexible-parser grammar repository and org:apache, a changed-files scan of all 410 open apache/lucene PRs, JIRA REST over LUCENE, LUCENENET and SOLR, lists.apache.org searches, and git log --grep=toQueryString over the full history; #1349's comments re-read for this row (no mention of the flexible parser). Gaps: GitHub full-text search can miss text that appears only in comments (the top hits' comments were read through the API), StackOverflow was judged from snippets, and private reports to security@lucene.apache.org are not visible.
- Lucene commit tested
- main
645d4fe14a20(2026-10-28;lucene/queryparseridentical toea57360912ed, where the hunt ran): the minimal test fails with assertions on and off through gradle in a scratch worktree and through a standalone runner; with the recommended fix it passes, as does the whole queryparser module (534 tests, seeds DEADBEEF and CAFEBABE) and the finder's and verifiers' test classes, and the exhaustive field-name check drops from 3,388 to 101 mismatches (all a sibling escaper gap or harness artifacts). 10.6.0 fails with assertions on and off; the version-history runs ran 2.9.0, 3.6.2, 4.0.0, 8.11.4, 9.0.0, 9.12.3, 10.0.0 and 10.5.2 (SHA-1-checked jars, all fail). Upstream main2f424fd428da(2026-10-30) has the same code [read].
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/FieldQueryNode.java:65-71 (at ea57360912ed) (toQueryString: this.field + ":" + getTermEscaped(escaper)); core/nodes/QuotedFieldQueryNode.java:39; core/nodes/FuzzyQueryNode.java:55; standard/nodes/AbstractRangeQueryNode.java:166 (sb.append(getField()).append(":")); standard/nodes/PointQueryNode.java:89; standard/nodes/WildcardQueryNode.java:47; standard/nodes/RegexpQueryNode.java:92; standard/nodes/IntervalQueryNode.java:49lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QueryNode.java:26 (at ea57360912ed) ('convert to a query string understood by the query parser'); core/nodes/package-info.java:42-43 ('can also generate a query string that can be parsed back by the original text parser'); core/parser/EscapeQuerySyntax.java:21-23lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/StandardSyntaxParser.jj:336-344 (at ea57360912ed) (FieldName(): 'This utility method strips escape characters from field names')lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/TestQPHelper.java:817-820 (at ea57360912ed) (escaped field names a\-b, a\+b, a\:b, a\\b asserted)lucene/CHANGES.txt:281-283 (at ea57360912ed) (11.0.0 Bug Fixes, GITHUB#7865: range toQueryString 'can be parsed back into the original node')https://github.com/apache/lucene/issues/1349 (LUCENE-271 comments, read-only gh issue view, 2026-10-26)
- The finding in 30 seconds
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/FieldQueryNode.java:56-58, :65-71a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QuotedFieldQueryNode.java:39; core/nodes/FuzzyQueryNode.java:55; standard/nodes/AbstractRangeQueryNode.java:166; standard/nodes/PointQueryNode.java:89; standard/nodes/WildcardQueryNode.java:47; standard/nodes/RegexpQueryNode.java:93; standard/nodes/IntervalQueryNode.java:49a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/AnyQueryNode.java:121; core/nodes/ProximityQueryNode.java:186; standard/nodes/WildcardQueryNode.java:42-48; standard/nodes/RegexpQueryNode.java:92-94; standard/nodes/IntervalQueryNode.java:48-50 (no `new AnyQueryNode` or `new ProximityQueryNode` in lucene/queryparser/src/java)a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/StandardSyntaxParser.jj:131-133, :144-147, :160, :328, :336-344a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/parser/EscapeQuerySyntax.java:21-33
- Who is affected
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/QueryParserHelper.java:172; core/nodes/package-info.java:28a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/builders/QueryTreeBuilder.java:161; standard/builders/BooleanQueryNodeBuilder.java:72; standard/builders/MatchAllDocsQueryNodeBuilder.java:42; standard/builders/MatchNoDocsQueryNodeBuilder.java:42; standard/processors/AllowLeadingWildcardProcessor.java:74; standard/nodes/IntervalQueryNode.java:54
- Why it looks unintended
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/QueryNode.java:26; core/nodes/package-info.java:42-43; core/parser/EscapeQuerySyntax.java:22-23a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/StandardSyntaxParser.jj:336-344a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/test/org/apache/lucene/queryparser/flexible/standard/TestQPHelper.java:817-820a Lucene main checkout (645d4fe14a20) lucene/CHANGES.txt:275 (11.0.0 Bug Fixes), :296-298 (GITHUB#7865)a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/core/nodes/TokenizedPhraseQueryNode.java:47; standard/nodes/MultiPhraseQueryNode.java:62; standard/parser/StandardSyntaxParser.jj:161 (TERM needs one character)
- Suggested fix
a Lucene main checkout (645d4fe14a20) lucene/queryparser/src/java/org/apache/lucene/queryparser/flexible/standard/parser/EscapeQuerySyntaxImpl.java:100-146 (escapeIgnoringCase); standard/parser/StandardSyntaxParser.jj:379; GitHub PR #16853 (open; read-only, 2026-10-31)
- Prior reports
GitHub (read-only, 2026-10-31): gh search issues/prs on apache/lucene; contents API for upstream main FieldQueryNode.java (line 69)
- TestToQueryStringFieldNames.java (one test class):
repro/LFV-356/src/org/apache/lucene/queryparser/flexible/standard/TestToQueryStringFieldNames.java(33 lines)
Made in parallel with this doc from the code at 645d4fe14a20 and an executed probe on main (the parse, print and re-parse of the example, with assertions on and off, and with the recommended fix).
assets/LFV-356/bug.png(528 KB)