SimpleQueryParser lets you glue operators to tokens, as in token1+token2. After a phrase slop such as ~2, the parser skips the next character, so a glued +, |, quote or ( loses its meaning.
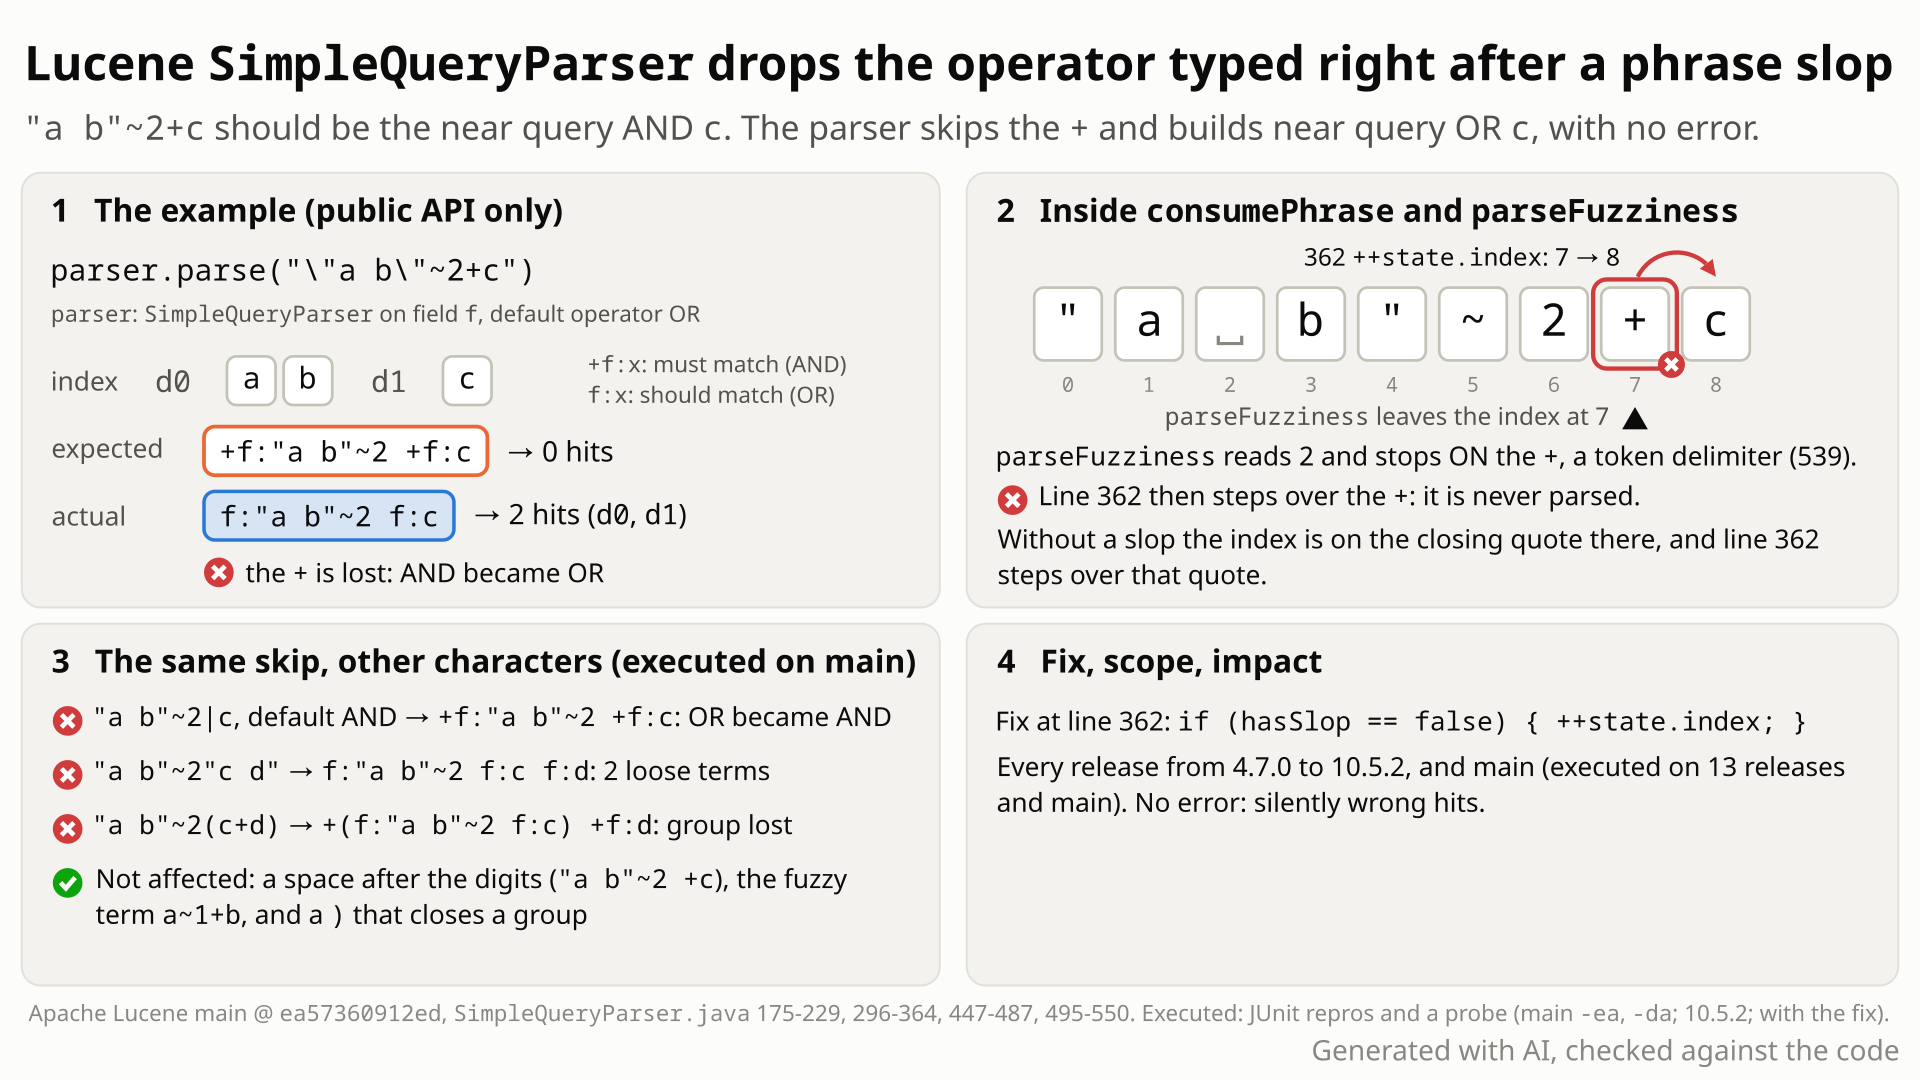
"a b"~2+c on two documents, the characters with the parser's position (the slop parse stops on the + at position 7, then line 362 steps to 8), the other characters skipped the same way, and the fix. Select the still to open it at full size. Generated with AI, checked against the code.- Index three documents: "new york pizza", "new york bagels" and "chicago pizza". Parse
"new york"~2+pizzawithSimpleQueryParserand its default settings: the phrase new york with up to 2 positions of slop, AND pizza. - You expect 1 hit, "new york pizza". With a space,
"new york"~2 +pizza, or without the slop,"new york"+pizza, that is exactly what you get. - Instead you get 3 hits. The parser reads the slop digit
2and stops on the+; then a leftover step, meant to skip the phrase's closing quote, skips the+. The query is built as phrase OR pizza. - The same happens to
|(with default operator AND, an OR becomes an AND), to a quote (the next phrase becomes loose words) and to((the group is lost). No error, with assertions on or off. - A space after the slop digits avoids it. A fuzzy term (
a~1+b) and a)that closes a group are not affected.
Every SimpleQueryParser user with the default flags (the near operator is on by default) who types a sloppy phrase followed, with no space, by +, |, a quote or (. No scale is needed. By code reading, parsers built on this class downstream inherit it. The shape is rare, and the searches found no prior report.
Mechanism, terms and numbers761 words
SimpleQueryParser's javadoc says that whitespace and ( ) + | " delimit tokens, that a phrase is a token, that token1+token2 is AND and token1|token2 is OR (written without spaces), and that "term1 term2"~5 is a near query. When a phrase with a slop is followed directly by one of those delimiters, the parser skips the delimiter: "a b"~2+c becomes f:"a b"~2 f:c (OR) instead of +f:"a b"~2 +f:c, although "a b"~2 +c and "a b"+c both give the AND. On the documents "new york pizza", "new york bagels" and "chicago pizza", "new york"~2+pizza matches 3 documents instead of 1.
The cause is an off-by-one in consumePhrase: parseFuzziness reads the slop digits and stops on the delimiter after them, and the unconditional ++state.index that follows, written in 2013 to step over the closing quote, then steps over that delimiter. It needs the default flags only, raises no error, and is in every release since 4.7.0 (2014), the first with the ~ operator. The fix is one condition: skip the closing quote only when there was no slop.
- Slop (near query).
"a b"~2is a phrase whose words may be up to 2 positions apart (PhraseQuery(2, "f", "a", "b")). An empty~followed by another character means slop 2 (since 6.5.0); a~at the very end of the input means no slop. - Default operator. What two tokens with nothing between them combine with: OR, unless
setDefaultOperator(MUST). - Delimiter. A character that ends a token: whitespace,
",|,+,(or)(javadocSimpleQueryParser.java:41-42,tokenFinished:536-550).
| input | default operator | expected (= the spaced form) | on main |
|---|---|---|---|
"a b"~2+c | OR | +f:"a b"~2 +f:c | f:"a b"~2 f:c |
"a b"~+c (empty slop = 2) | OR | +f:"a b"~2 +f:c | f:"a b"~2 f:c |
"a b"~2|c | AND | f:"a b"~2 f:c | +f:"a b"~2 +f:c |
"a b"~2"c d" | OR | f:"a b"~2 f:"c d" | f:"a b"~2 f:c f:d |
"a b"~2(c+d) | OR | f:"a b"~2 (+f:c +f:d) | +(f:"a b"~2 f:c) +f:d |
"new york"~2+pizza on {"new york pizza", "new york bagels", "chicago pizza"} | OR | 1 hit | 3 hits |
The expected column is what the javadoc's operators define and what the same input with a space after the slop gives on main; the slop 2 of an empty ~ is the parser's own rule, not a javadoc statement. Not affected: "a b"+c (no slop), the fuzzy term a~1+b, a ) that closes a group right after the slop ((x|"a b"~2)+c), and an extraneous ) ("a b"~2)c), which is ignored either way.
Further cases (executed on main, 10.5.2 and with the fix):
- A glued
+under default AND, or|under default OR, is skipped too. When a token follows, the default operator then gives the same query; when a second operator follows, it does not, because the parser keeps the first explicit operator: under default AND"a b"~2+|cgives OR on main and AND with a space or the fix. - The skip also follows slop text that does not parse:
"a b"~x+cgives slop 0 and loses the+(f:"a b" f:c), and so do"a b"~1a+cand"a b"~2\+c. - An empty phrase:
a""~+agivesf:a f:ainstead of+f:a +f:a.
consumePhrase(SimpleQueryParser.java:296-364) reads the phrase up to its closing quote. If~and more characters follow, it moves onto the~and setshasSlop(:317-324).parseFuzziness(:495-533, called at:356) advances from the~and stops at the first delimiter (:505-507), so the index is left on the+.consumePhrasethen always runs++state.index(:362). That line dates from 2013, when the index was always on the closing quote there. After a slop it skips the+, and the parse loop never sees it.- The lost
+or|leaves the next token to the default operator; a lost quote turns the next phrase into separate terms; a lost(merges the group into the main sequence. consumeTokencalls the sameparseFuzzinessfor fuzzy terms (:410) with no trailing increment, soa~1+bkeeps its AND. A group's)is safe becauseconsumeSubQueryparses the group's inner text as its own substring (:288-289).
// SimpleQueryParser.java:355-362
if (hasSlop) {
  branch = newPhraseQuery(phrase, parseFuzziness(state)); // returns with the index ON the delimiter
} else {
  branch = newPhraseQuery(phrase, 0);
}
buildQueryTree(state, branch);

++state.index; // meant to step over the closing quote; after a slop it skips the delimiter
Exposure and likelihood298 words
- Who is exposed. Every caller of
SimpleQueryParserwith the default flags: the two-argument and the weights constructors pass-1(SimpleQueryParser.java:141-148), which includesNEAR_OPERATOR. Nothing has to be configured. There is no other in-tree caller outside the parser's own package. - What it takes. A
+,|,"or(typed directly after the slop digits, after an empty~, or after slop text that does not parse (~x). Glued operators are the documented style of this syntax (token1+token2), so users who write"new york"~2+pizza, and code that builds query strings by concatenation, can produce it. - What goes wrong. A query of the wrong structure, silently. Under default OR it over-matches: AND becomes OR, AND NOT becomes OR NOT, a phrase becomes loose terms. Under default AND a glued
|under-matches: OR becomes AND, while a lost quote still widens the query (the second phrase becomes required loose terms: 2 hits instead of 1 on the documents "a b c d" and "a b d c"). A lost(can go either way. No exception, crash or index change. - Downstream (by code reading only, not run). Elasticsearch's and OpenSearch's
simple_query_stringparsers and Solr's simple query parser extendSimpleQueryParser;consumePhraseis private, so they inherit the parse loop. - How likely. Rare: slop is an advanced feature, the upstream test writes
"foo bar"~12 bazwith a space, the most natural glued case (a)closing a group) is unaffected, and the searches found no prior report (see Prior reports). - Opt-out. The targeted opt-out is turning
NEAR_OPERATORoff, which disables phrase slop altogether; turning off the phrase operator or the operator that follows also removes the path, but disables more syntax. The practical workaround is a space after the slop digits.
The test shows that SimpleQueryParser skips the + typed directly after a phrase slop, so "a b"~2+c does not parse like "a b"~2 +c.
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.queryparser.simple;

import org.apache.lucene.tests.analysis.MockAnalyzer;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestSimpleQueryParserSlopOperator extends LuceneTestCase {

  public void testAndDirectlyAfterPhraseSlop() {
    SimpleQueryParser parser = new SimpleQueryParser(new MockAnalyzer(random()), "field");
    // expected: "a b"~2+c parses like "a b"~2 +c (phrase AND c); actual: the '+' is skipped (phrase OR c)
    assertEquals(parser.parse("\"a b\"~2 +c"), parser.parse("\"a b\"~2+c"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-359/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/facet/build/libs/lucene-facet-$V.jar
CP=$CP:$LUCENE/lucene/queries/build/libs/lucene-queries-$V.jar
CP=$CP:$LUCENE/lucene/queryparser/build/libs/lucene-queryparser-$V.jar
CP=$CP:$LUCENE/lucene/sandbox/build/libs/lucene-sandbox-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.queryparser.simple.TestSimpleQueryParserSlopOperator
# the module(s) facet also need their third-party runtime jars
- Expected vs actual
- Expected
+field:"a b"~2 +field:c(phrase AND c); actualfield:"a b"~2 field:c(phrase OR c), with-eaand-da.
More files, environment, full output38 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: expected:<+field:"a b"~2 +field:c> but was:<field:"a b"~2 field:c>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
       org.junit.Assert.assertEquals(Assert.java:146)
org.apache.lucene.queryparser.simple.TestSimpleQueryParserSlopOperator.testAndDirectlyAfterPhraseSlop(TestSimpleQueryParserSlopOperator.java:27)- The javadoc defines
token1+token2as AND and"term1 term2"~5as a near query, so"a b"~2+cis valid syntax. - The parser itself stops the slop at the
+, and keeps it after a space, after a phrase without slop and aftera~1+b. - The skipping step is older than the slop feature: it was written to skip the closing quote.
The full argument251 words
- Contract.
SimpleQueryParser.java:40-42: "Tokens are considered to be any of a term, phrase, or subquery ... Whitespace ... and certain operators may be used to delimit tokens ( ) + | \" .":50-51: "'+' specifies AND operation: token1+token2", "'|' specifies OR operation: token1|token2".:56: "'~N' at the end of phrases specifies near query: \"term1 term2\"~5". - Upstream tests.
testORPhraserequires"foo bar"|"star wars"to be an OR although the test helper's default operator is AND, so an operator glued to a phrase must be honoured (testANDPhraseagrees, but under that default it cannot tell a kept+from a dropped one). No test covers an operator glued to a slop;testPhraseWithSlopchecks"foo bar"~12 bazwith a space, which the skip does not harm, so it is not evidence either way. With the fix all 46TestSimpleQueryParsertests pass. - The parser's own consistency.
parseFuzzinessends the slop exactly at the+becausetokenFinishedsays it is a delimiter, and then the delimiter is discarded. The fuzzy-term path calls the same helper without the extra step and keeps the operator. - History. The
++state.indexcame with the class (LUCENE-5336, 2013), when the index was always on the closing quote at that point. LUCENE-5410 (2014) put the slop branch in front of it without changing it. Its review noted that the term and phrase paths differ "in how they consume/increment state.data and state.index", but no comment discusses an operator after a slop. No CHANGES, MIGRATE or javadoc text describes the skip.
The devil's-advocate check246 words
The strongest "works as designed" case (the GPT-5.6 reviews, the devil's advocate and the adjudication looked for it): the javadoc promises only a best effort, "Any errors in query syntax will be ignored and the parser will attempt to decipher what it can; however, this may mean odd or unexpected results", and slop parsing is lenient on purpose ("foo bar"~1a and "foo bar"~-1 silently give slop 0 in an upstream test). A maintainer could call an operator glued to a slop badly composed input. They could also point out that no upstream example or test puts an operator right after a slop, that - is not a delimiter and is swallowed into the slop text, and that the behaviour has not changed in twelve years, so a stored query could depend on it.
Why it fails: the input is not a syntax error, since the javadoc defines every piece of it; the parser itself recognizes the + as the end of the slop and then throws it away; the same delimiter is honoured after a space, after a phrase without slop and after a fuzzy term; the lenient tests are about the slop text itself, while the + after a valid ~2 is outside it; and the cause is a leftover increment from before the slop feature, not a decision. Twelve years of the same behaviour argue for a CHANGES entry, not for keeping a skip that no documentation describes. Verdict: not intended, a defect.
Recommended Run the trailing increment only when there was no slop
Skip the closing quote only when there was no slop: wrap the trailing ++state.index in consumePhrase in if (hasSlop == false). Then the new test passes 7 of 7, the existing 46 TestSimpleQueryParser tests still pass, and so does the whole queryparser module (540 tests, 0 failures).
      buildQueryTree(state, branch);

-      ++state.index;
+      if (hasSlop == false) {
+        // skip the closing quote (or a trailing '~'); after a slop, parseFuzziness already left the
+        // index on the delimiter that ended it, which must still be parsed, or at the end of input
+        ++state.index;
+      }
    }
  }
All options and trade-offs4 options · 569 words
One fix was built and validated in a scratch worktree at ea57360912ed (option A), together with a variant that moves the same line (option B).
fix.diff, +5/-1 in SimpleQueryParser.java. Without a slop the index is on the closing quote (or a trailing ~ at the end of the input) and must be skipped as before. With a slop, parseFuzziness has already consumed the ~ and the digits and stands on the delimiter or at the end of the input, so nothing is left to skip; the parse loop then handles the delimiter as it does after a space.
      buildQueryTree(state, branch);

-      ++state.index;
+      if (hasSlop == false) {
+        // skip the closing quote (or a trailing '~'); after a slop, parseFuzziness already left the
+        // index on the delimiter that ended it, which must still be parsed, or at the end of input
+        ++state.index;
+      }
    }
  }
Trade-offs
- The resulting query changes only when a
+,|,"or(follows the slop text: after a valid or empty slop (the bug), and also after slop text that does not parse ("a b"~x+c), which then parses like its spaced form. Whitespace, an extraneous)and the end of input give the same query as before (executed). - A stored query written in the glued shape and tuned to today's result would now parse as documented, so a CHANGES entry under bug fixes is worth adding.
- Not reviewed by a committer.
What the checks validated
- Stock: this doc's test fails 6 of 7 with assertions on and off; with the fix all 7 pass.
- The simple package (
TestSimpleQueryParser46 tests and the new test), assertions on and off: 53 tests, 0 failures. - The whole queryparser module: 31 classes, 540 tests, 0 failures, 1 skipped.
:lucene:queryparser:check -x testpasses (google-java-format, ecjLint, forbiddenApis).- Every earlier hunt test with the fix shadowed on the main jars passes (the finder's 4, the independent reproducer's 6 and its empty-slop test, the cross-model review stage's 5, the devil's advocate's 3), and the security probe gives the spaced results.
- The finder's two exhaustive harnesses with the same one-condition change report 0 mismatches (10,047,388 and 2 x 11,413,636 checks).
- After the fact checks the patch's code comment was reworded (comment only): both diffs apply to
ea57360912ed, google-java-format finds nothing to change, and this doc's test passes 7 of 7 with it, assertions on and off.
option-b-move-increment.diff: put ++state.index in the else branch next to newPhraseQuery(phrase, 0). It reads as "skip the closing quote where it is still the current character".
Trade-offs
Same behaviour as the recommended option; a matter of style.
What the checks validated
The simple package passes: 53 tests, 0 failures (assertions on).
Change the shared helper instead of the phrase path.
Trade-offs
Not recommended and not tested: the fuzzy-term caller relies on the index being left on the delimiter, so it would break a~1+b.
Put a space after the slop digits ("a b"~2 +c); applications that build query strings should do the same, and keep access restrictions in a separate FILTER clause.
Trade-offs
Avoids the symptom; does not fix the parser.
The parser returns the whole query, so a restriction written in this syntax inherits the misparse. A glued + turns its AND into OR and it fails open: in the probe 7 of 8 documents match instead of 3. Only the rule's author creates the shape; a separate FILTER clause and the documented escaping contain it. No exploit known.
Semi-formal. While building exhaustive checks of SimpleQueryParser, an AI tool spotted the extra step by reading the code. The checks then found it as the only mismatch: over all 2.4 million strings of up to 7 characters from an 8-symbol alphabet, a space next to an operator changed the query only after a phrase slop.
The method in full179 words
Method: bounded-exhaustive checking on the stock jar (the hunt's semi-formal tier; no model checker, SMT solver or prover).
- In a hunt unit (query parsers, 2026-10-26) the finder, an AI tool, saw the off-by-one by reading
consumePhrasewhile building two harnesses. Its first run, every string of up to 5 characters, found nothing: the bug needs at least 6. - Metamorphic check. "A space next to an operator does not change the query", over every string of up to 7 characters over
a + | - " ~ 1and space: 2,396,745 strings, 10,047,388 checks, 819 mismatches per default operator, every one a phrase followed by~. - Translation validation. An independent reference semantics of the documented grammar, evaluated as match sets on all 40 documents of up to 3 tokens over {a, b, c}: 11,413,636 checks per default operator, 354,538 (OR) and 349,990 (AND) mismatches, every one an operator directly after
phrase~N. - With the fix both harnesses report 0 mismatches. The finder then wrote a deterministic public-API JUnit; the independent checks, history sweep, prior-report search and security assessment followed.
No prior report found (2026-10-26): 179 read-only queries and checks over Lucene issues and PRs, commits, mailing lists, JIRA, open-PR file lists, downstream trackers, Stack Overflow and the web. Closest: the 2014 change that introduced it; its review does not mention this case.
Searches4 searches
Verdict new: no issue, PR, JIRA entry, list thread, forum post or downstream report describes the parser dropping the character typed after a phrase slop, by anyone. No open PR touches the parser's package, and the newest upstream commits to the file are formatting changes. Limits: GitHub search drops punctuation, so the literal trigger cannot be searched; a report worded only as "AND is ignored" could be missed; private reports are not visible.
| Where | When | How | Found |
|---|---|---|---|
| apache/lucene issues and PRs (migrated JIRA included), commits | 2026-10-26 | a scripted prior-report search (34 GitHub and commit queries) and 25 GraphQL searches; re-checked | only #6473 (LUCENE-5410, the introducing change; all 20 comments read), #6400 (LUCENE-5336, origin of the increment), #8763 (empty slop means 2), #11687 (open, stack overflow on deep nesting) and unrelated parser issues |
| Open PRs | 2026-10-26 | the changed files of all 411 open apache/lucene PRs; a title search | none touches the simple query parser package |
| Mailing lists and JIRA | 2026-10-26 | dev@, java-user@, issues@, commits@ (40 queries); LUCENE and SOLR JQL (14 queries) | no report; a 2018 java-user@ thread loses an operator through '-' with whitespace operators off, a different input and mechanism |
| Downstream, forums and the web | 2026-10-26 | Elasticsearch, OpenSearch, Solr and Lucene.NET issues and PRs (6 phrasings per repository, each as issue and PR search, plus 5 tool queries); 7 Stack Overflow queries; 12 web queries; 8 forum and list pages read | no report; Elasticsearch #4985 is the 2014 copy of the introducing code |
Introduced in 4.7.0 by LUCENE-5410 (2014), which added ~ to the parser and put the slop branch in front of an older step that skips the closing quote. Wrong on all 13 releases run, from 4.7.0 to 10.5.2, and on main; never fixed. 4.7.0 is the first release with the class at all.
Versions tested7 rows
Introduced by LUCENE-5410 "add fuzzy and near to SimpleQueryParser" (issue #6473; patch by @dakrone, committed by @rmuir on 2014-02-02 as 584fda3bdf0 on trunk and b18fdadedec on branch_4x, an SVN-era patch with no pull request). The skipping ++state.index is older: LUCENE-5336 (3c9e753df64, 2013-11-12) added it when the index was always on the closing quote at that point.
consumePhrase is unchanged in all 110 release tags of the history clone (4.7.0 to 10.5.2; the clone lacks 8.8.2 and 8.9.0 to 8.11.4, of which 8.8.2 and 8.11.4 were executed); parseFuzziness changed in 6.5.0 (an empty slop means 2), 9.0.0 and 9.10.0 without moving where the index stops. Not a regression. Upstream main (head f4cc6ac2097c, 2026-10-26) has no change to the file since df6f71a3729, a formatting commit already in the tested tree.
| Version or commit | Verdict | Result |
|---|---|---|
main ea57360912ed | affected | this doc's test 6 of 7 fail (gradle and harness, -ea and -da); portable probe fails |
| 10.0.0, 10.5.2 | affected | portable probe fails; this doc's test 6 of 7 fail on 10.5.2 |
| 9.0.0, 9.12.3 | affected | portable probe fails; this doc's test 6 of 7 fail on 9.12.3 |
| 5.0.0, 6.4.2, 6.5.0, 6.6.6, 7.7.3, 8.8.2, 8.11.4 | affected | portable probes fail (6.6.6 by the devil's advocate's probe, 8.8.2 by the fact check) |
| 4.7.0, 4.10.4 | first release | portable probe fails; 4.7.0 is the first release with SimpleQueryParser and the '~' operator |
| 4.6.1 | API absent | the simple query parser package does not exist; the probe does not compile |
| fix on main | not affected | this doc's test 7 of 7, the simple package 53 tests and the queryparser module 540 tests pass |
An independent reproducer, a devil's advocate and an adjudication, each running tests on main, and a "works as designed" review from another model family (OpenAI GPT-5.6, reading only) say real. A refute review that could not run code said "not real" only procedurally. This doc's own test was run on main, 10.5.2, 9.12.3 and with the fix.
Checks and verdicts423 words
Every check ran on main ea57360912ed; the GPT-5.6 reviews could read code but not run it, and the harness that drove them re-ran the finder's repro (not a reproduction of their own).
| Check | Verdict | What it found |
|---|---|---|
| finder | candidate | JUnit 4 of 4 fail on main (-ea, -da), 10.5.2 and 9.12.3; pass with the fix; upstream TestSimpleQueryParser 46 of 46 with the fix. |
| refute review (GPT-5.6, reading only) | not real, low (procedural) | Could not run code, so it voted not real on procedure only; it agreed with the root cause, found the inputs within the contract and rated the intended argument weak. A separate run re-ran the repro: 4 of 4 fail. |
| Independent reproducer | real | Own JUnit from the claim alone: 5 of 6 fail on main, 10.5.2 and 9.12.3, adding the '(' case; the fuzzy-term control passes; 6 of 6 with the fix; the empty slop loses the '+' too. |
| "works as designed" review (GPT-5.6, reading only) | real, medium | Intended argument weak: the disclaimer covers syntax errors and this input is valid syntax. A separate JUnit fails 4 of 5 on main and 9.12.3 and passes with the fix. |
| Devil's advocate | real, high | No javadoc, test, CHANGES, MIGRATE or issue text makes the skip intended; its probe fails on 10.5.2, 9.12.3, 8.11.4, 6.6.6 and 5.0.0. |
| adjudication | confirmed, high | Re-ran the independent reproduction's JUnit: 5 of 6 fail with -ea and -da, 6 of 6 pass with the fix; not a duplicate. |
| Follow-up re-run and audit | keep | Fresh seeds: the finder's test fails on main (-ea, -da) and 10.5.2 and the independent reproduction's on main (-ea, -da); both pass with the fix; a new probe shows a ')' closing a group is not affected; the audit's own probe agrees. |
| this doc's re-runs (2026-10-26) | reproduced; fix validated | New 7-test JUnit: 6 of 7 fail on main (gradle and harness, -ea and -da), 10.5.2 and 9.12.3; with the fix 7 of 7 pass and the queryparser module passes (540 tests). |
| fact checks and diagram check (2026-10-26) | reproduced; text corrected | An AI tool that did not write this doc re-ran the gradle command, the fix, the harnesses and its own probe: no false statement, 5 precision points. An independent reviewer from another model family (OpenAI GPT-5.6, reading only) found 7 errors (0 high), 6 overclaims and 5 missing caveats, none against the bug or the fix; a diagram check found one wrong state value in the diagram. All were fixed. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 405 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,427 words
- Registry title
- SimpleQueryParser drops the '+', '|', quote or '(' typed directly after a phrase slop, so "a b"~2+c parses as phrase OR c and "a b"~2|c (default operator AND) as phrase AND c
- Area
- queryparser / SimpleQueryParser (near operator: consumePhrase phrase slop)
- Priority
- Low, rank 263: Default SimpleQueryParser syntax, but only an operator glued directly after phrase-slop digits triggers it, and a space avoids it.
- Impact class
- silent wrong results
- Impact note
- Every SimpleQueryParser user with the default flags (NEAR_OPERATOR is on by default) who types a sloppy phrase immediately followed by '+', '|', a quote or '(' with no space gets a query of the wrong structure and wrong hits with no error (AND becomes OR under the default OR, OR becomes AND under default MUST, a following phrase becomes loose terms, a following group loses its grouping); no scale is needed, every release since 4.7.0 has it, a space after the slop digits avoids it, and a ')' that closes a group directly after the slop is not affected.
- Summary
- You parse "a b"~2+c with SimpleQueryParser and expect what its javadoc defines, the near query AND c, just as "a b"~2 +c and "a b"+c parse. Instead the parser skips the character right after the slop digits, so the '+' is lost and you get phrase OR c (on an index with the documents 'a b' and 'c' it matches 2 documents instead of 0); the same happens to '|' ("a b"~2|c becomes AND under default MUST), to a quote ("a b"~2"c d" becomes the phrase OR c OR d) and to '(' ("a b"~2(c+d) loses its group). The cause is an off-by-one in consumePhrase: parseFuzziness already stops on the delimiter that ends the slop, and the unconditional '++state.index' that was written to step over the closing quote then skips that delimiter.
- Introduced
- 584fda3bdf0a5b044046feb63c322ae8dee997a4 (trunk, LUCENE-5410 'add fuzzy and near to SimpleQueryParser', svn r1563558) and its branch_4x backport b18fdadedecad444583eaa0eb343c35d6aa84707 (svn r1563562, the commit that shipped first, in 4.7.0); an SVN-era commit of a JIRA patch, no pull request; issue LUCENE-5410 = apache/lucene#6473 (CHANGES credit 'Lee Hinman via Robert Muir'). The skipping '++state.index' itself is older (LUCENE-5336, 3c9e753df64 / 64e591e1b7a, 2013-11-12), when it only stepped over the closing quote; LUCENE-5410 put the slop branch, whose parseFuzziness leaves the index on the next delimiter, in front of it. [read: git blame and git log -S hasSlop in the full-history clone; exec: 4.7.0 fails, and 4.7.0 with SimpleQueryParser.java from the parent 64e591e1b7a shadowed passes only trivially, because '~' was not an operator yet] (2014-02-02)
- First affected version
- 4.7.0 [exec] (the first release with SimpleQueryParser and its '~' operator; 4.6.1 has no SimpleQueryParser, the probe does not compile)
- Affected versions
- every release from 4.7.0 to 10.5.2 (the last before 10.6.0) and main ea57360912ed; never fixed. [exec] the follow-up's version-portable main() probe (4 bug cases against their spaced forms, 2 controls) fails on 4.7.0, 4.10.4, 5.0.0, 6.4.2, 6.5.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main and passes on main with the fix; the finder's JUnit fails 4 of 4 on main (-ea, -da), 10.5.2 and 9.12.3; the independent reproduction's JUnit fails 5 of 6 on main (-ea, -da), 10.5.2 (-ea, -da) and 9.12.3; the intended-behaviour check's main() probe fails on 10.5.2, 9.12.3, 8.11.4, 6.6.6 and 5.0.0. [read] consumePhrase is whitespace-normalized identical in all 110 release tags of the history clone (4.7.0 to 10.5.2) and on main (the clone lacks 8.9.0 to 8.11.3; 8.11.4 was executed); parseFuzziness changed in 6.5.0 (LUCENE-7712: an empty slop means 2), 9.0.0 and 9.10.0, none of which moves where the index stops; the newest upstream commits to the file on main (df6f71a3729, in the tested tree) and branch_10x (ef740ebd967) change only javadoc formatting. All runs on JDK 25, aarch64 Linux.
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new, 179 logged queries and checks: a scripted prior-report search with 100 queries over apache/lucene issues and PRs, commits, downstream repositories, the dev@, java-user@, issues@ and commits@ lists, the LUCENE JIRA archive and the web; 25 GitHub GraphQL searches over apache/lucene; the changed files of all 411 open apache/lucene PRs (none touches lucene/queryparser/.../simple/); 24 searches, each as issue and PR search, over elastic/elasticsearch, opensearch-project/OpenSearch, apache/solr and apache/lucenenet; 6 JQL queries over SOLR and LUCENE; 7 Stack Overflow queries; 8 forum and list pages read; the upstream commit history of the file; and the finder's earlier 51-query run). No item reports or discusses SimpleQueryParser dropping the character after a phrase slop. Closest items, none the same bug: #6473 (LUCENE-5410, the introducing change; all 20 comments read, none mentions a delimiter after a phrase slop), #6400 (LUCENE-5336, origin of the increment), #8763 (LUCENE-7712, empty slop means 2), #11687 (open, stack overflow on deep nesting), #9611, #10407, #8541, #7359, the java-user@ thread of 2018-04-12 'SimpleQueryParser does not tokenize on NOT operator' (no replies; an operator lost in tokenisation too, but a different input and mechanism: '-' is not a delimiter when WHITESPACE_OPERATOR is disabled), SOLR-8318, SOLR-5447, SOLR-10897, elastic/elasticsearch#4985 (the copy of the LUCENE-5410 code), #62789, #7875, #4911, #23366 and opensearch-project/OpenSearch#22557 (a nesting-depth pre-scan, not the slop path). Not fixed upstream. Gaps: GitHub search drops punctuation, so the literal trigger cannot be searched; 2 Stack Exchange queries failed on quota and 2 Stack Overflow pages were read by title only; keyword search can miss a report that says only 'AND is ignored'; private reports are not visible.
- Lucene commit tested
- 2026-10-26 on main
ea57360912ed(commit of 2026-10-24): this doc's test through gradle with assertions on and off and through the standalone harness, also on the 10.5.2 and 9.12.3 release jars; the earlier checks' tests on main, 10.5.2 and 9.12.3; a version-portablemain()on 4.7.0, 4.10.4, 5.0.0, 6.4.2, 6.5.0, 7.7.3, 8.11.4, 9.0.0, 9.12.3, 10.0.0, 10.5.2 and main (and, in the fact check, 8.8.2), and another on 6.6.6; the recommended fix in a scratch worktree atea57360912ed(removed afterwards): the simple package with assertions on and off, the whole queryparser module (540 tests) and the static checks; every earlier hunt test with the fix shadowed.
- Finding record
lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:36-45 (at ea57360912ed) (intent: 'a person should be able to type whatever they want'; whitespace and ( ) + | " delimit tokens; syntax errors 'may mean odd or unexpected results'), :50-57 (token1+token2 is AND, token1|token2 is OR, "term1 term2"~5 is a near query, ( ) give precedence), :146-148 (default flags -1 include NEAR_OPERATOR), :237-293 (consumeSubQuery finds the matching ')' and parses the group as its own substring), :314-325 (consumePhrase: closing quote followed by '~' sets hasSlop), :355-362 (parseFuzziness, then the unconditional ++state.index), :495-533 (parseFuzziness stops on tokenFinished and leaves the index on the delimiter), :536-550 (tokenFinished: the delimiter set)
- The finding in 30 seconds
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:40-42, 50-51, 56 (javadoc: delimiters, + and |, near query), 175-235 (parseSubQuery), 237-294 (consumeSubQuery; substring at 288-289), 296-364 (consumePhrase; hasSlop 317-324; parseFuzziness call 356; ++state.index 362), 366-432 (consumeToken; parseFuzziness 410, no trailing increment), 495-533 (parseFuzziness; tokenFinished break 505-507), 536-550 (tokenFinished)Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:186-207 (an explicit operator is ignored when one is already set), 322-324 (hasSlop only when characters follow the '~'), 512-525 (empty slop 2; NumberFormatException gives 0)
- Who is affected
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:141-148 (default flags -1), :50 (token1+token2), :108-136 (the operator flags), :536-546 (tokenFinished checks each flag)Lucene main ea57360912ed: lucene/queryparser/src/test/org/apache/lucene/queryparser/simple/TestSimpleQueryParser.java:135 ("foo bar"~12 baz with a space), :602-609 (testDisableSlop)
- Why it looks unintended
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:40-42, 44-45, 50-51, 56, 362, 505-507Lucene main ea57360912ed: lucene/queryparser/src/test/org/apache/lucene/queryparser/simple/TestSimpleQueryParser.java:54-63 (the test helper's default operator MUST), :113-136 (testPhraseWithSlop; lenient slops 124-127; spaced form 135), :155-163 (testANDPhrase), :195-203 (testORPhrase)
- Suggested fix
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:366-432 (consumeToken relies on parseFuzziness leaving the index on the delimiter)
- Diagrams
Lucene main ea57360912ed: lucene/queryparser/src/java/org/apache/lucene/queryparser/simple/SimpleQueryParser.java:355-362, 495-533 (the steps shown)
- TestSimpleQueryParserSlopOperator.java (JUnit test):
repro/LFV-359/src/org/apache/lucene/queryparser/simple/TestSimpleQueryParserSlopOperator.java(29 lines)
A summary diagram (PNG), made in parallel with this text from the code at ea57360912ed and the executed runs.
assets/LFV-359/bug.png(405 KB)