A suffix rule's condition is about the end of the root. When the condition is shorter than the letters the rule strips, Lucene tests it on the first stripped letters instead of the last ones (and the other way round for prefixes).
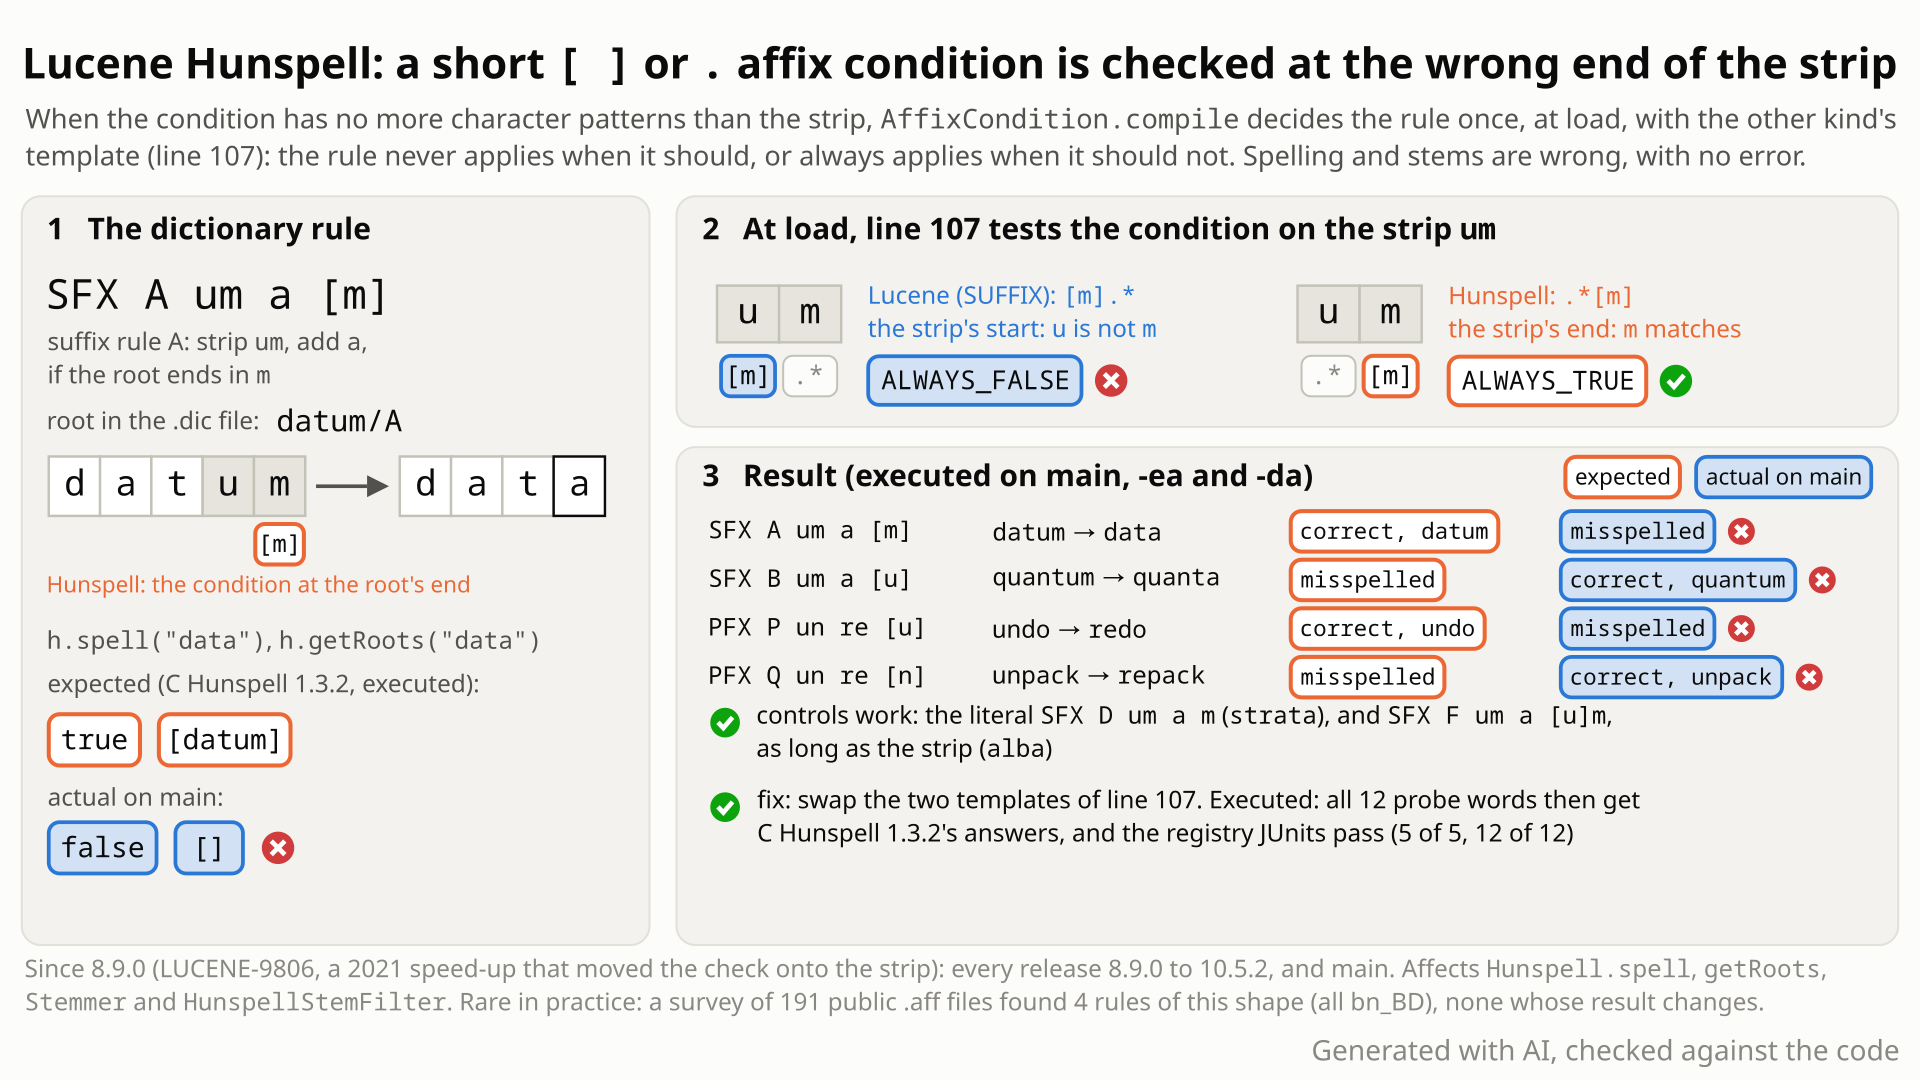
SFX A um a [m] on datum: at load, line 107 tests [m] on the strip's first letter u instead of its last letter m, so data is rejected. The table shows all four rules, expected against actual. Select the still to open it at full size. Generated with AI, checked against the code.- Load a dictionary with the suffix rule
SFX A um a [m]: remove the 2 lettersum, adda, but only if the root ends inm. The.dicfile has the rootdatum/A. - You expect
spell("data")to be true with the rootdatum. C Hunspell says so, and Lucene says so too when the same condition is writtenm, without brackets. - You get false and no root, with no error, and
HunspellStemFilterleavesdataunstemmed. The opposite also happens: withSFX B um a [u]onquantum,quantais accepted, althoughquantumdoes not end inu. - Why: the 1-letter condition fits inside the 2-letter strip, so Lucene decides the rule once, at load, with
"um".matches("[m].*"). That tests the strip's first letteru; a suffix condition belongs at its last letterm. Prefix rules are mirrored:redo(fromundo) is rejected andrepackis stemmed tounpack. - Affected are conditions that Lucene treats as patterns (they contain
[ ],.or a dash-) and that have fewer character patterns than the strip; plain-letter conditions are lined up correctly. None of the 191 public dictionaries surveyed changes its results, so custom dictionaries are the ones at risk.
Only users of Lucene's opt-in Hunspell analysis (Hunspell, HunspellStemFilter) whose dictionary has a PFX or SFX rule with a pattern condition (with [ ], . or -) shorter than its strip. No error is raised. In 191 surveyed public dictionaries, 4 rules have this shape and none changes a result, so custom dictionaries are the ones at risk.
Mechanism, terms and numbers799 words
A Hunspell affix rule has a strip, an affix and a condition: SFX A um a [m] means "remove um, add a, if the root ends in m". When a condition contains [ ], . or - and has no more character patterns than the strip has letters, it lies wholly inside the strip, and AffixCondition.compile decides the rule once, at load: it matches the strip against kind == PREFIX ? ".*" + condition : condition + ".*" (AffixCondition.java:107). That tests a suffix condition at the strip's start and a prefix condition at its end, the opposite of Hunspell. So the rule never applies when it should (data from datum rejected, redo from undo rejected) or always applies when it should not (quanta accepted with root quantum, repack stemmed to unpack). Hunspell.spell, getRoots, the Stemmer and HunspellStemFilter give these wrong answers with no error, while the same condition written as a plain letter (m) works. C Hunspell 1.3.2 gives the expected answers. It is a regression from LUCENE-9806 (3a99e2aa82d, 2021), present in every release from 8.9.0 to 10.6.0 (10.6.0 by reading) and on main; the fix swaps the two templates. None of the 191 surveyed public dictionaries changes its results.
- Affix rule: a line
SFX flag strip affix condition(orPFX) in the.afffile. To make a word from a root, remove the strip from the root's end (start forPFX) and add the affix, but only if the root meets the condition.SFX A um a [m]turnsdatumintodata. - Condition: a pattern of single characters: a letter,
.(any character) or[...](a set;[^...]its complement). hunspell(5) explains its own exampleSFX B y ied yas "can be added to the words terminated with an `y'": a suffix condition is matched against the root's last characters, which include the strip. - Lucene's shortcut: when spelling or stemming, Lucene sees the word with strip and affix already removed, so
AffixCondition.compilesplits the condition at load into the part that falls on the strip, checked once, and the part that falls on the remaining stem.
- A condition that contains
[,.or-, thatuniqueKeyhas not already mapped to "always true" (it does so for.alone and for a condition that literally equals the strip's start or end,AffixCondition.java:73-80), and that has no more character patterns than the strip lies wholly on the strip (:105-106). - Lucene then decides the rule once:
String regex = kind == PREFIX ? ".*" + condition : condition + ".*";andstrip.matches(regex) ? ALWAYS_TRUE : ALWAYS_FALSE(:107-108). condition + ".*"matches the strip's start, which is right for a prefix rule, but it is given to suffix rules;".*" + conditionmatches the strip's end and is given to prefix rules.- For conditions in Hunspell's syntax (letters,
.and[...], one character each) both templates agree when the condition is as long as the strip, so only shorter conditions get the wrong constant. Every consumer then uses that constant:Stemmer(forspell,getRootsandHunspellStemFilter), word-form generation and suggestions.
| rule, root | what Hunspell checks | what line 107 checks | Lucene | C Hunspell 1.3.2 |
|---|---|---|---|---|
SFX A um a [m], datum | last letter m: met | "um".matches("[m].*"), first letter u: false | data misspelled, no root | data, root datum |
SFX B um a [u], quantum | last letter m: never met | "um".matches("[u].*"): true | quanta correct, root quantum | quanta misspelled |
PFX P un re [u], undo | first letter u: met | "un".matches(".*[u]"), last letter n: false | redo misspelled | redo, root undo |
PFX Q un re [n], unpack | first letter u: never met | "un".matches(".*[n]"): true | repack correct, stem unpack | repack misspelled |
SFX D um a m (literal), stratum | last letter m: met | not reached (uniqueKey says always true) | strata, root stratum | the same |
The same condition gets different answers depending only on how it is spelled: for SFX abc d <cond> on the root xabc, stock main accepts xd with c, bc, abc and [a]bc and rejects it with [c], [b]c and .c; with the fix all 7 spellings (and the 7 prefix ones) agree.
A lone dash takes the same path: Lucene treats any condition with - as a pattern (AffixCondition.java:153-155), while hunspell(5) says "Dash hasn't got special meaning". So SFX A a- x - on the root ba- rejects bx on main, while C Hunspell 1.3.2 gives bx with the root ba-, and so does Lucene with the fix.
Exposure and likelihood264 words
- Who. Users of Lucene's Hunspell analysis: the spell checker
Hunspell(spell,getRoots, suggestions) andHunspellStemFilter/HunspellStemFilterFactory. No default analyzer uses Hunspell. - Two halves. A condition that is redundant with the strip (
SFX A um a [m]) is never applied, so correct words are rejected and stems are lost; it is natural to write, and C Hunspell 1.3.2 applies it with no warning, also in 8-bit mode. A condition that contradicts the strip (SFX B um a [u]) is always applied, so wrong words are accepted and wrong stems appear; C Hunspell in 8-bit mode warns "incompatible stripping characters and condition" for such rules, so they are unusual (the 1.7.2 source skips that check in UTF-8 mode). - Real dictionaries. 191 public
.afffiles (99 from LibreOffice, 92 from wooorm/dictionaries, 2,306,338 rules) contain 4 rules of this shape, all in the LibreOfficebn_BDfolder. Their bracket holds both characters of the strip, so both ends agree and no result changes. The survey counted conditions with[,.or-. None of the surveyed dictionaries is affected; others were not checked. - Effect. Silent wrong spelling verdicts, missing stems (
datastaysdata) and invented ones (repackbecomesunpack, so on a stemmed field the queryunpackmatchesrepack).HunspellStemFilteralso runs at index time, so the indexed stems of such words change with the fix. - Scale. None needed: one word triggers it, deterministically, every time such a dictionary is loaded.
- Versions. Every release from 8.9.0 to 10.6.0 (10.6.0 by reading), and main.
The test shows that a Hunspell suffix rule whose bracket condition is shorter than its strip is checked against the start of the strip instead of the end of the root (SFX A abc d [c] on root xabc).
/*
 * Licensed to the Apache Software Foundation (ASF) under one or more
 * contributor license agreements.  See the NOTICE file distributed with
 * this work for additional information regarding copyright ownership.
 * The ASF licenses this file to You under the Apache License, Version 2.0
 * (the "License"); you may not use this file except in compliance with
 * the License.  You may obtain a copy of the License at
 *
 *     http://www.apache.org/licenses/LICENSE-2.0
 *
 * Unless required by applicable law or agreed to in writing, software
 * distributed under the License is distributed on an "AS IS" BASIS,
 * WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
 * See the License for the specific language governing permissions and
 * limitations under the License.
 */
package org.apache.lucene.analysis.hunspell;

import java.io.ByteArrayInputStream;
import java.nio.charset.StandardCharsets;
import java.util.List;
import org.apache.lucene.tests.util.LuceneTestCase;

public class TestAffixConditionShorterThanStrip extends LuceneTestCase {

  public void testSuffixConditionAtEndOfRoot() throws Exception {
    String aff = "SFX A Y 1\nSFX A abc d [c]\n";
    String dic = "1\nxabc/A\n";
    Dictionary dictionary =
        new Dictionary(
            new ByteArrayInputStream(aff.getBytes(StandardCharsets.UTF_8)),
            List.of(new ByteArrayInputStream(dic.getBytes(StandardCharsets.UTF_8))),
            false,
            SortingStrategy.inMemory());
    // expected: xd (= xabc - abc + d, and the root xabc ends in c) is correct; actual: rejected
    assertEquals("spell(\"xd\")", true, new Hunspell(dictionary).spell("xd"));
  }
}
# in a copy of this finding's repro folder (repro/LFV-374/, which holds src/)
# Lucene checkout at the tested commit, built with: ./gradlew --no-daemon assemble   (JDK 25)
LUCENE=/path/to/lucene; V=12.0.0-SNAPSHOT
CP=$LUCENE/lucene/core/build/libs/lucene-core-$V.jar
CP=$CP:$LUCENE/lucene/codecs/build/libs/lucene-codecs-$V.jar
CP=$CP:$LUCENE/lucene/test-framework/build/libs/lucene-test-framework-$V.jar
CP=$CP:$LUCENE/lucene/analysis/common/build/libs/lucene-analysis-common-$V.jar
CP=$CP:randomizedtesting-runner-2.9.2.jar:junit-4.13.2.jar:hamcrest-3.0.jar   # test-framework dependencies (Maven Central)
CP=$CP:junit-platform-console-standalone-6.1.3.jar   # JUnit Platform console launcher (Maven Central)

javac -d classes -cp "$CP" $(find src -name '*.java')

# run 1: assertions on, seed DEADBEEF
java -ea -esa --add-modules jdk.incubator.vector --enable-native-access=ALL-UNNAMED -Dtests.seed=DEADBEEF \
     -cp "classes:$CP" org.junit.platform.console.ConsoleLauncher \
     execute --select-class org.apache.lucene.analysis.hunspell.TestAffixConditionShorterThanStrip
- Expected vs actual
- Expected
spell("xd")to be true (xabc ends in c, and the same rule with the literal conditioncaccepts it); actual: false (expected:<true> but was:<false>), with-eaand-da.
More files, environment, full output34 words
| lucene | Lucene main e1faeba08bde (2026-11-02) |
|---|---|
| jdk | 25.0.3+9-LTS |
# Lucene main 645d4fe14a20, assertions on (-ea), seed DEADBEEF: 1 test(s) run, 1 failed
    => java.lang.AssertionError: spell("xd") expected:<true> but was:<false>
       org.junit.Assert.fail(Assert.java:89)
       org.junit.Assert.failNotEquals(Assert.java:835)
       org.junit.Assert.assertEquals(Assert.java:120)
org.apache.lucene.analysis.hunspell.TestAffixConditionShorterThanStrip.testSuffixConditionAtEndOfRoot(TestAffixConditionShorterThanStrip.java:36)- Lucene disagrees with itself: the literal condition
mworks,[m]does not; only this one line uses the wrong end. - hunspell(5) says
SFX B y ied yapplies to "words terminated with an y"; C Hunspell acceptsdataand rejectsquanta. - A regression from a 2021 speed-up (LUCENE-9806): the old code had both templates the right way round.
The full argument399 words
- Contract. hunspell(5): the condition "must be met before the affix can be applied",
[...]is a character set and.any character; the exampleSFX B 0 ed [^y]/SFX B y ied yis explained as "First B suffix can be added to a word if the last character of the word isn'ty'. Second suffix can be added to the words terminated with any'" (C Hunspell 1.7.2man/hunspell.5:88-89,:95-98,:541-544). The man page does not state "the end of the root" as a rule in so many words; its example and the C code fix the alignment:SfxEntry::checkwordbuilds stem + strip and tests the condition backwards from the end,PfxEntry::checkwordbuilds strip + stem and tests forwards (affentry.cxx:232-243,:651-667). - Lucene's own javadoc.
acceptsStem: "whether the given word matches this condition as a stem with both "strip" and "affix" removed" (AffixCondition.java:63-66). Package: "A Java implementation of Hunspell stemming and spell-checking algorithms".Hunspell: "can be used in place of native Hunspell for many languages"; its examples ("For example:") of what is not supported yet are Hungarian, characters outside the Basic Multilingual Plane and the PHONE option (Hunspell.java:35-44). CHANGES 8.9.0, LUCENE-9687: "fix various behavior differences between Java and C++ implementations". - Lucene contradicts itself.
uniqueKeyaligns literal conditions the Hunspell way (strip.endsWith(condition)forSFX,strip.startsWith(condition)forPFX,AffixCondition.java:73-80), asserted byTestAffixCondition.testUniqueKey(uniqueKey(SUFFIX, "abc", "bc")is always true); the branch for conditions longer than the strip does too (:111-123). Somand[m], orc,[c]and.c, give different answers. - History. Before
3a99e2aa82d(LUCENE-9806, "speed up affix condition checking", 2021-02-24),DictionarybuiltisSuffix ? ".*" + condition : condition + ".*"and ran it on the whole root, which is correct. The commit moved the check onto the strip alone and kept the two templates with the kinds swapped. Its PR description says "No new tests"; the review is about regex and automaton building. The only bracket case inTestAffixConditionthat reaches this branch has as many patterns as the strip, where both templates agree. - Tests. None asserts the current behaviour: Lucene's test fixtures have one short regexp rule, where both alignments agree; C Hunspell 1.7.2's tests have none. Every hunspell test that runs passes with the fix (13 are skipped because they need external dictionaries).
The devil's-advocate check153 words
Strongest case (the intended-behaviour checker, the cross-model reviewers and the adjudication): a condition that lies wholly inside the strip is either redundant or contradicts the strip, so such rules are odd dictionary input; the man page does not literally say "the end of the root"; HunspellStemFilter is @lucene.experimental; no public dictionary is affected.
Why it fails: the redundant case (SFX A um a [m]) is ordinary, and C Hunspell 1.3.2 applies it with no warning; Dictionary loads both kinds of rule without a ParseException; the man page's own example and the C code fix the alignment; Lucene's literal path and longer-condition path use that alignment, so m and [m] disagree, which no reading of the format allows; Hunspell and Dictionary are not experimental, and "experimental" is about API stability, not wrong results; rarity bears on impact, not on intent. Every reviewer rated the intended-behaviour case weak. Verdict: a defect.
Recommended Swap the two templates (one line)
Swap the two templates on line 107 of AffixCondition.compile, so a suffix condition is matched at the strip's end and a prefix condition at its start: kind == PREFIX ? condition + ".*" : ".*" + condition. Validated: every repro and every hunspell test passes, and so does the module's lint check.
       if (conditionChars <= strip.length()) {
-        String regex = kind == PREFIX ? ".*" + condition : condition + ".*";
+        // the condition lies inside the strip: it must match the strip's start (PFX) or end (SFX)
+        String regex = kind == PREFIX ? condition + ".*" : ".*" + condition;
         return strip.matches(regex) ? ALWAYS_TRUE : ALWAYS_FALSE;
       }
All options and trade-offs2 options · 540 words
One fix was built and validated in a scratch worktree; the second option is an equivalent rewrite that was not run. A related bug in the same lines (dash ranges in the strip part) has its own fix and can share a PR.
In AffixCondition.compile, the branch for a condition that lies inside the strip (AffixCondition.java:106-109):
       if (conditionChars <= strip.length()) {
-        String regex = kind == PREFIX ? ".*" + condition : condition + ".*";
+        // the condition lies inside the strip: it must match the strip's start (PFX) or end (SFX)
+        String regex = kind == PREFIX ? condition + ".*" : ".*" + condition;
         return strip.matches(regex) ? ALWAYS_TRUE : ALWAYS_FALSE;
       }
Trade-offs
- None found for cost: the branch still runs once per distinct rule at load and still returns a constant.
- For conditions in Hunspell's syntax it changes results only for conditions shorter than the strip (a condition with other Java regex characters, outside the format, can change at equal length too:
.*bon the suffix stripabcgoes from always true to always false). Dictionaries with such rules accept and stem differently after the upgrade, so fields stemmed with them need reindexing. - The dash-range handling in the same lines (
[a-c]read as a range) is a separate bug with its own fix; a lone-condition is this bug and the swap fixes it.
What the checks validated
- Gradle, scratch worktree at
a9779ef3c193, seedDEADBEEF, assertions on and off. Stock, with the unit test and the four repro classes: 31 tests, 20 failures (the paste-ready test 3 of 4, the finder's 4 of 5, the independent reproducer's 10 of 12, the spellings test 2 of 2, the new unit test); every control passes. - With the fix,
--tests 'org.apache.lucene.analysis.hunspell.*': 50 classes, 182 tests, 0 failures, 13 skipped (they need external dictionaries); that is Lucene's 46 hunspell test classes with 159 tests, including the new unit test, plus the 4 repro classes. :lucene:analysis:common:check -x testwith the fix, the unit test and the paste-ready test passes (formatting, ecj lint, forbidden APIs).- Repro harness: the paste-ready test fails 3 of 4 on main (assertions on and off), 10.5.2 and 9.12.3, and passes 4 of 4 with the fix. A probe of the lone-dash rule
SFX A a- x -:bxrejected on main, accepted with the fix, as C Hunspell 1.3.2 answers. - Earlier, on
ea57360912ed: the finder's test 5 of 5, the independent reproducer's 12 of 12 and upstreamTestAffixCondition7 of 7 and the 146 tests of Lucene's hunspell test classes pass with the swap; the bounded-exhaustive check of the real class (144,482,592 cases) loses its 4 wrong-end classes;3a99e2aa82dplus the swap is correct.
For SUFFIX, match the strip's last conditionChars characters against the condition (strip.substring(strip.length() - conditionChars).matches(condition)); for PREFIX, the first ones.
Trade-offs
For conditions made of Hunspell's one-character patterns (letters, ., [...]) this gives the same answers as the swap and states the intent more plainly, at a slightly larger diff; conditions with other regex characters could behave differently. Not run.
Indexes built with HunspellStemFilter and such a rule hold the wrong stems (for example repack indexed as unpack, data not as datum), so those fields need reindexing after the fix.
While writing an SMT model of how AffixCondition.compile splits a condition between strip and stem, the finder suspected this branch; the model found mismatches only for conditions shorter than the strip. A bounded-exhaustive check of the real class confirmed it, and JUnit tests on the public API reproduced it.
The method in full175 words
Method: semi-formal (a hypothesis from code reading while modelling, witnessed by the model and by a bounded-exhaustive check of the real code). Hunt unit on Hunspell, main ea57360912ed, 2026-10-26.
- SMT model (Z3) of
compile's split of a condition into a strip part and a stem part, against the hunspell(5) semantics: mismatches are satisfiable only when the condition has fewer character patterns than the strip, for both prefix and suffix rules; unsatisfiable for equal or longer conditions and for the corrected model. - Bounded-exhaustive translation validation of the real
AffixConditionon the stock jar: 40,494 conditions, strips up to 3 and stems up to 2 characters, 144,482,592 checks. 4 wrong-end classes for shorter conditions, gone with the swap (the remaining dash-range classes are the separate bug; with both fixes 0 checks differ). - JUnit on the public API, then C Hunspell 1.3.2 as the oracle, independent reproduction, cross-model reviews, a devil's advocate and an adjudication (see the checks below).
- Survey of 191 public dictionaries for rules of this shape (4 found, none changing a result).
No prior report: 54 recorded searches on 2026-10-26 (GitHub issues, PRs and commits; Elasticsearch, OpenSearch and Solr; the Lucene mailing lists; JIRA; the web), and the changed files of all open PRs re-checked on 2026-10-28. The closest item is LUCENE-9806 (#10845), the change that introduced it.
Searches4 searches
No report, issue, PR, list thread or downstream report about this behaviour was found. The only high-overlap items are the change that introduced it; older condition bugs have other root causes and predate it.
| Where | When | How | Found |
|---|---|---|---|
| GitHub apache/lucene issues, PRs and commits (search tool and manual searches) | 2026-10-26 | class and method names (AffixCondition, compile, uniqueKey), symptoms (condition strip, suffix condition, prefix condition swapped, bracket condition), several phrasings; plus a full listing of every apache/lucene issue and PR (202 hunspell or affix items); all 411 open PRs listed, and the changed files of the 168 with module:analysis or no module label checked | only #10845 / lucene-solr#2423 / 3a99e2aa82d, the change that introduced it (empty issue body, no discussion of this branch); #16422 is the only open PR touching a hunspell file (directive parsing only) |
| GitHub apache/lucene, open PRs | 2026-10-28 | the changed files of all 410 open PRs (the 4 with 100 or more files re-listed through GitHub's PR-files API) | only #16422 (the same one-file change of Dictionary.java on main) and #16911 ("Decommission branch 10x", which deletes every file of branch_10x) touch hunspell files; neither changes line 107 on main |
| Downstream: Elasticsearch, OpenSearch, Solr; the reference hunspell repository; all of GitHub | 2026-10-26 | GitHub search | none; OpenNLP has a separate class of the same name |
| dev@, java-user@, issues@ and commits@ lists, JIRA (LUCENE), the web | 2026-10-26 | search tool queries and lists.apache.org directly; the review of lucene-solr#2423 read in full | none relevant; #10724 (LUCENE-9685) is an earlier, different prefix-condition fix; #6830 (LUCENE-5768) and #6839 (LUCENE-5777) are 2014 bugs in code later replaced |
Introduced by 3a99e2aa82d (LUCENE-9806, a speed-up merged 2021-02-24). First affected release 8.9.0; 8.8.2 is correct. All 60 releases from 8.0.0 to 10.5.2 were run: the 41 from 8.9.0 on are wrong. Not fixed upstream.
Versions tested7 rows
Introduced by 3a99e2aa82d860b6a319cea39607ab3c8ef590b5, "LUCENE-9806: Hunspell: speed up affix condition checking (#2423)" (@donnerpeter, reviewed by @rmuir, merged 2021-02-24; issue #10845, a sub-task of LUCENE-9687, #10726). It reached branch_8x through the backport c6b964a11576 (lucene-solr#2499, 2021-05-28), with the identical line. Before it, Dictionary matched isSuffix ? ".*" + condition : condition + ".*" against the whole root, which is correct.
The spell-checking class Hunspell first ships in 8.9.0; the stemming path exists in every 8.x release. A separate, older prefix defect in 8.0.0-8.8.2 (a prefix rule whose strip is longer than its affix gave no stem even with a literal condition) is not this bug.
| Version or commit | Verdict | Result |
|---|---|---|
main a9779ef3c193 and ea57360912ed | affected | JUnit fails with assertions on and off; the portable probe is wrong in 6 of 6 cases |
| 10.0.0 to 10.5.2 | affected | portable probe wrong in 6 of 6 on every release; JUnit fails on 10.5.2 |
| 9.0.0 to 9.12.3 | affected | portable probe wrong in 6 of 6 on every release; JUnit fails on 9.12.3 |
| 8.9.0 to 8.11.4 | affected | portable probe wrong in 6 of 6 on every release |
| 8.0.0 to 8.8.2 (19 releases) | not affected | portable probe correct; controls pass |
commits e1ff4c13541f (parent), 3a99e2aa82d, 3a99e2aa82d + swap | bisect | parent correct, the commit wrong in 6 of 6, the commit plus the swap correct |
upstream main cf398bfb142c, branch_10x, branch_10_6, branch_10_5 (2026-10-26); upstream main c5ab3e57b9ba (2026-10-28) | read | the template is unchanged (#16919, merged 2026-10-28, changed two other lines of the file, and the fix still applies); no open PR changes the file on main |
An independent reproducer, cross-model reviews, an intended-behaviour devil's advocate, an adjudication and a credibility audit. Every re-run on main failed with assertions on and off, and every run with the fix passed. A cross-model review could not run code and returned its procedural default while agreeing on the root cause.
Checks and verdicts345 words
Each check ran or read on its own; the registration check and this doc re-ran the tests with fresh seeds, through the harness and through gradle on a9779ef3c193.
| Check | Verdict | What it found |
|---|---|---|
| finder (SMT model, bounded-exhaustive check, JUnit) | candidate | Z3 model and 144,482,592 checks of the real class; JUnit fails 4 of 5 on main (assertions on and off), 10.5.2 and 9.12.3; the fix passes 5 of 5 and the 146 existing hunspell tests. |
| cross-model review, refute lens | not real, low (procedural) | An independent reviewer from another model family (OpenAI GPT-5.6) could not run code; its reading agreed with the root cause and rated the intended-behaviour case weak; a separate re-run failed 4 of 5. |
| independent reproducer | real | Own 12-test JUnit with other words fails 10 of 12 on main (assertions on and off), 10.5.2 and 9.12.3; controls pass; its own swap passes 12 of 12; C Hunspell 1.3.2 agrees with the expected values; the public stemming probe is wrong from 8.9.0 and right on 8.8.2. |
| cross-model review, works-as-designed lens | real, high | OpenAI GPT-5.6, reading only: intended-behaviour argument weak, root cause agreed, fix correct; a separate run re-ran the finder's test (4 of 5 fail) and C Hunspell 1.3.2 on the finder's dictionary. |
| intended-behaviour devil's advocate | real | No intended-behaviour argument holds; its own test shows 14 equivalent spellings of one condition disagreeing on stock and agreeing with the fix; no Lucene or C Hunspell fixture asserts the current behaviour. |
| adjudication | confirmed, high | Re-ran the independent reproducer's test (10 of 12 fail), the finder's with assertions off (4 of 5 fail) and the reproducer's test with the swap (12 of 12 pass). Caveat: low practical impact. |
| credibility audit | keep | Re-ran both tests on main (4 of 5 and 10 of 12 fail) and checked the root cause, the oracle and the score. |
| main refresh and this doc | still reproduces | On a9779ef3c193 the finder's test still fails 4 of 5; this doc's gradle and harness runs are listed under the fix. |
The diagram as a still image, generated with AI and checked against the code. It is under 10 MB, the limit for a GitHub attachment.
- PNG 432 KB
Finding record, Lucene and upstream sources, repro files and diagram notes1,373 words
- Registry title
- Hunspell: a bracket or dot affix condition with fewer character patterns than the strip is checked against the wrong end of the strip (a suffix rule at the strip's start, a prefix rule at its end), so the rule never applies when it should, or always applies when it should not
- Area
- analysis / hunspell (affix conditions: Dictionary loading, Hunspell.spell/getRoots, Stemmer and HunspellStemFilter)
- Priority
- Low, rank 464: Short bracket affix conditions silently give wrong spelling verdicts and stems, including in HunspellStemFilter, but this changes no result in any surveyed public dictionary, so it follows the spell-check rows.
- Impact class
- silent wrong results
- Impact note
- Only applications that use the opt-in Hunspell analysis (Hunspell.spell and getRoots, HunspellStemFilter and the Stemmer [exec]; word-form generation and suggestions use the same compiled condition, by code reading only) with a dictionary that has a PFX or SFX rule whose condition uses [ ] or . and has fewer character patterns than its strip get wrong spelling verdicts and wrong or missing stems, with no error; no scale is needed and every release from 8.9.0 to 10.6.0 has it (10.6.0 by reading), but the finder's survey of 191 public .aff files found only 4 rules of this shape (all in bn_BD) and none whose result changes.
- Summary
- You load a Hunspell dictionary with the suffix rule 'SFX A abc d [c]' (strip abc, add d, condition [c]) on the root xabc and expect the condition to be tested where Hunspell lines it up, at the end of the root, which for a condition shorter than the strip is the end of the strip: xd should be a correct word with stem xabc and 'SFX A abc e [a]' should never apply, as C Hunspell 1.3.2 answers and as Lucene itself answers when the same condition is written as the literal c. Instead Lucene rejects xd and accepts xe as a form of xabc, and the prefix rules 'PFX B abc d [a]' and 'PFX B abc e [c]' on the root abcx are reversed the same way (dx rejected, ex accepted); spell, getRoots and HunspellStemFilter give these wrong verdicts and stems with no error. The cause is AffixCondition.compile: for a condition with [ ] or . and no more character patterns than the strip, it decides the rule once at load by matching the strip against 'kind == PREFIX ? "." + condition : condition + "."', which tests the strip's start for SFX and its end for PFX, the two templates swapped between the kinds.
- Introduced
- 3a99e2aa82d860b6a319cea39607ab3c8ef590b5, LUCENE-9806 'Hunspell: speed up affix condition checking' (apache/lucene-solr#2423, by donnerpeter, reviewed by rmuir, merged 2021-02-24; migrated issue apache/lucene#10845; a sub-task of LUCENE-9687, #10726) [read: git blame of AffixCondition.java:106-108 points to this commit and the lines are unchanged since; exec: the version-portable probe is correct with the hunspell package of the parent e1ff4c13541f shadowed over the 9.0.0 jars, wrong in 6 of 6 cases with that of 3a99e2aa82d, and correct with 3a99e2aa82d plus the one-line template swap]. Reached 8.x through the branch_8x backport c6b964a11576 (lucene-solr#2499, LUCENE-9687; identical line at its AffixCondition.java:94). A regression: before it, Dictionary built 'isSuffix ? "." + condition : condition + "."' and matched it against the whole root (stem plus strip), which is correct; the commit moved the check onto the strip alone and gave each template to the other kind (2021-02-24 (main); 2021-05-28 (branch_8x backport))
- First affected version
- 8.9.0 [exec] (all 19 releases from 8.0.0 to 8.8.2 are correct [exec]; the stemming path exists in every 8.x release, while the spell-checking class Hunspell first ships in 8.9.0); on the 9.x line 9.0.0 [exec]
- Affected versions
- every release from 8.9.0 to 8.11.4, 9.0.0 to 9.12.3 and 10.0.0 to 10.5.2 (41 releases), 10.6.0 (by reading) and main ea57360912ed. Executed: the version-portable public-API probe (Dictionary + HunspellStemFilter, 6 bug cases xd, xe, data, quanta, redo, repack with expected values from C Hunspell 1.3.2, plus 2 literal-condition controls) on all 60 Maven Central releases from 8.0.0 to 10.5.2 and on main with -ea and -da: 8.0.0-8.8.2 correct, 8.9.0-10.5.2 and main wrong in all 6 cases, controls pass everywhere; the finder's JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3 (it compiles from 9.9.0 on); the independent reproduction's JUnit fails on main (-ea, -da), 10.5.2 and 9.12.3. [read] the line is identical at 10.5.2, 9.12.3 and 9.0.0. Not fixed upstream: main 645d4fe14a2 still fails [exec 2026-10-29, -ea and -da; #16919 changed AffixCondition.java only at :126 and :147]; the template is unchanged on branch_10x 657014b3c57 and branch_10_6 4ae946e5a9b [read 2026-10-29] and on branch_10_5 [read 2026-10-26]. 10.6.0 (released 2026-10-29) was read, not executed. All runs on aarch64 with JDK 25
- Status
- documented (brief, checks and a per-finding doc exist)
- Verification
- Confirmed by AI-run checks: an independent repro, a cross-model review that could only read the code (its low-confidence “not real” is procedural), an intended-behaviour check, a prior-report search and a skeptical audit; not yet triaged by a person.
- Found by
- semi-formal: code reading; also reached by Z3, exhaustive check
- Upstream and prior reports
- none found (2026-10-26, read-only, the prior-report record verdict new, 54 query records: a scripted prior-report search over GitHub issues and PRs, commits, downstream repositories (Elasticsearch, OpenSearch, Solr), the dev@, java-user@, issues@ and commits@ lists, JIRA and the web; manual gh searches of apache/lucene, the downstream repositories, the reference hunspell repository and all of GitHub; a full listing of every apache/lucene issue and PR (202 hunspell or affix items, none of the 72 created after 2021-02-24 matches); the changed files of all 411 open apache/lucene PRs; lists.apache.org direct; the review of lucene-solr#2423 read in full; the intended-behaviour check's searches agree). Closest items: #10845 (LUCENE-9806), lucene-solr#2423 and commit 3a99e2aa82d, the change that introduced it (no discussion of this branch); #10724 (LUCENE-9685), an earlier, different prefix-condition fix; #6830 (LUCENE-5768) and #6839 (LUCENE-5777), 2014 condition bugs in code that was later replaced; #16422, the only open PR touching a hunspell file (Dictionary.java directive parsing only). Not fixed upstream (AffixCondition.java:107 unchanged on upstream main 645d4fe14a2, branch_10x 657014b3c57, branch_10_6 4ae946e5a9b and branch_10_5; #16919 touched the file only at :126 and :147; recheck 2026-10-29).
- Lucene commit tested
- main
a9779ef3c193: gradle in a scratch worktree (assertions on and off, stock and with the fix, the module's lint check) and the repro harness (stock with assertions on and off, fix shadowed); the 10.5.2 and 9.12.3 release jars (JUnit). Mainea57360912ed(hunt, verifiers, adjudication, follow-up and audit, 2026-10-26; no hunspell file differs froma9779ef3c193). The version-portable stemming probe on all 60 Maven Central releases from 8.0.0 to 10.5.2, and commit isolation ate1ff4c13541f(parent),3a99e2aa82dand3a99e2aa82dplus the swap. C Hunspell 1.3.2 as the oracle. On 2026-10-28 the doc's fact checks re-ran the gradle command and the harness, and a probe of the lone-dash ruleSFX A a- x -ran on main and with the fix.
- Finding record
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/AffixCondition.java at ea57360912ed: :63-67 (acceptsStem javadoc 'whether the given word matches this condition as a stem with both strip and affix removed'), :73-80 uniqueKey (strip.endsWith(condition) for SFX, strip.startsWith for PFX), :105-109 (the short-condition branch, line 107 the swapped template), :111-123 (the condition-longer-than-strip branch, correct alignment)lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:748-760 (affix parser: condition defaults to '.', uniqueKey, AffixCondition.compile once per distinct key); Stemmer.java:505-521 (the compiled condition is checked on the stem with strip and affix removed)lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestAffixCondition.java (testUniqueKey: uniqueKey(SUFFIX, "abc", "bc") and uniqueKey(PREFIX, "abc", "ab") are ALWAYS_TRUE_KEY; its bracket cases, [io]j and the unclosed o[ioj on strip oj, have as many character patterns as the strip)
- The finding in 30 seconds
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/AffixCondition.java:34-57, 63-66, 73-80, 86-129 (105-108 the branch, 107 the template), 153-155lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/Dictionary.java:748-760; Stemmer.java:516-521; GeneratingSuggester.java:270; WordFormGenerator.java:107, 362
- Why it looks unintended
lucene/analysis/common/src/java/org/apache/lucene/analysis/hunspell/AffixCondition.java:63-66, 73-80, 105-123; Hunspell.java:35-44, 71-73; package-info.java:19-20; HunspellStemFilter.java:39lucene/analysis/common/src/test/org/apache/lucene/analysis/hunspell/TestAffixCondition.java:49-64lucene/CHANGES.txt:5368-5369
- TestAffixConditionShorterThanStrip.java (JUnit test):
repro/LFV-374/src/org/apache/lucene/analysis/hunspell/TestAffixConditionShorterThanStrip.java(38 lines)
A picture of the doc's worked example, made in parallel with this doc from the code at a9779ef3c193 and executed probe runs.
assets/LFV-374/bug.png(432 KB)